Oct
05
2026
--

Thread Pool in Percona Server and MySQL (Part 1)

Thread Pool in Percona Server and MySQL (Part 1)

A new version of Community MySQL Server July release contains two versions 26.7.0 and 9.7.2. It is an important milestone because it finally brings a Thread Pooling feature to the community. The official MySQL Server Thread Pool plugin existed for a long time, but was available exclusively for MySQL Enterprise Edition.

Before MySQL 26.7.0 / 9.7.2 the most popular free thread pooling enabled alternatives were:

  • Percona Server for MySQL, which shipped Thread Pool functionality as a plugin
  • MariaDB with the Thread Pooling built into the server
  • Third-party plugins such as xiezhenye/mysql-plugin-threadpool available on GitHub

Now we will be able to see what benefits the thread pooling mechanism brings to MySQL Server and compare it with the implementation of the thread pool in Percona Server for MySQL.

Part 1 will explain the basics of thread pooling and analyze the efficiency of its implementation in Percona Server for MySQL. The performance comparison between Percona Server and MySQL Server is done in Part 2.

What is Thread Pooling and why is it needed?

Thread Pooling is a technique that reuses a fixed number of pre-created threads to handle multiple client connections and execute statements inside a database.

By default, MySQL creates a dedicated thread whenever a client connects, runs the queries, and then destroys the thread when finished. When connection counts grow very large, this default method causes performance to drop significantly because creating, destroying, and constantly switching between thousands of threads wastes system resources and causes contention.

This blog post from Vadim Tkachenko explains the working of thread pool, which gives an easy to understand similarity with the car traffic:

SimCity outages, traffic control and Thread Pool for MySQL

More information about it can be found in Percona Documentation.

WARNING: the post is several pages long because it looks into different aspects of thread pooling and compares the effect of various options. If you do not want to dive into the details, feel free to read the SPOILER below and proceed to the Conclusion section.

SPOILER: Thread Pool is not a universal database booster, which always brings performance up. Like every advanced tool it should be used with full understanding of the goals and objectives. Otherwise the results might be far from perfect.

How it works

  1. Thread Groups: The pool divides threads into distinct groups that are assigned to a specific CPU core. For this reason the number of groups often matches the number of CPU cores.
  2. Round-Robin Assignment: As client connections come in, they are distributed evenly across these groups.
  3. Listening and Queuing: Inside each group, a listener thread monitors incoming queries and places them into either a high-priority queue (such as queries within an active transaction) or a normal/low-priority queue.
  4. Execution and Reuse: Worker threads pick up queries from the queues (handling high-priority items first), execute them, and then wait to handle the next request instead of shutting down.

See also:

Thread Pool configuration:

In this research we will be sweeping across the range of various parameters of the Thread Pool and see how the performance of the server is affected.

The base line will be the server configuration when the thread pool is not enabled. This is done by setting thread_handling=one-thread-per-connection. When the pooling is enabled (thread_handling=pool-of-threads) the benchmark will set different values for the following variables that control the thread pool behavior:

Name Sweep range Description
thread_pool_size 10 / 20 / 40 / 80 / 120 / 160 Number of thread groups in the pool.
NOTE: thread_pool_size=5 was also tested, but the performance was unsatisfactory, for that reason it is not included in the report.
thread_pool_max_threads /
thread_pool_max_active_query_threads
12000 Maximum number of threads in the pool.
thread_pool_oversubscribe /
thread_pool_query_threads_per_group
2 / 3 / 4 Number of threads that can be active at the same time within the same group.


Other Configuration and Methodology

The configuration was as follows:

Benchmark Sysbench OLTP Read-Write
CPU Intel Xeon Gold 6230 (2×20 cores, HT = 80 logical CPUs)
RAM 187 GiB DDR4
Storage NVMe SSD (2.9 TB) INTEL SSDPE2KE032T8
OS Ubuntu 24.04, kernel 6.8.0-60-generic
DB Engines Percona Server for MySQL 9.7.1-1 (release build)

MySQL Server 26.7.0 (release build)

Additional dimensions for the benchmark:

Database Sizes (Row Number) 24Gb (100M rows)
Number of tables in DB Schema 20 (this number is constant for all runs)

Database Schema definition can be downloaded from here: 

https://percona-lab-results.github.io/2026-interactive-metrics/schema_dump.sql

Number of concurrent threads 40 / 80 / 120 / 160 / 320 / 640 / 1280 / 2560 / 5120
Buffer to Data Ratio 1:12 (I/O bound), 1:2 (Partially buffered), 1:1 (Fully buffered)

Execution of the benchmarks was done as follows:

Ramp-up 48G – 600 sec (10 min)

The Ramp-up times were established experimentally depending on the Data Size until the point when increasing them further did not bring significant changes.

Measurement window 900 sec (15 min)

Ideally it should be as long as possible, but measurements should take reasonable time. Hence, we used the experience of previous benchmarks and established that this window is adequate for the purpose.

Number of runs 1 

Could be more runs, but testing took a long time.

Important Database Configuration options (the actual config files with specific settings for each run can be downloaded from the interactive graphs):

InnoDB – Buffer pool Tier
innodb_buffer_pool_size 2G/12G/32G
innodb_buffer_pool_load_at_startup OFF
innodb_buffer_pool_dump_at_shutdown OFF
Threading
thread_stack 512K
thread_cache_size 256
back_log 4096
InnoDB I/O
innodb_io_capacity 10000
innodb_io_capacity_max 20000
innodb_read_io_threads 16
innodb_write_io_threads 16
innodb_use_native_aio ON
InnoDB Log / Durability
innodb_log_buffer_size 256M
innodb_flush_log_at_trx_commit 1 # full ACID
innodb_doublewrite ON
InnoDB – Concurrency & OLTP Tuning
innodb_stats_on_metadata OFF
innodb_open_files 65536
innodb_lock_wait_timeout 50
innodb_rollback_on_timeout ON
Per-Session Buffers
sort_buffer_size     4M
join_buffer_size     4M
read_buffer_size     2M
read_rnd_buffer_size 4M
tmp_table_size       256M
max_heap_table_size 256M
Binary Log
disable_log_bin ON # Disabled binlog
Other InnoDB settings
innodb_redo_log_capacity     4G
innodb_change_buffering      none
innodb_flush_method          O_DIRECT
innodb_buffer_pool_instances Calculated as
(innodb_buffer_pool_size G / 5)
But must be in range [1..8]
Misc server settings
collation_server utf8mb4_unicode_ci
bulk_insert_buffer_size 256M
myisam_sort_buffer_size  128M
key_buffer_size          64M # MyISAM only, keep small for OLTP


Results

The scope of results is broad and therefore the results presentation will be divided into the sections.

Percona Server 9.7.1-1 with and without thread pool:

The most impressive effect of the thread pool can be illustrated on the following graph where the level of oversubscription is 4 (os4 in the legend) and the number of thread groups is 10 (TP 10 in the legend).

 Graph 1.0 – best effect of thread pooling [ INTERACTIVE GRAPH ][ TABLE ]Graph 1.1 - thread pool size variations
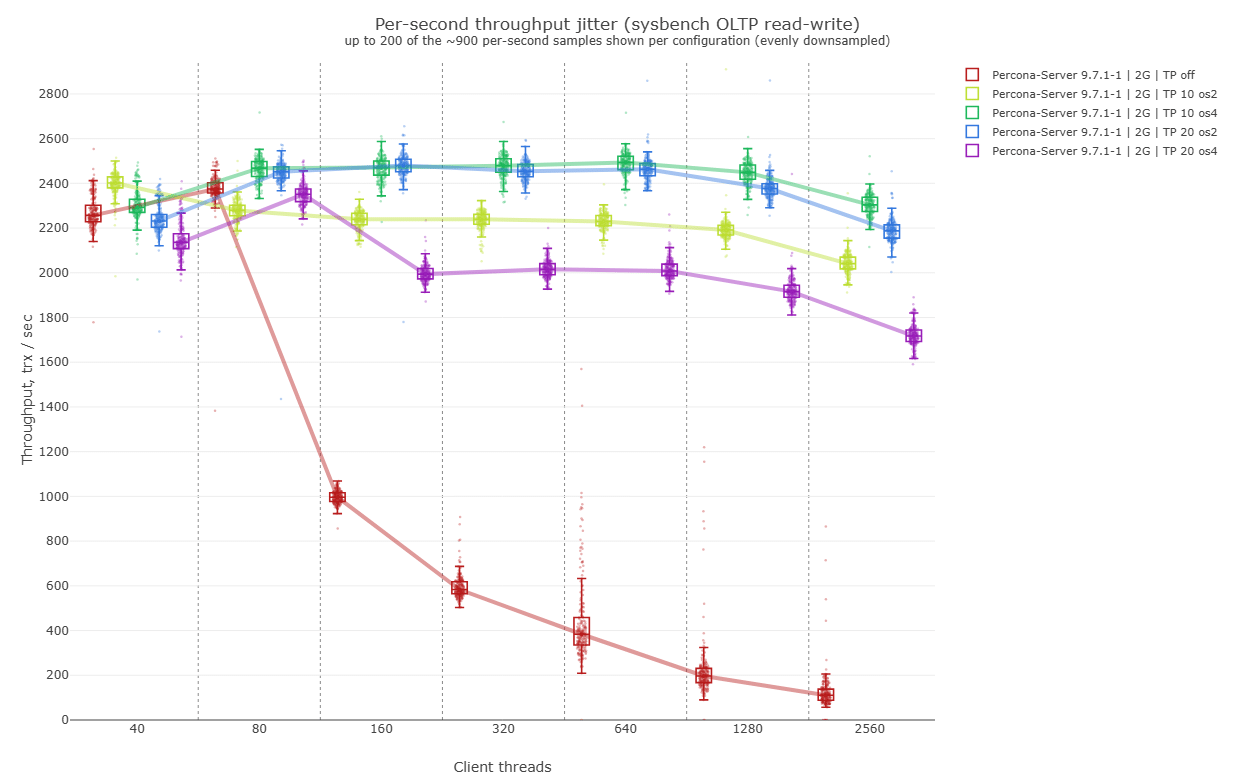
The green line (thread_pool_size=10/thread_pool_oversubscribe=4) is closely followed by the blue line, which corresponds to the number of groups 20 and the oversubscription 2.

As the graph shows – the effect of the thread pool on the performance in the low thread count (40/80) is relatively small. A notable effect starts to show at 120 threads when non-pooled configuration TPS plunges down. It is good to keep in mind that the thread pooling mechanism is not a universal performance booster. Though, it helps to avoid system thrashing when the number of threads is much larger than CPU cores can process.

With 2560 connections the best configuration with thread pool shows excellent efficiency of 2304 TPS against 129 TPS without the thread pool, which is 17.9 times faster. Some thread-pooled configurations are more efficient than the other ones. The combination thread_pool_size=20 with thread_pool_oversubscribe=4 fails to prevent sharp TPS drop at 120 client connections, though its shape improves as the number of connections increases.The drop from the maximum of 2485 TPS at 640 connections to 2304 TPS at 2560 connections is visible (7.5%), but not critical.

Interesting that the optimal number of groups is smaller than the number of physical CPU cores (40).

Another important observation is that in this test increase of the number of thread groups causes the TPS performance to drop: the curve with thread_pool_size=20 is below thread_pool_size=10 and thread_pool_size=40/80/120/160 are even lower.

 Graph 1.1 – thread pool size variations [ INTERACTIVE GRAPH ][ TABLE ]Graph 1.1 - thread pool size variations
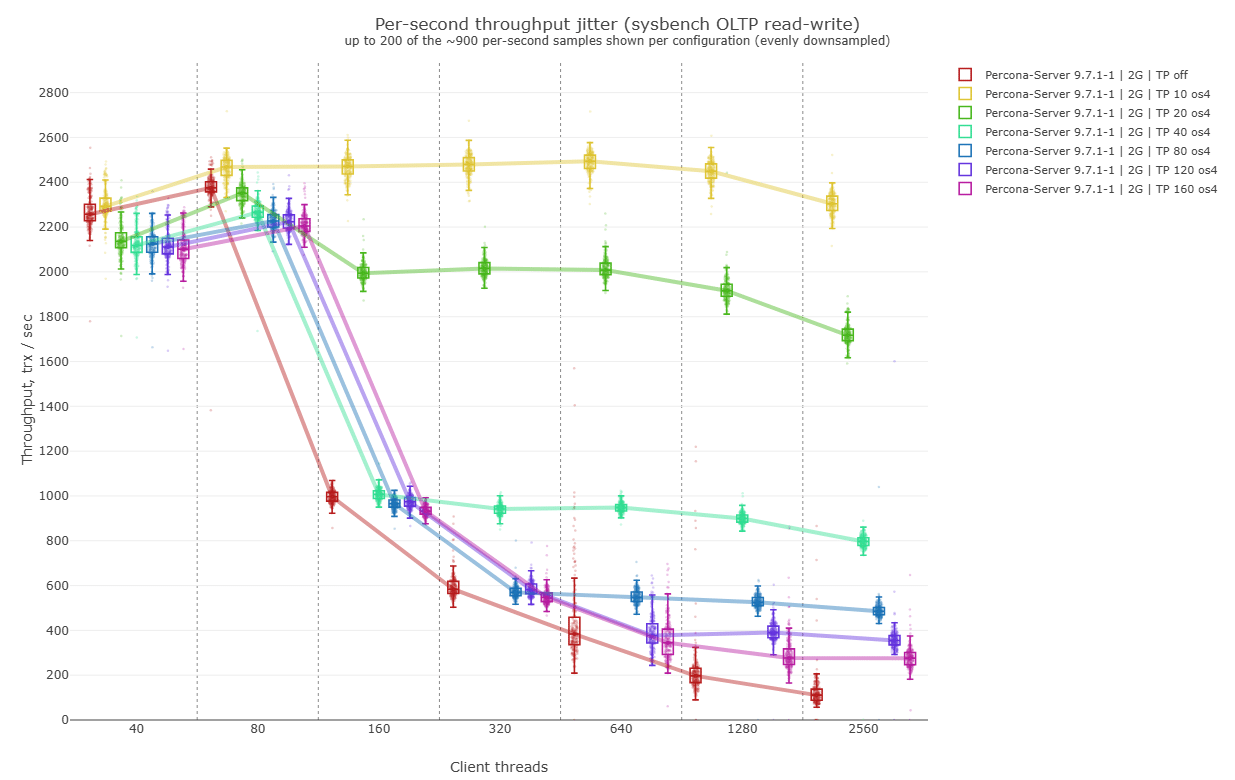
The next graph shows how TPS changes when we consider the optimal value for thread_pool_size=10, but change thread_pool_oversubscribe.

 Graph 2.0 – oversubscription variations [ INTERACTIVE GRAPH ][ TABLE ]Graph 2.0 - oversubscription variations
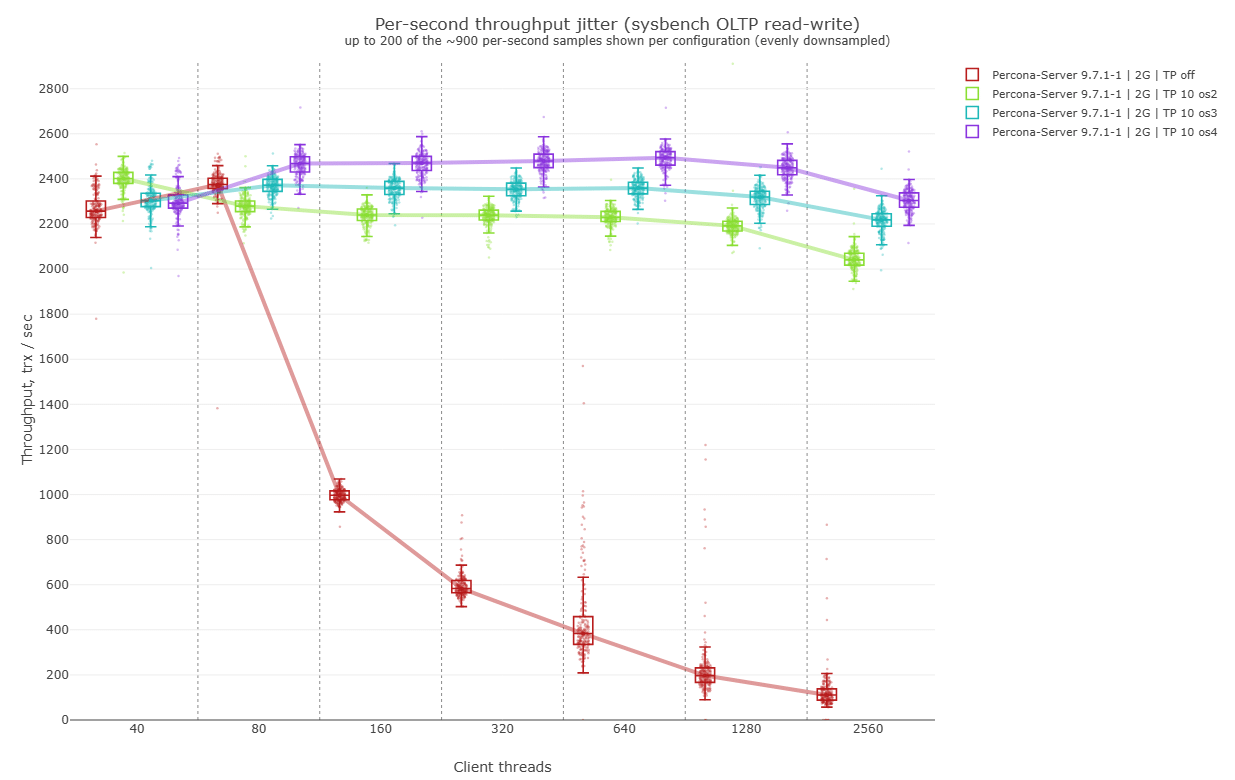
With the best configuration (thread_pool_oversubscribe=4) having 2304 TPS and the least performing pooling configuration (thread_pool_oversubscribe=2) with 2043 TPS the speed difference is 11%. So, a non-optimal oversubscription value can incur a significant penalty.

The above two cases correspond to the I/O bound scenario when the data size (24G) is much larger than the server buffer size (2G).

Let us see how the buffer pool efficiency changes as innodb_buffer_pool_size increased to 12G, which allows buffering approximately half of the data set.

 Graph 3.0 – partially buffered data set (12G buffer)  [ INTERACTIVE GRAPH ][ TABLE ]Graph 3.0 - partially buffered data set (12G buffer)
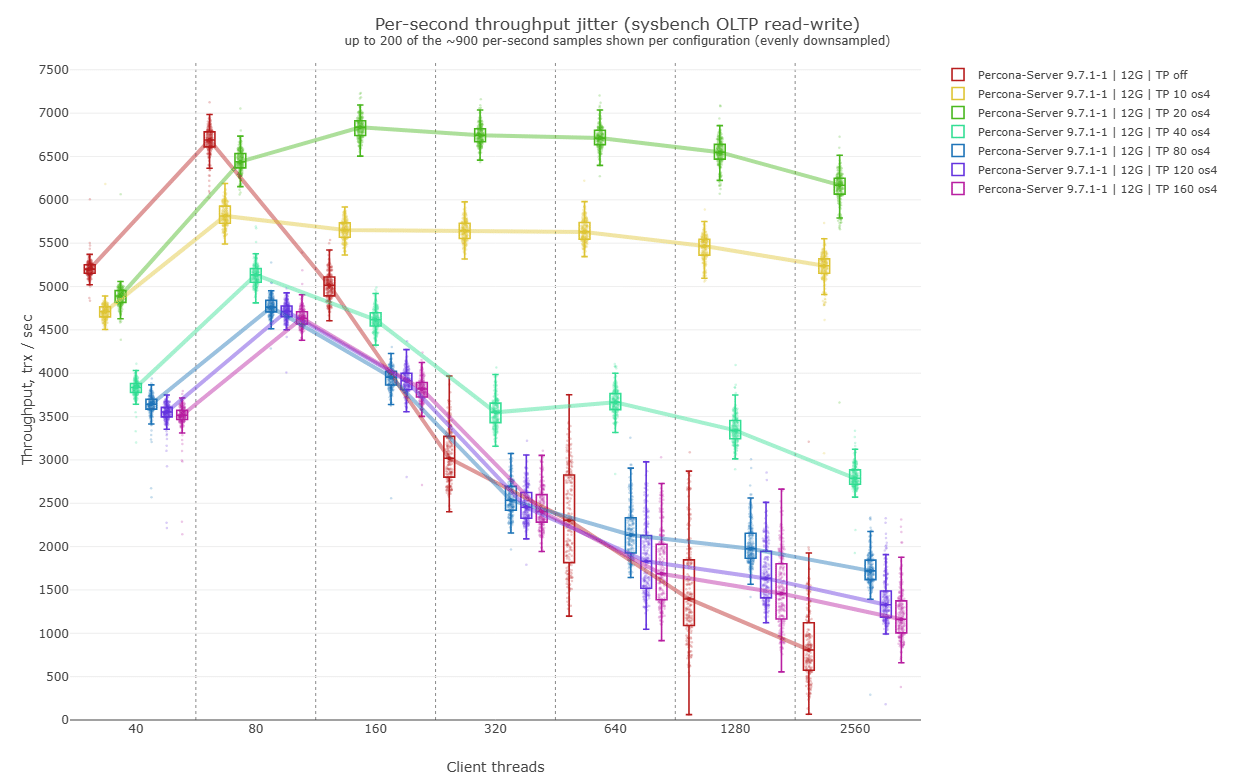
This time thread_pool_size=20 is the optimal value for the data size (24G) and the allocated server buffer size (12G). The non-optimal oversubscription values have a similar effect (look at INTERACTIVE GRAPH) on the performance as in Graph 2.0.

When the server configuration moves to the fully buffered data set the distribution of performance is changed:

 Graph 4.0 – fully buffered data set (32G buffer)  [ INTERACTIVE GRAPH ][ TABLE ]Graph 4.0 - fully buffered data set (32G buffer)
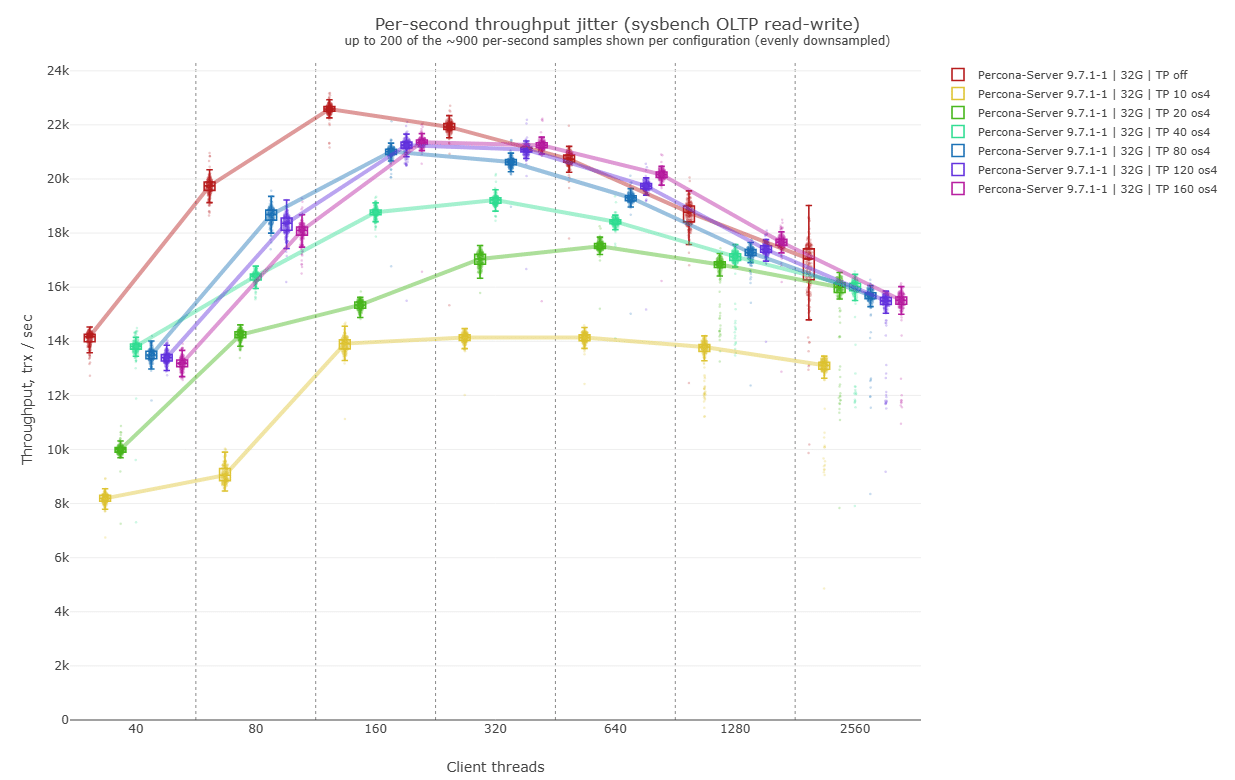
The configuration without the thread pool wins in all number of client connections in this test. The largest deviation from the base line is observed around 80 to 640 connections, but then the performance converses to around 16K TPS for all configurations. The configuration with  thread_pool_size=10 is now the slowest one and larger thread pool sizes perform better.

Varying oversubscription did not have a notable effect with fully buffered data.

NOTE: It would be interesting to see if thread pool wins with 5K or 10K connections. We might do another research devoted to extremely high thread count, but this post describes the efficiency of the thread pool across the low (40) to the high (2560) number of client connection threads.

Despite not having superior performance with regards to TPS with the fully buffered data set, the thread pool is still beneficial with regards to predictability of the server behavior. What I mean by this is most of the clients (95%) connected to the server have their transactions executed quickly, but a minority (5%) have to wait much longer. The response latency for the unlucky 5% might be out of the acceptable range. The long waiting clients do not care about other clients whose data was quickly processed. Therefore, the raw TPS does not hold much value for them.

 Graph 5.0 – p95 latency  [ INTERACTIVE GRAPH ][ TABLE ]Graph 5.0 - p95 latency
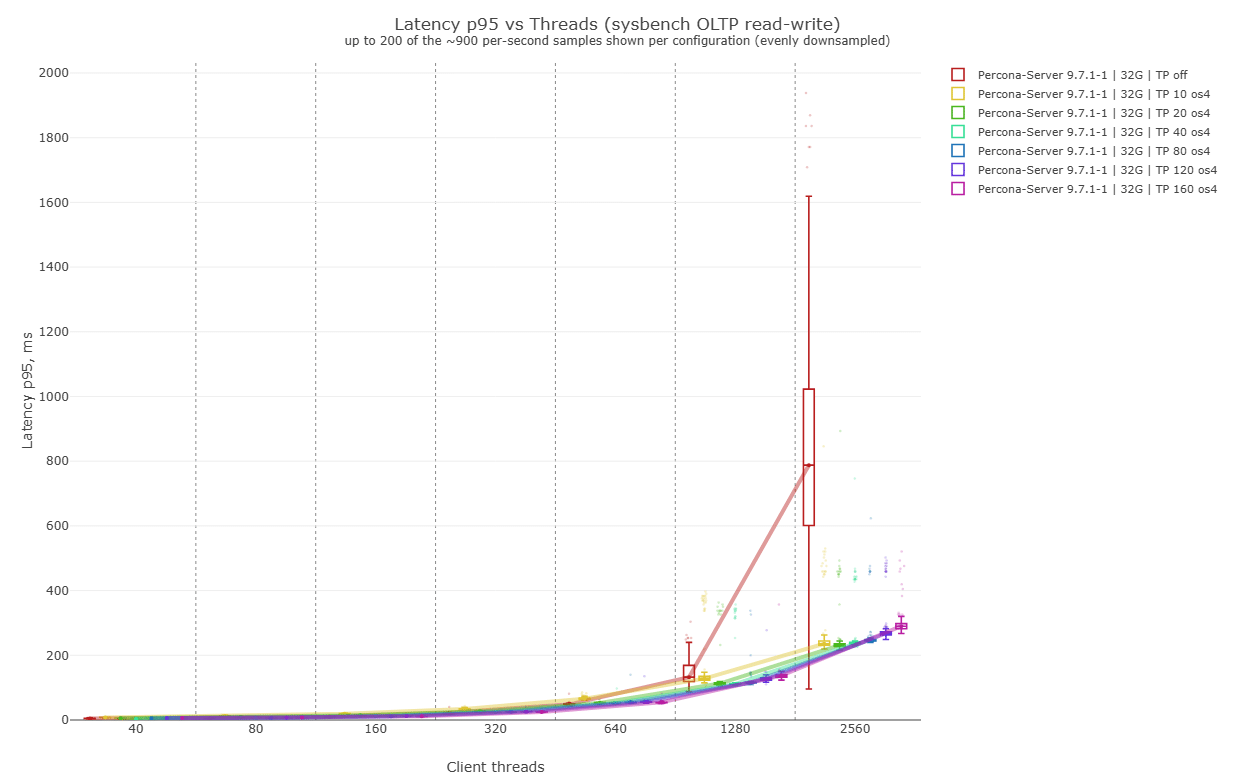
Unlike TPS when the higher value is better, the p95 Latency should be kept as low as possible.

Up to 1280 client connections the p95 latency was grouping around roughly the same numbers. However, for 2560 connections it changed dramatically. The configuration with disabled thread pooling suddenly demonstrated much longer p95 than the pooled counterparts.

The 5% of clients will have to wait longer than 787 ms if the thread pool is not used. The pooled configurations keep a much tighter range of 235-297 ms. The system performs as well as its slowest/weakest link and if a client application performs several transactions it is more likely to end up waiting significantly longer. For some outliers the latency reached 2000 ms. 


Conclusion

Thread pooling does not bring any gains and even causes a small slow down on a low number of server connections.

The most visible effect of thread pooling can be seen in the scenario when I/O is one of the factors that limit performance.

Careful tuning of thread pool options is required to get the best performance. Even a seemingly small variation from optimal parameter values can cause large performance drops.

However, when properly configured, it can show spectacular results with almost 18 times TPS boost compared to the same server running without thread pool.

For system stability we should not only consider the raw TPS numbers, but also the latency related to processing of some transactions. Even if no TPS gain is obtained, the thread pool allows to minimize the waiting time for slowest transactions.

The post Thread Pool in Percona Server and MySQL (Part 1) appeared first on Percona.
Oct
01
2026
--

Talking Drupal #572 – The PHP Foundation

Today we are talking about PHP, Open Source, and Sustainability with guest Elizabeth Barron. We’ll also cover AI Image Classification as our module of the week.

For show notes visit: https://www.talkingDrupal.com/572

Topics

  • What is the PHP Foundation
  • Language Health Challenges
  • Paid Core Developers
  • Release Infrastructure
  • Foundation Role and Perception
  • Docs and Onboarding
  • Elizabeth Open Source Journey
  • Future of PHP Ecosystem
  • Listener Elephant Question
  • Ecosystem Security Hub
  • Advisory Board Limits
  • Modernizing Mailing Lists
  • Foundation Awareness Push
  • PHP Ambassadors Strategy
  • State of PHP Survey
  • Five Year Vision
  • Community Hour Podcast
  • php.net Design Refresh

Resources

Guests

Elizabeth Barron – thephp.foundation elizabethbarron

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi Tim Sharp – tea-sharp

MOTW Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

  • Brief description:
    • Have you ever wanted the images in your Drupal media library to be automatically given alt text, a rich description, and a set of tags, using AI? There’s a recipe for that.
  • Module name/project name:
  • Brief history
    • How old: created in Sep 2025 by Artem Dmitriiev (a.dmitriiev) of 1xINTERNET
    • Versions available: 1.1.1, which requires Drupal 11.2 or newer
  • Maintainership
    • Actively maintained, latest release and commit just two weeks ago
    • Security coverage
    • Number of open issues: 9 open issues, 4 of which are bugs
  • Usage stats:
    • No usage data reported
  • Module features and usage
    • This recipe applies core’s image media type recipe, then adds a description field and a tags field to image media, with tags in a new “Image Classification” vocabulary
    • Editors get a “Generate Alt Text” button right on the image field, using the Field Widget Actions module, with a prompt written like an accessibility expert: under 100 characters, no “image of”, flag logos and graphics
    • On save, a vision model writes a description of up to eight sentences: colours, photo versus illustration, people, mood, and key objects, using the media name for context
    • Tagging is chained off that description rather than the image itself, picking or creating up to five short, general terms, and reusing similar existing tags where it can
    • It also adds bulk actions to the media admin view, so you can run description and tagging across an existing library, not just new uploads
    • Description and tag filters are added to the media library, including the widget, so editors can search for “sunny summer day” right in the image picker
    • The stated bigger goal is making images discoverable by RAG and other AI search, so good descriptions become a foundation for future AI features. In fact, this recipe is a dependency for the Canvas AI Image Search recipe, which is still a work in progress
    • Under the hood, images get scaled to 400px wide and converted to PNG before they’re sent to the model, which keeps things faster and cheaper
    • One caveat: your site needs an AI provider with a default “chat with image vision” model, and the recipe checks for that when it’s applied
    • Also worth a look: the description prompt asks the model to describe people’s age, gender, and ethnicity, and even name them if it can, so you may want to review that prompt for your privacy policies, and adjust accordingly
    • Like any recipe, it provides a robust starting point for some compelling features, and every prompt and setting can be tweaked after you apply it
    • Lastly, I wanted to mention that in today’s Driesnote in here in Rotterdam, Dries demoed being able to use MCP to search images on his own site. A recipe like this could help you make sure the images in your media library have sufficient metadata to make that work reliably
Oct
01
2026
--

Tuning Percona ClusterSync for MongoDB Performance

Percona ClusterSync for MongoDB (PCSM) synchronizes data from a source MongoDB cluster (including Atlas) to a target MongoDB cluster in two stages. It first creates a consistent starting point and clones the existing collections and indexes. At the same time, it captures source changes through MongoDB change streams. Once the initial copy is complete, PCSM applies those changes to the target until the target catches up with the source. 

PCSM’s latest architectural changes introduce several new parameters to improve initial clone speed and continuous replication throughput. This post aims to equip you with some ideas to help tune PCSM for maximum performance.

As usual, tune gradually and monitor source and target CPU, disk, network usage, connection counts, and replication lag after each change. Use Percona Monitoring and Management (PMM) to help you identify any bottlenecks. Don’t forget to keep an eye on the same metrics for the host running PCSM as well. 

Initial Clone Phase

The Initial cloning phase is mainly affected by collection parallelism, read and insert workers, segment size, and read batch size. You configure all of this while starting the pcsm process. 

Collection Parallelism

Parameter: clone-num-parallel-collections

The default is 2, which is quite conservative. This controls how many collections are cloned at the same time.

Increase it when:

  • The source has many collections.
  • The source and target have spare CPU and disk capacity.

It could be a good idea to start with 4 parallel collections for each CPU core and test higher values as long as the target is not saturated. Excessive parallelism will increase disk contention and connection usage.

Read and Insert Workers

Parameters:

  • clone-num-read-workers
  • clone-num-insert-workers

Defaults are:

  • Read workers: max(NumCPU/4, 1)
  • Insert workers: NumCPU × 2

Read workers fetch documents from the source. Insert workers write batches to the target.

Increase the number of read workers when the source reads limit throughput. Increase insert workers when the target has available write capacity and insert queues are building up. Target indexes are maintained during clone inserts, so additional insert workers can increase write contention.

Do not increase both aggressively at the same time. If target CPU or disk latency increases without a corresponding increase in throughput, reduce insert concurrency.

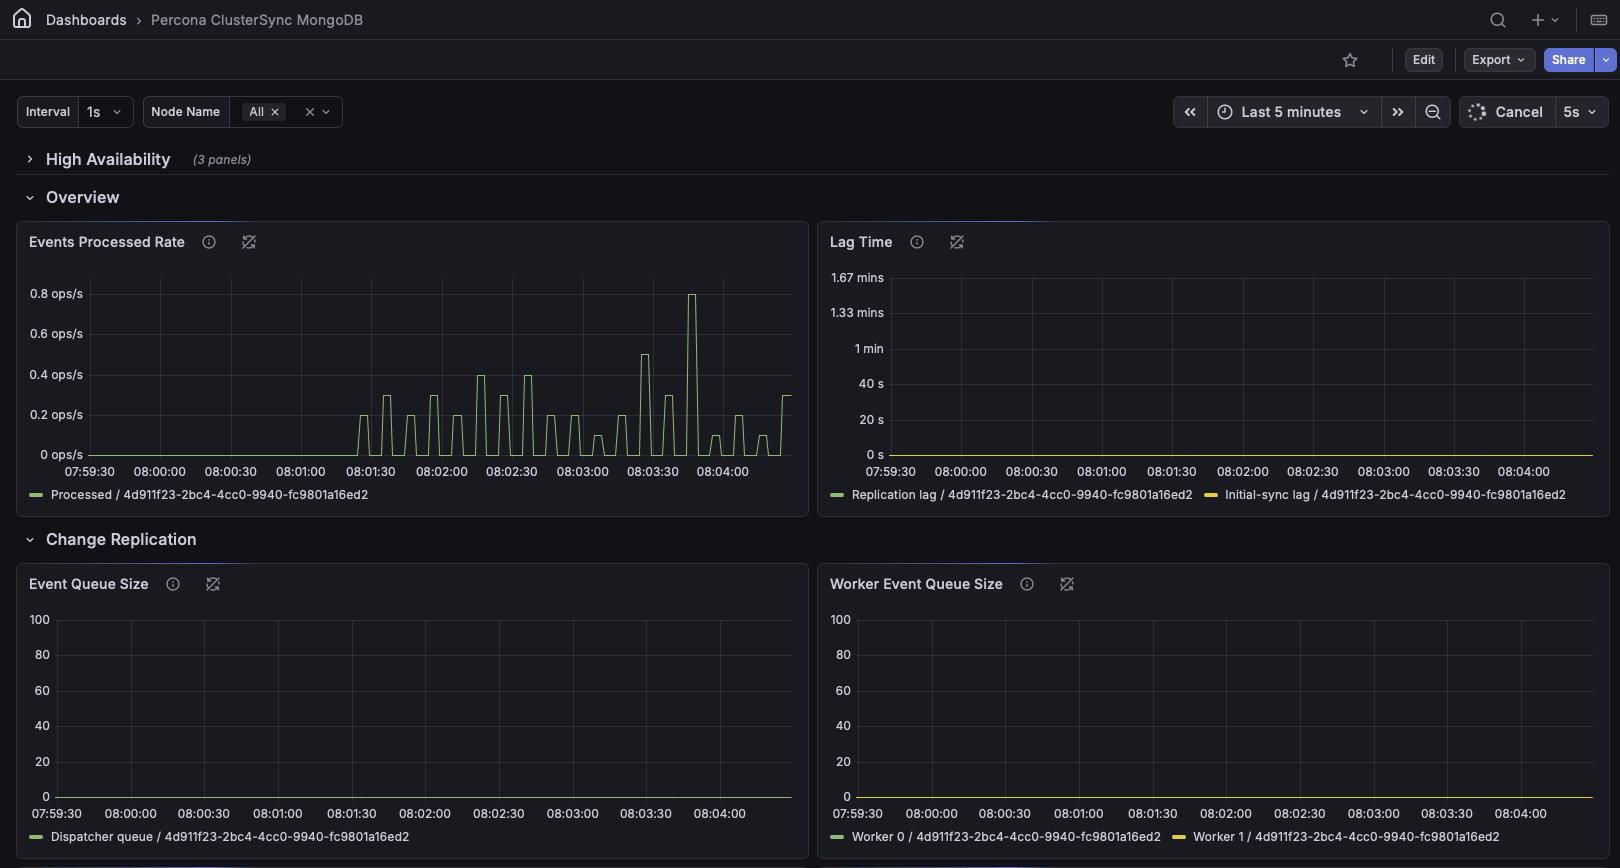
For continuous replication, PCSM does expose queue-depth metrics you can check in PMM:

percona_clustersync_mongodb_repl_event_queue_size 
percona_clustersync_mongodb_repl_worker_event_queue_size{worker="..."} 
percona_clustersync_mongodb_repl_worker_bulk_queue_size{worker="..."}

Continuous Replication Phase

Continuous replication is mainly affected by worker count, change-stream batch size, queue sizes, bulk size, flush interval, and bulk-write mode.

Replication Workers

Parameter: repl-num-workers

The default is the number of CPUs.

Increase this setting when worker queues grow and the target still has available CPU, storage, and connections. A useful test value is twice the number of CPUs.

More workers will not improve throughput for high contention workloads (e.g. operations targeting the same set of documents). Events for the same document remain processed in order on a single worker at a time.

Change-Stream Batch Size

Parameter: repl-change-stream-batch-size

The default is 10,000 events.

Larger values reduce change-stream round trips during sustained workloads. You may experiment with values such as 20,000 or 50,000.

Larger batches use more memory and may increase burst latency.

Event and Worker Queues

Parameters:

  • repl-event-queue-size
  • repl-worker-queue-size

Both default to 5,000 events.

These queues absorb temporary bursts between change-stream reading, event routing, and target writes.

Test values such as 10,000 or 25,000 when queues fill briefly during write stalls. Larger queues do not improve sustained throughput if the target is permanently slower than the source.

The worker queue is allocated per worker, so its memory impact increases with repl-num-workers.

Bulk Size and Flush Interval

Parameters:

  • repl-bulk-ops-size
  • repl-worker-flush-interval

The default bulk size is 5,000 operations. The default flush interval is 1 second.

For higher throughput, test:

  • repl-bulk-ops-size=10000
  • repl-worker-flush-interval=2s

Larger bulks reduce MongoDB command overhead but may increase replication latency.

For lower latency, use a shorter flush interval, such as 100ms to 500ms.

Actual bulks remain limited by MongoDB’s wire-message size. Large documents may reach the byte limit before reaching the configured operation count.

Asynchronous Bulk Queue

Parameter: repl-worker-bulk-queue-size

The default is 3. This controls how many completed bulks can wait behind an in-flight write.

Test values of 5 or 10 when target writes are slower than event processing. Increasing this value can keep workers busy, but it also increases memory usage and may allow replication lag to grow when the target cannot keep up.

Collection-Level Bulk Writes

Parameter: use-collection-bulk-write

Benchmark this option against the default (false).

By default, a single bulk written can contain operations for multiple databases and collections. Collection-level bulk writes=true groups operations by namespace instead, and may improve workloads spread across many collections.

PCSM may select collection-level writes automatically for target versions without client-level bulk-write support.

Connection Pools

PCSM supports the MongoDB URI option maxPoolSize. If it is omitted, the driver default is 100 connections per client.

Example:

mongodb://target-host/?maxPoolSize=300

Connection-pool sizing becomes important when increasing clone or replication workers.

Start with a moderate explicit value and increase it only when workers are waiting for connections. Avoid unlimited pools unless there is a specific reason to remove the limit.

Compression

PCSM supports separate compressor settings for source and target connections.

Parameters:

  • source-client-compressors
  • target-client-compressors

The default preference is:

snappy, zstd, zlib

PCSM matches the order the compressors are negotiated by MongoDB by default. Typically  snappy is used since it has lowest overhead but the compression is not as good as zstd or zlib. You may try the other compressors if optimizing for least possible network bandwidth usage.

Recommended Tuning Order 

Now that we know the most important parameters, it makes sense to run some tests and keep iterating to find the optimal values. 

The recommended workflow is:

  1. Establish a baseline using the default settings.
  2. Set an appropriate maxPoolSize on the source and target URIs.
  3. Find the ideal clone collection parallelism.
  4. Play with clone read and insert workers independently.
  5. Tune the replication worker count. 

In the end, the fastest configuration is the one that keeps PCSM and MongoDB busy without saturating storage, CPU, memory, or connections on either source or target. 

The post Tuning Percona ClusterSync for MongoDB Performance appeared first on Percona.
Sep
30
2026
--

Percona ClusterSync for MongoDB Goes Highly Available: Active-Standby Failover

Editor’s Note: This article was originally authored by Inel Pandzic.

Migrating data between MongoDB clusters is rarely a five-minute job. A large initial clone followed by days of change-stream replication is normal, and for all that time, Percona ClusterSync for MongoDB (PCSM) is a critical piece of your infrastructure. Until now, it was also a single point of failure: if the host, container, or pod running PCSM crashed, replication stopped dead. Nobody took over. An operator had to notice the outage and manually recover the process before synchronization could resume.
That changes with PCSM 1.0.0, which introduces built-in active-standby high availability for the replication phase.

What’s new

You can now run multiple PCSM instances pointed at the same source and target clusters. They coordinate through a MongoDB-backed lease stored on the target cluster: exactly one instance holds the lease and is ACTIVE — it runs replication. The rest stay STANDBY and take over automatically when the lease expires. No external coordinator— the target MongoDB cluster you already have is the source of truth.
Best of all, HA is always on and requires zero configuration changes. A single instance simply wins the lease immediately and behaves exactly as before. If you want failover, just start a second (or third) instance with the same source and target, and you’re done.

How it works

Three mechanisms make failover safe: lease-based election, term fencing, and checkpoint-based recovery.

Lease election without split-brain

All coordination state lives in the percona_clustersync_mongodb database on the target. Election is a single atomic conditional write: an instance claims the lease only if the current one has expired, and expiry is evaluated against the server clock. Two racing standbys cannot both win, and clock skew between PCSM hosts is irrelevant — MongoDB’s clock is the only one that matters.
The lease itself is one small document – percona_clustersync_mongodb.lease:

{
    "_id": "lease",
    "term": 7,
    "instanceId": "b3f1c2a4-9d7e-4c11-8a2f-1e6b0d5c9a77",
    "electionDate": { "$date": "2026-07-17T09:14:02.190Z" },
    "expiresAt": { "$date": "2026-07-17T09:20:41.882Z" }
}

Term-based fencing: no zombie writes

The term field a monotonic fencing token that increments on every election (every ACTIVE->STANDBY change), and it’s stamped into every checkpoint (percona_clustersync_mongodb.checkpoints) write the ACTIVE makes. Consider the classic distributed-systems nightmare: an ACTIVE stalls (GC pause, network partition, pod killed and instance restarted before the lease expired), its lease expires, a standby is promoted — and then the old instance wakes up and keeps writing as if nothing happened. With term fencing, that “zombie” active’s checkpoint writes carry a stale term. The target rejects them, the deposed instance notices, and it self-demotes to STANDBY. The new ACTIVE’s state is never corrupted.

The failover path – Checkpoint-based Recovery

On promotion, the new ACTIVE resumes replication from the persisted checkpoint — the same crash-recovery mechanism PCSM has always used, now triggered automatically. Timings are fixed in this release: the lease TTL is 10 seconds, the ACTIVE renews every 3 seconds, and each instance heartbeats every 3 seconds. In practice, a hard-killed ACTIVE is replaced within roughly the lease TTL.

Failover during the initial clone

One boundary to know: HA covers the change-stream replication phase. The initial clone currently is not resumable. If the ACTIVE dies mid-clone, a standby is still promoted, detects the interrupted clone during recovery, and fails cleanly with an explicit reason surfaced in both the logs and /status:   initial clone interrupted by failover and is not resumable; start a new run to re-clone from scratch   Recovery is a plain /start on the new ACTIVE, which restarts the sync from scratch. Automatic failover kicks in once the clone completes and continuous replication begins.

Operating an HA deployment

Each instance maintains a liveness document (percona_clustersync_mongodb.members) on the target, and API responses include a cluster envelope so an operator hitting any node can see who is ACTIVE: me (the instance you reached), role, and the full member list with every live instance’s host, port, and role. If you send an operational command (/start, /pause, /finalize, …) to a STANDBY, it responds with HTTP 409 and error: "not_active" — with the same envelope in the body, so your client can immediately locate the ACTIVE and retry there:

HTTP/1.1 409 Conflict

{
    "ok": false,
    "error": "not_active",
    "me": { "instanceId": "6a2d8e10-4b3c-4f97-9c0a-2f7e1b4d6c88" },
    "role": "STANDBY",
    "group": {
        "term": 7,
        "members": [
            {
                "instanceId": "b3f1c2a4-9d7e-4c11-8a2f-1e6b0d5c9a77",
                "host": "pcsm0",
                "port": 2242,
                "role": "ACTIVE"
            },
            {
                "instanceId": "6a2d8e10-4b3c-4f97-9c0a-2f7e1b4d6c88",
                "host": "pcsm1",
                "port": 2243,
                "role": "STANDBY"
            }
        ]
    }
}

No guessing, no stale DNS tricks.
Two operational notes:

  • The envelope appears only when more than one live member is observed. A lone instance returns responses byte-identical to the pre-HA API, so existing tooling keeps working unchanged. Treat the envelope as optional.
  • /metrics (and pprof) are served on every role.

For cleanup, two new direct commands clear HA state on the target while no server is running: pcsm reset members and pcsm reset lease.

Observability: watching a failover happen

Each instance exports HA metrics on /metrics, on every role:

  • percona_clustersync_mongodb_ha_active — gauge; 1 = ACTIVE, 0 = STANDBY
  • percona_clustersync_mongodb_ha_term — gauge; current lease term
  • percona_clustersync_mongodb_ha_role_transitions_total — counter; role changes on this instance

With these few metrics you can build a dashboard that tells the whole HA story at a glance: a state timeline of ha_active per instance doubles as the deployment roster and shows who is ACTIVE and since when, ha_term shows the current fencing term, and the rate of ha_role_transitions_total per instance works as a flap detector (0 means stable; a climbing number means trouble). We ship exactly such a board with the project — grab the Grafana dashboard JSON from the repo and use it as a starter for your own monitoring.

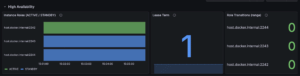
Here is a healthy three-instance deployment: one ACTIVE, two STANDBYs, term 1, no transitions.

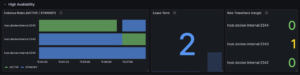
And the same deployment right after the ACTIVE was killed: the instance on port 2243 took over, the lease term incremented to 2, and its transition counter recorded the promotion. The old ACTIVE rejoined as a STANDBY.

One glance at the timeline tells you the full failover story — who held the lease, when it changed hands, and whether the deployment has been stable since.

Getting started

Upgrade note: replication state from 0.9.0 is not compatible with 1.0.0. Run pcsm reset against the target before starting replication with the new version.
Then simply start more than one instance:

pcsm --source "mongodb://src-mongos:27017" \
--target "mongodb://tgt-mongos:27017"

Run the same command on a second host, check /status on either one, and you’ll see one ACTIVE and one STANDBY. Kill the ACTIVE and watch the standby pick up replication from the last checkpoint within seconds.

Join the Community

Percona thrives on community collaboration. As we continue to refine PCSM and celebrate its production-ready GA release, we invite you to get involved. We welcome bug reports, feature suggestions, and code contributions. Your input helps us build the tools the MongoDB community actually needs. We encourage you to deploy PCSM in your production environments today! Check out the PCSM repository and join the journey with us!

Ready to break free from vendor lock-in? Check out the PCSM Documentation to get started with your first sync today.

The post Percona ClusterSync for MongoDB Goes Highly Available: Active-Standby Failover appeared first on Percona.
Sep
29
2026
--

Valkey Memory Optimization, Version by Version and Encoding: How Many Bytes Did Each Release Actually Save?

Introduction

This RAM/Memory reduction is most useful for Valkey 9.1 environments that are key string heavy. They are used extensively in caching, sessions/authentication, real-time apps, ecomm, Ad tech/martech, and gaming.
These scenarios see a reduction of 37.5%, which has been attained in our testing environments versus version 7.2.. The biggest jump in the reduction came between 7.2 and 8.1 where the difference was 29.8%. Although the reduction doesn’t apply to every Valkey environment, those that are string heavy should experience 37.5% RAM reductions.

RAM usage scenario:

Starting point: 1 TB on Valkey 7.2

  • Valkey 7.2: 1,000 GB
  • Valkey 8.0: ~800 GB
  • Valkey 8.1: ~640 GB
  • Valkey 9.1: ~630 GB

This post is based on a rigorous benchmark and a structural teardown of the source, aimed at answering three questions:

    1. For the same data, how much memory does each version actually save?
    2. Where exactly does that saving come from at the data-structure level?
    3. How do different data structures and encoding result in significantly different memory footprints?


1. Test Setup: 

Five versions were tested — 7.2.14, 8.0.10, 8.1.9, 9.0.5, and 9.1.1 — all built from source, all using jemalloc 5.3.0 as the allocator, so version is the only variable.

Test Environment settings:

  • Standalone mode, not cluster, to rule out cluster-level overhead
  • –maxmemory 0, –save “” –appendonly no, to keep persistence and eviction out of the picture
  • valkey-benchmark -t set -n 1000000 -r 1000000 -d 16: one million SETs, 16-byte values
  • Both -n and -r are set to 1,000,000 on purpose — this causes random-key collisions, so only about 63.2% (~632K) land as unique keys. This matches the official Valkey benchmark methodology exactly
  • The baseline (empty instance) memory is subtracted for each version, giving the true marginal bytes per key


2. Results: Memory per Key, Version by Version

Version Unique Keys used_memory Bytes / Key vs Prev vs 7.2.14
7.2.14 632,181 61.78 MB 102.48 B — baseline
8.0.10 632,565 57.00 MB 94.49 B ?7.8% ?7.8%
8.1.9 632,573 43.43 MB 71.98 B ?23.8% ?29.8%
9.0.5 631,672 43.36 MB 71.99 B +0.0% ?29.8%
9.1.1 631,985 38.58 MB 64.02 B ?11.1% ?37.5%

We can see that across roughly 632K unique keys, the size of per key averages 102.48 bytes in version 7.2.14 down to 64.02 bytes in 9.1.1 — a cumulative drop of 37.5%. In other words, the same hardware stores roughly 60% more of these small keys on 9.1 than it did on 7.2. We can see 8.1 alone accounts for the single biggest jump, at -23.8%, because that’s where the hash table got rewritten. However 9.0 shows basically zero change, since that release simply wasn’t targeting memory.


3. Let us see how the change happens version by version.

7.2 ? 8.0: Embedding the Key into dictEntry

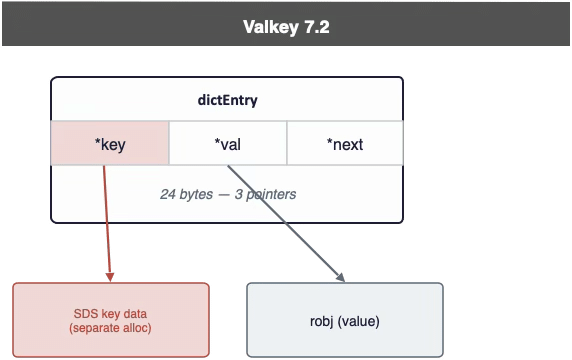
Valkey 7.2 dictEntry diagram: a 24-byte struct of three pointers (*key, *val, *next), with *key pointing to separately allocated SDS key data and *val pointing to the robj value


In 7.2, dictEntry is a classic three-pointer struct — *key, *val, *next — 24 bytes total. The catch is that the key itself is a pointer to a separately allocated SDS blob: every lookup pays for an extra malloc and an extra memory hop just to read the key.


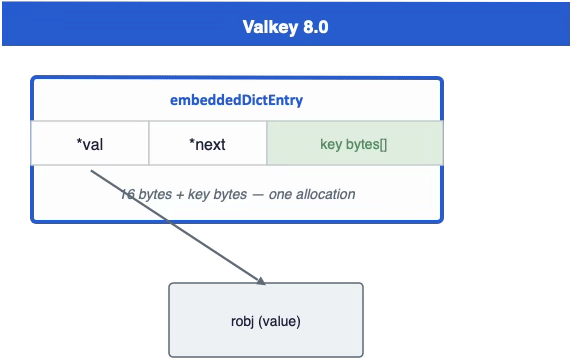
Valkey 8.0 embeddedDictEntry diagram: *val and *next pointers with the key bytes stored inline in one allocation (16 bytes plus key bytes), pointing to the robj value


8.0 introduces embeddedDictEntry: the key’s bytes are stored inline right after the struct. *val, *next, plus the inlined key data come to 16 bytes plus the key length — one allocation instead of two.

Result: ?8 bytes per key, one fewer memory hop on every lookup, automatic on upgrade, no config changes needed.

8.0 ? 8.1: A Cache-Line-Sized Hash Table

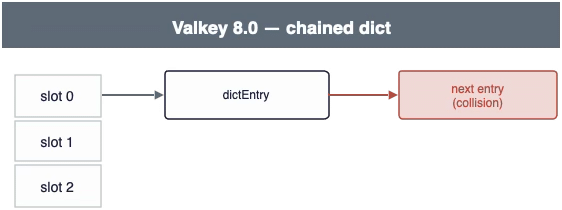
This is the single largest jump in the whole series. In 8.0, the dictionary is a classic chained hash table: reaching a value means “bucket ? entry ? key ? value” — four memory hops (plus two more per hash collision).


Valkey 8.0 chained dict diagram: hash table slots pointing to dictEntry structs, with collisions chained to the next entry


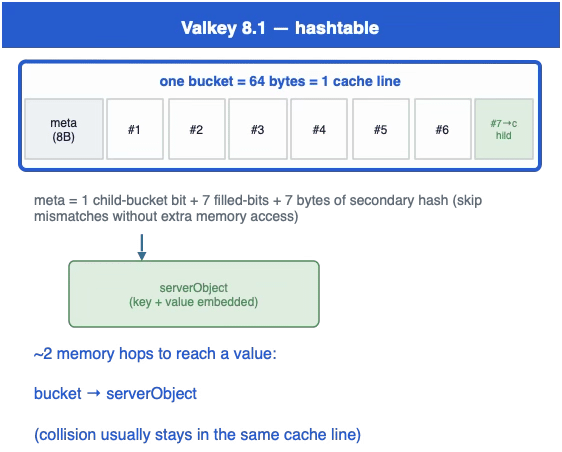
8.1 rewrites this as a new hashtable structure where one bucket is exactly 64 bytes — the size of a CPU cache line, — with the key and value embedded directly inside it.The bucket’s 8-byte metadata region packs a “has-child-bucket” bit, 7 filled-bits, and 7 bytes of secondary hash, letting most non-matching candidates be skipped without an extra memory access. Key and value are embedded in the same serverObject, shortening the path to roughly two hops — “bucket ? serverObject” — and a hash collision usually stays within the same cache line.

dictEntry as a struct disappears entirely. The result is roughly ?20 bytes per key-value pair (?30 bytes for keys with a TTL) — the single biggest jump in the entire 7.2?9.1 series.


Valkey 8.1 hashtable diagram: one 64-byte cache-line bucket with an 8-byte metadata region and seven entry slots, pointing to a serverObject with the key and value embedded, about two memory hops per lookup

9.0 ? 9.1: Reusing the Pointer Field Itself


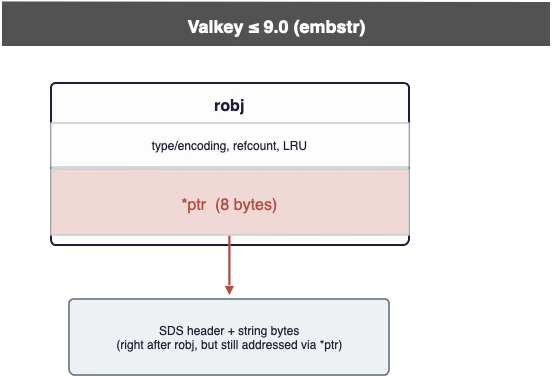
Valkey 9.0 and earlier embstr diagram: robj header (type/encoding, refcount, LRU) with an 8-byte *ptr field pointing to the SDS header and string bytes placed right after the robj

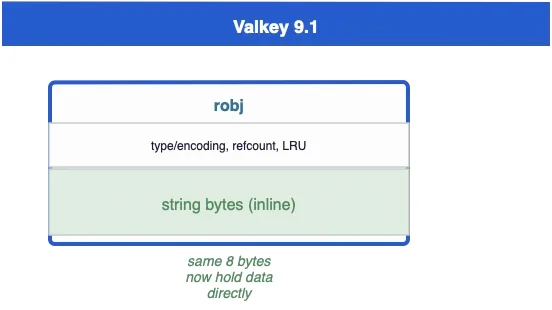
Valkey 9.1 robj diagram: the same 8 bytes previously used for *ptr now hold short string bytes inline, removing the pointer

In earlier versions, embedded strings (embstr) still wasted an 8-byte pointer field simply referencing the contiguous payload. 9.1’s fix: for short strings, the string bytes are stored directly inline in those same 8 bytes normally used for the pointer — no pointer needed, and no separate allocation for the value.

Result: up to a 20% memory reduction for strings under 128 bytes — and the benchmark’s “key + 16-byte value” pairs sit right in the middle of that range.

The three structural changes account for most of the improvement: 

8.0 inlined the key directly into dictEntry, eliminating a separate allocation and one memory hop (?8 bytes/key);    8.1 rewrote the dictionary into a 64-byte, cache-line-aligned hashtable that embeds both key and value, collapsing the lookup path from four hops to about two and removing dictEntry altogether (roughly ?20 to ?30 bytes per entry);   and 9.1 reused the embedded-string pointer field to store short string data inline instead of pointing to it, cutting up to 20% off strings under 128 bytes. 

Together, these changes show that Valkey’s memory efficiency gains came from targeted, low-level restructuring of core data structures rather than a single sweeping rewrite.


4. Same 1 Million Records, Two Encodings, 54% Less Memory

Two approaches to the same data:

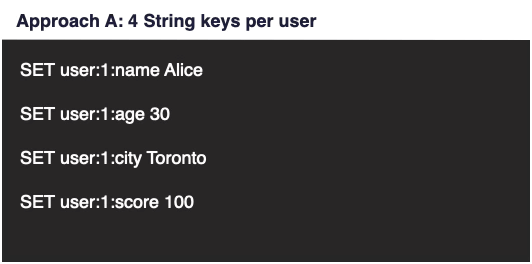
  • Approach A: 4 separate String keys per user (SET user:1:name Alice, etc.)
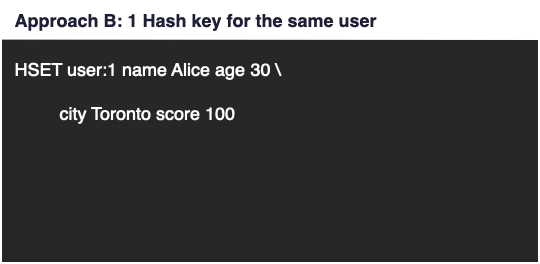
  • Approach B: 1 Hash key per user, 4 fields (HSET user:1 name Alice age 30 city Toronto score 100)

Approach A: four separate Valkey String keys per user using SET user:1:name Alice, SET user:1:age 30, SET user:1:city Toronto, SET user:1:score 100

Approach B: one Valkey Hash key per user using HSET user:1 name Alice age 30 city Toronto score 100


Same data, same record count. Approach A uses 220 MB; Approach B uses 100 MB — a 54% reduction. That gap comes from the fact that every key pays a fixed per-key overhead: four keys pay it four times, one key pays it once.

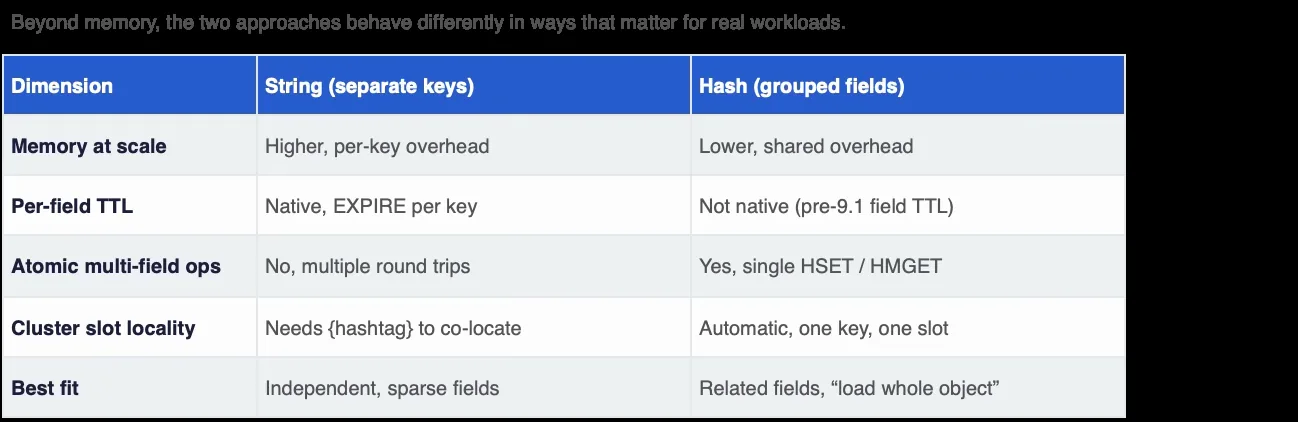
Beyond raw memory — where Hash wins because it shares per-key overhead, there’s per-field TTL, where String is native with EXPIRE per key, while Hash didn’t natively support field-level TTL before 7.4. 

For atomic multi-field operations, Hash wins with a single HSET or HMGET, while String needs multiple round trips. 

For cluster slot locality, String needs a manual {hashtag} to co-locate related keys, while a Hash is automatically one key, one slot. 

So there’s no universally correct choice — it’s memory versus flexibility, and it interacts with your cluster routing strategy too.


Comparison table of Valkey String (separate keys) versus Hash (grouped fields) across memory at scale, per-field TTL, atomic multi-field operations, cluster slot locality and best fit

Summary

Testing five Valkey versions (7.2.14 through 9.1.1) under identical conditions, per-key memory for a simple SET workload dropped from 102.48 bytes to 64.02 bytes — a cumulative 37.5% reduction, with 8.1 alone responsible for the largest single jump (?23.8%) and 9.0 showing essentially no change. Three targeted structural rewrites drove this: 8.0 inlined the key into dictEntry, removing a separate allocation (?8 bytes/key); 8.1 replaced the chained hash table with a 64-byte, cache-line-aligned hashtable that embeds key and value together, cutting the lookup path from four hops to two and eliminating dictEntry entirely (?20 to ?30 bytes/entry); and 9.1 reused the embedded-string pointer field to store short string data inline, saving up to 20% for strings under 128 bytes. Separately, how the same data is modeled also matters as much as the version: storing a user’s data as 4 individual String keys costs 220 MB, versus 100 MB for the same fields grouped into a single Hash — a 54% saving driven by paying the fixed per-key overhead once instead of four times. That memory advantage comes with trade-offs, though: Hash lags String on native per-field TTL support (pre-7.4) but wins on atomic multi-field operations and automatic cluster slot locality, so the right choice depends on whether memory efficiency or per-field flexibility matters more for the use case.


The post Valkey Memory Optimization, Version by Version and Encoding: How Many Bytes Did Each Release Actually Save? appeared first on Percona.
Sep
28
2026
--

PgQ and PgQue: Workflow Engines you might need in PostgreSQL

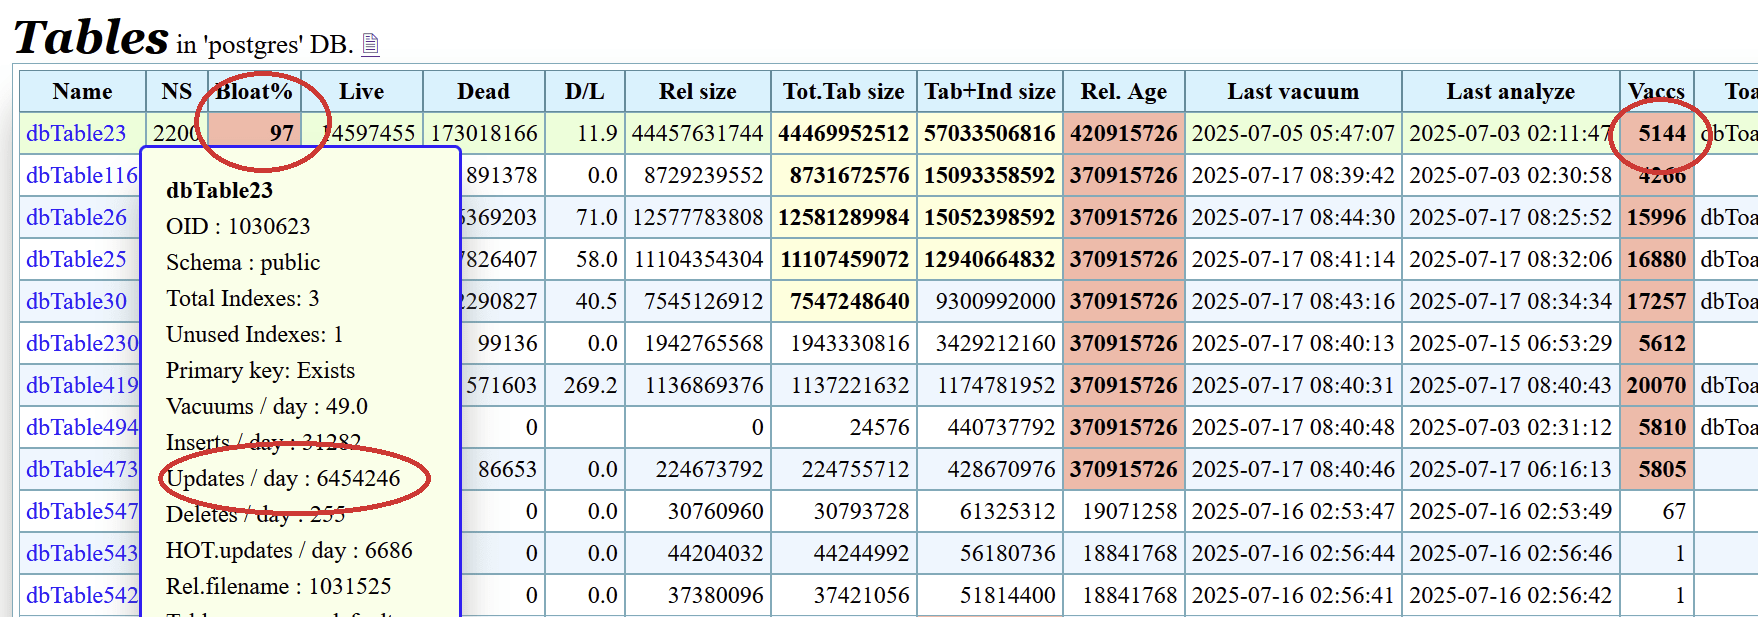
In many real production databases, we often see some tables receiving high-frequency updates (millions per day) and autovacuum running repeatedly (hundreds of times per day). Additionally, those tables can sometimes become heavily bloated. The end effect is poor performance, poor concurrency, and an unmanageable database.

In case we are using methods pg_gather for diagnosis, such anomalies are easy to spot by clicking on the table header to sort.

Very often, a closer look at these tables reveals that status-update workloads are driving these heavy updates. Many times, even the table names reveal their purpose through words like “task”, “queue”, or “bucket”. A discussion with application architects often reveals that these tables are used for specific workflows, with status fields tracking what is completed and what remains pending for further processing. There can also be multiple workflow stages. Sounds like use case for Kafka, right? Yes, Kafka is widely used to manage such workflows.

While this is happening on the database side, the buzz around “Just use PostgreSQL” is becoming increasingly popular. System designers and architects want to reduce the complexity of maintaining multiple components and dealing with operational issues. More complexity implies more potential failures. Recently, Chandan Shukla wrote a blog post titled PostgreSQL as a Workflow Engine: Building Reliable Long-Running AI Jobs Without Kafka, detailing trade-offs and considerations for building a simple yet reliable workflow engine using simple methods.

Yet, critical questions remain:

  1. Is there a better way to architect database workflows in PostgreSQL?
  2. Can we build a highly scalable system without the performance degradation caused by frequent updates and table bloat?
  3. Is it possible to eliminate the complexity of external components like Kafka in favor of a purely PostgreSQL-centric workflow engine?

Yes, we can. Furthermore, when building modern enterprise applications where data arrives as events that trigger subsequent workflows, I strongly recommend modeling the architecture around those events from the very beginning. . This concept is not new in the PostgreSQL ecosystem, However it is important to periodically highlight wonderful community tools, especially since PostgreSQL projects lack a centralized marketing framework. The original PgQ was created by Marko Kreen as part of Skytools. Largely forgotten for over 20 years—perhaps due to limited documentation—it was brought back into the spotlight by community members like Alexander Kukushkin through talks at various PostgreSQL conferences, such as PostgreSQL queues done right with PgQ – POSETTE 2026.

Later, Nikolay Samokhvalov took on the effort to refresh the framework by modernizing the codebase as PgQue, providing better documentation, and delivering informative talks. PgQue does not require any binary extensions to be installed or added to the system.

Why this implementation is different

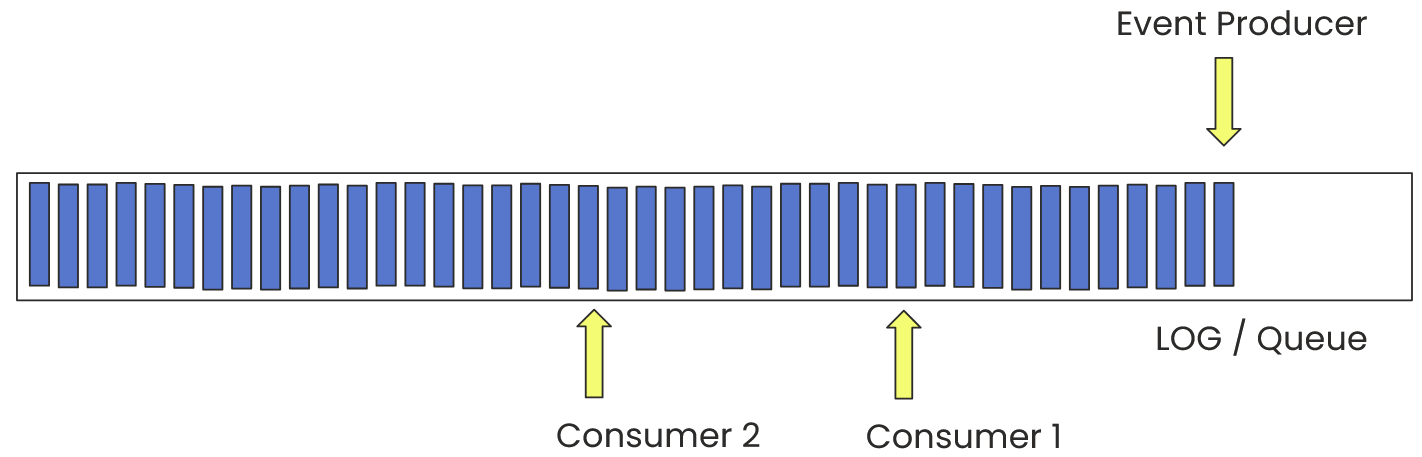
A generic queue implementation in PostgreSQL using native SQL features like FOR UPDATE SKIP LOCKED can lead to massive table bloat, concurrency bottlenecks, and performance degradation over a time. In contrast, a queue implementation leveraging PostgreSQL-specific features—such as storing snapshot information and identifying transactions completed between two snapshots—avoids these pitfalls entirely. Instead of updating event status flags in place, events are simply inserted into an append-only log (a partitioned table). This approach transfers the responsibility of tracking the position  of consumption to the consumer, which is far cheaper to maintain and resolves the issues mentioned above. No more updates, bloat, or concurrency issues on the queue log! An additional advantage of this approach is that there can be multiple consumers working on the same event log/Queue.

PgQue provides all above mentioned advantages as a ready to use framework, such that noone need to spend time in reinventing all those good learnings and intricacies of PostgreSQL snapshots.

Despite the name, PgQue is not a queue in the usual sense: events are not removed when consumed. Ack simply advances that consumer’s cursor. The model is a shared, append-only log — closer to a Kafka topic, and closest of all to Pulsar, whose subscription model is almost the same. Every registered consumer keeps its own position over the same events and independently sees all of them; the events are stored once, with no copy per subscriber.

Two things Kafka has, PgQue does not. There are no partitions — so no per-key ordering guarantee. And the cursor is not an offset: it points at a tick (a time slice), not at a message, so a consumer commits “through tick 900”, never “through event 4712”. Retention differs too — space is reclaimed by rotating and truncating tables, but only once the slowest consumer has moved past them. The guaranteed rewind window is one rotation period 2 hours by default, and a stalled consumer blocks reclamation rather than losing data. But the PgQue offers queue semantics Kafka leaves to the application: per-consumer redelivery – a failed event is re-appended as a private copy visible only to the consumer that “nack”ed it, a built-in dead-letter queue (DLQ), and competing consumers via the cooperative-consumer API — Pulsar’s Shared subscription, and marked experimental as of writing this blog.

Events are batched, which means that a single fetch request by a consumer can return a list of events in a batch. This significantly reduces back-and-forth network interactions with the server. Once the consumer finishes processing those events, it sends an acknowledgment to the server, which increments the pointer to the next batch. Yes, Please note that acknowledgement is per batch, not per message. So if the processing of a specific message fails, that message needs to be negatively acknowledged, before the batch is acknowledged.

Batch boundaries are marked by a ticker (a clock ticker), which ticks at scheduled intervals—such as every 1/10th of a second or every second. Only transactions completed between the previous batch and the current batch are visible to consumers.

What is new in PgQue

PgQ’s core mechanics—snapshot-based batching, tick generation, TRUNCATE-based table rotation, and per-consumer cursors—are carried over entirely rather than cherry-picked.

What PgQue changes is everything that previously made the engine difficult to deploy: C extensions, external daemons, overly permissive default roles, and the requirement for users to explicitly manage ticks.

pgque.ticker_loop() is a procedure, allowing it to commit between iterations. pg_cron triggers it once per second, and within that second, it ticks at the specified interval. The configuration parameter pgque.config.tick_period_ms sets this rate—100 ms by default, tunable to any exact divisor of 1000 ms.

Some of the main features include:

  1. LISTEN/NOTIFY on every tick: The ticker emits pg_notify(‘pgque_<queue>’, tick_id) after producing a tick, allowing consumers to wait on notifications rather than polling.
  2. Clear and separate roles: PgQue provides distinct security roles for producers and consumers via pgque_writer and pgque_reader, alongside an administrative role named pgque_admin.
  3. Send and receive APIs: Core APIs providing essential queue functionality, including send(), send_batch(), subscribe(), unsubscribe(), receive(), ack(), and nack().
  4. Dead-letter queue: After a sufficient number of failed retry attempts, messages can be moved to a dead-letter queue using dlq_inspect(), dlq_replay(), dlq_replay_all(), dlq_purge(), and event_dead().
  5. Idempotent producers: Deduplicates publishes by key so that retrying producers do not double-publish messages, using send_idem() and maint_idem().
  6. Cooperative consumers: Enables multiple workers to share a single logical consumer cursor, allowing fan-out and work-sharing on the same queue via register_subconsumer(), subscribe_subconsumer(), receive_coop(), and touch_subconsumer().
  7. Management control: Control queue state, scheduler registration, and configuration in a single operation via start(), stop(), status(), version(), set_tick_period_ms(), and uninstall().
  8. Observability: Provides queue and consumer statistics, health scoring, stuck-consumer detection, and an OpenTelemetry-compatible metrics view via queue_stats(), consumer_stats(), queue_health(), otel_metrics(), stuck_consumers(), throughput(), and error_rate().
  9. Delayed delivery: Schedule events for future execution, promoted into the queue when due via send_at() and maint_d

How to use PgQue in applications

An application client can use raw SQL APIs provided by PgQue or leverage official client libraries. As of writing this article, client libraries exist for Python, Go, TypeScript, and Ruby under the “client” directory of the repository. If you are using a programming language other than these four, the existing client libraries can serve as a reference implementation.

I am going to mention only how to use it. But if you are interested in how internally it works, I would recommend this blog and concepts

Producer

In case, you want to test producers and consumers from a psql commandline prompt, the necessary steps are covered with detailed explanations in the tutorial.

The producer simply needs to publish events to the queue using PL/pgSQL functions provided by the PgQue as follows:

select pgque.send('orders', '{"order_id": 43, "total": 10.00}'::jsonb);

where “orders” is the queue name and the JSONB string represents the message payload.

If this is an active queue, no additional steps are needed. However, on lower-activity queues (default 500 events since the last tick), you can manually trigger a tick using the
pgque.force_next_tick()  function as follows, because ticking is throttled to avoid wastages.

select pgque.force_next_tick('orders');

The background ticker will then assign this event to the next batch.

Consumer

On the consumer side, call the
pgque.receive()  function:

select * from pgque.receive('orders', 'processor', 100);

following is a sample output:

postgres=> select * from pgque.receive('orders', 'processor', 100);
msg_id | batch_id |     type      |     payload     | retry_count |          created_at           | extra1 | extra2 | extra3 | extra4
--------+----------+---------------+-----------------+-------------+-------------------------------+--------+--------+--------+--------
  2003 |        8 | order.created | {"order_id": 1} |             | 2026-09-04 14:08:57.472283-04 |        |        |        |
  2004 |        8 | order.created | {"order_id": 2} |             | 2026-09-04 14:08:57.472283-04 |        |        |        |
  2005 |        8 | order.created | {"order_id": 3} |             | 2026-09-04 14:08:57.472283-04 |        |        |        |
(3 rows)

In lower-activity queues, consumers may encounter empty batches (batches containing no events). Empty batches require no acknowledgment; calling receive() automatically completes them and advances the consumer cursor. Conversely, non-empty batches must be acknowledged via ack(); otherwise, subsequent calls will repeatedly return the same unacknowledged batch. The standard consumer processing loop follows this pattern:

receive batch ? if messages exist, process and acknowledge ? repeat.

following SQL snippet demonstrates this logic when testing from a
psql
 session:

do $$
  declare
    v_head  bigint;
    v_msgs  pgque.message[];
    m       pgque.message;
    v_prev  bigint;
    v_now   bigint;
    v_pass  int := 0;
  begin
    select last_tick_id into v_head from pgque.get_queue_info('orders');

    loop
      v_pass := v_pass + 1;
      select last_tick into v_prev
      from pgque.get_consumer_info('orders', 'processor');

      select coalesce(array_agg(r), '{}')
      into v_msgs
      from pgque.receive('orders', 'processor', 1000) as r;

      if array_length(v_msgs, 1) > 0 then
        foreach m in array v_msgs loop
          raise notice 'msg_id=% type=% payload=%', m.msg_id, m.type, m.payload;
        end loop;
        perform pgque.ack(v_msgs[1].batch_id);
        raise notice 'batch % acked, % messages, pass %',
                     v_msgs[1].batch_id, array_length(v_msgs, 1), v_pass;
        exit;                     -- drop this line to drain everything
      end if;

      commit;                     -- one batch per transaction

      select last_tick into v_now
      from pgque.get_consumer_info('orders', 'processor');

      exit when v_now >= v_head;  -- caught up to where we started
      exit when v_now = v_prev;   -- cursor stalled: no further tick
      exit when v_pass > 2000;    -- safety guard
    end loop;

    raise notice 'passes=% last_tick=%', v_pass, v_now;
  end $$

Now, consider a common scenario: a consumer receives a batch of events, but while some events process successfully, others fail. How should this be handled?

This is where negative acknowledgments (nack) apply. Any events that fail processing must be negative-acknowledged before acknowledging the entire batch. Here is an example statement to nack message ID 2004 within batch ID 8:

select pgque.nack(8, m, '30 seconds', 'downstream 503')
from pgque.receive('orders', 'processor', 100) as m
where m.msg_id = 2004;

Once all failed messages in a batch have been negative-acknowledged, the consumer can safely acknowledge the batch:

select pgque.ack(8);

Execution order is critical here because calling ack() advances the consumer cursor past the batch window. Negative-acknowledged messages are moved to a retry queue and re-enqueued into the main queue after the specified delay (30 seconds in this example).

If a consumer repeatedly fails to process an event, will it retry indefinitely? No. Similar to Kafka, PgQue implements a Dead Letter Queue (DLQ). Once the configured retry threshold is exceeded, the event moves to the DLQ. You can configure the maximum retry count using:

select pgque.set_queue_config('orders', 'max_retries', '2');

Summary

The zero-bloat behavior pioneered by PgQ has proven effective in production since 2007. PgQue inherits these benefits along with its core architectural strengths: snapshot-based batching, tick generation, TRUNCATE-based table rotation, and consumer cursor tracking. System performance, stability, and scalability heavily depend on solid design. PgQue offers a simple, well-architected framework to implement workflow management entirely inside PostgreSQL, eliminating the need for external tools like Kafka.

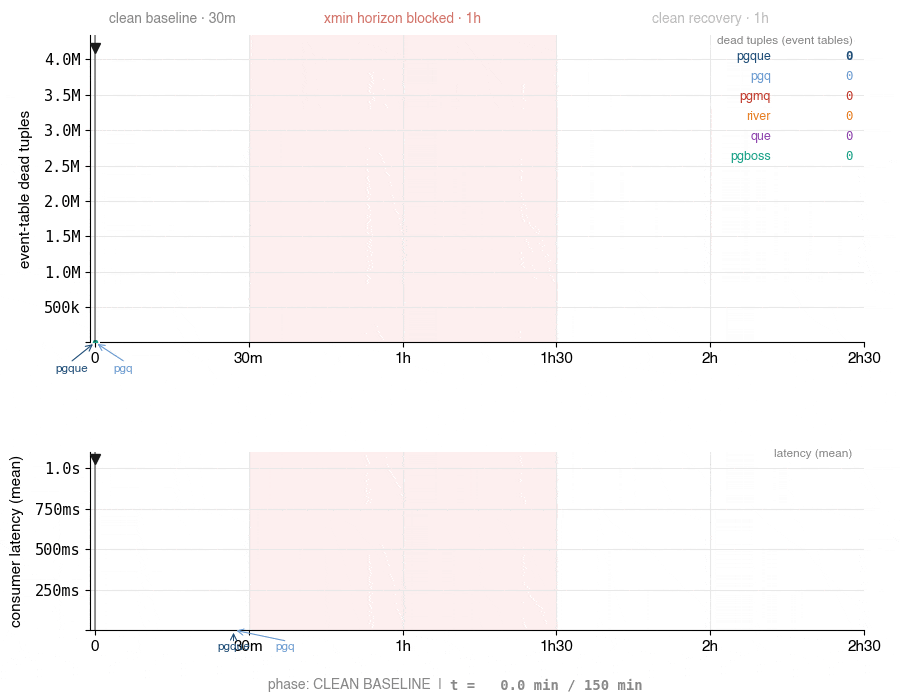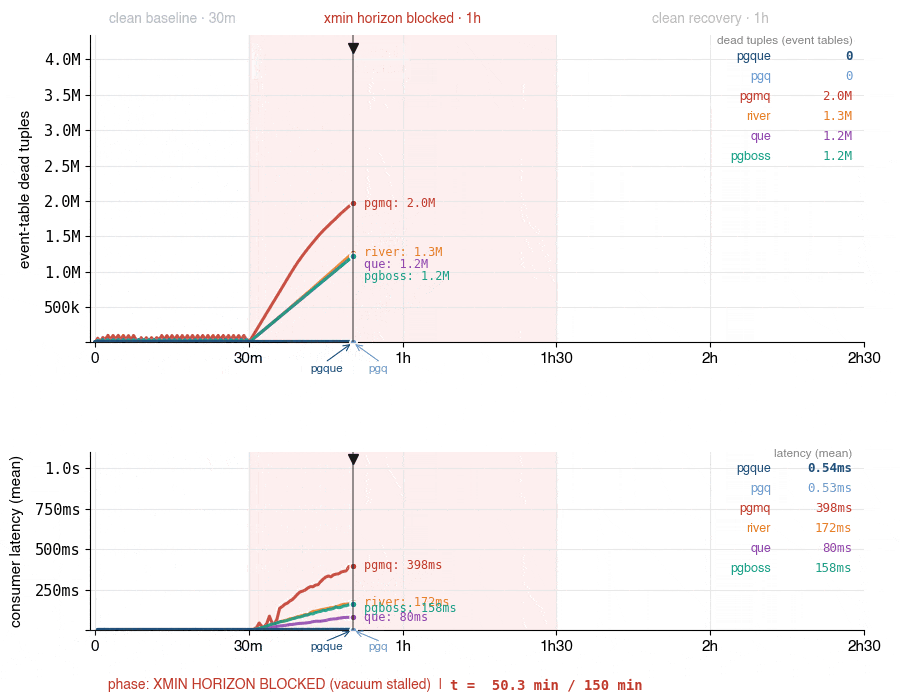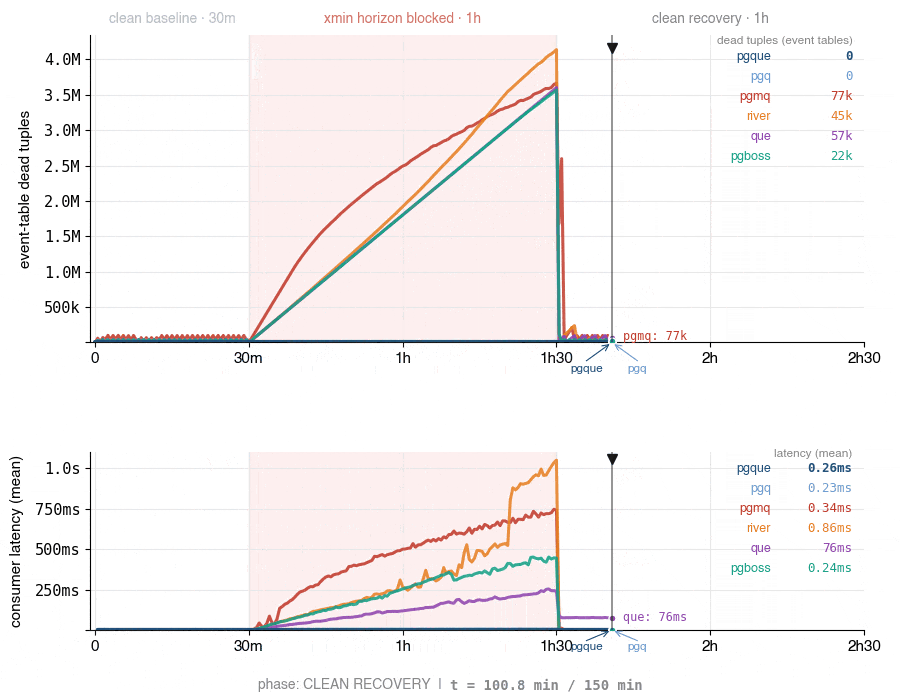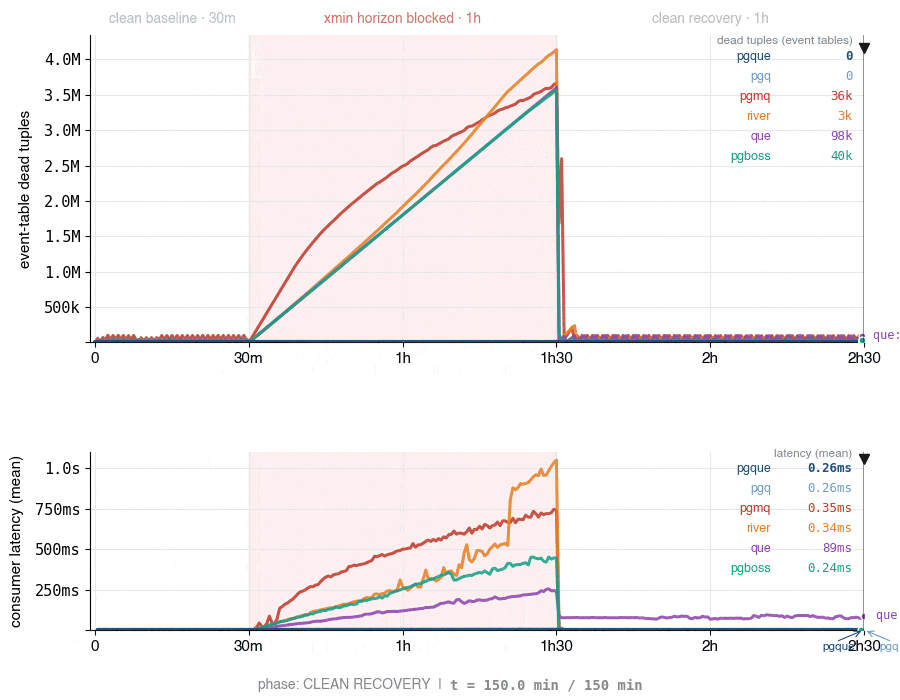
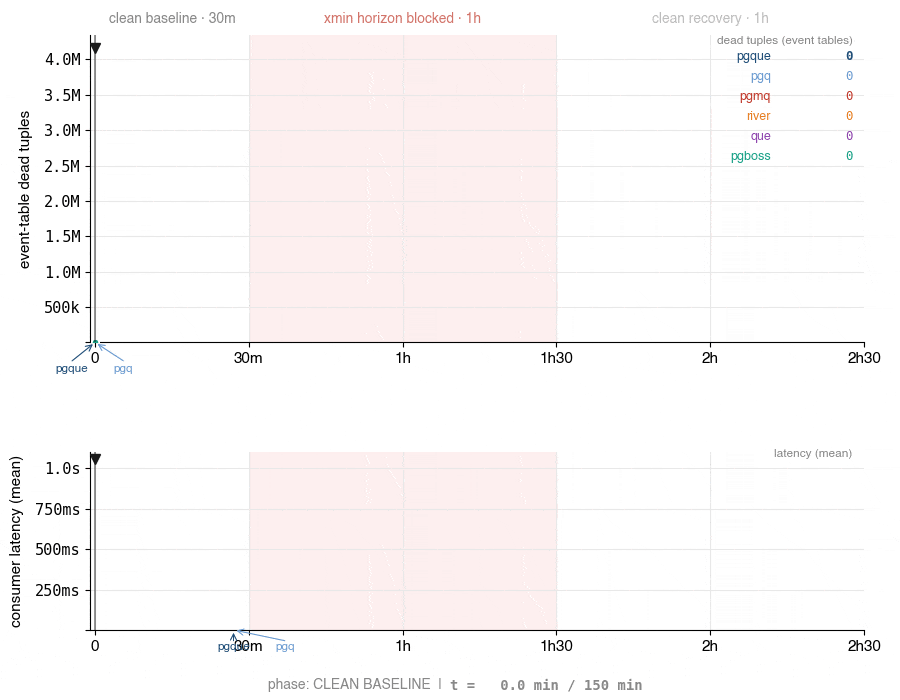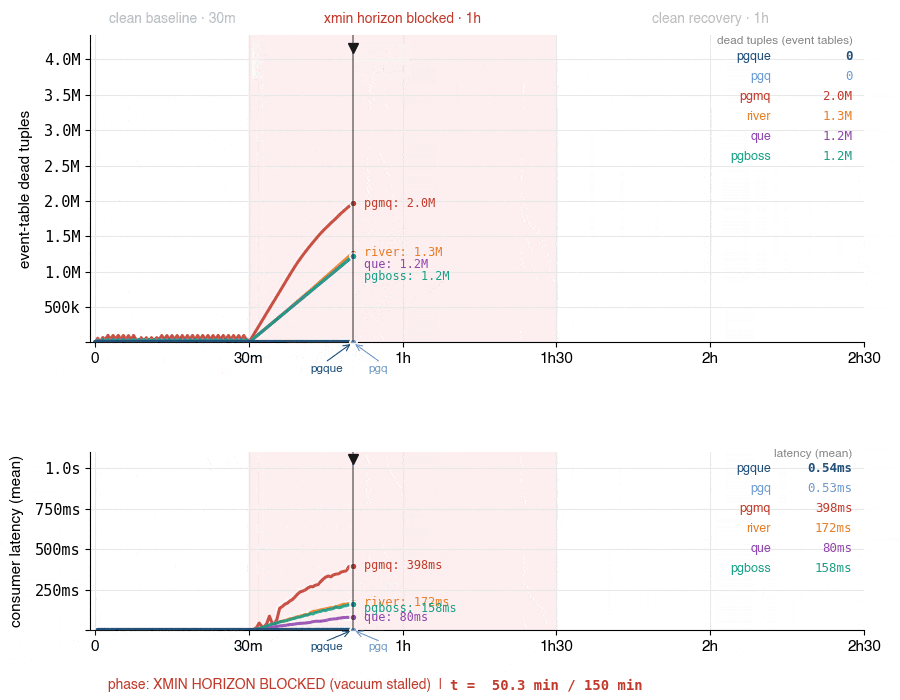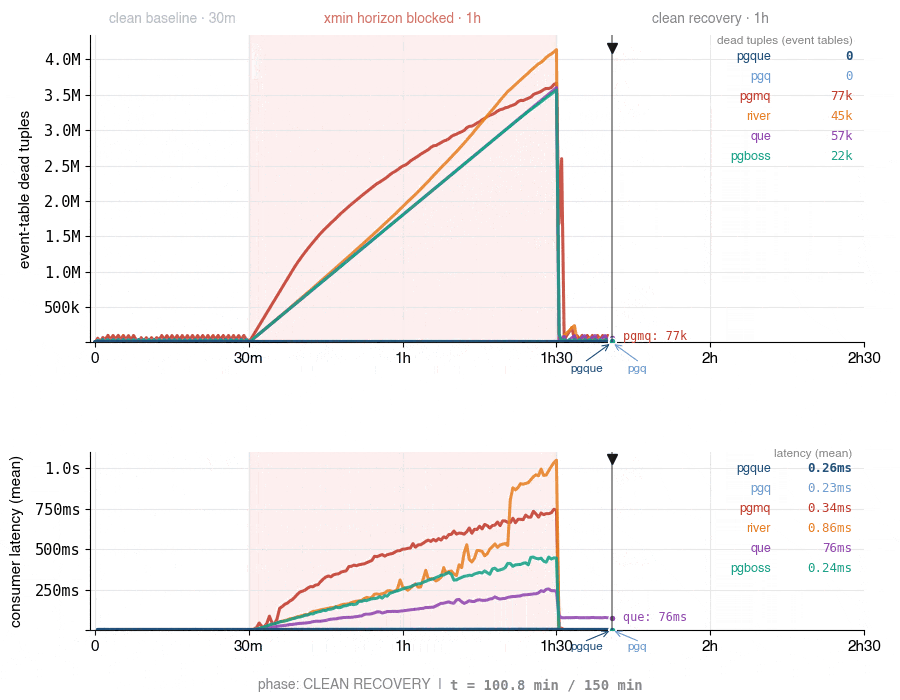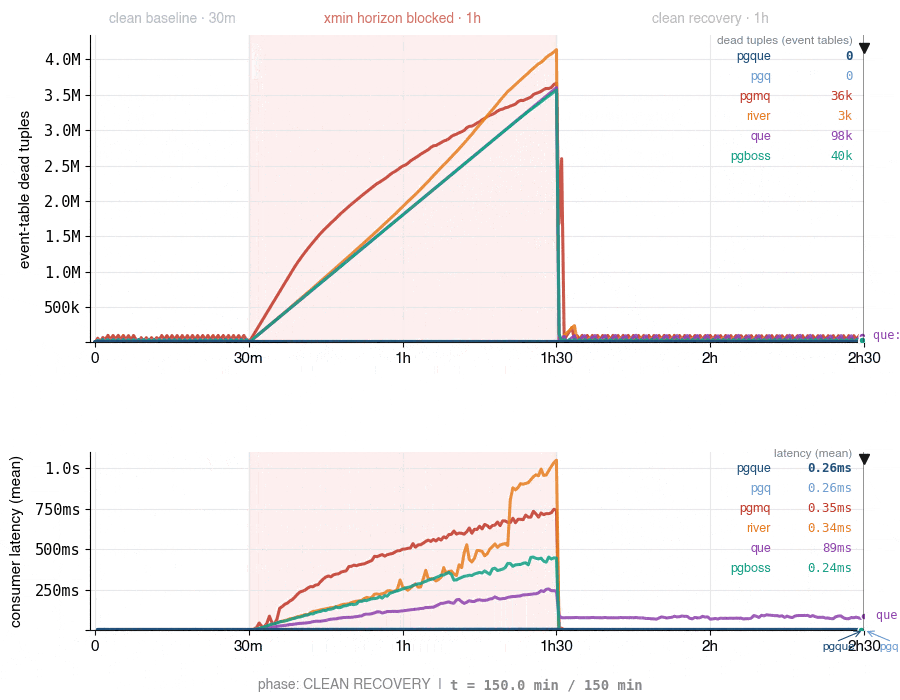
To see performance and efficiency comparisons with other approaches, check out https://pgque.dev/images/death_spiral.gif.

As shown in the graph, there are no spikes in the XID horizon or consumer latency. Metric lines for both PgQue and PgQ remain consistently low and near-flat during testing.

The post PgQ and PgQue: Workflow Engines you might need in PostgreSQL appeared first on Percona.
Written by in: Zend Developer |
Sep
28
2026
--

When pt-online-schema-change “where” Meets Galera: Understanding Chunk Auto-Resize and Flow Control

Percona Toolkit’s pt-online-schema-change (pt-osc) has long been the preferred solution for performing online schema changes with minimal downtime. Its chunk-based copy algorithm is designed to adapt dynamically to the workload, making it suitable for very large tables in production environments.

However, under specific conditions, one of its optimization mechanisms can become counterproductive.

During a customer engagement involving Percona XtraDB Cluster (PXC), we investigated a case where running pt-online-schema-change with a selective –where clause caused severe Galera Flow Control and general overhead, effectively stalling the cluster for an extended period. The issue was not caused by the schema change itself, but by the interaction between:

  • adaptive chunk auto-resizing
  • highly selective copying of the newest rows
  • clustered replication in Galera
  • InnoDB checkpointing

This article explains why it happens and proposes a set of practical mitigations that eliminate the root cause.


The Scenario

Consider a large table containing hundreds of millions of rows.

Instead of rebuilding the entire table, we only want to copy a subset of rows and apply a schema change like adding a new index.

The command looks similar to:

pt-online-schema-change \
--alter "ADD INDEX idx_status(status)" \
--where "created_at &gt;= NOW() - INTERVAL 30 DAY" \
D=test,t=events \
--execute --force

This is a common approach when:

  • historical data can be ignored
  • only active records require modification
  • performing staged migrations
  • reducing migration time

At first glance this seems perfectly reasonable.

Unfortunately, it exposes an interesting corner case in pt-online-schema-change.


How Chunk Auto-Resize Works

During the copy phase, pt-osc continuously adjusts the chunk size in order to keep each chunk copy close to the configured execution time (–chunk-time), 0.5 seconds by default.

Simplified, the algorithm works like this:

  • if chunks execute too quickly, increase the next chunk size
  • if chunks become slower, decrease the size
  • repeat until reaching a stable value

For ordinary table scans this works remarkably well because row density is relatively uniform.

The problem appears when most scanned rows are discarded by –where.


The Hidden Effect of a Selective WHERE Clause

Imagine a table like this with 1 billion rows:

Rows Match WHERE
990 million No
10 million Yes

Suppose the matching rows are located at the end of the clustered index — and that was exactly the case here. Keep in mind that chunk selection always relies on the Primary Key boundaries starting from minimum value, but in this case those boundaries were combined (AND) with the condition passed via –where. Since the created_at values increased in step with the Primary Key, all the matching rows ended up clustered at the end of the index.

For a long time pt-osc scans chunks where almost every row is rejected. The copy operation becomes extremely fast.

The adaptive algorithm interprets this as: “Chunks are too small.” It therefore keeps increasing the chunk size.

Eventually, when the scan reaches the first matching rows, the chunk size has already grown dramatically. Instead of copying a few thousand rows, pt-osc may suddenly copy hundreds of thousands—or even a million—of rows in a single transaction.

Nothing is technically wrong. But Galera now has a completely different problem.


Why Galera Suffers

Every copied chunk is replicated as a write set.

Very large transactions produce:

  • large write sets
  • long certification phases
  • increased apply queues
  • longer replication latency
  • Flow Control activation

Once Flow Control starts, cluster throughput decreases dramatically.

Application commits begin waiting.

In extreme situations the cluster appears almost frozen until the oversized transaction has been fully applied by every node.

Ironically, the adaptive algorithm—designed to optimize throughput—ends up creating exactly the workload pattern that Galera dislikes the most.

Why InnoDB Suffers too

As soon as the first large chunks began processing, the following messages appeared in the PXC writer node’s error log:

[Warning] [MY-014084] [InnoDB] Threads are unable to reserve space in redo log which can't be reclaimed 
due to the 'log_checkpointer' consumer still lagging behind at LSN = 852886039088. 
Consider increasing innodb_redo_log_capacity.

This indicates that InnoDB received a very large transaction, and the writing threads could not find enough free space in the redo logs because the log_checkpointer consumer was falling behind. In practice, this forces the server to trigger checkpoints more frequently and on a larger scale, which increases overall overhead.

After Galera Replication propagated the write set to the other nodes, the same type of message was observed on them as well, during the apply phase of the replicated transaction.

Symptoms

Typical symptoms include:

  • Flow Control percentage rapidly increasing
  • Growing wsrep_local_recv_queue
  • High replication lag between nodes
  • Application commits waiting
  • CPU utilization increasing
  • Large spikes in transaction apply time
  • More frequent InnoDB checkpoints on all the nodes

The schema change itself may still complete successfully, but the impact on production traffic can be severe. In the worst scenario this can lead to a complete stall of the cluster due to excessive flow control. This actually happened in production, and the cluster had to be restarted after remaining locked for dozens of minutes.


The Proposed Fixes

Here are a few options, starting with the simplest and most effective one: disable adaptive chunk resizing whenever a selective –where clause is used.

Instead of continuously increasing chunk sizes, keep them fixed throughout the operation.

Simply include the following options in the command:

--chunk-time = 0
--max-flow-ctl = 0

If –chunk-time option is set to zero, the chunk size doesn’t auto-adjust, so query times will vary, but query chunk sizes will not. Another way to do the same thing is to specify a value for –chunk-size explicitly, instead of leaving it at the default, and omit the option –chunk-time.

The adaptive algorithm is bypassed. Chunk execution becomes predictable. Transaction size remains bounded. Galera never receives unexpectedly massive write sets. The overall schema change may take slightly longer, but cluster stability improves dramatically. For production environments this is usually the preferable trade-off.


Another parameter you should consider is –max-flow-ctl.

With –max-flow-ctl=PCT, pt-osc periodically checks wsrep_flow_control_paused (the percentage of time the node has spent paused for flow control) and automatically pauses row copying whenever it exceeds the threshold, resuming once the cluster drops back below it.

Setting –-max-flow-ctl to zero (or very close to it, e.g. 1) makes pt-online-schema-change stop copying rows at the very first sign that any node has entered flow control, rather than tolerating some pause time before backing off — which is the safest possible stance for a production cluster, especially one that’s already showing signs of stress (like the checkpointer-lag warnings, where large transactions were pushing InnoDB’s redo log reclamation to its limit): any additional write pressure from the migration’s chunked copy could tip an already struggling node into a much bigger stall, so a near-zero threshold trades migration speed for safety, letting the tool fully defer to the cluster’s real-time capacity and only advance when there’s genuinely no contention, which is generally the right call for critical, latency-sensitive production workloads where a slower-but-safe schema change beats a fast one that risks a cluster-wide write freeze.

A related lever worth mentioning is –chunk-index. By default, pt-online-schema-change chunks the table using the primary key (or the most appropriate unique index it can find), which is precisely why, in our case, chunk boundaries tracked the same monotonically increasing column as created_at and produced the long stretch of near-empty chunks described above. If the table has a secondary index whose ordering is not correlated with created_at, forcing the tool to chunk on that index instead (–chunk-index=idx_name) can spread matching and non-matching rows more evenly across chunks, so the adaptive algorithm never sees the extended low-density run that drives chunk size to unsafe levels in the first place. That said, this is not a substitute for –chunk-time=0 and –max-flow-ctl: pt-osc’s own documentation warns that a poorly chosen chunking index can hurt performance, since it forces query plans, and few tables have a convenient index that is both selective enough to chunk on and uncorrelated with the –where condition. In practice, we recommend treating –chunk-index as a secondary, table-specific optimization, with fixed chunk sizes and flow-control awareness remaining the primary safeguard.


A third option is to avoid the –where clause altogether and split the task into two phases instead. First, run pt-archiver solely to delete the rows you no longer need; then run pt-online-schema-change to alter the table. This two-step procedure avoids any risk stemming from the non-uniform distribution of the matching rows.


Conclusion

pt-online-schema-change remains one of the best tools available for online schema migrations.

Nevertheless, when using –where to copy only a small subset of rows on Percona XtraDB Cluster, adaptive chunk resizing can unintentionally generate oversized transactions that trigger excessive Galera Flow Control and temporarily stall the cluster.

Keeping chunk sizes fixed eliminates this feedback loop, producing smoother replication behaviour and reducing the operational risk of online schema changes. Other fixes are also available.

Sometimes, predictability is a better optimization than aggressiveness.

The post When pt-online-schema-change “where” Meets Galera: Understanding Chunk Auto-Resize and Flow Control appeared first on Percona.

Sep
24
2026
--

Talking Drupal #571 – GovHub

Today we are talking about GovHub, Drupal in Government, and Why Governments Love Drupal with guest Jasmyne Epps. We’ll also cover Convivial Gov Site Template as our module of the week.

For show notes visit: https://www.talkingDrupal.com/571

Topics

  • GovHub Origins and Goals
  • Feature Requests and Governance
  • Why Government Chooses Drupal
  • Team Structure and Release Cadence
  • Accessibility and Compliance Strategy
  • Hosting Model and Multisite
  • Structured Content and Microcontent
  • Syndication and Emergency Alerts
  • Orchard Design System Explained
  • Training and Onboarding Editors
  • Gov Talks Conference
  • Logo Specs and Releases
  • Ticket Prioritization PRICE
  • QA Workflow with Tugboat
  • Handling Traffic Spikes
  • Drupal 11 Performance Talk
  • Drupal 11 Upgrade Gotchas
  • Getting Users Excited
  • Translation Strategy Limits
  • Why Government Loves Drupal

Resources

Guests

Jasmyne Epps – jasmyneepps.com jasmyneepps

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi Amber Matz – tugboatqa.com [amber himes matz](https://www.drupal.org/u/amber himes matz)

MOTW Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

  • Brief description:
    • Have you ever wanted to stand up a polished, accessible government website in Drupal (with components, content types, SEO, and cookie consent all wired up) without writing any code? There’s a site template for that.
  • Module name/project name:
  • Brief history
    • Created in March 2026 by Morpht, the shop behind the Convivial family — with Ivan Zugec leading the maintainer team.
    • Versions available: 1.3.3, which works with Drupal 11
  • Maintainership
    • Actively maintained: release just last week, on September 16th
    • Security coverage
    • Test coverage: functional tests for install and validation, plus a kernel requirements test.
    • Documentation there’s a full handbook over at docs.morpht.com, and a live demo at gov.convivial.io
    • Open issues: none?
  • Site template features and usage
    • Like the Haven site template we talked about a couple of weeks ago, Convivial Gov gives you a curated stack plus demo content, and in this case hands you a robust, ready-to-customize government site.
    • Because it’s built on Drupal CMS, you get all the latest Drupal tooling: Canvas for visual page building, Single Directory Components, and Recipes.
    • The front end is Morpht’s Morphos theme, built on Tailwind and DaisyUI, so you get dark mode, multiple colour palettes, and a big library of editor-friendly components out of the box. It’s worth mentioning that using the Morphos theme on a production site requires a paid license
    • The provided components are sorted into six buckets: container, content, child, element, background, and behavior. They include fun ones like scroll reveal and a colour palette switching behavior
    • The content model is broad. You get seven content types: Page, Section, Article, Publication, Resource, Topic, and Audience. And, they come with a stack of teaser and card view modes to display them.
    • The whole point is no-code: a site builder can compose sophisticated pages in Canvas without ever touching a template.
    • One thing to watch: the default timezone is Australia/Sydney out of the box
    • It’s also worth comparing Convivial Gov to another site template called Local. Both dropped in March 2026, both are Canvas-based Drupal CMS site templates for the public sector, and both lean on ECA for automation — so there’s real common ground. The difference is scope and mechanism. Local, from Annertech, is narrowly purpose-built for local councils and community-service directories: it ships a specific service information architecture — Service and Service Landing content types — with ECA wired so section pages stay in sync when service pages get published or updated, taking its cues from the gov.uk design system. Convivial Gov goes the other way — it’s design-system-led and general-purpose, a broad component library and content model meant for any government, agency, or marketing site rather than one particular workflow.
Sep
21
2026
--

DISTANCE() and VECTOR_DISTANCE(): Vector Similarity in Percona Server for MySQL 9.7

TL;DR

Percona Server for MySQL 9.7.2-2 now supports DISTANCE() for vector similarity scoring directly in SQL (COSINE, EUCLIDEAN, MANHATTAN, DOT metrics). This is the compute primitive you need to rank or filter embeddings by similarity directly in SQL. ANN indexing (e.g. HNSW, IVF) is the next milestone for fast large-scale similarity search; and this function provides the scoring layer that indexing strategies will further accelerate.

Why we’re adding this

MySQL’s native DISTANCE() and VECTOR_DISTANCE() functions are only available in HeatWave MySQL on OCI, not included in Community or Commercial MySQL, and limited to three metrics (COSINE, DOT, EUCLIDEAN). Percona is bringing the same capability to anyone running Percona Server for MySQL on any supported platform.

MySQL 9.7 already supports the VECTOR data type (TO_VECTOR() and FROM_VECTOR() functions) for storing embeddings. DISTANCE() is the natural next step: it lets you query by similarity directly in SQL, ranking or filtering rows based on vector distance, without leaving MySQL.

Background on Vectors & Distance Metrics

What’s a vector?

A fixed-length list of numbers, an “embedding” produced by an ML model to represent something (text, an image, a product, a user preference). The key insight: “similar” things end up with numerically close vectors, so you can compute their distance to rank or filter them.

What’s a distance metric?

A mathematical function that turns two vectors into a single number describing similarity. Here are the five metrics this release supports:

  • EUCLIDEAN (L2): Straight-line distance, the intuitive notion of geometric distance. General-purpose; works well when magnitude matters.
  • EUCLIDEAN_SQUARED: Same ranking as EUCLIDEAN, but skips the square root. Faster for comparisons and ORDER BY clauses when you only care about ordering, not the actual value.
  • MANHATTAN (L1): Grid-style distance (like taxicab distance on a city grid). More robust to outliers than Euclidean in some applications.
  • COSINE similarity: Measures the angle between two vectors. Cosine distance is computed as 1 minus the cosine similarity so that smaller value = more similar.
  • DOT (inner product): Raw dot product sum(a[i] * b[i]). Used by models trained specifically for dot-product similarity (e.g., some matrix-factorization systems). Normally higher values mean more similar but since it is common in the industry to multiply by -1 and flip the scale: now smaller values = more similar, in line with the other metrics above.

What’s SIMD?

Single Instruction, Multiple Data: a CPU capability that performs the same arithmetic on many numbers at once instead of one at a time. Distance math over hundreds of dimensions (embedding size) is exactly the kind of repetitive arithmetic that SIMD accelerates. The Percona implementation automatically detects and uses the best SIMD tier available on your hardware at startup, no recompilation needed per target architecture.

Meet DISTANCE() / VECTOR_DISTANCE()

Function signature:

DISTANCE(vector1, vector2, metric)

Where: – vector1 and vector2 are VECTOR data type or binary string literals (via TO_VECTOR()). – metric is a fixed literal string (case-insensitive, not a column nor an expression): ‘EUCLIDEAN’, ‘EUCLIDEAN_SQUARED’, ‘MANHATTAN’, ‘COSINE’, or ‘DOT’. – Returns a DOUBLE representing the distance/similarity score.

Synonym: VECTOR_DISTANCE() is an alias with identical behavior.

Choosing a metric: Match the metric to how your embedding model was trained. Most modern embedding models (OpenAI, Cohere, etc.) are trained with COSINE similarity, so use ‘COSINE’. If magnitude carries meaning (e.g., you’re working with raw feature vectors, not normalized embeddings), use ‘EUCLIDEAN’ or ‘EUCLIDEAN_SQUARED’. When in doubt, check your embedding model’s documentation.

  • All dimensions must match: Both vectors must have the same dimensionality, or the function returns an error.
  • If either input is NULL, the result is NULL.

Getting started: Step-by-step example

1. Create a table with vector embeddings

CREATE TABLE products (
 id INT PRIMARY KEY,
 name VARCHAR(255),
 embedding VECTOR(1536)  -- Example: 1536-dimensional embedding
);

2. Insert some embeddings

INSERT INTO products VALUES
 (1, 'Product A', TO_VECTOR('[0.1, 0.2, 0.3, ..., 0.384]')),
 (2, 'Product B', TO_VECTOR('[0.15, 0.25, 0.35, ..., 0.385]')),
 (3, 'Product C', TO_VECTOR('[0.5, 0.6, 0.7, ..., 0.800]'));

3. Query by similarity

Find the top-5 products most similar to a query embedding:

SELECT id, name, DISTANCE(embedding, TO_VECTOR('[0.12, 0.22, 0.32, ..., 0.382]'), 'EUCLIDEAN') AS similarity_score
FROM products
ORDER BY similarity_score
LIMIT 5;

Results ordered by highest similarity first (best/closest matches first) :

id | name       | similarity_score
---|------------|------------------
2  | Product B  | 0.5432109
1  | Product A  | 0.9654321
3  | Product C  | 0.9876543

Under the hood: SIMD dispatch that adapts to your hardware

The engineering story behind the performance claim: instead of compiling the binary once for a specific CPU (with -march=native), Percona’s implementation detects the CPU’s capabilities at startup and selects the best available SIMD tier:

  • SSE4.2 (x86_64) or NEON (aarch64):  128-bit SIMD, ~2–3× speedup over scalar.
  • AVX2 (x86_64):  256-bit SIMD, ~4–6× speedup.
  • AVX-512F (x86_64): 512-bit SIMD, ~8–12× speedup on CPUs that support it.
  • SVE2 (aarch64): scalable SIMD on ARM, adapts to the CPU’s vector width.
  • Scalar: unoptimized fallback, works everywhere.

Dimension-aware kernel selection: Distance calculations on small vectors (<16 dimensions) uses the narrower 128-bit tier, because the overhead of setting up larger SIMD registers outweighs the benefit. Larger vectors automatically use the widest available tier.

Unaligned loads by design: VECTOR column data isn’t guaranteed to be cache-line aligned (and shouldn’t require alignment). All SIMD kernels use unaligned-load intrinsics as modern CPUs have identical throughput for aligned and unaligned loads when data is in cache. By always using unaligned loads, we avoid faulting on misaligned input without sacrificing performance.

Current limitations and what’s coming next

DISTANCE() is a scalar function that computes the distance between two vectors and returns a single number. Without an approximate-nearest-neighbor (ANN) index, a query like ORDER BY DISTANCE(…) LIMIT k over a large table is a full table scan: you call the distance function on every row, then sort. It’s correct and SIMD-accelerated per row, but it scales as O(n), not O(log n).

The natural next step: ANN indexing. To make large-scale similarity search fast (e.g., finding the 10 nearest neighbors in a table of 1 million vectors in milliseconds), you need an approximate-nearest-neighbor index: HNSW (Hierarchical Navigable Small World), IVF (Inverted File with refinement), or similar. These are graph-based or clustering-based structures that prune the search space and return approximate results much faster. This is the direction the vector feature is building toward, and it’s on the roadmap. For now, DISTANCE() is the scoring primitive that those indexing strategies will accelerate.

While ANN indexing delivers speed, it relies on approximate results. Should your application require exact precision instead of estimates, the DISTANCE() function is available in Percona Server for MySQL 9.7.2-2.

We want your feedback

Try it out and let us know what you think: – Report bugs or feature ideas on JIRA. – Join the conversation on Percona community forum. – Questions about usage or performance? Reach out to us.

Your feedback shapes the roadmap, especially use cases you’d like to see (e.g., specific ANN index strategies, embedding model integrations, performance tuning for your workload).

See also


Written by Catalin Besleaga. Reviewed by Dennis Kittrell and Peter Zaitsev.
Percona® is a registered trademark of Percona LLC. MySQL® is a registered trademark of Oracle Corporation.

The post DISTANCE() and VECTOR_DISTANCE(): Vector Similarity in Percona Server for MySQL 9.7 appeared first on Percona.

Sep
17
2026
--

Talking Drupal #570 – Laravel & Marketing PHP

Today we are talking about Laravel, Marketing, and The PHP Foundation with guest Matt Stauffer. We’ll also cover Formdazzle as our module of the week.

For show notes visit: https://www.talkingDrupal.com/570

Topics

  • What Is Laravel
  • Writing Laravel Books
  • AI and Technical Writing
  • Laravel Versus CMS
  • Drupal as Framework
  • Integrating Laravel and CMS
  • Laravel and Symfony
  • Marketing Modern PHP
  • Laravel Community Marketing
  • Jigsaw and Onramp
  • Drupal Marketing Lessons
  • Onboarding Focus in Laravel
  • Laravel BDFL Changes
  • Onboarding And Docs
  • Drupal Framework Perception
  • What PHP Foundation Does
  • Marketing PHP Vs Laravel
  • AI Answers And Positioning
  • Cross Ecosystem Collaboration

Resources

Guests

Matt Stauffer – mattstauffer.com

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi Amber Matz – tugboatqa.com [amber himes matz](https://www.drupal.org/u/amber himes matz)

MOTW Correspondent

Bernardo Martinez – bernardm28

  • Brief description:
    • This week’s module is Formdazzle, a developer tool that makes theming Drupal forms easier.
    • Drupal’s Form API is a powerful abstraction, but when you want to target one specific field, label, button, or form wrapper, the default Twig template suggestions can be limited.
    • The module works by taking information Drupal already knows about the form, like the form ID, element type, and element name, and using that to generate more targeted Twig template suggestions.
    • For example, in a Drupal View with exposed filters, you may want to style the Reset button differently from the Submit button. By default, Drupal renders both buttons through the same input–submit.html.twig template, which makes it difficult to customize them independently. This module lets you assign different templates to individual form buttons—such as Submit, Reset, or Filter—based on their action, type, and other properties.
    • This module has no configuration. Just enable the module and it starts working and look at the twig debug comments including extra template suggestions.
  • Module name/project name:
  • Brief history
    • How old: created in 13 September 2019 by johnalbin
    • Versions available: ^10.1 ^11 ^12
  • Maintainership
    • Actively maintained
    • Last release was 1 September 2026, currently the module has two maintainers Stephen Mustgrave and John Albin.
    • The module includes both test and security coverage.
  • Usage stats:
  • Module features and usage
    • There’s no configuration. Just enable the module and it starts working, including with Views exposed forms and Webform.
    • Formdazzle automatically adds more specific theme suggestions based on the form ID, element type, and element name.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com