Apr
30
2026
--

Run an ALTER TABLE for a huge table in Aurora

Recently, we received an alert for one of our Managed Services customers indicating that the auto_increment value for the table was 80% of its maximum capacity. The column was INT UNSIGNED, which has a limit of 4,294,967,295.

At 80%, we have enough time to change it to BIGINT.…. Right? Let’s see.

So we used pt-online-schema-change to perform the alter.

It started running at a good pace but slowed over time.


Why?

Well, let’s look at the definition of the table:

mysql> show create table myschema.mytableG
*************************** 1. row ***************************
       Table: mytable
Create Table: CREATE TABLE `mytable` (
  `id` int unsigned NOT NULL AUTO_INCREMENT,
  `long_column` varchar(1000) NOT NULL,
  `state` tinyint unsigned NOT NULL,
  `created` timestamp NOT NULL DEFAULT CURRENT_TIMESTAMP,
  `short_column` varchar(30) NOT NULL,
  PRIMARY KEY (`id`),
  KEY `idx_long_column` (`long_column`,`state`),
  KEY `idx_short_column` (`short_column`,`state`),
  KEY `idx_short_col2` (`short_column`)
) ENGINE=InnoDB AUTO_INCREMENT=4009973818 DEFAULT CHARSET=utf8mb3

NOTE1: The index on long_column is for a varchar column with a length of 1000; it may not be required, and an index prefix may be more helpful here.

NOTE2: The index idx_short_col2 is duplicated, as it is covered by the index idx_short_column.

Those changes require testing and are out of scope for this emergency, but they are worth mentioning.


Table size:

+---------------+------------+------------+---------+----------+---------+----------+--------+
| TABLE_SCHEMA  | TABLE_NAME | TABLE_ROWS | DATA_GB | INDEX_GB | FREE_GB | TOTAL_GB | ENGINE |
+---------------+------------+------------+---------+----------+---------+----------+--------+
| myschema      | mytable    | 3906921584 |    1118 |     1790 |       0 |     2907 | InnoDB |
+---------------+------------+------------+---------+----------+---------+----------+--------+

Look at the indexes being way bigger than the data.

mysql> SELECT database_name, table_name, index_name, ROUND(stat_value * @@innodb_page_size / 1024 / 1024, 2) AS size_in_mb FROM mysql.innodb_index_stats WHERE stat_name = 'size' AND index_name != 'PRIMARY' and database_name='myschema' and table_name='mytable' ORDER BY size_in_mb DESC;
+---------------+------------+-------------------+------------+
| database_name | table_name | index_name        | size_in_mb |
+---------------+------------+-------------------+------------+
| myschema      | mytable    | idx_long_column   | 1583538.95 |
| myschema      | mytable    | idx_short_column  |  126432.98 |
| myschema      | mytable    | idx_short_col2    |  122699.95 |
+---------------+------------+-------------------+------------+
3 rows in set (0.01 sec)

While the pt-online-schema-change runs, it copies the data to a new table. As the data is being copied, the secondary indexes must be maintained.

NOTE the huge index for a varchar(1000) that is ~1.5T in size. Maintaining such an index becomes increasingly expensive as the data size increases.

The pt-online-schema-change had been running for ~8 days, and its latest estimate was 53 more days, which we can’t afford, since the maximum value would be exceeded in ~15 days. 

Copying `myschema`.`mytable`:  12% 53+16:48:01 remain
Copying `myschema`.`mytable`:  12% 53+16:48:30 remain
Copying `myschema`.`mytable`:  12% 53+16:48:59 remain
Copying `myschema`.`mytable`:  12% 53+16:49:26 remain
Copying `myschema`.`mytable`:  12% 53+16:49:53 remain
Copying `myschema`.`mytable`:  12% 53+16:50:19 remain
Copying `myschema`.`mytable`:  12% 53+16:50:49 remain
Copying `myschema`.`mytable`:  12% 53+16:51:17 remain
Copying `myschema`.`mytable`:  12% 53+16:51:45 remain


So what do we do now?

We suggested canceling the pt-online-schema-change and creating an Aurora blue-green deployment.

Then perform the direct ALTER on the green cluster. And finally, when ready, do the failover.


Sounds good, doesn’t it?


First, we need to ensure that the new cluster (green) has the replica_type_conversions  parameter in its cluster parameter group to “ALL_NON_LOSSY, ALL_UNSIGNED” in order to be able to replicate from an int unsigned column to a bigint unsigned column.

So we tried that, it started too fast ~0.036% per minute, that’s 2 days. That’s great!

We left the process running over the weekend, but we noticed it started to slow down again… By Monday, it was advancing at ~0.01% every 5 mins, which gives an ETA of 34 days. 

Why? 

Again, using the direct ALTER MySQL copies the data to a temp table, and the bigger the data, the harder it is to maintain the indexes. 

Again, unacceptable.

Note that with the above 2 approaches, we lost ~12 days of precious time, and the deadline for auto_increment exhaustion was approaching.

Then we thought: What if we drop the secondary indexes, do the alter, and then add the indexes back?

In theory, it should be faster, as:

  • Dropping the indexes is a metadata-only operation with ONLINE DDL.
  • Altering the column datatype from INT to BIGINT is not an ONLINE operation, but the fact that it doesn’t have to update secondary indexes during row copying to a new temporary table prevents the slowdown.
  • Adding back the secondary indexes is an ONLINE DDL operation:


“Online DDL support for adding secondary indexes means that you can generally speed the overall process of creating and loading a table and associated indexes by creating the table without secondary indexes, then adding secondary indexes after the data is loaded.”

https://dev.mysql.com/doc/refman/8.4/en/innodb-online-ddl-operations.html

So let’s do this:

The deletion of the indexes was really quick, as expected (metadata-only operation):

mysql> ALTER TABLE myschema.mytable DROP INDEX idx_long_column, DROP INDEX idx_short_column, DROP INDEX idx_short_col2;
Query OK, 0 rows affected (49.40 sec)
Records: 0  Duplicates: 0  Warnings: 0


Then the change of the datatype:

mysql> ALTER TABLE myschema.mytable CHANGE COLUMN id id bigint unsigned NOT NULL AUTO_INCREMENT;
Query OK, 4058047205 rows affected (13 hours 9 min 10.62 sec)
Records: 4058047205  Duplicates: 0  Warnings: 0


Looks very promising!!!


The final step, add back the indexes:

mysql> ALTER TABLE myschema.mytable ADD INDEX `idx_long_column` (`long_column`,`state`), ADD INDEX `idx_short_column` (`short_column`,`state`), ADD INDEX `short_col2` (`short_column`);
ERROR 1878 (HY000): Temporary file write failure.


Why?

Well, the INPLACE operation uses the tmp dir to write sort files. In Aurora, there are certain limits for the temporary space based on the instance type

In a regular MySQL instance, we can modify the innodb_tmpdir to another location with enough disk space; however, in Aurora, the parameter is not modifiable, which could have made the whole process easier.

Even with a larger instance type, it’s hard to create the 1.5T index without breaking open the piggy bank.


Last resort, add the indexes back with the COPY algorithm:

mysql> ALTER TABLE myschema.mytable ALGORITHM=COPY, ADD INDEX `idx_long_column` (`long_column`,`state`), ADD INDEX `idx_short_column` (`short_column`,`state`), ADD INDEX `idx_short_col2` (`short_column`);
Query OK, 4147498819 rows affected (6 days 1 hour 55 min 57.00 sec)
Records: 4147498819  Duplicates: 0  Warnings: 0


Why does it work? Because ALTER TABLE using the COPY algorithm uses the datadir as the destination for the temporary table, the rows are copied there. It doesn’t have the limitation of the temporary directory mentioned above.

We were able to make it on time about 4 days before the auto_increment exhaustion, preventing downtime.


In retrospective we could have used the following approach to avoid the use of the blue/green deployment:

  1. Perform a pt-online-schema-change on the main table, dropping the indexes, and changing the column type to bigint. ( with –no-swap-tables –no-drop-old-table –no-drop-new-table –no-drop-triggers).
  2. Add the secondary indexes using the direct alter with the COPY algorithm in the _new table.
  3. Once the alter finishes, swap the tables and drop the triggers.


Conclusion:

What initially looked like an easy task with pt-online-schema-change, ended up being more complex. 

You need to check the data definition, the index sizes, the Aurora limits, and how the different algorithms work to make a decision on the best way to proceed with those tasks, specially on situations like these where you have the pressure of the auto_increment being exhausted and there’s risk of downtime if it is not done on time.

And of course, monitor auto_increment exhaustion for your tables, and use a reasonable threshold that gives you enough time to plan and change the table definition. You can use Percona Monitoring and Management for this, specifically on the MySQL > MySQL Table Details dashboard.

The post Run an ALTER TABLE for a huge table in Aurora appeared first on Percona.
Apr
30
2026
--

Run an ALTER TABLE for a huge table in Aurora

Recently, we received an alert for one of our Managed Services customers indicating that the auto_increment value for the table was 80% of its maximum capacity. The column was INT UNSIGNED, which has a limit of 4,294,967,295.

At 80%, we have enough time to change it to BIGINT.…. Right? Let’s see.

So we used pt-online-schema-change to perform the alter.

It started running at a good pace but slowed over time.


Why?

Well, let’s look at the definition of the table:

mysql> show create table myschema.mytableG
*************************** 1. row ***************************
       Table: mytable
Create Table: CREATE TABLE `mytable` (
  `id` int unsigned NOT NULL AUTO_INCREMENT,
  `long_column` varchar(1000) NOT NULL,
  `state` tinyint unsigned NOT NULL,
  `created` timestamp NOT NULL DEFAULT CURRENT_TIMESTAMP,
  `short_column` varchar(30) NOT NULL,
  PRIMARY KEY (`id`),
  KEY `idx_long_column` (`long_column`,`state`),
  KEY `idx_short_column` (`short_column`,`state`),
  KEY `idx_short_col2` (`short_column`)
) ENGINE=InnoDB AUTO_INCREMENT=4009973818 DEFAULT CHARSET=utf8mb3

NOTE1: The index on long_column is for a varchar column with a length of 1000; it may not be required, and an index prefix may be more helpful here.

NOTE2: The index idx_short_col2 is duplicated, as it is covered by the index idx_short_column.

Those changes require testing and are out of scope for this emergency, but they are worth mentioning.


Table size:

+---------------+------------+------------+---------+----------+---------+----------+--------+
| TABLE_SCHEMA  | TABLE_NAME | TABLE_ROWS | DATA_GB | INDEX_GB | FREE_GB | TOTAL_GB | ENGINE |
+---------------+------------+------------+---------+----------+---------+----------+--------+
| myschema      | mytable    | 3906921584 |    1118 |     1790 |       0 |     2907 | InnoDB |
+---------------+------------+------------+---------+----------+---------+----------+--------+

Look at the indexes being way bigger than the data.

mysql> SELECT database_name, table_name, index_name, ROUND(stat_value * @@innodb_page_size / 1024 / 1024, 2) AS size_in_mb FROM mysql.innodb_index_stats WHERE stat_name = 'size' AND index_name != 'PRIMARY' and database_name='myschema' and table_name='mytable' ORDER BY size_in_mb DESC;
+---------------+------------+-------------------+------------+
| database_name | table_name | index_name        | size_in_mb |
+---------------+------------+-------------------+------------+
| myschema      | mytable    | idx_long_column   | 1583538.95 |
| myschema      | mytable    | idx_short_column  |  126432.98 |
| myschema      | mytable    | idx_short_col2    |  122699.95 |
+---------------+------------+-------------------+------------+
3 rows in set (0.01 sec)

While the pt-online-schema-change runs, it copies the data to a new table. As the data is being copied, the secondary indexes must be maintained.

NOTE the huge index for a varchar(1000) that is ~1.5T in size. Maintaining such an index becomes increasingly expensive as the data size increases.

The pt-online-schema-change had been running for ~8 days, and its latest estimate was 53 more days, which we can’t afford, since the maximum value would be exceeded in ~15 days. 

Copying `myschema`.`mytable`:  12% 53+16:48:01 remain
Copying `myschema`.`mytable`:  12% 53+16:48:30 remain
Copying `myschema`.`mytable`:  12% 53+16:48:59 remain
Copying `myschema`.`mytable`:  12% 53+16:49:26 remain
Copying `myschema`.`mytable`:  12% 53+16:49:53 remain
Copying `myschema`.`mytable`:  12% 53+16:50:19 remain
Copying `myschema`.`mytable`:  12% 53+16:50:49 remain
Copying `myschema`.`mytable`:  12% 53+16:51:17 remain
Copying `myschema`.`mytable`:  12% 53+16:51:45 remain


So what do we do now?

We suggested canceling the pt-online-schema-change and creating an Aurora blue-green deployment.

Then perform the direct ALTER on the green cluster. And finally, when ready, do the failover.


Sounds good, doesn’t it?


First, we need to ensure that the new cluster (green) has the replica_type_conversions  parameter in its cluster parameter group to “ALL_NON_LOSSY, ALL_UNSIGNED” in order to be able to replicate from an int unsigned column to a bigint unsigned column.

So we tried that, it started too fast ~0.036% per minute, that’s 2 days. That’s great!

We left the process running over the weekend, but we noticed it started to slow down again… By Monday, it was advancing at ~0.01% every 5 mins, which gives an ETA of 34 days. 

Why? 

Again, using the direct ALTER MySQL copies the data to a temp table, and the bigger the data, the harder it is to maintain the indexes. 

Again, unacceptable.

Note that with the above 2 approaches, we lost ~12 days of precious time, and the deadline for auto_increment exhaustion was approaching.

Then we thought: What if we drop the secondary indexes, do the alter, and then add the indexes back?

In theory, it should be faster, as:

  • Dropping the indexes is a metadata-only operation with ONLINE DDL.
  • Altering the column datatype from INT to BIGINT is not an ONLINE operation, but the fact that it doesn’t have to update secondary indexes during row copying to a new temporary table prevents the slowdown.
  • Adding back the secondary indexes is an ONLINE DDL operation:


“Online DDL support for adding secondary indexes means that you can generally speed the overall process of creating and loading a table and associated indexes by creating the table without secondary indexes, then adding secondary indexes after the data is loaded.”

https://dev.mysql.com/doc/refman/8.4/en/innodb-online-ddl-operations.html

So let’s do this:

The deletion of the indexes was really quick, as expected (metadata-only operation):

mysql> ALTER TABLE myschema.mytable DROP INDEX idx_long_column, DROP INDEX idx_short_column, DROP INDEX idx_short_col2;
Query OK, 0 rows affected (49.40 sec)
Records: 0  Duplicates: 0  Warnings: 0


Then the change of the datatype:

mysql> ALTER TABLE myschema.mytable CHANGE COLUMN id id bigint unsigned NOT NULL AUTO_INCREMENT;
Query OK, 4058047205 rows affected (13 hours 9 min 10.62 sec)
Records: 4058047205  Duplicates: 0  Warnings: 0


Looks very promising!!!


The final step, add back the indexes:

mysql> ALTER TABLE myschema.mytable ADD INDEX `idx_long_column` (`long_column`,`state`), ADD INDEX `idx_short_column` (`short_column`,`state`), ADD INDEX `short_col2` (`short_column`);
ERROR 1878 (HY000): Temporary file write failure.


Why?

Well, the INPLACE operation uses the tmp dir to write sort files. In Aurora, there are certain limits for the temporary space based on the instance type

In a regular MySQL instance, we can modify the innodb_tmpdir to another location with enough disk space; however, in Aurora, the parameter is not modifiable, which could have made the whole process easier.

Even with a larger instance type, it’s hard to create the 1.5T index without breaking open the piggy bank.


Last resort, add the indexes back with the COPY algorithm:

mysql> ALTER TABLE myschema.mytable ALGORITHM=COPY, ADD INDEX `idx_long_column` (`long_column`,`state`), ADD INDEX `idx_short_column` (`short_column`,`state`), ADD INDEX `idx_short_col2` (`short_column`);
Query OK, 4147498819 rows affected (6 days 1 hour 55 min 57.00 sec)
Records: 4147498819  Duplicates: 0  Warnings: 0


Why does it work? Because ALTER TABLE using the COPY algorithm uses the datadir as the destination for the temporary table, the rows are copied there. It doesn’t have the limitation of the temporary directory mentioned above.

We were able to make it on time about 4 days before the auto_increment exhaustion, preventing downtime.


In retrospective we could have used the following approach to avoid the use of the blue/green deployment:

  1. Perform a pt-online-schema-change on the main table, dropping the indexes, and changing the column type to bigint. ( with –no-swap-tables –no-drop-old-table –no-drop-new-table –no-drop-triggers).
  2. Add the secondary indexes using the direct alter with the COPY algorithm in the _new table.
  3. Once the alter finishes, swap the tables and drop the triggers.


Conclusion:

What initially looked like an easy task with pt-online-schema-change, ended up being more complex. 

You need to check the data definition, the index sizes, the Aurora limits, and how the different algorithms work to make a decision on the best way to proceed with those tasks, specially on situations like these where you have the pressure of the auto_increment being exhausted and there’s risk of downtime if it is not done on time.

And of course, monitor auto_increment exhaustion for your tables, and use a reasonable threshold that gives you enough time to plan and change the table definition. You can use Percona Monitoring and Management for this, specifically on the MySQL > MySQL Table Details dashboard.

The post Run an ALTER TABLE for a huge table in Aurora appeared first on Percona.
Apr
30
2026
--

Managing Valkey Cluster in Kubernetes

Over the last several years, Percona has introduced several rock-star Kubernetes Operators for managing MySQL, Percona XtraDB Cluster, MongoDB, and PostgreSQL. For Valkey, we are actively working with the community to contribute our knowledge, and experience to help brainstorm, develop, and test the official Valkey Operator for Kubernetes.

While the Valkey Operator has not yet released a GA 1.0 version, we wanted to take this opportunity to highlight some recently added features.

Cluster Configuration

Up until recently, there was no native ability to provide configuration parameters to the Valkey server process running inside each deployed pod. This hurdle is now overcome, and you can supply configuration natively within the deployment CR.

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-valkey-cluster1
spec:
  shards: 3
  replicas: 1
  config:
    maxmemory: 500mb
    maxmemory-policy: allkeys-lfu
    maxclients: 5000
    commandlog-execution-slower-than: 10000

For now, these parameters are set on initial cluster deployment. There is already traction underway to allow certain parameters to be dynamically set at runtime. There are a small handful of certain cluster-based parameters that cannot be overridden by the user, otherwise it would break operator functionality.

User Access Control List (ACL)

Managing users is always a tedious task for any database administrator. Creating ACLs for users in Valkey can be a bit confusing coming from a traditional RDBMS using GRANT syntax. To make things just a bit easier, Valkey Operator has added user permissions management to the deployment CR.

Firstly, create your Secret containing usernames, and passwords:

apiVersion: v1
kind: Secret
metadata:
  name: valkey-cluster-sample-users
data:
  alicepw: M21wdHlQQHNzdzByZA==
  davidold: OVYqTHQlYXU4Mk5tdTlyeQ==
  davidnew: VmFsa2V5I1J1bHojMjIzMw==

Next, deploy your cluster with users:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-cool-valkey-cluster
spec:
  shards: 3
  replicas: 1
  users:
    - name: alice
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys: [alicepw]
      commands:
        allow: ["@read", "@write", "@connection"]
        deny: ["@admin", "@dangerous"]
      keys:
        readWrite: ["app:*", "cache:*"]
        readOnly: ["shared:*", "config:*"]
        writeOnly: ["logs:*", "metrics:*"]
    - name: david
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys:
          - davidold
          - davidnew
      commands:
        allow: ["@admin"]

There’s quite a lot going on here. Let’s break it down by first looking at the user ‘alice’: 

The ‘alice’ user is enabled, with a password found in the referenced Secret and secret key. Next, we can see what commands, or in this case, command groups (Noted with ‘@’) that alice is allowed to execute, and which commands/groups are denied. Lastly, permissions on specific key patterns are identified for maximum security restrictions.

The other user, ‘david’, can access all of the admin-group commands, and cannot read or write to any keys. Note that david’s secret key reference is an array, which means you can provide multiple passwords per user; great for password rotation! Once david confirms the new password, the old password references can be removed from the CR and Secret, and the Valkey Operator will synchronize the ACLs.

Users are dynamic, which means they can be added, removed, and modified without restarting the cluster.

TLS Support

Bring on the encryption! TLS support was also recently added to the Valkey Operator. Create your Secret with the CA, TLS Key, and Cert files, and tell the CR where to find them:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: cluster-sample
spec:
  shards: 3
  replicas: 1
  tls:
    certificate:
      secretName: my-valkey-tls-secret

Once deployed, the Valkey operator will mount the referenced secret to each pod, and add all the proper configuration parameters. By doing so, the operator enforces SSL/TLS communication between each Valkey cluster node, securing node-to-node, and replication traffic within your kubernetes network. Additionally, by creating user certificates signed by the same CA, traffic between your clients, and the Valkey clusters nodes is secured. This configuration is BYOC (bring-your-own-certificate), which works well with the popular CertManager, or other certificate authority you may be using.

On The Horizon

As a teaser, here are a couple other features coming soon to Valkey Operator:

  • Data Persistence: The ability to enable background snapshots of the in-memory dataset for backup, and recovery. Additionally, supporting the AOF (append-only file) for streaming changes.
  • Simple Replication: The operator currently only supports Valkey in cluster mode. Be on the lookout for traditional primary -> N-replica configurations, along with Sentinel monitoring.

Join Us

Want to contribute to the Valkey Operator? Join any of the discussions/issues on our github, or come introduce yourself in the Valkey Slack community.

The post Managing Valkey Cluster in Kubernetes appeared first on Percona.

Apr
30
2026
--

Managing Valkey Cluster in Kubernetes

Over the last several years, Percona has introduced several rock-star Kubernetes Operators for managing MySQL, Percona XtraDB Cluster, MongoDB, and PostgreSQL. For Valkey, we are actively working with the community to contribute our knowledge, and experience to help brainstorm, develop, and test the official Valkey Operator for Kubernetes.

While the Valkey Operator has not yet released a GA 1.0 version, we wanted to take this opportunity to highlight some recently added features.

Cluster Configuration

Up until recently, there was no native ability to provide configuration parameters to the Valkey server process running inside each deployed pod. This hurdle is now overcome, and you can supply configuration natively within the deployment CR.

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-valkey-cluster1
spec:
  shards: 3
  replicas: 1
  config:
    maxmemory: 500mb
    maxmemory-policy: allkeys-lfu
    maxclients: 5000
    commandlog-execution-slower-than: 10000

For now, these parameters are set on initial cluster deployment. There is already traction underway to allow certain parameters to be dynamically set at runtime. There are a small handful of certain cluster-based parameters that cannot be overridden by the user, otherwise it would break operator functionality.

User Access Control List (ACL)

Managing users is always a tedious task for any database administrator. Creating ACLs for users in Valkey can be a bit confusing coming from a traditional RDBMS using GRANT syntax. To make things just a bit easier, Valkey Operator has added user permissions management to the deployment CR.

Firstly, create your Secret containing usernames, and passwords:

apiVersion: v1
kind: Secret
metadata:
  name: valkey-cluster-sample-users
data:
  alicepw: M21wdHlQQHNzdzByZA==
  davidold: OVYqTHQlYXU4Mk5tdTlyeQ==
  davidnew: VmFsa2V5I1J1bHojMjIzMw==

Next, deploy your cluster with users:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-cool-valkey-cluster
spec:
  shards: 3
  replicas: 1
  users:
    - name: alice
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys: [alicepw]
      commands:
        allow: ["@read", "@write", "@connection"]
        deny: ["@admin", "@dangerous"]
      keys:
        readWrite: ["app:*", "cache:*"]
        readOnly: ["shared:*", "config:*"]
        writeOnly: ["logs:*", "metrics:*"]
    - name: david
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys:
          - davidold
          - davidnew
      commands:
        allow: ["@admin"]

There’s quite a lot going on here. Let’s break it down by first looking at the user ‘alice’: 

The ‘alice’ user is enabled, with a password found in the referenced Secret and secret key. Next, we can see what commands, or in this case, command groups (Noted with ‘@’) that alice is allowed to execute, and which commands/groups are denied. Lastly, permissions on specific key patterns are identified for maximum security restrictions.

The other user, ‘david’, can access all of the admin-group commands, and cannot read or write to any keys. Note that david’s secret key reference is an array, which means you can provide multiple passwords per user; great for password rotation! Once david confirms the new password, the old password references can be removed from the CR and Secret, and the Valkey Operator will synchronize the ACLs.

Users are dynamic, which means they can be added, removed, and modified without restarting the cluster.

TLS Support

Bring on the encryption! TLS support was also recently added to the Valkey Operator. Create your Secret with the CA, TLS Key, and Cert files, and tell the CR where to find them:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: cluster-sample
spec:
  shards: 3
  replicas: 1
  tls:
    certificate:
      secretName: my-valkey-tls-secret

Once deployed, the Valkey operator will mount the referenced secret to each pod, and add all the proper configuration parameters. By doing so, the operator enforces SSL/TLS communication between each Valkey cluster node, securing node-to-node, and replication traffic within your kubernetes network. Additionally, by creating user certificates signed by the same CA, traffic between your clients, and the Valkey clusters nodes is secured. This configuration is BYOC (bring-your-own-certificate), which works well with the popular CertManager, or other certificate authority you may be using.

On The Horizon

As a teaser, here are a couple other features coming soon to Valkey Operator:

  • Data Persistence: The ability to enable background snapshots of the in-memory dataset for backup, and recovery. Additionally, supporting the AOF (append-only file) for streaming changes.
  • Simple Replication: The operator currently only supports Valkey in cluster mode. Be on the lookout for traditional primary -> N-replica configurations, along with Sentinel monitoring.

Join Us

Want to contribute to the Valkey Operator? Join any of the discussions/issues on our github, or come introduce yourself in the Valkey Slack community.

The post Managing Valkey Cluster in Kubernetes appeared first on Percona.

Apr
30
2026
--

Continued Commitment to Percona XtraDB Cluster

At Percona, our priority has always been to provide the open source database solutions that our users can count on for the long term. Percona XtraDB Cluster (PXC) is a core part of that promise, delivering the high availability, scalability, and data integrity that mission-critical MySQL deployments depend on.

MariaDB has announced that September 30, 2026 will be the end-of-life date for continued maintenance and regular binary releases of MySQL Galera Cluster. We want to be clear about what this means for the organizations that rely on PXC: nothing is changing. Our commitment to PXC and the community that runs it is as strong as ever.

What is ending upstream is precisely what we already have in place. For anyone looking for an alternative path forward, PXC is the natural place to land.

What PXC users can count on

  • Our open Galera fork: Percona maintains its own Galera repository, open today and staying that way. We track upstream Galera releases, carry the fixes our customers need, and keep the codebase fully available for the community. PXC is built on this work, on terms we control.
  • Regular releases at the current cadence: Binary releases, bug fixes, and security patches continue to ship on the same terms and schedule our users have come to expect. You can review our full release history and release notes on the Percona documentation site.
  • Long-term support: PXC remains fully supported under our existing long-term support terms. If your organization is planning three to five years ahead, PXC is a safe foundation for those plans.
  • Compatibility and ecosystem integration: Strong binary compatibility with MySQL and Percona Server for MySQL, tight integration with Percona XtraBackup and Percona Monitoring and Management, and continued support across Kubernetes and traditional deployment environments.

What we’re continuing to invest in

Our engineering teams remain committed to making PXC better, focused on the things that make it a trusted choice: performance, stability, security, and a smooth operator experience. That work continues at pace. The PXC you depend on today will keep getting better, and the PXC you are evaluating for tomorrow will be ready when you need it.

Talk to us

If you have specific questions about your PXC deployment, your upgrade path, or your long-term high availability strategy, we’d love to hear from you. Reach out to your Percona contact, post a question in the Percona community forums, or connect with our team directly. High availability is too important to leave to uncertainty, and we are here to make sure you have the clarity and the support you need.

The post Continued Commitment to Percona XtraDB Cluster appeared first on Percona.

Apr
29
2026
--

Troubleshooting logical replication delay made easy

This blog is based on a real production case in which users experienced a serious delay in logical replication. Let me try to explain how to approach similar cases and analyze them in an easy method, because lag in logical replication is a common problem, and we should expect it to come up for different environments. But sometimes troubleshooting can be challenging, especially on DBaaS environments where we won’t get in-depth information at OS / hardware level. Such situations force us to deal with limited information which is available within the PostgreSQL connection (No host-level troubleshooting possible)

The Case

The case that triggered this blog was an attempt to migrate from one cloud vendor, to a recent version of PostgreSQL on a DBaaS offering of another cloud vendor. They started observing huge replication lag and reported to Percona. As usual, we started with pg_gather data collection.

(At Percona, we use pg_gather for diagnosis. Even though this blog and diagnosis refers to pg_gather report, any good diagnosis tool / scripts which can help to study the wait-event pattern and lag details could be able to help)

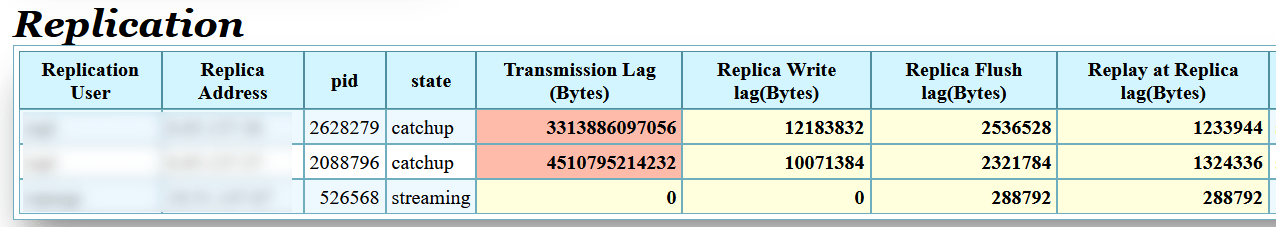
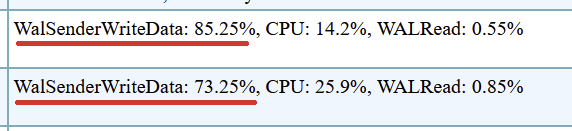
We saw upto 4.5 terabyte lag is happening at the transmission side (Publisher) on the customer case. The “Transmission”  lag” is the difference between the latest generated LSN and the LSN which the WAL Sender is able to send (sent_lsn of pg_stat_replication). That’s a first indication that the problem is mainly at the publisher side (WAL Sender) and it is not able to send the information fast enough.

Next step of investigation is to understand what both those WAL Senders might be doing. The wait event information for each WAL Sender could provide a clear clue on where the delay is happening.

Both the WAL Senders are mainly waiting in “WalSenderWriteData” event upto 85% of its time. This is a very unusual level of wait.

Following is the logic behind this.

  1. Logical decoding hands a finished record to
    WalSndWriteData()
  2. The data is queued in the
    libpq  send buffer with
    pq_putmessage_noblock
  3. A non-blocking flush is attempted with
    pq_flush_if_writable() .  But when the kernel send buffer is full, internal_flush_buffer() returns 0 with EAGAIN / EWOULDBLOCK  and data stays buffered —
    pq_is_send_pending()  becomes
    true
  4. The fast-path return is skipped, so it enters
    ProcessPendingWrites()
  5. There,
    WalSndWait(WL_SOCKET_WRITEABLE | WL_SOCKET_READABLE, sleeptime, WAIT_EVENT_WAL_SENDER_WRITE_DATA)  blocks until the socket is writable again or the subscriber sends a reply — that wait is what shows up as wait-event WalSenderWriteData

Source code reference : src/backend/replication/walsender.c

Which means that this wait event could happen due to the following reasons which I could think about. I would appreciate your comments if you know more reasons.

  1. The subscriber’s apply worker not consuming the stream fast enough (apply lock contention, slow I/O, heavy CPU load on the subscriber) — its TCP receive buffer fills up, the TCP window shrinks to zero,  the publisher’s
    send()  returns EAGAIN, and the WAL sender spins in the loop.
  2. Saturated network bandwidth between publisher and subscriber. There we have two cases. Traffic originating from Publisher to Subscriber could be slow OR handshake/acknowledgement traffic from Subscriber back to Publisher could be slow. The symptoms may differ.
  3. Large decoded transactions produce bursts of WalSndWriteData calls faster than the network can absorb them. This is generally a temporary problem and the cluster might catchup once the overhead of the large transaction is over.

Now the question would be : Now we know all the probable causes, but how to narrow down to the most probable cause ?, so that we can have an action plan.

At Percona, our engineers take time to put all hypotheses for testing, trying to simulate similar conditions and produce observable and reproducible cases. One might argue that we can use low level tracing / OS level tools at this stage to narrow down. Definitely, Yes. That’s the most appropriate thing to do. However many of the users may not have low level access and DBaaS offerings prevent it by design. But the good news is that wait – event patterns can tell us a story in more detail.

Slow Network traffic from Publisher to subscriber

If the network connectivity from Publisher side is slow or suffering with high latency, the send buffer won’t get cleared fast enough. Resulting in repeated attempts to send the data.

When we simulated the situation in the lab, we observed the similar Transmission side lag

Since this is a network connection problem, automatically the acknowledgment coming from the subscriber side will also be delayed and expected to show lags in all Write, Flush and Replay stages, which is visible in the data collection.

Obviously, our next question is what WALSender is doing ?. The wait events reveal that

The WAL sender is struggling to send data to Standby. This matches with what the user was seeing in their database.

Meanwhile, at the subscriber side, what we could see is that the apply worker is majorly sitting idle in the main loop: LogicalApplyMain

Two other major symptoms to be noted in the cases is 1). much smaller “Write lag” and compared to “Transmission lag” and  2.). Both the subscribers are suffering the lag, which is less probable if the problem is on the subscriber side.  Even additional clues like data collection running longer when executed from the publisher side about the subscriber instance is also supplementary evidence.

All the above symptoms helps us to conclude with a reasonable level of confidence that the network traffic from the Publisher is the problem.

Overloaded or slow Subscriber node

The problem could be caused by subscriber not communicating fast enough with Publisher. In such cases the replication lag is expected. I tested that scenario and the following is the observation.

The cause of the lag shifts from the “Transmission lag” to “Replica Write Lag”, which  is the difference between send_lsn and write_lsn.

The WAL Sender / publisher side don’t have any problem in sending

That looks really cool. The major wait event is WalSenderWaitForWal. Which means that the WAL sender is just waiting for the next WAL to be flushed and ready, In other words, sleeping until the next commit.

However, the situation on the Subscriber side is different. Unlike in the previous case, the apply worker could be busy with all sorts of work, no more free time to wait in the main loop.

The wait events and their percentage may vary depending on the performance-bottleneck on the subscriber side.

Slow traffic from Subscriber to Publisher

The impact of the network traffic from the Subscriber side back to Publisher has less effect than that from Publisher side. Because the data flow is from Publisher to Subscriber. The Subscriber needs to send only handshake acknowledgment information back to the publisher, which requires less bandwidth. So an apply worker can be waiting in the main loop (LogicalApplyMain)

But contrary to expectations, there could be cases of significant CPU usage if there are repeated attempts to reach primary, it may be consuming significant CPU cycles.  If we are suspecting network problems from the subscriber side, paying close attention to PostgreSQL logs is important.

There can be timeout captured in PostgreSQL logs at the publisher side

2026-04-23 17:34:07.078 UTC [36057] postgres@postgres LOG:  terminating walsender process due to replication timeout
2026-04-23 17:34:07.078 UTC [36057] postgres@postgres CONTEXT:  slot "sub", output plugin "pgoutput", in the commit callback, associated LSN DA/70450B8
2026-04-23 17:34:07.078 UTC [36057] postgres@postgres STATEMENT:  START_REPLICATION SLOT "sub" LOGICAL D9/DF13B50 (proto_version '4', streaming 'parallel', origin 'any', publication_names '"pub"')

Corresponding errors might be appearing at subscriber side also

2026-04-23 17:36:00.933 UTC [38413] ERROR:  could not receive data from WAL stream: SSL connection has been closed unexpectedly
2026-04-23 17:36:00.940 UTC [38428] LOG:  logical replication apply worker for subscription "sub" has started
2026-04-23 17:36:00.946 UTC [18241] LOG:  background worker "logical replication apply worker" (PID 38413) exited with exit code 1

All these are indications of poor connection.

Summary

PostgreSQL Wait events provide lots of visibility into PostgreSQL and underlying infrastructure problems. Reading it with PostgreSQL statistics information (pg_stat_*) and PostgreSQL log  could provide answers for a lot of questions as follows easily.

  1. Where is the problem ?. Which side of replication is lagging ?
  2. What are WAL Senders and WAL Receivers doing ? Are they busy doing something ? Is there anything pending or sitting idle ?
  3. Are there any hits of underlying infrastructure problems ?
  4. Is the problem correlatable with the wait events ?

Collecting and correlating the wait-event data from both sides of the replication, checking the LSN differences,  and information from PostgreSQL logs  gives us a complete picture.

All it takes is just a couple of minutes! With the right tools and methods in hand. I would like to encourage readers to make use of wait event pattern analysis for easy spotting of performance bottlenecks, if you are not doing it already. It can save you from the treachery of all indepth tracing. Observed Replication lag can be treated as a symptom of something more serious underlying.

This blog is written for those who don’t have access to OS level, But if we have access, getting into details is far easier. For example, the send queue (Send-Q) of the Publisher host can be checked like:

postgres@node0:~$ ss -tnp
State            Recv-Q            Send-Q                         Local Address:Port                       Peer Address:Port             Process
ESTAB            0                 18791538                          172.18.0.2:5432                         172.18.0.3:44974             users:(("postgres",pid=48178,fd=11))


The post Troubleshooting logical replication delay made easy appeared first on Percona.

Apr
29
2026
--

XtraBackup incremental prepare phase is 2x-3x faster!

TL;DR

Percona XtraBackup is a 100% open-source backup solution for Percona Server for MySQL and MySQL®. It is designed for high-availability environments, performing online, non-blocking, and highly secure backups of transactional systems without interrupting your production traffic.

While full backups work for small databases, large-scale systems rely on incremental backups to save space and time. However, the “prepare” stage, required to make the incremental backups consistent, was slow because XtraBackup processed the .delta files serially. The .delta files are generated per table and store only the modifications since the last backup.

Great news! In XtraBackup versions 8.0.35-33 and 8.4.0-3 and later, we’ve added support for the --parallel option during the prepare stage. This option lets XtraBackup process multiple .delta files simultaneously, significantly reducing the preparation time, especially when you have a large number of IBD files.

Please add --parallel=X, with the number of threads to use, to the xtrabackup --prepare --apply-log-only command to speed up the incremental prepare operation.

The Incremental Backup Workflow

Before we dive into the performance gains, it’s important to understand how Incremental backups work.

1. Creating the Backups

The process starts with a full backup followed by a backup that captures the changes since the last backup. This smaller backup is called an incremental backup. XtraBackup creates .delta files during incremental backups. Let’s review an example.

  • Take Full Backup: Your starting point is Point A. This backup is an entire copy of your data.
  • Take Inc1 Backup: XtraBackup identifies the changes between Point A and Point B. It creates a .delta file for every table that has been changed. Delta files contain only the pages that changed between the backups.
  • Take Inc2 Backup: XtraBackup identifies the changes between Point B and Point C. It creates a new set of .delta files for this specific period.

For more detailed steps/commands, please check the documentation here: https://docs.percona.com/percona-xtrabackup/8.0/create-incremental-backup.html

2. Preparing the Backups

To restore the data to the latest point, you must merge these changes back into the full backup. The “prepare” phase works differently here:

  • Prepare Inc1: You merge the Inc1 changes into the full backup using the --apply-log-only option. In this step, XtraBackup applies the .delta files and the redo logs, but does not apply the Undo logs
  • Prepare Inc2: You merge the Inc2 changes into the updated base using the --apply-log-only option. XtraBackup applies the .delta files and the Redo logs but skips the Undo logs.
  • Final Prepare: After all the incremental backups are merged, you run a final prepare command on the full backup. This final step applies the Undo logs to make the entire dataset consistent. If you apply the Undo logs during the intermediate steps, you cannot merge any further backups.

More detailed steps to prepare an incremental backup are described here: https://docs.percona.com/percona-xtrabackup/8.0/prepare-incremental-backup.html

The Improvement: Parallel Incremental Delta Apply

We have improved the Incremental Delta Apply phase. These are “Prepare inc1” and “Prepare inc2” phases as described above. --parallel option should be used along with the --apply-log-only to apply the .delta files in parallel.

We completed this essential improvement as part of [PXB-3427].

In previous versions, XtraBackup applied the .delta files as soon as a file was discovered in the incremental backup directory. Starting with versions 8.0.35-33 and 8.4.0-3, to apply the .delta files, XtraBackup scans the backup directory and builds a queue of delta files. Multiple threads (defined by --parallel ) consume this queue simultaneously. Each thread reads a .delta file and writes its pages to the corresponding InnoDB Data File (.ibd file).

Benchmarks

This benchmark is created using the scripts, and the instructions are in JIRA: PXB-3427

xtrabackup prepare performance

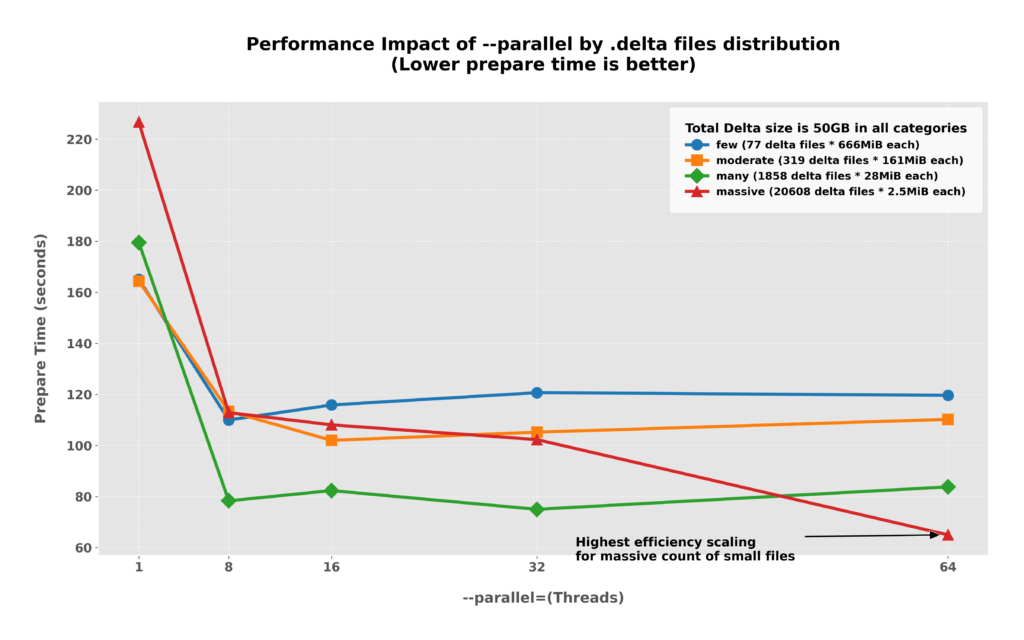
When your backup contains a large number of small .delta files, increasing the --parallel value can drastically reduce the time taken to prepare the incremental backup by distributing the high per-file overhead across more threads. However, for other categories with fewer or larger files, performance typically plateaus after 16 threads, and pushing higher can even lead to slight regressions due to thread management overhead. While there is no single “golden value” to recommend for every scenario, we recommend starting with a value of 8 to find the optimal balance for your specific environment.

Disk Utilization with XtraBackup prepare using --parallel=1 vs --parallel=64

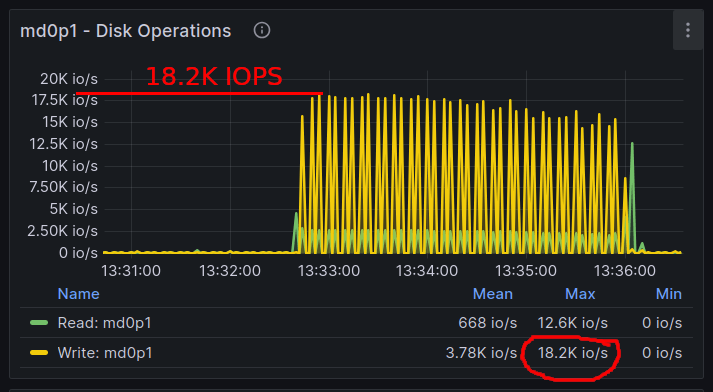
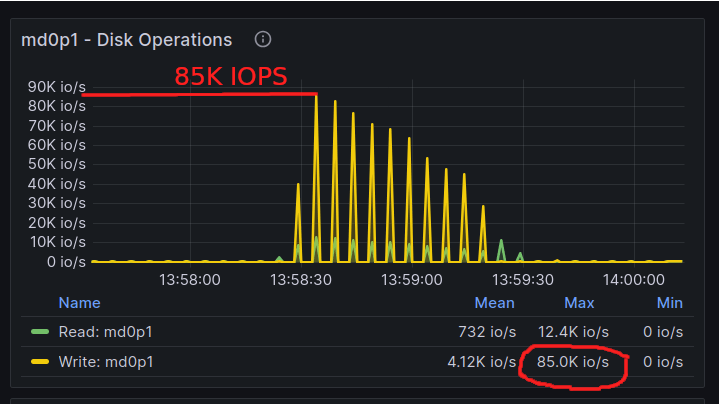
The PMM graphs below show the Disk IOPs used by the XtraBackup prepare command. The graph is generated when XtraBackup applies the incremental backup to a full backup directory. Incremental backup directory that has 20,608 .delta files, each of which is 2.5 MB.

With --parallel=1

xtrabackup incremental disk IOPs with --parllel=1

With --parallel=1, max Disk IOPs utilized is 18.2 K, and the XtraBackup prepare operation finished in 3.76 minutes.

With --parallel=64

xtrabackup incremental delta prepare performance with parallel 64


With --parallel=64, the max Disk Write IOPs utilized is 85K, and the XtraBackup prepare operation finished in around a minute. XtraBackup utilized 4.67x more disk IOPS and finished 3.49x faster.

Results from the bug reporter

We saw some amazing results shared by the reporter on PXB-3427.  The time required for XtraBackup prepare command (--prepare --apply-log-only)  to complete, reduced from 237 minutes to just 6 minutes. That’s an incredible 40X speed-up!

Here are the details from their setup:

  • Full backup: 235,188 *.ibd files
  • Incremental backup: 236,214 *.ibd.delta files
  • Average .delta size: 53,041 bytes (~53KB)
  • Threads used: 48 (–parallel=48)
  • Disk specs: 25K IOPS performance and an average of 500 to 600 MB/s of throughput

We hear you! This specific feature came to us from a post on the community forum. We reached out, asked them to create a JIRA ticket, and then implemented the improvement. We wanted to share this story as a demonstration of our commitment to listening to and acting on community feedback!

The post XtraBackup incremental prepare phase is 2x-3x faster! appeared first on Percona.

Apr
29
2026
--

XtraBackup incremental prepare phase is 2x-3x faster!

TL;DR

Percona XtraBackup is a 100% open-source backup solution for Percona Server for MySQL and MySQL®. It is designed for high-availability environments, performing online, non-blocking, and highly secure backups of transactional systems without interrupting your production traffic.

While full backups work for small databases, large-scale systems rely on incremental backups to save space and time. However, the “prepare” stage, required to make the incremental backups consistent, was slow because XtraBackup processed the .delta files serially. The .delta files are generated per table and store only the modifications since the last backup.

Great news! In XtraBackup versions 8.0.35-33 and 8.4.0-3 and later, we’ve added support for the --parallel option during the prepare stage. This option lets XtraBackup process multiple .delta files simultaneously, significantly reducing the preparation time, especially when you have a large number of IBD files.

Please add --parallel=X, with the number of threads to use, to the xtrabackup --prepare --apply-log-only command to speed up the incremental prepare operation.

The Incremental Backup Workflow

Before we dive into the performance gains, it’s important to understand how Incremental backups work.

1. Creating the Backups

The process starts with a full backup followed by a backup that captures the changes since the last backup. This smaller backup is called an incremental backup. XtraBackup creates .delta files during incremental backups. Let’s review an example.

  • Take Full Backup: Your starting point is Point A. This backup is an entire copy of your data.
  • Take Inc1 Backup: XtraBackup identifies the changes between Point A and Point B. It creates a .delta file for every table that has been changed. Delta files contain only the pages that changed between the backups.
  • Take Inc2 Backup: XtraBackup identifies the changes between Point B and Point C. It creates a new set of .delta files for this specific period.

For more detailed steps/commands, please check the documentation here: https://docs.percona.com/percona-xtrabackup/8.0/create-incremental-backup.html

2. Preparing the Backups

To restore the data to the latest point, you must merge these changes back into the full backup. The “prepare” phase works differently here:

  • Prepare Inc1: You merge the Inc1 changes into the full backup using the --apply-log-only option. In this step, XtraBackup applies the .delta files and the redo logs, but does not apply the Undo logs
  • Prepare Inc2: You merge the Inc2 changes into the updated base using the --apply-log-only option. XtraBackup applies the .delta files and the Redo logs but skips the Undo logs.
  • Final Prepare: After all the incremental backups are merged, you run a final prepare command on the full backup. This final step applies the Undo logs to make the entire dataset consistent. If you apply the Undo logs during the intermediate steps, you cannot merge any further backups.

More detailed steps to prepare an incremental backup are described here: https://docs.percona.com/percona-xtrabackup/8.0/prepare-incremental-backup.html

The Improvement: Parallel Incremental Delta Apply

We have improved the Incremental Delta Apply phase. These are “Prepare inc1” and “Prepare inc2” phases as described above. --parallel option should be used along with the --apply-log-only to apply the .delta files in parallel.

We completed this essential improvement as part of [PXB-3427].

In previous versions, XtraBackup applied the .delta files as soon as a file was discovered in the incremental backup directory. Starting with versions 8.0.35-33 and 8.4.0-3, to apply the .delta files, XtraBackup scans the backup directory and builds a queue of delta files. Multiple threads (defined by --parallel ) consume this queue simultaneously. Each thread reads a .delta file and writes its pages to the corresponding InnoDB Data File (.ibd file).

Benchmarks

This benchmark is created using the scripts, and the instructions are in JIRA: PXB-3427

xtrabackup prepare performance

When your backup contains a large number of small .delta files, increasing the --parallel value can drastically reduce the time taken to prepare the incremental backup by distributing the high per-file overhead across more threads. However, for other categories with fewer or larger files, performance typically plateaus after 16 threads, and pushing higher can even lead to slight regressions due to thread management overhead. While there is no single “golden value” to recommend for every scenario, we recommend starting with a value of 8 to find the optimal balance for your specific environment.

Disk Utilization with XtraBackup prepare using --parallel=1 vs --parallel=64

The PMM graphs below show the Disk IOPs used by the XtraBackup prepare command. The graph is generated when XtraBackup applies the incremental backup to a full backup directory. Incremental backup directory that has 20,608 .delta files, each of which is 2.5 MB.

With --parallel=1

xtrabackup incremental disk IOPs with --parllel=1

With --parallel=1, max Disk IOPs utilized is 18.2 K, and the XtraBackup prepare operation finished in 3.76 minutes.

With --parallel=64

xtrabackup incremental delta prepare performance with parallel 64


With --parallel=64, the max Disk Write IOPs utilized is 85K, and the XtraBackup prepare operation finished in around a minute. XtraBackup utilized 4.67x more disk IOPS and finished 3.49x faster.

Results from the bug reporter

We saw some amazing results shared by the reporter on PXB-3427.  The time required for XtraBackup prepare command (--prepare --apply-log-only)  to complete, reduced from 237 minutes to just 6 minutes. That’s an incredible 40X speed-up!

Here are the details from their setup:

  • Full backup: 235,188 *.ibd files
  • Incremental backup: 236,214 *.ibd.delta files
  • Average .delta size: 53,041 bytes (~53KB)
  • Threads used: 48 (–parallel=48)
  • Disk specs: 25K IOPS performance and an average of 500 to 600 MB/s of throughput

We hear you! This specific feature came to us from a post on the community forum. We reached out, asked them to create a JIRA ticket, and then implemented the improvement. We wanted to share this story as a demonstration of our commitment to listening to and acting on community feedback!

The post XtraBackup incremental prepare phase is 2x-3x faster! appeared first on Percona.

Apr
29
2026
--

Orchestrator’s Next Chapter: What It Means for Percona Customers

Last week, ProxySQL announced that they are taking over the maintenance and development of Orchestrator, the MySQL high-availability and topology management tool originally authored by Shlomi Noach. You can read their announcement here: Announcing the future of Orchestrator.

We want to briefly share Percona’s position on the news.

We welcome this

Orchestrator became the de facto standard for MySQL topology management and automated failover, and it has been a foundational tool in the ecosystem for over a decade. When the upstream project was archived, many operators were left running internal forks. A revived project under active development, with a stated roadmap and continued Apache 2.0 licensing, is good news for the MySQL community, and we’re glad to see ProxySQL step up to take it on. Thanks are due to Shlomi Noach for creating Orchestrator in the first place, and to everyone who contributed to it over the years.

A small clarification on Percona’s role

The ProxySQL announcement kindly credited Percona alongside GitHub for “stewardship over the years.” To be accurate: Percona has never been a maintainer of the upstream Orchestrator project. What we have done, and will continue to do, is support our customers who rely on it. That includes operational guidance, troubleshooting, and carrying internal patches where a customer situation requires it. The upstream project itself has always lived with Shlomi and later with the team at GitHub.

Nothing changes for Percona customers

If you are a Percona customer running Orchestrator today, your support experience is unchanged. We will continue helping you operate it in production, diagnose issues, and plan around its role in your high-availability stack. That commitment is steady regardless of where the upstream project lives.

Orchestrator’s maintenance also matters to us beyond support engagements. Percona Operator for MySQL uses Orchestrator to manage asynchronous topologies, so our own product depends on the project staying healthy. That’s part of why we plan to coordinate closely with the ProxySQL team as the next chapter unfolds.

Coordinating with the ProxySQL team

We plan to open coordination conversations with the ProxySQL team to make sure that operators running Orchestrator today, including our customers, have a smooth path as the project evolves. We wish the ProxySQL team well in this next chapter and look forward to supporting the community alongside them.

If you’re a Percona customer, reach out to your account team with any questions about your Orchestrator deployment. If you’re running Orchestrator outside of a Percona engagement and want to talk through support options, get in touch with our MySQL team.


The post Orchestrator’s Next Chapter: What It Means for Percona Customers appeared first on Percona.

Apr
28
2026
--

Ensuring PostgreSQL Backup Continuity: A pgBackRest Update

pgBackRest is a foundational component of the PostgreSQL backup solutions supported by Percona, playing a critical role in ensuring reliable and resilient data protection for our customers. It is a testament to the strength of the open source community that pgBackRest has become such a robust, widely trusted tool over the years.
Recently, changes around the pgBackRest project have raised questions across the PostgreSQL community.

At Percona, we want to address this clearly and simply:
Our customers can continue to rely on us.

Our Commitment to You

Percona remains fully committed to supporting PostgreSQL backup and recovery solutions built on top of pgBackRest. This includes:

  • Continued support for existing deployments
  • Ongoing expertise and operational guidance
  • Ensuring stability and reliability for production environments

Your systems, and your data protection strategy, remain safe in our hands.

Supporting Open Source, Responsibly

We deeply respect the work of the pgBackRest maintainers and the broader PostgreSQL community. Open source evolves and moments like this are part of that journey.

At the same time, moments like this highlight a broader industry reality: widely adopted open source projects can sometimes depend heavily on a small number of contributors. Ensuring long-term sustainability often requires broader collaboration, shared ownership, and continued investment.

Our focus is not on the circumstances, but on what comes next:

  • Working collaboratively with the community to support continuity and stability
  • Actively contributing engineering expertise to help maintain and evolve critical functionality
  • Investing in efforts that strengthen the long-term sustainability of PostgreSQL backup tooling
  • Helping provide clarity and direction for users navigating these changes

Looking Ahead

Percona is actively evaluating the best long-term path to ensure a stable, sustainable, and community-aligned future for PostgreSQL backup solutions.
We will continue to collaborate, contribute, and invest in the ecosystem to help ensure that PostgreSQL users have dependable, production-ready backup solutions.

Learn More

For additional context and a deeper technical perspective, please read our community post:

? https://percona.community/blog/2026/04/28/pgbackrest-is-archived-what-now/

The post Ensuring PostgreSQL Backup Continuity: A pgBackRest Update appeared first on Percona.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com