Aug
31
2026
--

Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption

Expired TLS certificates can prevent new client connections and, when X.509 is used for Percona Server for MongoDB internal authentication, also prevent members of a replica set or sharded cluster from authenticating to one another.

In this post we will discuss performing a same-CA renewal: replacement certificates for server, member, and client leaf are issued by the existing trusted CA, and the X.509 attributes used for cluster membership do not change. In this scenario, the rotateCertificates command reloads TLS material for new connections without restarting mongod or mongos.

Important: Do not apply this hot-reload procedure when replacing the issuing CA, changing a certificate subject DN, or changing cluster-membership attributes. Those are not ordinary renewals.

What rotates, and what does not

Percona Server for MongoDB can reload the files configured through the following TLS options:

net:
  tls:
    mode: requireTLS
    certificateKeyFile: /etc/mongod/tls/server.pem
    CAFile: /etc/mongod/tls/ca.pem
    clusterFile: /etc/mongod/tls/cluster.pem

The certificateKeyFile contains the certificate and private key presented to normal clients. The clusterFile holds the certificate and key that a mongod or mongos process presents when connecting to other cluster members. If clusterFile is not configured, certificateKeyFile is also used for member authentication.

The rotateCertificates command affects new TLS connections. It does not terminate established client sessions or force a replica-set election.

Before the maintenance window

Begin this process well in advance of the certificate expiry, and avoid performing your first attempt in a production environment.

  1. Inventory every process and client certificates. Include all mongod members, all mongos routers, application drivers, mongosh hosts, backup jobs, monitoring, and automation tools.
  2. Confirm this is a same-CA renewal. The issuer chain trusted by every participant stays the same, and the O, OU, and DC attributes used for default internal X.509 membership matching remain unchanged.
  3. Create a new PEM file for every server and client that needs rotation. A PEM file referenced by certificateKeyFile or clusterFile must include both the certificate and its matching private key. The file must strictly contain the key first, followed by the certificate, including their encapsulation boundaries.
  4. Verify the new certificate details and validate the cert against the CA before copying to the production TLS directory

Stage a renewed server or member certificate

There are a few limitations for rotating certificates online:

  • Each new certificate must have the same filename and same filepath as the certificate it is replacing.
  • If the TLS Certificate is password-protected, its password must be the same as the old certificate it is replacing.

If CAFile, a CRL, or another configured TLS input is being renewed as part of the same operation, replace it before invoking the reload command. The command reloads the configured TLS inputs as a set; a missing or invalid input causes the reload to fail.

Luckily, incorrect certificate files will cause the rotation to fail, but will not invalidate the existing configuration or have any other side effects.

Reload one process

Connect directly to the specific mongod or mongos with an administrative user and execute the following command:

db.getSiblingDB("admin").runCommand({rotateCertificates: 1, message: "Renewed TLS certificate"})'

Immediately validate a new TLS connection to that process with a renewed client certificate. Also inspect the log for the successful certificate-rotation message and any TLS errors. Check our documentation for guidelines to perform the procedure on a replica set or sharded cluster.

Final validation and cleanup

After completing the procedure, it is a good idea to reconfirm the expiry date and SANs of the certificate presented by every mongod and mongos. Retain the old certificates only for the approved overlap period, then remove or revoke them. Don’t forget to record the new expiry dates and create alerts with enough lead time before the expiration date of the new certificates.

When the CA or member identity changes

A different procedure is required when any of the following changes:

  • The issuing CA or trusted CA chain.
  • The subject DN used by a MONGODB-X509 client user.
  • The O, OU, or DC values used for default intra-cluster X.509 membership matching.
  • net.tls.clusterAuthX509.attributes or net.tls.clusterAuthX509.extensionValue.

This is a topic for another time.


The post Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption appeared first on Percona.

Aug
31
2026
--

Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption

Expired TLS certificates can prevent new client connections and, when X.509 is used for Percona Server for MongoDB internal authentication, also prevent members of a replica set or sharded cluster from authenticating to one another.

In this post we will discuss performing a same-CA renewal: replacement certificates for server, member, and client leaf are issued by the existing trusted CA, and the X.509 attributes used for cluster membership do not change. In this scenario, the rotateCertificates command reloads TLS material for new connections without restarting mongod or mongos.

Important: Do not apply this hot-reload procedure when replacing the issuing CA, changing a certificate subject DN, or changing cluster-membership attributes. Those are not ordinary renewals.

What rotates, and what does not

Percona Server for MongoDB can reload the files configured through the following TLS options:

net:
  tls:
    mode: requireTLS
    certificateKeyFile: /etc/mongod/tls/server.pem
    CAFile: /etc/mongod/tls/ca.pem
    clusterFile: /etc/mongod/tls/cluster.pem

The certificateKeyFile contains the certificate and private key presented to normal clients. The clusterFile holds the certificate and key that a mongod or mongos process presents when connecting to other cluster members. If clusterFile is not configured, certificateKeyFile is also used for member authentication.

The rotateCertificates command affects new TLS connections. It does not terminate established client sessions or force a replica-set election.

Before the maintenance window

Begin this process well in advance of the certificate expiry, and avoid performing your first attempt in a production environment.

  1. Inventory every process and client certificates. Include all mongod members, all mongos routers, application drivers, mongosh hosts, backup jobs, monitoring, and automation tools.
  2. Confirm this is a same-CA renewal. The issuer chain trusted by every participant stays the same, and the O, OU, and DC attributes used for default internal X.509 membership matching remain unchanged.
  3. Create a new PEM file for every server and client that needs rotation. A PEM file referenced by certificateKeyFile or clusterFile must include both the certificate and its matching private key. The file must strictly contain the key first, followed by the certificate, including their encapsulation boundaries.
  4. Verify the new certificate details and validate the cert against the CA before copying to the production TLS directory

Stage a renewed server or member certificate

There are a few limitations for rotating certificates online:

  • Each new certificate must have the same filename and same filepath as the certificate it is replacing.
  • If the TLS Certificate is password-protected, its password must be the same as the old certificate it is replacing.

If CAFile, a CRL, or another configured TLS input is being renewed as part of the same operation, replace it before invoking the reload command. The command reloads the configured TLS inputs as a set; a missing or invalid input causes the reload to fail.

Luckily, incorrect certificate files will cause the rotation to fail, but will not invalidate the existing configuration or have any other side effects.

Reload one process

Connect directly to the specific mongod or mongos with an administrative user and execute the following command:

db.getSiblingDB("admin").runCommand({rotateCertificates: 1, message: "Renewed TLS certificate"})'

Immediately validate a new TLS connection to that process with a renewed client certificate. Also inspect the log for the successful certificate-rotation message and any TLS errors. Check our documentation for guidelines to perform the procedure on a replica set or sharded cluster.

Final validation and cleanup

After completing the procedure, it is a good idea to reconfirm the expiry date and SANs of the certificate presented by every mongod and mongos. Retain the old certificates only for the approved overlap period, then remove or revoke them. Don’t forget to record the new expiry dates and create alerts with enough lead time before the expiration date of the new certificates.

When the CA or member identity changes

A different procedure is required when any of the following changes:

  • The issuing CA or trusted CA chain.
  • The subject DN used by a MONGODB-X509 client user.
  • The O, OU, or DC values used for default intra-cluster X.509 membership matching.
  • net.tls.clusterAuthX509.attributes or net.tls.clusterAuthX509.extensionValue.

This is a topic for another time.


The post Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption appeared first on Percona.

Aug
27
2026
--

Talking Drupal #567 – Common Vulnerabilities & Exposures

Today we are talking about Security, Vulnerabilities, and how to avoid exposure with guest Dave Welch. We’ll also cover Security Scanner as our module of the week.

For show notes visit: https://www.talkingDrupal.com/567

Topics

  • What Are CVEs
  • CVE Lifecycle and Disclosure
  • AI Era Security Challenges
  • What CVE Program Excludes
  • Patch Fast Reality
  • Global Security Signals
  • CVE Timing Judgment
  • KEV Flags Explained
  • CVE Updates Link Rot
  • Who Decides CVE
  • Sneaky Patch Dangers
  • ADP Program Fixes
  • Small Team Triage
  • Vulnerability Tsunami AI
  • Autonomous Security Future
  • Legal Pressure Budgets

Resources

Guests

David Welch – github: dwelch2344 dwelch2344

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi JD Flynn – dorficus

MOTW Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

  • Brief description:
    • Have you ever wanted a fast way to catch the security mistakes that slip into custom Drupal code — especially the code your AI assistant just wrote — before it ships? There’s a module for that.
  • Module name/project name:
  • Brief history
    • How old: created in July 2026 by Mayank Gupta (mayankguptadotcom) of Acquia
    • Versions available: 1.0.0, which works with Drupal 10.3 and 11
  • Maintainership
    • Actively maintained — created and shipped its first stable this summer, with steady development right through late July
    • Security coverage
    • Test coverage — and it’s strong: unit and kernel tests, including a regression corpus built from real Drupal core advisories
    • Documentation? In-depth README with a full check table and CI recipes, plus a CHANGELOG
    • Number of open issues: 1 issue, not a bug
  • Usage stats:
    • 2 sites (it’s brand new)
  • Module features and usage
    • Provide a Drush command, has no UI — you point drush security:scan at a module or any path, it reads the code statically, and prints a prioritized, OWASP-mapped list of things to review
    • It’s built for the age of AI-written code — the checks target the classes AI assistants keep reintroducing: routes with no access check, #markup and |raw XSS, missing CSRF tokens, unserialize() on untrusted data, hardcoded secrets
    • Then there’s an optional deep pass: with the Psalm static analysis scanning engine installed, it’ll trace untrusted input across functions and files to catch cross-function issues. And it’s honest about state — the report always says whether that deep pass ran, was skipped, or failed, so a failure never gets mistaken for a clean scan
    • One nice detail under the hood: a tokenizer-backed “code map” that knows whether a match is real code, a comment, or a string — so it won’t flag the word “unserialize” sitting in a doc comment. That kills the single biggest source of false positives
    • The checks are regression-tested against real Drupal advisories (Drupalgeddon, Drupalgeddon2, the 2019 unserialize bug, etc) so a pattern that caused an actual CVE can’t quietly come back in your custom code
    • Output comes in three flavors: a readable table, JSON for CI and AI agents, and SARIF — which means findings show up as annotations right on your GitHub or GitLab merge-request diff instead of buried in a job log
    • For adopting it on an existing codebase there’s a baseline file — you fingerprint the findings you’ve reviewed, with a required reason on each, and they stop failing the build but never go invisible; every run still counts them
    • It exits non-zero on error-level findings, so it drops straight into CI or a pre-commit hook
    • And it’s extensible — checks are Drupal plugins with a #[SecurityCheck] attribute, so any module can add its own or alter the ones that ship
    • Big caveat, and the module says this itself: a finding means “review this,” not “this is broken.” Static analysis has false positives, and a clean scan doesn’t prove the code is secure — access-control logic especially still needs human review
    • I first heard about this module over beverages at Drupalcamp Asheville, so I know that this module was largely vibe-coded, after having an AI agent ingest every single Drupal security team CVE. So I like to think of this module as security pattern recognition tool, but of course it does even more
Aug
27
2026
--

Benchmarking vector indexes

Nearly every database has vector search now, and every one of them has a blog post with a big number in it. Almost none of those numbers can be checked, because the thing that makes them meaningful is usually missing.

We built a vector-bench to stop guessing. You name the engines you want, build them from pinned versions, put each one in the same container on the same cores with the same data, run the same measurements against all of them, and write a report. This post is about how it measures.

If you work with databases but haven’t touched vectors yet, the first half is the part you need.

What’s being indexed

An embedding is a fixed-length array of floats that comes out of a model. The useful property is that semantically similar inputs land close together when you measure the distance between them.

Two distance measures cover almost everything. L2 is an ordinary straight-line distance, the Pythagorean one, extended to however many dimensions you have. Cosine Similarity  measures the angle between two vectors and ignores their length. Which one applies is decided by the model that produced the embeddings. It isn’t a choice you get to make at query time, and getting it wrong is a good way to produce nonsense.

So the query you want is “the 10 rows whose vectors are nearest this one”:

SELECT id FROM documents ORDER BY distance(embedding, ?) LIMIT 10;

That 10 is k.

Now the problem. Answering that exactly means computing the distance from your query vector to every single row, then sorting. No B-tree or hash index helps, because neither one can order a million points by proximity in 1536 dimensions. Exact vector search is a full table scan with a lot of arithmetic bolted on.

A vector index gives up exactness to avoid that. It looks at a few thousand promising candidates instead of every row and returns the best it found. That’s the approximate nearest neighbour search, or ANN. It’s usually right.

“Usually” is doing a lot of work in that sentence, and pinning it down is most of what this benchmark does.
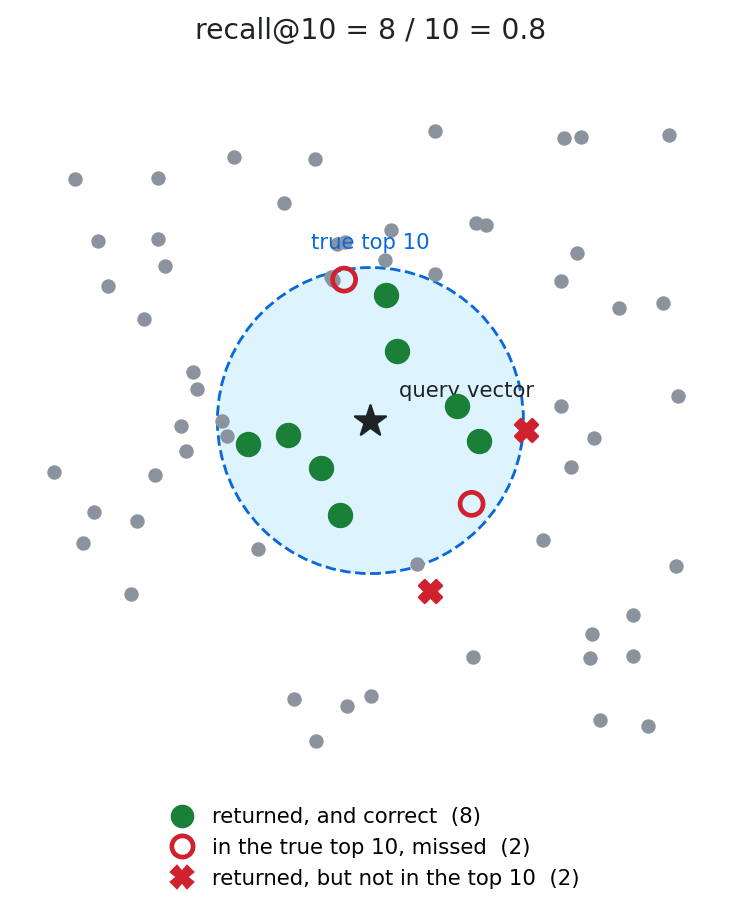
To score that you need to know the right answer in the first place. That’s the ground truth: the true nearest neighbours for every query, computed once by brute force with no index involved. The public ANN datasets ship theirs alongside the vectors, and without it you couldn’t score an approximate index at all.

This is the number that makes everything else meaningful, and it’s the one most vector search claims leave out. That omission is the reason this project exists.

The two kinds of vector index

Almost every database that has added vector search picked one of two designs. They attack the same problem from opposite ends, and which one you have decides what you’re allowed to tune.

HNSW

HNSW stands for Hierarchical Navigable Small World, which is a mouthful for something fairly intuitive. If you’ve ever implemented a skip list, you already have the shape of it.

It’s a graph of vectors built in layers. Every vector is a node, linked to some number of its nearest neighbours. The top layer has few nodes and its links jump long distances across the data. Each layer below has more nodes and shorter links. A search starts at the top and keeps hopping to whichever neighbour is closer to the query. When nothing is closer, it drops a layer and carries on, until it runs out of layers.
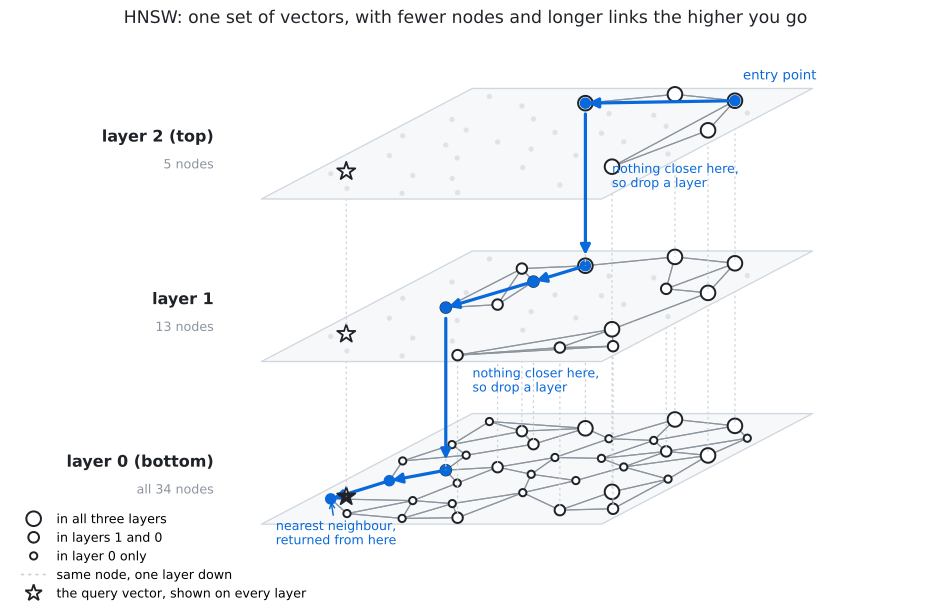
Two settings matter:

  • M is how many links each node keeps. It’s fixed when the index is built. Higher M means a better-connected graph and better recall, at the cost of a slower build and a bigger index.
  • ef_search is how many candidates the search keeps track of while it walks. It’s a session variable, so you can change it per query. Turn it up and the search visits more nodes, gets better recall, and runs slower.

There’s ef_construction too, the same idea applied while the index is being built. Not every engine lets you set it, which turns out to matter when you try to compare them fairly.

IVF

IVF stands for Inverted File. It partitions the data instead of linking it, not unlike list partitioning on a table.

At build time it groups the vectors into nlist clusters, each with a representative vector at its centre. At query time it compares the query against those representatives, picks the closest nprobe clusters, and searches only inside them. It builds much faster than HNSW and uses less memory, but usually gives worse recall at the same speed. It misses when the true neighbour happens to sit just outside the clusters it looked in.
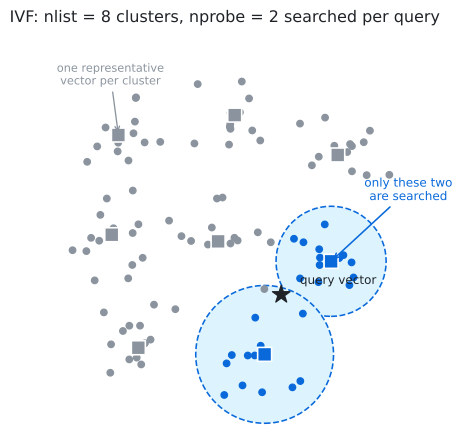
We only test engines running HNSW, which is what most databases shipped. Putting an IVF engine on the same chart would mostly measure the gap between two algorithms rather than how well anybody implemented one, so IVF-only engines get their own bucket.

Why one number is never enough

Recall isn’t a property of an engine. It’s a setting, and ef_search is the dial.

Here’s one HNSW index on one machine, same data, same queries. The only difference is that on the first row the search tracks 10 candidate nodes as it walks the graph, and on the second it tracks 800:

ef_search=10 3,678 queries/sec recall 0.9593
ef_search=800 409 queries/sec recall 0.9987

Keeping 800 candidates instead of 10 finds a better answer and takes nine times as long. Both rows are honest measurements of the same index on the same hardware.
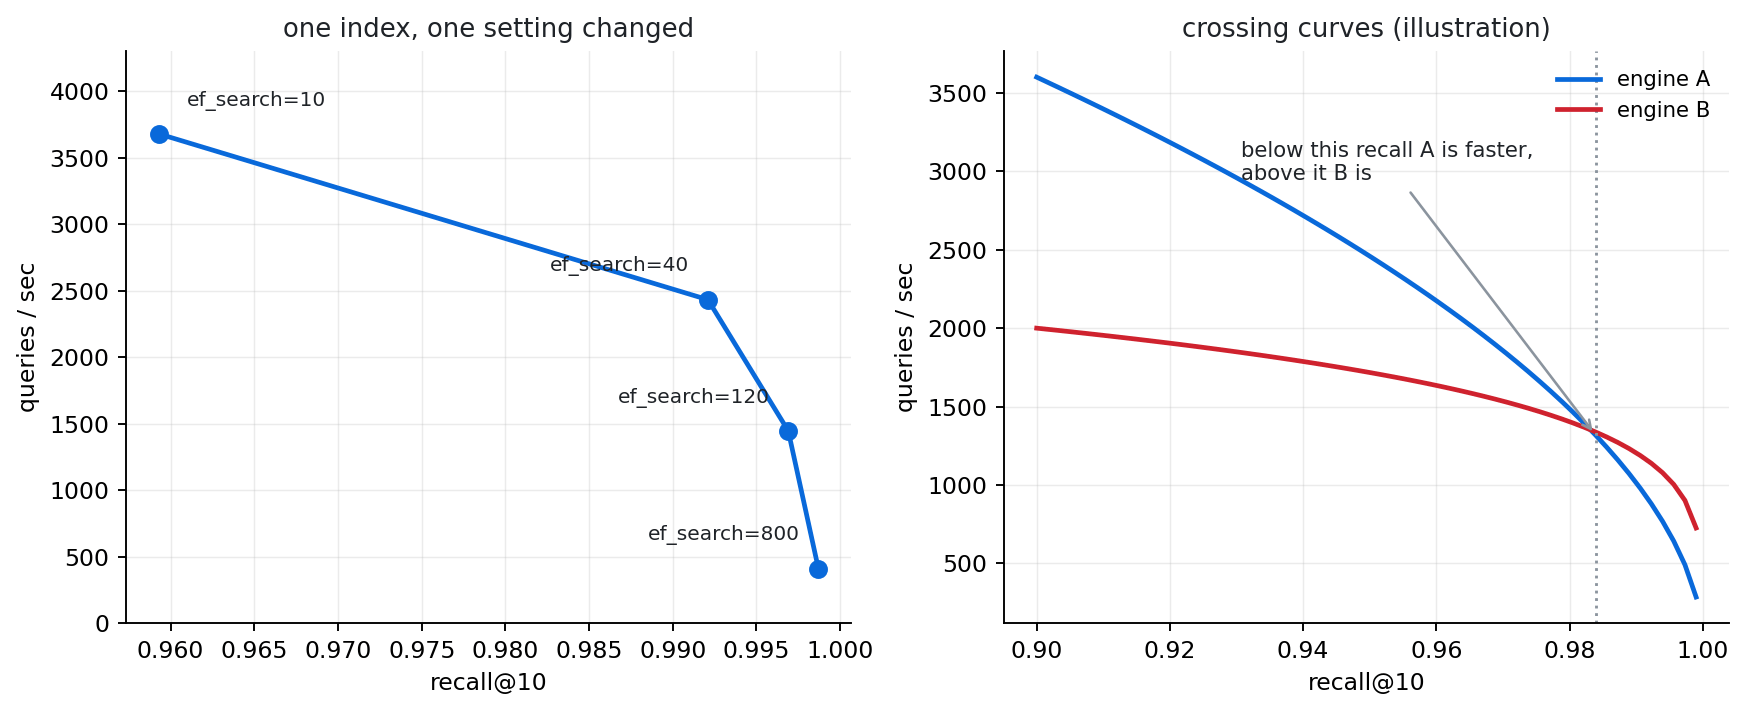
Which is why “our database does 3,678 vector queries a second” tells you nothing. You don’t know how often it was handing back the wrong rows, and the person quoting it may not know either. The reverse is just as empty: recall with no throughput next to it is free, because recall 1.0 is always available if you turn the index off and scan the table.

Every measurement here is a pair. If you take one thing from this post, take that.

What the harness puts on each engine

One table per engine. An id, an integer tag column used only by the filtered tests, the vector, and an HNSW index on it at a configured M.

CREATE TABLE t1 (
id INTEGER PRIMARY KEY,
tag INTEGER NOT NULL,
v VECTOR(1536)
);


Then two queries, plain top-k and the same search restricted to a subset of rows:

SELECT id FROM t1 ORDER BY distance(v, ?) LIMIT 10;
SELECT id FROM t1 WHERE tag < ? ORDER BY distance(v, ?) LIMIT 10;


tag holds values 0 to 99 spread evenly, so tag < 10 passes about 10% of rows and tag < 1 about 1%. That’s how we control selectivity.

Every engine writes all of this differently. Some declare the index inside CREATE TABLE, others want a separate CREATE INDEX, and the distance functions have different names everywhere. Translating that is the driver’s job, and the drivers are the only engine-specific code in the whole harness.

Every engine also has at least one setup detail that will quietly wreck your numbers. PostgreSQL, for instance, stores oversized values out of line in what it calls TOAST, and a 1536-dimension vector counts as oversized. Unless the column is set to STORAGE PLAIN, every single distance comparison pays for an extra fetch. It’s one line of DDL. Miss it and you publish PostgreSQL looking slow for a reason that has nothing to do with its vector search, and you’d never know from the results.

What we measure

Recall against throughput. Iterate ef_search against a fixed index, record recall and QPS at each point, repeat at a few values of M. k=10 throughout. The query vectors come from the dataset’s own held-out query set, never from the rows we loaded, because searching for a vector that’s already in the index is a much easier problem and would flatter everybody equally.

The two settings behave completely differently, and it shapes how long a run takes. ef_search is a session variable, so iterating it reuses the index that’s already built and each extra point costs almost nothing. M is baked into the index, so every value of M means dropping the table and loading the entire dataset again. On a million 1536-dimension vectors that’s hours per value. Hence many ef_search points and very few M values.

Build cost. Wall time, rows per second, index size on disk, peak memory.

This is the easiest place in the whole benchmark to publish a misleading number, because engines don’t build the index the same way. Engines can build indexes either incrementally, bulk, or both. What does that mean? 

Incremental. The graph is updated on every INSERT. Loading is slow, but when the last row lands the index is finished and the table is ready to query.

Bulk. All the rows load first, then the whole graph gets built in one pass. Much faster in total, but the table can’t answer a vector query until the build finishes.

Those are two different operations. One engine in our set does both, and its bulk path loaded 18 times more rows per second than its own incremental path. Same engine, same data, same machine, 18x apart.

So a bulk number from one engine put next to an incremental number from another doesn’t compare engines at all. It compares two ways of building an index, and the ratio looks impressive enough that people quote it anyway. We measure both paths on any engine that has both, and the report says which is which.

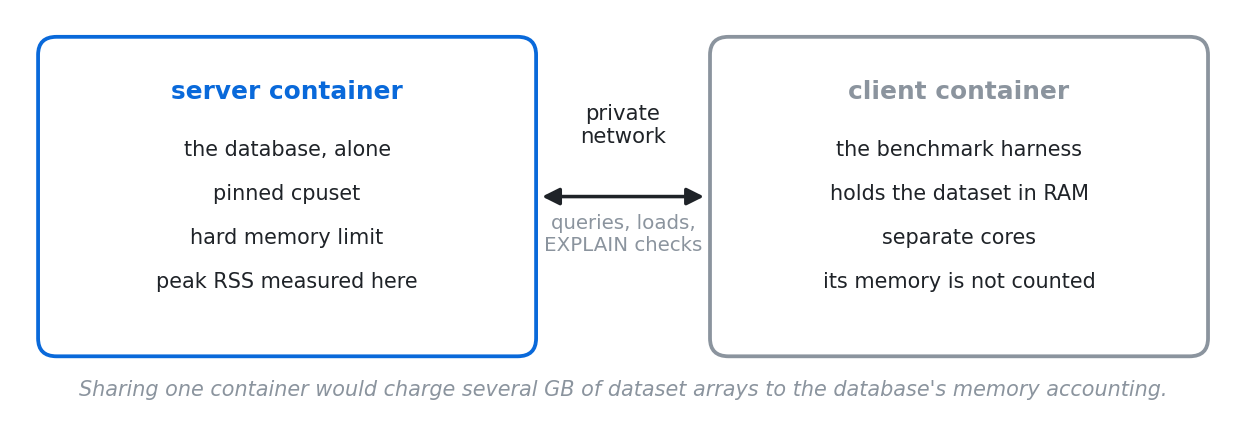
Peak memory comes from the server’s container, with the database as the only thing running in it. The harness runs in a separate container and reaches the server over a private network.

That separation matters more than it sounds. The client holds the entire dataset in memory, several GB of Python arrays. If it shared a container with the database, the container’s memory accounting would count those arrays as database memory, and every memory figure we published would be inflated by whatever the client happened to be holding.
Concurrency. QPS and latency percentiles from 1 to 32 clients. Engines cache their graphs in quite different ways and none of that shows up until clients start competing for the same cache. We report how much of the ideal speedup each engine actually got alongside raw QPS, because an engine that stops gaining throughput at 2 clients while its p99 gets 15 times worse is doing something very different from one that keeps scaling, and a throughput column on its own hides that completely.

Filtered search, at several selectivities down to 1% of rows passing. This is the case that’s supposed to justify keeping vectors in your database instead of a dedicated store, so it deserves more attention than it usually gets.

Filtering changes what “correct” means. The true top 10 among rows where tag < 10 is not the true top 10 overall, so for every selectivity we recompute ground truth by brute force over only the rows that pass. Score filtered results against the unfiltered ground truth that shipped with the dataset and every engine gets a recall near zero. We know, because we did exactly that for a while.

Some queries come back with fewer than 10 rows. In one run, 81 out of 200 did. This is not the data running out. At 10% selectivity about 99,000 rows pass the filter, so there are always at least 10 to find. The cause is the order of the operations. HNSW searches by distance first, then applies the WHERE clause. It gathers a few thousand candidates, the filter throws most of them away, and sometimes fewer than 10 are left. (If a filter really did match fewer than 10 rows, the ground truth shrinks too, and the engine still scores 1.0.) Recall already handles this. A row the engine did not return counts as a miss, so six correct rows score 0.6. We report the count because two different problems score the same. “10 rows, four of them wrong” and “six rows, all correct” are both 0.6. The first needs a wider search. The second needs iterative scanning. The count tells you which one you have. It also means the throughput is flattered, since six rows is less work than ten.

Churn. Recall and throughput before and after deleting and reinserting part of the corpus, since deletions leave graph edges pointing at rows that are gone. Whether rebuilding the index recovers what’s lost, we don’t know yet. It’s the obvious next thing to test and we haven’t done it.

Keeping the comparison fair

Everything runs twice.

The normalized pass gives every engine identical CPU, memory and cache budgets, so a difference in the results belongs to the implementation rather than to who was handed more RAM. The tuned pass lets each engine use the settings its own documentation recommends. Tuned is more realistic and less controlled, which is exactly why it doesn’t replace the first one. A result that survives both passes is about the engine. One that flips between them is interesting for a completely different reason.

Cores are pinned explicitly. One logical CPU per physical core, because SMT siblings share execution units and two threads on one core don’t behave like two cores. Never a mix of P-cores and E-cores on hybrid chips either, since migration between core types adds more variance than several of the effects we’re trying to measure. Durability is relaxed the same way everywhere, or we’d be comparing default fsync policies and calling it vector search.

Some differences can’t be equalised at all, so we write them down instead of pretending. A knob only one engine exposes goes unused in the normalized pass, because using it would hand that engine a tuning axis nobody else has. An engine that insists on a particular isolation level gets it set for everyone. And defaults that are obviously placeholders get sized from a shared budget — one family of engines still ships a 16 MiB graph cache, which is nothing, and judging an engine on a value its own vendor expects you to change measures absolutely nothing. All of these land in a “known asymmetries” section above the results.

One hardware note that catches people out. Several of these implementations ship hand-written AVX-512 code for the distance maths, where a single instruction does the arithmetic for 16 floats at once. The same index on a CPU without AVX-512 is effectively a different benchmark, and the slowdown isn’t the same for every engine, so you can’t even scale the numbers to compensate. The CPU model and its feature flags go into every run’s manifest for that reason, along with engine versions and commits, image IDs, and the resource limits as they are actually resolved rather than as we requested them. No manifest, no report.

Reading the results

Read the validity section before you look at a single chart. Our reports go environment, then validity, then known asymmetries, then results, in that order on purpose. A failed phase, an engine returning short result sets, a CPU missing the instruction set the engines wanted — all of it lands in front of you before you’ve formed an opinion.

The thing to watch for is the silent full scan.

Any of these engines will quietly stop using the vector index and scan the table instead. A scan returns exact results, slowly, so in the output it looks like high recall and low throughput. That’s indistinguishable from a conservatively tuned index unless you go and read the query plan.

It happens for thoroughly boring reasons. One engine’s optimizer costs the vector index against a table scan and takes the scan once the LIMIT is above roughly a quarter of the table, and we still haven’t found a setting that moves it. Another falls back with no error and no warning when the query asks for a different distance than the index was built for — build the index for cosine, write the query with the L2 operator, and you get a sequential scan and a sort, with nothing anywhere to tell you.

So every driver runs EXPLAIN for each configuration and checks the index name appears in the plan.

WARNING: vector index NOT used (k=10, filtered=True). Plan: …Seq Scan…

Anything that is scanned goes into validity. This is far and away the easiest way to produce impressive vector benchmark numbers by accident, and if a benchmark doesn’t mention checking for it, we’d want to know why before believing anything in it.

For recall against throughput, the useful presentation is a curve rather than a number. Iterate ef_search, plot recall against QPS, keep the best points: for each level of accuracy, the highest throughput anything reached at it. One engine beats another only where its curve sits above the other’s at the same recall. If the curves cross, then the answer genuinely depends on how accurate you need to be, and saying so is a result rather than a dodge.

Curves do invite comparing shapes instead of heights at one point, so there are bar charts as well, QPS at recall floors of 0.90, 0.95 and 0.99. Pick the accuracy you’d actually accept and read across.

Things that went wrong while we built this

Worth listing, partly because they’re the reason to trust anything else here, and partly because anyone building something similar will walk into them.

Our first ingest numbers were garbage. The load path was doing one INSERT per network round trip with autocommit on, and we measured 88 rows a second. Batching 500 rows per transaction took the same engine to 373. Publishing the first number would have been benchmarking our own client and calling it a database.

Filtered search and churn were scored against full-corpus ground truth even on runs that used a subset of rows. Every engine looked bad and the bug was entirely ours. Ground truth is now keyed on dataset, k, row count and selectivity.

Both resource passes shared one results directory, and the ANN runner skips configurations that already have results. So the tuned pass quietly skipped everything the normalized pass had computed, and our tuned numbers were mostly normalized numbers wearing a different label. That one took an embarrassingly long time to notice.

Readiness probes lie. One engine’s standard “are you accepting connections” check returns success before the database it’s supposed to create actually exists. The probe passed, the first query failed, and we spent a while convinced it was an engine problem.

The most recent one, on a 1536-dimension corpus. The ANN runner holds the whole dataset in memory twice, once in the parent process and again in a forked worker, and the copies aren’t shared. That’s roughly 12 GB for a million embeddings, on top of whatever the server is using, in a container we’d sized for the server alone. The kernel killed the worker. The runner doesn’t check worker exit codes, so it logged “Terminating 1 workers”, exited successfully and wrote no results — which looks exactly like a run that had nothing left to do. Three hours to fail, and it failed silently.

Adding a database

This is the part we cared most about getting right, because the whole point was to avoid rebuilding the apparatus every time somebody ships vector search. Each engine needs:

  • a Dockerfile producing a runtime image and a test image from a pinned version
  • a config declaring ports, credentials, and which server settings map onto the normalized CPU and memory budget
  • a module for the recall and throughput side
  • a driver: create index, load, query, filtered query, index size, and the EXPLAIN check

What’s next

Results, published with the manifests and the raw per-configuration records, so you can check them instead of taking our word for it.

Everything is at https://github.com/Percona-Lab/vector-bench harness, drivers, Dockerfiles, docs. If we’re measuring something wrong, or being unfair to an engine you know better than we do, tell us.

The post Benchmarking vector indexes appeared first on Percona.
Aug
27
2026
--

Performance Progression of Percona Server for MySQL 8.4

1. Purpose and scope

This performance investigation aims to look into the read/write performance of Percona Server for MySQL 8.4 and how it changed between versions released in 2026:

  • 8.4.8-8 released on 12 March 2026
  • 8.4.10-10 released on 30 June 2026
  • 8.4.11-11 released on 20 August 2026

We want to see if there are improvements in scalability and performance in OLTP read/write operations, where the improvements are most noticeable and how they were achieved. For some readers this material might help with making the decision whether upgrading to a newer version is worth the effort.

An important note is that the new features or security patches will not be taken into consideration.

Measuring Latency (Percentiles) and Resource Utilization (CPU, RAM, I/O) is not in the scope of this post.


2. Configuration and Methodology

The configuration was as follows:

Benchmark Sysbench OLTP Read-Write
CPU Intel Xeon Gold 6230 (2×20 cores, HT = 80 logical CPUs)
RAM 187 GiB DDR4
Storage NVMe SSD (2.9 TB) INTEL SSDPE2KE032T8
OS Ubuntu 24.04, kernel 6.8.0-60-generic
DB Engines Percona Server for MySQL 8.4.8-8 (release build)
Percona Server for MySQL 8.4.10-10 (release build)Percona Server for MySQL 8.4.11-11 (release build)

The benchmarks were done across the following dimensions:

Database Sizes (Row Number) 24Gb (100M rows) / 48Gb (200M rows) / 96Gb (400M rows)
Number of tables in DB Schema 20 (this number is constant for all runs)

Database Schema definition can be downloaded from here: 

https://percona-lab-results.github.io/2026-interactive-metrics/schema_dump.sql

Number of concurrent threads 1 / 4 / 16 / 32 / 64 / 128 / 256 / 512
Buffer to Data Ratio 1:12 (I/O bound), 1:2 (Partially buffered), 1:1 (Fully buffered)

One of the points in benchmarking was to create combinations of similar Buffer to Data Ratios, but with the different Database Sizes. This gives us the following possible combinations of innodb_buffer_pool_size and Database Size:

1:12 (I/O bound) innodb_buffer_pool_size = 2G, Data Size = 24Gb
innodb_buffer_pool_size = 4G, Data Size = 48Gb
innodb_buffer_pool_size = 8G, Data Size = 96Gb
1:2 (Partially buffered) innodb_buffer_pool_size = 12G, Data Size = 24Gb
innodb_buffer_pool_size = 24G, Data Size = 48Gb
innodb_buffer_pool_size = 48G, Data Size = 96Gb
1:1 (Fully buffered) innodb_buffer_pool_size = 32G, Data Size = 24Gb
innodb_buffer_pool_size = 64G, Data Size = 48Gb
innodb_buffer_pool_size = 128G, Data Size = 96Gb

We should be able to see how efficiently the server manages an increasingly larger number of rows while keeping the Buffer to Data Ratio the same.

Execution of the benchmarks was done as follows:

Ramp-up 24G – 600 sec (10 min) – could be shorter
48G – 600 sec (10 min)96G – 900 sec (15 min)

The Ramp-up times were established experimentally depending on the Data Size until the point when increasing them further did not bring significant changes.
Measurement window 900 sec (15 min)

Ideally it should be as long as possible, but measurements should take reasonable time. Hence, we used the experience of previous benchmarks and established that this window is adequate for the purpose.
Number of runs 3

For each combination there are multiple runs.
The interactive graph can show data for individual runs as well as averaged value.

Important Database Configuration options (the actual config files with specific settings for each run can be downloaded from the interactive graphs):

InnoDB – Buffer pool Tier
innodb_buffer_pool_size 2G/4G/8G/12G/24G/32G/48G/64G/128G
innodb_buffer_pool_load_at_startup OFF
innodb_buffer_pool_dump_at_shutdown OFF
Thread Pool
thread_handling pool-of-threads
thread_pool_size 80 # match physical core count
thread_pool_max_threads 2000
thread_pool_oversubscribe 3
Threading
thread_stack 512K
thread_cache_size 256
back_log 4096
InnoDB I/O
innodb_io_capacity 10000
innodb_io_capacity_max 20000
innodb_read_io_threads 16
innodb_write_io_threads 16
innodb_use_native_aio ON
InnoDB Log / Durability
innodb_log_buffer_size 256M
innodb_flush_log_at_trx_commit 1 # full ACID
innodb_doublewrite ON
InnoDB – Concurrency & OLTP Tuning
innodb_stats_on_metadata OFF
innodb_open_files 65536
innodb_lock_wait_timeout 50
innodb_rollback_on_timeout ON
Per-Session Buffers
sort_buffer_size     4M
join_buffer_size     4M
read_buffer_size     2M
read_rnd_buffer_size 4M
tmp_table_size       256M
max_heap_table_size 256M
Binary Log
disable_log_bin ON # Disabled binlog
Other InnoDB settings
innodb_redo_log_capacity     4G
innodb_change_buffering      none
innodb_flush_method          O_DIRECT
innodb_buffer_pool_instances Calculated as
(innodb_buffer_pool_size G / 5)
But must be in range [1..8]
Misc server settings
collation_server utf8mb4_unicode_ci
bulk_insert_buffer_size 256M
myisam_sort_buffer_size  128M
key_buffer_size          64M # MyISAM only, keep small for OLTP

In the high concurrency scenario when all CPU cores are working under maximum load the performance fluctuations might appear out of the ability of a specific CPU crystal to work at a specific sustainable maximum frequency. Intel Xeon Gold 6230 processors installed in the test servers have a base frequency of 2100 MHz and maximum turbo frequency of 3900 MHz. However, such turbo frequency can only be achieved for a short period of time on an isolated core. The load and the heat production of the physical core neighbours limit the frequency of the whole CPU. Some CPU’s were able to hold 2530 MHz on all cores for 20+ hours of intense load, others could only reach 2420 MHz. For consistency of the tests the turbo frequency was capped to 2400 MHz from the beginning on all servers. It helped to eliminate the struggle between turbo mode trying to increase the frequency beyond sustainable levels and the CPU thermal protection bringing the clock down. More stable hardware performance reduced the measurement fluctuations during the benchmark runs regardless if they were done on the same or a different physical server.


3. Results

First, let’s check the I/O bound scenario where the InnoDB Buffer to Data Size is the smallest (1:12).

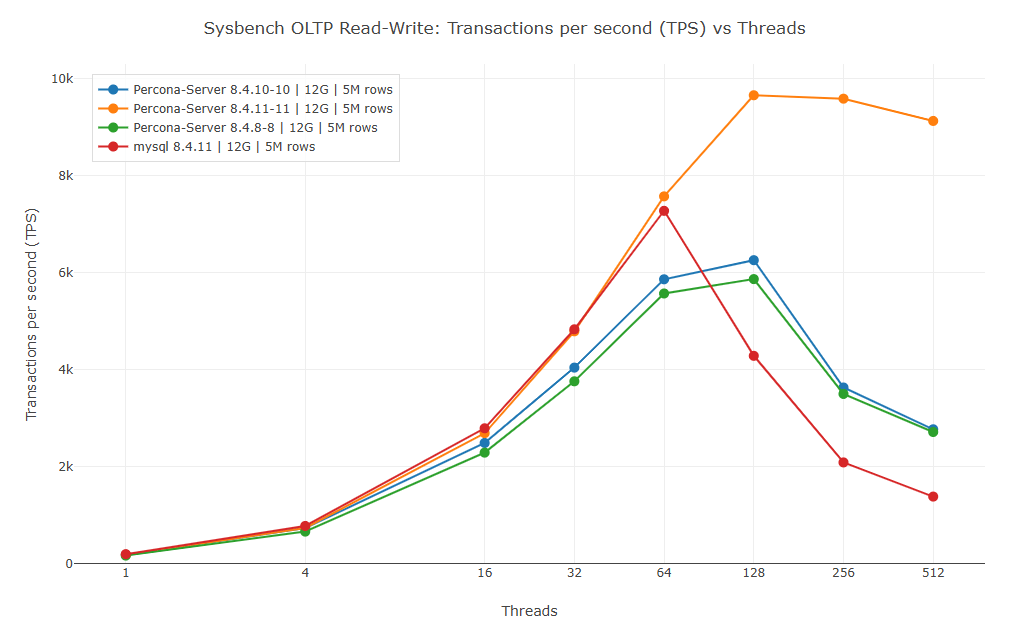
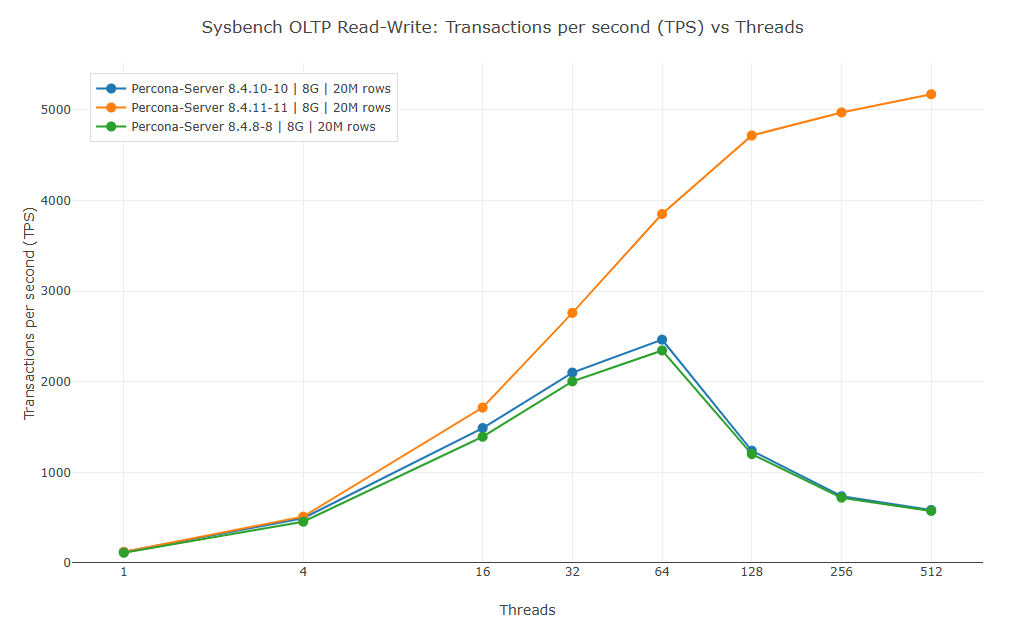
The graph shows the configurations with innodb_buffer_pool_size=8G and Data Size 96G (or 20M rows per table, 400M rows in total):


[ INTERACTIVE GRAPH ][ TABLE ]

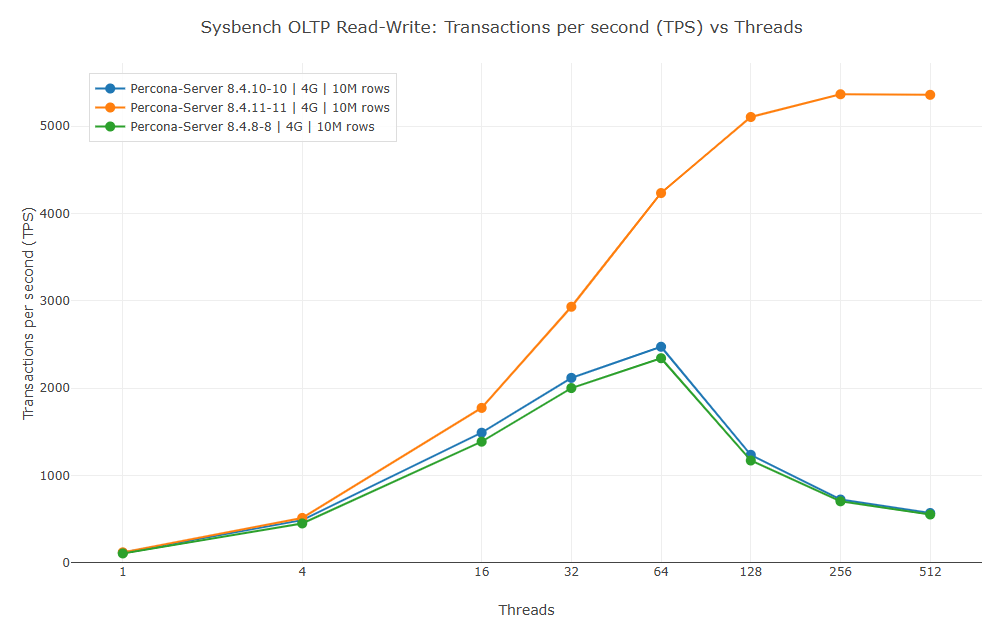
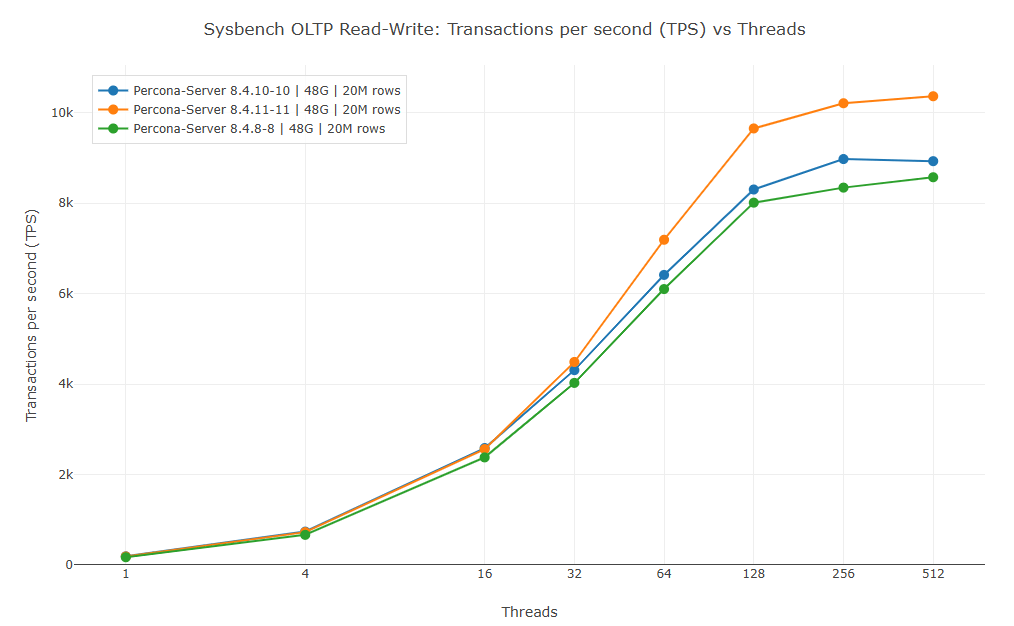
The first thing that catches the eye is the hugely superior performance of the version 8.4.11-11 over 8.4.10-10 and 8.4.8-8 in the high thread numbers. In the situations when the number of physical cores (80) is smaller than the number of threads (128+) the versions 8.4.10-10 and 8.4.8-8 have a steep performance degradation. However, the TPS for 8.4.11-11 keeps growing. This is due to the optimization done to InnoDB LRU pages flushing algorithm. The optimization specifically targeted the scenario when the data size is larger than the available server buffers and the server has many concurrent connections doing random read-write operations. The optimizations in 8.4.11-11 deserve a separate explanation and they will be published in another blog post.

The less noticeable, but important difference can be spotted between the TPS for 8.4.8-8 and 8.4.10-10.

The version 8.4.10-10 shows better performance (especially at the saturation point with 64 threads), which should mostly be attributed to the introduction of Performance Guided Optimization (PGO). 

More information on PGO can be found here:

https://docs.percona.com/percona-server/8.4/pgo.html

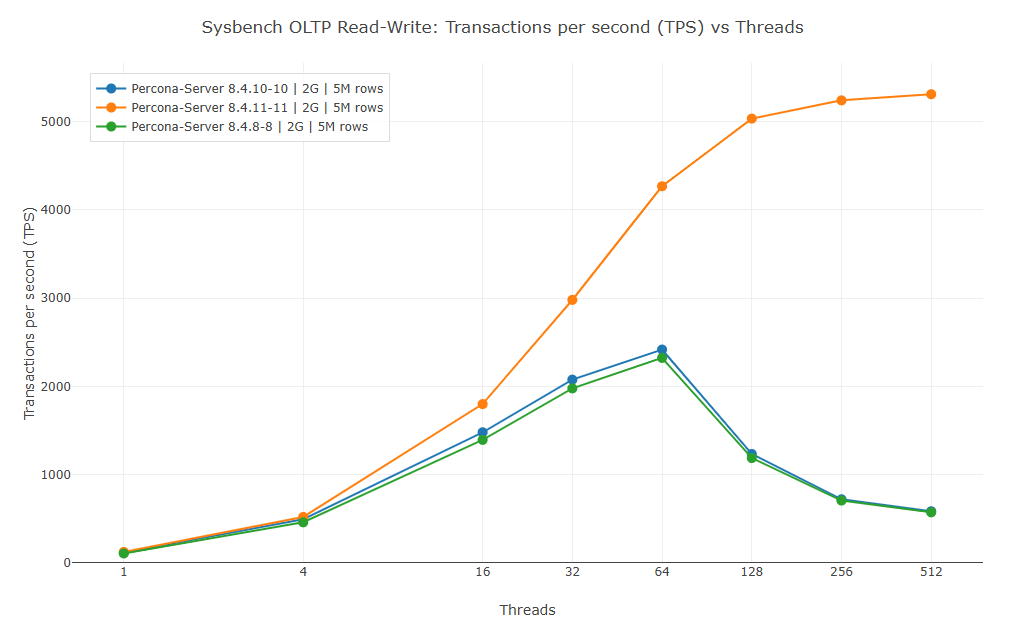
With the smaller data and buffer sizes the performance difference gives an almost identical picture:

4G buffer, 48G data [ INTERACTIVE GRAPH ][ TABLE ] 2G buffer, 24G data [ INTERACTIVE GRAPH ][ TABLE ]

Now let’s review what happens with the ratio 1:2.
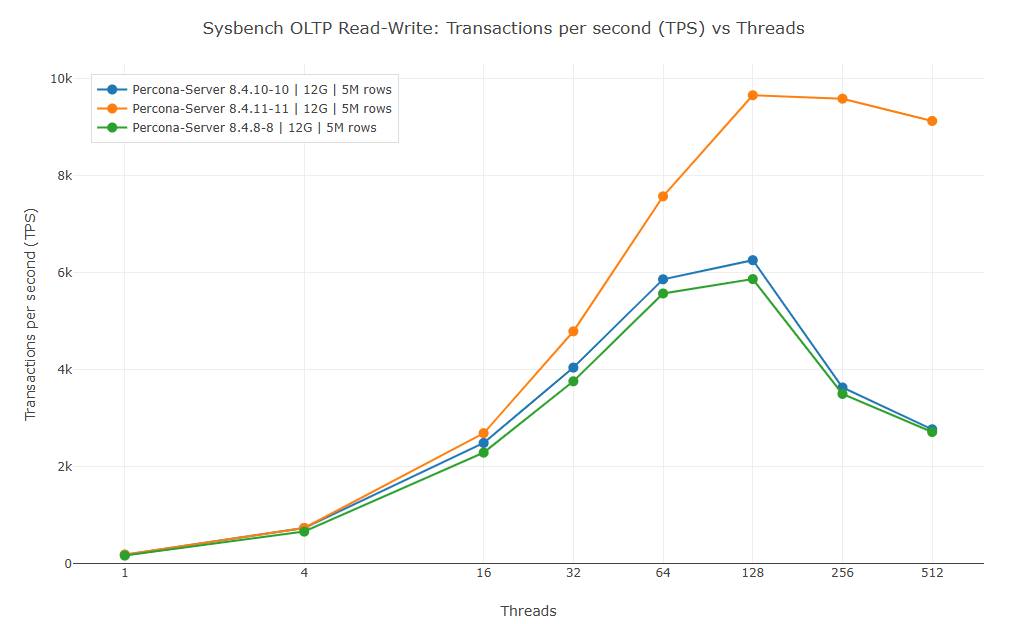
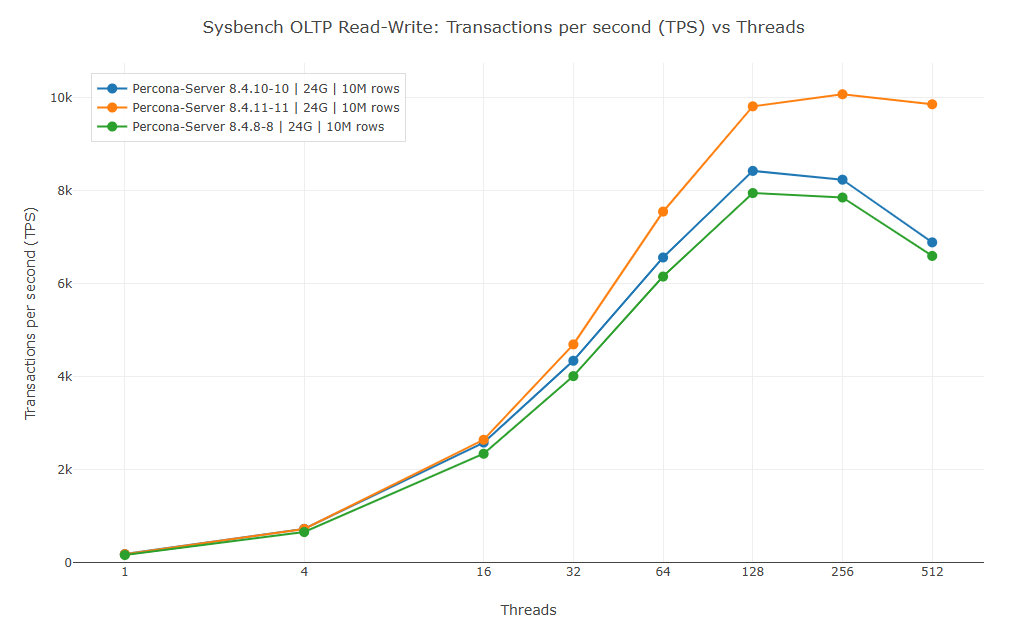
This time the buffer pool size also plays a more significant role and the performance difference is not characterized by the Buffer / Data size ratio.

With innodb_buffer_pool_size=12G and 24G data size the performance gap between 8.4.11-11 and older versions is still huge as can be seen on the graph:


[ INTERACTIVE GRAPH ][ TABLE ]

However, setting innodb_buffer_pool_size=24G and 48G data size reduces the gap. The superiority of 8.4.11-11 is still visible:


[ INTERACTIVE GRAPH ][ TABLE ]

Moving to innodb_buffer_pool_size=48G and 96G data size shrinks the gap even more:


[ INTERACTIVE GRAPH ][ TABLE ]

In this post we are not going to talk about mechanisms behind shrinking performance gaps in 1:2 Buffer / Data size ratio.

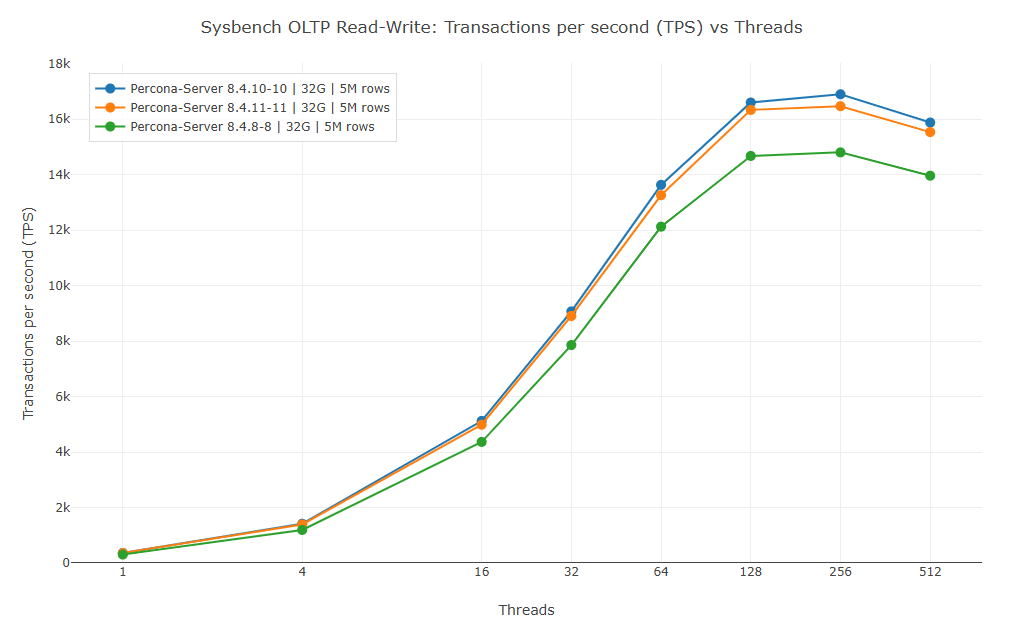
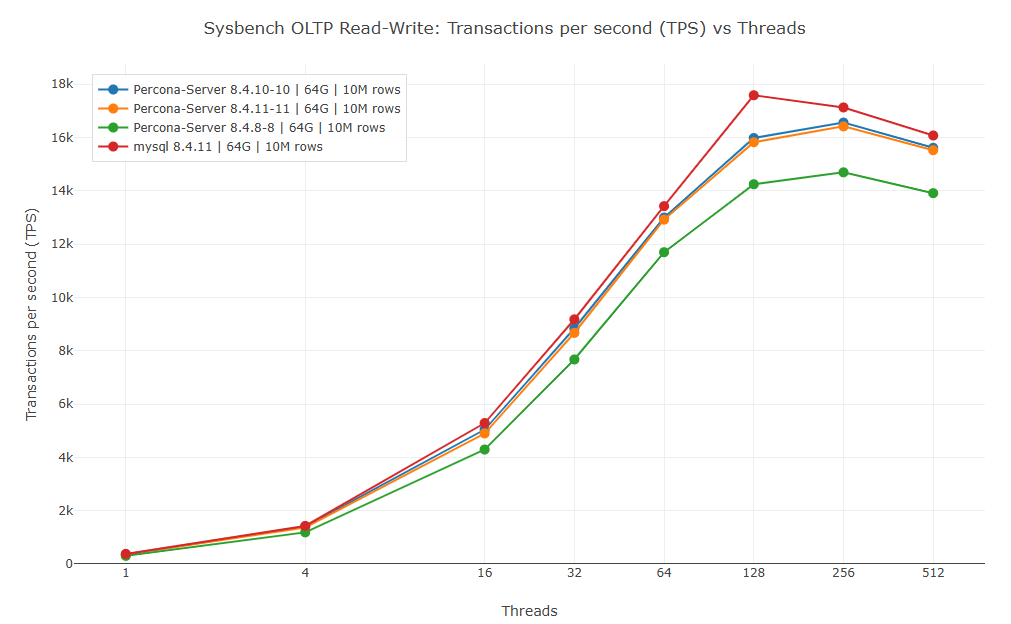
Holding the entire data set in memory is not the most common thing for the database server, but in some cases it happens. Therefore, we are covering such situations as well.


[ INTERACTIVE GRAPH ][ TABLE ]

As the above graph shows, 8.4.10-10 is slightly ahead of 8.4.11-11, but the gap is very small.

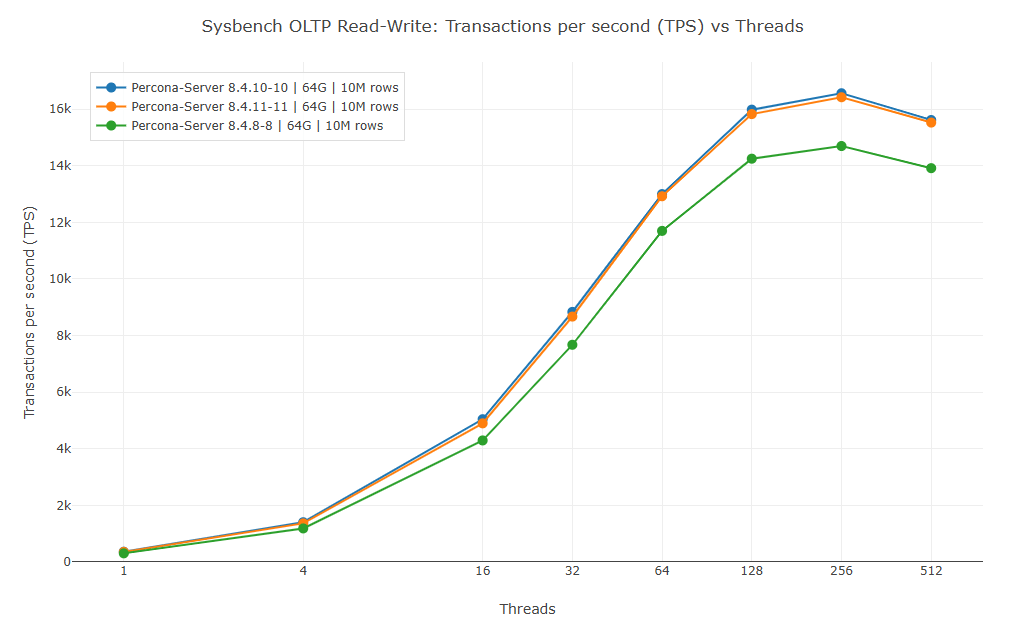
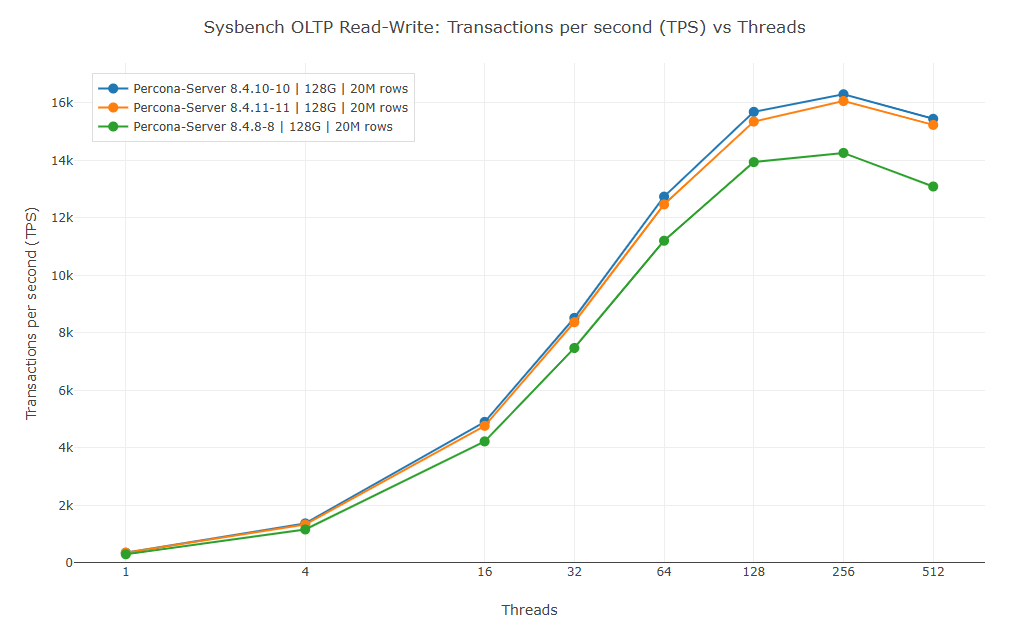
This behavior is consistent with other data sizes for fully buffered data:

innodb_buffer_pool_size=64G and 48G Data Size:


[ INTERACTIVE GRAPH ][ TABLE ]

innodb_buffer_pool_size=128G and 96G Data Size:


[ INTERACTIVE GRAPH ][ TABLE ]

Again, we will not go into details about why this happens. Though it is worth noting that both 8.4.10-10 and 8.4.11-11 do better than 8.4.8-8 in all runs and configurations.

The table interpretation of the results is available as well.


4. Comparing with Upstream MySQL 8.4.11.

The performance improvements in Percona Server for MySQL 8.4.11-11 are not a part of the Upstream MySQL 8.4.11. The patch was specifically designed to address the issue of Percona Server being slower than MySQL in I/O bound scenarios.

Also, the patch eliminated the abrupt performance degradation in the higher thread count after reaching the saturation point at 64 threads:

[ INTERACTIVE GRAPH ][ TABLE ]

As the graph shows – Percona Server 8.4.8-8 / 8.4.10-10 was slower than MySQL in lower thread count. Although it was still faster in 128+ threads, the Percona Server was still subject to a substantial slow-down. That is where Percona Server 8.4.11-11 really shines.

However, with the fully buffered data MySQL goes faster than any Percona Server:


[ INTERACTIVE GRAPH ][ TABLE ]

5. Summary

The Performance of the Percona Server 8.4 for MySQL is progressing well from older to newer version offering significant performance improvements especially in the version 8.4.11-11. This version shows very significant improvements in performance on the data sets that require I/O. Also, it outperformed the upstream MySQL 8.4.11.

With fully buffered data sets the version 8.4.10-10 is slightly better than 8.4.11-11. MySQL Server in this case shows the fastest performance.

The PGO had a positive impact demonstrating the version 8.4.10-10 being faster in all tests on all configurations than 8.4.8-8.

The performance depends not only on the ratio between the buffer and the data size, but also on the buffer size.

The post Performance Progression of Percona Server for MySQL 8.4 appeared first on Percona.

Aug
26
2026
--

Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in

These days there’s been a lot of talk about Postgres having an impact on “everything”. Whether it’s replacing legacy systems, creating a new greenfield project or even implementing it as a back-end to an agentic AI, Postgres is today’s poster child for innovation.

So performing something as dull and straightforward as a database migration should be easy, eh?

Well, not quite.

Its popular adoption and success has, in a sense, created a problem of its own making, which is otherwise known as the Walled Garden Effect.

The Walled Garden effect in open source is where software that is nominally open but a vendor, platform, or ecosystem has exerted control over its governance, distribution and compatibility in such a manner that its interaction with the same open source technology managed in another environment becomes problematic.

It’s an unfortunate reality that some commercial ecosystems built around Postgres can become walled gardens. Postgres itself remains open and portable, but its widespread adoption has also produced commercial ecosystems in which that portability can become progressively constrained.

At its most extreme; here are the risks of a Walled Garden to the Postgres end-user:

  • In the context of a Postgres offering from a cloud computing service offering DBaaS:
    • They “Control” the core platform, set the standards, and host the marketplace.
    • They “Acquire” developers, hardware manufacturers, and service providers who build products that add value to the core platform.
    • They “Convince” users to join the ecosystem whose data, attention, and capital eventually fuels the network’s growth.
    • The financial and cultural health of satellite vendors whose very existence is “Tied” directly to the decisions and policies made by the platform owner.
  • In the context of the technology used:
    • Modifying” the backend with unique attributes while enticing you with standard front-end protocols. A Postgres compatible interface does not necessarily imply Postgres equivalent portability. A service may emulate familiar SQL, drivers, and tools all the while introducing backend capabilities or operational dependencies that do not exist in community Postgres.
  • What it means over the life of your system:
    • As the ecosystem becomes more valuable to the user, it creates a greater “Disincentive” to exit.
    • If an exit strategy is undertaken:
      • High switching “Costs” can be incurred when migration introduces data-integrity risks and extraordinary complexity into what has become a tightly integrated workflow.
      • Extra “Expert” costs must be budgeted because specialized expertise may be required when vendor-specific features or dependencies exceed the experience of in-house staff.

        Working on past projects I’ve often found myself paraphrasing an old Eagles refrain “You can provision Postgres any time you like, but your architecture can never leave.

        While PostgreSQL itself is fully open-source and free, some vendors have created a Hotel California effect using these three specific mechanisms:

      • Proprietary Forks & Features: They offer “Postgres-compatible” databases. They add custom, closed-source performance layers or automated scaling. If you build your application to rely on these specific features, moving back to community Postgres can require a massive architecture rewrite.
      • Migration Cost Asymmetry: Moving data into an ecosystem can be relatively inexpensive. Moving that database to an alternate environment later can be considerably more complex.
      • Ecosystem Gravity: Databases do not sit in a vacuum. Once your Postgres instance is tightly integrated with a vendor’s proprietary backup systems, security roles (IAM), and serverless analytics tools, leaving the database can mean rebuilding your entire infrastructure. Postgres data can remain portable while the architecture surrounding it becomes progressively less portable.

        So what does it mean for you?

        While today’s database landscape can make vendor dependency seem unavoidable, it isn’t. There are still organizations that build commercial services around the principles that made open source successful in the first place: transparency, interoperability, portability, and the customer’s freedom to choose where and how their software runs. Percona is one example of a commercial model built around the premise that commercial expertise and open-source values do not have to be opposing ideas.

        Reference:
        https://arxiv.org/html/2409.01118v1 

The post Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in appeared first on Percona.

Aug
25
2026
--

Replication Lag on AWS FSx: The Hidden EC2 Single-Flow Bandwidth Limit

A recent case in our Percona Support team started with a familiar complaint. A PostgreSQL standby lagging behind its primary. Although the problem was simple, it brought a specific flavor that’s worth sharing.

The customer had already reached out to AWS Support about the storage layer behind the database, an Amazon FSx filesystem mounted over NFS on the standby’s EC2 instance. Let’s not stigmatize the infrastructure choice. It met the customer’s requirements, and they paid for provisioned resources to guarantee a performance baseline, a better starting point than many similar cases we see.

AWS confirmed that both the EC2 instance and the FSx filesystem looked healthy, with the filesystem sitting at roughly 50% of its provisioned capacity. From that angle, storage looked like a non-issue, and the investigation could easily have moved elsewhere in PostgreSQL.

We see this pattern often enough to call it out. A component reporting comfortable headroom relative to its provisioned limit does not mean the component isn’t the bottleneck. This post walks through what we found and why the standard utilization numbers didn’t show it.

The problem with looking at utilization alone

Provisioned IOPS and throughput numbers describe what a storage backend can deliver, regardless of what the path between the database host and that backend can actually carry.

An EC2 instance talking to FSx over NFS goes through several layers, including the instance’s own network bandwidth, the network path to the filesystem, and the filesystem’s own limits. Usually, monitoring dashboards only consider the last of those. If any of the other layers cap out below the provisioned limit, the system can become saturated even as every capacity dashboard still shows green.

That’s exactly what we found here.

Step 1. vmstat shows processes stuck waiting on I/O

The first signal came from vmstat. The “b” column reports the number of processes blocked waiting for I/O to complete. In a healthy system, “b” sits at zero most of the time, with occasional small blips, but not this time. The “wa” column was also consistently high across all samples, pointing to storage/network wait, while si/so stayed low, an early sign that memory wasn’t the initial suspect.

procs -------------memory------------ ---swap-- -----io---- ---system---- ------cpu-----
 r  b   swpd   free   buff  cache       si   so    bi    bo   in   cs     us sy id wa st
15 10 839168 1411800      0 199145760    7   18    14    25   23   21      7 15 61 17  0
 3 10 839424 1399408      0 199137696   12   84    12    84 198108 221859 11 18 50 20  0
 9  5 839424 1453656      0 199109952   12    4    12     8 206128 237222 10 17 51 22  0
10  7 839424 1412500      0 199134752   20    8    44     8 221809 252061 11 18 50 21  0
 8  7 839168 1439736      0 199120608   20   56    20    56 212175 236773 11 17 52 20  0
12  8 839424 1436540      0 199113056   28   72    28   544 212031 238994 11 18 51 19  0
 5  4 839680 1829036      0 198694080   32   96    32    96 176937 185345 10 16 53 21  0
 6  8 839680 1632944      0 198926912    0    0     0    28 213123 253983 10 16 55 19  0
14 15 843008 1677392      0 198866720    8 3620     8  3620 193275 227061 11 16 52 21  0
 5 14 843264 1639992      0 198931488    0  288     0   288 237257 273167 11 18 50 21  0

That was not an occasional blip. Across all the samples, we classified every reading:

awk '$1 ~ /^[0-9]+$/ && $2 ~ /^[0-9]+$/ { b=$2+0; n++; if (b==0) a++; else if (b<=5) c++; else if (b<=10) d++; else e++ } END { printf "b = 0      : %6d (%5.1f%%)\nb = 1-5    : %6d (%5.1f%%)\nb = 6-10   : %6d (%5.1f%%)\nb > 10     : %6d (%5.1f%%)\ntotal      : %6d\n", a,100*a/n, c,100*c/n, d,100*d/n, e,100*e/n, n }' vmstat.log
b = 0      :      1 (  0.6%)
b = 1-5    :     86 ( 47.8%)
b = 6-10   :     79 ( 43.9%)
b > 10     :     14 (  7.8%)
total      :    180

“b” was above zero in 99.4% of samples, and above 5 more than half the time. The CPU columns in the same output showed a consistent I/O wait (wa) value across all lines. Both point to a storage subsystem bottleneck, somewhere between the disk, the network, or the NFS server.

Step 2. nfsiostat sends mixed signals

nfsiostat displays NFS traffic by read and write operations, including latency. Looking at averages:

fs-xxxxxxxxxxxxxxxxx.fsx.us-east-1.amazonaws.com:/fsx mounted on /postgres/data1:

          ops/s       rpc bklog
      15927.396           0.000

read:              ops/s            kB/s           kB/op         retrans    avg RTT (ms)    avg exe (ms)  avg queue (ms)          errors
                7144.840      303386.959          42.462        0 (0.0%)           1.304          12.281          10.960       72 (0.0%)
write:             ops/s            kB/s           kB/op         retrans    avg RTT (ms)    avg exe (ms)  avg queue (ms)          errors
                3040.323       94332.387          31.027        0 (0.0%)           1.976         136.517         134.531        0 (0.0%)

Average write exe time is 136.52 ms, most of which (134.53 ms) is queue time. That’s already a red flag, as 136.52 ms is long enough for any modern storage system. Since most of the time is spent in the queue rather than in the actual round trip, the bottleneck doesn’t seem to be the underlying disks themselves.

Comparing peak and p95 usage against the provisioned limits looked fine at first:

grep -A1 '^read:' nfsiostat.log | awk '/^ +[0-9]/{print $2}' | tail -n +2 | sort -rn | \
awk -v prov=1280 'NR==1{max=$1}{v[NR]=$1} END{p95=v[int(NR*0.05)];
printf "NFS reads (%d x 1s samples) vs %d MB/s provisioned\n  PEAK : %7.0f MB/s (%.2f Gbit/s) = %2.0f%% of provisioned\n  p95  : %7.0f MB/s (%.2f Gbit/s) = %2.0f%% of provisioned\n  CEILING: no sample exceeds %.0f MB/s (p95 is within %.1f%% of peak)\n",
NR, prov, max*1024/1e6, max*1024*8/1e9, 100*(max*1024/1e6)/prov, p95*1024/1e6, p95*1024*8/1e9, 100*(p95*1024/1e6)/prov, max*1024/1e6, 100*(max-p95)/max}'

NFS reads (179 x 1s samples) vs 1280 MB/s provisioned
  PEAK :     626 MB/s (5.01 Gbit/s) = 49% of provisioned
  p95  :     623 MB/s (4.98 Gbit/s) = 49% of provisioned
  CEILING: no sample exceeds 626 MB/s (p95 is within 0.5% of peak)

grep -A1 'rpc bklog' nfsiostat.log | awk '/^ +[0-9]/{print $1}' | tail -n +2 | sort -rn | \
awk -v prov=80000 'NR==1{max=$1}{v[NR]=$1} END{
printf "NFS IOPS (%d x 1s samples) vs %d provisioned\n  PEAK : %6.0f ops/s = %2.0f%% of provisioned\n  p50  : %6.0f ops/s = %2.0f%% of provisioned\n",
NR, prov, max, 100*max/prov, v[int(NR*0.5)], 100*v[int(NR*0.5)]/prov}'

NFS IOPS (179 x 1s samples) vs 80000 provisioned
  PEAK :  33676 ops/s = 42% of provisioned
  p50  :  16170 ops/s = 20% of provisioned

49% of provisioned throughput and 42% of provisioned IOPS at peak. On paper, this storage subsystem has plenty of room left. This is the same conclusion AWS Support reached, and it’s a reasonable one to draw from these two numbers alone.

Step 3. The distribution tells a different story from the average

Peak and p95 only describe the top of the range. They don’t say how often the system sits there. So we built a distribution of every 1-second read throughput sample instead of collapsing it into a single peak or percentile:

grep -A1 '^read:' nfsiostat.log | awk '/^ +[0-9]/{print $2}' | tail -n +2 | \
awk '{g=$1*1024*8/1e9; b=int(g*4); c[b]++; n++; if(c[b]>mx)mx=c[b]}
END{printf "NFS read throughput distribution (%d x 1s samples)\n\n",n;
for(i=0;i<=21;i++) if(i in c){bar=""; w=int(c[i]*50/mx); for(j=0;j<w;j++) bar=bar "#";
printf "%4.2f-%4.2f Gbit/s |%-50s| %3d (%4.1f%%)\n", i/4, i/4+0.25, bar, c[i], 100*c[i]/n}}'

NFS read throughput distribution (179 x 1s samples)
1.25-1.50 Gbit/s |###                                               |   2 ( 1.1%)
1.50-1.75 Gbit/s |#######                                           |   4 ( 2.2%)
1.75-2.00 Gbit/s |#########                                         |   5 ( 2.8%)
2.00-2.25 Gbit/s |#                                                 |   1 ( 0.6%)
2.25-2.50 Gbit/s |#########                                         |   5 ( 2.8%)
2.50-2.75 Gbit/s |######################                            |  12 ( 6.7%)
2.75-3.00 Gbit/s |##############                                    |   8 ( 4.5%)
3.00-3.25 Gbit/s |###########################                       |  15 ( 8.4%)
3.25-3.50 Gbit/s |########################                          |  13 ( 7.3%)
3.50-3.75 Gbit/s |#####################################             |  20 (11.2%)
3.75-4.00 Gbit/s |##############################################    |  25 (14.0%)
4.00-4.25 Gbit/s |###################################               |  19 (10.6%)
4.25-4.50 Gbit/s |#########################                         |  14 ( 7.8%)
4.50-4.75 Gbit/s |##############                                    |   8 ( 4.5%)
4.75-5.00 Gbit/s |##################################################|  27 (15.1%)
5.00-5.25 Gbit/s |#                                                 |   1 ( 0.6%)

The single most common bucket among all samples is 4.75-5.00 Gbit/s, and no sample surpassed 5.01 Gbit/s, not a random peak but a ceiling. Every time the workload tried to push beyond 5 Gbit/s, it was capped at that rate instead of climbing further, which explains the queue time we saw in nfsiostat. The requests were piling up behind a virtual wall unrelated to the FSx filesystem’s provisioned throughput.

Step 4. The limit on the network path

A number that consistently caps out at 5 Gbit/s pointed us to networking limits rather than disk performance issues. According to AWS documentation, an r5n.8xlarge instance provides 25 Gbps of bandwidth. However, an EC2 instance can become a victim of what AWS calls “single-flow traffic” (a single TCP connection). This limitation caps network transfer bandwidth at 5 Gbps regardless of the EC2 instance’s total aggregate network bandwidth, and it applies to most of today’s EC2 instances.

One look at the mount confirmed a single flow was carrying everything:

fs-xxxxxxxxxxxxxxxxx.fsx.us-east-1.amazonaws.com:/fsx on /postgres/data1 type nfs4 (rw,relatime,vers=4.2,rsize=1048576,wsize=1048576,namlen=255,hard,fatal_neterrors=none,proto=tcp,timeo=600,retrans=2,sec=sys,clientaddr=10.0.0.10,local_lock=none,addr=10.0.0.20)

No nconnect option, which means a single TCP connection was carrying all NFS traffic between the EC2 instance and FSx. That single connection was subject to EC2’s single-flow bandwidth limit, not the instance’s aggregate limit, and definitely not the throughput FSx itself was provisioned for. The 25 Gbps the EC2 instance could theoretically use, and the 10.2 Gbps throughput FSx could theoretically deliver, were both irrelevant as long as everything moved through a single flow capped at roughly 5 Gbps.

This is why the AWS Support answer and the customer’s own checks weren’t wrong, but were just looking at the wrong layer.

The fix

NFS supports the nconnect mount option, which allows a client to multiplex operations across multiple TCP connections to the same NFS export rather than a single one. It’s supported on NFS v3, v4.0, v4.1, and v4.2, and available by default on modern Linux kernels (5.3+), with backports available on some enterprise distributions. AWS itself documents and suggests using nconnect when possible:

sudo mount -t nfs -o nconnect=16 filesystem_dns_name:/vol_path /localpath

We recommended reviewing the nconnect configuration with their own infrastructure team or AWS Support, since this is a network and infrastructure configuration decision, not a PostgreSQL one. We did not commit to a specific nconnect value, not because we didn’t want to, but because properly benchmarking it would require resources and access our team didn’t have. 

The customer came back after setting nconnect=16 and reported that the lag immediately started to close. That’s a good outcome, but the value itself probably deserves a second look. Any value greater than the default of a single connection would have shown improvements right away in this capped environment. However, sixteen connections (16*5 Gbps each) is a theoretical maximum of 80 Gbps, far beyond both endpoints in this setup, the EC2 instance’s own 25 Gbps aggregate limit, and the 10.2 Gbps FSx filesystem’s own provisioned throughput.

Two connections would theoretically already reach close to the FSx throughput ceiling, and three would cover it with a comfortable buffer. Going straight to sixteen removed the bottleneck, but it also means the OS is maintaining far more resources with no measurable benefit.

Parallelism doesn’t scale as a clean multiplication of a single connection’s throughput. Other resources, on both the client and server sides, become part of the equation as concurrency increases. As with any other piece of infrastructure or software, finding the right number requires proper benchmarking.

As a database support team, our role was to identify and prove the cause behind the lag, provide the evidence, and propose a possible path forward.

Conclusion

A component reporting low utilization against its provisioned limit doesn’t rule out an I/O bottleneck elsewhere in the path, it only rules out that specific limit. In this case, FSx itself was never the problem. The actual constraint was the single-flow network bandwidth cap between the EC2 instance and its FSx filesystem, throttling every request that went through it.

Two things are worth carrying into the next investigation, like this one. First, vmstat’s “b” column and a sustained “wa” value are cheap and fast signals that something downstream of PostgreSQL is the bottleneck, before diving into storage-specific tooling. Second, when checking a metric against a provisioned limit, consider the full distribution of samples, not just the peak or a single percentile. A value that repeatedly hits the same ceiling (even one well below the provisioned maximum) is a stronger signal than a single peak value.

The post Replication Lag on AWS FSx: The Hidden EC2 Single-Flow Bandwidth Limit appeared first on Percona.

Aug
25
2026
--

Software Bill of Materials in Percona Server for MongoDB

Introduction

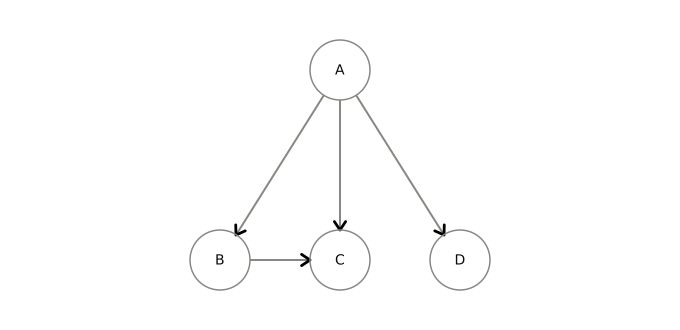
A software bill of materials (SBOM) offers end users enhanced supply chain visibility, thereby facilitating license compliance and timely vulnerability detection. An SBOM of an application, library, or framework (collectively referred to as a “component”) is a machine-readable document that enumerates all other components it incorporates, including transitive ones. In this way, an SBOM represents the dependency graph of a particular component. For each component, including the one for which the SBOM is created, it provides the component’s specific version and license.

Given the dependency graph in the figure below, the SBOM for component A would include components B, C, and D. In addition, the SBOM would list each relationship between components (depicted as arrows in the figure) in its “dependencies” section.

Periodic SBOM scans

Given an SBOM file for a component, one can scan it for vulnerabilities with one of the many available tools. If the tool doesn’t show any, it can be tempting to declare that we are safe and forget about the SBOM until the next version of the component in question is released, together with a new SBOM. That, however, would be a mistake.

SBOM scanning tools have two data inputs. The first one is an SBOM itself. It is passed to the tool explicitly and typically doesn’t change over time for a particular component version. The second data input is the complete opposite: it is implicit and updated daily or even more often. We are talking about the vulnerability database(s). SBOM scanning tools download the updates to the vulnerability database(s) before each SBOM scan. The same scan command, using the same SBOM file that previously reported no vulnerabilities, can easily report serious vulnerabilities in an hour.

That is why it is important to run scans periodically to be notified of new vulnerabilities in a timely manner and to start remediation before the component’s maintainers prepare a fix. This is especially true in the era of AI-assisted vulnerability discovery, which often leaves maintainers overloaded with vulnerability reports, so fixing takes longer than before.

SBOMs in Percona Server for MongoDB

Since versions 7.0.39-21, 8.0.28-12, and 8.3.7-1, Percona Server for MongoDB (further referred to as PSMDB) provides SBOMs in its binary packages. In Debian and RPM packages, one can find the SBOM in the /usr/share/doc/percona-server-mongodb-server/sbom.cdx.json file once the percona-server-mongodb-server package is installed. In the binary tarball, the SBOM is located at doc/sbom.cdx.json relative to the tarball’s root directory. As you might have already guessed, the cdx extension in the filename indicates that the SBOM is in the CycloneDX format.

Percona Server for MongoDB also provides two SBOMs for its Docker images. The first one covers PSMDB exclusively and is embedded in the image’s filesystem at the same /usr/share/doc/percona-server-mongodb-server/sbom.cdx.json path. It is the same SBOM as in the corresponding RPM package. The second one covers the image as a whole, including the base OS, libraries and utilities installed on top of it, and so on. This SBOM considers PSMDB as a dependency, and is associated with the Docker image as an OCI artifact.

Since PSMDB’s second SBOM differs little from other OCI-attached SBOMs in how it is scanned, we won’t discuss it here. One can refer to the documentation for detailed instructions and examples. Instead, the rest of the post focuses on the first SBOM: the one that is included in a Debian package, an RPM package, and a binary tarball, and embedded in the Docker image.

Scanning the SBOM

One can scan PSMDB’s SBOM with grype as follows:

grype --distro ubuntu:24.04 sbom:/usr/share/doc/percona-server-mongodb-server/sbom.cdx.json

Clearly, they need to pass the distribution name and version they run PSMDB on, e.g.: —distro rhel:9.8.

One can also use OWASP Dependency Track. Instead of being a command-line utility, Dependency Track is a fully fledged GUI-based service. Nevertheless, deploying it is as easy as two shell commands:

curl -fsSLO https://dependencytrack.org/docker-compose.yml
docker compose up -d

Then, do the following:

  • Go to http://localhost:8080 and authenticate with username admin and password admin
  • Change the password and reauthenticate with the username admin and the new password
  • In the left pane, select “Projects” and then click the “Create Project” button
  • After creating the project, click on its name and select the “Component” tab
  • Click the “Upload BOM” button and upload the “sbom.cdx.json” file

At the time of writing, Grype and OWASP Dependency Track are the only tools we are aware of that can scan PSMDB’s SBOM. Other popular options, notably Trivy, skip analysis of the most PSMDB dependencies in the SBOM. This is the result of the approach to dependency management that PSMDB has to follow.

Evaluating Scanning Results

Running Grype as shown above on the SBOM from PSMDB version 7.0.39-21 gives quite a scary report (redacted for length):

$ grype --distro ubuntu:24.04 \
    sbom:/usr/share/doc/percona-server-mongodb-server/sbom.cdx.json
NAME                          INSTALLED  VULNERABILITY   SEVERITY  EPSS
unicode-org/ICU4C             57.1       CVE-2016-7415   Critical  5.8% (92nd)
unicode-org/ICU4C             57.1       CVE-2017-14952  Critical  5.1% (91st)
unicode-org/ICU4C             57.1       CVE-2016-6293   Critical  5.0% (91st)
unicode-org/ICU4C             57.1       CVE-2017-17484  Critical  4.6% (90th)
unicode-org/ICU4C             57.1       CVE-2017-7867   High      4.6% (90th)
unicode-org/ICU4C             57.1       CVE-2017-7868   High      4.4% (90th)
unicode-org/ICU4C             57.1       CVE-2020-10531  High      2.7% (84th)
unicode-org/ICU4C             57.1       CVE-2017-15422  Medium    2.5% (82nd)
unicode-org/ICU4C             57.1       CVE-2017-15396  Medium    2.2% (80th)
libtom/LibTomCrypt            1.18.2     CVE-2019-17362  Critical  3.1% (86th)
google.opensource/Protobuf    3.19.5     CVE-2024-7254   High      2.8% (84th)
c-ares/c-ares                 1.19.1     CVE-2024-25629  Medium    0.3% (27th)
pcre2/PCRE2                   10.40      CVE-2022-41409  High      1.1% (63rd)
google.opensource/gRPC (C++)  1.46.6     CVE-2026-33186  Critical  1.6% (72nd)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-44487  High      100.0% (99th)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-4785   High      0.7% (48th)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-33953  High      0.5% (38th)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-32732  Medium    0.5% (41st)
mongodb/mongodb/mongo         7.0.39     CVE-2017-2665   High      0.3% (25th)
mongodb/mongodb/mongo         7.0.39     CVE-2014-8180   Medium    0.3% (19th)
mongodb/MongoDB C Driver      1.27.6     CVE-2026-6231   High      0.2% (8th)
mongodb/MongoDB C Driver      1.27.6     CVE-2025-12119  Low       0.2% (10th)
mongodb/MongoDB C Driver      1.27.6     CVE-2026-4359   Low       0.2% (8th)

The first thing to note about the results above is that PSMDB version 7.0.39-21 does not introduce all those vulnerabilities. They have existed for a long time in the 7.0 version series; the SBOM and the scanning tools only made them visible.

We can start sorting out this pile of vulnerabilities with the critical CVE-2026-33186 in the gRPC framework. If we read its description, we will learn that it affects only the Go implementation of the framework. The C++ implementation used in PSMDB is hosted in a separate repository (https://github.com/grpc/grpc, as opposed to https://github.com/grpc/grpc-go) and is not affected by the vulnerability. But why did Grype report it then? We believe that is a result of the quite wide Common Platform Enumeration (CPE) of this component in the SBOM file:

cpe:2.3:a:grpc:grpc:1.46.6:*:*:*:*:*:*:*

In the CVEs page, CPE is cpe:2.3:a:grpc:grpc:*:*:*:*:*:go:*:* stating that only Go code is vulnerable. So the SBOM’s CPE matched the CVE’s CPE, making Grype report the vulnerability, though it is a false positive in reality.

Another gRPC vulnerability, CVE-2023-44487, does not apply to Percona Server for MongoDB either. It is exploitable only if the support of the alternative gRPC-based wire-protocol transport is enabled during the build process. It is disabled by default, though, and Percona has never enabled it.

Next, let us look at the critical CVE-2016-7415 in ICU4C, which is a C/C++ library for handling Unicode. The CVE correctly points out that version 57.1 is vulnerable to a buffer overflow. However, the PSMDB codebase has local fixes for this and other ICU4C-related CVEs. This is still version 57.1, but with fixes applied.

Finally, consider the critical vulnerability CVE-2019-17362 in LibTomCrypt. Its description says the issue is in the der_decode_utf8_string function in the der_decode_utf8_string.c file. However, Percona Server for MongoDB codebase does not even include the file: only a small part of LibTomCrypt is vendored into the PSMDB codebase, leaving der_decode_utf8_string.c aside. That brings us to the conclusion that the vulnerability does not actually affect Percona Server for MongoDB.

False Positives and Paranoia

By now, you have probably noticed a pattern here. Many of the reported CVEs are false positives, meaning that they are reported but don’t actually affect PSMDB. One may argue that Grype produces too many of them. But there are a couple of reasons for that. First, Grype could not know about local patches for some components, components excluded from the build, or partially vendored components.

Second, if we consider the “paranoia spectrum”, where the left extreme is total naivety and the right one is being suspicious even in innocent cases, it is perfectly reasonable for a security tool to lean to the right end. In our use case, that means reporting false-positive results and leaving the analysis to a human being is a much safer choice than omitting a potential issue that could turn into a serious security breach.

Vulnerability Exploitability Exchange

Repeating the analysis we showed above for each reported CVE on the user side is tedious and sometimes difficult. In theory, a user could realize CVE-2026-33186 (an issue in the Go code) and CVE-2019-17362 (an issue in the code that doesn’t actually exist in PSMDB) are false positives. But it would be unreasonable to expect a user to dig into the internals of Percona Server for MongoDB to discover that some code is excluded from the build (CVE-2023-44487) or has local patches (CVE-2016-7415).

That is why the developers of Percona Server for MongoDB conducted the analysis themselves and prepared its results as a Vulnerability Exploitability eXchange (VEX) document. Each Percona Server for MongoDB release that comes with an SBOM file (versions 7.0.39-21, 8.0.28-12, and 8.3.7-1 and above) also has a corresponding VEX document located at https://percona.github.io/percona-server-mongodb/vex/percona-server-mongodb-<version>.vex.json. Below is an example of downloading the VEX document and using it in Grype to filter out false positives for version 7.0.39-21 (redacted for length):

$ curl -fsSLO https://percona.github.io/percona-server-mongodb/vex/percona-server-mongodb-7.0.39-21.vex.json
$ grype --distro ubuntu:24.04 \
    --vex=percona-server-mongodb-7.0.39-21.vex.json \
    sbom:/usr/share/doc/percona-server-mongodb-server/sbom.cdx.json
NAME                      INSTALLED  VULNERABILITY  SEVERITY  EPSS
mongodb/MongoDB C Driver  1.27.6     CVE-2026-6231  High      0.2% (8th)

We can see that after taking a VEX document into account, only one vulnerability that actually affects PSMDB remains. What is more, a VEX document can list not only those vulnerabilities that don’t affect particular software but also those that actually do. In our case, percona-server-mongodb-7.0.39-21.vex.json says that CVE-2026-6231 would affect PSMDB only if Queryable Encryption (aka Field Level Encryption) is enabled. As a side comment, at Percona, we plan to eliminate that vulnerability in the future.

The dependency on MongoDB Community Edition

An attentive reader could have probably noticed that scanning the SBOM of Percona Server for MongoDB version 7.0.39-21 reported a couple of vulnerabilities in mongodb/mongodb/mongo, also version 7.0.39, which can look strange, but it is actually not. Percona Server for MongoDB is a fork and a drop-in replacement of MongoDB Community Edition. That is the reason every vulnerability that affects the latter also affects the former. Percona Server for MongoDB having a “dependency” on MongoDB Community Edition enables SBOM scanning tools to detect vulnerabilities in the MongoDB Community Edition code itself, in addition to those in its dependencies.

Shared Libraries

Even if an SBOM scanning tool had shown no CVEs after being passed a VEX file, we still can’t conclude that our PSMDB deployment is free from known vulnerabilities. That is because an SBOM file can’t cover dependencies linked to Percona Server for MongoDB at runtime as shared libraries. Their specific versions are governed by a particular OS and can change over time. Even if the PSMDB package for a particular OS version included shared libraries specifying their versions at build time, any upgrade of the packages on the machine where PSMDB is installed could make those versions incorrect.

In addition to periodically scanning the Percona Server for MongoDB SBOM, we recommend that users download and scan the SBOMs for the shared libraries that Percona Server for MongoDB directly links to at runtime. At the time of writing, those libraries are:

Name Typical Linked Library Filename(s)
GNU C Library libc.so.6, libm.so.6, libresolv.so.2, etc.
GCC Support Library libgcc_s.so.1
libcurl libcurl.so.4
Cyrus SASL libsasl2.so.2
Kerberos 5 GSS-API libgssapi_krb5.so.2
OpenLDAP liblber.so.2, libldap.so.2
OpenSSL libcrypto.so.3, libssl.so.3

Please note version numbers in library filenames above (e.g. 6 in libc.so.6). They are just examples and can differ from platform to platform.

Conclusion

Percona Server for MongoDB has provided SBOM and VEX documents since versions 7.0.39-21, 8.0.28-12, and 8.3.7-1, giving users better visibility into its supply chain for both licensing and security. Regularly scanning PSMDB’s SBOM, along with the SBOMs of the shared libraries it links to, helps operators detect potential vulnerabilities and begin remediation before they become security breaches.

The post Software Bill of Materials in Percona Server for MongoDB appeared first on Percona.

Aug
20
2026
--

Talking Drupal #566 – DrupalEasy: Responsible Drupal AI

Today we are talking about Drupal, AI, and learning to use it responsibly with guest Mike Anello. We’ll also cover Entity Mesh as our module of the week.

For show notes visit: https://www.talkingDrupal.com/566

Topics

  • Course overview
  • Fast moving modules
  • Inside vs outside AI
  • No code approach
  • Keeping curriculum current
  • Essentials vs add ons
  • Chat Claude Code setup
  • Inside vs Outside AI
  • Rules and Provider Calls
  • Guardrails in Drupal UI
  • Model QA and Testing
  • Local Models and Costs
  • Token Budgets and Logging
  • Course Use Cases Overview
  • RAG and Vector Basics
  • Class Schedule and Pricing
  • AI Predictions and Wrap

Resources

Guests

Mike Anello – drupaleasy.com ultimike

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi JD Flynn – dorficus

MOTW Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

  • Brief description:
    • Have you ever wanted a way to analyze and visualize the ways in which the content on your Drupal site is interlinked? There’s a module for that.
  • Module name/project name:
  • Brief history
    • How old: created in Jan 2025 by Jorge Tutor (gedur) of Metadrop
    • Versions available: 2.1.0 and 2.0.3, both of which work with Drupal 11
  • Maintainership
    • Actively maintained, latest release last month, and a commit just yesterday
    • Security coverage
    • Test coverage
    • Documentation? Project page is pretty descriptive
    • Number of open issues: 13 open issues, 4 of which are bugs, but 2 of those were marked fixed in the past week
  • Usage stats:
    • 437 sites
  • Module features and usage
    • With Entity Mesh installed, the module will analyze the rendered output of your nodes using a chosen account, looking for links to other content
    • That means it will find not just links in entity relationship fields, but also links within formatted text, menus, and more
    • The results can be visualized in a D3.js 3D visualization, displayed as a table, or exported as a CSV
    • The report also exposes a set of Views-style filters, to help you narrow down to the specific set of information you want to understand
    • Entity Mesh analyzes the DOM of your rendered nodes, looking for links, iframes, and images. Internal paths are further analyzed and categorized, for example based on whether the specified path redirects, is broken, points to something that is access-denied, and so on
    • From a marketing perspective, that allows you to understand the paths available to navigate from a source page to a target page, the content linked to or from a specific page, and will also augment the content deletion confirmation form to advise the user of any existing links to the content being deleted
    • There are obvious SEO advantages to being able to find redirect chain, broken or access denied links, and there are GDPR compliance implications for being able to identify iframes that might load third-party cookies
    • The project page also mentions that this module could be very useful to run after a content migration, for QA
    • The actual analysis of your site content be triggered by drush, an admin form, or by cron, and you can set limits on the size of the batch to run, because of the weight it puts on your site by rendering every node it analyzes
    • The current versions Entity Mesh also depend on the Entity Registry and Entity Render Context modules, that have essentially the same maintainers, so if there’s only part of Entity Mesh that you really need, you could also give those a look
    • Back in episode #321 we covered Entity Usage, and there are some definite similarities, but also some differences. While they both provide reporting on content relationships, Entity Usage does so by examining structured field values at save time. So, the information gathered is different, and collects data that can be displayed in views or custom code.
Aug
20
2026
--

Talking Drupal #566 – DrupalEasy: Responsible Drupal AI

Today we are talking about Drupal, AI, and learning to use it responsibly with guest Mike Anello. We’ll also cover Entity Mesh as our module of the week.

For show notes visit: https://www.talkingDrupal.com/566

Topics

  • Course overview
  • Fast moving modules
  • Inside vs outside AI
  • No code approach
  • Keeping curriculum current
  • Essentials vs add ons
  • Chat Claude Code setup
  • Inside vs Outside AI
  • Rules and Provider Calls
  • Guardrails in Drupal UI
  • Model QA and Testing
  • Local Models and Costs
  • Token Budgets and Logging
  • Course Use Cases Overview
  • RAG and Vector Basics
  • Class Schedule and Pricing
  • AI Predictions and Wrap

Resources

Guests

Mike Anello – drupaleasy.com ultimike

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi JD Flynn – dorficus

MOTW Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

  • Brief description:
    • Have you ever wanted a way to analyze and visualize the ways in which the content on your Drupal site is interlinked? There’s a module for that.
  • Module name/project name:
  • Brief history
    • How old: created in Jan 2025 by Jorge Tutor (gedur) of Metadrop
    • Versions available: 2.1.0 and 2.0.3, both of which work with Drupal 11
  • Maintainership
    • Actively maintained, latest release last month, and a commit just yesterday
    • Security coverage
    • Test coverage
    • Documentation? Project page is pretty descriptive
    • Number of open issues: 13 open issues, 4 of which are bugs, but 2 of those were marked fixed in the past week
  • Usage stats:
    • 437 sites
  • Module features and usage
    • With Entity Mesh installed, the module will analyze the rendered output of your nodes using a chosen account, looking for links to other content
    • That means it will find not just links in entity relationship fields, but also links within formatted text, menus, and more
    • The results can be visualized in a D3.js 3D visualization, displayed as a table, or exported as a CSV
    • The report also exposes a set of Views-style filters, to help you narrow down to the specific set of information you want to understand
    • Entity Mesh analyzes the DOM of your rendered nodes, looking for links, iframes, and images. Internal paths are further analyzed and categorized, for example based on whether the specified path redirects, is broken, points to something that is access-denied, and so on
    • From a marketing perspective, that allows you to understand the paths available to navigate from a source page to a target page, the content linked to or from a specific page, and will also augment the content deletion confirmation form to advise the user of any existing links to the content being deleted
    • There are obvious SEO advantages to being able to find redirect chain, broken or access denied links, and there are GDPR compliance implications for being able to identify iframes that might load third-party cookies
    • The project page also mentions that this module could be very useful to run after a content migration, for QA
    • The actual analysis of your site content be triggered by drush, an admin form, or by cron, and you can set limits on the size of the batch to run, because of the weight it puts on your site by rendering every node it analyzes
    • The current versions Entity Mesh also depend on the Entity Registry and Entity Render Context modules, that have essentially the same maintainers, so if there’s only part of Entity Mesh that you really need, you could also give those a look
    • Back in episode #321 we covered Entity Usage, and there are some definite similarities, but also some differences. While they both provide reporting on content relationships, Entity Usage does so by examining structured field values at save time. So, the information gathered is different, and collects data that can be displayed in views or custom code.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com