Aug
27
2026
--

Benchmarking vector indexes

Nearly every database has vector search now, and every one of them has a blog post with a big number in it. Almost none of those numbers can be checked, because the thing that makes them meaningful is usually missing.

We built a vector-bench to stop guessing. You name the engines you want, build them from pinned versions, put each one in the same container on the same cores with the same data, run the same measurements against all of them, and write a report. This post is about how it measures.

If you work with databases but haven’t touched vectors yet, the first half is the part you need.

What’s being indexed

An embedding is a fixed-length array of floats that comes out of a model. The useful property is that semantically similar inputs land close together when you measure the distance between them.

Two distance measures cover almost everything. L2 is an ordinary straight-line distance, the Pythagorean one, extended to however many dimensions you have. Cosine Similarity  measures the angle between two vectors and ignores their length. Which one applies is decided by the model that produced the embeddings. It isn’t a choice you get to make at query time, and getting it wrong is a good way to produce nonsense.

So the query you want is “the 10 rows whose vectors are nearest this one”:

SELECT id FROM documents ORDER BY distance(embedding, ?) LIMIT 10;

That 10 is k.

Now the problem. Answering that exactly means computing the distance from your query vector to every single row, then sorting. No B-tree or hash index helps, because neither one can order a million points by proximity in 1536 dimensions. Exact vector search is a full table scan with a lot of arithmetic bolted on.

A vector index gives up exactness to avoid that. It looks at a few thousand promising candidates instead of every row and returns the best it found. That’s the approximate nearest neighbour search, or ANN. It’s usually right.

“Usually” is doing a lot of work in that sentence, and pinning it down is most of what this benchmark does.
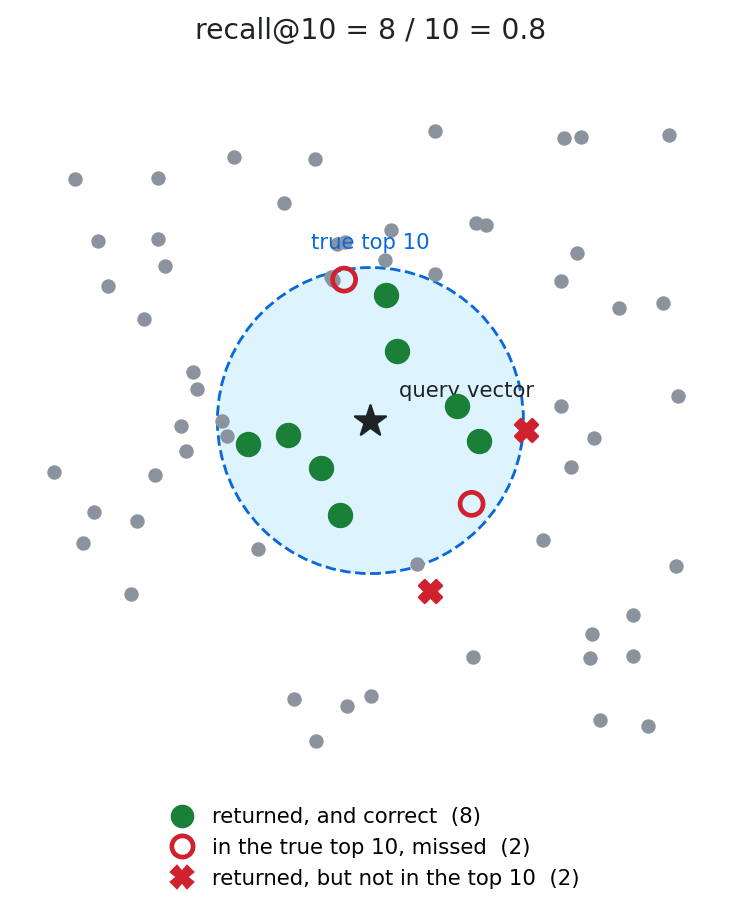
To score that you need to know the right answer in the first place. That’s the ground truth: the true nearest neighbours for every query, computed once by brute force with no index involved. The public ANN datasets ship theirs alongside the vectors, and without it you couldn’t score an approximate index at all.

This is the number that makes everything else meaningful, and it’s the one most vector search claims leave out. That omission is the reason this project exists.

The two kinds of vector index

Almost every database that has added vector search picked one of two designs. They attack the same problem from opposite ends, and which one you have decides what you’re allowed to tune.

HNSW

HNSW stands for Hierarchical Navigable Small World, which is a mouthful for something fairly intuitive. If you’ve ever implemented a skip list, you already have the shape of it.

It’s a graph of vectors built in layers. Every vector is a node, linked to some number of its nearest neighbours. The top layer has few nodes and its links jump long distances across the data. Each layer below has more nodes and shorter links. A search starts at the top and keeps hopping to whichever neighbour is closer to the query. When nothing is closer, it drops a layer and carries on, until it runs out of layers.
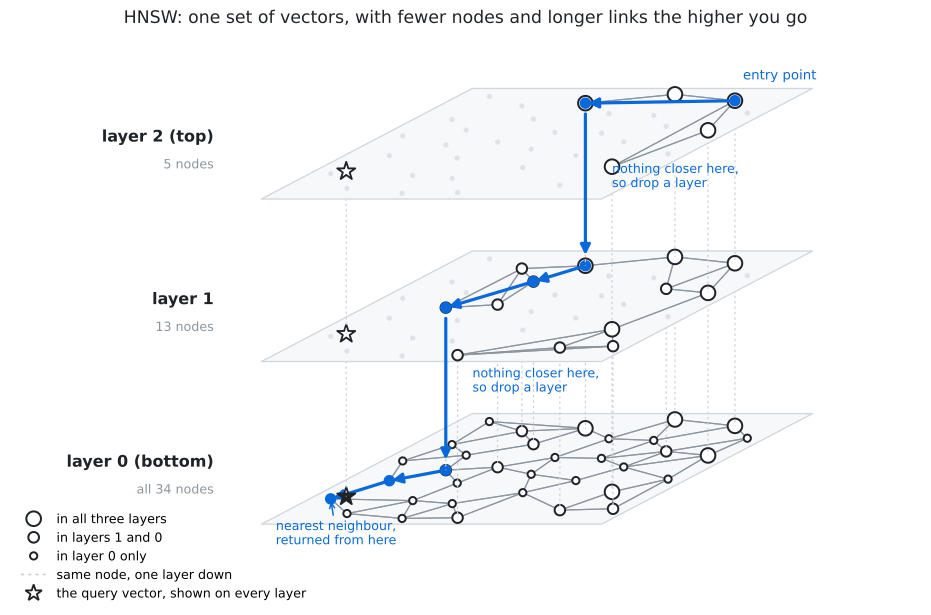
Two settings matter:

  • M is how many links each node keeps. It’s fixed when the index is built. Higher M means a better-connected graph and better recall, at the cost of a slower build and a bigger index.
  • ef_search is how many candidates the search keeps track of while it walks. It’s a session variable, so you can change it per query. Turn it up and the search visits more nodes, gets better recall, and runs slower.

There’s ef_construction too, the same idea applied while the index is being built. Not every engine lets you set it, which turns out to matter when you try to compare them fairly.

IVF

IVF stands for Inverted File. It partitions the data instead of linking it, not unlike list partitioning on a table.

At build time it groups the vectors into nlist clusters, each with a representative vector at its centre. At query time it compares the query against those representatives, picks the closest nprobe clusters, and searches only inside them. It builds much faster than HNSW and uses less memory, but usually gives worse recall at the same speed. It misses when the true neighbour happens to sit just outside the clusters it looked in.
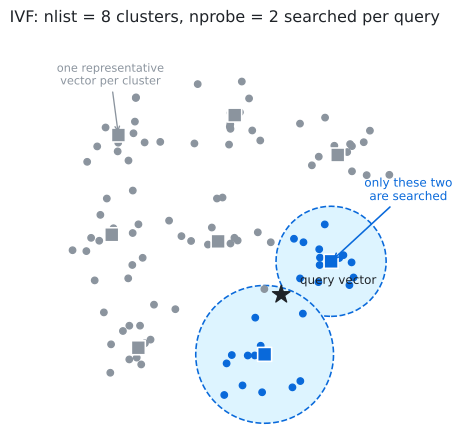
We only test engines running HNSW, which is what most databases shipped. Putting an IVF engine on the same chart would mostly measure the gap between two algorithms rather than how well anybody implemented one, so IVF-only engines get their own bucket.

Why one number is never enough

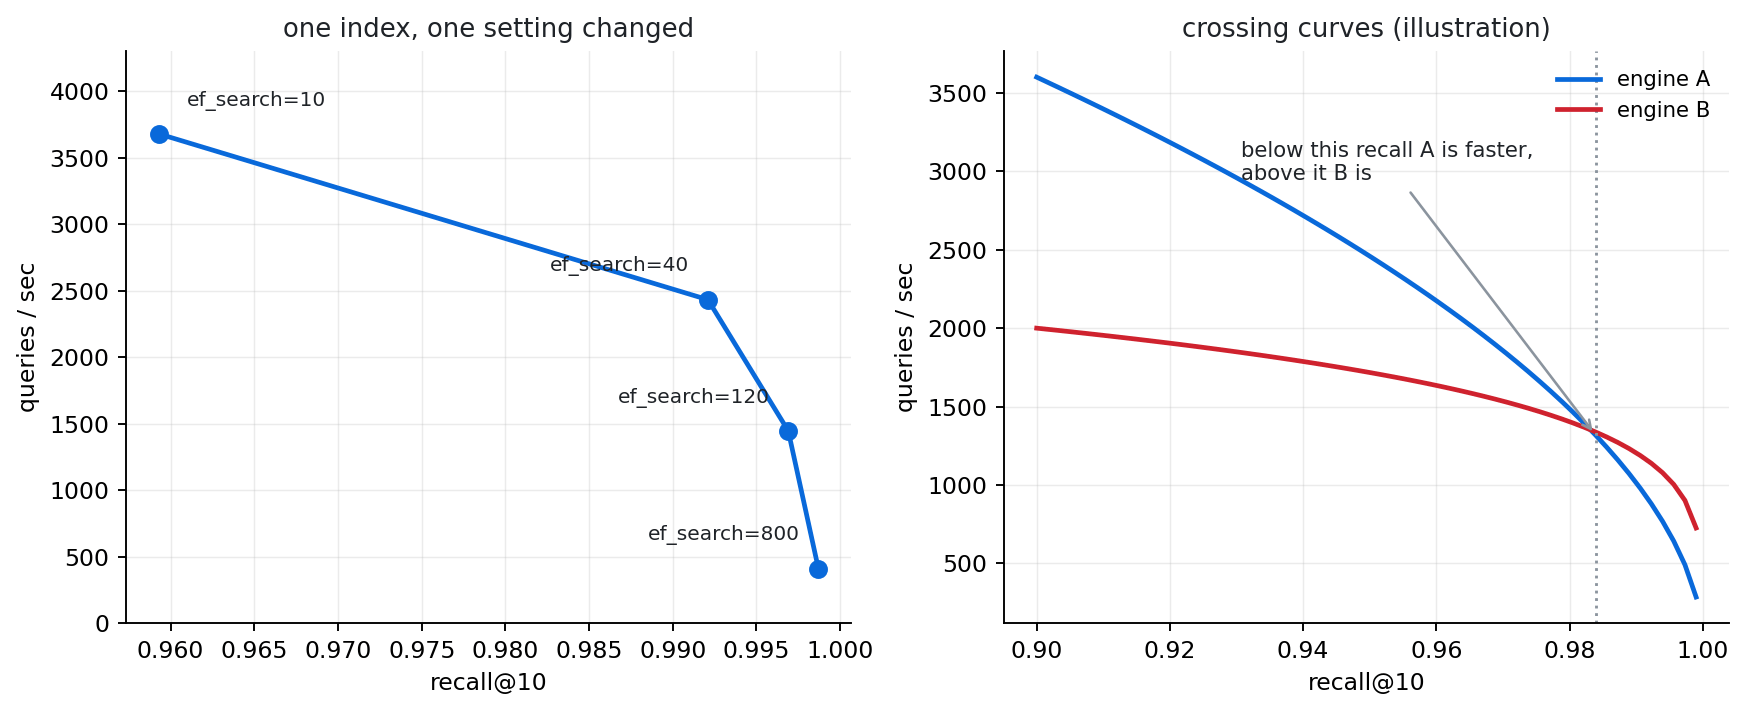
Recall isn’t a property of an engine. It’s a setting, and ef_search is the dial.

Here’s one HNSW index on one machine, same data, same queries. The only difference is that on the first row the search tracks 10 candidate nodes as it walks the graph, and on the second it tracks 800:

ef_search=10 3,678 queries/sec recall 0.9593
ef_search=800 409 queries/sec recall 0.9987

Keeping 800 candidates instead of 10 finds a better answer and takes nine times as long. Both rows are honest measurements of the same index on the same hardware.
Which is why “our database does 3,678 vector queries a second” tells you nothing. You don’t know how often it was handing back the wrong rows, and the person quoting it may not know either. The reverse is just as empty: recall with no throughput next to it is free, because recall 1.0 is always available if you turn the index off and scan the table.

Every measurement here is a pair. If you take one thing from this post, take that.

What the harness puts on each engine

One table per engine. An id, an integer tag column used only by the filtered tests, the vector, and an HNSW index on it at a configured M.

CREATE TABLE t1 (
id INTEGER PRIMARY KEY,
tag INTEGER NOT NULL,
v VECTOR(1536)
);


Then two queries, plain top-k and the same search restricted to a subset of rows:

SELECT id FROM t1 ORDER BY distance(v, ?) LIMIT 10;
SELECT id FROM t1 WHERE tag < ? ORDER BY distance(v, ?) LIMIT 10;


tag holds values 0 to 99 spread evenly, so tag < 10 passes about 10% of rows and tag < 1 about 1%. That’s how we control selectivity.

Every engine writes all of this differently. Some declare the index inside CREATE TABLE, others want a separate CREATE INDEX, and the distance functions have different names everywhere. Translating that is the driver’s job, and the drivers are the only engine-specific code in the whole harness.

Every engine also has at least one setup detail that will quietly wreck your numbers. PostgreSQL, for instance, stores oversized values out of line in what it calls TOAST, and a 1536-dimension vector counts as oversized. Unless the column is set to STORAGE PLAIN, every single distance comparison pays for an extra fetch. It’s one line of DDL. Miss it and you publish PostgreSQL looking slow for a reason that has nothing to do with its vector search, and you’d never know from the results.

What we measure

Recall against throughput. Iterate ef_search against a fixed index, record recall and QPS at each point, repeat at a few values of M. k=10 throughout. The query vectors come from the dataset’s own held-out query set, never from the rows we loaded, because searching for a vector that’s already in the index is a much easier problem and would flatter everybody equally.

The two settings behave completely differently, and it shapes how long a run takes. ef_search is a session variable, so iterating it reuses the index that’s already built and each extra point costs almost nothing. M is baked into the index, so every value of M means dropping the table and loading the entire dataset again. On a million 1536-dimension vectors that’s hours per value. Hence many ef_search points and very few M values.

Build cost. Wall time, rows per second, index size on disk, peak memory.

This is the easiest place in the whole benchmark to publish a misleading number, because engines don’t build the index the same way. Engines can build indexes either incrementally, bulk, or both. What does that mean? 

Incremental. The graph is updated on every INSERT. Loading is slow, but when the last row lands the index is finished and the table is ready to query.

Bulk. All the rows load first, then the whole graph gets built in one pass. Much faster in total, but the table can’t answer a vector query until the build finishes.

Those are two different operations. One engine in our set does both, and its bulk path loaded 18 times more rows per second than its own incremental path. Same engine, same data, same machine, 18x apart.

So a bulk number from one engine put next to an incremental number from another doesn’t compare engines at all. It compares two ways of building an index, and the ratio looks impressive enough that people quote it anyway. We measure both paths on any engine that has both, and the report says which is which.

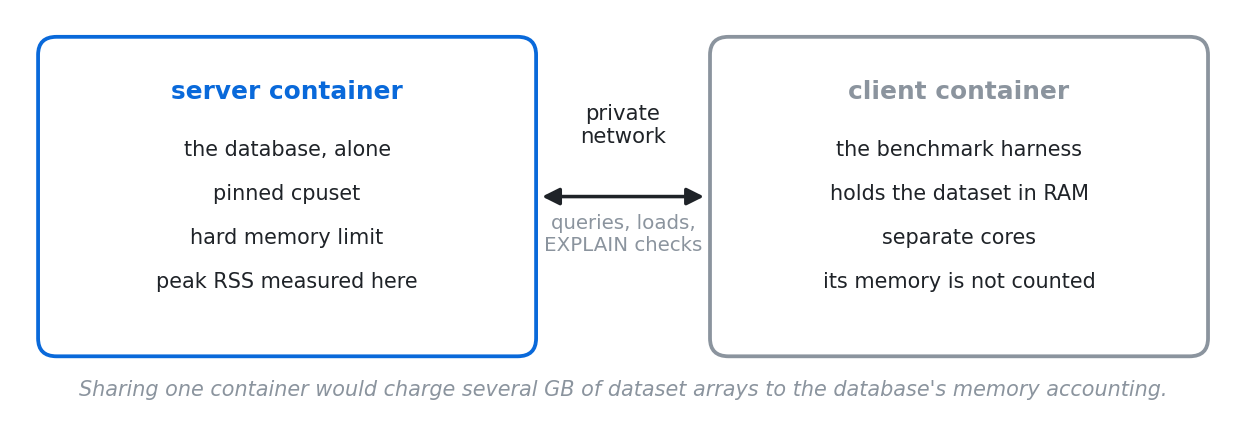
Peak memory comes from the server’s container, with the database as the only thing running in it. The harness runs in a separate container and reaches the server over a private network.

That separation matters more than it sounds. The client holds the entire dataset in memory, several GB of Python arrays. If it shared a container with the database, the container’s memory accounting would count those arrays as database memory, and every memory figure we published would be inflated by whatever the client happened to be holding.
Concurrency. QPS and latency percentiles from 1 to 32 clients. Engines cache their graphs in quite different ways and none of that shows up until clients start competing for the same cache. We report how much of the ideal speedup each engine actually got alongside raw QPS, because an engine that stops gaining throughput at 2 clients while its p99 gets 15 times worse is doing something very different from one that keeps scaling, and a throughput column on its own hides that completely.

Filtered search, at several selectivities down to 1% of rows passing. This is the case that’s supposed to justify keeping vectors in your database instead of a dedicated store, so it deserves more attention than it usually gets.

Filtering changes what “correct” means. The true top 10 among rows where tag < 10 is not the true top 10 overall, so for every selectivity we recompute ground truth by brute force over only the rows that pass. Score filtered results against the unfiltered ground truth that shipped with the dataset and every engine gets a recall near zero. We know, because we did exactly that for a while.

Some queries come back with fewer than 10 rows. In one run, 81 out of 200 did. This is not the data running out. At 10% selectivity about 99,000 rows pass the filter, so there are always at least 10 to find. The cause is the order of the operations. HNSW searches by distance first, then applies the WHERE clause. It gathers a few thousand candidates, the filter throws most of them away, and sometimes fewer than 10 are left. (If a filter really did match fewer than 10 rows, the ground truth shrinks too, and the engine still scores 1.0.) Recall already handles this. A row the engine did not return counts as a miss, so six correct rows score 0.6. We report the count because two different problems score the same. “10 rows, four of them wrong” and “six rows, all correct” are both 0.6. The first needs a wider search. The second needs iterative scanning. The count tells you which one you have. It also means the throughput is flattered, since six rows is less work than ten.

Churn. Recall and throughput before and after deleting and reinserting part of the corpus, since deletions leave graph edges pointing at rows that are gone. Whether rebuilding the index recovers what’s lost, we don’t know yet. It’s the obvious next thing to test and we haven’t done it.

Keeping the comparison fair

Everything runs twice.

The normalized pass gives every engine identical CPU, memory and cache budgets, so a difference in the results belongs to the implementation rather than to who was handed more RAM. The tuned pass lets each engine use the settings its own documentation recommends. Tuned is more realistic and less controlled, which is exactly why it doesn’t replace the first one. A result that survives both passes is about the engine. One that flips between them is interesting for a completely different reason.

Cores are pinned explicitly. One logical CPU per physical core, because SMT siblings share execution units and two threads on one core don’t behave like two cores. Never a mix of P-cores and E-cores on hybrid chips either, since migration between core types adds more variance than several of the effects we’re trying to measure. Durability is relaxed the same way everywhere, or we’d be comparing default fsync policies and calling it vector search.

Some differences can’t be equalised at all, so we write them down instead of pretending. A knob only one engine exposes goes unused in the normalized pass, because using it would hand that engine a tuning axis nobody else has. An engine that insists on a particular isolation level gets it set for everyone. And defaults that are obviously placeholders get sized from a shared budget — one family of engines still ships a 16 MiB graph cache, which is nothing, and judging an engine on a value its own vendor expects you to change measures absolutely nothing. All of these land in a “known asymmetries” section above the results.

One hardware note that catches people out. Several of these implementations ship hand-written AVX-512 code for the distance maths, where a single instruction does the arithmetic for 16 floats at once. The same index on a CPU without AVX-512 is effectively a different benchmark, and the slowdown isn’t the same for every engine, so you can’t even scale the numbers to compensate. The CPU model and its feature flags go into every run’s manifest for that reason, along with engine versions and commits, image IDs, and the resource limits as they are actually resolved rather than as we requested them. No manifest, no report.

Reading the results

Read the validity section before you look at a single chart. Our reports go environment, then validity, then known asymmetries, then results, in that order on purpose. A failed phase, an engine returning short result sets, a CPU missing the instruction set the engines wanted — all of it lands in front of you before you’ve formed an opinion.

The thing to watch for is the silent full scan.

Any of these engines will quietly stop using the vector index and scan the table instead. A scan returns exact results, slowly, so in the output it looks like high recall and low throughput. That’s indistinguishable from a conservatively tuned index unless you go and read the query plan.

It happens for thoroughly boring reasons. One engine’s optimizer costs the vector index against a table scan and takes the scan once the LIMIT is above roughly a quarter of the table, and we still haven’t found a setting that moves it. Another falls back with no error and no warning when the query asks for a different distance than the index was built for — build the index for cosine, write the query with the L2 operator, and you get a sequential scan and a sort, with nothing anywhere to tell you.

So every driver runs EXPLAIN for each configuration and checks the index name appears in the plan.

WARNING: vector index NOT used (k=10, filtered=True). Plan: …Seq Scan…

Anything that is scanned goes into validity. This is far and away the easiest way to produce impressive vector benchmark numbers by accident, and if a benchmark doesn’t mention checking for it, we’d want to know why before believing anything in it.

For recall against throughput, the useful presentation is a curve rather than a number. Iterate ef_search, plot recall against QPS, keep the best points: for each level of accuracy, the highest throughput anything reached at it. One engine beats another only where its curve sits above the other’s at the same recall. If the curves cross, then the answer genuinely depends on how accurate you need to be, and saying so is a result rather than a dodge.

Curves do invite comparing shapes instead of heights at one point, so there are bar charts as well, QPS at recall floors of 0.90, 0.95 and 0.99. Pick the accuracy you’d actually accept and read across.

Things that went wrong while we built this

Worth listing, partly because they’re the reason to trust anything else here, and partly because anyone building something similar will walk into them.

Our first ingest numbers were garbage. The load path was doing one INSERT per network round trip with autocommit on, and we measured 88 rows a second. Batching 500 rows per transaction took the same engine to 373. Publishing the first number would have been benchmarking our own client and calling it a database.

Filtered search and churn were scored against full-corpus ground truth even on runs that used a subset of rows. Every engine looked bad and the bug was entirely ours. Ground truth is now keyed on dataset, k, row count and selectivity.

Both resource passes shared one results directory, and the ANN runner skips configurations that already have results. So the tuned pass quietly skipped everything the normalized pass had computed, and our tuned numbers were mostly normalized numbers wearing a different label. That one took an embarrassingly long time to notice.

Readiness probes lie. One engine’s standard “are you accepting connections” check returns success before the database it’s supposed to create actually exists. The probe passed, the first query failed, and we spent a while convinced it was an engine problem.

The most recent one, on a 1536-dimension corpus. The ANN runner holds the whole dataset in memory twice, once in the parent process and again in a forked worker, and the copies aren’t shared. That’s roughly 12 GB for a million embeddings, on top of whatever the server is using, in a container we’d sized for the server alone. The kernel killed the worker. The runner doesn’t check worker exit codes, so it logged “Terminating 1 workers”, exited successfully and wrote no results — which looks exactly like a run that had nothing left to do. Three hours to fail, and it failed silently.

Adding a database

This is the part we cared most about getting right, because the whole point was to avoid rebuilding the apparatus every time somebody ships vector search. Each engine needs:

  • a Dockerfile producing a runtime image and a test image from a pinned version
  • a config declaring ports, credentials, and which server settings map onto the normalized CPU and memory budget
  • a module for the recall and throughput side
  • a driver: create index, load, query, filtered query, index size, and the EXPLAIN check

What’s next

Results, published with the manifests and the raw per-configuration records, so you can check them instead of taking our word for it.

Everything is at https://github.com/Percona-Lab/vector-bench harness, drivers, Dockerfiles, docs. If we’re measuring something wrong, or being unfair to an engine you know better than we do, tell us.

The post Benchmarking vector indexes appeared first on Percona.
Aug
27
2026
--

Performance Progression of Percona Server for MySQL 8.4

1. Purpose and scope

This performance investigation aims to look into the read/write performance of Percona Server for MySQL 8.4 and how it changed between versions released in 2026:

  • 8.4.8-8 released on 12 March 2026
  • 8.4.10-10 released on 30 June 2026
  • 8.4.11-11 released on 20 August 2026

We want to see if there are improvements in scalability and performance in OLTP read/write operations, where the improvements are most noticeable and how they were achieved. For some readers this material might help with making the decision whether upgrading to a newer version is worth the effort.

An important note is that the new features or security patches will not be taken into consideration.

Measuring Latency (Percentiles) and Resource Utilization (CPU, RAM, I/O) is not in the scope of this post.


2. Configuration and Methodology

The configuration was as follows:

Benchmark Sysbench OLTP Read-Write
CPU Intel Xeon Gold 6230 (2×20 cores, HT = 80 logical CPUs)
RAM 187 GiB DDR4
Storage NVMe SSD (2.9 TB) INTEL SSDPE2KE032T8
OS Ubuntu 24.04, kernel 6.8.0-60-generic
DB Engines Percona Server for MySQL 8.4.8-8 (release build)
Percona Server for MySQL 8.4.10-10 (release build)Percona Server for MySQL 8.4.11-11 (release build)

The benchmarks were done across the following dimensions:

Database Sizes (Row Number) 24Gb (100M rows) / 48Gb (200M rows) / 96Gb (400M rows)
Number of tables in DB Schema 20 (this number is constant for all runs)

Database Schema definition can be downloaded from here: 

https://percona-lab-results.github.io/2026-interactive-metrics/schema_dump.sql

Number of concurrent threads 1 / 4 / 16 / 32 / 64 / 128 / 256 / 512
Buffer to Data Ratio 1:12 (I/O bound), 1:2 (Partially buffered), 1:1 (Fully buffered)

One of the points in benchmarking was to create combinations of similar Buffer to Data Ratios, but with the different Database Sizes. This gives us the following possible combinations of innodb_buffer_pool_size and Database Size:

1:12 (I/O bound) innodb_buffer_pool_size = 2G, Data Size = 24Gb
innodb_buffer_pool_size = 4G, Data Size = 48Gb
innodb_buffer_pool_size = 8G, Data Size = 96Gb
1:2 (Partially buffered) innodb_buffer_pool_size = 12G, Data Size = 24Gb
innodb_buffer_pool_size = 24G, Data Size = 48Gb
innodb_buffer_pool_size = 48G, Data Size = 96Gb
1:1 (Fully buffered) innodb_buffer_pool_size = 32G, Data Size = 24Gb
innodb_buffer_pool_size = 64G, Data Size = 48Gb
innodb_buffer_pool_size = 128G, Data Size = 96Gb

We should be able to see how efficiently the server manages an increasingly larger number of rows while keeping the Buffer to Data Ratio the same.

Execution of the benchmarks was done as follows:

Ramp-up 24G – 600 sec (10 min) – could be shorter
48G – 600 sec (10 min)96G – 900 sec (15 min)

The Ramp-up times were established experimentally depending on the Data Size until the point when increasing them further did not bring significant changes.
Measurement window 900 sec (15 min)

Ideally it should be as long as possible, but measurements should take reasonable time. Hence, we used the experience of previous benchmarks and established that this window is adequate for the purpose.
Number of runs 3

For each combination there are multiple runs.
The interactive graph can show data for individual runs as well as averaged value.

Important Database Configuration options (the actual config files with specific settings for each run can be downloaded from the interactive graphs):

InnoDB – Buffer pool Tier
innodb_buffer_pool_size 2G/4G/8G/12G/24G/32G/48G/64G/128G
innodb_buffer_pool_load_at_startup OFF
innodb_buffer_pool_dump_at_shutdown OFF
Thread Pool
thread_handling pool-of-threads
thread_pool_size 80 # match physical core count
thread_pool_max_threads 2000
thread_pool_oversubscribe 3
Threading
thread_stack 512K
thread_cache_size 256
back_log 4096
InnoDB I/O
innodb_io_capacity 10000
innodb_io_capacity_max 20000
innodb_read_io_threads 16
innodb_write_io_threads 16
innodb_use_native_aio ON
InnoDB Log / Durability
innodb_log_buffer_size 256M
innodb_flush_log_at_trx_commit 1 # full ACID
innodb_doublewrite ON
InnoDB – Concurrency & OLTP Tuning
innodb_stats_on_metadata OFF
innodb_open_files 65536
innodb_lock_wait_timeout 50
innodb_rollback_on_timeout ON
Per-Session Buffers
sort_buffer_size     4M
join_buffer_size     4M
read_buffer_size     2M
read_rnd_buffer_size 4M
tmp_table_size       256M
max_heap_table_size 256M
Binary Log
disable_log_bin ON # Disabled binlog
Other InnoDB settings
innodb_redo_log_capacity     4G
innodb_change_buffering      none
innodb_flush_method          O_DIRECT
innodb_buffer_pool_instances Calculated as
(innodb_buffer_pool_size G / 5)
But must be in range [1..8]
Misc server settings
collation_server utf8mb4_unicode_ci
bulk_insert_buffer_size 256M
myisam_sort_buffer_size  128M
key_buffer_size          64M # MyISAM only, keep small for OLTP

In the high concurrency scenario when all CPU cores are working under maximum load the performance fluctuations might appear out of the ability of a specific CPU crystal to work at a specific sustainable maximum frequency. Intel Xeon Gold 6230 processors installed in the test servers have a base frequency of 2100 MHz and maximum turbo frequency of 3900 MHz. However, such turbo frequency can only be achieved for a short period of time on an isolated core. The load and the heat production of the physical core neighbours limit the frequency of the whole CPU. Some CPU’s were able to hold 2530 MHz on all cores for 20+ hours of intense load, others could only reach 2420 MHz. For consistency of the tests the turbo frequency was capped to 2400 MHz from the beginning on all servers. It helped to eliminate the struggle between turbo mode trying to increase the frequency beyond sustainable levels and the CPU thermal protection bringing the clock down. More stable hardware performance reduced the measurement fluctuations during the benchmark runs regardless if they were done on the same or a different physical server.


3. Results

First, let’s check the I/O bound scenario where the InnoDB Buffer to Data Size is the smallest (1:12).

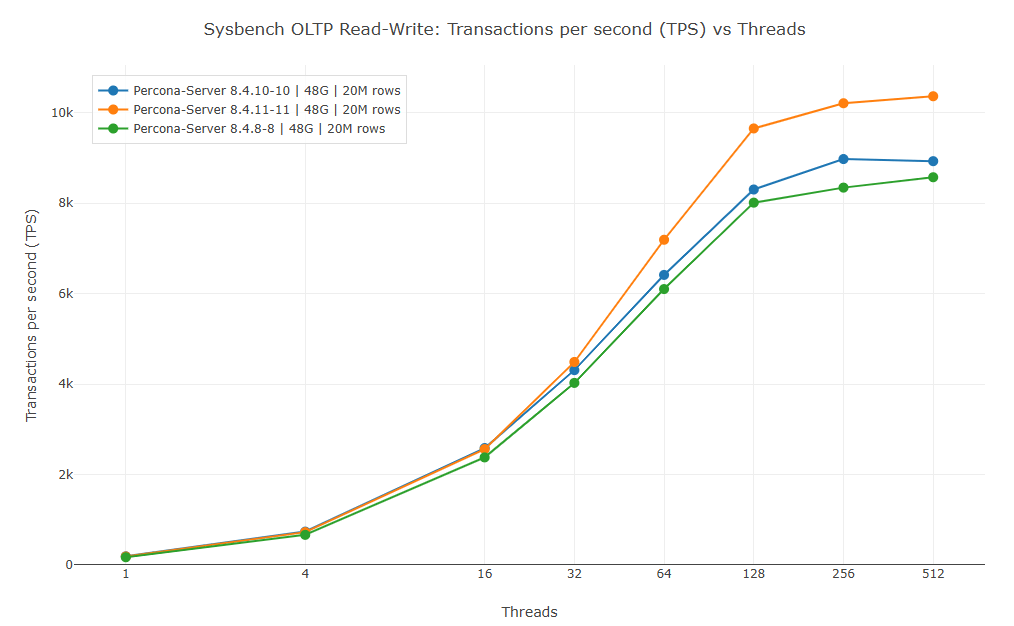
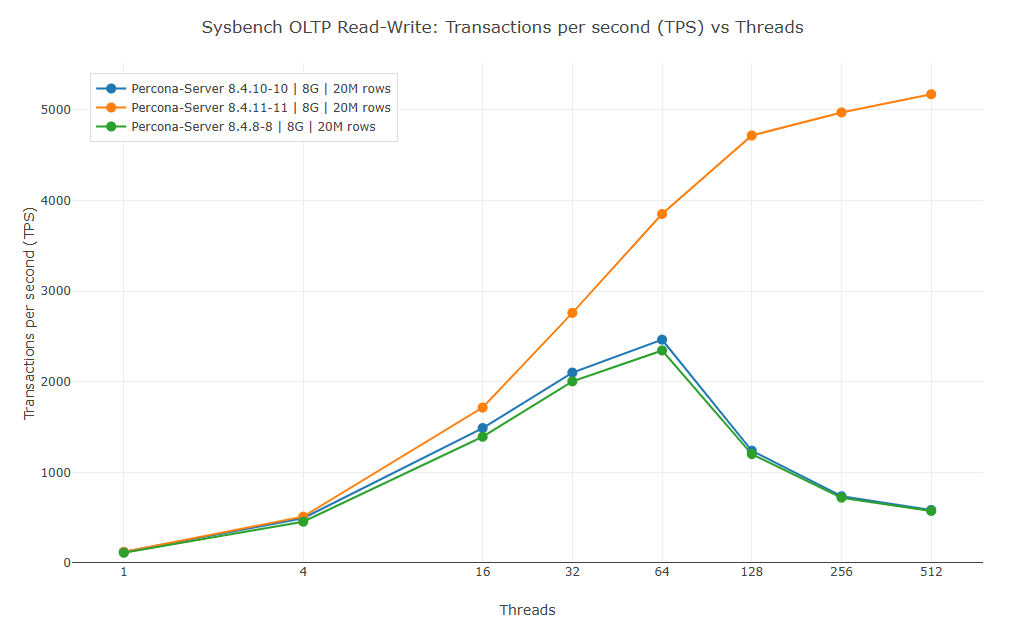
The graph shows the configurations with innodb_buffer_pool_size=8G and Data Size 96G (or 20M rows per table, 400M rows in total):


[ INTERACTIVE GRAPH ][ TABLE ]

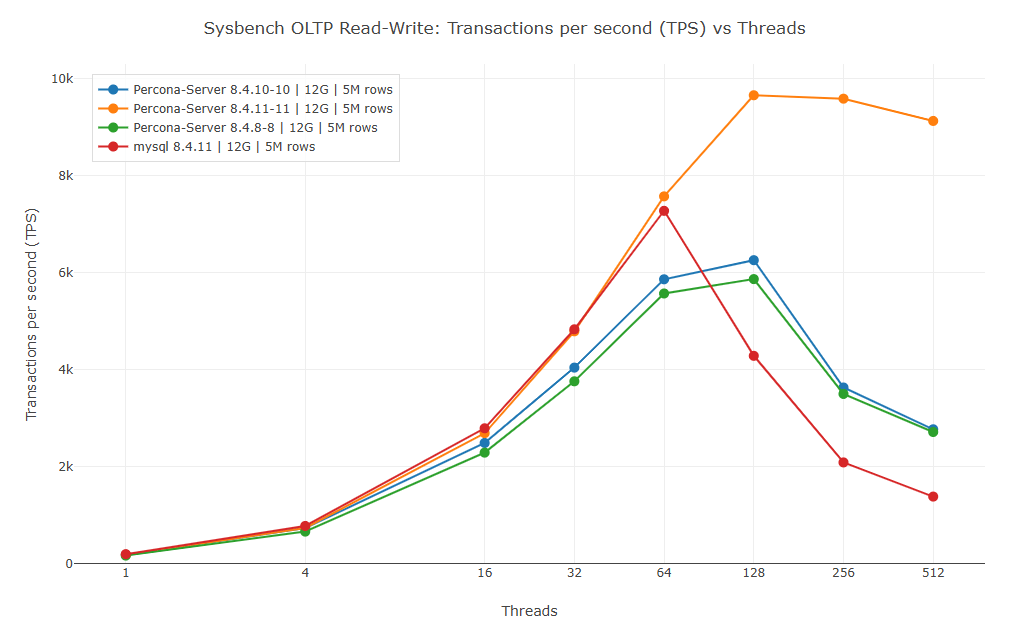
The first thing that catches the eye is the hugely superior performance of the version 8.4.11-11 over 8.4.10-10 and 8.4.8-8 in the high thread numbers. In the situations when the number of physical cores (80) is smaller than the number of threads (128+) the versions 8.4.10-10 and 8.4.8-8 have a steep performance degradation. However, the TPS for 8.4.11-11 keeps growing. This is due to the optimization done to InnoDB LRU pages flushing algorithm. The optimization specifically targeted the scenario when the data size is larger than the available server buffers and the server has many concurrent connections doing random read-write operations. The optimizations in 8.4.11-11 deserve a separate explanation and they will be published in another blog post.

The less noticeable, but important difference can be spotted between the TPS for 8.4.8-8 and 8.4.10-10.

The version 8.4.10-10 shows better performance (especially at the saturation point with 64 threads), which should mostly be attributed to the introduction of Performance Guided Optimization (PGO). 

More information on PGO can be found here:

https://docs.percona.com/percona-server/8.4/pgo.html

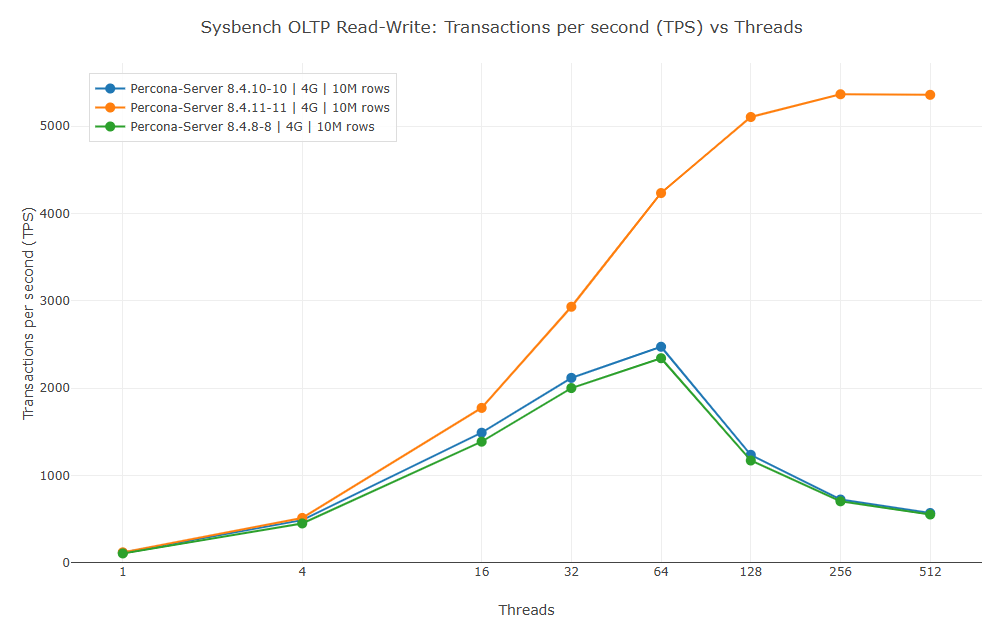
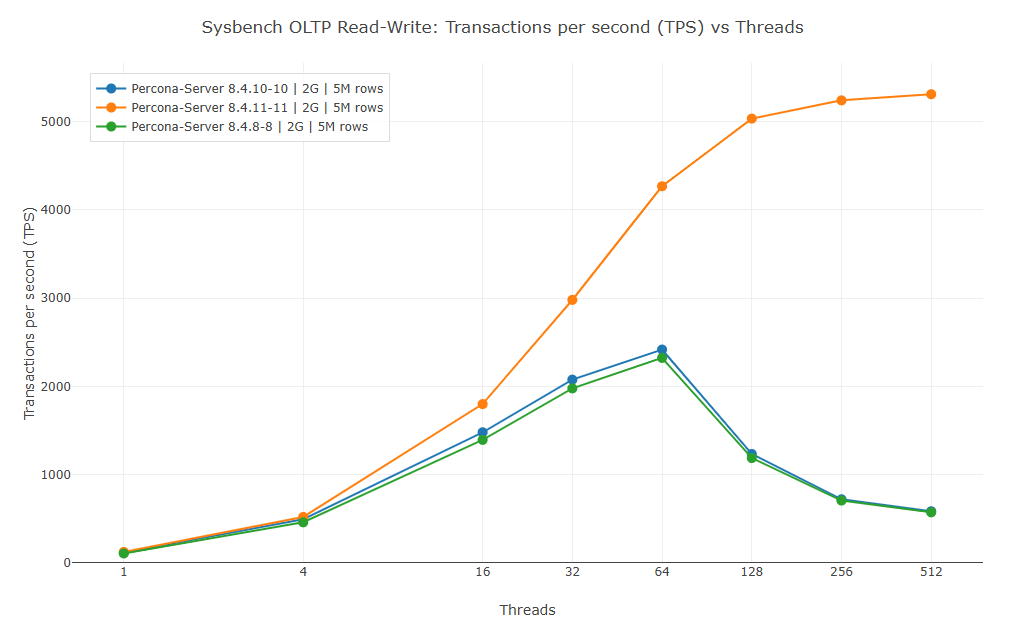
With the smaller data and buffer sizes the performance difference gives an almost identical picture:

4G buffer, 48G data [ INTERACTIVE GRAPH ][ TABLE ] 2G buffer, 24G data [ INTERACTIVE GRAPH ][ TABLE ]

Now let’s review what happens with the ratio 1:2.
This time the buffer pool size also plays a more significant role and the performance difference is not characterized by the Buffer / Data size ratio.

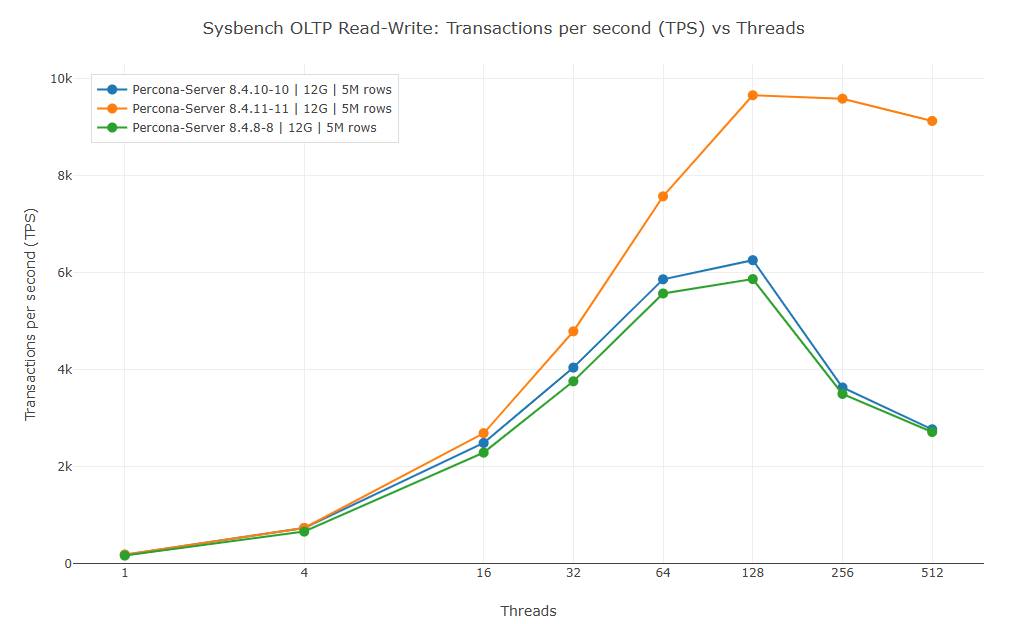
With innodb_buffer_pool_size=12G and 24G data size the performance gap between 8.4.11-11 and older versions is still huge as can be seen on the graph:


[ INTERACTIVE GRAPH ][ TABLE ]

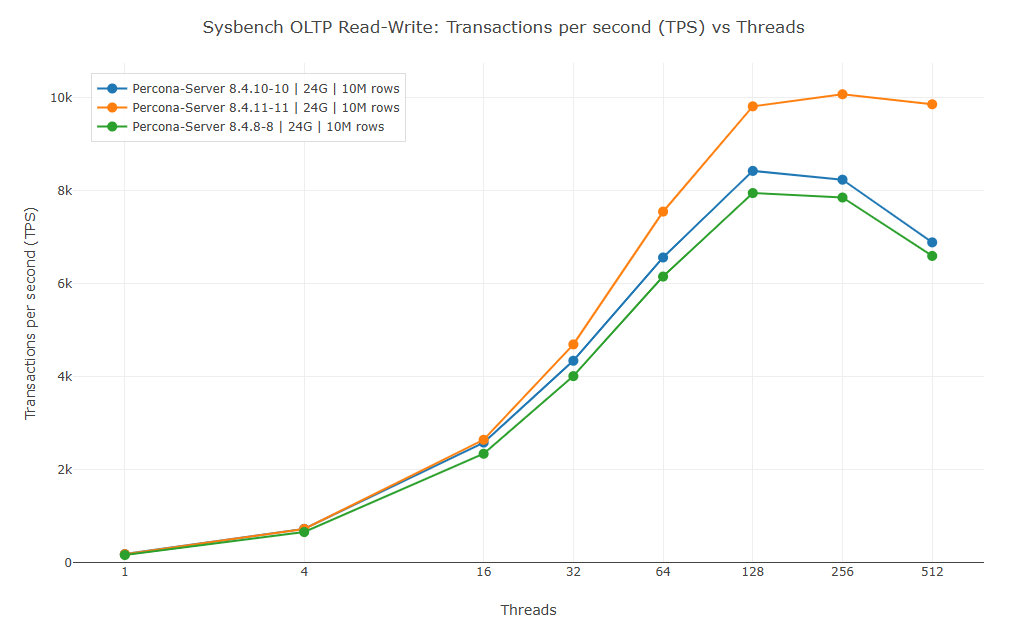
However, setting innodb_buffer_pool_size=24G and 48G data size reduces the gap. The superiority of 8.4.11-11 is still visible:


[ INTERACTIVE GRAPH ][ TABLE ]

Moving to innodb_buffer_pool_size=48G and 96G data size shrinks the gap even more:


[ INTERACTIVE GRAPH ][ TABLE ]

In this post we are not going to talk about mechanisms behind shrinking performance gaps in 1:2 Buffer / Data size ratio.

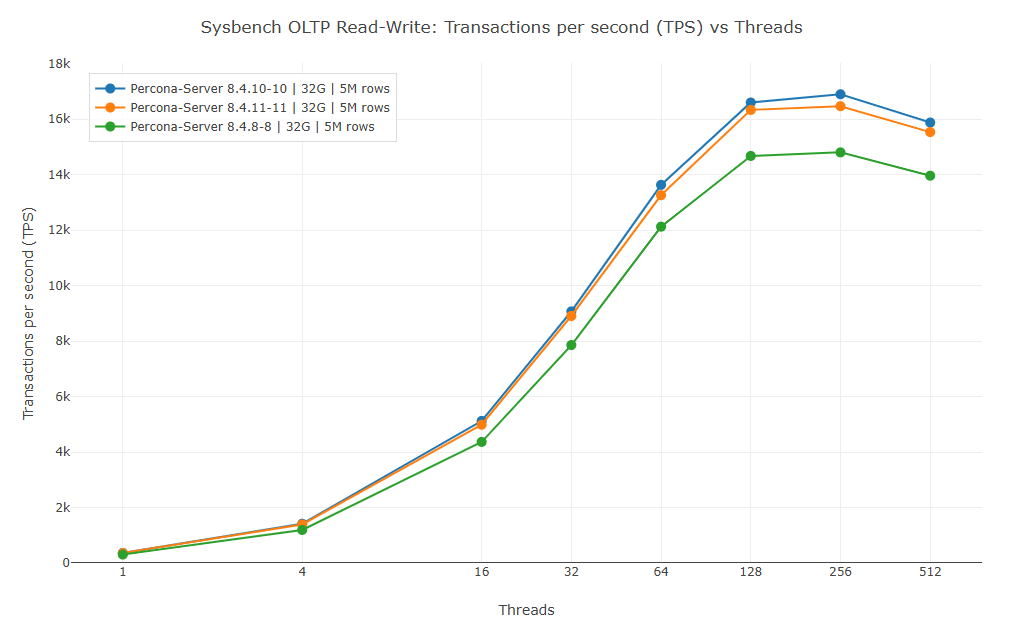
Holding the entire data set in memory is not the most common thing for the database server, but in some cases it happens. Therefore, we are covering such situations as well.


[ INTERACTIVE GRAPH ][ TABLE ]

As the above graph shows, 8.4.10-10 is slightly ahead of 8.4.11-11, but the gap is very small.

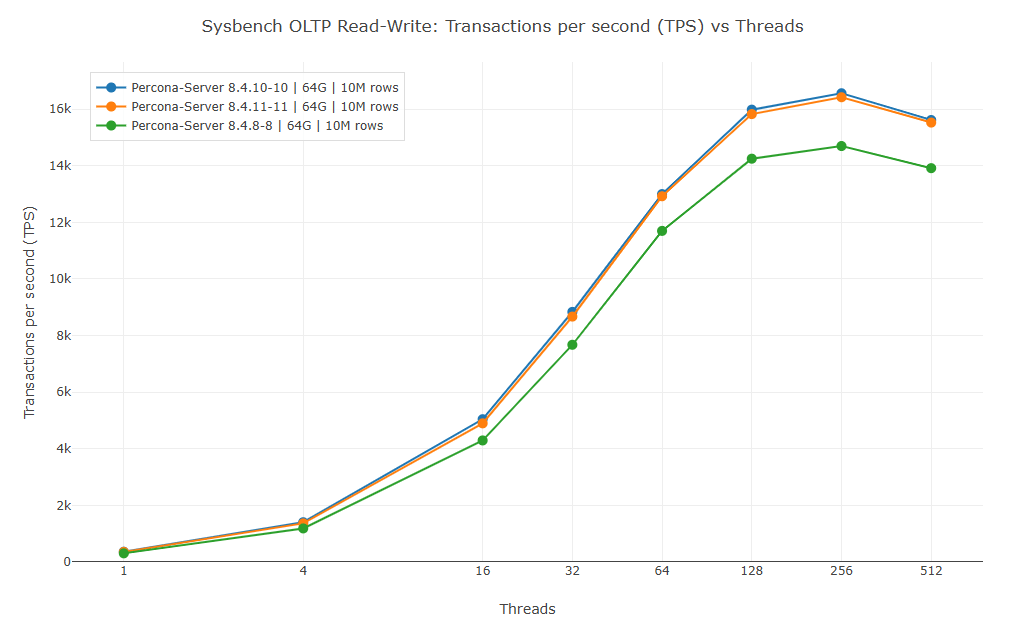
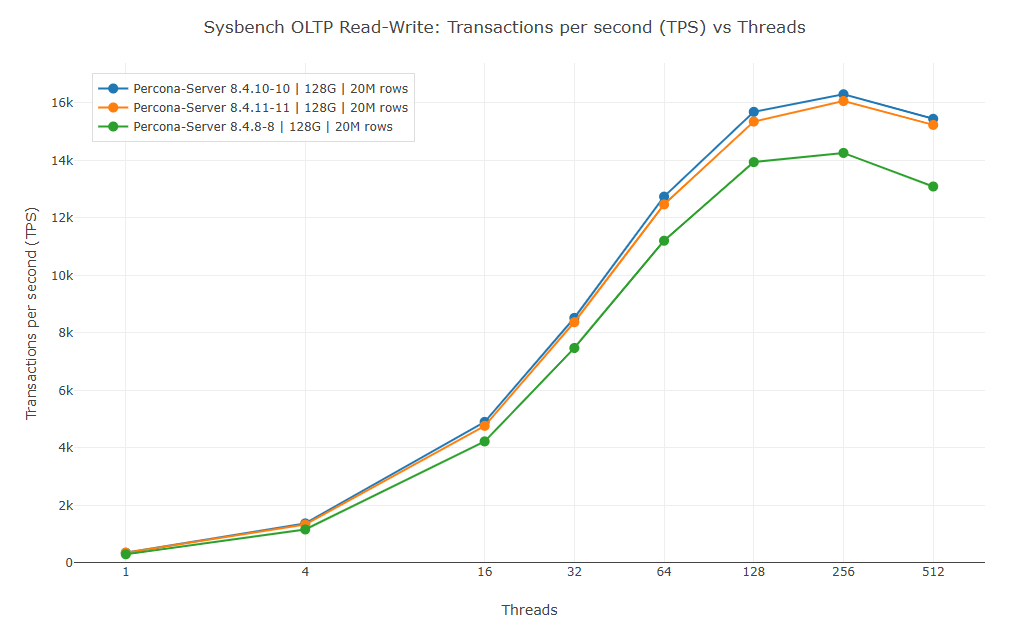
This behavior is consistent with other data sizes for fully buffered data:

innodb_buffer_pool_size=64G and 48G Data Size:


[ INTERACTIVE GRAPH ][ TABLE ]

innodb_buffer_pool_size=128G and 96G Data Size:


[ INTERACTIVE GRAPH ][ TABLE ]

Again, we will not go into details about why this happens. Though it is worth noting that both 8.4.10-10 and 8.4.11-11 do better than 8.4.8-8 in all runs and configurations.

The table interpretation of the results is available as well.


4. Comparing with Upstream MySQL 8.4.11.

The performance improvements in Percona Server for MySQL 8.4.11-11 are not a part of the Upstream MySQL 8.4.11. The patch was specifically designed to address the issue of Percona Server being slower than MySQL in I/O bound scenarios.

Also, the patch eliminated the abrupt performance degradation in the higher thread count after reaching the saturation point at 64 threads:

[ INTERACTIVE GRAPH ][ TABLE ]

As the graph shows – Percona Server 8.4.8-8 / 8.4.10-10 was slower than MySQL in lower thread count. Although it was still faster in 128+ threads, the Percona Server was still subject to a substantial slow-down. That is where Percona Server 8.4.11-11 really shines.

However, with the fully buffered data MySQL goes faster than any Percona Server:


[ INTERACTIVE GRAPH ][ TABLE ]

5. Summary

The Performance of the Percona Server 8.4 for MySQL is progressing well from older to newer version offering significant performance improvements especially in the version 8.4.11-11. This version shows very significant improvements in performance on the data sets that require I/O. Also, it outperformed the upstream MySQL 8.4.11.

With fully buffered data sets the version 8.4.10-10 is slightly better than 8.4.11-11. MySQL Server in this case shows the fastest performance.

The PGO had a positive impact demonstrating the version 8.4.10-10 being faster in all tests on all configurations than 8.4.8-8.

The performance depends not only on the ratio between the buffer and the data size, but also on the buffer size.

The post Performance Progression of Percona Server for MySQL 8.4 appeared first on Percona.

Aug
07
2026
--

The DuckDB MySQL engine at 500 GB

We ran DuckDB MySQL storage engine at scale factor 500. It is around 500 GB of raw TPC-H, three billion lineitem rows  on an 80-core server with 187 GB of RAM. Three engines on the same box: InnoDB, our MySQL+DuckDB engine, and plain DuckDB as the reference.

Here is what came out. InnoDB finished 18 of the 22 queries and spent more than 28 hours of query time on them. Four never finished. Our engine ran all 22 in about three minutes. It loaded the data 25 times faster than InnoDB, and it used 5 times less disk. On the queries it stays close to plain DuckDB, and on a few it is ahead.

It’s still an experiment, not production software. Code and the benchmark harness are on GitHub under GPLv2: https://github.com/Percona-Lab/ducksdb-mysql-engine.

The machine, and how we ran it

  • One server, 80 cores, 187.5 GB RAM.
  • SF500: about 500 GB of raw CSV, 3,000,028,242 lineitem rows.
  • Three engines, one at a time: InnoDB, our engine, native DuckDB.
  • All of it through the harness in the repo (bench/tb), in Docker.

Two details about how we ran it change how the numbers read.

The load streams. We generate a chunk of CSV, load it, delete it, then generate the next one. So the disk never holds more than one 20 GB chunk, which is the only reason 500 GB fits on the box at all.

And “native DuckDB” is not a second copy of the data. It opens the engine’s own DuckDB file read-only and queries that. Same bytes on both sides. That keeps the comparison honest, and it means there is no separate native load time to report.

Loading the data

Engine Load time
ENGINE=DuckDB (COPY fast path) 36m 05s
InnoDB (bulk LOAD DATA) 15h 21m

InnoDB took 25.5 times longer. The engine hands LOAD DATA straight to a DuckDB COPY instead of going row by row through the handler, so the three billion lineitem rows go in in about nineteen minutes, and the whole set in thirty-six. InnoDB inserts row by row and builds the primary key as it goes. That is where the rest of the fifteen hours goes.

Storage on disk

Component Size vs raw CSV
raw TPC-H CSV 500.0 GB 100%
ENGINE=DuckDB (tpch.duckdb) 132.4 GB 26% (3.78x smaller)
InnoDB (tpch/*.ibd) 673.2 GB 135%

DuckDB stores columns and compresses them, so 500 GB of CSV comes down to 132 GB. InnoDB stores rows and carries the index with them, and it ends up bigger than the CSV it came from: 673 GB, five times the DuckDB file. The InnoDB lineitem.ibd on its own is 446 GB. That is more than three times our entire database.

Storage, lower is better. The DuckDB engine holds all of SF500 in 132 GB.

Query time

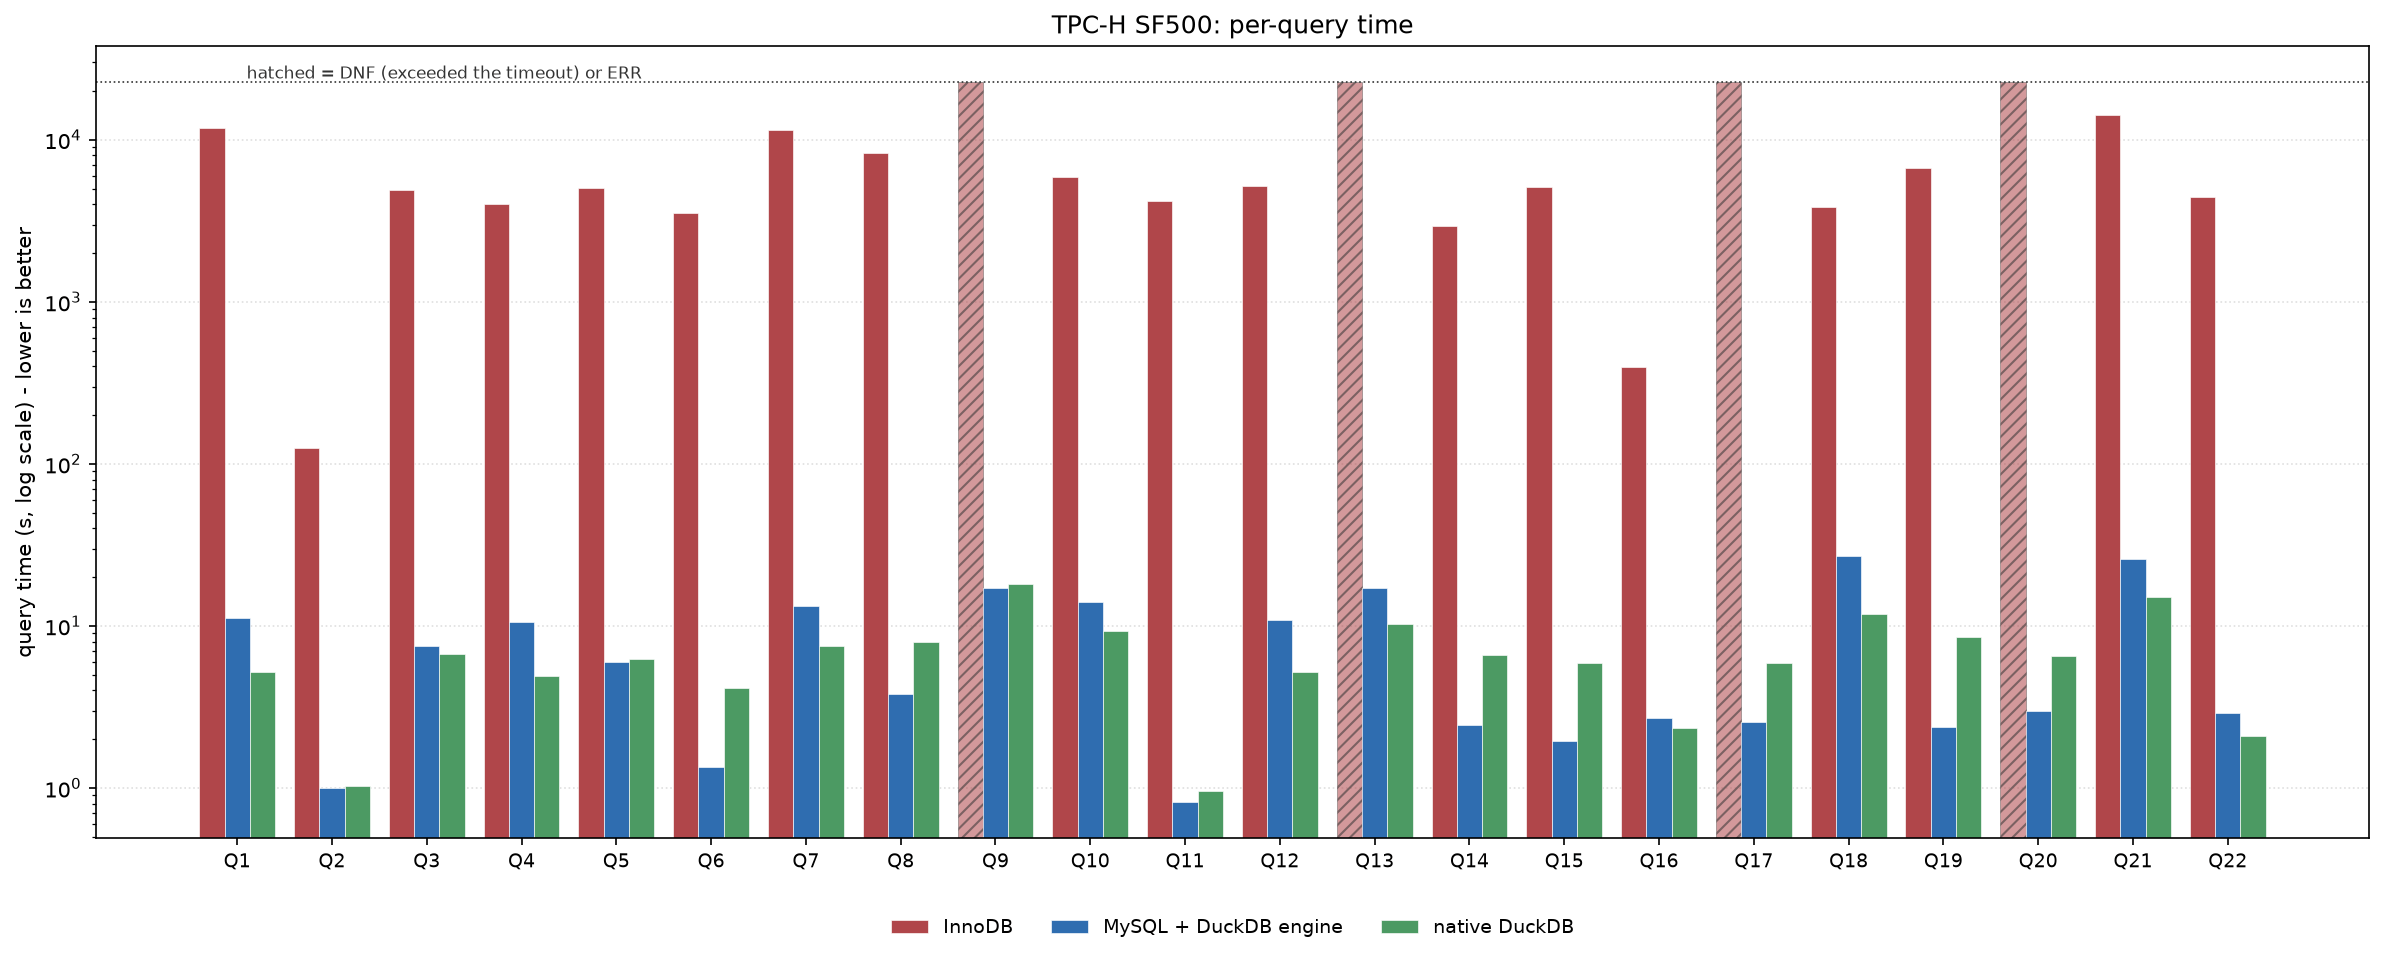
All 22 queries. Warm runs, minimum of a few, in seconds. InnoDB had a two-hour cap per query; the ones that hit it are marked DNF.


Query InnoDB MySQL+DuckDB (ours) native DuckDB
Q1 11864.5 11.1 5.2
Q6 3539.4 1.3 4.1
Q9 DNF 17.1 18.1
Q13 DNF 17.1 10.4
Q18 3846.1 27.0 11.9
Q19 6672.3 2.4 8.6
Q21 14211.7 26.0 15.1
All 22 18/22 finished, ~28 h 185.6 s 152.7 s

SF500, all 22 queries, log scale, lower is better. Hatched InnoDB bars did not finish inside the cap.

Two things to take from this.

InnoDB is far behind, which is no surprise. Scanning three billion rows for a wide GROUP BY or a six-way join is the wrong job for a row store. Four queries (Q9, Q13, Q17, Q20) did not finish at all, and the eighteen that did add up to more than 28 hours. This is the exact problem the engine is for. It is not a mark against InnoDB, which is doing the transactional job it was built for.

The comparison worth reading is our engine against plain DuckDB, since both are the same DuckDB reading the same file. Over all 22 they are close: 186 seconds for ours, 153 for native. Query by query it goes both ways. On the selective ones ours is often faster — Q6 (1.3 vs 4.1), Q19 (2.4 vs 8.6), Q17, Q20. On the biggest joins native wins — Q18 (27 vs 12), Q21, Q1. That gap comes from settings, not data: the memory limit, the thread count, and running inside mysqld versus a bare CLI. Either way, both are around a thousand times faster than the row store.

Correctness

We checked the answers, not only the clock. For every query we compared our engine’s output to native DuckDB’s, numbers rounded to four decimals and the order ignored. 21 of 22 matched exactly. None mismatched. One was skipped because a result file came back empty on one side. So the engine gives the same answers as plain DuckDB.

What this means, and where it stops

At 500 GB the small-scale picture holds and gets sharper. Analytical queries that took hours on InnoDB, or never finished, come back in seconds on the DuckDB engine. The load is far quicker, and the footprint is far smaller. All of it inside one MySQL server, with the tables queried the normal way.

The limits are the same as before:

  • It is for analytics, not OLTP. Point lookups and single-row work stay on the row path, where an index seek is the right tool.
  • DuckDB runs inside mysqld, so a heavy query under a tight memory limit can go over budget. DUCKSDB_MEMORY_LIMIT and DUCKSDB_TEMP_DIR let it spill to disk instead of failing. We set a limit here so the big CTEs spill rather than get OOM-killed.
  • Some queries still fall back to normal MySQL and run on the row path.
  • It is one workload on one machine. The result is strong, but the engine is still an experiment, not something for production traffic.

Try it

Pull the image and run your own queries:

docker run -d -p 3306:3306 -e MYSQL_ROOT_PASSWORD=secret \
  perconalab/ducksdb-mysql-engine:latest

The engine, the patches, and the harness that produced these numbers are on GitHub: https://github.com/Percona-Lab/ducksdb-mysql-engine. The per-query numbers and the method are in the repo. If it breaks, or your hardware gives different numbers, open an issue.

The post The DuckDB MySQL engine at 500 GB appeared first on Percona.

Jun
14
2026
--

The Failover Brownout: Rethinking High Availability in MySQL Group Replication

It is time to talk again about Flow control and group replication. This time with a special eye on the use of Group Replication in the Kubernetes context. In this article we will dig a bit on how it works and what are the various side effects. 


The problem

Recently I was refining the calculation I use in the MySQL calculator for Operator given I was constantly encountering a very serious problem with the Percona Server Operator.

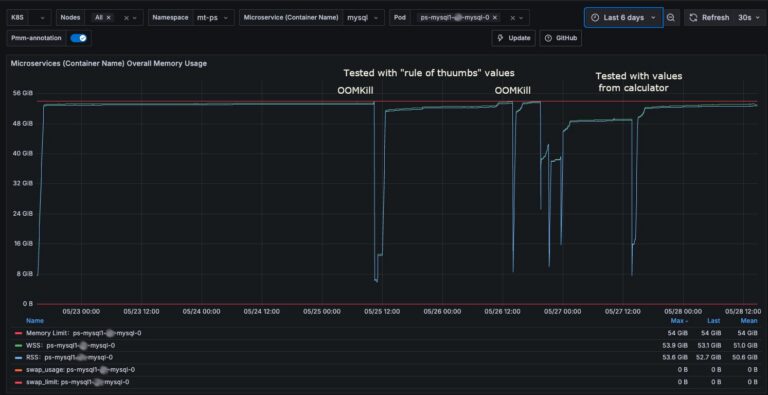
The problem is that when the deployment was/is serving a high level of traffic, it will, no matter what, end up in getting OMMKill by the K8 system. 

This because the pod was gradually consuming more and more memory, reaching the memory limit set in the CR specification. 


Now let me clarify a few things, to get straight to the facts.

Kubernetes itself does not OOMKill a pod for hitting its memory limit, the mechanism works as described below with mention on how Working Set Size (WSS) is calculated, and how OOMKills are triggered, and in the resource sections, the links to the official documentation and source code.


1. The Reality of OOMKills vs. Kubelet Evictions

It is crucial to distinguish between what the Linux kernel does and what Kubernetes does:

  • OOMKilled (Exit Code 137): This is executed entirely by the Linux kernel’s OOM Killer, not Kubernetes. When we set a memory limit in our Pod spec, Kubernetes translates that into a Linux cgroup constraint (memory.limit_in_bytes for cgroups v1, or memory.max for cgroups v2). If our container attempts to allocate more memory than this hard limit, and the kernel cannot reclaim any page cache (like inactive files), the kernel directly intervenes and terminates the process.
  • Node-Pressure Evictions: This is where Kubernetes actively observes memory. The kubelet monitors the working_set_bytes metric to protect the node from running out of memory. If the node’s memory drops below an eviction threshold, Kubernetes will actively evict pods to prevent the kernel from initiating a system-wide OOM kill.

2. How Working Set Size (WSS) is Calculated for the container

Kubernetes monitors container memory via cAdvisor, which is integrated directly into the kubelet. cAdvisor calculates the Working Set Size by taking the total memory usage and subtracting the inactive file cache (memory that the kernel can easily reclaim if it faces memory pressure).

Because active file caches and anonymous memory (like our application’s heap) cannot be easily evicted, this working set metric is the most accurate representation of the memory your container is forcing the system to hold.


The Calculation & cgroups Evolution The core mathematical calculation is Memory UsageInactive File Cache, but how cAdvisor fetches this data from the Linux kernel depends entirely on your node’s cgroup version. Modern cAdvisor relies heavily on the opencontainers/runc/libcontainer library to read these raw cgroup files:

  • cgroups v1: cAdvisor starts with the raw usage from memory.usage_in_bytes and subtracts the reclaimable cache found under the total_inactive_file key.
  • cgroups v2 (Unified): cAdvisor starts with the raw usage from memory.current and subtracts the reclaimable cache found under the inactive_file key.


The Underlying Code Logic While older versions used a static setMemoryStats function, modern Kubernetes branches handle this dynamically. The logic executes the following flow before reporting back to the kubelet:

  1. Detects Version: It identifies whether the node runs cgroups v1 or v2 to determine the correct inactive file key name.
  2. Fetch Usage: It pulls the raw memory usage from the container.
  3. Subtract Cache: It looks up the inactive file value and safely subtracts it from the usage (including a safeguard to ensure the working set never drops below zero).
  4. Report Metric: It sets this final calculated value as container_memory_working_set_bytes, which the kubelet then uses to decide if the node is under memory pressure.

Back to us 

At the end the point is that if our pod reaches the limit and we ARE NOT using the new swap feature existing in Kubernetes, our pod will be brutally killed, and in 99% of the cases our production will suffer a lot. !Ops spoiler!


To clearly understand what was causing the issue about this memory consumption and having my calculator fail, I started to collect the information about the memory usage in MySQL itself.


SELECT EVENT_NAME,CURRENT_NUMBER_OF_BYTES_USED / 1024 / 1024 AS current_usage_mb FROM performance_schema.memory_summary_global_by_event_name WHERE EVENT_NAME like ‘memory/%’ and EVENT_NAME not like ‘memory/performance%’  order by current_usage_mb desc limit 25;

Which will give you and output like this:

+---------------------------------------+------------------+
| EVENT_NAME                            | current_usage_mb |
+---------------------------------------+------------------+
| memory/innodb/buf_buf_pool            |   46398.92578125 |
| memory/group_rpl/GCS_XCom::xcom_cache |    1066.66179943 |
| memory/group_rpl/certification_info   |      92.45250702 |
| memory/innodb/log_buffer_memory       |      64.00096130 |
| memory/sql/TABLE                      |      49.90627003 |
| memory/innodb/memory                  |      34.68734741 |
| memory/innodb/ut0link_buf             |      24.00006104 |
| memory/innodb/lock0lock               |      21.40064240 |
| memory/mysqld_openssl/openssl_malloc  |       9.51009655 |
| memory/innodb/read0read               |       8.19496155 |
| memory/mysys/KEY_CACHE                |       8.00215149 |
| memory/innodb/sync0arr                |       7.03147125 |
| memory/innodb/ha_innodb               |       6.87006950 |
| memory/innodb/lock_sys                |       5.25009155 |
| memory/sql/log_sink_pfs               |       5.00003052 |
| memory/innodb/ut0pool                 |       4.00017548 |
| memory/sql/dd::objects                |       2.83031464 |
| memory/innodb/std                     |       2.72618866 |
| memory/innodb/os0file                 |       2.63054657 |
| memory/innodb/os0event                |       2.34302521 |
| memory/sql/TABLE_SHARE::mem_root      |       2.31734467 |
| memory/innodb/trx0trx                 |       2.22647858 |
| memory/temptable/physical_ram         |       1.00003052 |
| memory/sql/dd::String_type            |       0.94942093 |
| memory/innodb/btr0pcur                |       0.89743423 |
+---------------------------------------+------------------+


Plus I used PMM to collect memory information 

To simulate the load I used the sysbench-tpcc (tpc-c derivate test) variant and run the tests simulating a load of 1024 threads against a cluster based on machine with 16 Core and 64Gb volumes ~3k IOPS, so not gigantic but not small. 


The finding was almost immediate:

+---------------------------------------+------------------+
| EVENT_NAME                            | current_usage_mb |
+---------------------------------------+------------------+
| memory/innodb/buf_buf_pool            |   46398.92578125 |
| memory/group_rpl/certification_info   |    1431.67934418 | <constantly increasing
| memory/group_rpl/GCS_XCom::xcom_cache |    1066.63542366 |
| memory/sql/Gtid_set::Interval_chunk   |      95.52413940 |
| memory/innodb/log_buffer_memory       |      64.00096130 |
| memory/sql/TABLE                      |      48.17613125 |
| memory/innodb/memory                  |      35.08897400 |
| memory/innodb/ut0link_buf             |      24.00006104 |
| memory/innodb/lock0lock               |      21.40064240 |
| memory/innodb/read0read               |      14.86782837 |
| memory/mysqld_openssl/openssl_malloc  |      12.05916119 |
| memory/mysys/KEY_CACHE                |       8.00215149 |
| memory/innodb/sync0arr                |       7.03147125 |
| memory/innodb/ha_innodb               |       6.84074974 |
| memory/innodb/lock_sys                |       5.25009155 |
| memory/sql/log_sink_pfs               |       5.00003052 |
| memory/innodb/ut0pool                 |       4.00017548 |
| memory/sql/dd::objects                |       2.82012177 |
| memory/innodb/std                     |       2.72515869 |
| memory/innodb/os0file                 |       2.63054657 |
| memory/innodb/os0event                |       2.35884857 |
| memory/innodb/trx0trx                 |       2.22647858 |
| memory/sql/TABLE_SHARE::mem_root      |       1.83777618 |
| memory/innodb/trx0undo                |       1.26304626 |
| memory/mysys/lf_node                  |       1.08828735 |
+---------------------------------------+------------------+


Ok then … What is the certification info???

What is group_rpl/certification_info?

In MySQL, memory/group_rpl/certification_info is a Performance Schema memory instrument. It tracks the exact amount of RAM allocated to store the Certification Database (or Certification Info).

In Group Replication, nodes do not lock rows across the network while a transaction is executing. Instead, transactions execute locally and optimistically. When it is time to commit, the transaction undergoes a Certification Process to ensure no other concurrent transaction in the cluster has modified the exact same rows. The certification_info buffer is the in-memory hash map that makes this conflict detection possible.

1. What is it used for?

The certification_info structure acts as a tracking ledger for recently modified rows.

Here is how it works under the hood:

  • The Key-Value Pair: It is fundamentally an in-memory dictionary. The key is the hash of a modified row (extracted from the transaction’s “write set”), and the value is the Global Transaction Identifier (GTID) of the transaction that successfully modified it.
  • Conflict Detection: When a new transaction attempts to commit, it broadcasts its write set and the “snapshot version” of the database it saw when it started. The certifier cross-references the incoming transaction’s write set against the certification_info map.
  • The Decision: If the certification_info shows that a row was modified by a newer GTID that the incoming transaction did not “see” when it started, a conflict is flagged, and the transaction is aborted. If no conflict exists, the transaction is certified, and the certification_info map is updated with the new write set and GTID.

The primary does not hold onto this memory out of stubbornness; it does so because purging that data too early would destroy the cluster’s consistency in the event of a failover.


In Group Replication, garbage collection for the certification_info buffer is not triggered just because a transaction commits on the primary. It is triggered by a concept called the Stable Set. 

Every node in the cluster periodically broadcasts a message to the rest of the group saying, “Here are the GTIDs I have successfully applied to my disk.” The cluster then calculates a global low watermark. This watermark is the highest transaction GTID that every single member of the group has successfully applied. Garbage collection is only allowed to purge write-sets from the certification database that fall below this global watermark.
To note that this purge is a synchronous operation during which writes are forbidden.

2. How the Apply Queue Stalls the Watermark

When a secondary node starts lagging, its applier queue grows. This means the secondary is receiving transactions from the network quickly, but its SQL thread is too slow to actually execute them and commit them to disk.

Because the secondary hasn’t applied these transactions, it cannot report those GTIDs back to the group as “finished.”

  • The lagging secondary’s local watermark stalls.
  • Therefore, the global low watermark for the entire cluster stalls.
  • Because the global watermark hasn’t moved forward, the garbage_collect function on the primary (and all other nodes) says, “I am not allowed to delete any write-sets yet.”
  • As the primary continues to process new writes, the certification_info memory buffer grows continuously.

3. Why the Primary Cannot Purge Early

we might wonder: If the transaction is already committed on the primary, why does the primary care if the secondary has applied it? Why not just drop the write-set from its own memory?

The answer comes down to Failover Safety and Distributed Conflict Detection. GR is a shared-nothing, decentralized architecture. Even if you are running in Single-Primary  mode (keep this in mind will be important later), the underlying engine uses the exact same logic as Multi-Primary mode. 

Here is why the primary is forbidden from purging that data:

  • The Failover Scenario: Imagine our primary node crashes right now. The lagging secondary (which still has a massive apply queue) is immediately elected as the new primary.
  • The Conflict Risk: As the new primary, it starts accepting new writes from your application. However, it still has thousands of old transactions in its applier queue that it hasn’t written to disk yet!
  • The Necessity of the Buffer: When a new write comes in, the new primary must check if that write conflicts with any of the pending transactions in its apply queue. It does this by checking the certification_info map. If the old primary had purged the global certification data early, the new primary wouldn’t have the write-sets for those pending transactions. It would blindly accept the new write, causing a massive data conflict and breaking the replication group entirely.

Fine Marco, then what is the effect of this?


Well, drums roll …

… When a secondary node is elected as the new primary during a failover, it does not immediately open the floodgates to new writes. It keeps its super_read_only variable set to ON until it has completely drained its local apply queue of all transactions that were certified prior to the election.

This is an intentional design choice to guarantee that the new primary’s state is completely consistent with the old primary before it starts accepting new data.


4. Immediate Write Rejections (No Built-in Queuing)

The most critical impact to understand is that the new primary does not queue or pause new incoming writes while it catches up. It outright rejects them.

If our application or proxy routes a COMMIT, INSERT, UPDATE, or DELETE to the new primary while it is still processing the old queue, MySQL will immediately throw an error back to the client:

ERROR 1290 (HY000): The MySQL server is running with the –super-read-only option so it cannot execute this statement

5. The “Brownout” Window (Write Outage)

Because of this behavior, a failover in MySQL Group Replication does not instantly restore write availability. Our cluster experiences a “brownout”, a period where reads might succeed, but writes are entirely blocked.

The duration of this write outage is directly proportional to the size of the apply queue.

  • If the secondary was fully caught up, write availability is restored in milliseconds.
  • If the secondary was lagging by 50 minutes, your application will suffer a 50 minute write outage while the node applies the backlog.

6. Impact on Proxies (e.g., MySQL Router or ProxySQL)

If we are using a proxy layer to route your database traffic, the apply queue dictates how the proxy behaves during the transition:

  • MySQL Router: It continuously monitors the cluster topology and the super_read_only flag. Even though the node has technically been elected primary, Router will not open the read-write port to it until the apply queue drains and super_read_only flips to OFF. Depending on your application timeouts, client connections will either hang waiting for a writable connection or fail completely.
  • ProxySQL: Similar to Router, if it is configured to check for the read_only state, it will temporarily quarantine the new primary from the write hostgroup.
  • HAProxy (in Operator): Monitor both Primary state and read_only state, but it expose the Primary to writes causing the application to fail (bug we need to fix)  

7. Read Traffic and Stale Data

During this catch-up phase, the node will accept incoming SELECT queries (since it is still a valid database). However, because it is actively churning through the old primary’s backlog, the data being read is temporarily stale.

If your application reads a row that is sitting in the apply queue but hasn’t been committed to disk yet, it will get the old version of that row.

Why Flow Control is Critical

Because a large apply queue turns a seamless failover into a severe, application-breaking write outage, Group Replication includes the Flow Control feature.

Flow Control monitors the size of the apply queues across all secondaries. If a secondary starts lagging too far behind, Flow Control should actively throttle the write throughput on the current primary to allow the lagging node to catch up. It is essentially a trade-off: we accept a slight performance hit during normal operations to guarantee that your database recovers almost instantly during a failover.

However, this is not what really happens.

1. It is Reactive, Not Proactive (The Polling Blind Spot)

Flow control does not intercept and evaluate every single transaction in real-time. Instead, it relies on a periodic polling interval governed by group_replication_flow_control_period (which defaults to 1 second).

Once a second, the cluster checks the size of the apply queues and the certifier queues.

  • The Vulnerability: If our application generates a massive spike of 50,000 writes in 500 milliseconds, the primary will happily accept and certify all of them. Flow control will not even notice the spike until the next 1 second polling interval hits. By the time it decides to apply a throttle, the damage is already done, and the secondary’s queue is already overflowing.

2. The PID Controller’s “Soft Brake” Math

When flow control does decide to throttle, it does not simply freeze the primary. It uses a PID (Proportional-Integral-Derivative) controller algorithm to calculate a “write quota” (the maximum number of transactions the primary is allowed to commit in the next second).

The PID controller is deliberately tuned to be gentle. It wants to gracefully degrade performance rather than cause immediate application timeouts.

  • When the secondary’s queue breaches the group_replication_flow_control_applier_threshold (default 25,000 transactions), the PID controller reduces the primary’s quota incrementally.
  • The Failure Point: If the primary’s incoming write rate is astronomically higher than the secondary’s disk IO capacity, this incremental “step down” in the quota is too slow. The primary is still allowed to write, say, 10,000 transactions per second, while the secondary is only applying 2,000. The queue continues to grow aggressively despite the throttle being “active.”

3. The Concurrency Mismatch (Parallel vs. Serial)

This is often the silent killer that defeats flow control. Flow control makes mathematical assumptions about how fast the secondary should be able to apply transactions based on recent history.

However, the primary node might be executing writes using hundreds of highly concurrent threads. The secondary relies on the parallel applier to keep up. If the incoming workload suddenly includes transactions that cannot be parallelized, such as writes hitting overlapping rows, cascading foreign key updates, or DDL statements, the secondary’s applier instantly drops from executing in parallel down to a single, serialized thread.

When this serialization happens, the secondary’s applier rate plummets instantly. Flow control, which only checks in once a second and adjusts gradually, cannot brake the primary fast enough to compensate for the secondary suddenly dropping to a crawl.

What can we do?

At the moment of writing there are only two things that can be done.

  1. Make Flow control more aggressive
  2. Increase the number of replication appliers


1. Making Flow Control More Aggressive

We can configure Flow Control to be a bit more aggressive. It will still remain a suggestion but a strong one.

How it works (The Configuration):

  • Lower the Threshold: By reducing group_replication_flow_control_applier_threshold (default is 25,000) to something like 1,000 or 500, we force the PID controller to kick in almost immediately when a spike occurs.
  • Remove the Safety Net: By keeping  group_replication_flow_control_min_quota to 0 (default), we remove the minimum write guarantee. If the secondary falls behind, Flow Control is allowed to throttle the primary’s writes down to zero, also if this will never happen.
  • Increase the Sensitivity: We can tweak the PID controller’s math (using the derivative and proportional tuning variables) to react much more aggressively to queue growth.
          group_replication_flow_control_hold_percent=100
          group_replication_flow_control_release_percent=5


The reality check, does it work?:

If the expectation is to have a rigid control over the applier queue on the lagging secondary, then the answer is NO. No matter what, at the moment flow control is not designed to act as we are used to in PXC (Percona Xtradb Cluster), where we have a rigid control of the pending queue also at the cost of delaying the writes. In Group Replication  the Flow Control will never bring the write to 0, the unfortunate aspect is that the mechanism is not enough to keep the queue under control.


2. Increasing Replication Appliers 

To help the secondary chew through the queue faster, we can increase the number of parallel threads it uses to write to disk.

How it works: We can increase the replica_parallel_workers (formerly slave_parallel_workers) setting. GR is exceptionally smart about this. Because of the certification process we discussed earlier, GR already knows exactly which transactions modify which rows. It uses a writeset-based dependency tracker to safely hand off non-conflicting transactions to multiple worker threads simultaneously.
The formula that is normally used to calculate the number of replication workers is to set 2.5 workers for each available core. IE if we have 14000m CPUs in our CR (K8) then we can assign ~35 workers, this is definitely higher than the default value of 4.   

The reality check, does it work?Yes, but only if our workload allows it.

  • The Catch – The Serialization Wall: Parallel appliers only work if the transactions do not conflict. If our application has 50 concurrent threads all trying to update the same “inventory count” row, or updating a highly contentious table, those transactions cannot be parallelized. The secondary’s coordinator thread will see the row-level conflicts and force those transactions to wait in line and execute sequentially. We could allocate 128 parallel workers, but 127 of them will sit idle while one thread does all the work.
  • The Catch – Context Switching: More threads do not magically create more disk IOPS. If we set the workers too high (e.g., beyond the physical CPU core count or disk IO capacity), the secondary’s InnoDB engine will spend more time context-switching and fighting over internal mutex locks than actually committing data. In many cases, over-allocating parallel workers actually slows down the apply rate.

Do we have any conclusions?

1. If HA is the goal, enforce Strict Flow Control

If our absolute top priority is High Availability, specifically achieving a near-zero Recovery Time Objective (RTO), we must configure an aggressive flow control.

  • The Logic: Fast failovers require small apply queues. To guarantee a small apply queue, we must strictly throttle the primary the millisecond the secondary starts to lag.
  • The Trade-off: we are protecting the cluster’s failover readiness at the expense of application write latency. If there is a massive write spike, our application will face timeouts and connection errors, but if the primary server suddenly catches fire, our database will recover and elect a new primary almost instantly.

The problem is that Group Replication is not able to act like that today, this is something we eventually need to implement to have better HA.

2. If Performance is the goal, relax Flow Control

If our top priority is keeping the application fast and ensuring COMMIT latencies remain extremely low, we should relax flow control or rely on the generous defaults.

  • The Logic: By relaxing flow control, we allow the primary to run at the absolute maximum speed its local disks and CPU allow. It does not care if the secondaries fall behind. Our application users remain happy and experience zero throttling.
  • The Trade-off: We are accepting severe risks to your HA posture. If the primary crashes while the secondaries have a massive apply queue, we will suffer a long write outage (the brownout) while the new primary catches up. Additionally, we are accepting the risk that the certification_info memory buffer will grow significantly on the primary and eventually have the pod OOMKilled .

3. Is this not what Asynchronous replication with semy-sync offers?


1. The Similarities

If we look purely at how a single transaction flows and how a failover behaves, GR and Semi-Sync look like twins:

  • The Durability Guarantee: Semi-Sync: The primary waits to commit until at least one secondary confirms it has received the transaction and written it to its local Relay Log. 
    • GR: The primary waits to commit until a majority quorum of nodes confirm they have received the transaction, certified it, and written it to their local relay logs.
  • The Failover Delay (The Queue):  In both systems, the secondary receiving the data does not mean the secondary has applied the data to its InnoDB tables.
    • If a crash happens, both systems require the new primary to completely execute its pending queue (Relay Log for Semi-Sync, Apply Queue for GR) before it is safe to accept new writes.

2. The Crucial Differences

If they behave so similarly, why use GR at all?
The differences lie entirely in automation, consensus, and split-brain protection. Semi-Sync is just a data transport mechanism; GR is a full state-machine cluster.

Here is what GR gives you that Semi-Sync does not:

  • Automatic Election and Orchestration:
    • Semi-Sync: If the primary dies, Semi-Sync does nothing. The cluster sits there broken. You must rely on external tools (like Orchestrator or manual DBA intervention) to detect the crash, pick the most up-to-date secondary, wait for its relay log to apply, disable read_only, and re-point the application.
    • GR: The cluster detects the failure natively. The remaining nodes use Paxos consensus to elect a new primary automatically, manage the queue drain natively via the super_read_only flip we discussed, and self-heal.
  • Split-Brain Protection (Network Partitions):
    • Semi-Sync: If our network splits in half, an external failover tool might accidentally promote a secondary while the old primary is still alive and accepting writes. We now have a split-brain, and our data is permanently corrupted.
    • GR: GR enforces strict quorum. If a network split happens, the side of the network with the minority of nodes will automatically fence itself off and refuse all writes. Split-brain is mathematically prevented.
  • The Certification Database:
    • As we established, GR requires the certification map to ensure the new primary doesn’t accept writes that conflict with its unapplied queue. Semi-Sync does not have this; it relies entirely on the external failover tool to guarantee no writes touch the new primary until the relay log is 100% applied.

3. Final observation

If we are using Single-Primary GR with relaxed flow control, we have essentially built a highly-automated, consensus-driven version of Semi-Sync replication. 

We have the exact same apply-queue bottleneck during failover, but we have traded the need for external orchestrator tools for built-in Paxos consensus and native split-brain protection.


Conclusions (for real)

When we run MySQL on a traditional, dedicated Virtual Machine, memory limits are “soft.” If the certification_info database explodes and consumes an extra 10GB of RAM because of the applier lag, the Linux OS might start aggressively swapping inactive pages to disk, but the MySQL process usually survives. Performance degrades, but the database stays online.

In Kubernetes, memory limits are “hard.” As we discussed earlier, Kubernetes enforces pod memory limits via cgroups v2 (memory.max). The Linux kernel’s OOM Killer has no understanding of database quorum, failover states, or apply queues. It only sees math: Working Set Size > memory.max = Terminate Process (Exit Code 137).

The Chain Reaction of Relaxed Flow Control in k8s

If we prioritize “performance” by relaxing Flow Control in a Kubernetes environment, we are essentially setting a ticking time bomb. Here is the chain of events:

  1. The Spike: Our application experiences a massive write spike.
  2. The Queue: The secondary pod’s disk cannot keep up, and its applier queue grows to 1,000,000 transactions.
  3. The Memory Sprawl: Because the queue is large, the global low-watermark stalls. The Primary pod is forbidden from garbage collecting the certification_info map. The in-memory hash map balloons in size.
  4. The Execution: The memory.current metric will reach the memory.max, kernel will trigger the OMMKill process. First action will be to try to free the page.cache related to the process. If the purge is successful and the memory.current is less than memory.max then the process will persist, otherwise the kernel will kill it.
    We can use the WSS metric to predict a successful OMMKill.
    The Primary pod’s Working Set Size (WSS) breaches its Kubernetes memory limit, this is a fair estimate not an absolute value.
  5. The Catastrophe: The Linux OOM Killer instantly assassinates the Primary MySQL process.

Because we tried to avoid a few seconds of write latency by keeping relaxed Flow Control, we inadvertently caused a hard crash of the primary database pod, with long write downtime.

The Architectural Law

Therefore, here is my statement as architectural law for containerized environments: In Kubernetes, High Availability and Pod stability are so intrinsically linked that Flow Control must act as hard as it can to cap the apply queue.

  • We cannot allow unbounded memory growth in a container. The only way to bound certification_info memory is to bound the apply queue.
  • The only way to bound the apply queue is with strict, aggressive Flow Control.
  • Increasing the number of replication appliers helps but is not the conclusive answer.

In a Kubernetes environment, we must tune group_replication_flow_control_applier_threshold to a strict, low number, and accept that during massive traffic spikes, our application will experience write throttling. It is infinitely better for our application’s connection pool to wait 2 seconds for a COMMIT to succeed than for the primary database pod to be violently OOMKilled by the kernel, and have to wait for minutes or hours to recover write capabilities.

Note

Just as a mention this is exactly how Percona Operator with Percona Xtradb Cluster works. To be more specific, PXC and in general solutions based on Galera have a Flow Control mechanism that enforces the queue to be inside hard limits. While this more invasive control may be noticeable at application level, it guarantees that the other nodes are not lagging behind the primary and this is why it is a stronger HA solution in the Kubernetes environment.


Reference

https://github.com/Tusamarco/mysqloperatorcalculator

Managing Resources and OOMKills: Resource Management for Pods and Containers (This page details how memory limits are enforced reactively by the Linux kernel via OOM kills).

How WSS triggers Evictions: Node-pressure Eviction (This page explicitly details how the kubelet uses the memory.available signal, which is derived from node capacity minus the working set size).

Latest changes. Pointer to the code 

Swap Memory Management (Core Concepts & Configuration): https://kubernetes.io/docs/concepts/cluster-administration/swap-memory-management/

The post The Failover Brownout: Rethinking High Availability in MySQL Group Replication appeared first on Percona.

Apr
21
2026
--

Impacts of updates in open-source databases

We recently looked at how various open-source database engines maintain their secondary indexes (in a previous analysis) and found significant differences.  The maintenance of indexes is not the only aspect where storage engines differ, another significant difference is how they handle simple row updates.  These updates highlight how these open-source databases organize data and manage the versions of records while processing transactions. The management of versions is called MVCC, which stands for Multi-version Concurrency Control. In this post, we’ll examine one aspect of open-source database engines: how IO-efficient they are for simple updates.

While performing updates, storage engines require access to storage for multiple reasons. Obviously, in order to update a record, it must be read from storage and, eventually, it will need to be written back. The storage engines also have to manage the record versions which, depending on the MVCC implementation, may require additional IOPs.  All storage engines also use operational journal to sequentially log their operation for recovery purpose. These journals are called redo or WAL and are normally only written to. Finally, there must be crash protections against partial writes which could cause data corruption. Such protections also normally only consist of writes.

For this post, we’ll conduct an experiment using the dataset created during the previous post and update an unindexed column from 100k randomly chosen rows. In order to see the impacts of data reorganization, we’ll run updates to the same set of rows a second time. In both cases, we’ll examine the total number of required IOPs, limited to a size of 16KB.

Generalities about MVCC

Since the MVCC implementations are less known, let’s first examine what exactly their responsibilities are. MVCC is required only when there is significant concurrency for access and manipulation of data. At low concurrency, locking is simpler and often preferred. A good example of this is MySQL’s MyISAM engine, where any attempt to write to a table results in a full table lock.  At higher concurrency, many sessions have queries running simultaneously. MVCC manages the record versions and determines which version a given transaction can see and update.

IO-wise, the aspects of MVCC that concern us relate to the handling and storage of the record versions. These versions are organized into lists and sorted by age. From a base record, there are two possible approaches for these lists: from oldest to newest (O2N) or from newest to oldest (N2O). Most storage engines use the N2O approach, with PostgreSQL being a notable exception, using mostly an O2N approach. Let’s discuss in more detail examples of these two implementations.

PostgreSQL MVCC

As mentioned above, PostgreSQL uses mostly an oldest to newest (O2N) approach. When a row is updated, the whole row is copied to a new position, and only the version pointer (CTID) is updated in the original row. The old version will eventually be removed by the vacuum process. In a sense, an update in PostgreSQL is essentially an INSERT followed by an eventual DELETE. When a row needs to be accessed without an index, the oldest version is accessed and then the versions are iterated until the version compatible with the current transaction number is found. This means heavily updated rows could have a long list of versions and be slower to access. At some point, though, the vacuum process will kick in and shrink the list, removing the irrelevant versions.

PostgreSQL uses physical positions of rows (CTID) as pointers for indexes. After an update to a non-indexed column, the original index record points to the oldest version. An additional index entry is added if the updated row have been written a new page. The PostgreSQL behavior with row versions is quite complex, it is likely there are aspects I don’t fully grasp. If someone wants to experiment and dig further on this topic, I recommend the pageinspect extension, it is really awesome. Eventually, IOPs will be needed during vacuum to remove the old versions.

For more information on this topic, the following link is a good starting point on PostgreSQL MVCC implementation. We must also keep on our radar a project developing a new MVCC implementation called Orioledb but so far, it has a low adoption rate.

InnoDB MVCC

InnoDB is a fairly typical implementation of the newest-to-oldest (N2O) approach. For simplicity, we’ll restrict ourselves to updates. When a transaction updates a row, the row diff (or delta) is copied to the undo space. Then, the row is edited, and as part of the process, the field DB_ROLL_PTR is set to point to the undo position of the row diff. Finally, the field DB_TRX_ID is set to the ID of the transaction modifying the row.  When another transaction attempts to read the same row, if its transaction ID is smaller than the recorded DB_TRX_ID, the DB_ROLL_PTR points to the previous version of the row.

When no running transaction needs an undo entry, the purge process removes it. That means for short transactions, the undo space lives in memory and is only persisted by the redo log. This removes a significant amount of IOPs. Also, the secondary indexes are not impacted because they use logical pointers, the primary key. For more information on InnoDB MVCC, see this excellent article.

Results

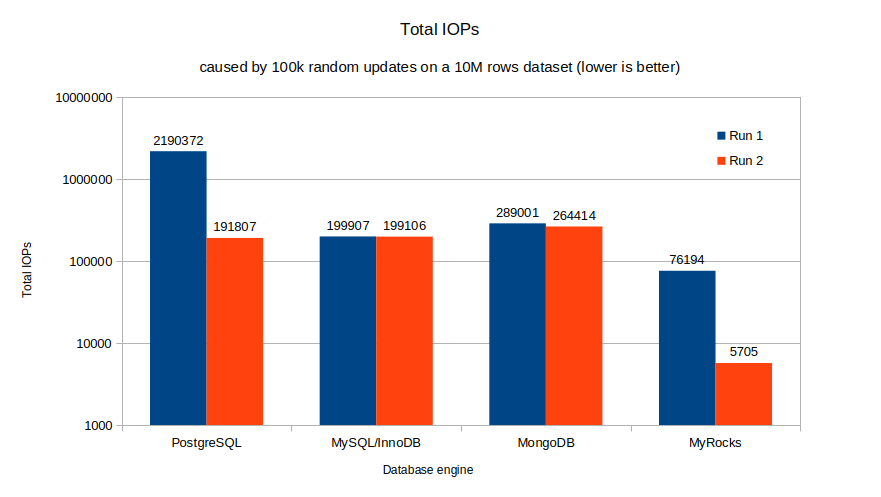
The starting point of this experiment is the dataset at the end of our previous experiment, centered on the maintenance of secondary indexes. These datasets have 10 million rows in a table with 7 indexes, one primary on an integer and 6 on large varchar UUID values. From that dataset, 100k rows were randomly selected for an update on the unindexed column, status.  The updates were executed twice to illustrate the reorganization of data caused by the MVCC implementations.  The best way to illustrate the impacts is to report the total number of IOPs (read and writes) to/from storage. For consistency, IOP sizes are limited to 16KB. The results are shown below:

Total number of IOPs required to perform 100k updates

It is important to note the logarithmic scale used for Total IOPs. The large variation in IOPs imposed that choice of scale for readability.

PostgreSQL

The “Run 1” of PostgreSQL illustrates the issues with its MVCC implementation. It is actually worse than I expected. This first set of updates required, on average, nearly 22 IOPs per update. A significant amount of these IOPs are caused by Full Page Writes (FPW). FPW occurs the first time a page is modified after a checkpoint. It is there to protect against torn pages, serving the same purpose as the InnoDB doublewrite buffer with MySQL.

Since PostgreSQL MVCC copies updated rows to new pages (which are append-only), this has the benefit of grouping the active rows. In our experiment, the updated rows, about 1% of all the rows, end up grouped together in a limited number of database pages. Because of this, the “Run 2” required less than 1/10th of the IOPs of “Run 1”. It is important to highlight the importance of this behavior as nearly all database workloads present a small subset of very active rows. While PostgreSQL old MVCC implementation bears a very high cost for the initial run, it kind of self-tunes for a much better “Run 2”.

InnoDB

InnoDB results are better in terms of IOPs and feature-less, both runs are within a few hundred IOPs of each other. This is a testimony to its younger MVCC design. The actual number of IOPs required is just a few percent above the second run of PostgreSQL. This means, while its behavior is excellent, performance will not improve over time with a small set of active rows.

MongoDB

MongoDB WiredTiger engine required about 33% more IOPs than InnoDB in our experiment. Because of the way MongoDB evaluates updates, the actual value of the status had to be modified between the update runs, otherwise the second update would have been a no-op. The second run required about 8% less IOPs than the first one.

MyRocks

RocksDB is optimized for writes, and it shows. MyRocks demonstrates a significant advantage over other engines. It required about 1/3rd of the IOPs of the second contender (InnoDB) for “Run 1” and, amazingly, only 1/30th of PostgreSQL (2nd best) for “Run 2”. Clearly, if your workload is dominated by writes, and you can cope with slightly slower reads, you should take a look at MyRocks.

Conclusion

This database experiment sheds some light on the various Multi-version concurrency control implementations of popular database engines. We have observed large variations in the number of required IOPs between engines for similar workloads.

Here are some key points to remember:

  • PostgreSQL MVCC implementation is the most inefficient in terms of IOPs
  • PostgreSQL efficiency improves considerably for “Run 2”.
  • PostgreSQL groups active rows together, improving efficiency.
  • InnoDB is a bit more efficient than MongoDB, but both are stable between runs
  • Given this is a write-only benchmark, MyRocks efficiency is in a different league as it plays to its strength
  • MyRocks is the clear winner, especially for the 2nd run, at more than an order of magnitude better than any other engine
  • MyRocks also groups active rows together, improving efficiency

The post Impacts of updates in open-source databases appeared first on Percona.
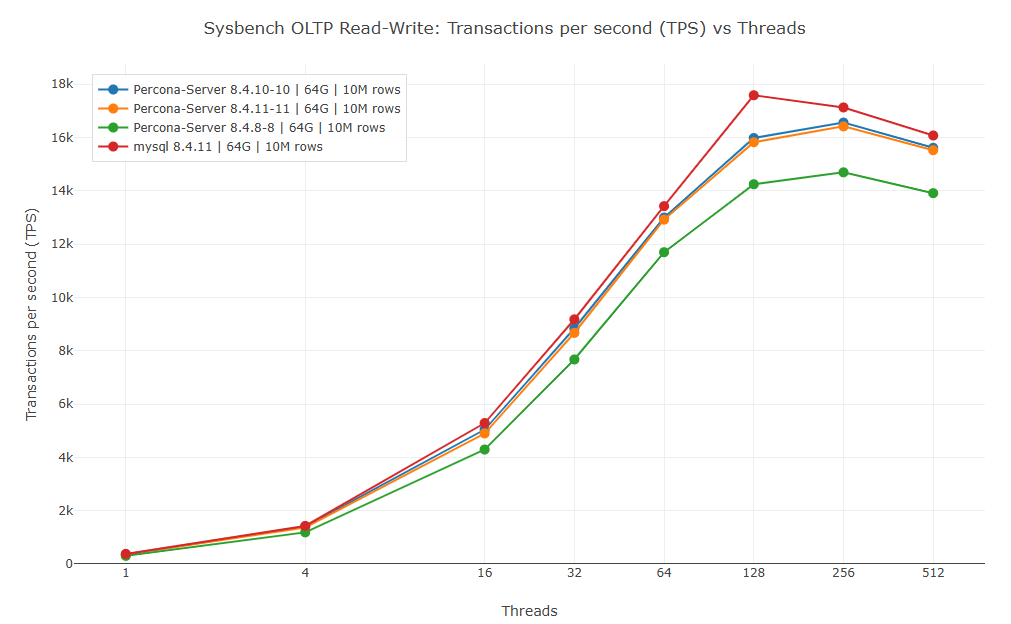
Apr
01
2026
--

Benchmarking MyRocks vs. InnoDB in Memory-Constrained Environments

Benchmarking MyRocks vs. InnoDB in Memory-Constrained Environments

It is a well-known fact in the database world that InnoDB is incredibly fast when the entire database fits into memory. But what happens when your data grows beyond your available RAM?

MyRocks, built on RocksDB, is frequently recommended as a superior choice for environments constrained by memory, thanks to its design for efficient operation with limited resources. This advantage was previously supported by Vadim Tkachenko in his MyRocks Performance blog post. Therefore, our current analysis sought to validate MyRocks’ suitability for such scenarios using the most recent Percona Server for MySQL 8.4.7-7 with MyRocks 9.3.1-3, tested on modern hardware. Specifically, we benchmarked MyRocks against InnoDB in conditions where the database size exceeded available memory, thereby imposing a heavy load on storage I/O.

Test Setup

VM Configurations

Our primary goal was to evaluate the scalability of MyRocks versus InnoDB across varying hardware resources. We tested three different VM configurations to observe how each engine adapted to resource constraints:

  • Large: 64 vCPUs + 128 GB RAM
  • Medium: 32 vCPUs + 64 GB RAM
  • Small: 16 vCPUs + 32 GB RAM

Database Sizing

Using sysbench, we populated a database with 32 tables of 20 million rows each (640 million rows in total). The resulting on-disk database sizes:

  • InnoDB: 161 GB
  • MyRocks (with LZ4 compression): 125 GB

As a result, these sizes create a critical distinction in our test scenarios. The database size exceeds available memory (significantly so for the Medium and the Small instance), forcing the engines to rely heavily on storage I/O and testing their efficiency under pressure.

Engine Tuning: Optimal I/O Settings

We aimed to identify optimal configurations for MyRocks and InnoDB engines on three distinct hardware profiles and compare their relative performance ratios. Additionally, we maintained ACID compliance throughout the benchmark, with binary logging enabled. The following default settings remained unchanged:

  • sync_binlog=1
  • innodb_flush_log_at_trx_commit=1
  • rocksdb_flush_log_at_trx_commit=1

Before running the benchmarks, we tuned both engines for maximum throughput in this specific environment. In fact, they required very different approaches. For InnoDB, the best performance was achieved using direct I/O for writes:

  • innodb_flush_method=O_DIRECT (Direct Writes on; default for MySQL/Percona Server 8.4)
  • innodb_buffer_pool_size set to 75% of available memory.

In contrast, for MyRocks we found that relying on the OS page cache yielded better results than direct I/O. We kept the default MyRocks page cache options (Direct Reads and Writes off), allowing the page cache to handle the heavy lifting:

  • rocksdb_use_direct_reads=OFF
  • rocksdb_use_direct_io_for_flush_and_compaction=OFF
  • rocksdb_block_cache_size set to only 1/8 of available memory.

The observation that optimal throughput is achieved when rocksdb_block_cache_size is configured at just one-eighth of the available memory suggests that this parameter is not directly equivalent to innodb_buffer_pool_size, indicating that MyRocks’ caching mechanism is less efficient than InnoDB’s buffer pool.

Workloads

We used three standard Sysbench OLTP scripts to simulate different usage patterns:

  1. Read Only (oltp_read_only.lua): Standard read-only workload — 14 queries/trx: 10 point selects, 4 range queries (simple, sum, order, distinct).
  2. Write Only (oltp_write_only.lua): Pure data ingestion and modification — 4 queries/trx: 1 index update, 1 non-index update, 1 delete, 1 insert.
  3. Mixed Read/Write (oltp_read_write.lua): A balanced mix of selects, updates, deletes, and inserts — 18 queries/trx: The 14 read queries from Read Only + the 4 write queries from Write Only.

Furthermore, we used the default --rand-type=uniform to maximize memory pressure: unlike a Pareto distribution, where ~80% of accesses hit only ~20% of the data, uniform access spreads queries evenly across all rows — effectively simulating a ~5x larger working set and forcing both engines to contend with the full dataset exceeding available RAM. Detailed command-line options are listed in the appendix.

Results

All benchmarks were executed using Percona Server 8.4.7-7. The results below are presented in Queries Per Second (QPS). We conducted tests across concurrency levels ranging from 8 to 64 threads. In the tables below, cells are color-coded as a heatmap comparing InnoDB and MyRocks directly at each concurrency level: green indicates higher (better) throughput, while red indicates lower throughput.

Round 1: Read Only Workload

Configuration for Read Only Workload 8 thds 16 thds 32 thds 64 thds
InnoDB Small Instance (32 GB, 16 vCPU) 20,157 36,956 57,088 71,989
InnoDB Medium Instance (64 GB, 32 vCPU) 23,229 46,134 77,052 98,325
InnoDB Large Instance (128 GB, 64 vCPU) 34,670 69,508 133,670 191,537
MyRocks Small Instance (32 GB, 16 vCPU) 17,285 30,644 44,141 53,836
MyRocks Medium Instance (64 GB, 32 vCPU) 20,228 39,069 56,491 68,572
MyRocks Large Instance (128 GB, 64 vCPU) 30,595 65,481 127,327 179,350


InnoDB outperformed MyRocks in the read-only scenario across every configuration, but the margin varied dramatically with instance size. On the Large instance, the gap stayed in single digits — just 5–7% at 32 and 64 threads — where the 128 GB buffer pool could cache a substantial portion of the 161 GB dataset. However, on the more memory-constrained Small and Medium instances, InnoDB’s advantage grew with concurrency, reaching 34% on Small and 43% on Medium at 64 threads. This suggests that InnoDB’s buffer pool management becomes increasingly effective relative to MyRocks’ OS page cache as concurrency rises, but only when memory is tight enough that both engines are fighting for I/O. Conversely, when more memory is available, MyRocks’ compressed 125 GB dataset nearly fits in RAM, closing the gap.

Round 2: Mixed Read/Write Workload

Configuration for Mixed Read/Write 8 thds 16 thds 32 thds 64 thds
InnoDB Small Instance (32 GB, 16 vCPU) 11,521 19,520 28,346 36,110
InnoDB Medium Instance (64 GB, 32 vCPU) 13,156 23,991 37,414 48,714
InnoDB Large Instance (128 GB, 64 vCPU) 17,664 32,113 54,424 73,957
MyRocks Small Instance (32 GB, 16 vCPU) 15,008 25,950 36,192 44,031
MyRocks Medium Instance (64 GB, 32 vCPU) 16,848 31,251 48,617 60,480
MyRocks Large Instance (128 GB, 64 vCPU) 22,878 41,565 74,066 100,436


Once writes entered the picture, the balance shifted decisively in MyRocks’ favor. Specifically, MyRocks outperformed InnoDB by 22–36% across every instance size and concurrency level. The advantage was remarkably consistent: roughly 28–33% on the Small and Medium instances, and 29–36% on the Large instance. Notably, the mixed workload contains 14 read queries and only 4 write queries per transaction, yet the write-side efficiency of MyRocks’ LSM-tree architecture more than compensated for InnoDB’s read-side strengths. Overall, this consistency across hardware profiles indicates that the benefit is structural — rooted in how each engine handles I/O under memory pressure — rather than a quirk of a particular VM size.

Round 3: Write Only Workload

Configuration for Write Only Workload 8 thds 16 thds 32 thds 64 thds
InnoDB Small Instance (32 GB, 16 vCPU) 8,019 14,752 22,649 26,225
InnoDB Medium Instance (64 GB, 32 vCPU) 8,704 17,072 31,326 36,219
InnoDB Large Instance (128 GB, 64 vCPU) 9,520 19,358 41,045 61,334
MyRocks Small Instance (32 GB, 16 vCPU) 14,421 24,515 37,751 44,721
MyRocks Medium Instance (64 GB, 32 vCPU) 14,760 26,814 43,819 62,622
MyRocks Large Instance (128 GB, 64 vCPU) 14,572 27,455 47,276 71,736


The write-only workload produced the most dramatic differences. On the Small instance, MyRocks was 67–80% faster than InnoDB; on the Medium instance, 40–73% faster. Even on the Large instance, MyRocks maintained a 15–53% lead. Furthermore, an interesting pattern emerges in the MyRocks numbers: at 8 threads, write throughput was nearly identical across all three instance sizes (~14,400–14,800 QPS), suggesting that at low concurrency MyRocks’ I/O efficiency — not raw hardware — is the primary performance driver. InnoDB, by contrast, started from a much lower baseline (8,000–9,500 QPS at 8 threads) but scaled more steeply with additional resources, reaching 61,334 QPS on the Large instance at 64 threads — still 15% behind MyRocks’ 71,736 QPS. In summary, the takeaway is clear: when writes dominate and memory is scarce, MyRocks’ LSM-tree design delivers substantially higher throughput, and the advantage is greatest on the smallest, most resource-constrained instances.

Key Takeaways

1. InnoDB retains a read-only advantage, but the gap depends on available memory. InnoDB was 5–7% faster on the Large instance, where its buffer pool could cache a meaningful portion of the dataset. On memory-constrained Small and Medium instances, InnoDB’s lead grew to 17–43% at higher concurrency — yet even there, InnoDB’s absolute read performance remained lower than what MyRocks achieved on one instance size larger.

2. MyRocks wins mixed workloads convincingly. Across all instance sizes and concurrency levels, MyRocks delivered 22–36% higher throughput than InnoDB in the Mixed Read/Write round. The write-side efficiency more than compensated for InnoDB’s read-side strengths.

3. MyRocks dominates write-heavy workloads. In the Write Only round, MyRocks outperformed InnoDB by 60–80% on the Small and Medium instances and by 15–53% on the Large instance. Its LSM-tree architecture converts random writes into sequential I/O, a decisive advantage when disk access is the bottleneck.

4. Memory constraints amplify MyRocks’ advantage. Across all write-involving workloads, the performance gap between MyRocks and InnoDB was widest on the smallest instances, where the database-to-memory ratio was highest. For example, on the Small instance in the write-only test, MyRocks was up to 80% faster than InnoDB. As available memory increased, InnoDB’s buffer pool could cache more of the working set and partially close the gap — but never enough to overtake MyRocks.

5. MyRocks scales efficiently on modest hardware. Write throughput on MyRocks remained remarkably consistent across instance sizes at low concurrency (~14,400–14,800 QPS at 8 threads regardless of VM size), indicating that its I/O efficiency — not raw hardware — is the primary performance driver. InnoDB, by contrast, needed the Large instance to approach comparable write throughput at high concurrency.

Practical Guidance

If your workload is predominantly reads and you have sufficient RAM to cache a meaningful portion of your dataset, InnoDB is still the best choice. However, if your application involves significant write activity — especially in environments where the dataset substantially exceeds available memory — MyRocks offers a compelling performance advantage. For mixed workloads in memory-constrained environments, which represent a common real-world scenario, MyRocks delivers consistently higher throughput and should be seriously considered as an alternative to InnoDB.

Beyond raw throughput, MyRocks delivered a 22% smaller on-disk footprint (125 GB vs. 161 GB) thanks to LZ4 compression — a meaningful reduction that compounds across large fleets and translates directly into lower storage costs. Combined with up to 80% higher write throughput under memory pressure and 22–36% higher mixed-workload performance, MyRocks presents a strong case for deployments where datasets are growing faster than memory budgets. Moreover, as DRAM and NAND prices continue to rise — driven in part by surging demand from AI infrastructure — the ability to do more with less memory becomes an increasingly valuable engineering lever. For teams running large InnoDB databases that are hitting I/O bottlenecks or facing prohibitive hardware upgrade costs, MyRocks offers a practical path to better performance without scaling up.

Appendix

Hardware Setup

We used a high-performance Supermicro server:

  • CPU: EPYC 9654, 96 cores, 192 threads available
  • Memory: 512 GB DDR5 4800 MT/s
  • Storage: 2 x 3.2 TB Micron 7450 MAX U.3 SSD
  • Filesystem: xfs with “noatime,nodiratime,logbsize=256k,discard” attributes
  • OS: Ubuntu 24.04.3, kernel 6.8.0-90-generic with “performance” governor, turbo boost off, address randomization off

We ran our tests inside KVM virtual machines to simulate realistic cloud/virtualized environments. To isolate performance, we disabled access to the host page cache (driver cache='none') and used a separate 1 TB partition for virtual machines (driver type='raw' io='native'). Furthermore, to maximize stability, we disabled memory ballooning and ensured only one virtual machine was active at any given time.

Benchmark Procedure

  1. Data Preparation: We created a template database consisting of 32 tables, each containing 20 million rows, for a total of 640 million rows.
  2. Workload Execution: We tested three distinct workloads at concurrency levels of 8, 16, 32, and 64 threads. The duration for each test run was 900 seconds for read workloads and 1800 seconds for all other workloads. We discarded initial unstable results to account for the database warm-up phase.
  3. State Restoration: To ensure consistency, the database was restored from the template after each workload completion.

Configuration Files and Scripts

To ensure transparency and reproducibility, we have made all scripts and configuration files used for these benchmarks available below.

Sysbench Command-Line Options

We used the following sysbench workloads with default settings:

Read Only = "oltp_read_only.lua --skip-trx=off --point-selects=10 --range_selects=on --simple-ranges=1 --sum-ranges=1 --order-ranges=1 --distinct-ranges=1 --rand-type=uniform"
Mixed Read Write = "oltp_read_write.lua --skip-trx=off --point-selects=10 --range_selects=on --simple-ranges=1 --sum-ranges=1 --order-ranges=1 --distinct-ranges=1 --index-updates=1 --non-index-updates=1 --delete_inserts=1 --rand-type=uniform"
Write Only = "oltp_write_only.lua --skip-trx=off --index-updates=1 --non-index-updates=1 --delete_inserts=1 --rand-type=uniform"

The post Benchmarking MyRocks vs. InnoDB in Memory-Constrained Environments appeared first on Percona.
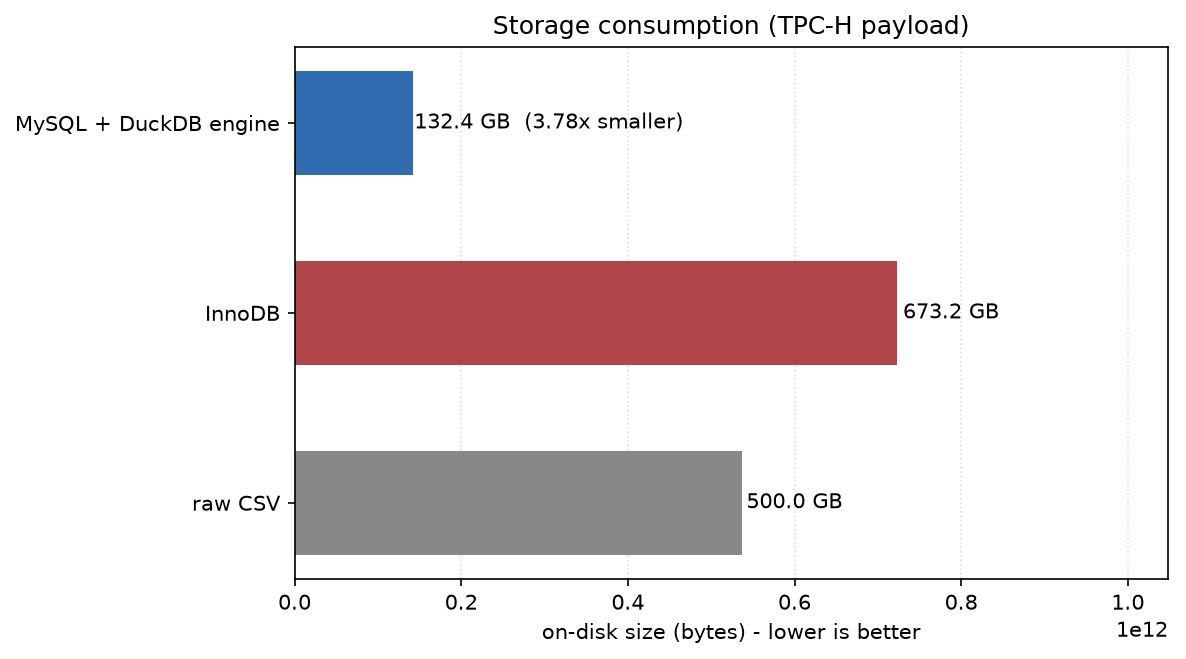
Apr
01
2026
--

Benchmarking MyRocks vs. InnoDB in Memory-Constrained Environments

Benchmarking MyRocks vs. InnoDB in Memory-Constrained Environments It is a well-known fact in the database world that InnoDB is incredibly fast when the entire database fits into memory. But what happens when your data grows beyond your available RAM? MyRocks, built on RocksDB, is frequently recommended as a superior choice for environments constrained by memory, […]

Mar
26
2026
--

2026 – MySQL Ecosystem Performance Benchmark Report

By Percona Lab Results  ·  2026  ·  MySQL MariaDB Percona Benchmark Database MySQL Ecosystem Performance Benchmark Report 2026 Comparative Analysis of InnoDB-Compatible Engines — Percona Lab Results Repository: github.com/Percona-Lab-results/2026-interactive-metrics Interactive graphs available: Explore the full dataset dynamically — click any graph below to open the interactive version. OLTP Read-Write Local — interactive benchmark graph OLTP […]

Jan
23
2026
--

MySQL January 2026 Performance Review

MySQL January 2026 Performance ReviewThis article is focused on describing the latest performance benchmarking executed on the latest releases of Community MySQL, Percona Server for MySQL and MariaDB.  In this set of tests I have used the machine described here.  Assumptions There are many ways to run tests, and we know that results may vary depending on how you […]

Jan
14
2026
--

The Importance of Realistic Benchmark Workloads

The Importance of Realistic Benchmark WorkloadsUnveiling the Limits: A Performance Analysis of MongoDB Sharded Clusters with plgm In any database environment, assumptions are the enemy of stability. Understanding the point at which a system transitions from efficient to saturated is essential for maintaining uptime and ensuring a consistent and reliable user experience. Identifying these limits requires more than estimation—it demands […]

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com