Sep
16
2026
--

Group Replication Beyond a Single Cluster: DC-DR with Percona (PS MySQL) Operator

A while ago, we discussed the cross-site replication feature of the Percona PXC operator. Recently, a similar cross-site replication feature was introduced in the Percona (PS MySQL) operator v1.2.0, a topology based on Group Replication/InnoDB Cluster.

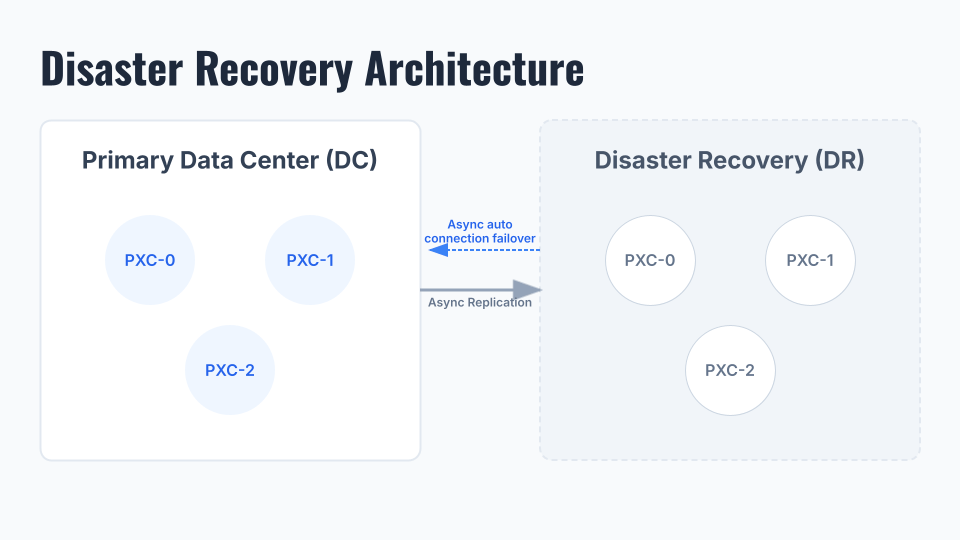
In this blog post, we will explore how to add a DR Cluster to an existing DC Cluster to form a ClusterSet environment, which provides a seamless switchover between DC/DR members. The good part is that all the complexity and configuration will be managed by the Percona operator, with very few setup steps required.
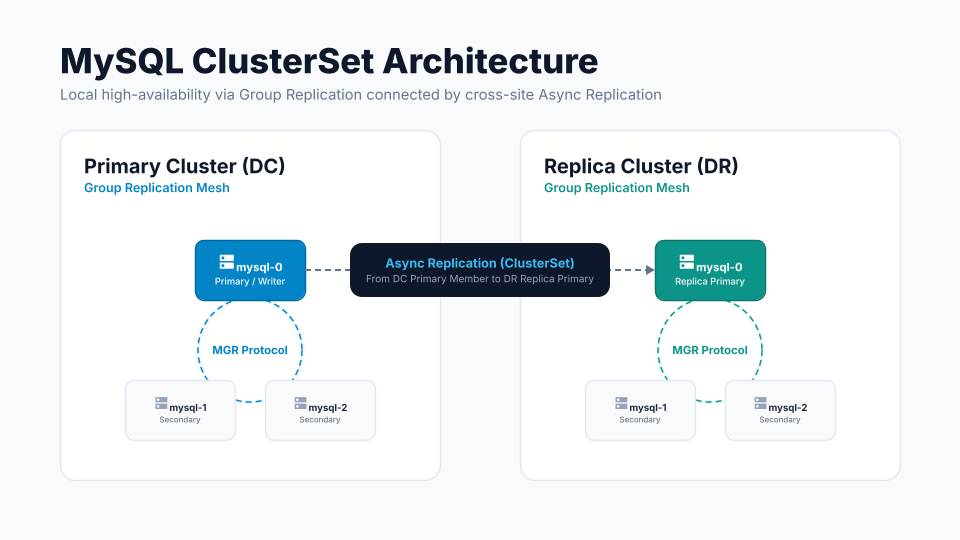
Group Replication (DC-DR) using Innodb ClusterSet


Let’s discuss how we can implement a cross-site replication (DC-DR) topology across two separate database clusters.

Environment used for Demonstration

  • Two separate database clusters (pscluster1 and pscluster2) are deployed within a single GCP/Kubernetes environment, each managed by a dedicated operator.
  • Percona Operator for MySQL( based on Percona Server for MySQL) has a version. 1.2.0
  • MySQL version 8.4.10.
  • Network connectivity between DC/DR components.

DC (pscluster1) configuration

Step 1:  Deploying the cluster on the DC side.

shell> kubectl get ps -n ps
NAME          REPLICATION         ENDPOINT                 STATE   MYSQL   ORCHESTRATOR   HAPROXY   ROUTER   AGE
ps-cluster1   group-replication   ps-cluster1-haproxy.ps   ready   3                      3                  28m

shell> kubectl get pods -n ps
NAME                                             READY   STATUS    RESTARTS   AGE
percona-server-mysql-operator-6b78d5f68c-bzg6r   1/1     Running   0          30m
ps-cluster1-haproxy-0                            2/2     Running   0          28m
ps-cluster1-haproxy-1                            2/2     Running   0          27m
ps-cluster1-haproxy-2                            2/2     Running   0          27m
ps-cluster1-mysql-0                              2/2     Running   0          29m
ps-cluster1-mysql-1                              2/2     Running   0          28m
ps-cluster1-mysql-2                              2/2     Running   0          26m

Step 2: Retrieve the DC’s InnoDB cluster name, which will be required later to construct the ClusterSet.

shell> kubectl get ps ps-cluster1 -n ps -o jsonpath='{.status.innodbClusterName}{"\n"}'
pscluster1

Step 3: Get a service endpoint which is used when setting up the ClusterSet environment. We will use ps-cluster1-mysql-primary, which is mapped to the current Primary node in the existing cluster.

shell> kubectl get services -n ps

NAME                        TYPE        CLUSTER-IP       EXTERNAL-IP   PORT(S)                                           AGE
ps-cluster1-haproxy         ClusterIP   34.118.225.215   <none>        3306/TCP,3307/TCP,3309/TCP,33060/TCP,33062/TCP    29m
ps-cluster1-mysql           ClusterIP   None             <none>        3306/TCP,33062/TCP,33060/TCP,6450/TCP,33061/TCP   29m
ps-cluster1-mysql-primary   ClusterIP   34.118.229.137   <none>        3306/TCP,33062/TCP,33060/TCP,6450/TCP,33061/TCP   29m
ps-cluster1-mysql-proxy     ClusterIP   None             <none>        3306/TCP,33062/TCP,33060/TCP,6450/TCP,33061/TCP   29m
ps-cluster1-mysql-unready   ClusterIP   None             <none>        3306/TCP,33062/TCP,33060/TCP,6450/TCP,33061/TCP   29m

Step 4: The DR site should have the same credentials as DC. We need to export the DC secret containing the credentials and import it into the DR cluster.

shell> kubectl get secret ps-cluster1-secrets -n ps -o yaml > source-secret.yaml

We also need to perform a couple of cleanups in the exported secret file.

  • Remove the annotations, creationTimestamp, resourceVersion, selfLink, and uid metadata fields.
  • As per the requirement, change the namespace/instance and other unwanted details as per your replica site.

E.g,

shell> yq eval 'del(.metadata.ownerReferences, .metadata.annotations, .metadata.creationTimestamp, .metadata.resourceVersion, .metadata.selfLink, .metadata.uid)' source-secret.yaml > replica-secret.yaml

shell> yq eval '.metadata.namespace = "ps-dr"' -i replica-secret.yaml

shell> sed -i '' 's/ps-cluster1/ps-cluster2/g' replica-secret.yaml

The final ready secret file looks like this. 

apiVersion: v1
data:
  clusterset: XVpMQz0+LEVDe3kyQGR6TQ==
  heartbeat: YmFONW1KTE8oLTxdVVB7Kg==
  monitor: UC1oOHokRksoMnpSMWsmJg==
  operator: SDMrblpSQm0yRHdhV3dteX0=
  orchestrator: cEVqMEUlaGp5fShudyZURHtl
  replication: ZjldZlkwa3ZwNWU8KVpsag==
  root: e3BycEl+LlcrPFVUUTwpaG4=
  xtrabackup: eFhNNENIRF4wJXZ7bjxbKi11ag==
kind: Secret
metadata:
  labels:
    app.kubernetes.io/component: database
    app.kubernetes.io/instance: ps-cluster2
    app.kubernetes.io/managed-by: percona-server-mysql-operator
    app.kubernetes.io/name: mysql
    app.kubernetes.io/part-of: percona-server
  name: ps-cluster2-secrets
  namespace: ps-dr
type: Opaque

DR (pscluster2) Cluster configuration

Step 1: First, we need to import the modified secret file replica-secret.yaml and initialise the DR cluster.

shell> kubectl apply -f deploy/replica-secret.yaml -n ps-dr
secret/ps-cluster2-secrets created

shell> kubectl get secrets -n ps-dr
NAME                      TYPE     DATA   AGE
...
ps-cluster2-secrets   Opaque   8      12s
...

Also, we need to make some modifications to the custom resource file cr.yaml to initialise the DR cluster.

metadata:
  finalizers:
    - percona.com/delete-mysql-pods-in-order
#    - percona.com/delete-ssl
#    - percona.com/delete-mysql-pvc
  name: ps-cluster2

spec:
  crVersion: 1.2.0
  secretsName: ps-cluster2-secrets

mysql:
    clusterType: group-replication
    size: 3
    image: percona/percona-server:8.4.10-10.1
    bootstrap:
      mode: manual

shell> kubectl apply -f deploy/cr.yaml -n ps

Note: We set spec.mysql.bootstrap.mode to manual so Pod mysql-0 does not form a Group Replication group until the ClusterSet adopts it and references the secret file we copied from the DC.

It is also expected that after applying the Custom Resource file cr.yaml, the Pod mysql-0 starts but stays NotReady. The cluster ps-cluster2 reports the Initialising state and the AwaitingExternalBootstrap condition in status. Pods mysql-1 and mysql-2 do not start until Pod mysql-0  joins the Group Replication.

Once we deploy the custom resource, we can notice the status below. Please note that the complete Pods will be ready only once DR successfully syncs and joins the DC cluster. 

shell> kubectl get ps -n ps-dr
NAME          REPLICATION         ENDPOINT                    STATE          MYSQL   ORCHESTRATOR   HAPROXY   ROUTER   AGE
ps-cluster2   group-replication   ps-cluster2-haproxy.ps-dr   initializing                                             17m

shell> kubectl get pods -n ps-dr
NAME                                             READY   STATUS    RESTARTS   AGE
percona-server-mysql-operator-6b78d5f68c-4gsm9   1/1     Running   0          28m
ps-cluster2-mysql-0

Step 2: We need to note down the DR InnoDB cluster name, which will later be used by the ClusterSet.

shell> kubectl get ps ps-cluster2 -n ps -o jsonpath='{.status.innodbClusterName}{"\n"}'
pscluster2

Step 3: We need to identify the DR cluster endpoint that is reachable from the DC. This endpoint will be used to feed the clone and perform other management operations.

We will use the local FQDN ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr.svc.cluster.local of the ps-cluster2-mysql-0 Pod, which is currently initialised and awaiting the ready state.

shell> kubectl get pods -n ps-dr
NAME                                             READY   STATUS    RESTARTS   AGE
percona-server-mysql-operator-6b78d5f68c-4gsm9   1/1     Running   0          48m
ps-cluster2-mysql-0                              1/2     Running   0          37m

By connecting to the DC Primary Pod, we can verify cross-communication between the DC and the DR.

shell> kubectl exec -it ps-cluster1-mysql-0 -n ps -- sh

sh-5.1$ curl -v ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr.svc.cluster.local:3306
*   Trying 10.60.1.7:3306...
* Connected to ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr.svc.cluster.local (10.60.1.7) port 3306 (#0)
> GET / HTTP/1.1
> Host: ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr.svc.cluster.local:3306
> User-Agent: curl/7.76.1
> Accept: */*

Data Restoration Part

By default, when the DR site initialises and attempts to join the ClusterSet, it receives data from the source/DC via the clone recovery method.

The Operator uses MySQL Shell to create a physical snapshot of the dataset from the Source/DC and transfer it to the DR Replica.

Alternatively, we can manually perform a backup and restore on the target cluster. This strategy helps when integrating the DR site into the ClusterSet, as pre-populating the data and GTID history allows it to apply only delta changes rather than performing a full initial synchronisation. For large datasets or to prevent excessive load and performance degradation on the donor node, a backup-and-restore approach can be considered.

Here, we will use the clone recovery method to sync the DR cluster.

Next, we will deploy the ClusterSet configurations so that DR joins the DC cluster via a data clone and connects via Asynchronous Replication to stay in sync.

Below is the clusterset.yaml file where we pass the various information like (Secrets, DC/DR Endpoints, Cluster Name etc) , which we fetched in some of the above steps earlier.

kind: PerconaServerMySQLClusterSet
metadata:
  name: my-cluster-set
  finalizers:
    - percona.com/clusterset-dissolve
spec:
#  unsafeFlags:
#    forcedFailover: false
#    forcedClusterRemoval: false
  primaryCluster: pscluster1
  credentialsSecret:
    name: ps-cluster1-secrets
    key: clusterset
  sslMode: AUTO
  createReplicaClusterOptions:
    recoveryMethod: clone
  clusters:
    - innodbClusterName: pscluster1
      endpoints:
      - host: ps-cluster1-mysql-primary.ps.svc.cluster.local
        port: 3306
    - innodbClusterName: pscluster2
      endpoints:
      - host: ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr.svc.cluster.local
        port: 3306
  mysqlshellRunner:
    image: percona/percona-server:8.4.10-10.1

We will apply the changes only to the DC node.

kubectl apply -f deploy/clusterset.yaml

Please note: Member “ps-cluster2-mysql-0” on the DR side will connect to the DC via asynchronous replication. While the local members of the DR will join via the Group Replication mechanism. 

This action will also start a separate backend job on DC, which creates an associated Pod to perform the ClusterSet activity.

shell> kubectl get jobs -n ps
NAME                                    STATUS    COMPLETIONS   DURATION   AGE
my-cluster-set-pscluster2-add-replica   Complete             1/1           23s        53s

….

shell> kubectl get pods -n ps
NAME                                             READY   STATUS    RESTARTS   AGE
my-cluster-set-pscluster2-add-replica-wk7xd      1/1     Running             0          3s

As soon as the process completes successfully, the job and associated Pod will be removed from the list.

There is one extra pod that can be noticed, and it persists. This provides a utility/client for running MySQL Shell commands against the MySQL ClusterSet.

shell> kubectl get pods -n ps
NAME                                             READY   STATUS    RESTARTS   AGE
my-cluster-set-runner-5d68fbcc74-svmpw           1/1     Running   0          10h

If the job fails or errors occur, we need to investigate the exact problem using the information below.

kubectl describe job <jobname>
kubectl describe pod <add-replica pod>
kubectl logs <add-replica pod>

Finally, we can check the Pod status on the DR cluster. It will now reflect all MySQL and haproxy pods in the fully completed/ready state.  

shell> kubectl get pods -n ps-dr
NAME                                             READY   STATUS    RESTARTS      AGE
percona-server-mysql-operator-6b78d5f68c-4gsm9   1/1     Running   0             11h
ps-cluster2-haproxy-0                            2/2     Running   0             36m
ps-cluster2-haproxy-1                            2/2     Running   0             36m
ps-cluster2-haproxy-2                            2/2     Running   0             36m
ps-cluster2-mysql-0                              2/2     Running   1 (37m ago)   11h
ps-cluster2-mysql-1                              2/2     Running   1 (36m ago)   36m
ps-cluster2-mysql-2                              2/2     Running   1 (34m ago)   35m

Verification of ClusterSet completion

We can check the ClusterSet information below if it has been processed successfully without any errors.

shell> kubectl get ps-clusterset my-cluster-set -n ps
NAME             PRIMARY      ENDPOINT                                        READY
my-cluster-set   pscluster1   ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306   True

shell> kubectl get ps-clusterset my-cluster-set -n ps -o yaml
apiVersion: ps.percona.com/v1
kind: PerconaServerMySQLClusterSet
metadata:
  annotations:
    kubectl.kubernetes.io/last-applied-configuration: |
      {"apiVersion":"ps.percona.com/v1","kind":"PerconaServerMySQLClusterSet","metadata":{"annotations":{},"finalizers":["percona.com/clusterset-dissolve"],"name":"my-cluster-set","namespace":"ps"},"spec":{"clusters":[{"endpoints":[{"host":"ps-cluster1-mysql-primary.ps.svc.cluster.local","port":3306}],"innodbClusterName":"pscluster1"},{"endpoints":[{"host":"ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr.svc.cluster.local","port":3306}],"innodbClusterName":"pscluster2"}],"createReplicaClusterOptions":{"recoveryMethod":"clone"},"credentialsSecret":{"key":"clusterset","name":"ps-cluster1-secrets"},"mysqlshellRunner":{"image":"percona/percona-server:8.4.10-10.1"},"primaryCluster":"pscluster1","sslMode":"AUTO"}}
  creationTimestamp: "2026-09-11T05:20:08Z"
  finalizers:
  - percona.com/clusterset-dissolve
  generation: 5
  name: my-cluster-set
  namespace: ps
  resourceVersion: "1789143099049519007"
  uid: 6cfdce40-e1e0-47c8-bdae-1cd847938f29
spec:
  clusters:
  - endpoints:
    - host: ps-cluster1-mysql-primary.ps.svc.cluster.local
      port: 3306
    innodbClusterName: pscluster1
  - endpoints:
    - host: ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr.svc.cluster.local
      port: 3306
    innodbClusterName: pscluster2
  createReplicaClusterOptions:
    recoveryMethod: clone
  credentialsSecret:
    key: clusterset
    name: ps-cluster1-secrets
  mysqlshellRunner:
    image: percona/percona-server:8.4.10-10.1
  primaryCluster: pscluster1
  sslMode: AUTO
status:
  clusters:
    pscluster1:
      clusterRole: PRIMARY
      globalStatus: OK
      primary: ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306
    pscluster2:
      clusterRole: REPLICA
      globalStatus: OK
      primary: ""
  conditions:
  - lastTransitionTime: "2026-09-11T05:25:07Z"
    message: ""
    reason: DeploymentReady
    status: "True"
    type: MySQLShellRunnerReady
  - lastTransitionTime: "2026-09-11T05:25:10Z"
    message: ""
    reason: ClusterSetBootstrapped
    status: "True"
    type: ClusterSetBootstrapped
  - lastTransitionTime: "2026-09-11T05:25:13Z"
    message: All Clusters available.
    reason: ClusterSetHealthy
    status: "True"
    type: Ready
  lastObservedAt: "2026-09-11T16:11:39Z"
  lastObservedGeneration: 5
  primaryCluster: pscluster1
  primaryClusterEndpoint: ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306

Also, we can manually access any running MySQL Pod and confirm the ClusterSet status.

shell> kubectl exec -it ps-cluster1-mysql-0 -n ps -- sh

sh-5.1$ mysqlsh --uri=root@localhost:3306

MySQL  localhost:3306 ssl  JS > var clusterset =  dba.getClusterSet()
 MySQL  localhost:3306 ssl  JS > clusterset.status({extended:1})
{
    "clusters": {
        "pscluster1": {
            "clusterRole": "PRIMARY", 
            "globalStatus": "OK", 
            "primary": "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306", 
            "status": "OK", 
            "statusText": "Cluster is ONLINE and can tolerate up to ONE failure.", 
            "topology": {
                "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306": {
                    "address": "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306", 
                    "memberRole": "PRIMARY", 
                    "mode": "R/W", 
                    "readReplicas": {}, 
                    "role": "HA", 
                    "status": "ONLINE", 
                    "version": "8.4.10"
                }, 
                "ps-cluster1-mysql-1.ps-cluster1-mysql.ps:3306": {
                    "address": "ps-cluster1-mysql-1.ps-cluster1-mysql.ps:3306", 
                    "memberRole": "SECONDARY", 
                    "mode": "R/O", 
                    "readReplicas": {}, 
                    "replicationLagFromImmediateSource": "", 
                    "replicationLagFromOriginalSource": "", 
                    "role": "HA", 
                    "status": "ONLINE", 
                    "version": "8.4.10"
                }, 
                "ps-cluster1-mysql-2.ps-cluster1-mysql.ps:3306": {
                    "address": "ps-cluster1-mysql-2.ps-cluster1-mysql.ps:3306", 
                    "memberRole": "SECONDARY", 
                    "mode": "R/O", 
                    "readReplicas": {}, 
                    "replicationLagFromImmediateSource": "", 
                    "replicationLagFromOriginalSource": "", 
                    "role": "HA", 
                    "status": "ONLINE", 
                    "version": "8.4.10"
                }
            }, 
            "transactionSet": "50cc4081-ad9a-11f1-b815-1602eb3926cb:1-4,65edbac6-ad9a-11f1-9dbe-1602eb3926cb:1-139"
        }, 
        "pscluster2": {
            "clusterRole": "REPLICA", 
            "clusterSetReplication": {
                "applierStatus": "APPLIED_ALL", 
                "applierThreadState": "Waiting for an event from Coordinator", 
                "applierWorkerThreads": 4, 
                "receiver": "ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr:3306", 
                "receiverStatus": "ON", 
                "receiverThreadState": "Waiting for source to send event", 
                "replicationSsl": "TLS_AES_128_GCM_SHA256 TLSv1.3", 
                "replicationSslMode": "REQUIRED", 
                "source": "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306"
            }, 
            "clusterSetReplicationStatus": "OK", 
            "globalStatus": "OK", 
            "status": "OK", 
            "statusText": "Cluster is ONLINE and can tolerate up to ONE failure.", 
            "topology": {
                "ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr:3306": {
                    "address": "ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr:3306", 
                    "memberRole": "PRIMARY", 
                    "mode": "R/O", 
                    "readReplicas": {}, 
                    "replicationLagFromImmediateSource": "", 
                    "replicationLagFromOriginalSource": "", 
                    "role": "HA", 
                    "status": "ONLINE", 
                    "version": "8.4.10"
                }, 
                "ps-cluster2-mysql-1.ps-cluster2-mysql.ps-dr:3306": {
                    "address": "ps-cluster2-mysql-1.ps-cluster2-mysql.ps-dr:3306", 
                    "memberRole": "SECONDARY", 
                    "mode": "R/O", 
                    "readReplicas": {}, 
                    "replicationLagFromImmediateSource": "", 
                    "replicationLagFromOriginalSource": "", 
                    "role": "HA", 
                    "status": "ONLINE", 
                    "version": "8.4.10"
                }, 
                "ps-cluster2-mysql-2.ps-cluster2-mysql.ps-dr:3306": {
                    "address": "ps-cluster2-mysql-2.ps-cluster2-mysql.ps-dr:3306", 
                    "memberRole": "SECONDARY", 
                    "mode": "R/O", 
                    "readReplicas": {}, 
                    "replicationLagFromImmediateSource": "", 
                    "replicationLagFromOriginalSource": "", 
                    "role": "HA", 
                    "status": "ONLINE", 
                    "version": "8.4.10"
                }
            }, 
            "transactionSet": "50cc4081-ad9a-11f1-b815-1602eb3926cb:1-4,65edbac6-ad9a-11f1-9dbe-1602eb3926cb:1-139", 
            "transactionSetConsistencyStatus": "OK", 
            "transactionSetErrantGtidSet": "", 
            "transactionSetMissingGtidSet": ""
        }
    }, 
    "domainName": "my-cluster-set", 
    "globalPrimaryInstance": "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306", 
    "metadataServer": "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306", 
    "primaryCluster": "pscluster1", 
    "status": "HEALTHY", 
    "statusText": "All Clusters available."
}

Validate Replication 

  • Log in to the Primary member and perform some writes.
shell> export PRIMARY=$(kubectl get pods -n ps -l mysql.percona.com/primary=true -o jsonpath='{.items[0].metadata.name}')
shell> echo $PRIMARY;
ps-cluster1-mysql-0

shell> kubectl exec -it ps-cluster1-mysql-0 -n ps -- sh
shell> mysql -uroot -p

mysql> CREATE DATABASE IF NOT EXISTS test;
mysql> CREATE TABLE IF NOT EXISTS test.t1 (id INT PRIMARY KEY); INSERT INTO test.t1 VALUES (1);

  • Connect to the DR and verify the sync.
shell> kubectl exec -it ps-cluster2-mysql-0 -n ps-dr -- sh
shell> mysql -uroot -p

mysql> SELECT * FROM test.t1;
+----+
| id |
+----+
|  1 |
+----+

We can also visit any MySQL Pod and run the following command to get the Primary member and group replication details.

mysql> select * from performance_schema.replication_group_members;
+---------------------------+--------------------------------------+------------------------------------------+-------------+--------------+-------------+----------------+----------------------------+
| CHANNEL_NAME              | MEMBER_ID                            | MEMBER_HOST                              | MEMBER_PORT | MEMBER_STATE | MEMBER_ROLE | MEMBER_VERSION | MEMBER_COMMUNICATION_STACK |
+---------------------------+--------------------------------------+------------------------------------------+-------------+--------------+-------------+----------------+----------------------------+
| group_replication_applier | 50cc4081-ad9a-11f1-b815-1602eb3926cb | ps-cluster1-mysql-0.ps-cluster1-mysql.ps |        3306 | ONLINE       | PRIMARY     | 8.4.10         | MySQL                      |
| group_replication_applier | 87137873-ad9a-11f1-ae3f-36b4b899b0ff | ps-cluster1-mysql-1.ps-cluster1-mysql.ps |        3306 | ONLINE       | SECONDARY   | 8.4.10         | MySQL                      |
| group_replication_applier | b952f0d3-ad9a-11f1-95a5-d6e7036e522a | ps-cluster1-mysql-2.ps-cluster1-mysql.ps |        3306 | ONLINE       | SECONDARY   | 8.4.10         | MySQL                      |
+---------------------------+--------------------------------------+------------------------------------------+-------------+--------------+-------------+----------------+----------------------------+
3 rows in set (0.00 sec)

DC-DR switchover/failover

Performing a planned switchover or an ad hoc failover process is quite simple here. All we need to execute the operations below.

Switchover:

shell> kubectl patch ps-clusterset my-cluster-set -n $SOURCE_NS \
  --type=merge -p '{"spec":{"primaryCluster":"replicacluster"}}'

Forced Failover:

shell> kubectl patch ps-clusterset my-cluster-set -n $SOURCE_NS --type=merge -p '{
  "spec": {
    "primaryCluster": "replicacluster",
    "unsafeFlags": {
      "forcedFailover": true
    }
  }
}'

So let’s try a Primary switchover activity from DC pscluster1 to DR pscluster2. Currently, pscluster2 has a REPLICA role.

MySQL  localhost:3306 ssl  JS > clusterset.status()
{
    "clusters": {
        "pscluster1": {
            "clusterRole": "PRIMARY", 
            "globalStatus": "OK", 
            "primary": "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306"
        }, 
        "pscluster2": {
            "clusterRole": "REPLICA", 
            "clusterSetReplicationStatus": "OK", 
            "globalStatus": "OK"
        }
    }, 
    "domainName": "my-cluster-set", 
    "globalPrimaryInstance": "ps-cluster1-mysql-0.ps-cluster1-mysql.ps:3306", 
    "primaryCluster": "pscluster1", 
    "status": "HEALTHY", 
    "statusText": "All Clusters available."
}

Run Switchover command:

shell> kubectl patch ps-clusterset my-cluster-set -n ps \
  --type=merge -p '{"spec":{"primaryCluster":"pscluster2"}}'

perconaservermysqlclusterset.ps.percona.com/my-cluster-set patched

Watch the progress:

shell> kubectl get ps-clusterset my-cluster-set -n ps -w
shell> kubectl get jobs -n ps | grep switchover

After some time, we can see pscluster2 become the Primary cluster.

shell> kubectl get ps-clusterset my-cluster-set -n ps -w
NAME             PRIMARY      ENDPOINT                                           NAME             PRIMARY      ENDPOINT   READY
my-cluster-set   pscluster1              False
my-cluster-set   pscluster2   ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr:3306   True

kubectl exec -it ps-cluster1-mysql-0 -n ps -- sh
sh-5.1$ mysqlsh --uri=root@localhost:3306

MySQL  localhost:3306 ssl  JS > clusterset.status()
{
    "clusters": {
        "pscluster1": {
            "clusterRole": "REPLICA", 
            "clusterSetReplicationStatus": "OK", 
            "globalStatus": "OK"
        }, 
        "pscluster2": {
            "clusterRole": "PRIMARY", 
            "globalStatus": "OK", 
            "primary": "ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr:3306"
        }
    }, 
    "domainName": "my-cluster-set", 
    "globalPrimaryInstance": "ps-cluster2-mysql-0.ps-cluster2-mysql.ps-dr:3306", 
    "primaryCluster": "pscluster2", 
    "status": "HEALTHY", 
    "statusText": "All Clusters available."
}

Once the switchover finishes successfully, all new writes now go to the new Primary cluster ps-cluster2 and the old DC “ps-cluster1” will automatically become the Async Replica. The application should connect with a load balancer (Haproxy/MySQL Router) endpoint, e.g., (ps-cluster2-haproxy), which will forward all requests to the backend node (by default) to the Primary member.

shell> kubectl get svc ps-cluster2-haproxy -n ps-dr
NAME                  TYPE        CLUSTER-IP      EXTERNAL-IP   PORT(S)                                          AGE
ps-cluster2-haproxy   ClusterIP   34.118.226.22   <none>        3306/TCP,3307/TCP,3309/TCP,33060/TCP,33062/TCP   12h

Key Takeaways

Configuring and managing a multi-region topology manually or on virtual machines can be quite challenging. By packaging these components within the Percona PS Operator/K8S, setting up cross-region environments becomes far simpler. This streamlined deployment is critical for establishing robust disaster recovery solutions, offloading production workloads, or scaling read operations. Furthermore, built-in support for seamless DC-DR switchovers and ad hoc failovers adds significant value to the architecture.

Before deploying these topologies into production environments, it is strongly advised to thoroughly test and validate their behaviour in lower or non-production environments. Proceed with production deployment only after achieving full confidence in the setup. 

The post Group Replication Beyond a Single Cluster: DC-DR with Percona (PS MySQL) Operator appeared first on Percona.
Sep
14
2026
--

Percona and HexaCluster: Faster, Safer Oracle Migration

Percona and HexaCluster have partnered to remove the hardest part of an open source database migration: getting off Oracle, SQL Server, DB2 or Sybase ASE with confidence, on a predictable timeline, without a multi-year consulting program. Percona brings open source expertise, its own distributions, operators and enterprise support. HexaCluster brings the assessment and migration engineering that gets workloads onto those supported databases.

In this Q&A, Avi Vallarapu, CEO of HexaCluster, explains what the partnership changes for organizations planning an Oracle migration, why a database migration assessment is the single most valuable step, and how a joint engagement runs from first assessment through long-term support.


Quick answer: what is the Percona and HexaCluster partnership?

Percona and HexaCluster is a joint database migration partnership that moves organizations off Oracle, SQL Server, DB2 and Sybase ASE onto Percona-supported open source databases, primarily PostgreSQL. HexaCluster runs the assessment and migration engineering, using its own DMAT and HexaRocket tooling. Percona runs the resulting database long term through its distributions, operators and support.

  • Problem it solves: disconnected migration tools and skipped assessments, which is where most Oracle migrations fail
  • What HexaCluster does: database migration assessment, automatic schema conversion, data migration, and live replication, with validation & rollback
  • What Percona does: the open source database destination, plus operators, distributions and expert support
  • Typical use case: Oracle, SQL Server, DB2 or Sybase ASE exits, data center exits, and hybrid cloud migrations

Short version: HexaCluster gets you to open source. Percona keeps you running on it. Together, that’s one path from a proprietary database to a fully supported open source one.


Q: What does HexaCluster do differently?

Avi: HexaCluster comes from the same place Percona does. We’re open source contributors first. Our team has contributed to more than 50 popular PostgreSQL extensions, and over 90 percent of what we build is open source.

The best known example is Ora2Pg, the most widely used open source Oracle-to-PostgreSQL migration tool, created and maintained by our team. Google Cloud, Microsoft Azure and AWS have all pointed customers to it for complex schema conversions. We’ve also built extensions that emulate Oracle and SQL Server behavior inside PostgreSQL, making application code portable instead of rewritten.

That work taught us where migrations actually break, which is where HexaRocket came from. Almost every existing migration tool is partial: some handle schema conversion, some handle data migration and change data capture, very few do both, and almost none give a credible rollback. Customers end up stitching disconnected tools together, and the seams between them are exactly where migrations fail.

HexaRocket runs the whole path in one platform: schema migration with validation, data migration with validation, change data capture for live replication, and reverse replication so you can roll back if something goes wrong. Rollback is what lets a CIO approve a cutover date.


Q: Why does the partnership with Percona matter?

Avi: Because neither company covers the whole journey alone. Percona is the master of open source on the services and product side: Percona Distribution for PostgreSQL, Percona MySQL, Percona Software for MongoDB, the Percona Operators, and enterprise support. That’s hard to replicate.

What Percona hasn’t done is move workloads off Oracle, SQL Server, DB2 or Sybase in the first place. That’s the gap HexaCluster bridges.

Put simply: HexaCluster gets you to open source, Percona keeps you running on it. That’s the whole journey covered by two open source companies, not a general-purpose systems integrator learning your database on your budget. It works in reverse for us too: when customers ask what they’re landing on, pointing at Percona’s distribution, with built-in transparent data encryption, makes that conversation simpler.


Q: How did this relationship start?

Avi: It’s not new. I joined Percona in 2018 to start and lead the PostgreSQL practice there. The relationship continued through everything I’ve built since, first through MigOps and now through HexaCluster. This partnership formalizes a working relationship that’s existed for years.


Q: What’s actually driving companies to do this right now?

Avi: Three things, stacking on top of each other.

Cost optimization. Commercial database licensing is one of the largest and least defensible line items in most infrastructure budgets. When finance looks for structural savings, this is where they land.

Scale in the AI era. Organizations are scaling data volumes faster than planned. Per-core commercial licensing turns growth into a penalty; open source turns it into a hardware conversation instead of a procurement one.

Features and performance. PostgreSQL isn’t the pragmatic compromise anymore. It’s the target: extensions, JSON, logical replication, partitioning, and now transparent data encryption through Percona’s work on the Distribution. The question has shifted from whether to adopt PostgreSQL to how fast the rest of the estate can follow.


Q: Where do companies most often go wrong in migrations?

Avi: They skip the assessment.

Migrations fail long before cutover, at the point someone estimates the effort without knowing what’s actually inside the databases. Some carry genuine complexity: heavy PL/SQL, embedded business logic, dependencies nobody has read in a decade. Others are almost trivial. Without an assessment, you can’t tell those apart, so both estimates are wrong.

Two mistakes compound that one: choosing a partner who treats your migration as a learning exercise, and choosing disconnected tools that leave the integration risk with you. Assessment first. Everything else gets easier after that.


Q: What does a Percona and HexaCluster engagement look like for a customer?

Avi: It’s one team across the full lifecycle. The engagement starts the moment someone first thinks about migrating: assessment, then roadmap and sequencing, then schema and data migration with validation at every stage, then cutover with rollback available, then production, then support for as long as the database lives.

The customer isn’t managing a handoff between an assessment vendor, a tooling vendor, a migration integrator and a support provider. That’s where cost, delay and blame usually live. The result is cost-effective and easier, because the people who build the tools are the same people who support the databases afterward.


Q: Can you make that concrete? What has this looked like in practice?

Avi: Two examples.

A leading Middle East bank had a very large Oracle footprint. We assessed 120 Oracle databases in 30 minutes, then handed them a complete migration roadmap within two days. Individual databases ranged from 30 minutes to four days of work to them out of Oracle each, roughly 40 person-days across the whole estate. We also ran a proof of concept in two days and showed a working migration, not just a demo.

A global enterprise moved 800 TB of databases from Oracle Standard Edition to Amazon Aurora PostgreSQL, covering more than 6,000 customers, as part of an acquisition strategy, completed over two years with validation and direct customer coordination throughout.

Both examples share the same pattern: unknowns get resolved at the start, not discovered in the middle.


Q: So what does the customer actually get out of this partnership?

Avi: The most valuable thing is that the customer doesn’t have to invent migration from scratch. It’s a solved problem they can buy: no unknowns, because the assessment tells you what’s in the estate before you commit to a plan; validation at every stage, so schema and data are verified, not assumed; rollback through reverse replication, which is what makes teams willing to schedule a cutover; and committed timelines, which is often the real blocker for leadership.


Q: If I’m a CIO reading this, what should I be asking myself?

Avi: Three questions, in this order.

Did I pick the right database to migrate first? Starting with the hardest one is the most common self-inflicted wound. It burns budget and demoralizes leadership before any value is delivered.

Have we actually assessed our databases, so we know which ones are low-hanging fruit and which need real engineering? Without that, you’re guessing.

Did we pick the right tooling: a platform genuinely built for end-to-end migration, not a set of disconnected tools stitched together? Get those three right, and the migration is largely an execution problem.


Q: What are the biggest migration goals you’re seeing?

Avi: Four exits dominate the conversations we’re in: Oracle, SQL Server, DB2 and Sybase ASE. Sybase ASE deserves a special mention, since customers there are being pushed toward SAP or SQL Server, trading one proprietary database for another. Through this partnership, PostgreSQL becomes a realistic, cheaper target instead.

Many of these tie into data center exits and hybrid cloud programs, where a single platform pays off most. We cover homogeneous migrations (PostgreSQL to PostgreSQL, MySQL to MySQL, any platform to any platform), heterogeneous migrations (Oracle, SQL Server, DB2 and Sybase ASE to PostgreSQL), and same-engine platform moves, like Azure Managed SQL to SQL Server on VMs. A data center exit is rarely one type of migration. It’s usually all three at once, under a deadline set by a lease or a contract.


Q: What are the next steps for someone reading this?

Avi: Start with the assessment. It’s fast, it’s concrete, and it’s the step that de-risks everything after it.

We invite organizations to run a DMAT database migration assessment across their estate and get back a detailed roadmap: which databases to move first, what effort each one takes, and what the cost savings look like. From there, Percona and HexaCluster can take it through to production and support it long term.

You don’t need to commit to a migration to find out what one would cost you. That’s the point of assessing first.

To start an assessment or discuss an Oracle, SQL Server, DB2 or Sybase ASE exit, contact your Percona representative or reach out to HexaCluster directly.

The post Percona and HexaCluster: Faster, Safer Oracle Migration appeared first on Percona.

Aug
27
2026
--

Benchmarking vector indexes

Nearly every database has vector search now, and every one of them has a blog post with a big number in it. Almost none of those numbers can be checked, because the thing that makes them meaningful is usually missing.

We built a vector-bench to stop guessing. You name the engines you want, build them from pinned versions, put each one in the same container on the same cores with the same data, run the same measurements against all of them, and write a report. This post is about how it measures.

If you work with databases but haven’t touched vectors yet, the first half is the part you need.

What’s being indexed

An embedding is a fixed-length array of floats that comes out of a model. The useful property is that semantically similar inputs land close together when you measure the distance between them.

Two distance measures cover almost everything. L2 is an ordinary straight-line distance, the Pythagorean one, extended to however many dimensions you have. Cosine Similarity  measures the angle between two vectors and ignores their length. Which one applies is decided by the model that produced the embeddings. It isn’t a choice you get to make at query time, and getting it wrong is a good way to produce nonsense.

So the query you want is “the 10 rows whose vectors are nearest this one”:

SELECT id FROM documents ORDER BY distance(embedding, ?) LIMIT 10;

That 10 is k.

Now the problem. Answering that exactly means computing the distance from your query vector to every single row, then sorting. No B-tree or hash index helps, because neither one can order a million points by proximity in 1536 dimensions. Exact vector search is a full table scan with a lot of arithmetic bolted on.

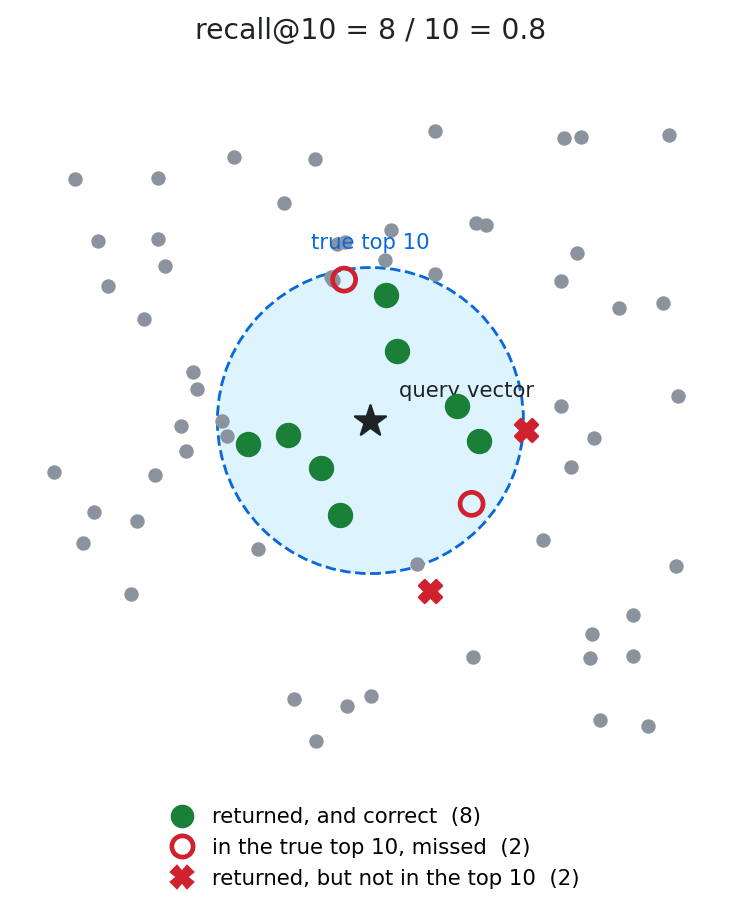
A vector index gives up exactness to avoid that. It looks at a few thousand promising candidates instead of every row and returns the best it found. That’s the approximate nearest neighbour search, or ANN. It’s usually right.

“Usually” is doing a lot of work in that sentence, and pinning it down is most of what this benchmark does.

To score that you need to know the right answer in the first place. That’s the ground truth: the true nearest neighbours for every query, computed once by brute force with no index involved. The public ANN datasets ship theirs alongside the vectors, and without it you couldn’t score an approximate index at all.

This is the number that makes everything else meaningful, and it’s the one most vector search claims leave out. That omission is the reason this project exists.

The two kinds of vector index

Almost every database that has added vector search picked one of two designs. They attack the same problem from opposite ends, and which one you have decides what you’re allowed to tune.

HNSW

HNSW stands for Hierarchical Navigable Small World, which is a mouthful for something fairly intuitive. If you’ve ever implemented a skip list, you already have the shape of it.

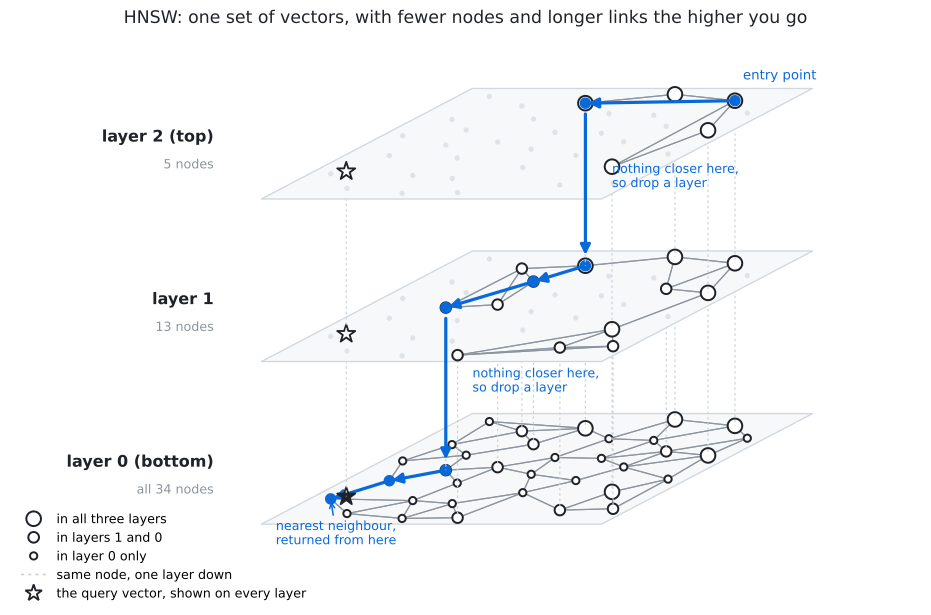
It’s a graph of vectors built in layers. Every vector is a node, linked to some number of its nearest neighbours. The top layer has few nodes and its links jump long distances across the data. Each layer below has more nodes and shorter links. A search starts at the top and keeps hopping to whichever neighbour is closer to the query. When nothing is closer, it drops a layer and carries on, until it runs out of layers.

Two settings matter:

  • M is how many links each node keeps. It’s fixed when the index is built. Higher M means a better-connected graph and better recall, at the cost of a slower build and a bigger index.
  • ef_search is how many candidates the search keeps track of while it walks. It’s a session variable, so you can change it per query. Turn it up and the search visits more nodes, gets better recall, and runs slower.

There’s ef_construction too, the same idea applied while the index is being built. Not every engine lets you set it, which turns out to matter when you try to compare them fairly.

IVF

IVF stands for Inverted File. It partitions the data instead of linking it, not unlike list partitioning on a table.

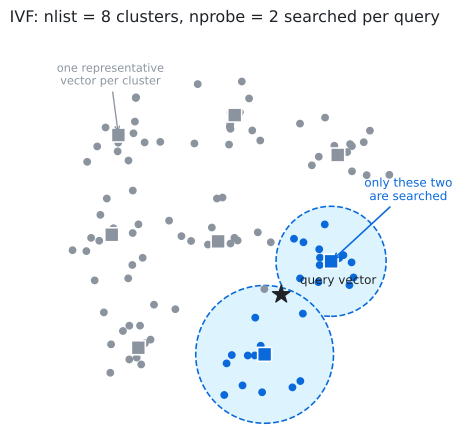
At build time it groups the vectors into nlist clusters, each with a representative vector at its centre. At query time it compares the query against those representatives, picks the closest nprobe clusters, and searches only inside them. It builds much faster than HNSW and uses less memory, but usually gives worse recall at the same speed. It misses when the true neighbour happens to sit just outside the clusters it looked in.

We only test engines running HNSW, which is what most databases shipped. Putting an IVF engine on the same chart would mostly measure the gap between two algorithms rather than how well anybody implemented one, so IVF-only engines get their own bucket.

Why one number is never enough

Recall isn’t a property of an engine. It’s a setting, and ef_search is the dial.

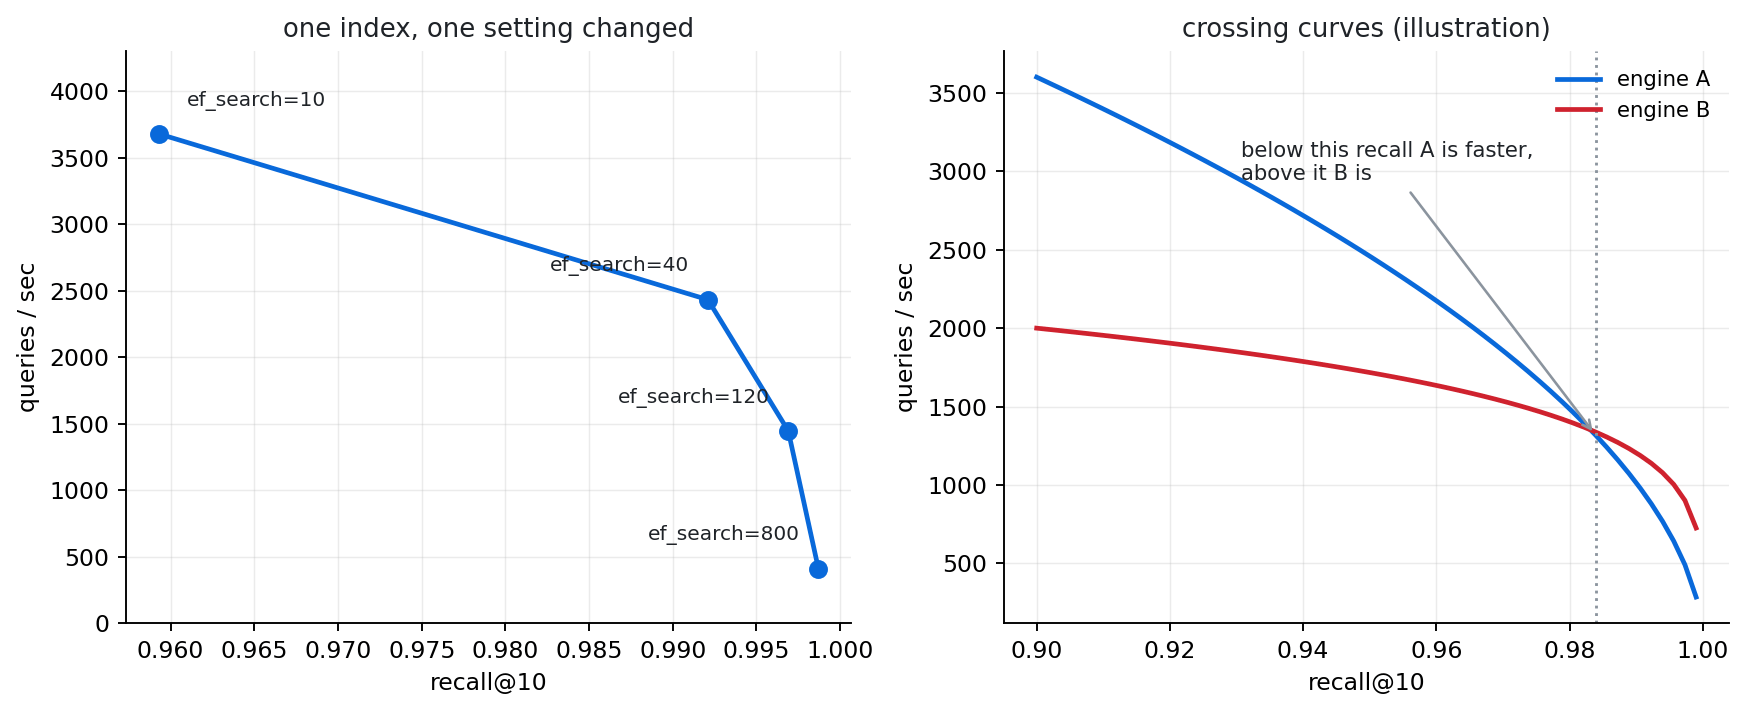
Here’s one HNSW index on one machine, same data, same queries. The only difference is that on the first row the search tracks 10 candidate nodes as it walks the graph, and on the second it tracks 800:

ef_search=10 3,678 queries/sec recall 0.9593
ef_search=800 409 queries/sec recall 0.9987

Keeping 800 candidates instead of 10 finds a better answer and takes nine times as long. Both rows are honest measurements of the same index on the same hardware.

Which is why “our database does 3,678 vector queries a second” tells you nothing. You don’t know how often it was handing back the wrong rows, and the person quoting it may not know either. The reverse is just as empty: recall with no throughput next to it is free, because recall 1.0 is always available if you turn the index off and scan the table.

Every measurement here is a pair. If you take one thing from this post, take that.

What the harness puts on each engine

One table per engine. An id, an integer tag column used only by the filtered tests, the vector, and an HNSW index on it at a configured M.

CREATE TABLE t1 (
id INTEGER PRIMARY KEY,
tag INTEGER NOT NULL,
v VECTOR(1536)
);


Then two queries, plain top-k and the same search restricted to a subset of rows:

SELECT id FROM t1 ORDER BY distance(v, ?) LIMIT 10;
SELECT id FROM t1 WHERE tag < ? ORDER BY distance(v, ?) LIMIT 10;


tag holds values 0 to 99 spread evenly, so tag < 10 passes about 10% of rows and tag < 1 about 1%. That’s how we control selectivity.

Every engine writes all of this differently. Some declare the index inside CREATE TABLE, others want a separate CREATE INDEX, and the distance functions have different names everywhere. Translating that is the driver’s job, and the drivers are the only engine-specific code in the whole harness.

Every engine also has at least one setup detail that will quietly wreck your numbers. PostgreSQL, for instance, stores oversized values out of line in what it calls TOAST, and a 1536-dimension vector counts as oversized. Unless the column is set to STORAGE PLAIN, every single distance comparison pays for an extra fetch. It’s one line of DDL. Miss it and you publish PostgreSQL looking slow for a reason that has nothing to do with its vector search, and you’d never know from the results.

What we measure

Recall against throughput. Iterate ef_search against a fixed index, record recall and QPS at each point, repeat at a few values of M. k=10 throughout. The query vectors come from the dataset’s own held-out query set, never from the rows we loaded, because searching for a vector that’s already in the index is a much easier problem and would flatter everybody equally.

The two settings behave completely differently, and it shapes how long a run takes. ef_search is a session variable, so iterating it reuses the index that’s already built and each extra point costs almost nothing. M is baked into the index, so every value of M means dropping the table and loading the entire dataset again. On a million 1536-dimension vectors that’s hours per value. Hence many ef_search points and very few M values.

Build cost. Wall time, rows per second, index size on disk, peak memory.

This is the easiest place in the whole benchmark to publish a misleading number, because engines don’t build the index the same way. Engines can build indexes either incrementally, bulk, or both. What does that mean? 

Incremental. The graph is updated on every INSERT. Loading is slow, but when the last row lands the index is finished and the table is ready to query.

Bulk. All the rows load first, then the whole graph gets built in one pass. Much faster in total, but the table can’t answer a vector query until the build finishes.

Those are two different operations. One engine in our set does both, and its bulk path loaded 18 times more rows per second than its own incremental path. Same engine, same data, same machine, 18x apart.

So a bulk number from one engine put next to an incremental number from another doesn’t compare engines at all. It compares two ways of building an index, and the ratio looks impressive enough that people quote it anyway. We measure both paths on any engine that has both, and the report says which is which.

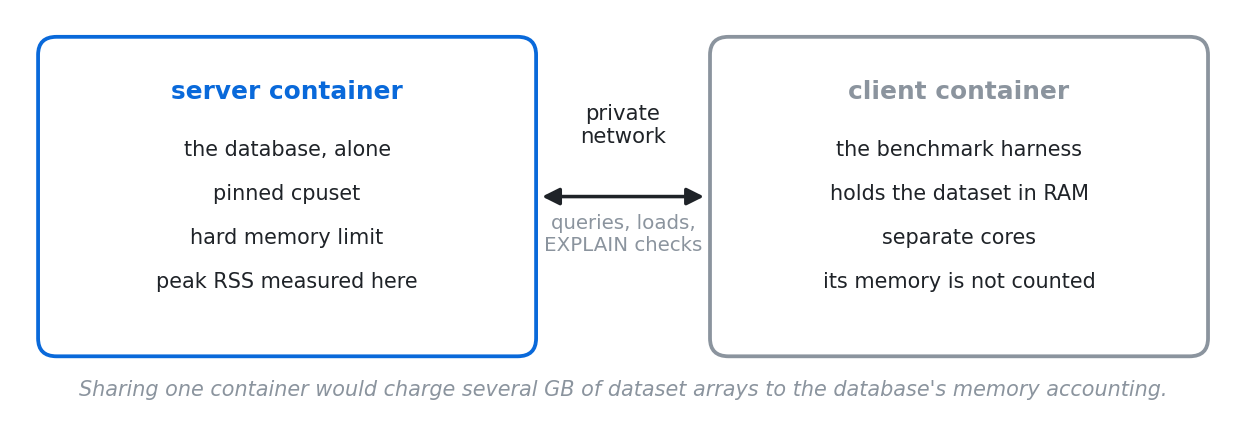
Peak memory comes from the server’s container, with the database as the only thing running in it. The harness runs in a separate container and reaches the server over a private network.

That separation matters more than it sounds. The client holds the entire dataset in memory, several GB of Python arrays. If it shared a container with the database, the container’s memory accounting would count those arrays as database memory, and every memory figure we published would be inflated by whatever the client happened to be holding.

Concurrency. QPS and latency percentiles from 1 to 32 clients. Engines cache their graphs in quite different ways and none of that shows up until clients start competing for the same cache. We report how much of the ideal speedup each engine actually got alongside raw QPS, because an engine that stops gaining throughput at 2 clients while its p99 gets 15 times worse is doing something very different from one that keeps scaling, and a throughput column on its own hides that completely.

Filtered search, at several selectivities down to 1% of rows passing. This is the case that’s supposed to justify keeping vectors in your database instead of a dedicated store, so it deserves more attention than it usually gets.

Filtering changes what “correct” means. The true top 10 among rows where tag < 10 is not the true top 10 overall, so for every selectivity we recompute ground truth by brute force over only the rows that pass. Score filtered results against the unfiltered ground truth that shipped with the dataset and every engine gets a recall near zero. We know, because we did exactly that for a while.

Some queries come back with fewer than 10 rows. In one run, 81 out of 200 did. This is not the data running out. At 10% selectivity about 99,000 rows pass the filter, so there are always at least 10 to find. The cause is the order of the operations. HNSW searches by distance first, then applies the WHERE clause. It gathers a few thousand candidates, the filter throws most of them away, and sometimes fewer than 10 are left. (If a filter really did match fewer than 10 rows, the ground truth shrinks too, and the engine still scores 1.0.) Recall already handles this. A row the engine did not return counts as a miss, so six correct rows score 0.6. We report the count because two different problems score the same. “10 rows, four of them wrong” and “six rows, all correct” are both 0.6. The first needs a wider search. The second needs iterative scanning. The count tells you which one you have. It also means the throughput is flattered, since six rows is less work than ten.

Churn. Recall and throughput before and after deleting and reinserting part of the corpus, since deletions leave graph edges pointing at rows that are gone. Whether rebuilding the index recovers what’s lost, we don’t know yet. It’s the obvious next thing to test and we haven’t done it.

Keeping the comparison fair

Everything runs twice.

The normalized pass gives every engine identical CPU, memory and cache budgets, so a difference in the results belongs to the implementation rather than to who was handed more RAM. The tuned pass lets each engine use the settings its own documentation recommends. Tuned is more realistic and less controlled, which is exactly why it doesn’t replace the first one. A result that survives both passes is about the engine. One that flips between them is interesting for a completely different reason.

Cores are pinned explicitly. One logical CPU per physical core, because SMT siblings share execution units and two threads on one core don’t behave like two cores. Never a mix of P-cores and E-cores on hybrid chips either, since migration between core types adds more variance than several of the effects we’re trying to measure. Durability is relaxed the same way everywhere, or we’d be comparing default fsync policies and calling it vector search.

Some differences can’t be equalised at all, so we write them down instead of pretending. A knob only one engine exposes goes unused in the normalized pass, because using it would hand that engine a tuning axis nobody else has. An engine that insists on a particular isolation level gets it set for everyone. And defaults that are obviously placeholders get sized from a shared budget — one family of engines still ships a 16 MiB graph cache, which is nothing, and judging an engine on a value its own vendor expects you to change measures absolutely nothing. All of these land in a “known asymmetries” section above the results.

One hardware note that catches people out. Several of these implementations ship hand-written AVX-512 code for the distance maths, where a single instruction does the arithmetic for 16 floats at once. The same index on a CPU without AVX-512 is effectively a different benchmark, and the slowdown isn’t the same for every engine, so you can’t even scale the numbers to compensate. The CPU model and its feature flags go into every run’s manifest for that reason, along with engine versions and commits, image IDs, and the resource limits as they are actually resolved rather than as we requested them. No manifest, no report.

Reading the results

Read the validity section before you look at a single chart. Our reports go environment, then validity, then known asymmetries, then results, in that order on purpose. A failed phase, an engine returning short result sets, a CPU missing the instruction set the engines wanted — all of it lands in front of you before you’ve formed an opinion.

The thing to watch for is the silent full scan.

Any of these engines will quietly stop using the vector index and scan the table instead. A scan returns exact results, slowly, so in the output it looks like high recall and low throughput. That’s indistinguishable from a conservatively tuned index unless you go and read the query plan.

It happens for thoroughly boring reasons. One engine’s optimizer costs the vector index against a table scan and takes the scan once the LIMIT is above roughly a quarter of the table, and we still haven’t found a setting that moves it. Another falls back with no error and no warning when the query asks for a different distance than the index was built for — build the index for cosine, write the query with the L2 operator, and you get a sequential scan and a sort, with nothing anywhere to tell you.

So every driver runs EXPLAIN for each configuration and checks the index name appears in the plan.

WARNING: vector index NOT used (k=10, filtered=True). Plan: …Seq Scan…

Anything that is scanned goes into validity. This is far and away the easiest way to produce impressive vector benchmark numbers by accident, and if a benchmark doesn’t mention checking for it, we’d want to know why before believing anything in it.

For recall against throughput, the useful presentation is a curve rather than a number. Iterate ef_search, plot recall against QPS, keep the best points: for each level of accuracy, the highest throughput anything reached at it. One engine beats another only where its curve sits above the other’s at the same recall. If the curves cross, then the answer genuinely depends on how accurate you need to be, and saying so is a result rather than a dodge.

Curves do invite comparing shapes instead of heights at one point, so there are bar charts as well, QPS at recall floors of 0.90, 0.95 and 0.99. Pick the accuracy you’d actually accept and read across.

Things that went wrong while we built this

Worth listing, partly because they’re the reason to trust anything else here, and partly because anyone building something similar will walk into them.

Our first ingest numbers were garbage. The load path was doing one INSERT per network round trip with autocommit on, and we measured 88 rows a second. Batching 500 rows per transaction took the same engine to 373. Publishing the first number would have been benchmarking our own client and calling it a database.

Filtered search and churn were scored against full-corpus ground truth even on runs that used a subset of rows. Every engine looked bad and the bug was entirely ours. Ground truth is now keyed on dataset, k, row count and selectivity.

Both resource passes shared one results directory, and the ANN runner skips configurations that already have results. So the tuned pass quietly skipped everything the normalized pass had computed, and our tuned numbers were mostly normalized numbers wearing a different label. That one took an embarrassingly long time to notice.

Readiness probes lie. One engine’s standard “are you accepting connections” check returns success before the database it’s supposed to create actually exists. The probe passed, the first query failed, and we spent a while convinced it was an engine problem.

The most recent one, on a 1536-dimension corpus. The ANN runner holds the whole dataset in memory twice, once in the parent process and again in a forked worker, and the copies aren’t shared. That’s roughly 12 GB for a million embeddings, on top of whatever the server is using, in a container we’d sized for the server alone. The kernel killed the worker. The runner doesn’t check worker exit codes, so it logged “Terminating 1 workers”, exited successfully and wrote no results — which looks exactly like a run that had nothing left to do. Three hours to fail, and it failed silently.

Adding a database

This is the part we cared most about getting right, because the whole point was to avoid rebuilding the apparatus every time somebody ships vector search. Each engine needs:

  • a Dockerfile producing a runtime image and a test image from a pinned version
  • a config declaring ports, credentials, and which server settings map onto the normalized CPU and memory budget
  • a module for the recall and throughput side
  • a driver: create index, load, query, filtered query, index size, and the EXPLAIN check

What’s next

Results, published with the manifests and the raw per-configuration records, so you can check them instead of taking our word for it.

Everything is at https://github.com/Percona-Lab/vector-bench harness, drivers, Dockerfiles, docs. If we’re measuring something wrong, or being unfair to an engine you know better than we do, tell us.

The post Benchmarking vector indexes appeared first on Percona.

Aug
26
2026
--

Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in

These days there’s been a lot of talk about Postgres having an impact on “everything”. Whether it’s replacing legacy systems, creating a new greenfield project or even implementing it as a back-end to an agentic AI, Postgres is today’s poster child for innovation.

So performing something as dull and straightforward as a database migration should be easy, eh?

Well, not quite.

Its popular adoption and success has, in a sense, created a problem of its own making, which is otherwise known as the Walled Garden Effect.

The Walled Garden effect in open source is where software that is nominally open but a vendor, platform, or ecosystem has exerted control over its governance, distribution and compatibility in such a manner that its interaction with the same open source technology managed in another environment becomes problematic.

It’s an unfortunate reality that some commercial ecosystems built around Postgres can become walled gardens. Postgres itself remains open and portable, but its widespread adoption has also produced commercial ecosystems in which that portability can become progressively constrained.

At its most extreme; here are the risks of a Walled Garden to the Postgres end-user:

  • In the context of a Postgres offering from a cloud computing service offering DBaaS:
    • They “Control” the core platform, set the standards, and host the marketplace.
    • They “Acquire” developers, hardware manufacturers, and service providers who build products that add value to the core platform.
    • They “Convince” users to join the ecosystem whose data, attention, and capital eventually fuels the network’s growth.
    • The financial and cultural health of satellite vendors whose very existence is “Tied” directly to the decisions and policies made by the platform owner.
  • In the context of the technology used:
    • “Modifying” the backend with unique attributes while enticing you with standard front-end protocols. A Postgres compatible interface does not necessarily imply Postgres equivalent portability. A service may emulate familiar SQL, drivers, and tools all the while introducing backend capabilities or operational dependencies that do not exist in community Postgres.
  • What it means over the life of your system:
    • As the ecosystem becomes more valuable to the user, it creates a greater “Disincentive” to exit.
    • If an exit strategy is undertaken:
      • High switching “Costs” can be incurred when migration introduces data-integrity risks and extraordinary complexity into what has become a tightly integrated workflow.
      • Extra “Expert” costs must be budgeted because specialized expertise may be required when vendor-specific features or dependencies exceed the experience of in-house staff.

        Working on past projects I’ve often found myself paraphrasing an old Eagles refrain “You can provision Postgres any time you like, but your architecture can never leave.“

        While PostgreSQL itself is fully open-source and free, some vendors have created a Hotel California effect using these three specific mechanisms:

      • Proprietary Forks & Features: They offer “Postgres-compatible” databases. They add custom, closed-source performance layers or automated scaling. If you build your application to rely on these specific features, moving back to community Postgres can require a massive architecture rewrite.
      • Migration Cost Asymmetry: Moving data into an ecosystem can be relatively inexpensive. Moving that database to an alternate environment later can be considerably more complex.
      • Ecosystem Gravity: Databases do not sit in a vacuum. Once your Postgres instance is tightly integrated with a vendor’s proprietary backup systems, security roles (IAM), and serverless analytics tools, leaving the database can mean rebuilding your entire infrastructure. Postgres data can remain portable while the architecture surrounding it becomes progressively less portable.

        So what does it mean for you?

        While today’s database landscape can make vendor dependency seem unavoidable, it isn’t. There are still organizations that build commercial services around the principles that made open source successful in the first place: transparency, interoperability, portability, and the customer’s freedom to choose where and how their software runs. Percona is one example of a commercial model built around the premise that commercial expertise and open-source values do not have to be opposing ideas.

        Reference:
        https://arxiv.org/html/2409.01118v1 

The post Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in appeared first on Percona.

May
04
2026
--

I Know Kung Fu

You might find this hard to believe, but AI has become kind of a thing around here.

Bennie published a post on our Build with AI competition last week, in which he shared that I was lucky enough to land the second place prize. Genuinely flattered, and a real thank you to Peter F, PZ, Vadim, and Bennie for organizing it. The recognition is great. But the part that does not quite come through in the recap is what those six weeks actually felt like from the inside. Forty-plus submissions, 10+ teams, marathon demo sessions that ran out of time twice over, and a constant drumbeat of ideas where every fifth one made me think “wait, we can just… ship that?”

Two submissions that really impressed me (and are worthy of high praise): Kedar Vaijanapurkar shipped a four-tool MySQL stack (Advisor, random data generator, CleanPrompt, and a Query Reviewer), any one of which on its own would have been a strong submission. And Daniil built a leaderboard for Percona ecosystem contributors plus a vector-search prototype running on Percona’s own products, which is exactly the dogfood story we want.

There were a lot more than three projects worth backing, which is part of why a second contest round is being coordinated later this year. A lot of the entries are not waiting for it either – they are already developing into real, operational utilities (some of mine included).

The two submissions of my own that I would point to first are IBEX and percona-dk.

IBEX (Integration Bridge for EXtended systems) is a local MCP multi-tool server that connects either a local model or a Percona-owned LLM to the systems where the most valuable context actually lives. Slack, Notion, Jira, ServiceNow, Salesforce, etc. A solution was needed here since we could not point the standard Claude or ChatGPT connectors at our sensitive internal data, and obviously most of the context that makes LLMs so valuable is precisely that kind of data.

percona-dk is the other one. It started as a way to keep AI honest about our own products by giving the AI tools our teams use (Claude, Cursor, anything that speaks MCP) direct access to Percona’s documentation, so the answer to a question about our products comes from real docs with linked citations instead of stale training data or even scraped web results that can get things wrong. It has evolved a fair bit since the contest. The Percona Community blog and forums are now indexed alongside the docs, Perconians are getting real day-to-day value out of it, and it is starting to look like the kind of thing that could grow into a community utility (perhaps even beyond Percona docs).

Those two were just the start. Once IBEX worked, I needed shared memory across LLMs, so I built that. Once I had three MCP servers running, the boilerplate got annoying, so I built CAIRN, a scaffolding tool that builds on Anthropic’s official MCP builder skill. The official skill walks you through writing a server step by step, but CAIRN spins up a complete, working project in minutes with a streamlined install wizard for non-technical users. It is now in the hands of other Perconians building their own MCP tools, and providing real value of its own. Then I learned about .mcpb files and Desktop Extensions (.dxt), packaged everything that way, and stood up an internal Claude plugin marketplace so any Perconian can install the lot from one place. Each layer opened a door I did not know existed until I was already through it. Some of those doors seemingly materialized from thin air as they magically aligned with new releases from Anthropic.

What started as a competition entry is now a small internal ecosystem. I am still a product person, not a software engineer. I am not going to pretend any of the code is pristine, and a lot of it was vibe-coded with Claude as a partner. But the architecture holds together, it works, and most of it is in daily use by people who are not me. That last part is the bit I am most proud of.

The next batch is pointed squarely at product operations. Making customer signals legible. Making internal telemetry something any teammate can talk to in plain English. The early returns are promising, and what gets me most excited is not the tech itself, it is watching people across Product, Engineering, and Support pull in the same direction with an AI colleague in the room. Turns out the interesting part of AI at work is not the model. It is the connective tissue.

I know Kung Fu

For a product guy who does not code for a living, this era is my “I know kung fu” moment. Not because I suddenly learned to fight. Because the move set I already had – product judgment, systems thinking, customer empathy, the ability to spec a thing precisely – just got a massive upgrade. The gap between “that would be useful” and “that exists now” is short enough to cross in an evening. I do not see it getting longer again.

Thanks for reading this far. If you want more detail or want to try anything not linked here, ping me. I am happy to share more.

The post I Know Kung Fu appeared first on Percona.

Apr
20
2026
--

Deploying Cross-Site Replication in Percona Operator for MySQL (PXC)

Having a separate DR cluster for production databases is a modern day requirement or necessity for tech and other related businesses that rely heavily on their database systems. Setting up such a [DC -> DR] topology for Percona XtraDB Cluster (PXC), which is a virtually- synchronous cluster, can be a bit challenging in a complex Kubernetes environment.

Here, Percona Operator for MySQL comes in handy, with a minimal number of steps to configure such a topology, which ensures a remote side backup or a disaster recovery solution.

So without taking much time, let’s see how the overall setup and configurations look from a practical standpoint.


PXC Cross-Site/Disaster Recovery


DC Configuration

1) Here we have a three-node PXC cluster running on the DC side.

shell> kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          23h
cluster1-haproxy-1                                 2/2     Running     0          23h
cluster1-haproxy-2                                 2/2     Running     0          23h
cluster1-pxc-0                                     3/3     Running     0          23h
cluster1-pxc-1                                     3/3     Running     0          7h37m
cluster1-pxc-2                                     3/3     Running     0          7h18m
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0          24h
xb-backup1-hlz2p                                   0/1     Completed   0          21h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0          13h

2) There are some configuration options which have to be enabled in a custom resource file[cr.yaml] to allow cross-site replication.

  • Expose all source PXC nodes so they can be communicated from outside or DR cluster.
expose:
      	enabled: true
      	Type: LoadBalancer

  • Define a dedicated replication channel and enable the source option.
replicationChannels:
    - name: pxc1_to_pxc2
      isSource: true

  • Finally, applying the custom resource changes.
shell> kubectl apply -f cr.yaml

3) Now we will notice some “EXTERNAL IP” details for each PXC node. This is the endpoint that DR node [cluster1-pxc-0] will use to connect to DC.

shell> kubectl get svc
NAME                              TYPE           CLUSTER-IP       EXTERNAL-IP     PORT(S)                                          AGE
cluster1-haproxy                  ClusterIP      34.118.227.249   <none>          3306/TCP,3309/TCP,33062/TCP,33060/TCP,8404/TCP   4h1m
cluster1-haproxy-replicas         ClusterIP      34.118.225.41    <none>          3306/TCP                                         4h1m
cluster1-pxc                      ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
cluster1-pxc-0                    LoadBalancer   34.118.234.140   34.29.145.138   3306:30425/TCP                                   4h1m
cluster1-pxc-1                    LoadBalancer   34.118.239.132   34.30.233.0     3306:31340/TCP                                   4h1m
cluster1-pxc-2                    LoadBalancer   34.118.236.64    35.225.0.19     3306:30642/TCP                                   4h1m
cluster1-pxc-unready              ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
percona-xtradb-cluster-operator   ClusterIP      34.118.235.168   <none>          443/TCP                                          4h11m

At this point, we are done with the DC setup. Next, we will take a backup from Source which we later used to build the DR.


Backup

  • Defining access key/secrets to connect to the GCP/S3 bucket.
cat backup-secret-s3.yaml

apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

  • In the custom resource file [cr.yaml] , we also need to define the bucket , secret file and endpoint/region details.
backup:

 storages:
   s3-us-west:
      type: s3
      verifyTLS: true

    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      region: us-west-2
      endpointUrl: https://storage.googleapis.com

…

shell> kubectl apply -f cr.yaml

  • Finally, we can take the backup by creating a [backup.yaml] file with below details.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterBackup
metadata:
#  finalizers:
#    - percona.com/delete-backup
  name: backup1
spec:
  pxcCluster: cluster1
  storageName:  s3-us-west

…

shell> kubectl apply -f cr.yaml

  • We can verify the successful backup as follows.
kubectl get pxc-backup
NAME      CLUSTER    STORAGE      DESTINATION                                     STATUS      COMPLETED   AGE
backup1   cluster1   s3-us-west   s3://<bucket>/cluster1-2026-04-07-15:55:46-full   Succeeded   125m        127m

As the backup is also ready, we can now move to the DR setup part.


DR Configuration

Below we have a similar PXC setup as having in DC in a separate Node/ K8s Cluster.

kubectl get pods -n pxc-dr
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          35h
cluster1-haproxy-1                                 2/2     Running     0          35h
cluster1-haproxy-2                                 2/2     Running     0          35h
cluster1-pxc-0                                     3/3     Running     0          35h
cluster1-pxc-1                                     3/3     Running     0          35h
cluster1-pxc-2                                     3/3     Running     0          35h
percona-xtradb-cluster-operator-6756dbf588-2wc5m   1/1     Running     0          38h
prepare-job-restore1-cluster1-8h4vn                0/1     Completed   0          35h
restore-job-restore1-cluster1-trfg6                0/1     Completed   0          35h
xb-cron-cluster1-fs-pvc-2026480025-372f8-wv6bt     0/1     Completed   0          28h
xb-cron-cluster1-fs-pvc-2026490025-372f8-gxd59     0/1     Completed   0          4h48m

First, we need to restore the backup on the DR server.

Data Restoration

  • Here we will create the [backup-secret-s3.yaml] file which contains the GCP/S3 credentials.
apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

…

shell> kubectl apply -f backup-secret-s3.yaml

  • Next, we will create a [restore.yaml] file while mentioning the backup source and other useful information.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterRestore
metadata:
  name: restore1
#  annotations:
#    percona.com/headless-service: "true"
spec:
  pxcCluster: cluster1
  backupSource:
#    verifyTLS: true
    destination: s3://<bucket>/cluster1-2026-04-07-15:55:46-full
    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      endpointUrl: https://storage.googleapis.com/

…

shell> kubectl apply -f restore.yaml

  • Once the restoration is finished successfully, we will see the status below.
shell> kubectl get pxc-restore
NAME       CLUSTER    STATUS      COMPLETED   AGE
restore1   cluster1   Succeeded               27m

Now we can do the remaining DR changes in the custom resource file [cr.yaml]. Basically, we need to add the replication channel and all source EXTERNAL-IPs. This cross-DC replication supports Automatic Asynchronous Replication Connection Failover feature, so in case any of the DC node is down, the Replica can connect and resume from other available DC nodes.

replicationChannels:
    - name: pxc1_to_pxc2
      isSource: false
      sourcesList:
      - host: 34.29.145.138  
        port: 3306
        weight: 100

      - host: 34.30.233.0
        port: 3306
        weight: 100

      - host: 35.225.0.19
        port: 3306
        weight: 100

…

shell> kubectl apply -f cr.yaml

For backup and restoration on the PXC operator, the manuals below can be referenced further.


Replication

Initially, when we check the replication status, we can notice the following error. This is because with [caching_sha2_password] authentication, it should be a secure SSL/TLS communication, or else we can use SOURCE_PUBLIC_KEY_PATH/GET_SOURCE_PUBLIC_KEY  which basicaly enables the RSA key pair-based password exchange by requesting the public key from the source. 

shell> kubectl exec -it cluster1-pxc-0  -- sh
shell> mysql -uroot -p

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Connecting to source
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: 
          Read_Source_Log_Pos: 4
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 4
        Relay_Source_Log_File: 
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
...

Error:

Last_IO_Error: Error connecting to source 'replication@35.225.0.19:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Access denied for user 'replication'@'35.225.0.19.' (using password: YES)

Once we passed “GET_SOURCE_PUBLIC_KEY” in the “CHANGE REPLICATION” command the  error is resolved and DR successfully able to communicate with the DC.

mysql> STOP REPLICA;
mysql> STOP REPLICA IO_THREAD FOR CHANNEL 'pxc1_to_pxc2';
mysql> CHANGE REPLICATION SOURCE TO SOURCE_USER='replication', SOURCE_PASSWORD='password', GET_SOURCE_PUBLIC_KEY=1 FOR CHANNEL 'pxc1_to_pxc2';
mysql> START REPLICA;

Note  – The Replication user will be auto-created on the DC node. So, with the help of below command we can get the decoded password for “replication” user.

shell> kubectl get secret cluster1-secrets -o jsonpath="{.data.replication}" | base64 --decode

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000006
          Read_Source_Log_Pos: 3047027
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 150132
        Relay_Source_Log_File: binlog.000006
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

The other PXC DR nodes will sync as usual with the Galera Synchronous replication process. 

Source Failover

The asynchronous connection failover is already enabled on the DR as we defined initially in the custom resource file. The “External IPs”  shows different here because they changed in this testing scenario.

mysql> select * from performance_schema.replication_asynchronous_connection_failover;
+--------------+---------------+------+-------------------+--------+--------------+
| CHANNEL_NAME | HOST          | PORT | NETWORK_NAMESPACE | WEIGHT | MANAGED_NAME |
+--------------+---------------+------+-------------------+--------+--------------+
| pxc1_to_pxc2 | 34.29.145.138 | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.45.151.96  | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.71.57.38   | 3306 |                   |    100 |              |
+--------------+---------------+------+-------------------+--------+--------------+
3 rows in set (0.00 sec)

Now, in case the existing Source DC[cluster1-pxc-2] is down, the DR will connect to one of the other available DC nodes based on the “Weight” and chronological order [pxc-2, pxc-1, pxc-0 etc].

  • Here, we temporarily take down the Source DC[cluster1-pxc-2] node.
kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS     AGE
cluster1-haproxy-0                                 2/2     Running     0            2d3h
cluster1-haproxy-1                                 2/2     Running     0            2d3h
cluster1-haproxy-2                                 2/2     Running     0            2d3h
cluster1-pxc-0                                     3/3     Running     0            2d3h
cluster1-pxc-1                                     3/3     Running     0            35h
cluster1-pxc-2                                     2/3     Running     1 (6s ago)   34h
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0            2d3h
xb-backup1-hlz2p                                   0/1     Completed   0            2d1h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0            41h
xb-cron-cluster1-fs-pvc-2026490026-372f8-mgfpv     0/1     Completed   0            17h

  • The DR replication breaks as it can’t reach the DC [cluster1-pxc-2].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Reconnecting after a failed source event read
                  Source_Host: 34.71.57.38
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000012
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000002
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000012
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
              Replicate_Do_DB: 
          Replicate_Ignore_DB: 
           Replicate_Do_Table: 
       Replicate_Ignore_Table: 
      Replicate_Wild_Do_Table: 
  Replicate_Wild_Ignore_Table: 
                   Last_Errno: 0
                   Last_Error: 
                 Skip_Counter: 0
          Exec_Source_Log_Pos: 198
              Relay_Log_Space: 602
              Until_Condition: None
               Until_Log_File: 
                Until_Log_Pos: 0
           Source_SSL_Allowed: No
           Source_SSL_CA_File: 
           Source_SSL_CA_Path: 
              Source_SSL_Cert: 
            Source_SSL_Cipher: 
               Source_SSL_Key: 
        Seconds_Behind_Source: NULL
Source_SSL_Verify_Server_Cert: Yes
                Last_IO_Errno: 2003
                Last_IO_Error: Error reconnecting to source 'replication@34.71.57.38:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Can't connect to MySQL server on '34.71.57.38:3306' (111)

  • Once it reaches the “source_retry_count” and “source_connect_retry”, the Replica connects to another Source DC[cluster1-pxc-1].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 34.45.151.96
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000007
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000003
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000007
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

Quick Summary

In this blog post, we walk through the steps to configure Cross-Site Replication in the Percona PXC operator. Although we have used the operator native Xtrabackup to feed the data to the DR via the restore process, we can also use logical backup options like (mysqldump, mydumper, etc.) to accomplish the same goals. 

Using an “Asynchronous Replication” process to sync DR could lead to delays or replication lag due to its flow, or, more importantly, when working across data centres, where network latency is a big factor. However, adding a DR(PXC) cluster to DC(PXC) directly via synchronous replication could be more impactful or lead to flow control issues if any of the DR nodes struggle or experience performance/saturation issues. So, it’s equally important to consider all aspects or challenges before deploying in production.

The post Deploying Cross-Site Replication in Percona Operator for MySQL (PXC) appeared first on Percona.

Feb
04
2026
--

Semantic Caching for LLM Apps: Reduce Costs by 40-80% and Speed up by 250x

?This post covers the topic of the video in more detail and includes some code samples. The $9,000 Problem You launch a chatbot powered by one of the popular LLMs like Gemini, Claude or GPT-4. It’s amazing and your users love it. Then you check your API bill at the end of the month: $15,000. […]
Feb
03
2026
--

Percona at 20: Why Our Open Source, Services-Led Model Still Works

In 2026, Percona turns 20. That milestone offers a good opportunity to pause and reflect, not just on where we have been, but on why our business model has worked for two decades in an industry that has seen constant change. From the beginning, Percona has followed a model that is sometimes misunderstood, occasionally questioned, […]
Sep
18
2025
--

Help Shape the Future of Vector Search in MySQL

Vector Search in MySQLAI and machine learning are seemingly everywhere, and that’s forcing every database company to think about vector search. Companies want to build things like smart search that actually understands what you mean, recommendation systems that know what you’ll like, and tools that can spot when something’s off. To make all of this work at the […]

Jul
18
2025
--

How Can AI Talk to My Database Part Two: MySQL and Gemini

Can AI Talk to My Database Part Two: MySQL and GeminiMy first experiments creating an MCP Server to provide AI access to a PostgreSQL database using the FastMCP Python framework and Anthropic’s and OpenAI’s APIs highlighted an important requirement: for now, these two APIs can only communicate with an MCP server through HTTPS over a public URL. While researching how to make this work (which […]

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com