Jul
22
2026
--

How to Migrate from MySQL Galera Cluster to Percona XtraDB Cluster

On December 1, 2025, MariaDB announced that MySQL Galera Cluster will reach end of life on September 30, 2026. After that date, the MySQL build of Galera stops receiving maintenance and binary releases, and all new clustering features land only in MariaDB Galera Cluster. MariaDB’s recommended path is an in-place migration onto their own server.

If you run MySQL Galera Cluster today, that gives you a real decision to make, and not much time to make it. The good news is that you have more than one option, and the one most teams overlook keeps you on MySQL.

You have two paths, not one

The deadline forces a move, but it does not force you onto MariaDB. There are two realistic destinations, and the difference between them is larger than it first appears, because one is a database engine change and the other is not.

MariaDB Galera Cluster Percona XtraDB Cluster (PXC)
Server MariaDB, a hard fork of MySQL Percona Server for MySQL, a drop-in compatible build of MySQL
Nature of the move Switch to a different database Server and distribution change within MySQL ecosystem
Relationship to MySQL A separate database with its own behavior and dialect The same MySQL you already run, kept compatible
What changes when you migrate New system tables, a different data dictionary, user accounts recreated by hand Stays within the MySQL family; schema and accounts carry over
Clustering MariaDB Galera Cluster Galera write-set replication on Percona’s own open fork
Ecosystem tooling MariaDB’s own backup and monitoring stack Percona XtraBackup, Percona Monitoring and Management, Percona Toolkit
Kubernetes MariaDB’s Kubernetes operator Percona Operator for MySQL
Support MariaDB Percona long-term support, no lock-in

The pattern holds across every row. MariaDB Galera Cluster moves you to a different database and asks you to rebuild around it, while PXC keeps the database you already have and changes what sits underneath it. That is what makes the move below a distribution change rather than a re-platforming.

“In-place” is still a database migration

MariaDB describes its path as near-zero downtime and in place. That is fair for the cluster mechanics, but it understates what is changing underneath. By MariaDB’s own migration documentation, moving to MariaDB Galera Cluster means a different system table structure, a fundamentally different data dictionary, and user accounts and privileges that are not mapped one-to-one and must be recreated by hand.

In other words, you are not upgrading MySQL Galera Cluster. You are moving to a different database that also happens to use Galera. For many teams that is a larger project than the “in-place” label suggests, with application testing, account re-creation, and a new server to operate and support afterward.

Why PXC is the natural landing spot

PXC treats this as continuity rather than conversion. It is MySQL, not a fork of it.

  • It is built on Percona Server for MySQL, a drop-in compatible build of MySQL, so your schema, system tables, and user accounts carry over as they are.
  • Its clustering uses the same Galera write-set replication model you already run, on Percona’s own open Galera fork, which we maintain and ship on our own schedule and on terms we control.
  • It keeps strong binary compatibility with MySQL and Percona Server for MySQL, and integrates with Percona XtraBackup, Percona Monitoring and Management, and both Kubernetes and traditional deployments.

For a MySQL Galera Cluster user, that means the move is a server and distribution change inside the MySQL family, not a migration to a new database.

For a fuller version of this argument, see Marco Tusa’s personal take: The Galera Crossroads: Why PXC is the Lifeline for MariaDB Community Users.

Why PXC, not just the easier migration

Staying on MySQL is the practical argument. There is also a case for choosing PXC on the merits, independent of how much migration effort each path takes.

  • It is genuinely MySQL, not a relative of it. PXC is Percona Server for MySQL, a drop-in compatible build of MySQL. MariaDB began as a MySQL fork but has diverged over the years and is no longer a drop-in replacement for MySQL. With PXC, your MySQL knowledge, queries, tooling, and application compatibility carry forward. With MariaDB, some of that has to be revisited.
  • Open source, with nothing held back. Percona ships its software, including PXC and our Galera fork, as open source, with no enterprise-only tier gating the features you depend on. MariaDB operates as a commercial vendor, with proprietary and enterprise components alongside the community server. If freedom from lock-in is part of why you run open source databases, that difference matters.
  • A steward with no competing database to sell you. This one is worth stating plainly. The company retiring the MySQL build of Galera is the same company recommending you move onto its own database. MariaDB owns Codership, the maintainer of Galera, and has set the end-of-life date while pointing those users to MariaDB Galera Cluster. Percona does not sell a competing database. Our interest is in keeping you successful on MySQL, which is the same interest you have.
  • A long track record in the MySQL ecosystem. Percona has maintained MySQL-focused software for years, including Percona Server for MySQL, Percona XtraBackup, Percona Monitoring and Management, and Percona XtraDB Cluster, all under long-term support. Supporting MySQL users is not a new direction for us.

Taken together, the question is not only which migration is easier. It is which project is built around keeping MySQL open, compatible, and independent, and which one benefits from MySQL Galera coming to an end.

What the migration looks like

Because PXC stays within the MySQL ecosystem, the migration is a distribution change rather than a re-platforming exercise, so the work is mostly planning, testing, and a controlled cutover.

Before you start. Inventory your current cluster: the exact MySQL and Galera versions, node topology, wsrep settings, and any custom configuration. Confirm the PXC version that lines up with your MySQL version, so you are moving across a compatible boundary rather than changing major versions at the same time. Stand up a staging cluster that mirrors production, and capture a baseline backup with Percona XtraBackup before you touch anything.

The right approach depends mainly on how much downtime you can tolerate, ranging from a straightforward binary swap during a maintenance window to a near-online cutover for systems that must stay available. The full, step-by-step guide lives on docs.percona.com, where we keep it current as the tooling improves, and we will link it here once it is published.

Whichever path you take, the same disciplines apply: rehearse the whole thing on staging first, validate application behavior and query performance against PXC before production, and keep a tested rollback (a verified backup or an untouched source cluster) until you are confident. Plan any cutover for a low-traffic window and watch cluster and replication health closely for the first hours afterward.

Start before the deadline

September 30, 2026 is when maintenance and binary releases stop for MySQL Galera Cluster. Running an unmaintained cluster past that point means no security patches and no bug fixes, which is not where you want a mission-critical system to sit. The time it takes to test and validate a move now is worth far more than the risk of waiting.

If you are weighing your options, the short version is this: you do not have to leave MySQL to keep a supported, open source Galera cluster. PXC is here, it is maintained, and it is the closest thing to staying exactly where you are.

Talk to us

If you want help mapping out a migration path, sizing the work, or pressure-testing your high availability strategy, reach out to your Percona contact, post in the Percona community forums, or connect with our team directly. We are happy to walk through it with you.


Written by Dennis Kittrell. Reviewed by Michal Nosek and Marco Tusa.

MySQL, MariaDB, and Galera Cluster are trademarks of their respective owners. Percona is not affiliated with, sponsored by, or endorsed by these owners.

The post How to Migrate from MySQL Galera Cluster to Percona XtraDB Cluster appeared first on Percona.
Apr
20
2026
--

Deploying Cross-Site Replication in Percona Operator for MySQL (PXC)

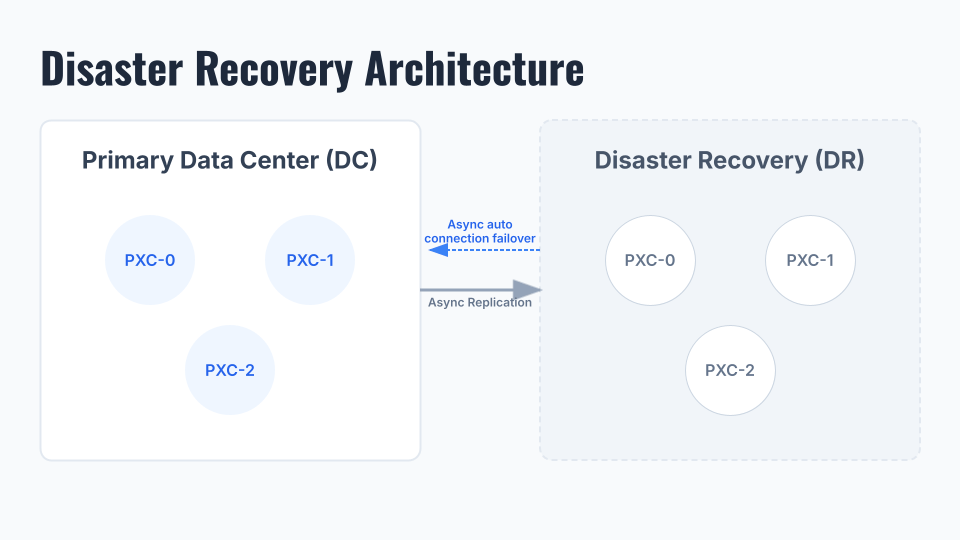
Having a separate DR cluster for production databases is a modern day requirement or necessity for tech and other related businesses that rely heavily on their database systems. Setting up such a [DC -> DR] topology for Percona XtraDB Cluster (PXC), which is a virtually- synchronous cluster, can be a bit challenging in a complex Kubernetes environment.

Here, Percona Operator for MySQL comes in handy, with a minimal number of steps to configure such a topology, which ensures a remote side backup or a disaster recovery solution.

So without taking much time, let’s see how the overall setup and configurations look from a practical standpoint.


PXC Cross-Site/Disaster Recovery


DC Configuration

1) Here we have a three-node PXC cluster running on the DC side.

shell> kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          23h
cluster1-haproxy-1                                 2/2     Running     0          23h
cluster1-haproxy-2                                 2/2     Running     0          23h
cluster1-pxc-0                                     3/3     Running     0          23h
cluster1-pxc-1                                     3/3     Running     0          7h37m
cluster1-pxc-2                                     3/3     Running     0          7h18m
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0          24h
xb-backup1-hlz2p                                   0/1     Completed   0          21h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0          13h

2) There are some configuration options which have to be enabled in a custom resource file[cr.yaml] to allow cross-site replication.

  • Expose all source PXC nodes so they can be communicated from outside or DR cluster.
expose:
      	enabled: true
      	Type: LoadBalancer

  • Define a dedicated replication channel and enable the source option.
replicationChannels:
    - name: pxc1_to_pxc2
      isSource: true

  • Finally, applying the custom resource changes.
shell> kubectl apply -f cr.yaml

3) Now we will notice some “EXTERNAL IP” details for each PXC node. This is the endpoint that DR node [cluster1-pxc-0] will use to connect to DC.

shell> kubectl get svc
NAME                              TYPE           CLUSTER-IP       EXTERNAL-IP     PORT(S)                                          AGE
cluster1-haproxy                  ClusterIP      34.118.227.249   <none>          3306/TCP,3309/TCP,33062/TCP,33060/TCP,8404/TCP   4h1m
cluster1-haproxy-replicas         ClusterIP      34.118.225.41    <none>          3306/TCP                                         4h1m
cluster1-pxc                      ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
cluster1-pxc-0                    LoadBalancer   34.118.234.140   34.29.145.138   3306:30425/TCP                                   4h1m
cluster1-pxc-1                    LoadBalancer   34.118.239.132   34.30.233.0     3306:31340/TCP                                   4h1m
cluster1-pxc-2                    LoadBalancer   34.118.236.64    35.225.0.19     3306:30642/TCP                                   4h1m
cluster1-pxc-unready              ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
percona-xtradb-cluster-operator   ClusterIP      34.118.235.168   <none>          443/TCP                                          4h11m

At this point, we are done with the DC setup. Next, we will take a backup from Source which we later used to build the DR.


Backup

  • Defining access key/secrets to connect to the GCP/S3 bucket.
cat backup-secret-s3.yaml

apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

  • In the custom resource file [cr.yaml] , we also need to define the bucket , secret file and endpoint/region details.
backup:

 storages:
   s3-us-west:
      type: s3
      verifyTLS: true

    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      region: us-west-2
      endpointUrl: https://storage.googleapis.com

shell> kubectl apply -f cr.yaml

  • Finally, we can take the backup by creating a [backup.yaml] file with below details.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterBackup
metadata:
#  finalizers:
#    - percona.com/delete-backup
  name: backup1
spec:
  pxcCluster: cluster1
  storageName:  s3-us-west

shell> kubectl apply -f cr.yaml

  • We can verify the successful backup as follows.
kubectl get pxc-backup
NAME      CLUSTER    STORAGE      DESTINATION                                     STATUS      COMPLETED   AGE
backup1   cluster1   s3-us-west   s3://<bucket>/cluster1-2026-04-07-15:55:46-full   Succeeded   125m        127m

As the backup is also ready, we can now move to the DR setup part.


DR Configuration

Below we have a similar PXC setup as having in DC in a separate Node/ K8s Cluster.

kubectl get pods -n pxc-dr
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          35h
cluster1-haproxy-1                                 2/2     Running     0          35h
cluster1-haproxy-2                                 2/2     Running     0          35h
cluster1-pxc-0                                     3/3     Running     0          35h
cluster1-pxc-1                                     3/3     Running     0          35h
cluster1-pxc-2                                     3/3     Running     0          35h
percona-xtradb-cluster-operator-6756dbf588-2wc5m   1/1     Running     0          38h
prepare-job-restore1-cluster1-8h4vn                0/1     Completed   0          35h
restore-job-restore1-cluster1-trfg6                0/1     Completed   0          35h
xb-cron-cluster1-fs-pvc-2026480025-372f8-wv6bt     0/1     Completed   0          28h
xb-cron-cluster1-fs-pvc-2026490025-372f8-gxd59     0/1     Completed   0          4h48m

First, we need to restore the backup on the DR server.

Data Restoration

  • Here we will create the [backup-secret-s3.yaml] file which contains the GCP/S3 credentials.
apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

shell> kubectl apply -f backup-secret-s3.yaml

  • Next, we will create a [restore.yaml] file while mentioning the backup source and other useful information.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterRestore
metadata:
  name: restore1
#  annotations:
#    percona.com/headless-service: "true"
spec:
  pxcCluster: cluster1
  backupSource:
#    verifyTLS: true
    destination: s3://<bucket>/cluster1-2026-04-07-15:55:46-full
    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      endpointUrl: https://storage.googleapis.com/

shell> kubectl apply -f restore.yaml

  • Once the restoration is finished successfully, we will see the status below.
shell> kubectl get pxc-restore
NAME       CLUSTER    STATUS      COMPLETED   AGE
restore1   cluster1   Succeeded               27m

Now we can do the remaining DR changes in the custom resource file [cr.yaml]. Basically, we need to add the replication channel and all source EXTERNAL-IPs. This cross-DC replication supports Automatic Asynchronous Replication Connection Failover feature, so in case any of the DC node is down, the Replica can connect and resume from other available DC nodes.

replicationChannels:
    - name: pxc1_to_pxc2
      isSource: false
      sourcesList:
      - host: 34.29.145.138  
        port: 3306
        weight: 100

      - host: 34.30.233.0
        port: 3306
        weight: 100

      - host: 35.225.0.19
        port: 3306
        weight: 100

shell> kubectl apply -f cr.yaml

For backup and restoration on the PXC operator, the manuals below can be referenced further.


Replication

Initially, when we check the replication status, we can notice the following error. This is because with [caching_sha2_password] authentication, it should be a secure SSL/TLS communication, or else we can use SOURCE_PUBLIC_KEY_PATH/GET_SOURCE_PUBLIC_KEY  which basicaly enables the RSA key pair-based password exchange by requesting the public key from the source. 

shell> kubectl exec -it cluster1-pxc-0  -- sh
shell> mysql -uroot -p

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Connecting to source
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: 
          Read_Source_Log_Pos: 4
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 4
        Relay_Source_Log_File: 
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
...

Error:

Last_IO_Error: Error connecting to source 'replication@35.225.0.19:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Access denied for user 'replication'@'35.225.0.19.' (using password: YES)

Once we passed “GET_SOURCE_PUBLIC_KEY” in the “CHANGE REPLICATION” command the  error is resolved and DR successfully able to communicate with the DC.

mysql> STOP REPLICA;
mysql> STOP REPLICA IO_THREAD FOR CHANNEL 'pxc1_to_pxc2';
mysql> CHANGE REPLICATION SOURCE TO SOURCE_USER='replication', SOURCE_PASSWORD='password', GET_SOURCE_PUBLIC_KEY=1 FOR CHANNEL 'pxc1_to_pxc2';
mysql> START REPLICA;

Note  – The Replication user will be auto-created on the DC node. So, with the help of below command we can get the decoded password for “replication” user.

shell> kubectl get secret cluster1-secrets -o jsonpath="{.data.replication}" | base64 --decode

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000006
          Read_Source_Log_Pos: 3047027
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 150132
        Relay_Source_Log_File: binlog.000006
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

The other PXC DR nodes will sync as usual with the Galera Synchronous replication process. 

Source Failover

The asynchronous connection failover is already enabled on the DR as we defined initially in the custom resource file. The “External IPs”  shows different here because they changed in this testing scenario.

mysql> select * from performance_schema.replication_asynchronous_connection_failover;
+--------------+---------------+------+-------------------+--------+--------------+
| CHANNEL_NAME | HOST          | PORT | NETWORK_NAMESPACE | WEIGHT | MANAGED_NAME |
+--------------+---------------+------+-------------------+--------+--------------+
| pxc1_to_pxc2 | 34.29.145.138 | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.45.151.96  | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.71.57.38   | 3306 |                   |    100 |              |
+--------------+---------------+------+-------------------+--------+--------------+
3 rows in set (0.00 sec)

Now, in case the existing Source DC[cluster1-pxc-2] is down, the DR will connect to one of the other available DC nodes based on the “Weight” and chronological order [pxc-2, pxc-1, pxc-0 etc].

  • Here, we temporarily take down the Source DC[cluster1-pxc-2] node.
kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS     AGE
cluster1-haproxy-0                                 2/2     Running     0            2d3h
cluster1-haproxy-1                                 2/2     Running     0            2d3h
cluster1-haproxy-2                                 2/2     Running     0            2d3h
cluster1-pxc-0                                     3/3     Running     0            2d3h
cluster1-pxc-1                                     3/3     Running     0            35h
cluster1-pxc-2                                     2/3     Running     1 (6s ago)   34h
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0            2d3h
xb-backup1-hlz2p                                   0/1     Completed   0            2d1h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0            41h
xb-cron-cluster1-fs-pvc-2026490026-372f8-mgfpv     0/1     Completed   0            17h

  • The DR replication breaks as it can’t reach the DC [cluster1-pxc-2].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Reconnecting after a failed source event read
                  Source_Host: 34.71.57.38
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000012
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000002
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000012
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
              Replicate_Do_DB: 
          Replicate_Ignore_DB: 
           Replicate_Do_Table: 
       Replicate_Ignore_Table: 
      Replicate_Wild_Do_Table: 
  Replicate_Wild_Ignore_Table: 
                   Last_Errno: 0
                   Last_Error: 
                 Skip_Counter: 0
          Exec_Source_Log_Pos: 198
              Relay_Log_Space: 602
              Until_Condition: None
               Until_Log_File: 
                Until_Log_Pos: 0
           Source_SSL_Allowed: No
           Source_SSL_CA_File: 
           Source_SSL_CA_Path: 
              Source_SSL_Cert: 
            Source_SSL_Cipher: 
               Source_SSL_Key: 
        Seconds_Behind_Source: NULL
Source_SSL_Verify_Server_Cert: Yes
                Last_IO_Errno: 2003
                Last_IO_Error: Error reconnecting to source 'replication@34.71.57.38:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Can't connect to MySQL server on '34.71.57.38:3306' (111)

  • Once it reaches the “source_retry_count” and “source_connect_retry”, the Replica connects to another Source DC[cluster1-pxc-1].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 34.45.151.96
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000007
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000003
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000007
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

Quick Summary

In this blog post, we walk through the steps to configure Cross-Site Replication in the Percona PXC operator. Although we have used the operator native Xtrabackup to feed the data to the DR via the restore process, we can also use logical backup options like (mysqldump, mydumper, etc.) to accomplish the same goals. 

Using an “Asynchronous Replication” process to sync DR could lead to delays or replication lag due to its flow, or, more importantly, when working across data centres, where network latency is a big factor. However, adding a DR(PXC) cluster to DC(PXC) directly via synchronous replication could be more impactful or lead to flow control issues if any of the DR nodes struggle or experience performance/saturation issues. So, it’s equally important to consider all aspects or challenges before deploying in production.

The post Deploying Cross-Site Replication in Percona Operator for MySQL (PXC) appeared first on Percona.

Jan
27
2026
--

Automatic “Multi-Source” Async Replication Failover Using PXC Replication Manager

Automatic "Multi-Source" Async Replication Failover Using PXC Replication ManagerThe replication  manager script can be particularly useful in complex PXC/Galera topologies that require Async/Multi-source replication. This will ease the auto source and replica failover to ensure all replication channels are healthy and in sync. If certain nodes shouldn’t  be part of a async/multi-source replication, we can disable the replication manager script there to tightly controlled the flow. Alternatively, node participation can be controlled by adjusting the weights in the percona.weight table, allowing replication behavior to be managed more precisely.

Jun
26
2025
--

Percona XtraDB Cluster: Our Commitment to Open Source High Availability

Percona XtraDB Cluster GaleraAt Percona, we’ve always been dedicated to providing robust, open source solutions that meet our users’ evolving needs. Percona XtraDB Cluster (PXC) stands as a testament to this commitment, offering a highly available and scalable solution for your MySQL and Percona Server for MySQL deployments. We understand that database high availability is critical for your […]

Jun
26
2025
--

Percona XtraDB Cluster: Our Commitment to Open Source High Availability

Percona XtraDB Cluster GaleraAt Percona, we’ve always been dedicated to providing robust, open source solutions that meet our users’ evolving needs. Percona XtraDB Cluster (PXC) stands as a testament to this commitment, offering a highly available and scalable solution for your MySQL and Percona Server for MySQL deployments. We understand that database high availability is critical for your […]

Jan
22
2025
--

Using Blue/Green Deployment For (near) Zero-Downtime Primary Key Updates in RDS MySQL

Blue Green Deployment RDS MySQLLarge tables can pose challenges for many operations when working with a database. Occasionally, we may need to modify the table definition. Since RDS replication does not use asynchronous for its replication, the typical switchover procedure is not feasible. However, the Blue/Green feature of RDS utilizes asynchronous replication, which allows us to update the table […]

Sep
11
2024
--

MongoDB: High Availability Topology for a Multi-Region Setting

MongoDB High Availability Topology for a Multi-Region SettingMongoDB high availability is essential to ensure reliability, customer satisfaction, and business resilience in an increasingly interconnected and always-on digital environment. Ensuring high availability for database systems introduces complexity, as databases are stateful applications. Adding a new operational node to a cluster can take hours or even days, depending on the dataset size. This is […]

Aug
14
2024
--

Effective Strategies for Recovering MySQL Group Replication From Failures

Group replication is a fault-tolerant/highly available replication topology that ensures if the primary node goes down, one of the other candidates or secondary members takes over so write and read operations can continue without any interruptions. However, there are some scenarios where, due to outages, network partitions, or database crashes, the group membership could be broken, or we end […]

May
29
2024
--

Valkey/Redis: Setting Up Replication

setting up replication in ValkeyIn most database systems, like MySQL, PostgreSQL, and MongoDB, replication of some kind is used to create a highly available architecture. Valkey/Redis is no different in this regard. Replication is native functionality to Valkey, supporting multiple replicas, and even chains of replication.To clear up any confusion, understand that Valkey replication is a different concept compared […]

May
21
2024
--

High Availability: Choosing the Right Option for Your Percona Monitoring and Management

high availability percona monitoring and managementEnsuring your monitoring system stays up and running is vital. High availability (HA) minimizes downtime for Percona Monitoring and Management (PMM) during hardware failures, in times of disaster recovery, or increased usage of the tool. It’s not just about extra storage, RAM, or CPU but rather having redundant systems ready to take over seamlessly, like […]

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com