Aug
13
2026
--

Replicating from InnoDB into a DuckDB storage engine

Our first post showed MySQL 9.7 with one change: mark a table ENGINE=DuckDB and its analytical queries run in DuckDB instead of InnoDB. The question we kept getting after that was about replication. Can you keep a normal InnoDB primary for the writes, and run a replica where the big tables are ENGINE=DuckDB? Then the heavy reports run on a column store, and ordinary MySQL replication keeps it current. No export job. No second database to sync by hand.

So we tried it. The first run failed, and it failed in a way that is easy to miss: the replica took every transaction, reported success, and stored nothing. We tracked down why, fixed it, and the whole test suite passes now. This post is what we tested, how we checked it, the bug we found, and where it stands.

It’s still an experiment, not production software. The code and the test harness are on GitHub under GPLv2: https://github.com/Percona-Lab/ducksdb-mysql-engine.

Why replicate into DuckDB

A DuckDB table on one server is already useful. The analytical queries get fast and the application does not change. But almost nobody runs their reports on the primary – they run them on a replica, so the big scans stay out of the way of the OLTP traffic.

So the shape of it is simple. The primary stays InnoDB and takes the writes. The replica has the same tables, only marked ENGINE=DuckDB. Row-based replication ships the changes across, the replica writes them into the column store, and the reports run there. You get an analytics replica out of the replication you already run.

Row events are engine-agnostic on purpose. The primary logs the row changes, not the SQL, and the replica applies them through the storage-engine API. On paper, then, the replica should not care that one side is InnoDB and the other DuckDB. We wanted to see the paper version hold up on a running server.

The setup

Two containers from the same image, one primary and one replica. It’s all in Docker, so it repeats cleanly.

  • Primary: InnoDB, binlog_format=ROW, GTID on.
  • Replica: same server, GTID on, tables made with ENGINE=DuckDB.
  • Replication uses SOURCE_AUTO_POSITION=1.

One thing you have to get right before any data moves. Create the replica tables as ENGINE=DuckDB yourself. A CREATE TABLE … ENGINE=InnoDB on the primary goes into the binlog with the ENGINE word still in it, and the replica runs it exactly as written, so you would end up with an InnoDB table there, not a DuckDB one. There is no automatic mapping. Pre-create the DuckDB tables on the replica, and let the row changes flow into them.

-- primary (InnoDB)
CREATE TABLE t1 (id BIGINT PRIMARY KEY, region INT, amount DECIMAL(12,2)) ENGINE=InnoDB;

-- replica (same columns, DuckDB)
CREATE TABLE t1 (id BIGINT PRIMARY KEY, region INT, amount DECIMAL(12,2)) ENGINE=DuckDB;

The other rule is a primary key on the replica table. UPDATE and DELETE row events find the row by its old image, and the engine needs the key for that. INSERT works without one, but put a key on it anyway.

One script drives all of this: bench/tb/07-replication-spike.sh. It starts both containers, wires up replication, runs every scenario below, and prints PASS or FAIL for each.

What we tested, and how

The part that matters is the checking. Row counts are not enough – the replica can hold the right number of rows and still have the wrong data in them. So after each step the script dumps the whole table on both sides, ordered by primary key, and compares an md5 of the two dumps. One byte off is a FAIL. And rather than sleep between steps, it waits on WAIT_FOR_EXECUTED_GTID_SET(), so the checks do not race the replica.

Here is what went through it.

Basic DML. Insert, update a row, delete a row, compared after each one.

All the column types, in a single wide table: signed and unsigned integers, DECIMAL, DOUBLE, DATE, DATETIME, TIMESTAMP, CHAR, VARCHAR, TEXT, BLOB, a few NULLs, and a unicode string. Insert it, update it, compare byte for byte. Blobs get their own note below.

DDL. ALTER TABLE ADD COLUMN, ALTER TABLE ADD INDEX, and DROP TABLE against a DuckDB replica table. These arrive as statements. We check that the column shows up, the index shows up, the old rows survive, and the drop removes the table.

Transactions. A transaction with two inserts and an update has to land on the replica as one unit. A transaction the primary rolls back has to leave nothing behind. We also open a transaction straight on the replica and both roll it back and commit it, to check the engine’s own commit and rollback.

Bulk load. 5000 rows through LOAD DATA on the primary, has to arrive and match.

Durability. Two cases, and the second is the hard one.

  • Clean restart. Stop the replica properly, write on the primary while it is down, start it again, and see it pick up from its GTID position.
  • Crash. Apply some rows, then SIGKILL the replica. No clean shutdown, no checkpoint. Bring it back, write more on the primary, and check one exact thing: every row present once. Nothing lost – DuckDB has to replay its write-ahead log when it opens the file – and nothing applied twice, which means the saved position has to line up with the data that actually reached disk.

The bug: multi-engine transactions lost data

The first full run fell down on the wide-table test. Zero rows on the replica, and then everything after it failed too. The applier had stopped with HA_ERR_KEY_NOT_FOUND. It went to UPDATE a row that was not there, because the INSERT before it had returned success and written nothing.

When a scenario fails, the harness saves the applier error, both server logs, and both schemas. The replica log had the line that mattered:

[Warning] Combining the storage engines InnoDB and DuckDB is deprecated, but the
statement or transaction updates both the InnoDB table mysql.slave_worker_info and the
DuckDB table rpl.wide.

That line is the whole thing. A replica does not only write your data. In the same transaction it also writes its own position into InnoDB system tables – mysql.slave_worker_info, the relay-log info, gtid_executed. So every applied transaction touches two engines at once: InnoDB for the position, DuckDB for the data. Two engines means MySQL runs a real two-phase commit: prepare, then commit.

Our prepare was wrong. It took the open DuckDB transaction, moved it into a registry meant for external XA COMMIT, and cleared the per-connection state. Then commit looked at that state, found it empty, and committed nothing. The position went into InnoDB, the GTID advanced, the binlog moved on, and the DuckDB rows were thrown away. No error anywhere. The replica looked healthy while it dropped every write.

We cut it down to the smallest case, with no replication at all. One server, one transaction into a DuckDB table and an InnoDB table:

BEGIN;
INSERT INTO duck VALUES (1,10),(2,20),(3,30);   -- DuckDB
INSERT INTO inno VALUES (1,10),(2,20),(3,30);   -- InnoDB
COMMIT;
-- duck: 0 rows   inno: 3 rows

InnoDB kept its three rows, DuckDB kept none, and COMMIT said it was fine. A DuckDB-only transaction was fine as well, because with one engine MySQL skips the prepare step. It only broke with a second engine in the transaction. And on a replica, that is every transaction.

The fix

Small change, in the engine’s transaction code. prepare now remembers which prepared transaction belongs to the connection, and commit finishes that one instead of an empty state. External XA is untouched. It went out as v0.2.3.

With that in place the reproducer keeps three rows in both tables, and the full run comes back clean, crash test included:

[8]  data integrity: all column types, NULL / unicode / negatives ....... PASS
[9]  DDL replication (ALTER ADD COLUMN / ADD INDEX / DROP) .............. PASS
[10] transactions (atomic commit, rollback, engine commit/rollback) ..... PASS
[11] bulk LOAD DATA on master -> replica ................................ PASS
[12] durability: graceful restart, then SIGKILL crash recovery .......... PASS

VERDICT: PASS=24  FAIL=0

The crash case is the important one. After a SIGKILL in the middle of applying, the replica came back with every committed row exactly once, matching the primary. Committed transactions survive the kill, and the position stays in step with them.

We left two tests behind so this cannot slip back in quietly: an MTR test, txn_mixed_engine, that runs a mixed DuckDB+InnoDB transaction on every build, and scripts/repro-2pc-dataloss.sh, which you can point at any published image to check it.

What works, and what doesn’t yet

Where it stands on v0.2.3, for an InnoDB primary feeding a DuckDB replica:

Scenario Result
INSERT / UPDATE / DELETE works, content matches
All column types (numeric, temporal, string, BLOB, NULL, unicode) works
ALTER ADD COLUMN / ADD INDEX, DROP TABLE works
Transaction commit / rollback works, atomic
Bulk LOAD DATA works
Graceful restart, resume from GTID works
SIGKILL crash, no loss / no duplicates works

The things to keep in mind:

  • Create the replica tables as ENGINE=DuckDB yourself. A replicated CREATE TABLE keeps the primary’s engine, so it will not turn into DuckDB on its own.
  • Replica tables need a primary key for UPDATE and DELETE.
  • The applier goes row by row. That is fine for a normal OLTP change stream. It is not fine for keeping up with a primary that bulk-loads at full speed – the replica will fall behind.
  • Committed transactions are crash-safe, with one small gap. The engine holds a prepared-but-not-committed transaction in memory only, so a crash in the short window between prepare and commit can lose that single transaction. The applier commits right away, so the window is small, but it is not zero.
  • Blobs behave differently over replication than through a direct statement. A plain UPDATE of a BLOB or TEXT column has a known limit in the engine and does not apply. Over replication it does apply, because the row event carries a full before-and-after image instead of the shared buffer the direct path uses.

And the obvious one. This is an experiment. It is a functional result from a test harness on small data, not an HA or failover benchmark. We did not test multi-source replication, filters, or a real write rate.

Where it stands

An InnoDB primary feeding a DuckDB replica works on v0.2.3. Inserts, updates, deletes, every common type, schema changes, transactions, bulk load – they all replicate and match, and it comes back clean from both a graceful restart and a hard kill. The one real bug, silent data loss on every replicated transaction, is found, understood, fixed, and covered by tests.

It is not production-ready, and we do not treat it as such. But the idea holds up. Point normal MySQL replication at a DuckDB replica, and you get an analytics copy that keeps itself in sync.

The post Replicating from InnoDB into a DuckDB storage engine appeared first on Percona.
Aug
07
2026
--

The DuckDB MySQL engine at 500 GB

We ran DuckDB MySQL storage engine at scale factor 500. It is around 500 GB of raw TPC-H, three billion lineitem rows  on an 80-core server with 187 GB of RAM. Three engines on the same box: InnoDB, our MySQL+DuckDB engine, and plain DuckDB as the reference.

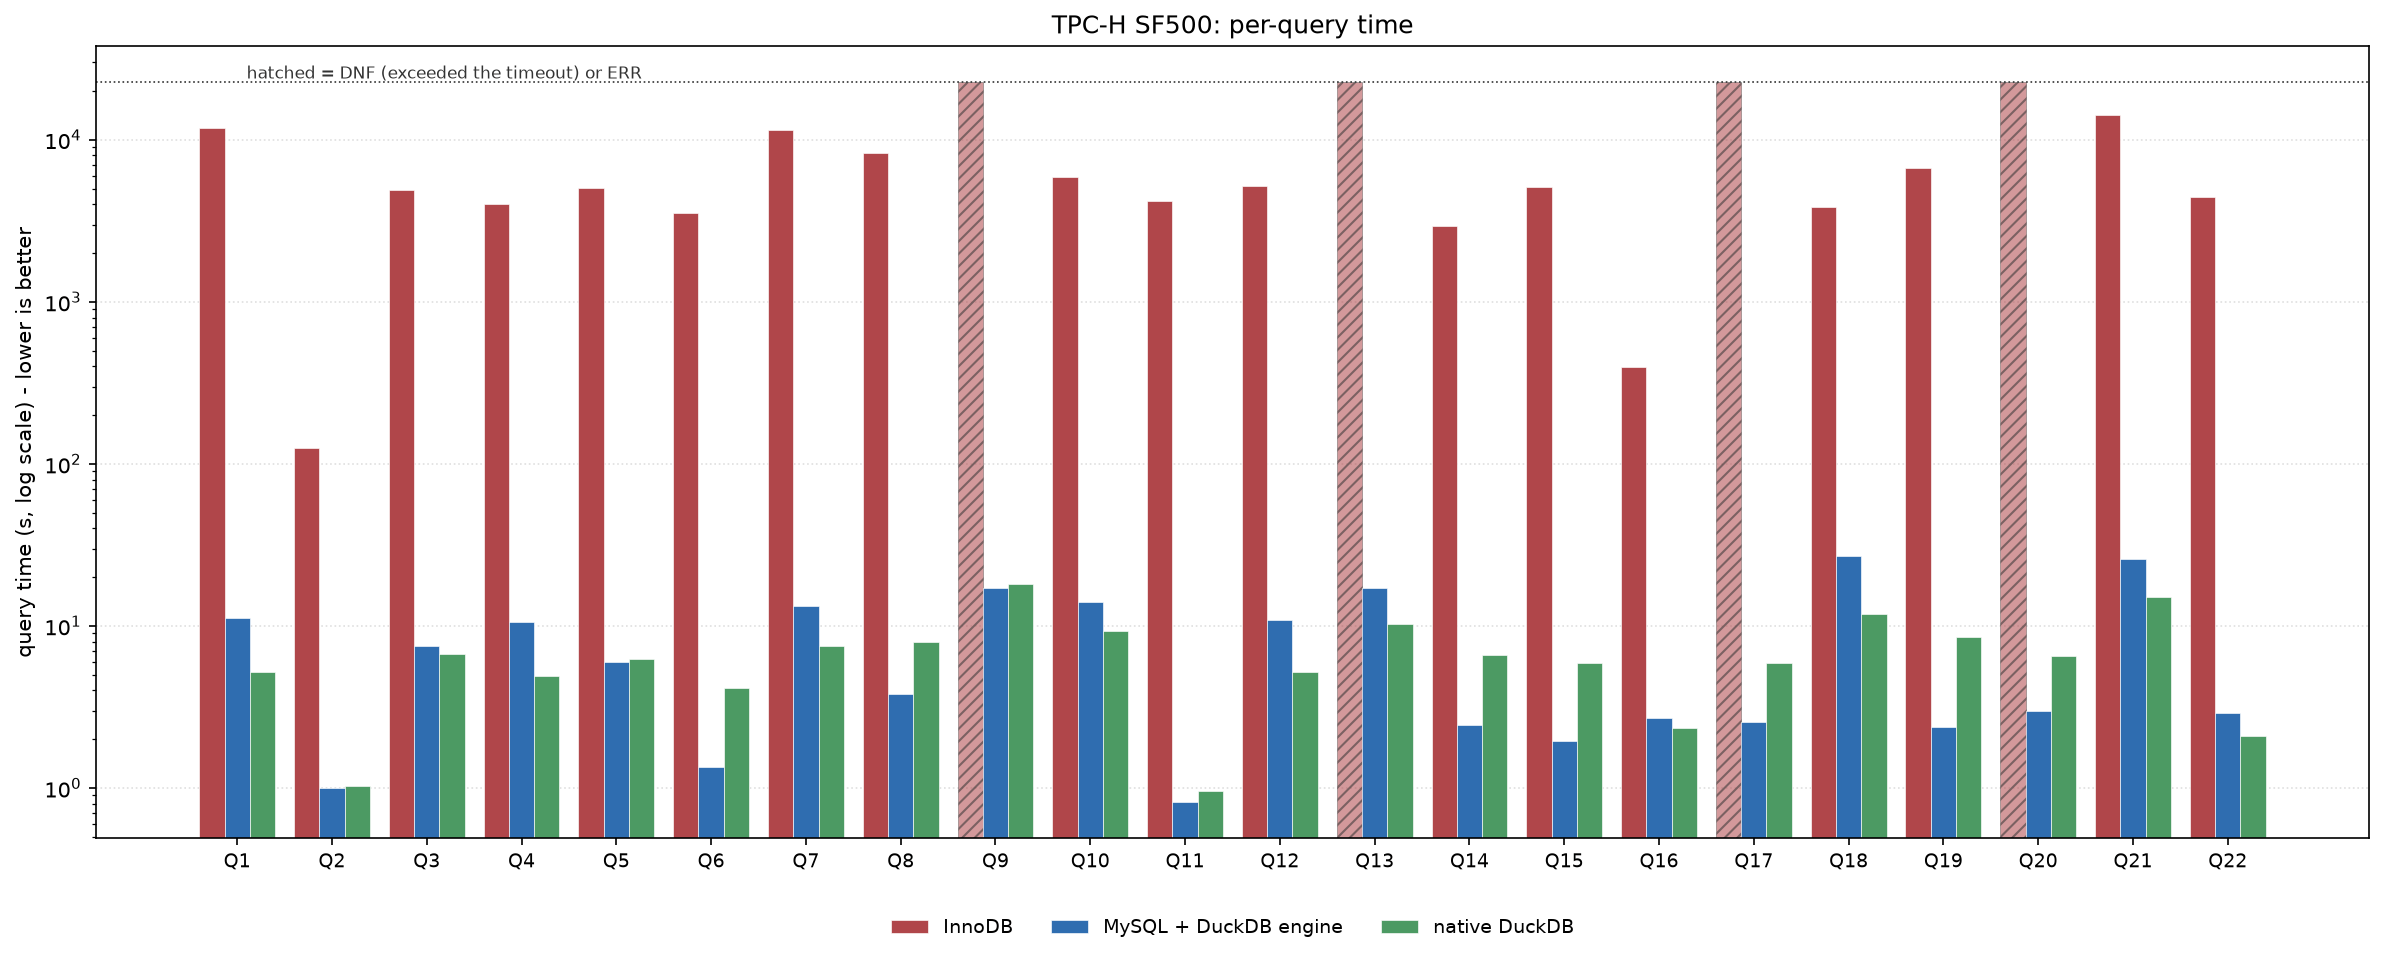
Here is what came out. InnoDB finished 18 of the 22 queries and spent more than 28 hours of query time on them. Four never finished. Our engine ran all 22 in about three minutes. It loaded the data 25 times faster than InnoDB, and it used 5 times less disk. On the queries it stays close to plain DuckDB, and on a few it is ahead.

It’s still an experiment, not production software. Code and the benchmark harness are on GitHub under GPLv2: https://github.com/Percona-Lab/ducksdb-mysql-engine.

The machine, and how we ran it

  • One server, 80 cores, 187.5 GB RAM.
  • SF500: about 500 GB of raw CSV, 3,000,028,242 lineitem rows.
  • Three engines, one at a time: InnoDB, our engine, native DuckDB.
  • All of it through the harness in the repo (bench/tb), in Docker.

Two details about how we ran it change how the numbers read.

The load streams. We generate a chunk of CSV, load it, delete it, then generate the next one. So the disk never holds more than one 20 GB chunk, which is the only reason 500 GB fits on the box at all.

And “native DuckDB” is not a second copy of the data. It opens the engine’s own DuckDB file read-only and queries that. Same bytes on both sides. That keeps the comparison honest, and it means there is no separate native load time to report.

Loading the data

Engine Load time
ENGINE=DuckDB (COPY fast path) 36m 05s
InnoDB (bulk LOAD DATA) 15h 21m

InnoDB took 25.5 times longer. The engine hands LOAD DATA straight to a DuckDB COPY instead of going row by row through the handler, so the three billion lineitem rows go in in about nineteen minutes, and the whole set in thirty-six. InnoDB inserts row by row and builds the primary key as it goes. That is where the rest of the fifteen hours goes.

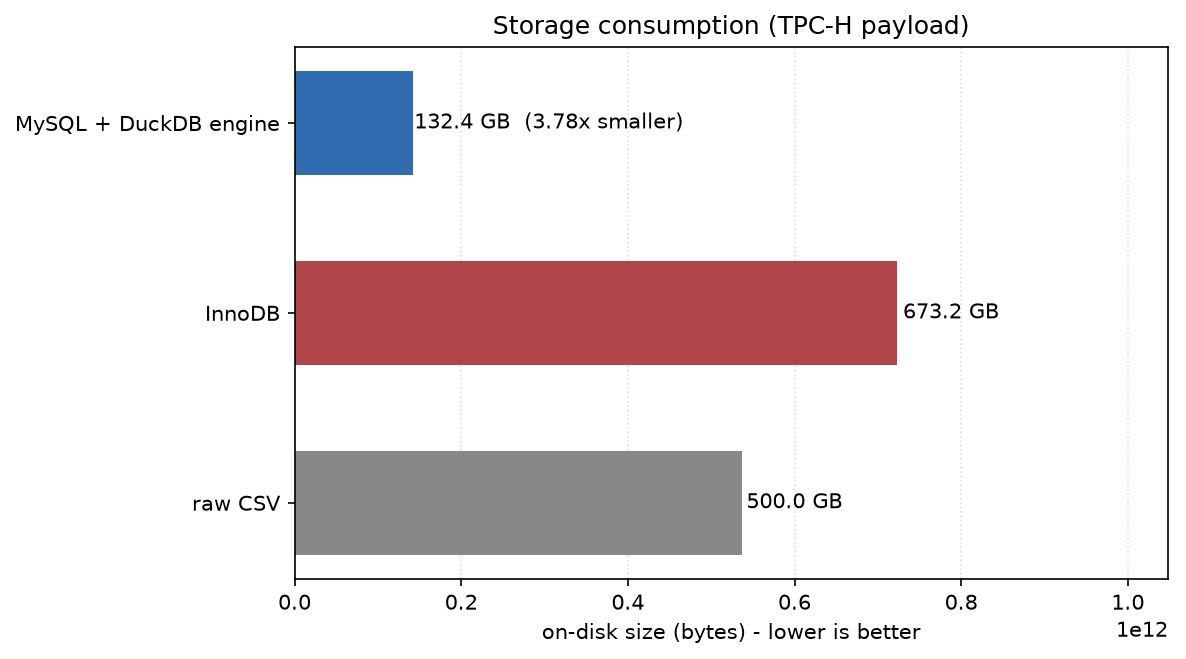
Storage on disk

Component Size vs raw CSV
raw TPC-H CSV 500.0 GB 100%
ENGINE=DuckDB (tpch.duckdb) 132.4 GB 26% (3.78x smaller)
InnoDB (tpch/*.ibd) 673.2 GB 135%

DuckDB stores columns and compresses them, so 500 GB of CSV comes down to 132 GB. InnoDB stores rows and carries the index with them, and it ends up bigger than the CSV it came from: 673 GB, five times the DuckDB file. The InnoDB lineitem.ibd on its own is 446 GB. That is more than three times our entire database.

Storage, lower is better. The DuckDB engine holds all of SF500 in 132 GB.

Query time

All 22 queries. Warm runs, minimum of a few, in seconds. InnoDB had a two-hour cap per query; the ones that hit it are marked DNF.


Query InnoDB MySQL+DuckDB (ours) native DuckDB
Q1 11864.5 11.1 5.2
Q6 3539.4 1.3 4.1
Q9 DNF 17.1 18.1
Q13 DNF 17.1 10.4
Q18 3846.1 27.0 11.9
Q19 6672.3 2.4 8.6
Q21 14211.7 26.0 15.1
All 22 18/22 finished, ~28 h 185.6 s 152.7 s

SF500, all 22 queries, log scale, lower is better. Hatched InnoDB bars did not finish inside the cap.

Two things to take from this.

InnoDB is far behind, which is no surprise. Scanning three billion rows for a wide GROUP BY or a six-way join is the wrong job for a row store. Four queries (Q9, Q13, Q17, Q20) did not finish at all, and the eighteen that did add up to more than 28 hours. This is the exact problem the engine is for. It is not a mark against InnoDB, which is doing the transactional job it was built for.

The comparison worth reading is our engine against plain DuckDB, since both are the same DuckDB reading the same file. Over all 22 they are close: 186 seconds for ours, 153 for native. Query by query it goes both ways. On the selective ones ours is often faster — Q6 (1.3 vs 4.1), Q19 (2.4 vs 8.6), Q17, Q20. On the biggest joins native wins — Q18 (27 vs 12), Q21, Q1. That gap comes from settings, not data: the memory limit, the thread count, and running inside mysqld versus a bare CLI. Either way, both are around a thousand times faster than the row store.

Correctness

We checked the answers, not only the clock. For every query we compared our engine’s output to native DuckDB’s, numbers rounded to four decimals and the order ignored. 21 of 22 matched exactly. None mismatched. One was skipped because a result file came back empty on one side. So the engine gives the same answers as plain DuckDB.

What this means, and where it stops

At 500 GB the small-scale picture holds and gets sharper. Analytical queries that took hours on InnoDB, or never finished, come back in seconds on the DuckDB engine. The load is far quicker, and the footprint is far smaller. All of it inside one MySQL server, with the tables queried the normal way.

The limits are the same as before:

  • It is for analytics, not OLTP. Point lookups and single-row work stay on the row path, where an index seek is the right tool.
  • DuckDB runs inside mysqld, so a heavy query under a tight memory limit can go over budget. DUCKSDB_MEMORY_LIMIT and DUCKSDB_TEMP_DIR let it spill to disk instead of failing. We set a limit here so the big CTEs spill rather than get OOM-killed.
  • Some queries still fall back to normal MySQL and run on the row path.
  • It is one workload on one machine. The result is strong, but the engine is still an experiment, not something for production traffic.

Try it

Pull the image and run your own queries:

docker run -d -p 3306:3306 -e MYSQL_ROOT_PASSWORD=secret \
  perconalab/ducksdb-mysql-engine:latest

The engine, the patches, and the harness that produced these numbers are on GitHub: https://github.com/Percona-Lab/ducksdb-mysql-engine. The per-query numbers and the method are in the repo. If it breaks, or your hardware gives different numbers, open an issue.

The post The DuckDB MySQL engine at 500 GB appeared first on Percona.

Apr
20
2026
--

Deploying Cross-Site Replication in Percona Operator for MySQL (PXC)

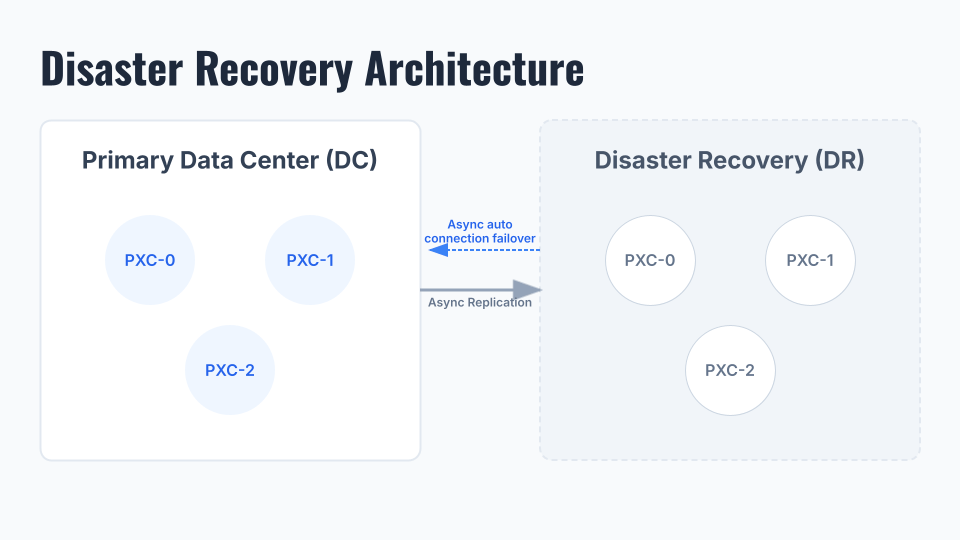
Having a separate DR cluster for production databases is a modern day requirement or necessity for tech and other related businesses that rely heavily on their database systems. Setting up such a [DC -> DR] topology for Percona XtraDB Cluster (PXC), which is a virtually- synchronous cluster, can be a bit challenging in a complex Kubernetes environment.

Here, Percona Operator for MySQL comes in handy, with a minimal number of steps to configure such a topology, which ensures a remote side backup or a disaster recovery solution.

So without taking much time, let’s see how the overall setup and configurations look from a practical standpoint.


PXC Cross-Site/Disaster Recovery


DC Configuration

1) Here we have a three-node PXC cluster running on the DC side.

shell> kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          23h
cluster1-haproxy-1                                 2/2     Running     0          23h
cluster1-haproxy-2                                 2/2     Running     0          23h
cluster1-pxc-0                                     3/3     Running     0          23h
cluster1-pxc-1                                     3/3     Running     0          7h37m
cluster1-pxc-2                                     3/3     Running     0          7h18m
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0          24h
xb-backup1-hlz2p                                   0/1     Completed   0          21h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0          13h

2) There are some configuration options which have to be enabled in a custom resource file[cr.yaml] to allow cross-site replication.

  • Expose all source PXC nodes so they can be communicated from outside or DR cluster.
expose:
      	enabled: true
      	Type: LoadBalancer

  • Define a dedicated replication channel and enable the source option.
replicationChannels:
    - name: pxc1_to_pxc2
      isSource: true

  • Finally, applying the custom resource changes.
shell> kubectl apply -f cr.yaml

3) Now we will notice some “EXTERNAL IP” details for each PXC node. This is the endpoint that DR node [cluster1-pxc-0] will use to connect to DC.

shell> kubectl get svc
NAME                              TYPE           CLUSTER-IP       EXTERNAL-IP     PORT(S)                                          AGE
cluster1-haproxy                  ClusterIP      34.118.227.249   <none>          3306/TCP,3309/TCP,33062/TCP,33060/TCP,8404/TCP   4h1m
cluster1-haproxy-replicas         ClusterIP      34.118.225.41    <none>          3306/TCP                                         4h1m
cluster1-pxc                      ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
cluster1-pxc-0                    LoadBalancer   34.118.234.140   34.29.145.138   3306:30425/TCP                                   4h1m
cluster1-pxc-1                    LoadBalancer   34.118.239.132   34.30.233.0     3306:31340/TCP                                   4h1m
cluster1-pxc-2                    LoadBalancer   34.118.236.64    35.225.0.19     3306:30642/TCP                                   4h1m
cluster1-pxc-unready              ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
percona-xtradb-cluster-operator   ClusterIP      34.118.235.168   <none>          443/TCP                                          4h11m

At this point, we are done with the DC setup. Next, we will take a backup from Source which we later used to build the DR.


Backup

  • Defining access key/secrets to connect to the GCP/S3 bucket.
cat backup-secret-s3.yaml

apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

  • In the custom resource file [cr.yaml] , we also need to define the bucket , secret file and endpoint/region details.
backup:

 storages:
   s3-us-west:
      type: s3
      verifyTLS: true

    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      region: us-west-2
      endpointUrl: https://storage.googleapis.com

…

shell> kubectl apply -f cr.yaml

  • Finally, we can take the backup by creating a [backup.yaml] file with below details.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterBackup
metadata:
#  finalizers:
#    - percona.com/delete-backup
  name: backup1
spec:
  pxcCluster: cluster1
  storageName:  s3-us-west

…

shell> kubectl apply -f cr.yaml

  • We can verify the successful backup as follows.
kubectl get pxc-backup
NAME      CLUSTER    STORAGE      DESTINATION                                     STATUS      COMPLETED   AGE
backup1   cluster1   s3-us-west   s3://<bucket>/cluster1-2026-04-07-15:55:46-full   Succeeded   125m        127m

As the backup is also ready, we can now move to the DR setup part.


DR Configuration

Below we have a similar PXC setup as having in DC in a separate Node/ K8s Cluster.

kubectl get pods -n pxc-dr
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          35h
cluster1-haproxy-1                                 2/2     Running     0          35h
cluster1-haproxy-2                                 2/2     Running     0          35h
cluster1-pxc-0                                     3/3     Running     0          35h
cluster1-pxc-1                                     3/3     Running     0          35h
cluster1-pxc-2                                     3/3     Running     0          35h
percona-xtradb-cluster-operator-6756dbf588-2wc5m   1/1     Running     0          38h
prepare-job-restore1-cluster1-8h4vn                0/1     Completed   0          35h
restore-job-restore1-cluster1-trfg6                0/1     Completed   0          35h
xb-cron-cluster1-fs-pvc-2026480025-372f8-wv6bt     0/1     Completed   0          28h
xb-cron-cluster1-fs-pvc-2026490025-372f8-gxd59     0/1     Completed   0          4h48m

First, we need to restore the backup on the DR server.

Data Restoration

  • Here we will create the [backup-secret-s3.yaml] file which contains the GCP/S3 credentials.
apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

…

shell> kubectl apply -f backup-secret-s3.yaml

  • Next, we will create a [restore.yaml] file while mentioning the backup source and other useful information.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterRestore
metadata:
  name: restore1
#  annotations:
#    percona.com/headless-service: "true"
spec:
  pxcCluster: cluster1
  backupSource:
#    verifyTLS: true
    destination: s3://<bucket>/cluster1-2026-04-07-15:55:46-full
    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      endpointUrl: https://storage.googleapis.com/

…

shell> kubectl apply -f restore.yaml

  • Once the restoration is finished successfully, we will see the status below.
shell> kubectl get pxc-restore
NAME       CLUSTER    STATUS      COMPLETED   AGE
restore1   cluster1   Succeeded               27m

Now we can do the remaining DR changes in the custom resource file [cr.yaml]. Basically, we need to add the replication channel and all source EXTERNAL-IPs. This cross-DC replication supports Automatic Asynchronous Replication Connection Failover feature, so in case any of the DC node is down, the Replica can connect and resume from other available DC nodes.

replicationChannels:
    - name: pxc1_to_pxc2
      isSource: false
      sourcesList:
      - host: 34.29.145.138  
        port: 3306
        weight: 100

      - host: 34.30.233.0
        port: 3306
        weight: 100

      - host: 35.225.0.19
        port: 3306
        weight: 100

…

shell> kubectl apply -f cr.yaml

For backup and restoration on the PXC operator, the manuals below can be referenced further.


Replication

Initially, when we check the replication status, we can notice the following error. This is because with [caching_sha2_password] authentication, it should be a secure SSL/TLS communication, or else we can use SOURCE_PUBLIC_KEY_PATH/GET_SOURCE_PUBLIC_KEY  which basicaly enables the RSA key pair-based password exchange by requesting the public key from the source. 

shell> kubectl exec -it cluster1-pxc-0  -- sh
shell> mysql -uroot -p

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Connecting to source
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: 
          Read_Source_Log_Pos: 4
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 4
        Relay_Source_Log_File: 
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
...

Error:

Last_IO_Error: Error connecting to source 'replication@35.225.0.19:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Access denied for user 'replication'@'35.225.0.19.' (using password: YES)

Once we passed “GET_SOURCE_PUBLIC_KEY” in the “CHANGE REPLICATION” command the  error is resolved and DR successfully able to communicate with the DC.

mysql> STOP REPLICA;
mysql> STOP REPLICA IO_THREAD FOR CHANNEL 'pxc1_to_pxc2';
mysql> CHANGE REPLICATION SOURCE TO SOURCE_USER='replication', SOURCE_PASSWORD='password', GET_SOURCE_PUBLIC_KEY=1 FOR CHANNEL 'pxc1_to_pxc2';
mysql> START REPLICA;

Note  – The Replication user will be auto-created on the DC node. So, with the help of below command we can get the decoded password for “replication” user.

shell> kubectl get secret cluster1-secrets -o jsonpath="{.data.replication}" | base64 --decode

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000006
          Read_Source_Log_Pos: 3047027
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 150132
        Relay_Source_Log_File: binlog.000006
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

The other PXC DR nodes will sync as usual with the Galera Synchronous replication process. 

Source Failover

The asynchronous connection failover is already enabled on the DR as we defined initially in the custom resource file. The “External IPs”  shows different here because they changed in this testing scenario.

mysql> select * from performance_schema.replication_asynchronous_connection_failover;
+--------------+---------------+------+-------------------+--------+--------------+
| CHANNEL_NAME | HOST          | PORT | NETWORK_NAMESPACE | WEIGHT | MANAGED_NAME |
+--------------+---------------+------+-------------------+--------+--------------+
| pxc1_to_pxc2 | 34.29.145.138 | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.45.151.96  | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.71.57.38   | 3306 |                   |    100 |              |
+--------------+---------------+------+-------------------+--------+--------------+
3 rows in set (0.00 sec)

Now, in case the existing Source DC[cluster1-pxc-2] is down, the DR will connect to one of the other available DC nodes based on the “Weight” and chronological order [pxc-2, pxc-1, pxc-0 etc].

  • Here, we temporarily take down the Source DC[cluster1-pxc-2] node.
kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS     AGE
cluster1-haproxy-0                                 2/2     Running     0            2d3h
cluster1-haproxy-1                                 2/2     Running     0            2d3h
cluster1-haproxy-2                                 2/2     Running     0            2d3h
cluster1-pxc-0                                     3/3     Running     0            2d3h
cluster1-pxc-1                                     3/3     Running     0            35h
cluster1-pxc-2                                     2/3     Running     1 (6s ago)   34h
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0            2d3h
xb-backup1-hlz2p                                   0/1     Completed   0            2d1h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0            41h
xb-cron-cluster1-fs-pvc-2026490026-372f8-mgfpv     0/1     Completed   0            17h

  • The DR replication breaks as it can’t reach the DC [cluster1-pxc-2].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Reconnecting after a failed source event read
                  Source_Host: 34.71.57.38
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000012
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000002
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000012
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
              Replicate_Do_DB: 
          Replicate_Ignore_DB: 
           Replicate_Do_Table: 
       Replicate_Ignore_Table: 
      Replicate_Wild_Do_Table: 
  Replicate_Wild_Ignore_Table: 
                   Last_Errno: 0
                   Last_Error: 
                 Skip_Counter: 0
          Exec_Source_Log_Pos: 198
              Relay_Log_Space: 602
              Until_Condition: None
               Until_Log_File: 
                Until_Log_Pos: 0
           Source_SSL_Allowed: No
           Source_SSL_CA_File: 
           Source_SSL_CA_Path: 
              Source_SSL_Cert: 
            Source_SSL_Cipher: 
               Source_SSL_Key: 
        Seconds_Behind_Source: NULL
Source_SSL_Verify_Server_Cert: Yes
                Last_IO_Errno: 2003
                Last_IO_Error: Error reconnecting to source 'replication@34.71.57.38:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Can't connect to MySQL server on '34.71.57.38:3306' (111)

  • Once it reaches the “source_retry_count” and “source_connect_retry”, the Replica connects to another Source DC[cluster1-pxc-1].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 34.45.151.96
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000007
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000003
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000007
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

Quick Summary

In this blog post, we walk through the steps to configure Cross-Site Replication in the Percona PXC operator. Although we have used the operator native Xtrabackup to feed the data to the DR via the restore process, we can also use logical backup options like (mysqldump, mydumper, etc.) to accomplish the same goals. 

Using an “Asynchronous Replication” process to sync DR could lead to delays or replication lag due to its flow, or, more importantly, when working across data centres, where network latency is a big factor. However, adding a DR(PXC) cluster to DC(PXC) directly via synchronous replication could be more impactful or lead to flow control issues if any of the DR nodes struggle or experience performance/saturation issues. So, it’s equally important to consider all aspects or challenges before deploying in production.

The post Deploying Cross-Site Replication in Percona Operator for MySQL (PXC) appeared first on Percona.

Jan
27
2026
--

Automatic “Multi-Source” Async Replication Failover Using PXC Replication Manager

Automatic "Multi-Source" Async Replication Failover Using PXC Replication ManagerThe replication  manager script can be particularly useful in complex PXC/Galera topologies that require Async/Multi-source replication. This will ease the auto source and replica failover to ensure all replication channels are healthy and in sync. If certain nodes shouldn’t  be part of a async/multi-source replication, we can disable the replication manager script there to tightly controlled the flow. Alternatively, node participation can be controlled by adjusting the weights in the percona.weight table, allowing replication behavior to be managed more precisely.

Dec
09
2025
--

How to Turn a MySQL Unique Key Into a Primary Key

A unique constraint specifies, one or more columns as unique it identifies. It is satisfied only when no two rows store the same non-null values at its core. A primary key constraint is a unique one that will say PRIMARY KEY in its defined way. It is satisfied only when rows unfold, and none may […]
Nov
14
2025
--

A Tale of Two Databases: No-Op Updates in PostgreSQL and MySQL

No-Op Updates in PostgreSQL and MySQLI’m lazy when I’m speakin’ I’m lazy when I walk I’m lazy when I’m dancin’ I’m lazy when I talk   X-Press 2 Feat. David Byrne – Lazy While preparing a blog post to compare how PostgreSQL and MySQL handle locks, as part of a series covering the different approaches to MVCC for these databases, […]
Nov
05
2025
--

Surprise with innodb_doublewrite_pages in MySQL 8.0.20+

innodb_doublewrite_pages in MySQL 8.0.20+In a recent post, The Quirks of Index Maintenance in Open Source Databases, I compared the IO load generated by open source databases while inserting rows in a table with many secondary indexes. Because of its change buffer, InnoDB was the most efficient solution. However, that’s not the end of the story. Evolution of the […]
Sep
17
2025
--

MySQL with Diagrams Part Three: The Life Story of the Writing Process

How MySQL writes workWhen you run a simple write, …it may look simple, but under the hood, MySQL’s InnoDB engine kicks off a pretty complex sequence to ensure your data stays safe, consistent, and crash-recoverable. In the top-left corner of the diagram, we see exactly where this begins — the moment the query is executed: [crayon-68cb7b0282a22221090106/] The log […]

May
29
2025
--

How to Safely Upgrade InnoDB Cluster From MySQL 8.0 to 8.4

Upgrade InnoDB ClusterIn this blog, we continue from where we left off in the previous post, InnoDB Cluster Setup: Building a 3-Node High Availability Architecture, where we demonstrated how to set up a MySQL InnoDB Cluster with three nodes to achieve high availability. Here, we walk through the step-by-step process of performing a rolling upgrade of that […]

May
20
2025
--

InnoDB Cluster: Set Up Router and Validate Failover

InnoDB Cluster: Set Up Router and Validate FailoverSetting up an InnoDB Cluster requires three key components: Group Replication, MySQL Shell, and MySQL Router. In the previous post, we covered the process of building a 3-node InnoDB Cluster. In this post, we shift our focus to configuring MySQL Router and validating failover functionality. Environment overview We are using three InnoDB Cluster nodes along […]

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com