May
24
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method

A Crunchy to Percona PostgreSQL migration is more straightforward than most cross-operator moves on Kubernetes, because the Percona PostgreSQL Operator is a hard fork of the Crunchy Data PostgreSQL Operator. Same Patroni HA, same pgBackRest backups, same overall CRD shape. This post walks through the safest of the three migration paths: a standby cluster method with near-zero downtime.

This is part 2 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0.

This post is the first practical playbook of the series. It covers the standby cluster method, the safest migration path when the downtime budget is tight. Part 3 will cover two simpler paths: backup-and-restore and persistent-volume reuse.

If you are landing here without context on why you might want to migrate at all, start with part 1. The rest of this post assumes you have already decided to move and want a tested playbook.


Migration approach in one paragraph

The Percona PostgreSQL Kubernetes Operator is a hard fork of the Crunchy Data PostgreSQL Kubernetes Operator, which simplifies the migration paths considerably: the same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both operators. All three migration paths in this series are reversible: because Percona’s operator is fully open source and remains compatible with the same backup format, the move back to Crunchy is also possible if your team decides to walk it


A note on the storage layer

All examples in this guide use an in-cluster SeaweedFS instance as the pgBackRest S3 repository. SeaweedFS is Apache-2.0 licensed, actively maintained, and a clean drop-in replacement for the role MinIO used to fill in this stack. Any other S3-compatible storage works just as well: AWS S3, Google Cloud Storage (via HMAC keys), Ceph RadosGW, Cloudflare R2, and so on. For non-SeaweedFS endpoints, remove repo1-s3-uri-style: path and repo1-s3-verify-tls: “n” from the pgBackRest configuration and replace the endpoint with your provider’s URL.


What this series does NOT cover

To keep scope honest:

  • Application-side connection-string changes beyond updating to the new pgBouncer service. If your app uses connection-pool tuning, custom auth, or a service mesh, that work stays with you.
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations. The PostgreSQL major version must match between the source and the target.
  • Crunchy enterprise-only features like TDE, Crunchy Postgres for Kubernetes-specific operators, or pgBackRest custom encryption. If your environment uses these, contact the Percona team for a tailored plan.
  • Operating two operators against the same namespace before the PGO hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any other S3-compatible service accessible from all cluster pods
Tools kubectl, helm (v3), yq

Different versions may differ slightly in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


Migration using a standby cluster

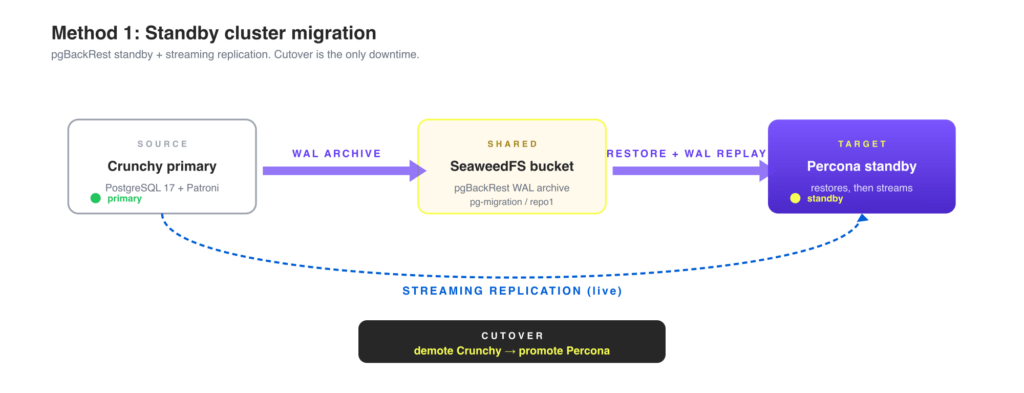
This is the safest method when the downtime budget is tight. The Percona cluster is brought up as a standby of the Crunchy primary, catches up via pgBackRest plus streaming replication, and is promoted at cutover. The only downtime is the cutover step itself.

You can wire the standby in two ways, and combining both gives you maximum safety:

  • pgBackRest repo-based standby seeds the standby from the latest base backup and replays archived WAL
  • Streaming replication keeps the standby in sync with the live primary


Overview


Before you begin

Set the target namespace once. Every command in this guide reads from this variable, so you can change it in a single place:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: “n” is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.


Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secret.yaml after filling in your access key and secret key:

# Copy and edit the file first to set your credentials.

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/01-pgbackrest-secret.yaml

Both secrets contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket and path. The repo1-path value must be identical in both cluster specs. Mismatched paths will prevent the Percona standby from finding the WAL archive.

The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Optional: deploy a Crunchy operator to test the migration end to end:

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait


Apply
examples/02-crunchy-source-cluster.yaml (or adapt your existing cluster’s pgBackRest config):

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/02-crunchy-source-cluster.yaml


The key pgBackRest settings in the example:

global:
  repo1-path: /crunchy-to-percona/repo1   # shared path, must match Percona side
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1


Wait for the cluster to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  --namespace $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s


Step 2. Trigger a full backup on the Crunchy cluster

Wait for the pgBackRest stanza to be created:

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Take a full backup before creating the Percona standby. This gives the standby a recent base to restore from, so it only needs to replay a small amount of WAL to catch up. This matches the realistic production migration pattern.

kubectl annotate postgrescluster crunchy-source \
  --namespace $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"


Wait for the backup job to complete:

kubectl wait job \
  -l postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Copy TLS certificates (cross-namespace only)

If the Percona cluster is in a different namespace from the Crunchy cluster, copy the Crunchy TLS secrets to the Percona namespace. These allow mutual TLS authentication during streaming replication:

for secret in crunchy-source-cluster-cert crunchy-source-replication-cert; do
  kubectl get secret "${secret}" -n <CRUNCHY_NS> -o json | \
    yq '{"apiVersion": .apiVersion, "kind": .kind, "data": .data,
         "metadata": {"name": .metadata.name}, "type": .type}' -o yaml | \
    kubectl -n $MIGRATION_NS apply -f -
done

If both clusters are in the same namespace, skip this step. The secrets are already accessible.


Step 4. Deploy the Percona PG Operator

The Crunchy PGO operator can stay in the same or a different namespace.

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

Wait until the operator deployment is ready:

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s


Step 5. Create the Percona cluster in standby mode

Note: The kubectl apply below pulls the CR manifest from the migration-from-crunchy-guide branch of the operator repo, which is the source for this guide’s examples. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation and pin to a released version tag rather than a feature branch.

Apply examples/03-percona-standby-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/03-percona-standby-cluster.yaml

The key settings that wire the Percona cluster to the Crunchy source:

standby:
  enabled: true
  repoName: repo1                             # restore initial base backup from this repo
  host: crunchy-source-ha.postgres-migration.svc.cluster.local
  port: 5432

secrets:
  customTLSSecret:
    name: crunchy-source-cluster-cert         # Crunchy CA for mutual TLS
  customReplicationTLSSecret:
    name: crunchy-source-replication-cert     # cert for _crunchyreplication user

The Percona operator will:

  1. Restore the base backup from the SeaweedFS bucket.
  2. Replay WAL from SeaweedFS until it catches up with the live Crunchy cluster.
  3. Switch to streaming replication from crunchy-source-ha.

Wait for the cluster to reach the ready state:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify that data is replicating to the standby:

STANDBY_POD=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/data=postgres \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery(), pg_last_wal_replay_lsn();"

Expected output: t (in recovery) and a non-null LSN.


Step 6. Verify replication lag before cutover

Query the Crunchy primary to confirm the Percona standby has caught up:

CRUNCHY_PRIMARY=$(kubectl get pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -c "
    SELECT
        client_addr,
        state,
        pg_wal_lsn_diff(sent_lsn, replay_lsn) AS byte_lag,
        write_lag,
        flush_lag,
        replay_lag
    FROM pg_stat_replication;
  "

Proceed to the next step only when write_lag and replay_lag are NULL or under a few seconds.


Step 7. Cutover the Crunchy cluster

This is the only step that causes downtime. Stop accepting writes on the application side, then patch the Crunchy cluster into standby mode. Patroni steps down and archives the final WAL.

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": true, "repoName": "repo1"}}}'

Verify demotion (poll until pg_is_in_recovery() returns t):

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"


Step 8. (Optional) Shut down the Crunchy cluster

Once the Percona standby has replayed all WAL, shut down the Crunchy cluster to prevent split-brain:

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"shutdown": true}}'

kubectl wait pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=delete \
  --timeout=120s || true


Step 9. Promote the Percona cluster

Confirm that the Percona standby has finished replaying all WAL (the LSN stops advancing):

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_last_wal_replay_lsn();"

Run this a few times. When the LSN is stable, replay is complete.

kubectl patch perconapgcluster percona-standby \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": false}}}'

Wait for the cluster to become ready and confirm it is writable:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=480s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f (the cluster is now the primary and accepts writes).


Step 10. Verify stanza creation

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 11. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery point on the new timeline. All future PITR restores will use this backup as their starting point, independent of the old Crunchy WAL archive.


Reconnecting your application

Update your application’s connection string to point at the Percona cluster’s pgBouncer service:

kubectl get service -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=pgbouncer

This migration path works almost entirely out of the box. For users coming from the Crunchy Data PostgreSQL Operator, this method feels familiar because it leverages the same standby/replica mechanisms used for HA and disaster recovery. The key difference is that you can now use this familiar mechanism to migrate safely to the Percona PostgreSQL Operator, a fully open-source alternative running on a fully open-source storage layer.


Rollback

The standby method is the most rollback-friendly of the three. Until you take the post-migration backup, the Crunchy cluster still holds the original timeline. To roll back:

  1. Stop writes on the Percona side and patch the Percona cluster back into standby mode (spec.standby.enabled: true).
  2. Patch the Crunchy cluster out of standby mode and let Patroni promote it.
  3. Verify with pg_is_in_recovery() on both sides.
  4. Switch the application connection string back to the Crunchy pgBouncer service.

After Step 11 (post-migration backup), the timelines have diverged. From that point, the rollback story is the same as a fresh restore, and you should treat the Crunchy cluster as a historical reference, not a live target.


Troubleshooting

Percona standby not connecting to the Crunchy primary. Verify the crunchy-source-ha service resolves from within the Percona pod:

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  bash -c "getent hosts crunchy-source-ha.${MIGRATION_NS}.svc.cluster.local"

Replication authentication errors. The Percona standby authenticates as the _crunchyreplication PostgreSQL user using the certificate in crunchy-source-replication-cert. Verify the secret exists and matches what the Crunchy operator generated:

kubectl get secret crunchy-source-replication-cert -n $MIGRATION_NS

pgBackRest restore fails. Confirm both secrets contain identical credentials and that repo1-path is the same in both cluster specs (/crunchy-to-percona/repo1 in this guide). Mismatched paths cause an archive.info missing error. Verify the bucket is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "

Timeline history file (00000002.history) missing after promotion. This is a known issue with Crunchy PGO’s async archive mode. After promotion, push the history file synchronously:

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  bash -c "
    pgbackrest --stanza=db --no-archive-async \
      archive-push \"\${PGDATA}/pg_wal/00000002.history\" || true
  "


What’s next

This was the safest migration path. Part 3 will cover two simpler options:

  • Backup and restore. The simplest path. You take a Crunchy pgBackRest backup and the Percona cluster bootstraps from it. Cutover is the time between the final backup and pointing the application at the new cluster.
  • Persistent volume reuse. For when you want to skip the data copy entirely. The Percona cluster takes over the existing PGDATA volume, no restore step required.

Pick the method that fits your downtime budget, data size, and storage layout.

This post covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method appeared first on Percona.
May
24
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method

A Crunchy to Percona PostgreSQL migration is more straightforward than most cross-operator moves on Kubernetes, because the Percona PostgreSQL Operator is a hard fork of the Crunchy Data PostgreSQL Operator. Same Patroni HA, same pgBackRest backups, same overall CRD shape. This post walks through the safest of the three migration paths: a standby cluster method with near-zero downtime.

This is part 2 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0.

This post is the first practical playbook of the series. It covers the standby cluster method, the safest migration path when the downtime budget is tight. Part 3 will cover two simpler paths: backup-and-restore and persistent-volume reuse.

If you are landing here without context on why you might want to migrate at all, start with part 1. The rest of this post assumes you have already decided to move and want a tested playbook.


Migration approach in one paragraph

The Percona PostgreSQL Kubernetes Operator is a hard fork of the Crunchy Data PostgreSQL Kubernetes Operator, which simplifies the migration paths considerably: the same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both operators. All three migration paths in this series are reversible: because Percona’s operator is fully open source and remains compatible with the same backup format, the move back to Crunchy is also possible if your team decides to walk it


A note on the storage layer

All examples in this guide use an in-cluster SeaweedFS instance as the pgBackRest S3 repository. SeaweedFS is Apache-2.0 licensed, actively maintained, and a clean drop-in replacement for the role MinIO used to fill in this stack. Any other S3-compatible storage works just as well: AWS S3, Google Cloud Storage (via HMAC keys), Ceph RadosGW, Cloudflare R2, and so on. For non-SeaweedFS endpoints, remove repo1-s3-uri-style: path and repo1-s3-verify-tls: “n” from the pgBackRest configuration and replace the endpoint with your provider’s URL.


What this series does NOT cover

To keep scope honest:

  • Application-side connection-string changes beyond updating to the new pgBouncer service. If your app uses connection-pool tuning, custom auth, or a service mesh, that work stays with you.
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations. The PostgreSQL major version must match between the source and the target.
  • Crunchy enterprise-only features like TDE, Crunchy Postgres for Kubernetes-specific operators, or pgBackRest custom encryption. If your environment uses these, contact the Percona team for a tailored plan.
  • Operating two operators against the same namespace before the PGO hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any other S3-compatible service accessible from all cluster pods
Tools kubectl, helm (v3), yq

Different versions may differ slightly in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


Migration using a standby cluster

This is the safest method when the downtime budget is tight. The Percona cluster is brought up as a standby of the Crunchy primary, catches up via pgBackRest plus streaming replication, and is promoted at cutover. The only downtime is the cutover step itself.

You can wire the standby in two ways, and combining both gives you maximum safety:

  • pgBackRest repo-based standby seeds the standby from the latest base backup and replays archived WAL
  • Streaming replication keeps the standby in sync with the live primary


Overview


Before you begin

Set the target namespace once. Every command in this guide reads from this variable, so you can change it in a single place:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: “n” is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.


Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secret.yaml after filling in your access key and secret key:

# Copy and edit the file first to set your credentials.

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/01-pgbackrest-secret.yaml

Both secrets contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket and path. The repo1-path value must be identical in both cluster specs. Mismatched paths will prevent the Percona standby from finding the WAL archive.

The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Optional: deploy a Crunchy operator to test the migration end to end:

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait


Apply
examples/02-crunchy-source-cluster.yaml (or adapt your existing cluster’s pgBackRest config):

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/02-crunchy-source-cluster.yaml


The key pgBackRest settings in the example:

global:
  repo1-path: /crunchy-to-percona/repo1   # shared path, must match Percona side
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1


Wait for the cluster to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  --namespace $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s


Step 2. Trigger a full backup on the Crunchy cluster

Wait for the pgBackRest stanza to be created:

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Take a full backup before creating the Percona standby. This gives the standby a recent base to restore from, so it only needs to replay a small amount of WAL to catch up. This matches the realistic production migration pattern.

kubectl annotate postgrescluster crunchy-source \
  --namespace $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"


Wait for the backup job to complete:

kubectl wait job \
  -l postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Copy TLS certificates (cross-namespace only)

If the Percona cluster is in a different namespace from the Crunchy cluster, copy the Crunchy TLS secrets to the Percona namespace. These allow mutual TLS authentication during streaming replication:

for secret in crunchy-source-cluster-cert crunchy-source-replication-cert; do
  kubectl get secret "${secret}" -n <CRUNCHY_NS> -o json | \
    yq '{"apiVersion": .apiVersion, "kind": .kind, "data": .data,
         "metadata": {"name": .metadata.name}, "type": .type}' -o yaml | \
    kubectl -n $MIGRATION_NS apply -f -
done

If both clusters are in the same namespace, skip this step. The secrets are already accessible.


Step 4. Deploy the Percona PG Operator

The Crunchy PGO operator can stay in the same or a different namespace.

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

Wait until the operator deployment is ready:

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s


Step 5. Create the Percona cluster in standby mode

Note: The kubectl apply below pulls the CR manifest from the migration-from-crunchy-guide branch of the operator repo, which is the source for this guide’s examples. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation and pin to a released version tag rather than a feature branch.

Apply examples/03-percona-standby-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/03-percona-standby-cluster.yaml

The key settings that wire the Percona cluster to the Crunchy source:

standby:
  enabled: true
  repoName: repo1                             # restore initial base backup from this repo
  host: crunchy-source-ha.postgres-migration.svc.cluster.local
  port: 5432

secrets:
  customTLSSecret:
    name: crunchy-source-cluster-cert         # Crunchy CA for mutual TLS
  customReplicationTLSSecret:
    name: crunchy-source-replication-cert     # cert for _crunchyreplication user

The Percona operator will:

  1. Restore the base backup from the SeaweedFS bucket.
  2. Replay WAL from SeaweedFS until it catches up with the live Crunchy cluster.
  3. Switch to streaming replication from crunchy-source-ha.

Wait for the cluster to reach the ready state:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify that data is replicating to the standby:

STANDBY_POD=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/data=postgres \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery(), pg_last_wal_replay_lsn();"

Expected output: t (in recovery) and a non-null LSN.


Step 6. Verify replication lag before cutover

Query the Crunchy primary to confirm the Percona standby has caught up:

CRUNCHY_PRIMARY=$(kubectl get pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -c "
    SELECT
        client_addr,
        state,
        pg_wal_lsn_diff(sent_lsn, replay_lsn) AS byte_lag,
        write_lag,
        flush_lag,
        replay_lag
    FROM pg_stat_replication;
  "

Proceed to the next step only when write_lag and replay_lag are NULL or under a few seconds.


Step 7. Cutover the Crunchy cluster

This is the only step that causes downtime. Stop accepting writes on the application side, then patch the Crunchy cluster into standby mode. Patroni steps down and archives the final WAL.

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": true, "repoName": "repo1"}}}'

Verify demotion (poll until pg_is_in_recovery() returns t):

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"


Step 8. (Optional) Shut down the Crunchy cluster

Once the Percona standby has replayed all WAL, shut down the Crunchy cluster to prevent split-brain:

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"shutdown": true}}'

kubectl wait pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=delete \
  --timeout=120s || true


Step 9. Promote the Percona cluster

Confirm that the Percona standby has finished replaying all WAL (the LSN stops advancing):

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_last_wal_replay_lsn();"

Run this a few times. When the LSN is stable, replay is complete.

kubectl patch perconapgcluster percona-standby \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": false}}}'

Wait for the cluster to become ready and confirm it is writable:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=480s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f (the cluster is now the primary and accepts writes).


Step 10. Verify stanza creation

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 11. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery point on the new timeline. All future PITR restores will use this backup as their starting point, independent of the old Crunchy WAL archive.


Reconnecting your application

Update your application’s connection string to point at the Percona cluster’s pgBouncer service:

kubectl get service -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=pgbouncer

This migration path works almost entirely out of the box. For users coming from the Crunchy Data PostgreSQL Operator, this method feels familiar because it leverages the same standby/replica mechanisms used for HA and disaster recovery. The key difference is that you can now use this familiar mechanism to migrate safely to the Percona PostgreSQL Operator, a fully open-source alternative running on a fully open-source storage layer.


Rollback

The standby method is the most rollback-friendly of the three. Until you take the post-migration backup, the Crunchy cluster still holds the original timeline. To roll back:

  1. Stop writes on the Percona side and patch the Percona cluster back into standby mode (spec.standby.enabled: true).
  2. Patch the Crunchy cluster out of standby mode and let Patroni promote it.
  3. Verify with pg_is_in_recovery() on both sides.
  4. Switch the application connection string back to the Crunchy pgBouncer service.

After Step 11 (post-migration backup), the timelines have diverged. From that point, the rollback story is the same as a fresh restore, and you should treat the Crunchy cluster as a historical reference, not a live target.


Troubleshooting

Percona standby not connecting to the Crunchy primary. Verify the crunchy-source-ha service resolves from within the Percona pod:

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  bash -c "getent hosts crunchy-source-ha.${MIGRATION_NS}.svc.cluster.local"

Replication authentication errors. The Percona standby authenticates as the _crunchyreplication PostgreSQL user using the certificate in crunchy-source-replication-cert. Verify the secret exists and matches what the Crunchy operator generated:

kubectl get secret crunchy-source-replication-cert -n $MIGRATION_NS

pgBackRest restore fails. Confirm both secrets contain identical credentials and that repo1-path is the same in both cluster specs (/crunchy-to-percona/repo1 in this guide). Mismatched paths cause an archive.info missing error. Verify the bucket is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "

Timeline history file (00000002.history) missing after promotion. This is a known issue with Crunchy PGO’s async archive mode. After promotion, push the history file synchronously:

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  bash -c "
    pgbackrest --stanza=db --no-archive-async \
      archive-push \"\${PGDATA}/pg_wal/00000002.history\" || true
  "


What’s next

This was the safest migration path. Part 3 will cover two simpler options:

  • Backup and restore. The simplest path. You take a Crunchy pgBackRest backup and the Percona cluster bootstraps from it. Cutover is the time between the final backup and pointing the application at the new cluster.
  • Persistent volume reuse. For when you want to skip the data copy entirely. The Percona cluster takes over the existing PGDATA volume, no restore step required.

Pick the method that fits your downtime budget, data size, and storage layout.

This post covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method appeared first on Percona.

Apr
30
2026
--

Managing Valkey Cluster in Kubernetes

Over the last several years, Percona has introduced several rock-star Kubernetes Operators for managing MySQL, Percona XtraDB Cluster, MongoDB, and PostgreSQL. For Valkey, we are actively working with the community to contribute our knowledge, and experience to help brainstorm, develop, and test the official Valkey Operator for Kubernetes.

While the Valkey Operator has not yet released a GA 1.0 version, we wanted to take this opportunity to highlight some recently added features.

Cluster Configuration

Up until recently, there was no native ability to provide configuration parameters to the Valkey server process running inside each deployed pod. This hurdle is now overcome, and you can supply configuration natively within the deployment CR.

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-valkey-cluster1
spec:
  shards: 3
  replicas: 1
  config:
    maxmemory: 500mb
    maxmemory-policy: allkeys-lfu
    maxclients: 5000
    commandlog-execution-slower-than: 10000

For now, these parameters are set on initial cluster deployment. There is already traction underway to allow certain parameters to be dynamically set at runtime. There are a small handful of certain cluster-based parameters that cannot be overridden by the user, otherwise it would break operator functionality.

User Access Control List (ACL)

Managing users is always a tedious task for any database administrator. Creating ACLs for users in Valkey can be a bit confusing coming from a traditional RDBMS using GRANT syntax. To make things just a bit easier, Valkey Operator has added user permissions management to the deployment CR.

Firstly, create your Secret containing usernames, and passwords:

apiVersion: v1
kind: Secret
metadata:
  name: valkey-cluster-sample-users
data:
  alicepw: M21wdHlQQHNzdzByZA==
  davidold: OVYqTHQlYXU4Mk5tdTlyeQ==
  davidnew: VmFsa2V5I1J1bHojMjIzMw==

Next, deploy your cluster with users:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-cool-valkey-cluster
spec:
  shards: 3
  replicas: 1
  users:
    - name: alice
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys: [alicepw]
      commands:
        allow: ["@read", "@write", "@connection"]
        deny: ["@admin", "@dangerous"]
      keys:
        readWrite: ["app:*", "cache:*"]
        readOnly: ["shared:*", "config:*"]
        writeOnly: ["logs:*", "metrics:*"]
    - name: david
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys:
          - davidold
          - davidnew
      commands:
        allow: ["@admin"]

There’s quite a lot going on here. Let’s break it down by first looking at the user ‘alice’: 

The ‘alice’ user is enabled, with a password found in the referenced Secret and secret key. Next, we can see what commands, or in this case, command groups (Noted with ‘@’) that alice is allowed to execute, and which commands/groups are denied. Lastly, permissions on specific key patterns are identified for maximum security restrictions.

The other user, ‘david’, can access all of the admin-group commands, and cannot read or write to any keys. Note that david’s secret key reference is an array, which means you can provide multiple passwords per user; great for password rotation! Once david confirms the new password, the old password references can be removed from the CR and Secret, and the Valkey Operator will synchronize the ACLs.

Users are dynamic, which means they can be added, removed, and modified without restarting the cluster.

TLS Support

Bring on the encryption! TLS support was also recently added to the Valkey Operator. Create your Secret with the CA, TLS Key, and Cert files, and tell the CR where to find them:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: cluster-sample
spec:
  shards: 3
  replicas: 1
  tls:
    certificate:
      secretName: my-valkey-tls-secret

Once deployed, the Valkey operator will mount the referenced secret to each pod, and add all the proper configuration parameters. By doing so, the operator enforces SSL/TLS communication between each Valkey cluster node, securing node-to-node, and replication traffic within your kubernetes network. Additionally, by creating user certificates signed by the same CA, traffic between your clients, and the Valkey clusters nodes is secured. This configuration is BYOC (bring-your-own-certificate), which works well with the popular CertManager, or other certificate authority you may be using.

On The Horizon

As a teaser, here are a couple other features coming soon to Valkey Operator:

  • Data Persistence: The ability to enable background snapshots of the in-memory dataset for backup, and recovery. Additionally, supporting the AOF (append-only file) for streaming changes.
  • Simple Replication: The operator currently only supports Valkey in cluster mode. Be on the lookout for traditional primary -> N-replica configurations, along with Sentinel monitoring.

Join Us

Want to contribute to the Valkey Operator? Join any of the discussions/issues on our github, or come introduce yourself in the Valkey Slack community.

The post Managing Valkey Cluster in Kubernetes appeared first on Percona.

Apr
20
2026
--

Deploying Cross-Site Replication in Percona Operator for MySQL (PXC)

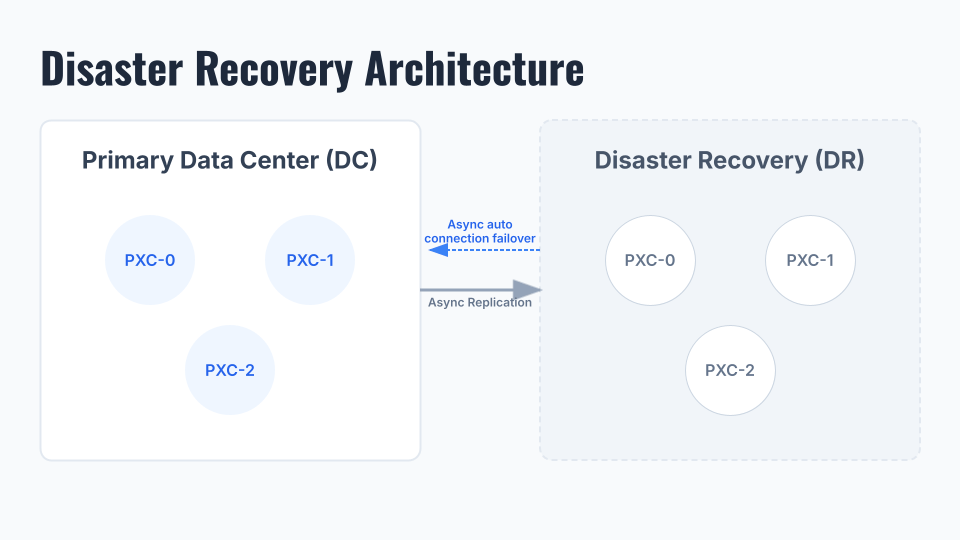
Having a separate DR cluster for production databases is a modern day requirement or necessity for tech and other related businesses that rely heavily on their database systems. Setting up such a [DC -> DR] topology for Percona XtraDB Cluster (PXC), which is a virtually- synchronous cluster, can be a bit challenging in a complex Kubernetes environment.

Here, Percona Operator for MySQL comes in handy, with a minimal number of steps to configure such a topology, which ensures a remote side backup or a disaster recovery solution.

So without taking much time, let’s see how the overall setup and configurations look from a practical standpoint.


PXC Cross-Site/Disaster Recovery


DC Configuration

1) Here we have a three-node PXC cluster running on the DC side.

shell> kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          23h
cluster1-haproxy-1                                 2/2     Running     0          23h
cluster1-haproxy-2                                 2/2     Running     0          23h
cluster1-pxc-0                                     3/3     Running     0          23h
cluster1-pxc-1                                     3/3     Running     0          7h37m
cluster1-pxc-2                                     3/3     Running     0          7h18m
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0          24h
xb-backup1-hlz2p                                   0/1     Completed   0          21h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0          13h

2) There are some configuration options which have to be enabled in a custom resource file[cr.yaml] to allow cross-site replication.

  • Expose all source PXC nodes so they can be communicated from outside or DR cluster.
expose:
      	enabled: true
      	Type: LoadBalancer

  • Define a dedicated replication channel and enable the source option.
replicationChannels:
    - name: pxc1_to_pxc2
      isSource: true

  • Finally, applying the custom resource changes.
shell> kubectl apply -f cr.yaml

3) Now we will notice some “EXTERNAL IP” details for each PXC node. This is the endpoint that DR node [cluster1-pxc-0] will use to connect to DC.

shell> kubectl get svc
NAME                              TYPE           CLUSTER-IP       EXTERNAL-IP     PORT(S)                                          AGE
cluster1-haproxy                  ClusterIP      34.118.227.249   <none>          3306/TCP,3309/TCP,33062/TCP,33060/TCP,8404/TCP   4h1m
cluster1-haproxy-replicas         ClusterIP      34.118.225.41    <none>          3306/TCP                                         4h1m
cluster1-pxc                      ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
cluster1-pxc-0                    LoadBalancer   34.118.234.140   34.29.145.138   3306:30425/TCP                                   4h1m
cluster1-pxc-1                    LoadBalancer   34.118.239.132   34.30.233.0     3306:31340/TCP                                   4h1m
cluster1-pxc-2                    LoadBalancer   34.118.236.64    35.225.0.19     3306:30642/TCP                                   4h1m
cluster1-pxc-unready              ClusterIP      None             <none>          3306/TCP,33062/TCP,33060/TCP                     4h1m
percona-xtradb-cluster-operator   ClusterIP      34.118.235.168   <none>          443/TCP                                          4h11m

At this point, we are done with the DC setup. Next, we will take a backup from Source which we later used to build the DR.


Backup

  • Defining access key/secrets to connect to the GCP/S3 bucket.
cat backup-secret-s3.yaml

apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

  • In the custom resource file [cr.yaml] , we also need to define the bucket , secret file and endpoint/region details.
backup:

 storages:
   s3-us-west:
      type: s3
      verifyTLS: true

    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      region: us-west-2
      endpointUrl: https://storage.googleapis.com

…

shell> kubectl apply -f cr.yaml

  • Finally, we can take the backup by creating a [backup.yaml] file with below details.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterBackup
metadata:
#  finalizers:
#    - percona.com/delete-backup
  name: backup1
spec:
  pxcCluster: cluster1
  storageName:  s3-us-west

…

shell> kubectl apply -f cr.yaml

  • We can verify the successful backup as follows.
kubectl get pxc-backup
NAME      CLUSTER    STORAGE      DESTINATION                                     STATUS      COMPLETED   AGE
backup1   cluster1   s3-us-west   s3://<bucket>/cluster1-2026-04-07-15:55:46-full   Succeeded   125m        127m

As the backup is also ready, we can now move to the DR setup part.


DR Configuration

Below we have a similar PXC setup as having in DC in a separate Node/ K8s Cluster.

kubectl get pods -n pxc-dr
NAME                                               READY   STATUS      RESTARTS   AGE
cluster1-haproxy-0                                 2/2     Running     0          35h
cluster1-haproxy-1                                 2/2     Running     0          35h
cluster1-haproxy-2                                 2/2     Running     0          35h
cluster1-pxc-0                                     3/3     Running     0          35h
cluster1-pxc-1                                     3/3     Running     0          35h
cluster1-pxc-2                                     3/3     Running     0          35h
percona-xtradb-cluster-operator-6756dbf588-2wc5m   1/1     Running     0          38h
prepare-job-restore1-cluster1-8h4vn                0/1     Completed   0          35h
restore-job-restore1-cluster1-trfg6                0/1     Completed   0          35h
xb-cron-cluster1-fs-pvc-2026480025-372f8-wv6bt     0/1     Completed   0          28h
xb-cron-cluster1-fs-pvc-2026490025-372f8-gxd59     0/1     Completed   0          4h48m

First, we need to restore the backup on the DR server.

Data Restoration

  • Here we will create the [backup-secret-s3.yaml] file which contains the GCP/S3 credentials.
apiVersion: v1
kind: Secret
metadata:
  name: my-cluster-name-backup-s3
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <KEY>
  AWS_SECRET_ACCESS_KEY: <SECRET>

…

shell> kubectl apply -f backup-secret-s3.yaml

  • Next, we will create a [restore.yaml] file while mentioning the backup source and other useful information.
apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBClusterRestore
metadata:
  name: restore1
#  annotations:
#    percona.com/headless-service: "true"
spec:
  pxcCluster: cluster1
  backupSource:
#    verifyTLS: true
    destination: s3://<bucket>/cluster1-2026-04-07-15:55:46-full
    s3:
      bucket: <bucket>
      credentialsSecret: my-cluster-name-backup-s3
      endpointUrl: https://storage.googleapis.com/

…

shell> kubectl apply -f restore.yaml

  • Once the restoration is finished successfully, we will see the status below.
shell> kubectl get pxc-restore
NAME       CLUSTER    STATUS      COMPLETED   AGE
restore1   cluster1   Succeeded               27m

Now we can do the remaining DR changes in the custom resource file [cr.yaml]. Basically, we need to add the replication channel and all source EXTERNAL-IPs. This cross-DC replication supports Automatic Asynchronous Replication Connection Failover feature, so in case any of the DC node is down, the Replica can connect and resume from other available DC nodes.

replicationChannels:
    - name: pxc1_to_pxc2
      isSource: false
      sourcesList:
      - host: 34.29.145.138  
        port: 3306
        weight: 100

      - host: 34.30.233.0
        port: 3306
        weight: 100

      - host: 35.225.0.19
        port: 3306
        weight: 100

…

shell> kubectl apply -f cr.yaml

For backup and restoration on the PXC operator, the manuals below can be referenced further.


Replication

Initially, when we check the replication status, we can notice the following error. This is because with [caching_sha2_password] authentication, it should be a secure SSL/TLS communication, or else we can use SOURCE_PUBLIC_KEY_PATH/GET_SOURCE_PUBLIC_KEY  which basicaly enables the RSA key pair-based password exchange by requesting the public key from the source. 

shell> kubectl exec -it cluster1-pxc-0  -- sh
shell> mysql -uroot -p

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Connecting to source
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: 
          Read_Source_Log_Pos: 4
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 4
        Relay_Source_Log_File: 
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
...

Error:

Last_IO_Error: Error connecting to source 'replication@35.225.0.19:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Access denied for user 'replication'@'35.225.0.19.' (using password: YES)

Once we passed “GET_SOURCE_PUBLIC_KEY” in the “CHANGE REPLICATION” command the  error is resolved and DR successfully able to communicate with the DC.

mysql> STOP REPLICA;
mysql> STOP REPLICA IO_THREAD FOR CHANNEL 'pxc1_to_pxc2';
mysql> CHANGE REPLICATION SOURCE TO SOURCE_USER='replication', SOURCE_PASSWORD='password', GET_SOURCE_PUBLIC_KEY=1 FOR CHANNEL 'pxc1_to_pxc2';
mysql> START REPLICA;

Note  – The Replication user will be auto-created on the DC node. So, with the help of below command we can get the decoded password for “replication” user.

shell> kubectl get secret cluster1-secrets -o jsonpath="{.data.replication}" | base64 --decode

mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 35.225.0.19
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000006
          Read_Source_Log_Pos: 3047027
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000001
                Relay_Log_Pos: 150132
        Relay_Source_Log_File: binlog.000006
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

The other PXC DR nodes will sync as usual with the Galera Synchronous replication process. 

Source Failover

The asynchronous connection failover is already enabled on the DR as we defined initially in the custom resource file. The “External IPs”  shows different here because they changed in this testing scenario.

mysql> select * from performance_schema.replication_asynchronous_connection_failover;
+--------------+---------------+------+-------------------+--------+--------------+
| CHANNEL_NAME | HOST          | PORT | NETWORK_NAMESPACE | WEIGHT | MANAGED_NAME |
+--------------+---------------+------+-------------------+--------+--------------+
| pxc1_to_pxc2 | 34.29.145.138 | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.45.151.96  | 3306 |                   |    100 |              |
| pxc1_to_pxc2 | 34.71.57.38   | 3306 |                   |    100 |              |
+--------------+---------------+------+-------------------+--------+--------------+
3 rows in set (0.00 sec)

Now, in case the existing Source DC[cluster1-pxc-2] is down, the DR will connect to one of the other available DC nodes based on the “Weight” and chronological order [pxc-2, pxc-1, pxc-0 etc].

  • Here, we temporarily take down the Source DC[cluster1-pxc-2] node.
kubectl get pods -n pxc
NAME                                               READY   STATUS      RESTARTS     AGE
cluster1-haproxy-0                                 2/2     Running     0            2d3h
cluster1-haproxy-1                                 2/2     Running     0            2d3h
cluster1-haproxy-2                                 2/2     Running     0            2d3h
cluster1-pxc-0                                     3/3     Running     0            2d3h
cluster1-pxc-1                                     3/3     Running     0            35h
cluster1-pxc-2                                     2/3     Running     1 (6s ago)   34h
percona-xtradb-cluster-operator-6756dbf588-vxjxt   1/1     Running     0            2d3h
xb-backup1-hlz2p                                   0/1     Completed   0            2d1h
xb-cron-cluster1-fs-pvc-2026480026-372f8-2gfhr     0/1     Completed   0            41h
xb-cron-cluster1-fs-pvc-2026490026-372f8-mgfpv     0/1     Completed   0            17h

  • The DR replication breaks as it can’t reach the DC [cluster1-pxc-2].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Reconnecting after a failed source event read
                  Source_Host: 34.71.57.38
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000012
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000002
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000012
           Replica_IO_Running: Connecting
          Replica_SQL_Running: Yes
              Replicate_Do_DB: 
          Replicate_Ignore_DB: 
           Replicate_Do_Table: 
       Replicate_Ignore_Table: 
      Replicate_Wild_Do_Table: 
  Replicate_Wild_Ignore_Table: 
                   Last_Errno: 0
                   Last_Error: 
                 Skip_Counter: 0
          Exec_Source_Log_Pos: 198
              Relay_Log_Space: 602
              Until_Condition: None
               Until_Log_File: 
                Until_Log_Pos: 0
           Source_SSL_Allowed: No
           Source_SSL_CA_File: 
           Source_SSL_CA_Path: 
              Source_SSL_Cert: 
            Source_SSL_Cipher: 
               Source_SSL_Key: 
        Seconds_Behind_Source: NULL
Source_SSL_Verify_Server_Cert: Yes
                Last_IO_Errno: 2003
                Last_IO_Error: Error reconnecting to source 'replication@34.71.57.38:3306'. This was attempt 2/3, with a delay of 60 seconds between attempts. Message: Can't connect to MySQL server on '34.71.57.38:3306' (111)

  • Once it reaches the “source_retry_count” and “source_connect_retry”, the Replica connects to another Source DC[cluster1-pxc-1].
mysql> show replica status\G;
*************************** 1. row ***************************
             Replica_IO_State: Waiting for source to send event
                  Source_Host: 34.45.151.96
                  Source_User: replication
                  Source_Port: 3306
                Connect_Retry: 60
              Source_Log_File: binlog.000007
          Read_Source_Log_Pos: 198
               Relay_Log_File: cluster1-pxc-0-relay-bin-pxc1_to_pxc2.000003
                Relay_Log_Pos: 369
        Relay_Source_Log_File: binlog.000007
           Replica_IO_Running: Yes
          Replica_SQL_Running: Yes
...

Quick Summary

In this blog post, we walk through the steps to configure Cross-Site Replication in the Percona PXC operator. Although we have used the operator native Xtrabackup to feed the data to the DR via the restore process, we can also use logical backup options like (mysqldump, mydumper, etc.) to accomplish the same goals. 

Using an “Asynchronous Replication” process to sync DR could lead to delays or replication lag due to its flow, or, more importantly, when working across data centres, where network latency is a big factor. However, adding a DR(PXC) cluster to DC(PXC) directly via synchronous replication could be more impactful or lead to flow control issues if any of the DR nodes struggle or experience performance/saturation issues. So, it’s equally important to consider all aspects or challenges before deploying in production.

The post Deploying Cross-Site Replication in Percona Operator for MySQL (PXC) appeared first on Percona.

Apr
01
2026
--

Percona Operator for PostgreSQL 2.9.0: PostgreSQL 18 Default, PVC Snapshot Backups, LDAP Support, and More!

We are excited to announce Percona Operator for PostgreSQL 2.9.0! In this release, we bring significant improvements across database lifecycle management, security, backup/restore, and operational observability, making it easier than ever to run production PostgreSQL on Kubernetes. Here’s a deep dive into what’s new.   Percona Operator for PostgreSQL 2.9.0 PostgreSQL 18 Is Now the […]
Feb
25
2026
--

Percona Operator for MongoDB 1.22.0: Automatic Storage Resizing, Vault Integration, Service Mesh Support, and More!

The latest release of the Percona Operator for MongoDB, 1.22.0 is here. It brings automatic storage resizing, HashiCorp Vault integration for system user credentials, better integration with service meshes, improved backup and restore options, and more. This post walks through the highlights and how they can help your MongoDB deployments on Kubernetes. Percona Operator for MongoDB […]

Jan
11
2024
--

Is MySQL Router 8.2 Any Better?

Is MySQL Router 8.2 Any BetterIn my previous article, Comparisons of Proxies for MySQL, I showed how MySQL Router was the lesser performing Proxy in the comparison. From that time to now, we had several MySQL releases and, of course, also some new MySQL Router ones.Most importantly, we also had MySQL Router going back to being a level 7 proxy […]

Nov
09
2023
--

Understanding What Kubernetes Is Used For: The Key to Cloud-Native Efficiency

What Kubernetes Is Used For

If you have any experience working with database software, you have undoubtedly heard the term Kubernetes a lot. You may already be using it daily and find it makes running applications in the cloud much more manageable. But for those who are not so familiar, in this post, we will discuss how Kubernetes has emerged as the unsung hero in an industry where agility and scalability are critical success factors.

At its core, Kubernetes (often abbreviated as K8s) is an open source tool that automates the deployment, scaling, and management of containerized applications. It simplifies infrastructure management and is the driving force behind many cloud-native applications and services.

For some background, Kubernetes was created by Google and is currently maintained by the Cloud Native Computing Foundation (CNCF). It has become the industry standard for cloud-native container orchestration.

To get you started with Kubernetes, this post offers a high-level introduction to its core features, highlighting its built-in advantages and showcasing some practical, real-world uses.  It’s important to note that this overview is not intended to be an exhaustive guide to every facet of Kubernetes. Kubernetes can be complex, which is why we offer comprehensive training that equips you and your team with the expertise and skills to manage database configurations, implement industry best practices, and carry out efficient backup and recovery procedures.

Making container deployment simpler

One of Kubernetes’ primary use cases is deploying containerized apps. Applications are packaged into a single, lightweight container with their dependencies, typically including the application’s code, customizations, libraries, and runtime environment. These containers encapsulate all the components necessary to run the application independently, making them portable and consistent across various environments. Kubernetes manages and orchestrates these containers, handling tasks such as deployment, scaling, load balancing, and networking.

With Kubernetes, you can define and manage your application deployments declaratively, meaning you can tell it how your apps should operate, and Kubernetes takes care of the rest.

Maintaining high availability

Kubernetes also makes it easier for applications to scale in response to changing workloads to maintain high availability. Applications can be horizontally scaled with Kubernetes by adding or deleting containers based on resource allocation and incoming traffic demands. It distributes the load among containers and nodes automatically, ensuring that your application can handle any spike in traffic without the need for manual intervention from an IT staff.

In addition, Kubernetes provides features like continuous monitoring, self-healing capabilities (automatically replacing containers if they happen to fail), and rolling updates (gradual updates of your applications), ensuring that your applications are always available — even in the face of failures or updates. And, if an issue ever does arise from an update, Kubernetes enables quick rollbacks to a previous version, preventing extended outages.

Multi-cloud deployments

Kubernetes is cloud-agnostic, freeing your applications from being tied to a single cloud provider. Your workloads, encapsulated in containers, can be deployed freely across different clouds or your own hardware. This portability ensures that your applications remain consistent and operational, regardless of where they are deployed.

Because of this flexibility, businesses may choose the infrastructure that best meets their needs. Instead of depending on the services of a single cloud vendor, Kubernetes provides the flexibility to distribute workloads over various cloud providers or on-premises infrastructure, reducing the risk of becoming trapped in a single ecosystem. This makes it much easier for organizations to transition to open source solutions, reduce costs, and avoid vendor lock-in.

Controlled access and security

A wide range of security capabilities are available with Kubernetes, which are intended to safeguard your clusters’ integrity and containerized applications. These consist of the following but are not restricted to:

  • Network policies: Establishing communication guidelines between pods provides additional protection at the network level. Essential features include Allow and Deny Rules, Ingress and Egress Rules, and Segmentation and Isolation. These are all intended to make it harder for someone to compromise other pods, even if they manage to gain access to one.
  • Role-Based Access Control (RBAC): RBAC manages permissions to ensure that only individuals, programs, or processes with the proper authorization can utilize particular resources. In essence, it establishes permissions within a Kubernetes cluster.
  • Secrets management: To guarantee that your applications can safely access the credentials they require, Kubernetes additionally offers a secure means of storing sensitive data, including configuration data, passwords, and API keys.

Cost and resource efficiency

One of Kubernetes’ main advantages is its efficient use of resources. By putting several containers onto a single node, it optimizes without over-provisioning and provides tools for setting resource limits and requests for containers. When you combine all of this, you can ensure that your apps are allotted the appropriate amount of CPU and memory in the most effective way possible, saving you money and improving performance.

Continuous Integration and Deployment (CI/CD)

Kubernetes is a dependable base for continuous integration and delivery pipelines and not just a platform for orchestrating containers. It can be easily combined with continuous integration/continuous delivery (CI/CD) tools to automate the building, testing, and deployment of applications, facilitating the release of new versions/updates and code across numerous servers — with no downtime — enhancing development workflows and providing for quicker time-to-market for your applications.

Efficient microservices

The technique of creating applications using microservices architecture makes it possible to divide an application into smaller, independently deployable services, which simplifies development and maintenance. These services, known as “microservices,” can interact with one another through APIs and are each intended to carry out a particular task or feature of the application.

Management of stateful applications

Although stateless applications are frequently associated with Kubernetes, this flexible platform can also effectively handle stateful workloads, such as database management. For companies looking to streamline stateful application management while maintaining high availability and data integrity, Kubernetes is an excellent option because of its automation, scalability, and dependability

Real-world Kubernetes use cases

Numerous industries, including finance, healthcare, e-commerce, education, etc., have adopted Kubernetes. It is an invaluable tool for resolving complicated issues and streamlining processes due to its flexibility and scalability. Here are a few examples of actual Kubernetes use cases across various industries:

E-commerce: Traffic to e-commerce platforms varies, particularly during sales, promotions, and holidays. The seamless shopping experience is ensured by Kubernetes, which assists in automatically scaling web applications to handle this increased load.

Entertainment: To guarantee that viewers have continuous access to films and TV series, film studios and television networks rely on Kubernetes for content delivery and streaming. Just consider the sheer number of people who stream Netflix every night!

Finance: Financial institutions utilize Kubernetes for its security and compliance features. It facilitates simple scalability and effective disaster recovery and enables them to deploy and administer applications in a highly regulated environment.

Education: Universities often use Kubernetes for projects that require substantial resources because it scales computing clusters for research, data analysis, and simulations.

Healthcare: Hospitals and healthcare providers use Kubernetes for processing and analyzing vast amounts of health data so that medical records, lab results, and patient information are protected and available when needed.

Telecommunications: By guaranteeing low-latency communication, Kubernetes assists the telecom sector in quickly deploying 5G and edge computing applications.

Conclusion

Kubernetes’ versatility and scalability empower organizations to streamline and simplify their containerized workloads while enhancing scalability, ensuring high availability, and improving resource efficiency. It is the go-to choice for businesses looking to move to the cloud, embrace microservices, and deploy applications across various environments, all while avoiding the high cost of vendor lock-in. 

Are you interested in learning more about Kubernetes or need assistance with your cloud-native strategy? With Percona Kubernetes Operators, you can manage database workloads on any supported Kubernetes cluster running in private, public, hybrid, or multi-cloud environments. They are 100% open source, free from vendor lock-in, usage restrictions, and expensive contracts, and include enterprise-ready features by default.


Learn more about Percona Kubernetes Operators

Discover how Percona Operator for MongoDB transformed one of our valued customers’ experience with Kubernetes. With Percona as their trusted partner, they’ve experienced reliable solutions and outstanding support for their database needs.


FAQ

What are some common use cases for Kubernetes?

Kubernetes is widely used for managing containerized applications, making it suitable for various scenarios, including web services, microservices, and data processing applications.

Is Kubernetes suitable for small businesses, or is it primarily for large enterprises?

All sizes of businesses can benefit from Kubernetes. Small businesses can also benefit from its features, like automation and resource optimization, even though large corporations frequently use it for complex workloads.

Can Kubernetes work with different cloud providers?

Yes, Kubernetes offers the flexibility and portability of your app since it is cloud-agnostic and compatible with multiple cloud providers.

Jan
20
2023
--

Help! I Am Out of Disk Space!

Out of Disk Space MySQL

Out of Disk Space MySQLHow can we fix a nasty out-of-space issue leveraging the flexibility of Percona Operator for MySQL?

When planning a database deployment, one of the most challenging factors to consider is the amount of space we need to dedicate to data on disk.

This is even more cumbersome when working on bare metal, as it is more difficult to add space when using this kind of solution with respect to the cloud.

When using cloud storage like EBS or similar, it is normally easy(er) to extend volumes, which gives us the luxury to plan the space to allocate for data with a good grade of relaxation. 

Is this also true when using a solution based on Kubernetes like Percona Operator for MySQL? Well, it depends on where you run it. However, if the platform you choose supports the option to extend volumes, K8s per se gives you the possibility to do so as well.

Nonetheless, if it can go wrong it will, and ending up with a fully filled device with MySQL is not a fun experience. 

As you know, on normal deployments, when MySQL has no space left on the device, it simply stops working, ergo it will cause a production down event, which of course is unfortunate and we want to avoid it at any cost.  

This blog is the story of what happened, what was supposed to happen, and why. 

The story

The case was on AWS using EKS.

Given all the above, I was quite surprised when we had a case in which a deployed solution based on Percona Operator for MySQL went out of space. However, we started to dig in and review what was going on and why.

The first thing we did was to quickly investigate what was really taking space, and that could have been an easy win if most of the space was taken by some log, but unfortunately, this was not the case, as data was really taking all the available space. 

The next step was to check what storage class (SC) was used for the PersistentVolumeClaim (PVC):

k get pvc
NAME                         VOLUME    CAPACITY   ACCESS MODES   STORAGECLASS
datadir-mt-cluster-1-pxc-0   pvc-<snip>   233Gi      RWO            io1
datadir-mt-cluster-1-pxc-1   pvc-<snip>   233Gi      RWO            io1
datadir-mt-cluster-1-pxc-2   pvc-<snip>   233Gi      RWO            io1

Ok we use the io1 SC, it is now time to check if the SC is supporting volume expansion:

kubectl describe sc io1
Name:            io1
IsDefaultClass:  No
Annotations:     kubectl.kubernetes.io/last-applied-configuration={"apiVersion":"storage.k8s.io/v1","kind":"StorageClass","metadata":{"annotations":{"storageclass.kubernetes.io/is-default-class":"false"},"name":"io1"},"parameters":{"fsType":"ext4","iopsPerGB":"12","type":"io1"},"provisioner":"kubernetes.io/aws-ebs"}
,storageclass.kubernetes.io/is-default-class=false
Provisioner:           kubernetes.io/aws-ebs
Parameters:            fsType=ext4,iopsPerGB=12,type=io1
AllowVolumeExpansion:  <unset> <------------
MountOptions:          <none>
ReclaimPolicy:         Delete
VolumeBindingMode:     Immediate
Events:                <none>

And no is not enabled, and in this case, we cannot just go and expand the volume, we must change the storage class settings first. To enable volume expansion, you need to delete the storage class and enable it again. 

Unfortunately, we were unsuccessful in doing that operation, because the storage class kept staying unset for  ALLOWVOLUMEEXPANSION. 

As said, this is a production down event, so we cannot invest too much time in digging into why it was not correctly changing the mode, we had to act quickly. 

The only option we had to fix it was:

  • Expand the io1 volumes from the AWS console (or AWS client)
  • Resize the file system 
  • Patch any K8 file to allow K8 to correctly see the new volume’s dimension  

Expanding EBS volumes from the console is trivial, just go to Volumes, select the volume you want to modify, choose modify, and change the size of it with the one desired, and done. 

Once that is done, connect to the Node hosting the pod which has the volume mounted like this:

k get pods -o wide|grep mysql-0
NAME                                        READY     STATUS    RESTARTS   AGE    IP            NODE             
cluster-1-pxc-0                               2/2     Running   1          11d    10.1.76.189     <mynode>.eu-central-1.compute.internal

Then we need to get the id of the PVC to identify it on the node:

k get pvc
NAME                         STATUS   VOLUME                                     CAPACITY   ACCESS MODES   STORAGECLASS
datadir-cluster-1-pxc-0   Bound    pvc-1678c7ee-3e50-4329-a5d8-25cd188dc0df   233Gi      RWO            io1

One note, when doing this kind of recovery with a Percona XtraDB Cluster-based solution, always recover node-0 first, then the others.  

So we connect to <mynode> and identify the volume: 

lslbk |grep pvc-1678c7ee-3e50-4329-a5d8-25cd188dc0df
nvme1n1      259:4    0  350G  0 disk /var/lib/kubelet/pods/9724a0f6-fb79-4e6b-be8d-b797062bf716/volumes/kubernetes.io~aws-ebs/pvc-1678c7ee-3e50-4329-a5d8-25cd188dc0df <-----

At this point we can resize it:

root@ip-<snip>:/# resize2fs  /dev/nvme1n1
resize2fs 1.45.5 (07-Jan-2020)
Filesystem at /dev/nvme1n1 is mounted on /var/lib/kubelet/plugins/kubernetes.io/aws-ebs/mounts/aws/eu-central-1a/vol-0ab0db8ecf0293b2f; on-line resizing required
old_desc_blocks = 30, new_desc_blocks = 44
The filesystem on /dev/nvme1n1 is now 91750400 (4k) blocks long.

The good thing is that as soon as you do that, the MySQL daemon sees the space and will restart, however, it will happen only on the current pod and K8 will still see the old dimension:

k get pv
NAME                                       CAPACITY   ACCESS MODES   RECLAIM POLICY   STATUS   CLAIM                            STORAGECLASS   REASON
pvc-1678c7ee-3e50-4329-a5d8-25cd188dc0df   333Gi      RWO            Delete           Bound    pxc/datadir-cluster-1-pxc-0   io1

To allow K8 to be aligned with the real dimension, we must patch the information stored, and the command is the following:

kubectl patch pvc <pvc-name>  -n <pvc-namespace> -p '{ "spec": { "resources": { "requests": { "storage": "NEW STORAGE VALUE" }}}}'
Ie:
kubectl patch pvc datadir-cluster-1-pxc-0 -n pxc -p '{ "spec": { "resources": { "requests": { "storage": "350" }}}}'

Remember to use as PVC-name the NAME coming from:

kubectl get pvc.

Once this is done, K8 will see the new volume dimension correctly.

Just repeat the process for Node-1 and Node-2 and …done, the cluster is up again.

Finally, do not forget to modify your custom resources file (cr.yaml) to match the new volume size. I.E.:

volumeSpec:
      persistentVolumeClaim:
        storageClassName: "io1"
        resources:
          requests:
            storage: 350G

The whole process took just a few minutes, it was time now to investigate why the incident happened and why the storage class was not allowing extension in the first place.  

Why it happened

Well, first and foremost the platform was not correctly monitored. As such there was a lack of visibility about space utilization and no alert about disk space. 

This was easy to solve by enabling the Percona Monitoring and Management (PMM) feature in the cluster cr and setting the alert in PMM once the nodes join it (see https://docs.percona.com/percona-monitoring-and-management/get-started/alerting.html for details on how to do it).

The second issue was the problem with the storage class. Once we had the time to carefully review the configuration files, we identified that there was an additional tab in the SC class, which was causing K8 to ignore the directive. 

It was supposed to be:

kind: StorageClass
apiVersion: storage.k8s.io/v1
metadata:
  name: io1
  annotations:
    storageclass.kubernetes.io/is-default-class: "false"
provisioner: kubernetes.io/aws-ebs
parameters:
  type: io1
  iopsPerGB: "12"
  fsType: ext4 
allowVolumeExpansion: true <----------

It was:
kind: StorageClass
apiVersion: storage.k8s.io/v1
metadata:
  name: io1
  annotations:
    storageclass.kubernetes.io/is-default-class: "false"
provisioner: kubernetes.io/aws-ebs
parameters:
  type: io1
  iopsPerGB: "12"
  fsType: ext4 
  allowVolumeExpansion: true. <---------

What was concerning was the lack of error returned by the Kubernetes API, so in theory the configuration was accepted but not really validated. 

In any case, once we had fixed the typo and recreated the SC, the setting for volume expansion was correctly accepted:

kubectl describe sc io1
Name:            io1
IsDefaultClass:  No
Annotations:     kubectl.kubernetes.io/last-applied-configuration={"allowVolumeExpansion":true,"apiVersion":"storage.k8s.io/v1","kind":"StorageClass","metadata":{"annotations":{"storageclass.kubernetes.io/is-default-class":"false"},"name":"io1"},"parameters":{"fsType":"ext4","iopsPerGB":"12","type":"io1"},"provisioner":"kubernetes.io/aws-ebs"}
,storageclass.kubernetes.io/is-default-class=false
Provisioner:           kubernetes.io/aws-ebs
Parameters:            fsType=ext4,iopsPerGB=12,type=io1
AllowVolumeExpansion:  True    
MountOptions:          <none>
ReclaimPolicy:         Delete
VolumeBindingMode:     Immediate
Events:                <none>

What should have happened instead?

If proper monitoring and alerting were in place, the administrators would have the time to act and extend the volumes without downtime. 

However, the procedure for extending volumes on K8 is not complex but also not as straightforward as you may think. My colleague Natalia Marukovich wrote a blog post, Percona Operator Volume Expansion Without Downtime, that gives you the step by step instructions on how to extend the volumes without downtime. 

Conclusion

Using the cloud, containers, automation, or more complex orchestrators like Kubernetes, does not solve all, does not prevent mistakes from happening, and more importantly, does not make the right decisions for you.

You must set up a proper architecture that includes backup, monitoring, and alerting. You must set the right alerts and act on them in time.

Finally, automation is cool, however, the devil is in the details and typos are his day-to-day joy. Be careful and check what you put online, do not rush it. Validate, validate, validate…

Great stateful MySQL to all.

Percona Monitoring and Management is a best-of-breed open source database monitoring solution. It helps you reduce complexity, optimize performance, and improve the security of your business-critical database environments, no matter where they are located or deployed.

Download Percona Monitoring and Management Today

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com