Jul
23
2026
--

Percona Operator for MongoDB 1.23.0: ClusterSync Migration, Vector Search, and PVC Snapshot Backups


Percona Operator for MongoDB 1.23.0 makes the operator a place you move to, not just a place you start. A new ClusterSync component clones a live source and follows its change streams, so leaving a hosted service is a short cutover rather than a long outage. Alongside it, this release adds semantic vector search and storage-layer snapshot backups, two features that matter most once the data is yours to run.

The three headline features are Percona ClusterSync for MongoDB, vector search, and PVC snapshot backups. ClusterSync clones and continuously replicates a live source into an operator-managed cluster. Vector search brings semantic queries to Percona Server for MongoDB. PVC snapshot backups move backups off the network path and onto the storage layer.

This release also widens where you can run it, adding official Rancher Kubernetes Engine (RKE2) support and full ARM64 images. Much of what shipped here traces back to requests on forums.percona.com and the public issue tracker.


In this post, you’ll learn about:

  • ClusterSync migration and replication
  • Vector search for semantic queries
  • PVC snapshot backups
  • Other improvements worth knowing about


Zero-Downtime Migration with Percona ClusterSync

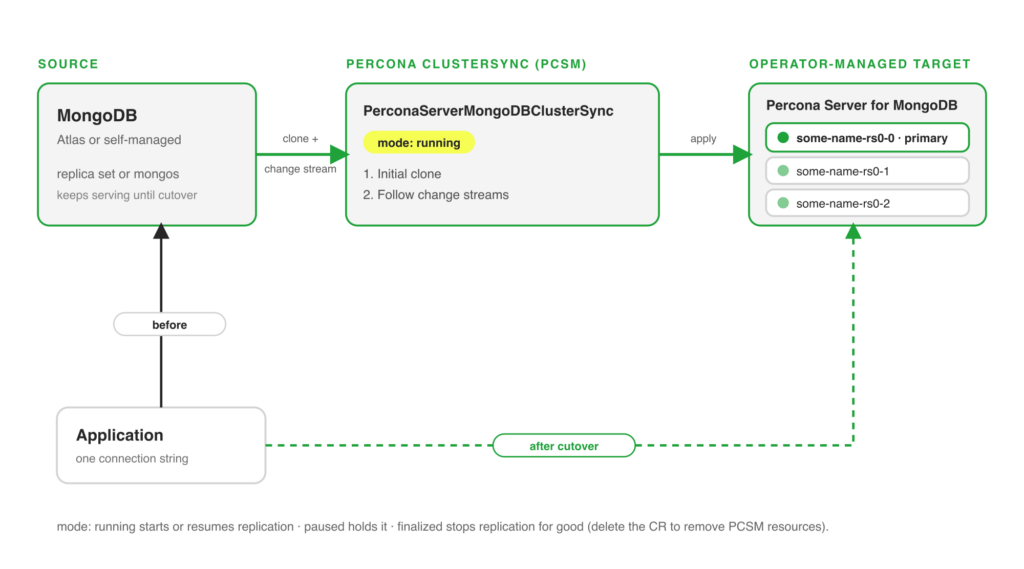
Moving a live MongoDB database onto the operator has always been the awkward first step. Dump-and-restore needs a maintenance window sized to your data, and hand-built replication between a source and a target is fragile to set up and easy to get wrong. This release introduces Percona ClusterSync for MongoDB (PCSM) as an operator-managed component, so the migration path is via a Kubernetes object rather than a runbook.


Why it matters

The common case is migrating a hosted MongoDB service, for example MongoDB Atlas, for an operator-managed Percona Server for MongoDB cluster you control end to end. A typical trigger in production is a hosted-service bill that climbs with the workload, or a compliance requirement to keep data inside your own VPC and region: a team running a user-profile store on Atlas points PCSM at it, lets the target catch up over a day or two while the application keeps serving from Atlas, then cuts over in a maintenance window measured in seconds. PCSM clones the existing data, then tracks ongoing changes through MongoDB change streams, so the target stays current while you validate it. When you are ready, you cut the application over during a short window rather than a long one. The same mechanism keeps a continuously updated replica for non-production use or a hybrid-cloud copy.

How it works

PCSM runs as its own container, deployed and managed through a new PerconaServerMongoDBClusterSync custom resource. It performs an initial clone from the source connection string, then consumes change stream events to apply subsequent writes to the target. A mode field controls the lifecycle: running starts or resumes replication, paused holds it, and finalized stops replication.


Wiring it up

apiVersion: psmdb.percona.com/v1
kind: PerconaServerMongoDBClusterSync
metadata:
  name: my-cluster-sync
spec:
  clusterName: my-target-cluster-name
  image: percona/percona-clustersync-mongodb:0.9.0
  # mode controls the PCSM lifecycle intent. Allowed values:
  #   running   - start/resume replication (default)
  #   paused    - pause an active replication
  #   finalized - stop replication
  mode: running
  source:
    uri: mongodb://source-cluster-mongos.source-namespace.svc.cluster.local:27017
    credentialsSecret: my-cluster-sync-source
  # excludeNamespaces lists MongoDB namespaces (db or db.collection) to skip.
  # excludeNamespaces:
  #   - admin
  #   - local

clusterName names the operator-managed target that receives the data. source.uri and source.credentialsSecret point at the database you are migrating from, which can be Atlas, a self-managed replica set, or another operator cluster. mode is the control you drive the cutover with: run to catch up, pause to hold, then finalize once the application points at the new cluster. The optional excludeNamespaces list skips databases or collections you do not want to copy.
 

Cutover and rollback

The cutover is yours to time, not the operator’s. During the running replication, the target trails the source by the change-stream lag, which you watch until it is small and steady. You then stop writes on the source, let the last events drain, and repoint the application at the target cluster. Because the source keeps serving until you move the application, a rollback before cutover is simply leaving the application where it is. After cutover, treat the move as one-way once writes flow to the target, so verify the target thoroughly during the sync window rather than after.

Note: The PCSM component ships at version 0.9.0 with this release. Test the full migration and cutover against a staging copy before you run it on production data, and keep the source available until you have verified the target.


Vector search for semantic queries

Vector search retrieves results by meaning rather than exact keyword match, which is the retrieval pattern behind semantic search and retrieval-augmented generation for AI applications. Teams that already store their data in MongoDB have had to copy vectors into a separate engine to do this, which adds a system to run and a pipeline to keep in sync. In production, this is the pattern behind a support tool that surfaces past tickets describing the same problem in different words, a product catalog that returns items by intent rather than exact keywords, and a RAG service that grounds a model on internal documents. This release lets you store and query vector data alongside your regular documents in Percona Server for MongoDB, so those workloads query one system instead of two.
 

How it works

The operator deploys and manages the mongot search process, wires its authentication and TLS to the rest of the cluster, and keeps the search index synchronized for both replica set and sharded deployments. Applications query the index through the same MongoDB connection they already use, so you add semantic search without a second client, a second driver, or a second set of credentials. You do not stand up or secure a separate search tier; the operator treats mongot as another managed component of the cluster.
 

Wiring it up

Enable the search component in the custom resource:

spec:
  search:
    enabled: true
    image: perconalab/percona-server-mongodb-operator:main-mongot
    size: 1
    storage:
      persistentVolumeClaim:
        resources:
          requests:
            storage: 10Gi
    resources:
      requests:
        cpu: "2"
        memory: 2Gi

size sets how many search nodes to run, and storage gives the search index its own PersistentVolumeClaim so it does not compete with the database volume. Size the resources block to your index: vector indexes are memory-sensitive, so give mongot enough headroom for the corpus you intend to query.

Note: Vector search is a tech preview in 1.23.0 and is not recommended for production yet. It requires Percona Server for MongoDB 8.3 or later.


PVC snapshot backups

Logical and streamed physical backups both push data across the network to object storage, and for a multi-terabyte cluster, that path is the bottleneck. Backups run long, restores run longer, and both compete with production traffic for CPU and bandwidth. This release adds backups built on PersistentVolumeClaim snapshots, which takes the storage layer directly.


Why it matters

A PVC snapshot is a point-in-time copy of your data volumes taken at the storage layer through the Kubernetes VolumeSnapshot API. Because the operator asks the storage provider for a snapshot instead of streaming bytes out, a backup typically completes in seconds or minutes regardless of database size, and a restore is correspondingly fast. Two production situations show the difference: a nightly backup that no longer fits its window as a cluster grows past a few terabytes, and a staging refresh that ties up resources for hours while it restores a streamed copy. A storage-layer snapshot turns both into a near-instant operation. The speed comes from how the storage layer implements snapshots: instead of copying the whole volume, most backends record only the blocks that changed since the previous snapshot and reference the rest, so the cost tracks your change rate rather than the total database size. Snapshots also work with encrypted and TLS-enabled clusters, and they use fewer cluster resources because there is no long-running data-transfer job.


Wiring it up

The operator takes snapshot backups in two ways: on demand through a PerconaServerMongoDBBackup object, or on a schedule through a backup task. The scheduled form looks like this, using the external type and a VolumeSnapshotClass:

spec:
  backup:
    tasks:
      - name: daily-snapshot
        enabled: false
        schedule: "0 0 * * *"
        retention:
          count: 1
          type: count
          deleteFromStorage: true
        type: external
        volumeSnapshotClass: YOUR-VOLUME-SNAPSHOT-CLASS

type: external tells the operator to take a storage-layer snapshot rather than stream a backup, and volumeSnapshotClass names the VolumeSnapshotClass your CSI driver provides. The retention block prunes old snapshots on the schedule you set. Your storage provider must support the Kubernetes VolumeSnapshot API for this to work.

Snapshot backups complement the streamed and logical backups the operator already supports; they do not replace them. Snapshots usually live in the same storage account and region as the volumes they copy, so keep a streamed backup to object storage for off-site and cross-region disaster recovery. A practical policy pairs frequent fast snapshots for quick local recovery with a less frequent streamed backup for durability, and the operator runs both from the same backup.tasks list.


Note:
PVC snapshot backups are a tech preview in 1.23.0 and are not recommended for production yet. Snapshot portability and retention semantics depend on your CSI driver, so test restores before you rely on them.


Other improvements

Beyond the three headline features, 1.23.0 ships a set of enhancements that smooth day-two operations:

  • Operator-generated connection string Secrets (K8SPSMDB-1537): the operator now publishes a ready-to-use MongoDB connection string (URI) in a Kubernetes Secret for the databaseAdmin user. An application can read that one Secret and connect to it, instead of building the URI itself from Pod names, Services, TLS settings, and credentials.
  • Workload Identity for GCS backups (K8SPSMDB-1602): back up to Google Cloud Storage without storing a service-account JSON key in a Secret.
  • Oracle Cloud Infrastructure Object Storage (K8SPSMDB-1644) and Alibaba Cloud OSS (K8SPSMDB-1519): two more native backup destinations.
  • Restore a collection under a different name (K8SPSMDB-1603): use selective.nsFrom and nsTo to restore one collection alongside the live one for inspection or recovery.
  • External nodes as arbiters (K8SPSMDB-1031): set arbiterOnly: true on an external node to place a tie-breaker vote in a third location without a data-bearing member.
  • cert-manager ClusterIssuer and TLS policy (K8SPSMDB-1413, K8SPSMDB-1458): point the operator at an existing ClusterIssuer, and use certManagementPolicy to keep certificate lifecycle fully under your control.
  • Tunable reconciliation interval (K8SPSMDB-1571): set RECONCILE_INTERVAL to reduce Kubernetes API load on large fleets (default 5s).
  • Query Analytics via mongolog for PMM (K8SPSMDB-1546): choose mongolog as the QAN source in Percona Monitoring and Management.
  • Custom sidecar health probes (K8SPSMDB-1701, K8SPSMDB-1728) and StatefulSet revisionHistoryLimit (K8SPSMDB-1572): finer control over probes and rollout history. 

For the full list, including bug fixes, see the release notes linked below.


Conclusion

Percona Operator for MongoDB 1.23.0 covers the arc from getting data in to keeping it safe: ClusterSync brings a live database onto the operator with a short cutover, vector search lets one system serve both documents and semantic queries, and PVC snapshot backups take the network out of the backup path. With RKE2 and full ARM64 support added, more of that runs on the platforms teams actually use. If there is a workflow you still script around the operator, tell us on the forum, since that is where releases like this one come from.


Try Percona Operator for MongoDB 1.23.0


The post Percona Operator for MongoDB 1.23.0: ClusterSync Migration, Vector Search, and PVC Snapshot Backups appeared first on Percona.

Jul
07
2026
--

Percona Operator for MySQL 1.2.0: Cross-Site Replication, Encrypted Backups, and Automatic Storage Scaling


Percona Operator for MySQL 1.2.0 is out, and it closes three gaps that platform teams hit once a MySQL deployment grows past a single cluster. Picture a fleet that has outgrown one region: you want a warm replica cluster in a second data center, backups in object storage that pass an auditor’s encryption check, and volumes that grow before they fill at 3 a.m. Until now, each of those meant scripting around the operator. This release brings all three into the custom resource.

The three headline features are cross-site replication for Group Replication, encrypted backups, and automatic storage scaling. Each one turns a manual, error-prone procedure into a declarative field you set once and let the operator reconcile.

The operator is open source and runs on any CNCF-certified Kubernetes distribution. Many of the changes in this release come straight from what users asked for on forums.percona.com and in the public issue tracker, from disaster-recovery topologies to backup encryption to storage that keeps up with data growth.

In this post, you’ll learn about:

  • Cross-site replication for Group Replication clusters
  • Encrypted backups to S3, GCS, and Azure
  • Automatic storage scaling for MySQL data volumes
  • Other improvements worth knowing about


Cross-site replication for Group Replication


Group Replication gives you a self-healing, multi-primary-capable cluster inside one Kubernetes cluster. What it does not give you on its own is a second site. If the region hosting your cluster goes down, Group Replication cannot fail over to hardware it does not know about. Teams have solved this by hand-wiring asynchronous replication between clusters and babysitting it, which is exactly the kind of stateful glue an operator should own.


Why it matters

A disaster-recovery topology is only useful if it is reproducible and observable. Hand-built replication links drift: someone changes a credential, a channel stalls, and nobody notices until the failover that was supposed to save you does not work. Declaring the topology as a Kubernetes object means the operator reconciles it continuously, and the same manifest recreates it in staging, in a runbook test, and in the real event.


How it works

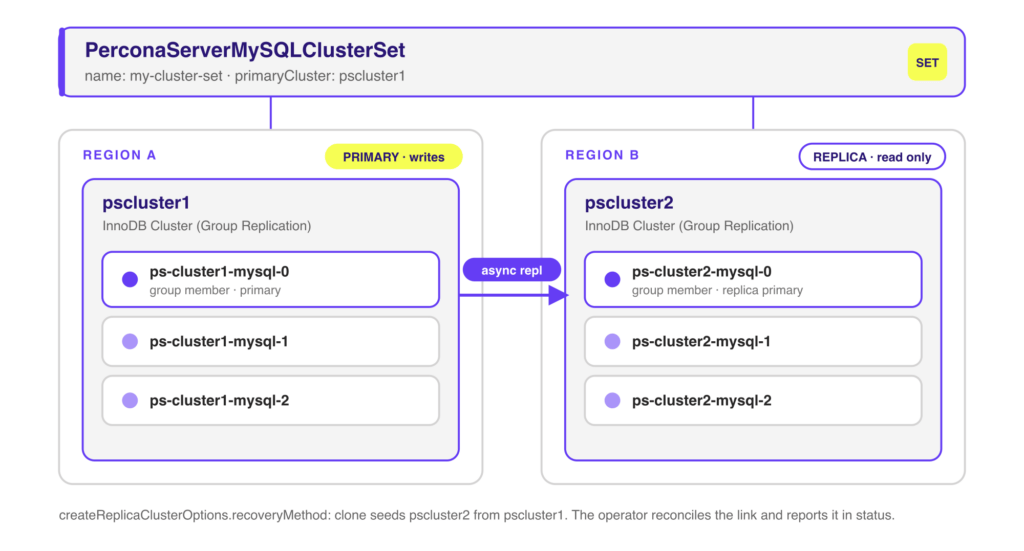
The operator adds a new custom resource, PerconaServerMySQLClusterSet, that groups two or more Group Replication clusters into a single set with one primary. The operator drives MySQL Shell to build the InnoDB ClusterSet, wires the replica clusters to the primary, and tracks the topology in the resource’s status. A replica cluster provisions from the primary using a chosen recovery method, so you do not stage data manually.

apiVersion: ps.percona.com/v1
kind: PerconaServerMySQLClusterSet
metadata:
  name: my-cluster-set
  finalizers:
    - percona.com/clusterset-dissolve
spec:
#  unsafeFlags:
#    forcedFailover: false
#    forcedClusterRemoval: false
  primaryCluster: pscluster1
  credentialsSecret:
    name: ps-cluster1-secrets
    key: clusterset
  sslMode: AUTO
  createReplicaClusterOptions:
    recoveryMethod: clone
  clusters:
    - innodbClusterName: pscluster1
      endpoints:
      - host: ps-cluster1-mysql-primary.default.svc.cluster.local
    - innodbClusterName: pscluster2
      endpoints:
      - host: ps-cluster2-mysql-0.ps-cluster2-mysql.default.svc.cluster.local
  mysqlshellRunner:
    image: percona/percona-server:8.4.10-10.1

primaryCluster names the source of truth. Each entry under clusters points at a Group Replication cluster by its InnoDB cluster name and reachable endpoints, so the clusters can live in separate namespaces or separate Kubernetes clusters joined by routable DNS. createReplicaClusterOptions.recoveryMethod: clone tells the replica to seed itself with a full clone. The percona.com/clusterset-dissolve finalizer ensures the operator tears the ClusterSet down cleanly instead of leaving orphaned replication channels behind.
 

Failover and cleanup

Once the set exists, the operator keeps the replica clusters attached to the primary and surfaces the topology in the resource’s status, so you can see which cluster is primary and whether every replica is connected without shelling into MySQL Shell. A planned switchover promotes a replica to primary. The unsafeFlags block gates the disruptive paths for when the primary is already gone.

Note: The unsafeFlags block gates disruptive operations such as forced failover and forced cluster removal. Leave these off for normal operation and reach for them only in a controlled recovery, since a forced failover can diverge history if the old primary comes back.


Encrypted backups

Backups are the copy of your data most likely to leave the cluster’s security boundary. They land in an object-storage bucket, get replicated across a provider’s regions, and often live longer than the database that produced them. If they are not encrypted before they leave the pod, a bucket misconfiguration or a leaked credential exposes the whole dataset. This release lets the operator encrypt backup data as it is


How it works

Backups in the operator run on Percona XtraBackup. XtraBackup encrypts the stream with its xbcrypt component before uploading, so the data is ciphertext at rest in the bucket and stays that way until you restore it with the same key. You supply the key through a Kubernetes Secret and reference that Secret from the backup configuration. The operator never bakes the key into a manifest or an image.


Wiring it up

Point a storage target at an encryption-key Secret with encryptionKeySecret:

apiVersion: ps.percona.com/v1
kind: PerconaServerMySQL
metadata:
  name: cluster1
spec:
  backup:
    storages:
      s3-us-west:
        type: s3
        encryptionKeySecret:
          key: encryptionKey
          name: my-s3-encryption-key-secret
        s3:
          bucket: S3-BACKUP-BUCKET-NAME-HERE
          credentialsSecret: cluster1-s3-credentials
          region: us-west-2

The same encryptionKeySecret field works under S3, GCS, and Azure storage targets, so a multi-cloud backup policy uses one consistent mechanism. You can also set an encryptionKeySecret at the backup level to apply one key across every storage target instead of repeating it per bucket. The referenced Secret holds the key under the encryptionKey data field.


Restoring an encrypted backup

Encryption is transparent on the way back in. When you restore, the operator reads the same Secret, hands the key to XtraBackup, and decrypts the stream before it prepares the data directory. The only hard requirement is that the key still exists: the restore fails fast if the Secret is missing or holds a different key than the one that produced the backup. Encryption also composes with backup compression, so you keep the smaller footprint and the ciphertext-at-rest guarantee at the same time.

Note: Keep the encryption key safe and versioned outside the cluster. A backup encrypted with a key you have lost is not recoverable. Treat the key with the same care as the backups themselves.


Automatic storage scaling

Running out of disk is one of the fastest ways to take a database down, and it rarely happens at a convenient hour. The operator has supported manual volume expansion since an earlier release: you raise resources.requests.storage, apply, and the operator grows the PersistentVolumeClaim for you. That still requires a human to notice the trend and act. Version 1.2.0 adds automatic scaling that watches usage and grows the volume on its own.


Why it matters

Storage growth is predictable in aggregate and unpredictable in timing. A batch import, a retention change, or an unexpected traffic spike can eat headroom faster than an on-call engineer can respond. Letting the operator resize before the volume fills turns a page someone at 3 a.m. incident into a log line, as long as your storage class supports online expansion.


How it works

You enable volume expansion, then define an autoscaling policy. The operator monitors each data PVC and, when usage crosses the threshold, grows the volume by a fixed step up to a ceiling you set. Because it builds on the Kubernetes volume-expansion API, the underlying storage class must have AllowVolumeExpansion: true.


Wiring it up

apiVersion: ps.percona.com/v1
kind: PerconaServerMySQL
metadata:
  name: cluster1
spec:
  enableVolumeExpansion: true
  storageScaling:
    enableVolumeScaling: true
    autoscaling:
      enabled: true
      growthStep: 2Gi
      maxSize: 10Gi
      triggerThresholdPercent: 80


triggerThresholdPercent is the fill level that triggers a resize (default 80, allowed range 50 to 95). growthStep is how much capacity each resize adds (default 2Gi), and maxSize caps total growth so a runaway workload cannot expand a volume without bound. The operator validates the relationship between these fields: autoscaling cannot be enabled unless enableVolumeScaling is on. For teams that prefer an external controller to own resizing, enableExternalAutoscaling hands that responsibility off instead.

The operator records each resize in the cluster status under storageAutoscaling, including the count of resizes and the timestamp of the last one. That gives you an audit trail and a signal worth alerting on: a volume that keeps hitting its growthStep is telling you the workload has changed, and a volume approaching maxSize is telling you to plan capacity before the ceiling stops the next resize.

Note: PVC expansion is one-way. Kubernetes can grow a volume but cannot shrink it, so set maxSize deliberately. Confirm your storage class allows expansion before you rely on this in production.


Other improvements

Beyond the three headline features, 1.2.0 ships a set of enhancements that smooth day-two operations:

  • Dedicated root user Secret (K8SPS-689): the operator publishes root connection details in a dedicated Secret, so applications and tooling read one predictable object instead of parsing several.
  • Disable NodePort allocation for LoadBalancer Services (K8SPS-496): set allocateLoadBalancerNodePorts: false to stop Kubernetes from opening NodePorts you never use behind a cloud load balancer.
  • Custom cluster naming for PMM (K8SPS-627): give a cluster a stable display name so multi-region and multi-namespace fleets stay legible in Percona Monitoring and Management.
  • Vault encryption Secret validation (K8SPS-487): the operator validates the Vault Secret and reports problems in status immediately, instead of failing later during an operation.
  • Concurrent reconciliation (K8SPS-434): tune how many clusters the operator reconciles at once through an environment variable, which helps a single operator manage a larger fleet.
  • Independent mysql-monit sidecar resources (K8SPS-742): set CPU and memory for the monitoring sidecar separately from the database container.
  • Orchestrator API authentication (K8SPS-19): the Orchestrator API now requires valid credentials.
  • Binlog storage configuration in restore objects (K8SPS-716): point a restore at the binlog storage it needs for point-in-time recovery.

For the full list, including bug fixes, see the release notes linked below.


Conclusion

Percona Operator for MySQL 1.2.0 extends the operator across the parts of the lifecycle that used to need custom glue: replication across sites, encryption of data that leaves the cluster, and storage that keeps up with growth. Platform teams running MySQL fleets on Kubernetes get declarative control over disaster recovery, a cleaner path through a security review, and one less 3 a.m. page. If there is a topology or a control you still have to script around, tell us on the forum, since that feedback is where releases like this one come from.


Try Percona Operator for MySQL 1.2.0


The post Percona Operator for MySQL 1.2.0: Cross-Site Replication, Encrypted Backups, and Automatic Storage Scaling appeared first on Percona.

Jun
30
2026
--

Community Docker Images: keeping the operator open without a vendor registry lock-in

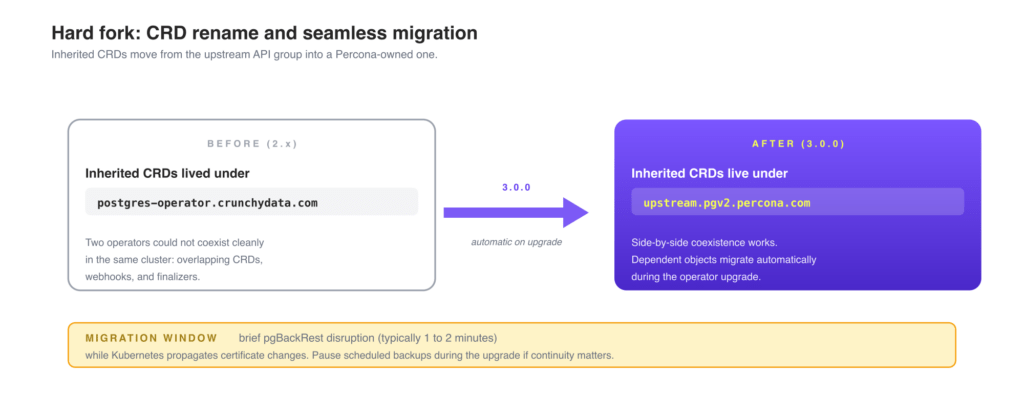
PostgreSQL community images address a real gap in how a Kubernetes database operator earns your trust. Running a database operator on Kubernetes means trusting two things: the code, and the container images the operator pulls. The code is on GitHub, easy to inspect, easy to fork. The container images, the registry that hosts them, and the license that governs them all sit with the vendor, and any of those three can change without the source repository changing at all. Starting with Percona Operator for PostgreSQL 3.0.0, you can run the operator against community images you build yourself from the official PostgreSQL packages on download.postgresql.org, in a registry you control.


TL;DR

  • Community Docker Images: tech preview in PGO 3.0.0, official in 3.1.0. Point the operator at upstream-built PostgreSQL images instead of the Percona Distribution images.
  • Build them yourself from the official PostgreSQL source. The Dockerfiles pull packages from download.postgresql.org (the PGDG repositories), so the trust chain runs from PGDG to your registry with no vendor in the middle.
  • There are limits. Anything Percona-specific (TDE in our distribution build, for example) does not exist in an upstream-built image. That trade is intentional.

In this post:

  • How open source gets diluted in practice
  • Why distributions exist anyway, honestly
  • How Community Docker Images work
  • Limits of the upstream path
  • What to try, what to tell us


How open source gets diluted

Open source has changed in the last few years, and not always for the better. Companies have learned that you can keep a project’s source code fully open and still capture most of the lock-in by quietly closing the parts that matter in production: the release artifacts, the container images, the supported OS list, the certified Kubernetes distributions, the marketplace listings.


Same project, closed artifacts

You can have a fully community CNCF project that does not appear on the Red Hat Marketplace except as a paid Enterprise edition. Similarly, you can have a vendor that ships one packaging in the community and a richer one in Enterprise with the features you actually need in production. The license still says “open source.” The practical experience says “you depend on us.” And the source repository’s license is not the only license that matters here: a vendor can change the license, the trademark policy, or the distribution terms on the container images alone, while leaving the source repository untouched. That has happened in the PostgreSQL operator space recently, and the community noticed.


Why the community is right to be wary

Nobody outside the vendor can predict when a license will change, when a feature will move behind a paywall, or when an external contribution will get rejected because it competes with an Enterprise feature. Recent history has plenty of examples and the PostgreSQL community has been paying attention. When this community resists vendor-controlled distributions, it is not nostalgia. It is a rational read of where things have gone before.

I work on Percona’s PostgreSQL operator, so I see this conversation from the vendor side. The skepticism is fair. The honest question for us is what to do about it.
 

Why distributions exist anyway

Acknowledging the community’s concerns does not mean distributions are pointless. There are real reasons to ship one, and pretending otherwise makes for bad blog posts.
 

What a distribution buys you

A vendor-built distribution lets the vendor:

  1. Control the build process, dependencies, and defaults so they fit a specific user shape.
  2. Ship hotfixes faster, because the whole release path sits in one place.
  3. Fork PostgreSQL itself when something the upstream community will not accept, or can take years to accept, matters to customers, such as Transparent Data Encryption.
  4. For a Kubernetes operator, ship images with exactly the tools and extensions the operator supports, and skip everything else. The CVE surface stays smaller.
  5. Give QA and Service teams a predictable environment. “We support extensions A, B, C and not D, X, Z” is only honest if QA actually exercises A, B, C and the Service team can work with them in the production environment.
  6. Give customers one accountable party for the full release cycle, from hotfix through package availability. Some teams explicitly need that contract for compliance and audit reasons.
  7. And yes, less positive reasons that we covered above also apply, which is exactly the part the community keeps pointing at.


The trade-off you accept

If you run the vendor distribution, you accept that the vendor’s registry, image policy, and supported-extension matrix become part of your stack. If the vendor changes any of that, your operator deployment changes with it. That is not hypothetical for users who have lived through it on other products.

So the real question is whether you can keep the benefits a distribution provides for the users who want them, while leaving an honest, supported door open for users who do not. That is the door PGO 3.0.0 opens.


Community PostgreSQL Images in PGO 3.0.0

Starting with Percona Operator for PostgreSQL 3.0.0, the operator can run against images built from upstream PostgreSQL packages, not just the Percona Distribution images. This is what we are calling Community PostgreSQL Images. In 3.0.0, the feature ships as a tech preview. In 3.1.0, these images become part of our official release cycle and are fully documented.

One of the main advantages of Community Docker Images is that the community can request or contribute any extension that does not exist in the official Percona PostgreSQL distribution. TimescaleDB and Citus are the first examples: the community asked for them, and we shipped both in the Community Images set from day one.


How to use “Community PostgreSQL images”

The operator does not care where the image came from, as long as the image meets the operator’s runtime expectations 

A typical CR using a community image looks like this:

apiVersion: pgv2.percona.com/v2
kind: PerconaPGCluster
metadata:
  name: cluster1
spec:
  image: registry.example.com/postgresql-community:18
  postgresVersion: 18
  proxy:
    pgBouncer:
      image: registry.example.com/pgbouncer-community:1.23
  backups:
    pgbackrest:
      image: registry.example.com/pgbackrest-community:2.51
  # other spec fields unchanged from a normal CR

The fields that change are spec.image, spec.proxy.pgBouncer.image, and spec.backups.pgbackrest.image. You can build and publish all three images under your own registry, with your own tags if that helps you track versions. The operator drives the rest of the deployment the same way it always has: instances, backups, replication, monitoring, all of it.


What ships are in each image

Each Community Docker Image is a thin layer over the chosen base (UBI9 or UBI8) plus the packages the operator needs for that role. Where you see {N}, substitute the PostgreSQL major you build for (17, 18, and so on).

postgres image (e.g. postgres17):

Package Role
postgresql{N}-server PostgreSQL server
postgresql{N}-contrib contrib modules
pg_repack_{N} online table/index reorganization
pgaudit_{N} audit logging
set_user_{N} privilege escalation control
pgvector_{N} vector similarity search
wal2json_{N} WAL to JSON logical decoding
pg_cron_{N} in-database cron scheduler
pgbackrest</code> backup/restore tool
patroni HA cluster manager
timescaledb-2-postgresql-{N} time-series extension (x86_64 only; EL9 only for PG18)
citus_{N} distributed PostgreSQL (PG16+ only)

pgbackrest image:

Package Role
pgbackrest backup/restore tool only

pgbouncer image:

Package Role
pgbouncer connection pooler only


The split is intentional. The postgres image ships the full operator-aware runtime. The backup and proxy images stay minimal. As a result, the operator’s components are in separate failure domains and shrink the attack surface of each container.


Limits worth being honest about

A community image is not a Percona Distribution image. Two practical consequences:

  • Distribution-only features will not work. Transparent Data Encryption, for example, lives in the Percona Distribution build. A community image built from upstream PostgreSQL does not include it. If you depend on TDE, run the distribution image.
  • Support boundaries are different. Percona Support is responsible for the Percona Distribution images and the operator code. A community image you built yourself

Ultimately, these are the right trade-offs. The point of community images is to give you transparency and control. Taking care of your own image is part of that deal. At the same time, we publish all three images under perconalab/percona-postgresql-operator on Docker Hub so you can evaluate the tech preview without standing up your own build pipeline first. perconalab is Percona’s non-production namespace, so use those images for testing. For production, build and sign your own.

UBI9 (EL9):

docker.io/perconalab/percona-postgresql-operator:main-postgres14-community
docker.io/perconalab/percona-postgresql-operator:main-postgres15-community
docker.io/perconalab/percona-postgresql-operator:main-postgres16-community
docker.io/perconalab/percona-postgresql-operator:main-postgres17-community
docker.io/perconalab/percona-postgresql-operator:main-postgres18-community
docker.io/perconalab/percona-postgresql-operator:main-pgbackrest-community
docker.io/perconalab/percona-postgresql-operator:main-pgbouncer-community
docker.io/perconalab/percona-postgresql-operator:main-upgrade-community

UBI8 (EL8):

docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres14-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres15-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres16-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres17-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres18-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-upgrade-community


How to build the images

The Dockerfile, the package list, and a sample CI job ship in percona-docker/postgresql-containers/community. The build is a regular make target on top of docker buildx, so you can run it on any multi-platform builder.

# Prerequisites: docker buildx with a multi-platform builder
docker buildx create --use --name multiarch

# Build and push all PostgreSQL community images (UBI9 / EL9)
git clone https://github.com/percona/percona-docker
cd percona-docker/postgresql-containers/community
make all TAG=1.0.0 REGISTRY=myrepo/percona-postgresql-operator

# Or a single image
make postgres17 TAG=1.0.0 REGISTRY=myrepo/percona-postgresql-operator

# UBI8 / EL8 variants
make all-ubi8 TAG=1.0.0-ubi8 REGISTRY=myrepo/percona-postgresql-operator

make all builds all three images (postgres, pgBouncer, pgBackRest) so they stay version-aligned. Override REGISTRY and TAG to point at your own namespace and tagging scheme. Once the images are in your registry, plug them into the CR fields shown earlier, and the operator picks them up.

Full build documentation: percona-docker/postgresql-containers/community/README.md.


How to contribute

Community images live in percona/percona-docker, and the build is driven by a transform.py generator that produces the Dockerfiles under build/. The files under build/ are regenerated on every sync, so contributions go through the generator, never through the generated files.

Full contribution guide: community/CONTRIBUTING.md.


How to provide feedback

Two channels, depending on the shape of the feedback:

  • GitHub issue on percona/percona-postgresql-operator with the community-images label. Use this for bug reports, missing extensions, build problems, and concrete requests. The label keeps all community-image reports in one filter the team watches.


What’s next

The first step was taking full engineering ownership of Percona Operator for PostgreSQL as an independent project, so the roadmap, the release cadence, and the governance live with one team that the community can talk to directly. Community PostgreSQL Images are the next step in that same commitment. If the community adopts this path, we have ideas for what to invest in next.

We will let the community tell us. If this is useful, we keep investing here. We are ready to add more features to the operator around Community Images. Conversely, if nobody adopts it, that is also a signal, and an honest one.

Try the tech preview in 3.0.0. Open an issue if the build flow is rougher than it should be. Tell us what you want next on the forum or directly on GitHub.


Try It Out

The post Community Docker Images: keeping the operator open without a vendor registry lock-in appeared first on Percona.

Jun
14
2026
--

The Failover Brownout: Rethinking High Availability in MySQL Group Replication

It is time to talk again about Flow control and group replication. This time with a special eye on the use of Group Replication in the Kubernetes context. In this article we will dig a bit on how it works and what are the various side effects. 


The problem

Recently I was refining the calculation I use in the MySQL calculator for Operator given I was constantly encountering a very serious problem with the Percona Server Operator.

The problem is that when the deployment was/is serving a high level of traffic, it will, no matter what, end up in getting OMMKill by the K8 system. 

This because the pod was gradually consuming more and more memory, reaching the memory limit set in the CR specification. 


Now let me clarify a few things, to get straight to the facts.

Kubernetes itself does not OOMKill a pod for hitting its memory limit, the mechanism works as described below with mention on how Working Set Size (WSS) is calculated, and how OOMKills are triggered, and in the resource sections, the links to the official documentation and source code.


1. The Reality of OOMKills vs. Kubelet Evictions

It is crucial to distinguish between what the Linux kernel does and what Kubernetes does:

  • OOMKilled (Exit Code 137): This is executed entirely by the Linux kernel’s OOM Killer, not Kubernetes. When we set a memory limit in our Pod spec, Kubernetes translates that into a Linux cgroup constraint (memory.limit_in_bytes for cgroups v1, or memory.max for cgroups v2). If our container attempts to allocate more memory than this hard limit, and the kernel cannot reclaim any page cache (like inactive files), the kernel directly intervenes and terminates the process.
  • Node-Pressure Evictions: This is where Kubernetes actively observes memory. The kubelet monitors the working_set_bytes metric to protect the node from running out of memory. If the node’s memory drops below an eviction threshold, Kubernetes will actively evict pods to prevent the kernel from initiating a system-wide OOM kill.

2. How Working Set Size (WSS) is Calculated for the container

Kubernetes monitors container memory via cAdvisor, which is integrated directly into the kubelet. cAdvisor calculates the Working Set Size by taking the total memory usage and subtracting the inactive file cache (memory that the kernel can easily reclaim if it faces memory pressure).

Because active file caches and anonymous memory (like our application’s heap) cannot be easily evicted, this working set metric is the most accurate representation of the memory your container is forcing the system to hold.


The Calculation & cgroups Evolution The core mathematical calculation is Memory UsageInactive File Cache, but how cAdvisor fetches this data from the Linux kernel depends entirely on your node’s cgroup version. Modern cAdvisor relies heavily on the opencontainers/runc/libcontainer library to read these raw cgroup files:

  • cgroups v1: cAdvisor starts with the raw usage from memory.usage_in_bytes and subtracts the reclaimable cache found under the total_inactive_file key.
  • cgroups v2 (Unified): cAdvisor starts with the raw usage from memory.current and subtracts the reclaimable cache found under the inactive_file key.


The Underlying Code Logic While older versions used a static setMemoryStats function, modern Kubernetes branches handle this dynamically. The logic executes the following flow before reporting back to the kubelet:

  1. Detects Version: It identifies whether the node runs cgroups v1 or v2 to determine the correct inactive file key name.
  2. Fetch Usage: It pulls the raw memory usage from the container.
  3. Subtract Cache: It looks up the inactive file value and safely subtracts it from the usage (including a safeguard to ensure the working set never drops below zero).
  4. Report Metric: It sets this final calculated value as container_memory_working_set_bytes, which the kubelet then uses to decide if the node is under memory pressure.

Back to us 

At the end the point is that if our pod reaches the limit and we ARE NOT using the new swap feature existing in Kubernetes, our pod will be brutally killed, and in 99% of the cases our production will suffer a lot. !Ops spoiler!


To clearly understand what was causing the issue about this memory consumption and having my calculator fail, I started to collect the information about the memory usage in MySQL itself.


SELECT EVENT_NAME,CURRENT_NUMBER_OF_BYTES_USED / 1024 / 1024 AS current_usage_mb FROM performance_schema.memory_summary_global_by_event_name WHERE EVENT_NAME like ‘memory/%’ and EVENT_NAME not like ‘memory/performance%’  order by current_usage_mb desc limit 25;

Which will give you and output like this:

+---------------------------------------+------------------+
| EVENT_NAME                            | current_usage_mb |
+---------------------------------------+------------------+
| memory/innodb/buf_buf_pool            |   46398.92578125 |
| memory/group_rpl/GCS_XCom::xcom_cache |    1066.66179943 |
| memory/group_rpl/certification_info   |      92.45250702 |
| memory/innodb/log_buffer_memory       |      64.00096130 |
| memory/sql/TABLE                      |      49.90627003 |
| memory/innodb/memory                  |      34.68734741 |
| memory/innodb/ut0link_buf             |      24.00006104 |
| memory/innodb/lock0lock               |      21.40064240 |
| memory/mysqld_openssl/openssl_malloc  |       9.51009655 |
| memory/innodb/read0read               |       8.19496155 |
| memory/mysys/KEY_CACHE                |       8.00215149 |
| memory/innodb/sync0arr                |       7.03147125 |
| memory/innodb/ha_innodb               |       6.87006950 |
| memory/innodb/lock_sys                |       5.25009155 |
| memory/sql/log_sink_pfs               |       5.00003052 |
| memory/innodb/ut0pool                 |       4.00017548 |
| memory/sql/dd::objects                |       2.83031464 |
| memory/innodb/std                     |       2.72618866 |
| memory/innodb/os0file                 |       2.63054657 |
| memory/innodb/os0event                |       2.34302521 |
| memory/sql/TABLE_SHARE::mem_root      |       2.31734467 |
| memory/innodb/trx0trx                 |       2.22647858 |
| memory/temptable/physical_ram         |       1.00003052 |
| memory/sql/dd::String_type            |       0.94942093 |
| memory/innodb/btr0pcur                |       0.89743423 |
+---------------------------------------+------------------+


Plus I used PMM to collect memory information 
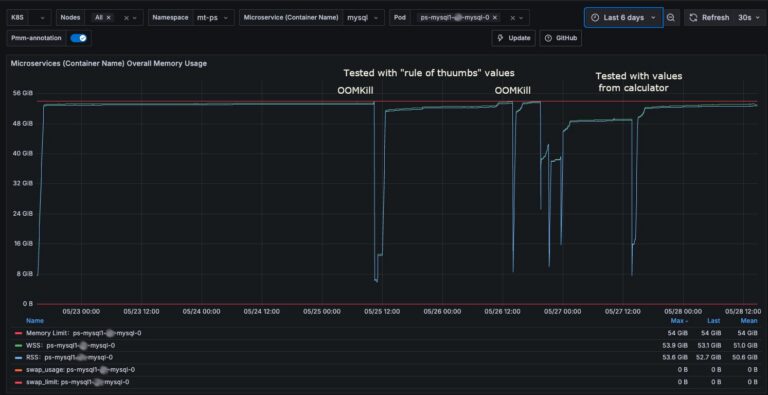
To simulate the load I used the sysbench-tpcc (tpc-c derivate test) variant and run the tests simulating a load of 1024 threads against a cluster based on machine with 16 Core and 64Gb volumes ~3k IOPS, so not gigantic but not small. 


The finding was almost immediate:

+---------------------------------------+------------------+
| EVENT_NAME                            | current_usage_mb |
+---------------------------------------+------------------+
| memory/innodb/buf_buf_pool            |   46398.92578125 |
| memory/group_rpl/certification_info   |    1431.67934418 | <constantly increasing
| memory/group_rpl/GCS_XCom::xcom_cache |    1066.63542366 |
| memory/sql/Gtid_set::Interval_chunk   |      95.52413940 |
| memory/innodb/log_buffer_memory       |      64.00096130 |
| memory/sql/TABLE                      |      48.17613125 |
| memory/innodb/memory                  |      35.08897400 |
| memory/innodb/ut0link_buf             |      24.00006104 |
| memory/innodb/lock0lock               |      21.40064240 |
| memory/innodb/read0read               |      14.86782837 |
| memory/mysqld_openssl/openssl_malloc  |      12.05916119 |
| memory/mysys/KEY_CACHE                |       8.00215149 |
| memory/innodb/sync0arr                |       7.03147125 |
| memory/innodb/ha_innodb               |       6.84074974 |
| memory/innodb/lock_sys                |       5.25009155 |
| memory/sql/log_sink_pfs               |       5.00003052 |
| memory/innodb/ut0pool                 |       4.00017548 |
| memory/sql/dd::objects                |       2.82012177 |
| memory/innodb/std                     |       2.72515869 |
| memory/innodb/os0file                 |       2.63054657 |
| memory/innodb/os0event                |       2.35884857 |
| memory/innodb/trx0trx                 |       2.22647858 |
| memory/sql/TABLE_SHARE::mem_root      |       1.83777618 |
| memory/innodb/trx0undo                |       1.26304626 |
| memory/mysys/lf_node                  |       1.08828735 |
+---------------------------------------+------------------+


Ok then … What is the certification info???

What is group_rpl/certification_info?

In MySQL, memory/group_rpl/certification_info is a Performance Schema memory instrument. It tracks the exact amount of RAM allocated to store the Certification Database (or Certification Info).

In Group Replication, nodes do not lock rows across the network while a transaction is executing. Instead, transactions execute locally and optimistically. When it is time to commit, the transaction undergoes a Certification Process to ensure no other concurrent transaction in the cluster has modified the exact same rows. The certification_info buffer is the in-memory hash map that makes this conflict detection possible.

1. What is it used for?

The certification_info structure acts as a tracking ledger for recently modified rows.

Here is how it works under the hood:

  • The Key-Value Pair: It is fundamentally an in-memory dictionary. The key is the hash of a modified row (extracted from the transaction’s “write set”), and the value is the Global Transaction Identifier (GTID) of the transaction that successfully modified it.
  • Conflict Detection: When a new transaction attempts to commit, it broadcasts its write set and the “snapshot version” of the database it saw when it started. The certifier cross-references the incoming transaction’s write set against the certification_info map.
  • The Decision: If the certification_info shows that a row was modified by a newer GTID that the incoming transaction did not “see” when it started, a conflict is flagged, and the transaction is aborted. If no conflict exists, the transaction is certified, and the certification_info map is updated with the new write set and GTID.

The primary does not hold onto this memory out of stubbornness; it does so because purging that data too early would destroy the cluster’s consistency in the event of a failover.


In Group Replication, garbage collection for the certification_info buffer is not triggered just because a transaction commits on the primary. It is triggered by a concept called the Stable Set. 

Every node in the cluster periodically broadcasts a message to the rest of the group saying, “Here are the GTIDs I have successfully applied to my disk.” The cluster then calculates a global low watermark. This watermark is the highest transaction GTID that every single member of the group has successfully applied. Garbage collection is only allowed to purge write-sets from the certification database that fall below this global watermark.
To note that this purge is a synchronous operation during which writes are forbidden.

2. How the Apply Queue Stalls the Watermark

When a secondary node starts lagging, its applier queue grows. This means the secondary is receiving transactions from the network quickly, but its SQL thread is too slow to actually execute them and commit them to disk.

Because the secondary hasn’t applied these transactions, it cannot report those GTIDs back to the group as “finished.”

  • The lagging secondary’s local watermark stalls.
  • Therefore, the global low watermark for the entire cluster stalls.
  • Because the global watermark hasn’t moved forward, the garbage_collect function on the primary (and all other nodes) says, “I am not allowed to delete any write-sets yet.”
  • As the primary continues to process new writes, the certification_info memory buffer grows continuously.

3. Why the Primary Cannot Purge Early

we might wonder: If the transaction is already committed on the primary, why does the primary care if the secondary has applied it? Why not just drop the write-set from its own memory?

The answer comes down to Failover Safety and Distributed Conflict Detection. GR is a shared-nothing, decentralized architecture. Even if you are running in Single-Primary  mode (keep this in mind will be important later), the underlying engine uses the exact same logic as Multi-Primary mode. 

Here is why the primary is forbidden from purging that data:

  • The Failover Scenario: Imagine our primary node crashes right now. The lagging secondary (which still has a massive apply queue) is immediately elected as the new primary.
  • The Conflict Risk: As the new primary, it starts accepting new writes from your application. However, it still has thousands of old transactions in its applier queue that it hasn’t written to disk yet!
  • The Necessity of the Buffer: When a new write comes in, the new primary must check if that write conflicts with any of the pending transactions in its apply queue. It does this by checking the certification_info map. If the old primary had purged the global certification data early, the new primary wouldn’t have the write-sets for those pending transactions. It would blindly accept the new write, causing a massive data conflict and breaking the replication group entirely.

Fine Marco, then what is the effect of this?


Well, drums roll …

… When a secondary node is elected as the new primary during a failover, it does not immediately open the floodgates to new writes. It keeps its super_read_only variable set to ON until it has completely drained its local apply queue of all transactions that were certified prior to the election.

This is an intentional design choice to guarantee that the new primary’s state is completely consistent with the old primary before it starts accepting new data.


4. Immediate Write Rejections (No Built-in Queuing)

The most critical impact to understand is that the new primary does not queue or pause new incoming writes while it catches up. It outright rejects them.

If our application or proxy routes a COMMIT, INSERT, UPDATE, or DELETE to the new primary while it is still processing the old queue, MySQL will immediately throw an error back to the client:

ERROR 1290 (HY000): The MySQL server is running with the –super-read-only option so it cannot execute this statement

5. The “Brownout” Window (Write Outage)

Because of this behavior, a failover in MySQL Group Replication does not instantly restore write availability. Our cluster experiences a “brownout”, a period where reads might succeed, but writes are entirely blocked.

The duration of this write outage is directly proportional to the size of the apply queue.

  • If the secondary was fully caught up, write availability is restored in milliseconds.
  • If the secondary was lagging by 50 minutes, your application will suffer a 50 minute write outage while the node applies the backlog.

6. Impact on Proxies (e.g., MySQL Router or ProxySQL)

If we are using a proxy layer to route your database traffic, the apply queue dictates how the proxy behaves during the transition:

  • MySQL Router: It continuously monitors the cluster topology and the super_read_only flag. Even though the node has technically been elected primary, Router will not open the read-write port to it until the apply queue drains and super_read_only flips to OFF. Depending on your application timeouts, client connections will either hang waiting for a writable connection or fail completely.
  • ProxySQL: Similar to Router, if it is configured to check for the read_only state, it will temporarily quarantine the new primary from the write hostgroup.
  • HAProxy (in Operator): Monitor both Primary state and read_only state, but it expose the Primary to writes causing the application to fail (bug we need to fix)  

7. Read Traffic and Stale Data

During this catch-up phase, the node will accept incoming SELECT queries (since it is still a valid database). However, because it is actively churning through the old primary’s backlog, the data being read is temporarily stale.

If your application reads a row that is sitting in the apply queue but hasn’t been committed to disk yet, it will get the old version of that row.

Why Flow Control is Critical

Because a large apply queue turns a seamless failover into a severe, application-breaking write outage, Group Replication includes the Flow Control feature.

Flow Control monitors the size of the apply queues across all secondaries. If a secondary starts lagging too far behind, Flow Control should actively throttle the write throughput on the current primary to allow the lagging node to catch up. It is essentially a trade-off: we accept a slight performance hit during normal operations to guarantee that your database recovers almost instantly during a failover.

However, this is not what really happens.

1. It is Reactive, Not Proactive (The Polling Blind Spot)

Flow control does not intercept and evaluate every single transaction in real-time. Instead, it relies on a periodic polling interval governed by group_replication_flow_control_period (which defaults to 1 second).

Once a second, the cluster checks the size of the apply queues and the certifier queues.

  • The Vulnerability: If our application generates a massive spike of 50,000 writes in 500 milliseconds, the primary will happily accept and certify all of them. Flow control will not even notice the spike until the next 1 second polling interval hits. By the time it decides to apply a throttle, the damage is already done, and the secondary’s queue is already overflowing.

2. The PID Controller’s “Soft Brake” Math

When flow control does decide to throttle, it does not simply freeze the primary. It uses a PID (Proportional-Integral-Derivative) controller algorithm to calculate a “write quota” (the maximum number of transactions the primary is allowed to commit in the next second).

The PID controller is deliberately tuned to be gentle. It wants to gracefully degrade performance rather than cause immediate application timeouts.

  • When the secondary’s queue breaches the group_replication_flow_control_applier_threshold (default 25,000 transactions), the PID controller reduces the primary’s quota incrementally.
  • The Failure Point: If the primary’s incoming write rate is astronomically higher than the secondary’s disk IO capacity, this incremental “step down” in the quota is too slow. The primary is still allowed to write, say, 10,000 transactions per second, while the secondary is only applying 2,000. The queue continues to grow aggressively despite the throttle being “active.”

3. The Concurrency Mismatch (Parallel vs. Serial)

This is often the silent killer that defeats flow control. Flow control makes mathematical assumptions about how fast the secondary should be able to apply transactions based on recent history.

However, the primary node might be executing writes using hundreds of highly concurrent threads. The secondary relies on the parallel applier to keep up. If the incoming workload suddenly includes transactions that cannot be parallelized, such as writes hitting overlapping rows, cascading foreign key updates, or DDL statements, the secondary’s applier instantly drops from executing in parallel down to a single, serialized thread.

When this serialization happens, the secondary’s applier rate plummets instantly. Flow control, which only checks in once a second and adjusts gradually, cannot brake the primary fast enough to compensate for the secondary suddenly dropping to a crawl.

What can we do?

At the moment of writing there are only two things that can be done.

  1. Make Flow control more aggressive
  2. Increase the number of replication appliers


1. Making Flow Control More Aggressive

We can configure Flow Control to be a bit more aggressive. It will still remain a suggestion but a strong one.

How it works (The Configuration):

  • Lower the Threshold: By reducing group_replication_flow_control_applier_threshold (default is 25,000) to something like 1,000 or 500, we force the PID controller to kick in almost immediately when a spike occurs.
  • Remove the Safety Net: By keeping  group_replication_flow_control_min_quota to 0 (default), we remove the minimum write guarantee. If the secondary falls behind, Flow Control is allowed to throttle the primary’s writes down to zero, also if this will never happen.
  • Increase the Sensitivity: We can tweak the PID controller’s math (using the derivative and proportional tuning variables) to react much more aggressively to queue growth.
          group_replication_flow_control_hold_percent=100
          group_replication_flow_control_release_percent=5


The reality check, does it work?:

If the expectation is to have a rigid control over the applier queue on the lagging secondary, then the answer is NO. No matter what, at the moment flow control is not designed to act as we are used to in PXC (Percona Xtradb Cluster), where we have a rigid control of the pending queue also at the cost of delaying the writes. In Group Replication  the Flow Control will never bring the write to 0, the unfortunate aspect is that the mechanism is not enough to keep the queue under control.


2. Increasing Replication Appliers 

To help the secondary chew through the queue faster, we can increase the number of parallel threads it uses to write to disk.

How it works: We can increase the replica_parallel_workers (formerly slave_parallel_workers) setting. GR is exceptionally smart about this. Because of the certification process we discussed earlier, GR already knows exactly which transactions modify which rows. It uses a writeset-based dependency tracker to safely hand off non-conflicting transactions to multiple worker threads simultaneously.
The formula that is normally used to calculate the number of replication workers is to set 2.5 workers for each available core. IE if we have 14000m CPUs in our CR (K8) then we can assign ~35 workers, this is definitely higher than the default value of 4.   

The reality check, does it work?Yes, but only if our workload allows it.

  • The Catch – The Serialization Wall: Parallel appliers only work if the transactions do not conflict. If our application has 50 concurrent threads all trying to update the same “inventory count” row, or updating a highly contentious table, those transactions cannot be parallelized. The secondary’s coordinator thread will see the row-level conflicts and force those transactions to wait in line and execute sequentially. We could allocate 128 parallel workers, but 127 of them will sit idle while one thread does all the work.
  • The Catch – Context Switching: More threads do not magically create more disk IOPS. If we set the workers too high (e.g., beyond the physical CPU core count or disk IO capacity), the secondary’s InnoDB engine will spend more time context-switching and fighting over internal mutex locks than actually committing data. In many cases, over-allocating parallel workers actually slows down the apply rate.

Do we have any conclusions?

1. If HA is the goal, enforce Strict Flow Control

If our absolute top priority is High Availability, specifically achieving a near-zero Recovery Time Objective (RTO), we must configure an aggressive flow control.

  • The Logic: Fast failovers require small apply queues. To guarantee a small apply queue, we must strictly throttle the primary the millisecond the secondary starts to lag.
  • The Trade-off: we are protecting the cluster’s failover readiness at the expense of application write latency. If there is a massive write spike, our application will face timeouts and connection errors, but if the primary server suddenly catches fire, our database will recover and elect a new primary almost instantly.

The problem is that Group Replication is not able to act like that today, this is something we eventually need to implement to have better HA.

2. If Performance is the goal, relax Flow Control

If our top priority is keeping the application fast and ensuring COMMIT latencies remain extremely low, we should relax flow control or rely on the generous defaults.

  • The Logic: By relaxing flow control, we allow the primary to run at the absolute maximum speed its local disks and CPU allow. It does not care if the secondaries fall behind. Our application users remain happy and experience zero throttling.
  • The Trade-off: We are accepting severe risks to your HA posture. If the primary crashes while the secondaries have a massive apply queue, we will suffer a long write outage (the brownout) while the new primary catches up. Additionally, we are accepting the risk that the certification_info memory buffer will grow significantly on the primary and eventually have the pod OOMKilled .

3. Is this not what Asynchronous replication with semy-sync offers?


1. The Similarities

If we look purely at how a single transaction flows and how a failover behaves, GR and Semi-Sync look like twins:

  • The Durability Guarantee: Semi-Sync: The primary waits to commit until at least one secondary confirms it has received the transaction and written it to its local Relay Log. 
    • GR: The primary waits to commit until a majority quorum of nodes confirm they have received the transaction, certified it, and written it to their local relay logs.
  • The Failover Delay (The Queue):  In both systems, the secondary receiving the data does not mean the secondary has applied the data to its InnoDB tables.
    • If a crash happens, both systems require the new primary to completely execute its pending queue (Relay Log for Semi-Sync, Apply Queue for GR) before it is safe to accept new writes.

2. The Crucial Differences

If they behave so similarly, why use GR at all?
The differences lie entirely in automation, consensus, and split-brain protection. Semi-Sync is just a data transport mechanism; GR is a full state-machine cluster.

Here is what GR gives you that Semi-Sync does not:

  • Automatic Election and Orchestration:
    • Semi-Sync: If the primary dies, Semi-Sync does nothing. The cluster sits there broken. You must rely on external tools (like Orchestrator or manual DBA intervention) to detect the crash, pick the most up-to-date secondary, wait for its relay log to apply, disable read_only, and re-point the application.
    • GR: The cluster detects the failure natively. The remaining nodes use Paxos consensus to elect a new primary automatically, manage the queue drain natively via the super_read_only flip we discussed, and self-heal.
  • Split-Brain Protection (Network Partitions):
    • Semi-Sync: If our network splits in half, an external failover tool might accidentally promote a secondary while the old primary is still alive and accepting writes. We now have a split-brain, and our data is permanently corrupted.
    • GR: GR enforces strict quorum. If a network split happens, the side of the network with the minority of nodes will automatically fence itself off and refuse all writes. Split-brain is mathematically prevented.
  • The Certification Database:
    • As we established, GR requires the certification map to ensure the new primary doesn’t accept writes that conflict with its unapplied queue. Semi-Sync does not have this; it relies entirely on the external failover tool to guarantee no writes touch the new primary until the relay log is 100% applied.

3. Final observation

If we are using Single-Primary GR with relaxed flow control, we have essentially built a highly-automated, consensus-driven version of Semi-Sync replication. 

We have the exact same apply-queue bottleneck during failover, but we have traded the need for external orchestrator tools for built-in Paxos consensus and native split-brain protection.


Conclusions (for real)

When we run MySQL on a traditional, dedicated Virtual Machine, memory limits are “soft.” If the certification_info database explodes and consumes an extra 10GB of RAM because of the applier lag, the Linux OS might start aggressively swapping inactive pages to disk, but the MySQL process usually survives. Performance degrades, but the database stays online.

In Kubernetes, memory limits are “hard.” As we discussed earlier, Kubernetes enforces pod memory limits via cgroups v2 (memory.max). The Linux kernel’s OOM Killer has no understanding of database quorum, failover states, or apply queues. It only sees math: Working Set Size > memory.max = Terminate Process (Exit Code 137).

The Chain Reaction of Relaxed Flow Control in k8s

If we prioritize “performance” by relaxing Flow Control in a Kubernetes environment, we are essentially setting a ticking time bomb. Here is the chain of events:

  1. The Spike: Our application experiences a massive write spike.
  2. The Queue: The secondary pod’s disk cannot keep up, and its applier queue grows to 1,000,000 transactions.
  3. The Memory Sprawl: Because the queue is large, the global low-watermark stalls. The Primary pod is forbidden from garbage collecting the certification_info map. The in-memory hash map balloons in size.
  4. The Execution: The memory.current metric will reach the memory.max, kernel will trigger the OMMKill process. First action will be to try to free the page.cache related to the process. If the purge is successful and the memory.current is less than memory.max then the process will persist, otherwise the kernel will kill it.
    We can use the WSS metric to predict a successful OMMKill.
    The Primary pod’s Working Set Size (WSS) breaches its Kubernetes memory limit, this is a fair estimate not an absolute value.
  5. The Catastrophe: The Linux OOM Killer instantly assassinates the Primary MySQL process.

Because we tried to avoid a few seconds of write latency by keeping relaxed Flow Control, we inadvertently caused a hard crash of the primary database pod, with long write downtime.

The Architectural Law

Therefore, here is my statement as architectural law for containerized environments: In Kubernetes, High Availability and Pod stability are so intrinsically linked that Flow Control must act as hard as it can to cap the apply queue.

  • We cannot allow unbounded memory growth in a container. The only way to bound certification_info memory is to bound the apply queue.
  • The only way to bound the apply queue is with strict, aggressive Flow Control.
  • Increasing the number of replication appliers helps but is not the conclusive answer.

In a Kubernetes environment, we must tune group_replication_flow_control_applier_threshold to a strict, low number, and accept that during massive traffic spikes, our application will experience write throttling. It is infinitely better for our application’s connection pool to wait 2 seconds for a COMMIT to succeed than for the primary database pod to be violently OOMKilled by the kernel, and have to wait for minutes or hours to recover write capabilities.

Note

Just as a mention this is exactly how Percona Operator with Percona Xtradb Cluster works. To be more specific, PXC and in general solutions based on Galera have a Flow Control mechanism that enforces the queue to be inside hard limits. While this more invasive control may be noticeable at application level, it guarantees that the other nodes are not lagging behind the primary and this is why it is a stronger HA solution in the Kubernetes environment.


Reference

https://github.com/Tusamarco/mysqloperatorcalculator

Managing Resources and OOMKills: Resource Management for Pods and Containers (This page details how memory limits are enforced reactively by the Linux kernel via OOM kills).

How WSS triggers Evictions: Node-pressure Eviction (This page explicitly details how the kubelet uses the memory.available signal, which is derived from node capacity minus the working set size).

Latest changes. Pointer to the code 

Swap Memory Management (Core Concepts & Configuration): https://kubernetes.io/docs/concepts/cluster-administration/swap-memory-management/

The post The Failover Brownout: Rethinking High Availability in MySQL Group Replication appeared first on Percona.
Jun
09
2026
--

Percona Operator for MySQL (PXC) 1.20.0: Automatic Storage Resizing, TLS Certificate Rotation, and ARM64 Support

Percona Operator for MySQL PXC 1.20.0 is out today, and it addresses three long-requested operational headaches: storage that grows on its own before it fills up, TLS certificates that rotate without cluster downtime, and images that run natively on ARM64.

Disk-full incidents on PXC clusters often arrive at 2 AM when monitoring alerts fire, and someone has to manually expand PVCs before writes grind to a halt. Certificate rotations have traditionally meant a carefully timed series of kubectl edits with real downtime risk. And ARM64 hardware has been increasingly common in dev clusters and cost-optimized cloud node pools, where x86-only images created extra friction. 1.20.0 addresses all three in a single release.

The operator is open source and runs on any CNCF-conformant Kubernetes distribution, including GKE, EKS, AKS, and OpenShift. It supports Kubernetes 1.33 through 1.36 and PXC 8.4, 8.0, and 5.7.


In this post, you’ll learn about:

  • Automatic PVC storage resizing with configurable thresholds and a hard cap
  • Zero-downtime TLS certificate rotation via a new Secret naming convention
  • Native ARM64 support across all operator images
  • PITR validation that catches misconfigured targets before restores begin
  • Configurable leader election for high-latency or unstable networks
  • Other improvements in this release


Automatic Storage Resizing


Why it matters

A full data volume is the most common cause of unplanned maintenance on a PXC cluster. Until now, avoiding it required external monitoring, manual kubectl patch pvc steps, and waiting for the storage class to honor the resize. Even with good alerting, the operator itself had no mechanism to react: it could only expand PVCs when you changed the spec by hand.

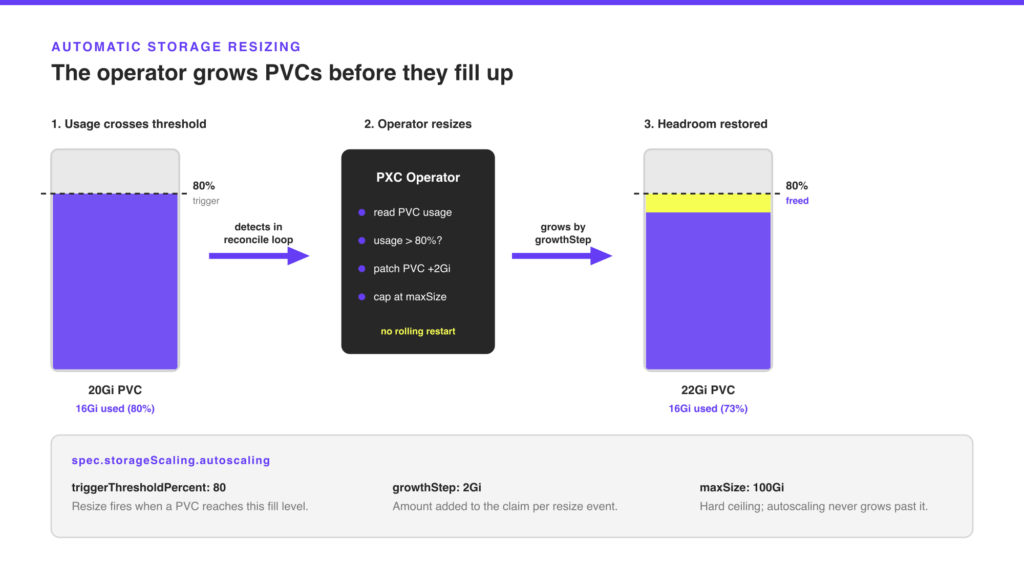
1.20.0 introduces built-in storage autoscaling. The operator polls each PVC’s actual disk usage, and when usage crosses a configured threshold, it automatically expands the claim. You set the trigger percentage, the step size per resize event, and an optional upper bound. The operator handles everything else.


How it works

The autoscaler runs inside the normal reconcile loop. It reads status.capacity.storage from each PXC PVC, compares current usage against triggerThresholdPercent, and issues a PVC resize when the threshold is crossed. It sets a percona.com/pvc-resize-in-progress annotation on the CR while an expansion is active. This annotation blocks concurrent rolling restarts or upgrades from starting, so nothing disrupts the cluster mid-resize.

You can also set enableExternalAutoscaling: true if an external tool, such as KEDA, already manages PVC sizes for your cluster. When you enable external autoscaling, the built-in loop skips its resize check entirely to avoid conflicts.


Wiring it up

Add storageScaling to your PerconaXtraDBCluster spec:

apiVersion: pxc.percona.com/v1
kind: PerconaXtraDBCluster
metadata:
  name: cluster1
spec:
  crVersion: 1.20.0
  storageScaling:
    enableVolumeScaling: true
    autoscaling:
      enabled: true
      triggerThresholdPercent: 80   # resize when a PVC is 80% full
      growthStep: 2Gi               # add 2Gi per resize event
      maxSize: 100Gi                # never grow beyond 100Gi per PVC
#     enableExternalAutoscaling: false

Any PVC expansion requires enableVolumeScaling: true, whether the autoscaler or a manual spec change triggers it. Setting autoscaling.enabled: true enables the threshold-based path on top of that. Leave the autoscaling block out if you only want to permit manual spec-driven resizes.


Caveats

Storage expansion requires a StorageClass with allowVolumeExpansion: true. Check before enabling:

kubectl get storageclass \
  -o jsonpath='{range .items[*]}{.metadata.name}{"\t"}{.allowVolumeExpansion}{"\n"}{end}'

Autoscaling applies only to PXC data volumes. If your storage class or CSI driver handles expansion externally, use enableExternalAutoscaling: true to prevent the two mechanisms from racing.


Automated TLS Certificate Rotation

Why it matters

Rotating TLS certificates on a live PXC cluster has always carried risk. The Galera protocol requires all nodes to trust each other’s CA simultaneously. Swap the CA on one node before the others accept it, and inter-node communication breaks. The safe approach requires a three-phase CA swap with rolling restarts between each phase: a process that is easy to get wrong under time pressure.

1.20.0 formalizes this into a first-class operator workflow. Create a Secret named <ssl-secret>-new containing the replacement credentials, and the operator runs the full three-phase rotation automatically, pausing for rolling restarts between each step.


How it works

The rotation proceeds in three steps that the operator coordinates:

  1. Combined CA phase. The old CA and new CA are merged into a single ca.crt and pushed to all nodes. Every node now trusts both roots.
  2. New leaf phase. The new tls.crt and tls.key are pushed node by node with a rolling restart. New leaf certs are signed by the new CA, and the combined CA means all nodes trust them.
  3. New CA only phase. The combined ca.crt is replaced with the new CA only. The old root is removed. Another rolling restart completes the rotation.

When step 3 completes, the operator automatically deletes the -new Secret. The cluster never loses TLS connectivity between nodes during the process.


Wiring it up

Given a cluster named cluster1 using the default SSL Secret cluster1-ssl, create the replacement:

kubectl create secret generic cluster1-ssl-new \
  --from-file=ca.crt=new-ca.crt \
  --from-file=tls.crt=new-server.crt \
  --from-file=tls.key=new-server.key

You do not need to change the PerconaXtraDBCluster CR. The operator detects the -new Secret on the next reconcile and starts the rotation. No kubectl patch on the CR, no operator restart.


Caveats

The operator does not yet surface rotation progress in .status.conditions. Monitor the rotation by watching PXC pods restart in sequence and checking that the -new Secret is eventually gone:

kubectl get pods -w -l app.kubernetes.io/component=pxc
kubectl get secret cluster1-ssl-new  # should 404 when rotation is complete


ARM64 Support


Why it matters

AWS Graviton3, Google Axion, and Azure Cobalt100 instances deliver better price-to-performance on memory-intensive workloads like PXC. Previously, running the operator on ARM64 nodes required cross-architecture scheduling workarounds or explicit node exclusions for operator pods. All PXC operator images now publish native linux/arm64 layers alongside nodeSelector


What is covered

Every image in the PXC operator stack ships multi-arch manifests in 1.20.0:

  • The operator manager image
  • The PXC xtrabackup sidecar
  • The log collector (Fluentbit-based)
  • The init container

This release also fixes a logrotate crash on ARM64 (K8SPXC-1821) that a missing dependency in the ARM64 container layer caused. 1.20.0 ships the fix.
 

Wiring it up

You do not need any configuration change. Pull the 1.20.0 operator image and Kubernetes schedules it on whichever architecture is available. To pin PXC pods explicitly to ARM64 nodes, add a nodeSelector or node affinity in the spec.pxc block:

spec:
  pxc:
    nodeSelector:
      kubernetes.io/arch: arm64


Other Improvements

  • PITR target validation before restore begins (K8SPXC-1318, K8SPXC-1634, K8SPXC-1635, K8SPXC-1793): The operator now validates PITR targets (type, GTID, timestamp) against available binary logs before starting a restore. It catches a misconfigured target before it pauses the cluster, rather than after.
  • Configurable leader election (K8SPXC-1805): Three new environment variables tune leader election timing for high-latency or flaky network environments.
  • SST retry limit (K8SPXC-1619): A new spec.pxc.sstRetryCount field caps the number of State Snapshot Transfer retry attempts, preventing a node that repeatedly fails SST from looping indefinitely.
  • Custom logrotate configuration (K8SPXC-1789): Supply a custom logrotate config via a ConfigMap reference in spec.logcollector.logRotate for fine-grained control over log rotation for PXC and utility containers.
  • Enhanced full cluster crash recovery (K8SPXC-1828): 1.20.0 hardens the crash recovery path to prevent potential data loss after sudden node power-offs.


Deprecation notice: PMM2 monitoring integration is deprecated in 1.20.0. Migrate to PMM 3 before version 1.22.0, when PMM2 support will be removed.


Conclusion

PXC Operator 1.20.0 turns three previously manual steps into operator-managed concerns: disk growth, certificate rotation, and ARM64 scheduling. Combined with PITR validation improvements and configurable leader election, this release reduces the operational surface area for clusters running under production pressure. If you run into edge cases with automatic storage resizing or TLS rotation, the community forum is the right place to share them.


Try It Out


The post Percona Operator for MySQL (PXC) 1.20.0: Automatic Storage Resizing, TLS Certificate Rotation, and ARM64 Support appeared first on Percona.
May
28
2026
--

Percona Operator for PostgreSQL 3.0.0: Hard Fork, OLM Scoping, Major Upgrades


The Percona Operator for PostgreSQL 3.0.0 is here. This is the release that completes the hard fork of the operator from the Crunchy Data PostgreSQL Operator into a fully independent project, with a dedicated upstream.pgv2.percona.com API group for the inherited CRDs, an automatic CRD-rename rollout for existing 2.x installs on upgrade, and a public roadmap that drives what comes next.

This release ships three headline changes that matter for production teams. The CRD renaming under a Percona-owned API group, which finally lets the Crunchy operator and the Percona operator coexist in the same Kubernetes cluster. Proper OLM namespace scoping for OpenShift installations. And the move to the official Percona Distribution image for major PostgreSQL version upgrades, aligning the upgrade path with the same binaries that run in your clusters.


All three land in service of the same goal: making 3.0.0 a clean, durable operational baseline for the operator’s next several years as an independent project. Future releases will be shaped by what the community asks for and contributes back. The public roadmap is the durable signal of that commitment.

In this post, you will learn about:

  • The hard fork and how the CRD rename unlocks coexistence with the Crunchy operator
  • OLM namespace-scoping improvements for OpenShift installations
  • The move to the official Percona Distribution image for major PostgreSQL version upgrades
  • Other improvements and the 2.7.0 deprecation
  • Supported PostgreSQL versions and platforms


Hard fork: CRDs renamed under upstream.pgv2.percona.com

The Percona Operator for PostgreSQL has, until now, been a soft fork. Custom Resources inherited from Crunchy PGO used the upstream postgres-operator.crunchydata.com API group. The two operators shared CRDs, which meant you could only run one of them in a given Kubernetes cluster. Installing both would lead to overlapping CRDs, conflicting webhooks, and finalizer collisions, so platform teams had to pick a side before they had finished evaluating.

Starting with 3.0.0, every inherited CRD is renamed into a new dedicated upstream.pgv2.percona.com API group (K8SPG-1007). Percona’s own native CRDs (such as PerconaPGCluster under pgv2.percona.com/v2) are unchanged. The change applies to the inherited resources: PostgresCluster, PGUpgrade, PGAdmin, and the rest.


Coexistence: running both operators in the same cluster

The practical effect is that the Crunchy Data PostgreSQL Operator and the Percona Operator for PostgreSQL can now run on the same Kubernetes cluster at the same time, even in the same namespaces, with no CRD or webhook conflict. That unlocks a few real workflows: evaluating both operators on the same staging cluster without spinning up a second cluster, running existing Crunchy-managed clusters in some namespaces while bringing up new Percona-managed clusters in others, or testing a new database version on the Percona side while production stays on Crunchy until you are confident. The choice between the two operators stops being all-or-nothing.


Upgrade behavior for existing 2.x installs

For an existing install, the upgrade to 3.0.0 is mechanically simple. The operator creates the new-API-group CRDs alongside the legacy ones, then runs a one-time migration that updates dependent objects (Secrets, certificates, finalizer references) to point at the new CRD instances. Existing custom resources keep working through the legacy CRDs during the transition, and once migration completes, all reconciliation moves to the new group.

Old PostgresCluster reference:

apiVersion: postgres-operator.crunchydata.com/v1beta1
kind: PostgresCluster
metadata:
  name: cluster1


New (after upgrade to 3.0.0):

apiVersion: upstream.pgv2.percona.com/v1beta1
kind: PostgresCluster
metadata:
  name: cluster1


Day-to-day, your PerconaPGCluster Custom Resource (the one most teams interact with directly) is unchanged. The rename mostly matters in three situations: when a kubectl filter or a GitOps repository hard-codes the old API group, when a CI pipeline references the legacy CRD by name, and when you run the Percona and Crunchy operators side by side and need them not to collide.

Note: During the CRD migration on upgrade, the release notes report brief disruptions to pgBackRest operations (typically 1 to 2 minutes) while Kubernetes propagates certificate changes. Plan the upgrade during a maintenance window if backup continuity is critical, or pause scheduled backups during the upgrade.

Full details on the API-group change are in the Percona PostgreSQL operator documentation.


Improved OLM namespace scoping for OpenShift

OpenShift users install operators through the OpenShift Lifecycle Manager (OLM), and OLM enforces an OperatorGroup to scope which namespaces an operator watches. In practice, 2.x had quirks: teams that selected “Single namespace” mode would sometimes see the operator reconciling CRs in other namespaces, and teams in “All namespaces” mode would sometimes see incomplete coverage when CRs were created in newly-added namespaces.

3.0.0 fixes this by aligning the operator’s namespace watch list with the OperatorGroup that OLM applies. All-namespaces installs watch all namespaces. Single-namespace installs respect the targetNamespaces set on the OperatorGroup.


Why it matters in shared infrastructure

For an OpenShift platform team running shared infrastructure, this distinction matters operationally. A typical setup has the database operator installed once in a platform namespace (such as openshift-operators) but expected to serve PerconaPGCluster resources owned by individual application teams in their own namespaces. If the operator over-reaches into namespaces it should not watch, RBAC noise multiplies. If it under-reaches, application teams file tickets about clusters that never reconcile. The 3.0.0 alignment with OperatorGroup semantics removes both failure modes.


OperatorGroup wiring

For users installing through OLM via the OpenShift web console, the install flow is unchanged. The fix is in how the operator’s reconciler interprets the OLM-supplied namespace scope after install. For users who manage OperatorGroups directly, a single-namespace install looks like this:

apiVersion: operators.coreos.com/v1
kind: OperatorGroup
metadata:
  name: percona-pg-operator-group
  namespace: postgres-prod
spec:
  targetNamespaces:
    - postgres-prod

And an all-namespaces install:

apiVersion: operators.coreos.com/v1
kind: OperatorGroup
metadata:
  name: percona-pg-operator-group
  namespace: openshift-operators
spec: {}

The empty spec: {} (or an OperatorGroup with no targetNamespaces) means “watch all namespaces” by OLM convention. The 3.0.0 operator now honors that.


Note: After you upgrade an existing 2.x install to 3.0.0, the operator may begin reconciling PerconaPGCluster resources in namespaces it had previously ignored due to the prior scoping bug. Audit existing CRs across your cluster before upgrading, especially if you have stale test clusters in unintended namespaces. The release notes call this out explicitly.

Note for community vs certified bundle users: Community OLM bundles did not support cluster-wide (all-namespaces) mode in earlier versions, 3.0.0 adds it. Certified bundles already supported cluster-wide mode, but they used a separate stable-cw channel for it with 3.0.0 the channels are unified, so users upgrading from a certified stable-cw install need to switch their subscription channel to stable to receive the upgrade.

For the full install workflow on OpenShift, see the OpenShift installation documentation.


Major PostgreSQL version upgrades now use the official Percona Distribution image


Major-version upgrades (for example, PostgreSQL 17 to 18) require running pg_upgrade, which needs binaries for both the source and target versions in the same environment. The operator has supported major-version upgrades since 2.x, but it shipped its own dedicated upgrade image to do so. That worked, but it meant a Percona-specific image lived in the upgrade path, separate from the same Percona Distribution for PostgreSQL build that runs in your clusters.


Switching to the official Percona Distribution image

In 3.0.0, the operator switches to using the official Percona Distribution for PostgreSQL image for major-version upgrades: percona/percona-distribution-postgresql-upgrade (current tag: 18.4-17.10-16.14-15.18-14.23-1, which encodes the bundled major versions). The benefit is alignment: the binaries that run pg_upgrade are the same binaries that ship in the corresponding percona-distribution-postgresql image you already run in production, built from the same source, signed the same way, and patched on the same schedule. The operator orchestrates the upgrade through the PerconaPGUpgrade Custom Resource that names the source and target versions, the upgrade image, and the target component images (PostgreSQL, pgBouncer, pgBackRest).


Running an upgrade through the PerconaPGUpgrade CR

A PostgreSQL 17 to 18 upgrade looks like this:

apiVersion: pgv2.percona.com/v2
kind: PerconaPGUpgrade
metadata:
  name: cluster1-17-to-18
spec:
  postgresClusterName: cluster1
  image: docker.io/percona/percona-distribution-postgresql-upgrade:18.4-17.10-16.14-15.18-14.23-1
  fromPostgresVersion: 17
  toPostgresVersion: 18
  toPostgresImage: docker.io/percona/percona-distribution-postgresql:18.4-1
  toPgBouncerImage: docker.io/percona/percona-pgbouncer:1.25.2-1
  toPgBackRestImage: docker.io/percona/percona-pgbackrest:2.58.0-2

Apply it with kubectl apply -f upgrade.yaml -n <namespace>. The operator reconciles the upgrade as a controlled, observable process: it brings the cluster down for the upgrade window, runs pg_upgrade from the bundled image, brings the cluster back up on the target version, and updates pgBouncer and pgBackRest images in the same step.

Operationally, this matters for teams running on PostgreSQL’s annual major-version cadence. Every September brings a new major release; staying on a supported version means executing one major upgrade per cluster per year. Pulling the upgrade image from the same percona-distribution-postgresql registry path as the runtime image means image-signature verification, mirror-to-private-registry rules, and CVE-scanning policies you already have in place apply to the upgrade flow without any per-image exception.

Note: The pgaudit extension is not upgraded automatically. After the operator completes the major version upgrade, drop and recreate pgaudit manually in each database that uses it: DROP EXTENSION pgaudit; followed by CREATE EXTENSION pgaudit;. The release notes call this out as a required step (K8SPG-1022). Also worth scanning for collation-dependent indexes after the upgrade and refreshing collation metadata with ALTER DATABASE <name> REFRESH COLLATION VERSION; per the upstream PostgreSQL 18 release notes.

Full procedure, prerequisites, and rollback notes are in the major version upgrade documentation.

Other Improvements

Operational polish landed alongside the headline changes:

  • Go 1.26 update (K8SPG-1019): the operator binary is now built with Go 1.26, picking up performance optimizations, tooling improvements, and the security fixes that landed in the Go runtime since the previous release.
  • pgaudit upgrade documentation (K8SPG-1022): the major-version upgrade docs now include an explicit pgaudit drop-and-recreate procedure, surfacing the gotcha that previously caught users mid-upgrade.

The release also defaults the cluster-upgrade documentation to PostgreSQL 18 across all examples and tutorials.


Supported software and platforms

The Percona Operator for PostgreSQL 3.0.0 is developed and tested on:

  • PostgreSQL: 14.23-1, 15.18-1, 16.14-1, 17.10-1, 18.4-1 
  • pgBackRest: 2.58.0-2
  • pgBouncer: 1.25.2-1
  • Patroni: 4.1.3
  • PostGIS: 3.5.6
  • PMM Client: 2.44.1-1 and 3.7.1


Supported Kubernetes platforms:

  • Google Kubernetes Engine (GKE) 1.33 to 1.35
  • Amazon Elastic Kubernetes Service (EKS) 1.33 to 1.35
  • OpenShift 4.18 to 4.21
  • Azure Kubernetes Service (AKS) 1.33 to 1.35
  • Minikube 1.38.1 (Kubernetes v1.35.1) for local development


Deprecation: 2.7.0 support dropped

Support for Custom Resource Definitions from operator version 2.7.0 has been removed. If you are still on 2.7.0, upgrade to 2.8.x or 2.9.x first, then upgrade to 3.0.0. The CRD migration described above only handles 2.8.x and 2.9.x to 3.0.0 transitions cleanly.


Conclusion

3.0.0 is the release where the Percona Operator for PostgreSQL becomes a fully independent project. The CRD rename removes the last upstream coupling that mattered operationally. The OLM scoping fix removes a long-standing OpenShift quirk. The official major-version upgrade image removes one of the more painful operational gaps in earlier versions.

Beyond the technical work, 3.0.0 is also where Percona’s commitment to community-driven development moves from intent to mechanism. The public roadmap is open. The issue tracker is open. The images are freely redistributable. Future releases will be shaped by what the community asks for, files, and contributes back. If there is a feature you want to see in 3.1.0 or 3.2.0, open an issue or a PR, that is where the work happens now.


Try It Out

The post Percona Operator for PostgreSQL 3.0.0: Hard Fork, OLM Scoping, Major Upgrades appeared first on Percona.
May
27
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Backup-Restore and PV Reuse


A Percona PostgreSQL operator pgBackRest restore is the simplest way to move off the Crunchy Data PostgreSQL Operator: take a full Crunchy backup, point the new Percona cluster’s dataSource at the existing pgBackRest archive, and the cluster bootstraps from it before its first start. This post covers that path, plus a second option, persistent-volume reuse, for cases where you want to skip the data copy entirely.

This is part 3 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0Part 2 covered the standby cluster method, the safest migration path when downtime budget is tight.

This post covers two simpler paths:

  • Backup and restore, the fastest if you can tolerate a short application-downtime window
  • Persistent volume reuse, when you want to skip the data copy entirely and keep the existing PGDATA

If you are landing here cold, start with part 1 for the why, then read Part 2 for the standby method. The rest of this post assumes you have already decided to migrate and want a tested playbook.

Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any S3-compatible service. Required for the backup-and-restore method, optional for PV reuse.
Tools kubectlhelm (v3)

Different versions may have slight differences in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


What this post does NOT cover

  • Application-side connection-string changes beyond updating to the new pgBouncer service
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations
  • Crunchy enterprise-only features like TDE or pgBackRest custom encryption
  • Operating two operators against the same namespace before the hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


1. Migration using backup and restore

This is often the fastest and simplest path, especially when you do not need a live standby. You take a full backup of the Crunchy source cluster, then create a Percona cluster that automatically restores from that backup before its first start.

Data written between the final backup and the application cutover is lost, so the migration window is the time between those two events. For a near-zero-downtime alternative, see part 2: standby cluster method.


Overview

Before you begin

Set the namespace once. Every command in this guide reads from this variable:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: "n" is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.

Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secrets.yaml:

# Copy and edit the file first to set your credentials.
kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/01-pgbackrest-secrets.yaml

Both contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket. The repo1-path value must match the path that will be referenced in the Percona dataSource.pgbackrest.global.repo1-path field.

Optional: deploy the Crunchy operator for testing. The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait

To start a fresh source cluster for testing, apply examples/02-crunchy-source-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/02-crunchy-source-cluster.yaml

The key pgBackRest settings:

global:
  repo1-path: /crunchy-to-percona/repo1   # source repo referenced in Percona dataSource
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1

Wait for the cluster and its pgBackRest stanza to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 2. Trigger a full backup (the migration cutover point)

This is the backup the Percona cluster will restore from. Stop accepting writes on the application side before triggering it to ensure a consistent snapshot, or accept that data written after this backup will be lost.

kubectl annotate postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"

kubectl wait job \
  --selector postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Deploy the Percona Operator

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s

Step 4. Create the Percona cluster from the backup

Apply examples/03-percona-restored-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/03-percona-restored-cluster.yaml

The key section that bootstraps the cluster from the Crunchy backup:

dataSource:
  pgbackrest:
    stanza: db
    configuration:
      - secret:
          name: percona-pgbackrest-secret
    global:
      # Must match repo1-path in the Crunchy source cluster exactly.
      repo1-path: /crunchy-to-percona/repo1
      repo1-s3-uri-style: path
      repo1-s3-verify-tls: "n"
    repo:
      name: repo1
      s3:
        bucket: pg-migration
        endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
        region: us-east-1

The Percona cluster’s own backup repository must use a different path from the Crunchy source:

backups:
  pgbackrest:
    global:
      repo1-path: /percona-restored/repo1   # different from Crunchy's path

As soon as the Custom Resource is applied, the cluster is bootstrapped from the storage referenced in dataSource and then started. Once the cluster becomes ready, you can immediately create new backups; in this case, repo1 from the backups section will be used as the target repository.

Wait for the cluster to reach ready state:

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify the data was restored successfully:

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f. The cluster is the primary and accepts writes.

Step 5. Verify the cluster is healthy

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Step 6. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery baseline on the Percona cluster’s own repository. All future PITR restores will use this backup, independent of the Crunchy archive.

Step 7. Reconnect your application

kubectl get service -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/role=pgbouncer

Step 8. Clean up the Crunchy cluster

Once the migration is verified and your application is connected to the new cluster:

kubectl delete postgrescluster crunchy-source -n $MIGRATION_NS
helm uninstall pgo -n $MIGRATION_NS


Rollback

Until Step 8, rollback is straightforward: switch the application connection string back to the Crunchy pgBouncer service. The Crunchy primary still holds the authoritative state because no writes were directed at the Percona cluster during the cutover (you stopped writes before Step 2). Any writes the application sent to the Percona cluster after cutover will not be present on Crunchy and would need to be replayed manually.

After Step 8, rollback requires restoring the Crunchy cluster from a backup, which is feasible because the original repo1 is still in the bucket.

Troubleshooting

archive.info missing. The repo1-path in dataSource.pgbackrest.global must match the Crunchy source cluster’s repo1-path exactly:

kubectl get postgrescluster crunchy-source -n $MIGRATION_NS \
  -o jsonpath='{.spec.backups.pgbackrest.global.repo1-path}'

kubectl get perconapgcluster percona-restored -n $MIGRATION_NS \
  -o jsonpath='{.spec.dataSource.pgbackrest.global.repo1-path}'


Restore job fails with TLS errors. pgBackRest requires HTTPS even with repo1-s3-verify-tls: "n". Verify SeaweedFS is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "


Cluster stuck in restoring state. Check the pgBackRest restore job logs:

kubectl logs \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/pgbackrest-restore=percona-restored \
  -n $MIGRATION_NS \
  -c pgbackrest

Data missing after restore. The restore captures data up to the latest backup. If post-backup data is critical, re-run the backup on the Crunchy cluster after quiescing writes, then delete and recreate the Percona cluster to restore from the newer backup.

2. Migration using existing persistent volumes

This method reuses the Crunchy primary’s PGDATA persistent volume directly. It avoids a full backup-restore cycle: you retain the Crunchy primary’s PV, delete the Crunchy cluster, then create a Percona cluster whose PVC binds to that same PV. PostgreSQL starts on the existing data directory without any restore step.

It is useful when:

  • you want to avoid copying data
  • your storage is very large
  • you must preserve the original data directory exactly
  • you removed the cluster but kept the PV


Overview


Before you begin

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS

Step 1. Deploy the Crunchy and Percona operators

Both operators run in the same namespace. Crunchy PGO is uninstalled during the migration once the PV is retained.

Note (Crunchy): The Helm install for Crunchy PGO below is shown only as a quick way to reproduce this blog post’s example. If you are running Crunchy PGO in production, follow the official Crunchy Data documentation for installation. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Note (Percona): The kubectl apply of the Percona operator below uses defult configuration of v3.0.0 from the operator repo for reproducibility of this guide. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation to ensure the cluster configuration is properly sized and configured for your workload and traffic requirements.

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

kubectl wait deployment pgo \
  -n $MIGRATION_NS --for=condition=Available --timeout=120s

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS --for=condition=Available --timeout=120s

Step 2. Start the Crunchy source cluster

If you already have a running Crunchy cluster with replicas: 1, proceed to Step 3.

To start a fresh cluster for testing:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/01-crunchy-source-cluster.yaml

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s

Step 3. Stop writes and identify the primary PV

Stop your application from writing to the database. This is the start of the downtime window. Then identify the primary pod, its PVC, and the backing PV:

PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -o jsonpath='{.items[0].metadata.name}')

PVC_NAME=$(kubectl get pod -n $MIGRATION_NS "${PRIMARY}" \
  -o jsonpath='{.spec.volumes[?(@.name=="postgres-data")].persistentVolumeClaim.claimName}')

PV_NAME=$(kubectl get pvc -n $MIGRATION_NS "${PVC_NAME}" \
  -o jsonpath='{.spec.volumeName}')

echo "Primary pod: ${PRIMARY}"
echo "PVC:         ${PVC_NAME}"
echo "PV:          ${PV_NAME}"

Step 4. Configure the source cluster to retain PVs

If you want to delete the Crunchy source cluster but keep the persistent volumes, the PV reclaim policy must be set to Retain. For dynamically provisioned PersistentVolumes, the default reclaim policy is Delete, which removes the data once there are no more PersistentVolumeClaims associated with the PV.

kubectl patch pv "${PV_NAME}" \
  -p '{"spec":{"persistentVolumeReclaimPolicy":"Retain"}}'

kubectl get pv -n $MIGRATION_NS

Delete the Crunchy cluster and uninstall PGO:

kubectl patch postgrescluster crunchy-source -n $MIGRATION_NS \
  --type=json -p='[{"op":"remove","path":"/metadata/finalizers"}]' 2>/dev/null || true

kubectl delete postgrescluster crunchy-source -n $MIGRATION_NS
helm uninstall pgo -n $MIGRATION_NS

After the PVC is deleted, the PV enters Released state. A Released PV retains its old claimRef and cannot be claimed by a new PVC until it is cleared:

kubectl patch pv "${PV_NAME}" --type=json \
  -p='[{"op":"remove","path":"/spec/claimRef"}]'

kubectl wait pv "${PV_NAME}" \
  --for=jsonpath='{.status.phase}'=Available \
  --timeout=60s

Label the PV so the Percona PVC selector binds to it exclusively. This prevents accidental binding to another available volume:

kubectl label pv "${PV_NAME}" percona-pv-migration=migrated


Step 5. Create the Percona cluster with the retained volume

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/02-percona-migrated-cluster.yaml

The key section that binds the PVC to the labelled PV:

instances:
  - name: instance1
    replicas: 1
    dataVolumeClaimSpec:
      selector:
        matchLabels:
          percona-pv-migration: migrated

The Percona Operator creates a PVC with that selector. The PVC binds to the labelled PV, and PostgreSQL starts on the existing PGDATA directory with no restore needed. pgBackRest uses a local PVC-backed repository (repo1.volume), so no S3 credentials or external storage are required, but you can use S3 storage as well.

Wait for the cluster to become ready and verify the data is intact:

kubectl wait perconapgcluster/percona-migrated \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-migrated,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f. The cluster is the primary and accepts writes.

Step 6. Scale up replicas

The cluster started with a single replica to reuse the migrated PV. Once the primary is healthy, drop the PVC selector and scale out so the operator can provision fresh replica volumes from the storage class:

kubectl patch perconapgcluster percona-migrated \
  --namespace $MIGRATION_NS \
  --type=json \
  -p='[
    {"op":"remove","path":"/spec/instances/0/dataVolumeClaimSpec/selector"},
    {"op":"replace","path":"/spec/instances/0/replicas","value":3}
  ]'

kubectl wait perconapgcluster/percona-migrated \
  --namespace $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=300s

Removing the selector here is important: leaving it in place would cause the new replica PVCs to fail provisioning because no other PV carries the migration label.

Step 7. Take a post-migration backup

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/03-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates the first backup on the Percona cluster’s local pgBackRest repository, establishing a baseline for future PITR restores.

Step 8. Reconnect your application

kubectl get service -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-migrated,postgres-operator.crunchydata.com/role=pgbouncer

Step 9. Cleanup

After the migration is verified, remove the migration label from the PV (Step 6 already removed the PVC selector that depended on it):

kubectl label pv "${PV_NAME}" percona-pv-migration-


Rollback

PV migration is the least rollback-friendly of the three methods. Once the Percona cluster has started writing to the PGDATA directory, the original Crunchy timeline is gone. If you need a way back, take a Crunchy-side pgBackRest backup before Step 4 and treat that backup as your rollback point. Recovery is then a fresh Crunchy cluster restored from that backup.

Troubleshooting

PVC stays in Pending state. The PVC selector did not match the labelled PV. Verify the label and PV phase:

kubectl get pv "${PV_NAME}" --show-labels
kubectl get pv "${PV_NAME}" -o jsonpath='{.status.phase}'

PostgreSQL fails to start (data directory errors). Check the database container logs:

kubectl -n $MIGRATION_NS logs "${PERCONA_PRIMARY}" -c database

If the Crunchy cluster was shut down uncleanly, there may be incomplete WAL. Patroni will attempt crash recovery automatically; check the logs for progress.

PV was deleted before setting Retain. If the PV was deleted along with the PVC (default Delete policy), the data is gone and PV migration is no longer possible. Use the backup-and-restore migration above, restoring from the most recent pgBackRest backup.


Conclusion

Two more migration paths from the Crunchy Data PostgreSQL Operator to the fully open-source Percona PostgreSQL Operator. Combined with Part 2, the series gives you three production-tested options:

  • Standby cluster (part 2): near-zero downtime via streaming replication and pgBackRest standby
  • Backup and restore (this post): the simplest path, restoring directly from a Crunchy pgBackRest backup
  • Persistent volume reuse (this post): when you want to keep storage and skip the data copy

All three approaches are safe, predictable, and reversible, with the rollback caveats noted in each section. Because Percona’s operator, images, and tooling are 100 percent open source, you keep full control: you can always migrate back to the Crunchy operator, or out to another open-source operator (Zalando, StackGres, CloudNativePG) using the same patterns. That last journey is a topic for a future post.

This post covers basic deployment patterns and simplified configuration examples. If your environment uses custom images, Crunchy enterprise features, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Backup-Restore and PV Reuse appeared first on Percona.
May
24
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method

A Crunchy to Percona PostgreSQL migration is more straightforward than most cross-operator moves on Kubernetes, because the Percona PostgreSQL Operator is a hard fork of the Crunchy Data PostgreSQL Operator. Same Patroni HA, same pgBackRest backups, same overall CRD shape. This post walks through the safest of the three migration paths: a standby cluster method with near-zero downtime.

This is part 2 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0.

This post is the first practical playbook of the series. It covers the standby cluster method, the safest migration path when the downtime budget is tight. Part 3 will cover two simpler paths: backup-and-restore and persistent-volume reuse.

If you are landing here without context on why you might want to migrate at all, start with part 1. The rest of this post assumes you have already decided to move and want a tested playbook.


Migration approach in one paragraph

The Percona PostgreSQL Kubernetes Operator is a hard fork of the Crunchy Data PostgreSQL Kubernetes Operator, which simplifies the migration paths considerably: the same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both operators. All three migration paths in this series are reversible: because Percona’s operator is fully open source and remains compatible with the same backup format, the move back to Crunchy is also possible if your team decides to walk it


A note on the storage layer

All examples in this guide use an in-cluster SeaweedFS instance as the pgBackRest S3 repository. SeaweedFS is Apache-2.0 licensed, actively maintained, and a clean drop-in replacement for the role MinIO used to fill in this stack. Any other S3-compatible storage works just as well: AWS S3, Google Cloud Storage (via HMAC keys), Ceph RadosGW, Cloudflare R2, and so on. For non-SeaweedFS endpoints, remove repo1-s3-uri-style: path and repo1-s3-verify-tls: “n” from the pgBackRest configuration and replace the endpoint with your provider’s URL.


What this series does NOT cover

To keep scope honest:

  • Application-side connection-string changes beyond updating to the new pgBouncer service. If your app uses connection-pool tuning, custom auth, or a service mesh, that work stays with you.
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations. The PostgreSQL major version must match between the source and the target.
  • Crunchy enterprise-only features like TDE, Crunchy Postgres for Kubernetes-specific operators, or pgBackRest custom encryption. If your environment uses these, contact the Percona team for a tailored plan.
  • Operating two operators against the same namespace before the PGO hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any other S3-compatible service accessible from all cluster pods
Tools kubectl, helm (v3), yq

Different versions may differ slightly in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


Migration using a standby cluster

This is the safest method when the downtime budget is tight. The Percona cluster is brought up as a standby of the Crunchy primary, catches up via pgBackRest plus streaming replication, and is promoted at cutover. The only downtime is the cutover step itself.

You can wire the standby in two ways, and combining both gives you maximum safety:

  • pgBackRest repo-based standby seeds the standby from the latest base backup and replays archived WAL
  • Streaming replication keeps the standby in sync with the live primary


Overview


Before you begin

Set the target namespace once. Every command in this guide reads from this variable, so you can change it in a single place:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: “n” is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.


Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secret.yaml after filling in your access key and secret key:

# Copy and edit the file first to set your credentials.

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/01-pgbackrest-secret.yaml

Both secrets contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket and path. The repo1-path value must be identical in both cluster specs. Mismatched paths will prevent the Percona standby from finding the WAL archive.

The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Optional: deploy a Crunchy operator to test the migration end to end:

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait


Apply
examples/02-crunchy-source-cluster.yaml (or adapt your existing cluster’s pgBackRest config):

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/02-crunchy-source-cluster.yaml


The key pgBackRest settings in the example:

global:
  repo1-path: /crunchy-to-percona/repo1   # shared path, must match Percona side
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1


Wait for the cluster to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  --namespace $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s


Step 2. Trigger a full backup on the Crunchy cluster

Wait for the pgBackRest stanza to be created:

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Take a full backup before creating the Percona standby. This gives the standby a recent base to restore from, so it only needs to replay a small amount of WAL to catch up. This matches the realistic production migration pattern.

kubectl annotate postgrescluster crunchy-source \
  --namespace $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"


Wait for the backup job to complete:

kubectl wait job \
  -l postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Copy TLS certificates (cross-namespace only)

If the Percona cluster is in a different namespace from the Crunchy cluster, copy the Crunchy TLS secrets to the Percona namespace. These allow mutual TLS authentication during streaming replication:

for secret in crunchy-source-cluster-cert crunchy-source-replication-cert; do
  kubectl get secret "${secret}" -n <CRUNCHY_NS> -o json | \
    yq '{"apiVersion": .apiVersion, "kind": .kind, "data": .data,
         "metadata": {"name": .metadata.name}, "type": .type}' -o yaml | \
    kubectl -n $MIGRATION_NS apply -f -
done

If both clusters are in the same namespace, skip this step. The secrets are already accessible.


Step 4. Deploy the Percona PG Operator

The Crunchy PGO operator can stay in the same or a different namespace.

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

Wait until the operator deployment is ready:

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s


Step 5. Create the Percona cluster in standby mode

Note: The kubectl apply below pulls the CR manifest from the migration-from-crunchy-guide branch of the operator repo, which is the source for this guide’s examples. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation and pin to a released version tag rather than a feature branch.

Apply examples/03-percona-standby-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/03-percona-standby-cluster.yaml

The key settings that wire the Percona cluster to the Crunchy source:

standby:
  enabled: true
  repoName: repo1                             # restore initial base backup from this repo
  host: crunchy-source-ha.postgres-migration.svc.cluster.local
  port: 5432

secrets:
  customTLSSecret:
    name: crunchy-source-cluster-cert         # Crunchy CA for mutual TLS
  customReplicationTLSSecret:
    name: crunchy-source-replication-cert     # cert for _crunchyreplication user

The Percona operator will:

  1. Restore the base backup from the SeaweedFS bucket.
  2. Replay WAL from SeaweedFS until it catches up with the live Crunchy cluster.
  3. Switch to streaming replication from crunchy-source-ha.

Wait for the cluster to reach the ready state:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify that data is replicating to the standby:

STANDBY_POD=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/data=postgres \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery(), pg_last_wal_replay_lsn();"

Expected output: t (in recovery) and a non-null LSN.


Step 6. Verify replication lag before cutover

Query the Crunchy primary to confirm the Percona standby has caught up:

CRUNCHY_PRIMARY=$(kubectl get pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -c "
    SELECT
        client_addr,
        state,
        pg_wal_lsn_diff(sent_lsn, replay_lsn) AS byte_lag,
        write_lag,
        flush_lag,
        replay_lag
    FROM pg_stat_replication;
  "

Proceed to the next step only when write_lag and replay_lag are NULL or under a few seconds.


Step 7. Cutover the Crunchy cluster

This is the only step that causes downtime. Stop accepting writes on the application side, then patch the Crunchy cluster into standby mode. Patroni steps down and archives the final WAL.

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": true, "repoName": "repo1"}}}'

Verify demotion (poll until pg_is_in_recovery() returns t):

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"


Step 8. (Optional) Shut down the Crunchy cluster

Once the Percona standby has replayed all WAL, shut down the Crunchy cluster to prevent split-brain:

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"shutdown": true}}'

kubectl wait pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=delete \
  --timeout=120s || true


Step 9. Promote the Percona cluster

Confirm that the Percona standby has finished replaying all WAL (the LSN stops advancing):

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_last_wal_replay_lsn();"

Run this a few times. When the LSN is stable, replay is complete.

kubectl patch perconapgcluster percona-standby \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": false}}}'

Wait for the cluster to become ready and confirm it is writable:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=480s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f (the cluster is now the primary and accepts writes).


Step 10. Verify stanza creation

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 11. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery point on the new timeline. All future PITR restores will use this backup as their starting point, independent of the old Crunchy WAL archive.


Reconnecting your application

Update your application’s connection string to point at the Percona cluster’s pgBouncer service:

kubectl get service -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=pgbouncer

This migration path works almost entirely out of the box. For users coming from the Crunchy Data PostgreSQL Operator, this method feels familiar because it leverages the same standby/replica mechanisms used for HA and disaster recovery. The key difference is that you can now use this familiar mechanism to migrate safely to the Percona PostgreSQL Operator, a fully open-source alternative running on a fully open-source storage layer.


Rollback

The standby method is the most rollback-friendly of the three. Until you take the post-migration backup, the Crunchy cluster still holds the original timeline. To roll back:

  1. Stop writes on the Percona side and patch the Percona cluster back into standby mode (spec.standby.enabled: true).
  2. Patch the Crunchy cluster out of standby mode and let Patroni promote it.
  3. Verify with pg_is_in_recovery() on both sides.
  4. Switch the application connection string back to the Crunchy pgBouncer service.

After Step 11 (post-migration backup), the timelines have diverged. From that point, the rollback story is the same as a fresh restore, and you should treat the Crunchy cluster as a historical reference, not a live target.


Troubleshooting

Percona standby not connecting to the Crunchy primary. Verify the crunchy-source-ha service resolves from within the Percona pod:

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  bash -c "getent hosts crunchy-source-ha.${MIGRATION_NS}.svc.cluster.local"

Replication authentication errors. The Percona standby authenticates as the _crunchyreplication PostgreSQL user using the certificate in crunchy-source-replication-cert. Verify the secret exists and matches what the Crunchy operator generated:

kubectl get secret crunchy-source-replication-cert -n $MIGRATION_NS

pgBackRest restore fails. Confirm both secrets contain identical credentials and that repo1-path is the same in both cluster specs (/crunchy-to-percona/repo1 in this guide). Mismatched paths cause an archive.info missing error. Verify the bucket is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "

Timeline history file (00000002.history) missing after promotion. This is a known issue with Crunchy PGO’s async archive mode. After promotion, push the history file synchronously:

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  bash -c "
    pgbackrest --stanza=db --no-archive-async \
      archive-push \"\${PGDATA}/pg_wal/00000002.history\" || true
  "


What’s next

This was the safest migration path. Part 3 will cover two simpler options:

  • Backup and restore. The simplest path. You take a Crunchy pgBackRest backup and the Percona cluster bootstraps from it. Cutover is the time between the final backup and pointing the application at the new cluster.
  • Persistent volume reuse. For when you want to skip the data copy entirely. The Percona cluster takes over the existing PGDATA volume, no restore step required.

Pick the method that fits your downtime budget, data size, and storage layout.

This post covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method appeared first on Percona.
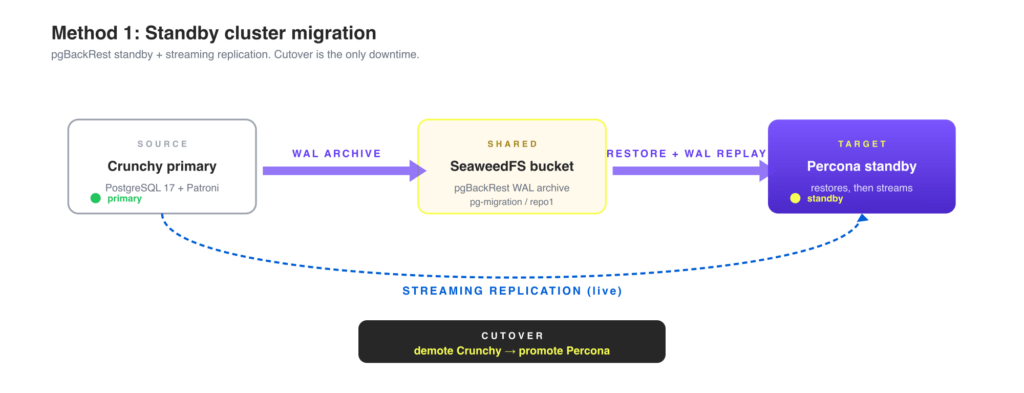
May
24
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method

A Crunchy to Percona PostgreSQL migration is more straightforward than most cross-operator moves on Kubernetes, because the Percona PostgreSQL Operator is a hard fork of the Crunchy Data PostgreSQL Operator. Same Patroni HA, same pgBackRest backups, same overall CRD shape. This post walks through the safest of the three migration paths: a standby cluster method with near-zero downtime.

This is part 2 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0.

This post is the first practical playbook of the series. It covers the standby cluster method, the safest migration path when the downtime budget is tight. Part 3 will cover two simpler paths: backup-and-restore and persistent-volume reuse.

If you are landing here without context on why you might want to migrate at all, start with part 1. The rest of this post assumes you have already decided to move and want a tested playbook.


Migration approach in one paragraph

The Percona PostgreSQL Kubernetes Operator is a hard fork of the Crunchy Data PostgreSQL Kubernetes Operator, which simplifies the migration paths considerably: the same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both operators. All three migration paths in this series are reversible: because Percona’s operator is fully open source and remains compatible with the same backup format, the move back to Crunchy is also possible if your team decides to walk it


A note on the storage layer

All examples in this guide use an in-cluster SeaweedFS instance as the pgBackRest S3 repository. SeaweedFS is Apache-2.0 licensed, actively maintained, and a clean drop-in replacement for the role MinIO used to fill in this stack. Any other S3-compatible storage works just as well: AWS S3, Google Cloud Storage (via HMAC keys), Ceph RadosGW, Cloudflare R2, and so on. For non-SeaweedFS endpoints, remove repo1-s3-uri-style: path and repo1-s3-verify-tls: “n” from the pgBackRest configuration and replace the endpoint with your provider’s URL.


What this series does NOT cover

To keep scope honest:

  • Application-side connection-string changes beyond updating to the new pgBouncer service. If your app uses connection-pool tuning, custom auth, or a service mesh, that work stays with you.
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations. The PostgreSQL major version must match between the source and the target.
  • Crunchy enterprise-only features like TDE, Crunchy Postgres for Kubernetes-specific operators, or pgBackRest custom encryption. If your environment uses these, contact the Percona team for a tailored plan.
  • Operating two operators against the same namespace before the PGO hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any other S3-compatible service accessible from all cluster pods
Tools kubectl, helm (v3), yq

Different versions may differ slightly in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


Migration using a standby cluster

This is the safest method when the downtime budget is tight. The Percona cluster is brought up as a standby of the Crunchy primary, catches up via pgBackRest plus streaming replication, and is promoted at cutover. The only downtime is the cutover step itself.

You can wire the standby in two ways, and combining both gives you maximum safety:

  • pgBackRest repo-based standby seeds the standby from the latest base backup and replays archived WAL
  • Streaming replication keeps the standby in sync with the live primary


Overview


Before you begin

Set the target namespace once. Every command in this guide reads from this variable, so you can change it in a single place:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: “n” is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.


Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secret.yaml after filling in your access key and secret key:

# Copy and edit the file first to set your credentials.

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/01-pgbackrest-secret.yaml

Both secrets contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket and path. The repo1-path value must be identical in both cluster specs. Mismatched paths will prevent the Percona standby from finding the WAL archive.

The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Optional: deploy a Crunchy operator to test the migration end to end:

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait


Apply
examples/02-crunchy-source-cluster.yaml (or adapt your existing cluster’s pgBackRest config):

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/02-crunchy-source-cluster.yaml


The key pgBackRest settings in the example:

global:
  repo1-path: /crunchy-to-percona/repo1   # shared path, must match Percona side
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1


Wait for the cluster to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  --namespace $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s


Step 2. Trigger a full backup on the Crunchy cluster

Wait for the pgBackRest stanza to be created:

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Take a full backup before creating the Percona standby. This gives the standby a recent base to restore from, so it only needs to replay a small amount of WAL to catch up. This matches the realistic production migration pattern.

kubectl annotate postgrescluster crunchy-source \
  --namespace $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"


Wait for the backup job to complete:

kubectl wait job \
  -l postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Copy TLS certificates (cross-namespace only)

If the Percona cluster is in a different namespace from the Crunchy cluster, copy the Crunchy TLS secrets to the Percona namespace. These allow mutual TLS authentication during streaming replication:

for secret in crunchy-source-cluster-cert crunchy-source-replication-cert; do
  kubectl get secret "${secret}" -n <CRUNCHY_NS> -o json | \
    yq '{"apiVersion": .apiVersion, "kind": .kind, "data": .data,
         "metadata": {"name": .metadata.name}, "type": .type}' -o yaml | \
    kubectl -n $MIGRATION_NS apply -f -
done

If both clusters are in the same namespace, skip this step. The secrets are already accessible.


Step 4. Deploy the Percona PG Operator

The Crunchy PGO operator can stay in the same or a different namespace.

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

Wait until the operator deployment is ready:

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s


Step 5. Create the Percona cluster in standby mode

Note: The kubectl apply below pulls the CR manifest from the migration-from-crunchy-guide branch of the operator repo, which is the source for this guide’s examples. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation and pin to a released version tag rather than a feature branch.

Apply examples/03-percona-standby-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/03-percona-standby-cluster.yaml

The key settings that wire the Percona cluster to the Crunchy source:

standby:
  enabled: true
  repoName: repo1                             # restore initial base backup from this repo
  host: crunchy-source-ha.postgres-migration.svc.cluster.local
  port: 5432

secrets:
  customTLSSecret:
    name: crunchy-source-cluster-cert         # Crunchy CA for mutual TLS
  customReplicationTLSSecret:
    name: crunchy-source-replication-cert     # cert for _crunchyreplication user

The Percona operator will:

  1. Restore the base backup from the SeaweedFS bucket.
  2. Replay WAL from SeaweedFS until it catches up with the live Crunchy cluster.
  3. Switch to streaming replication from crunchy-source-ha.

Wait for the cluster to reach the ready state:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify that data is replicating to the standby:

STANDBY_POD=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/data=postgres \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery(), pg_last_wal_replay_lsn();"

Expected output: t (in recovery) and a non-null LSN.


Step 6. Verify replication lag before cutover

Query the Crunchy primary to confirm the Percona standby has caught up:

CRUNCHY_PRIMARY=$(kubectl get pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -c "
    SELECT
        client_addr,
        state,
        pg_wal_lsn_diff(sent_lsn, replay_lsn) AS byte_lag,
        write_lag,
        flush_lag,
        replay_lag
    FROM pg_stat_replication;
  "

Proceed to the next step only when write_lag and replay_lag are NULL or under a few seconds.


Step 7. Cutover the Crunchy cluster

This is the only step that causes downtime. Stop accepting writes on the application side, then patch the Crunchy cluster into standby mode. Patroni steps down and archives the final WAL.

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": true, "repoName": "repo1"}}}'

Verify demotion (poll until pg_is_in_recovery() returns t):

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"


Step 8. (Optional) Shut down the Crunchy cluster

Once the Percona standby has replayed all WAL, shut down the Crunchy cluster to prevent split-brain:

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"shutdown": true}}'

kubectl wait pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=delete \
  --timeout=120s || true


Step 9. Promote the Percona cluster

Confirm that the Percona standby has finished replaying all WAL (the LSN stops advancing):

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_last_wal_replay_lsn();"

Run this a few times. When the LSN is stable, replay is complete.

kubectl patch perconapgcluster percona-standby \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": false}}}'

Wait for the cluster to become ready and confirm it is writable:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=480s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f (the cluster is now the primary and accepts writes).


Step 10. Verify stanza creation

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 11. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery point on the new timeline. All future PITR restores will use this backup as their starting point, independent of the old Crunchy WAL archive.


Reconnecting your application

Update your application’s connection string to point at the Percona cluster’s pgBouncer service:

kubectl get service -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=pgbouncer

This migration path works almost entirely out of the box. For users coming from the Crunchy Data PostgreSQL Operator, this method feels familiar because it leverages the same standby/replica mechanisms used for HA and disaster recovery. The key difference is that you can now use this familiar mechanism to migrate safely to the Percona PostgreSQL Operator, a fully open-source alternative running on a fully open-source storage layer.


Rollback

The standby method is the most rollback-friendly of the three. Until you take the post-migration backup, the Crunchy cluster still holds the original timeline. To roll back:

  1. Stop writes on the Percona side and patch the Percona cluster back into standby mode (spec.standby.enabled: true).
  2. Patch the Crunchy cluster out of standby mode and let Patroni promote it.
  3. Verify with pg_is_in_recovery() on both sides.
  4. Switch the application connection string back to the Crunchy pgBouncer service.

After Step 11 (post-migration backup), the timelines have diverged. From that point, the rollback story is the same as a fresh restore, and you should treat the Crunchy cluster as a historical reference, not a live target.


Troubleshooting

Percona standby not connecting to the Crunchy primary. Verify the crunchy-source-ha service resolves from within the Percona pod:

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  bash -c "getent hosts crunchy-source-ha.${MIGRATION_NS}.svc.cluster.local"

Replication authentication errors. The Percona standby authenticates as the _crunchyreplication PostgreSQL user using the certificate in crunchy-source-replication-cert. Verify the secret exists and matches what the Crunchy operator generated:

kubectl get secret crunchy-source-replication-cert -n $MIGRATION_NS

pgBackRest restore fails. Confirm both secrets contain identical credentials and that repo1-path is the same in both cluster specs (/crunchy-to-percona/repo1 in this guide). Mismatched paths cause an archive.info missing error. Verify the bucket is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "

Timeline history file (00000002.history) missing after promotion. This is a known issue with Crunchy PGO’s async archive mode. After promotion, push the history file synchronously:

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  bash -c "
    pgbackrest --stanza=db --no-archive-async \
      archive-push \"\${PGDATA}/pg_wal/00000002.history\" || true
  "


What’s next

This was the safest migration path. Part 3 will cover two simpler options:

  • Backup and restore. The simplest path. You take a Crunchy pgBackRest backup and the Percona cluster bootstraps from it. Cutover is the time between the final backup and pointing the application at the new cluster.
  • Persistent volume reuse. For when you want to skip the data copy entirely. The Percona cluster takes over the existing PGDATA volume, no restore step required.

Pick the method that fits your downtime budget, data size, and storage layout.

This post covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method appeared first on Percona.
May
19
2026
--

Not All Open Source Is Equal: Choosing a PostgreSQL Operator for Kubernetes in 2026


Choosing an open source PostgreSQL operator for Kubernetes used to be a question about features and community size. In 2026, it has become a question about licensing posture, image distribution, and whether the project you pick today will still be operationally open in three years.

This is part 1 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator.

  • Part 1 (this post): how the open-source landscape has shifted under your feet, and what to look for in an operator before you commit
  • Part 2: migrating from the Crunchy Data PostgreSQL Operator to the Percona PostgreSQL Operator using the standby cluster method (near-zero downtime)
  • Part 3: two simpler migration paths: backup-and-restore and persistent-volume reuse

In this post, you will learn about:

  • What has changed in the open-source landscape over the last few years, with specific examples
  • What licensing and redistribution actually mean for Kubernetes operators in production
  • How to evaluate whether a project is “open source in theory” or open source in practice
  • Where Percona’s PostgreSQL Operator fits in, and what the practical migration looks like

Open source isn’t what it used to be
The landscape of open source has undergone significant changes in recent years, and selecting the right operator and tooling for PostgreSQL clusters in Kubernetes has never been more important. Three recent shifts illustrate the pattern.


MinIO

MinIO was the default open-source S3-compatible storage backend for Kubernetes workloads for years. The trajectory over the last few years tells the story:

  • Switched its license to AGPLv3, with several enterprise features moved into a commercial-only edition
  • Entered what amounted to maintenance mode, narrowing community engagement, limiting support to paid subscriptions, and reducing acceptance of community contributions
  • On April 25, 2026, the github.com/minio/minio repository was archived by the project owner, ending public development of the open-source version

The code is still cloneable, but the project is no longer maintained as open source. Teams running MinIO in production now need an exit plan.


Bitnami images

Bitnami Docker images have long been a staple for databases (including Postgres), middleware, and developer tooling. In July 2025, Broadcom’s Tanzu Division announced Bitnami Secure Images and signalled the deprecation of the free public catalog. The concrete timeline that followed:

  • August 28, 2025: deprecation of non-hardened Debian-based images in the free tier began, and non-latest images started to be removed
  • September 29, 2025 (after community pushback): the public docker.io/bitnami catalog was reduced. The remaining free images were limited to a small curated set of latest-version, hardened images intended for development use; older versions of most applications were moved to a “Bitnami Legacy” repository
  • The full catalog and the hardened production images now require a paid Bitnami Secure Images subscription, reportedly priced in the tens of thousands of dollars per year per organization

For Kubernetes teams, the practical impact was immediate: any Helm chart that pinned a specific Bitnami image version (a recommended practice) found that image gone or moved, breaking CI pipelines and air-gapped deployments.


Crunchy Data PostgreSQL images

Crunchy Data illustrates the same dynamic in the Postgres operator space. To be clear: the Crunchy Data PostgreSQL Operator is a mature, well-engineered project, and the team behind it has done a lot of valuable work upstream and around pgBackRest and Patroni integrations. The point of this section is not the engineering, it is the redistribution and usage terms that govern the official builds.

Crunchy’s licensing shifts, 2022 to 2024

Between 2022 and 2024, several shifts occurred:

  • Redistribution restrictions. While the PostgreSQL code is open source, Crunchy’s official Docker images include branding and enterprise features that are not freely redistributable. The Crunchy Data Developer Program terms describe the software as intended for internal or personal use; production use by larger organizations typically requires an active support subscription.
  • Restrictions on consulting and resale. The terms explicitly prohibit using Crunchy’s images to deliver support or consulting services to others without an authorized agreement. The PostgreSQL source code remains open source, but the official images and their packaging are not freely redistributable, which limits practical use in commercial and customer-facing settings.
  • Registry move. Most images were moved to registry.developers.crunchydata.com, which requires authentication and acceptance of terms before pulling. That draws a clearer line between open-source code and proprietary builds.

In other words, the project is open source on the code side, but the practical artifacts (images, Helm releases) are gated.


What these restrictions really mean for Kubernetes users

When container images and operators come with redistribution limits, authentication requirements, or “internal-use-only” clauses, the impact on Kubernetes environments is immediate and concrete. Teams can no longer:

  • Build air-gapped clusters by mirroring images to a private registry without working through a license review
  • Rely on GitOps workflows that assume publicly accessible OCI images
  • Fork or customize the operator freely, because official images cannot be redistributed with modifications
  • Use the software in commercial or customer-facing products without additional licensing
  • Run multi-cluster or multi-tenant Postgres at scale without bumping into usage terms

For a database operator, where almost every operational pattern depends on the container images you can pull and run, these restrictions effectively turn a project into a “source-available but not operationally open” solution. The code is open. The operating story is not.
As a result, many teams are switching to fully open-source alternatives: the Percona Operator for PostgreSQL, CloudNativePG, Zalando Postgres Operator, StackGres, and a few others.


How to evaluate “open source” in 2026

The bigger picture here is that “open source” today often exists more in theory than in practice. It pays to look past the badge and check the operating reality. Three questions to ask before you commit to an operator:

1. Are the container images publicly redistributable?

If you cannot pull the official images without authentication, or you cannot mirror them to your private registry without a license review, your air-gapped and GitOps stories are constrained from day one. This is the question that turned out to be the most consequential one for MinIO, Bitnami, and Crunchy users in 2025.

2. Are core operational features in the open-source build, or behind a paywall?

Backup, monitoring, HA, and security features should be in the build everyone uses, not gated behind an enterprise tier. A “community edition” that omits the feature most teams actually need is a marketing build, not a real open-source build.

3. Is the governance and roadmap public?

A project where you can see the issues, the PRs, and the roadmap is one you can plan around. The Percona PG Operator’s public roadmap is an example of what this looks like in practice. A project run inside a vendor’s private tracker, by contrast, gives you no visibility.
These are not gotchas. They are the questions that decide whether a project will still serve you the same way in three years.


Migrate to freedom

Announcing the hard fork

We strongly believe in fully open-source software and want to increase our investment in the PostgreSQL and Kubernetes ecosystems. To back that up, we have decided to hard fork the Crunchy Data PostgreSQL Kubernetes Operator. Starting from version 3.0.0 (coming soon), the Percona PostgreSQL Kubernetes Operator is a fully independent project, with a public roadmap, public issue tracker, and freely redistributable images.

The hard fork is not a critique of Crunchy’s engineering. It is a commitment that the operator will keep evolving in a fully open-source direction, with no surprises about which features will be available to which audience.

Why migration is straightforward

Because the Percona PostgreSQL Operator is a hard fork of the Crunchy operator, the migration paths are surprisingly straightforward. The same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both, which means migration can be done in multiple ways, sometimes with near-zero downtime, sometimes faster with a small downtime window. The next two posts in this series walk through three concrete options.

What’s next

This was the “why.” The next two posts are the “how”:

  • Part 2: Standby cluster migration. Bring up a Percona cluster as a standby of the Crunchy primary, catch it up via pgBackRest plus streaming replication, and promote it at cutover. The only downtime is the cutover itself.
  • Part 3: Backup-restore and PV reuse. Two simpler paths: bootstrap a Percona cluster directly from a Crunchy pgBackRest backup, or retain the existing PGDATA persistent volume and have Percona pick up where Crunchy left off.

Reversibility and exit options

All three paths are reversible: because Percona’s operator, images, and tooling are 100 percent open source and remain compatible with the same backup format and the same Patroni HA model, you keep full control. You can migrate back to Crunchy if your team decides to, or out to another open-source operator (CloudNativePG, Zalando, StackGres) using the same patterns. That last journey is a topic for a future article.

This series covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Not All Open Source Is Equal: Choosing a PostgreSQL Operator for Kubernetes in 2026 appeared first on Percona.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com