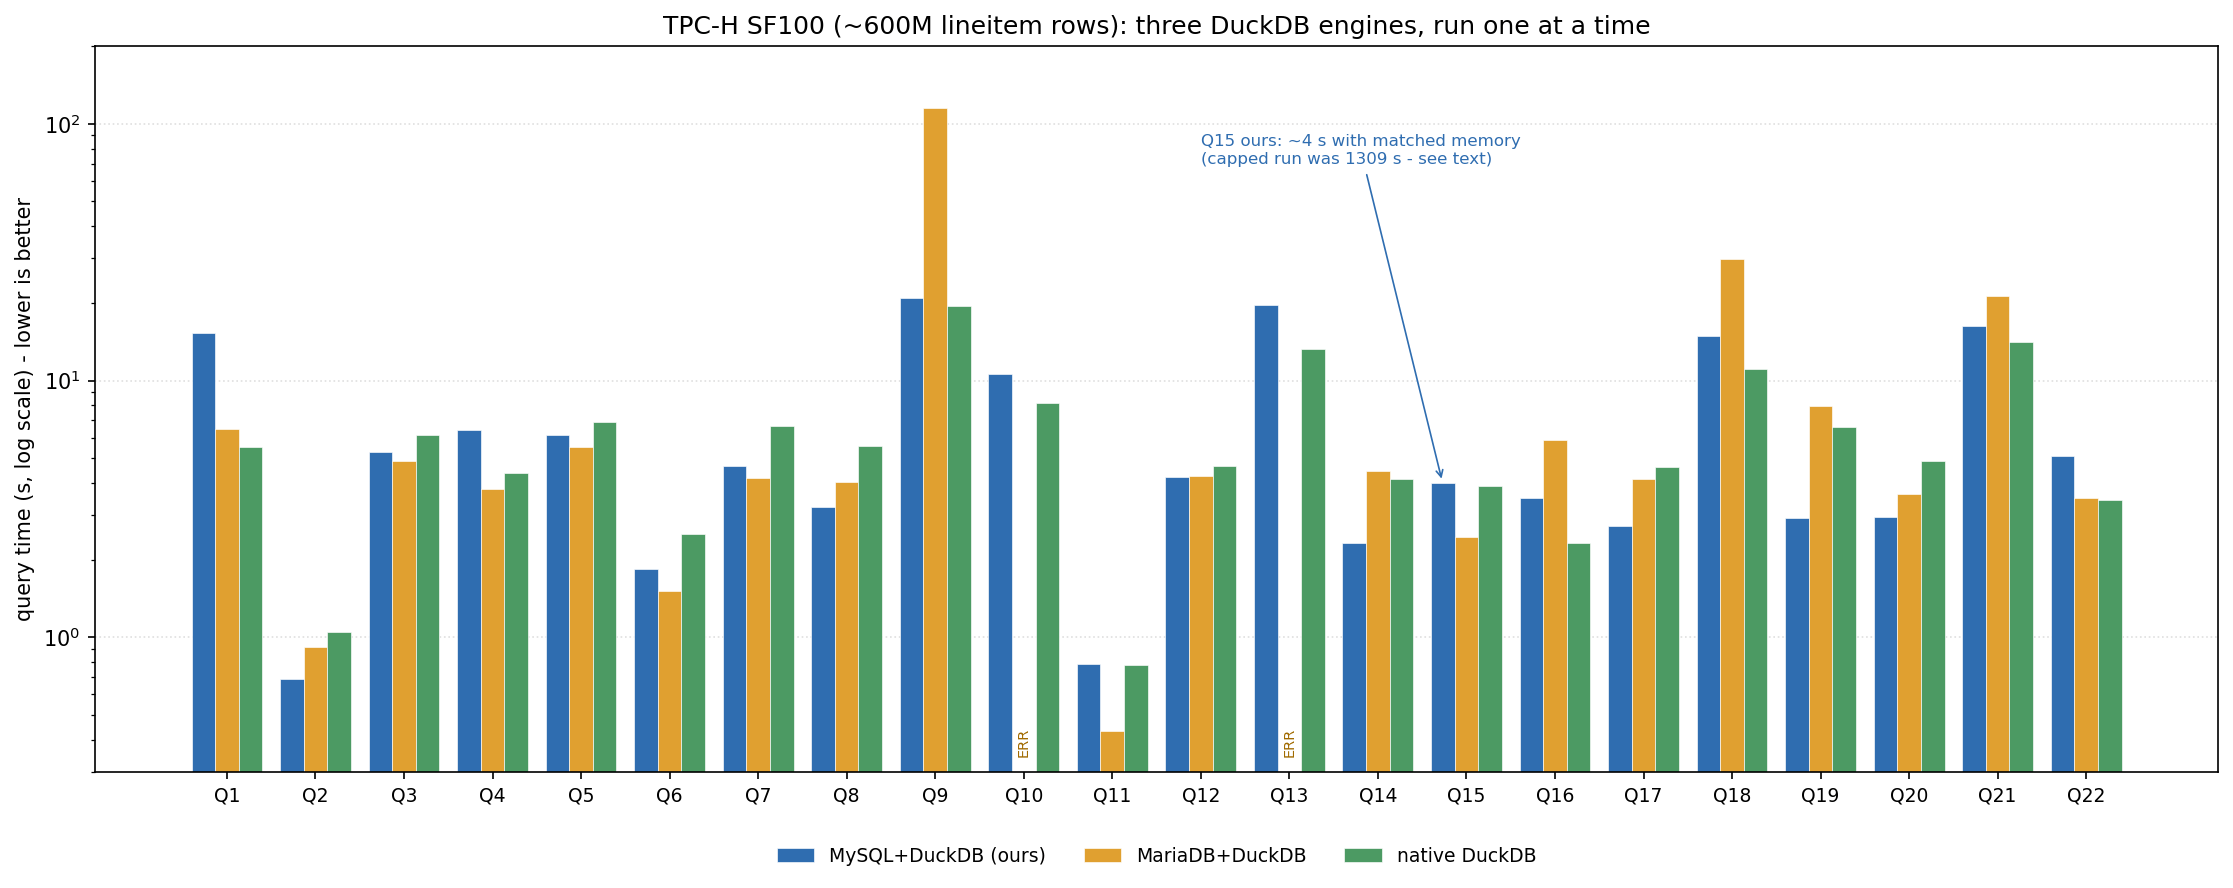Aug
19
2026
--

Stop guessing at gcache: inspect Galera/PXC write sets with gcache-inspector

The common practice is to size the Galera Cache based on write volume measured during peak load, but often it is more of a guesswork. The writeset cache capacity planning is crucial to shorten the maintenance time and avoid long state transfers while the cluster runs with reduced compute power. Now, if you could understand what’s exactly inside the cache, wouldn’t the planning be more aware as compared to only calculating the best size based on wsrep_received/replicated_bytes variables?

Similarly, while dealing with various incidents occurring in Percona XtraDB Cluster or MariaDB Galera Cluster environments, how many times did you stumble upon the fact that the GCache file (galera.cache) is a black box and you can’t inspect it in a meaningful way? 

In some scenarios, having the opportunity to see what exactly ended up in the cache file(s) could help us understand the write workload impact or what happened with transactions.

Why would one need to dig into galera.cache files, though? Let’s think about possible scenarios:

  • Debugging replication issues or conflicts (BF aborts, etc).
  • Understanding recent workload patterns per table (especially when binary log is not enabled or lost).
  • Understanding the IST capacity and why node joining falls back to SST.
  • Forensic analysis after incidents.
  • Why on-demand gcache.page.X files are created and what transactions are inside.
  • What committed writesets are still in “assigned / live” vs “released / reclaimable” state.
  • Observe / confirm the impact of binlog_row_image setting on the writesets size.

To address those, I decided to experiment with a tool that would decode the Galera cache files. As a result of these experiments, I recently published gcache-inspector – an open source project available on GitHub. 

Before I introduce how the tool works, let’s quickly review the write set caching process.

What is Galera Cache? 

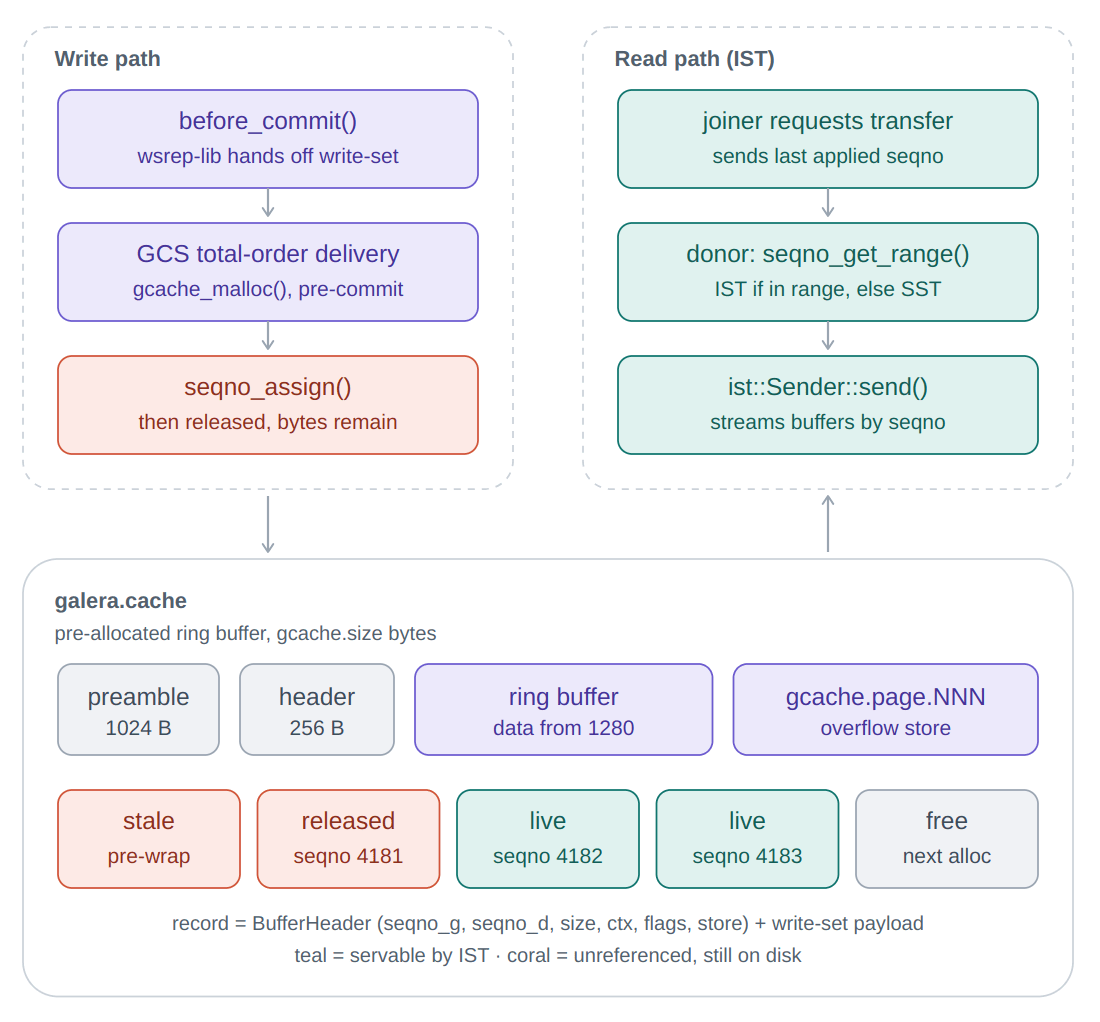
In short, it is a RingBuffer file storing Write-set Cache, which is also memory-mapped. Every replicated transaction is appended to it. Due to the fixed size, the oldest entries are overwritten to allow new writes. In special circumstances when the cache file is too small to fit a big transaction or old entries are not ready to be removed, additional on-demand cache files are created.

From the operational perspective, the most important role of the Galera cache is to provide quick incremental synchronization (IST) of (re-)joining cluster nodes. Having the cache of enough size, so that it can store enough time’s worth of writes, determines the joining process – whether a restarted node will be able to join quickly via IST or whether it will have to pull a full backup (SST) from the donor.

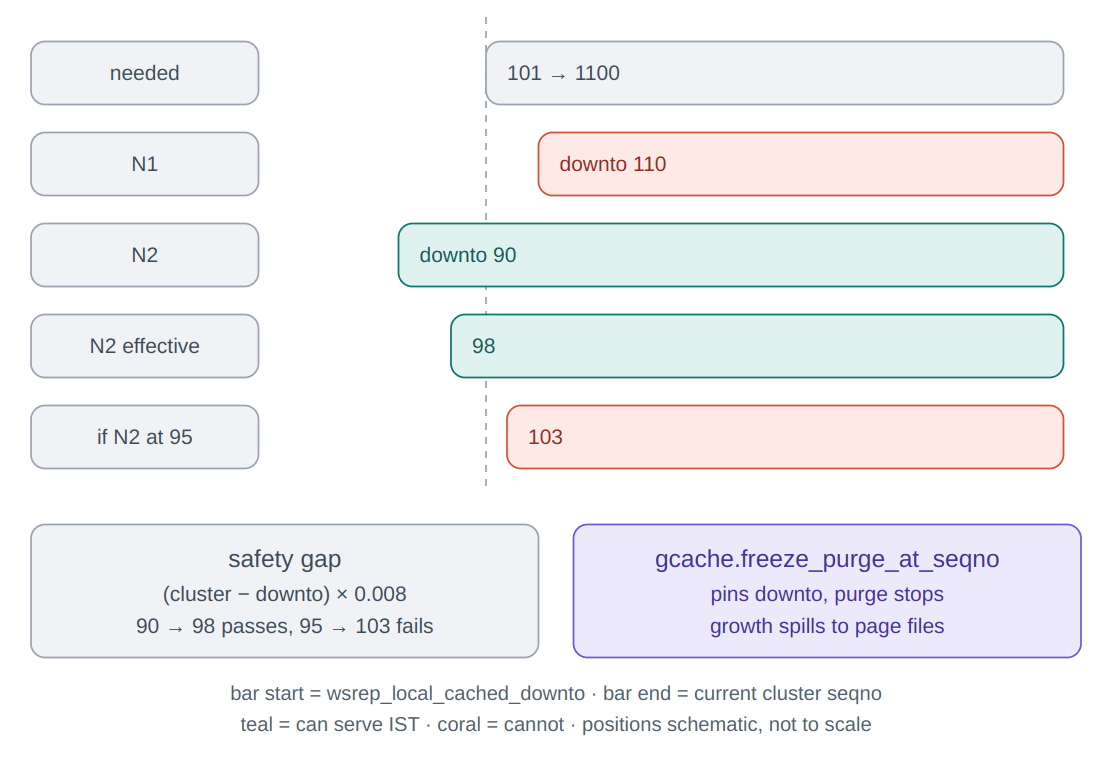
The diagram below shows the typical transaction lifecycle, role, and structure of the Galera cache.

The IST determination is a bit more complex than you’d expect. The joiner estimates the donor’s capabilities with some safety margin.

It is possible to verify the current potential donor Galera cache coverage from its wsrep_local_cached_downto status variable. Moreover, the cache rotation can be put on hold to extend the donor’s time window coverage via the gcache.freeze_purge_at_seqno provider option.

If the above diagram is difficult to digest, the following blog post should shed light on the process: https://www.percona.com/blog/understanding-ist-donor-selected/


Given all this complexity, you may sometimes just want to check and verify for yourself what on earth is in the Galera cache files, instead of guessing. 

And historically, the cache files were just a mystery – no tools available to actually properly inspect them. This is why I decided to experiment with a utility that would fill that gap.

The gcache-inspector

The tool I ended up with can fully decode the Galera cache files. It makes quick general write patterns statistics, write set nature information, and can decode the actual Row-based events (binary log style).

Gcache-inspector works offline (the examined PXC node can be running or not). You may point it to a galera.cache or gcache.page.X file. Below is an example of the default report without additional options used.

$ gcache-inspector --file node2/data/galera.cache 
=== gcache-inspector 0.2.5 — GCache Summary ===
File:    /data/sandboxes/pxc_msb_pxc8_4_10/node2/data/galera.cache
Size:    128.00 MB
Version: 2   UUID: 62f2ad43-8de5-11f1-9fb8-8bae2a687fc9
Seqno (retained):  2 – 4533  (4532 in cache)
Synced:  yes   Offset: 1704
Encrypted: no
Flavor:  PXC / MySQL 8.x

Write-sets found:  4498  4498 retained, 0 older/overwritten
Decodable seqnos:  3 – 4533  (4498 write-sets; pick one with --seqno)
Time range:        2026-08-01 22:12:58 – 2026-08-05 23:04:02 CEST  (span 96h51m4s, newest 12d ago)
DDL statements:    216
GTID events seen:  0
Rows changed:      513758  (95.20 MB)  [all write-sets]

Top 10 tables by row activity:
  table                                      insert   update   delete    ddl       size
  ???????????????????????????????????????????????????????????????????
  sbtest.sbtest1                               5039     5574       15      2        2.9M
  sbtest.sbtest32                              5053       37       18      2        0.9M
  sbtest.sbtest8                               5050       30       23      2        0.9M
  sbtest.sbtest60                              5049       31       21      2        0.9M
  sbtest.sbtest100                             5045       36       18      2        0.9M
  sbtest.sbtest10                              5054       26       19      2        0.9M
  sbtest.sbtest85                              5055       25       17      2        0.9M
  sbtest.sbtest35                              5042       40       14      2        0.9M
  sbtest.sbtest87                              5045       37       14      2        0.9M
  sbtest.sbtest33                              5048       30       18      2        0.9M

By using the --detail parameter, the tool will show per-individual sequence number details, i.e.:

$ gcache-inspector --file node2/data/galera.cache --detail --no-summary --seqno 100-105

=== Write-sets ===
  seqno 100           453632 B 2026-08-01 22:14:39  RELEASED  sbtest.sbtest16[i:2281 u:0 d:0]
  seqno 101              256 B 2026-08-01 22:14:39  RELEASED  1 DDL: CREATE INDEX k_16 ON sbtest16(k); sbtest.sbtest16[i:0 u:0 d:0]
  seqno 102              432 B 2026-08-01 22:14:39  RELEASED  1 DDL: CREATE TABLE sbtest17(; sbtest.sbtest17[i:0 u:0 d:0]
  seqno 103           540664 B 2026-08-01 22:14:39  RELEASED  sbtest.sbtest17[i:2719 u:0 d:0]
  seqno 104           453632 B 2026-08-01 22:14:39  RELEASED  sbtest.sbtest17[i:2281 u:0 d:0]
  seqno 105              256 B 2026-08-01 22:14:39  RELEASED  1 DDL: CREATE INDEX k_17 ON sbtest17(k); sbtest.sbtest17[i:0 u:0 d:0]

The above example shows that a transaction committed with the sequence number 100 has inserted 2281 rows into the table sbtest16 and did not update or delete any rows.

To see exactly what a given transaction was about, the --decode-rows option prints the whole event details. For example, it’s possible to see what rows were changed under seqno 4252:

$ gcache-inspector --file node2/data/galera.cache --decode-rows --no-summary --seqno 4252

-- seqno 4252 at 2026-08-01 22:15:32 (816 bytes) RELEASED
### DELETE FROM `sbtest`.`sbtest41`
### WHERE
###   @1= 1843
###   @2= 3562
###   @3= '55824051154-00248428540-43829027453-18090470997-77687189613-13487855838-34568671126-01577127301-81564593132-49010886470'
###   @4= '09475435259-72703365718-14065084029-80972334150-38881617733'
### INSERT INTO `sbtest`.`sbtest41`
### SET
###   @1= 1843
###   @2= 4879
###   @3= '37041074202-54426174421-76052854404-43175485519-62755971707-75981734496-81616509419-51624022546-52075561216-00090498892'
###   @4= '46023326729-33104312594-23620888475-28615232417-62781559343'

A DDL investigation example

Handling DDLs in Galera replication may be quite confusing. Even if, for instance, an ALTER query fails on the writer, it still gets replicated, causing surprising errors on the peer members, similar to this:

2026-08-05T21:04:02.137267Z 11 [ERROR] [MY-010584] [Repl] Replica SQL: Error 'Table 'sbtest.foo' doesn't exist' on query. Default database: 'sbtest'. Query: 'alter table foo engine=innodb', Error_code: MY-001146
2026-08-05T21:04:02.137334Z 11 [Warning] [MY-000000] [WSREP] Event 1 Query apply failed: 1, seqno 4533
2026-08-05T21:04:02.138503Z 0 [Note] [MY-000000] [Galera] Member 0(przemek-d1) initiates vote on 62f2ad43-8de5-11f1-9fb8-8bae2a687fc9:4533,aebcd4f61a8a51aa:  Table 'sbtest.foo' doesn't exist, Error_code: 1146;

Although such an event normally produces a GRA file to let us investigate, like in this case: GRA_11_4533_v2.log, now we can also look into the cache file for the same (here the SKIPPED flag confirms it was not applied):

$ gcache-inspector --file node2/data/galera.cache --detail --no-summary --seqno 4533

=== Write-sets ===
  seqno 4533             256 B 2026-08-05 23:04:02  RELEASED|SKIPPED  1 DDL: alter table foo engine=innodb; sbtest.foo[i:0 u:0 d:0]

Encrypted Galera Cache

For strict security compliance cases, Percona XtraDB Cluster allows encrypting the Gcache files. The tool allows inspection of encrypted files as well, if the encryption key or vault credentials are provided. But there is one caveat here. A regular, non-encrypted cache file will contain all replicated transactions immediately. Whilst the encrypted one will not show anything new until the encryption in-memory cache is filled or synced during shutdown. Therefore, new transactions are expected to appear in the encrypted cache file with a delay.

Note: the tool does not support encryption available in MariaDB Galera Cluster Enterprise Edition (no source code access).

An example output against an encrypted file:

$ gcache-inspector --file node1/data/galera.cache --keyring-file /opt/mysql/pxc8.4.10/keyring/component_keyring_file
=== gcache-inspector 0.2.5 — GCache Summary ===
File:   node1/data/galera.cache
Size:    128.00 MB
Version: 2   UUID: 62f2ad43-8de5-11f1-9fb8-8bae2a687fc9
Seqno (retained):  4395 – 4533  (139 in cache)
Synced:  yes   Offset: 1776
Encrypted: yes — decrypted   (enc version 1)
Master key: GaleraKey-d6945297-8f7a-11f1-9533-7a5bf82f508c@62eff734-8de5-11f1-b956-7f3a785ad5e2-1
Key source:/opt/mysql/pxc8.4.10/keyring/component_keyring_file (GaleraKey-d6945297-8f7a-11f1-9533-7a5bf82f508c@62eff734-8de5-11f1-b956-7f3a785ad5e2-1)
Cipher:    AES-256-ctr-file, clear below 0x400, counter from 0x0 [CTR unwrap (zero IV), keyring bytes]
Freshness: on a live node the encrypted file lags the in-memory cache (write-back page cache; flushed on eviction/shutdown)
Flavor:  PXC / MySQL 8.x

Write-sets found:  127  127 retained, 0 older/overwritten
Decodable seqnos:  4395 – 4533  (127 write-sets; pick one with --seqno)
Time range:        2026-08-01 22:15:32 – 2026-08-05 23:04:02 CEST  (span 96h48m30s, newest 12d ago)
DDL statements:    1
GTID events seen:  0
Rows changed:      5782  (2.08 MB)  [all write-sets]

Top 10 tables by row activity:
  table                                      insert   update   delete    ddl       size
  ???????????????????????????????????????????????????????????????????
  sbtest.sbtest1                                  2     5545        1      0        2.0M
  sbtest.sbtest58                                 5        1        2      0        0.0M
  sbtest.sbtest64                                 3        2        2      0        0.0M
  sbtest.sbtest52                                 4        1        2      0        0.0M
  sbtest.sbtest14                                 2        3        1      0        0.0M
  sbtest.sbtest26                                 2        2        2      0        0.0M
  sbtest.sbtest6                                  2        2        2      0        0.0M
  sbtest.sbtest98                                 3        1        2      0        0.0M
  sbtest.sbtest97                                 4        0        2      0        0.0M
  sbtest.sbtest68                                 1        4        0      0        0.0M

Summary

Although in most cases, problems with PXC/Galera replication can be successfully investigated based on error logs, binary logs, and GRA files, there may be more complex cases where you may want to look inside the Galera cache files. Or simply for experimenting or to allow better understanding of how it works. I hope gcache-inspector will help you do this. The tool is available as GPLv3, with Go source code and binary packages ready to play with on GitHub: https://github.com/PrzemekMalkowski/gcache-inspector. Demo recording: https://asciinema.org/a/1263342

If, despite acquiring details, you face undersized gcache or other reasons causing nodes to keep falling back to SST, Percona’s engineers can help you tackle those problems. Talk to us about a cluster health review https://www.percona.com/contact-us/

Additional references about Galera Cache can be found in the following blog posts by other Percona engineers:
https://www.percona.com/blog/all-you-need-to-know-about-gcache-galera-cache/
https://www.percona.com/blog/no-sst-node-rejoins/
https://www.percona.com/blog/understanding-ist-donor-selected/
https://www.percona.com/blog/gcache-and-record-set-cache-encryption-in-percona-xtradb-cluster-part-one/


The article was written by a human

The post Stop guessing at gcache: inspect Galera/PXC write sets with gcache-inspector appeared first on Percona.

Jul
23
2026
--

Percona Operator for MongoDB 1.23.0: ClusterSync Migration, Vector Search, and PVC Snapshot Backups


Percona Operator for MongoDB 1.23.0 makes the operator a place you move to, not just a place you start. A new ClusterSync component clones a live source and follows its change streams, so leaving a hosted service is a short cutover rather than a long outage. Alongside it, this release adds semantic vector search and storage-layer snapshot backups, two features that matter most once the data is yours to run.

The three headline features are Percona ClusterSync for MongoDB, vector search, and PVC snapshot backups. ClusterSync clones and continuously replicates a live source into an operator-managed cluster. Vector search brings semantic queries to Percona Server for MongoDB. PVC snapshot backups move backups off the network path and onto the storage layer.

This release also widens where you can run it, adding official Rancher Kubernetes Engine (RKE2) support and full ARM64 images. Much of what shipped here traces back to requests on forums.percona.com and the public issue tracker.


In this post, you’ll learn about:

  • ClusterSync migration and replication
  • Vector search for semantic queries
  • PVC snapshot backups
  • Other improvements worth knowing about


Zero-Downtime Migration with Percona ClusterSync

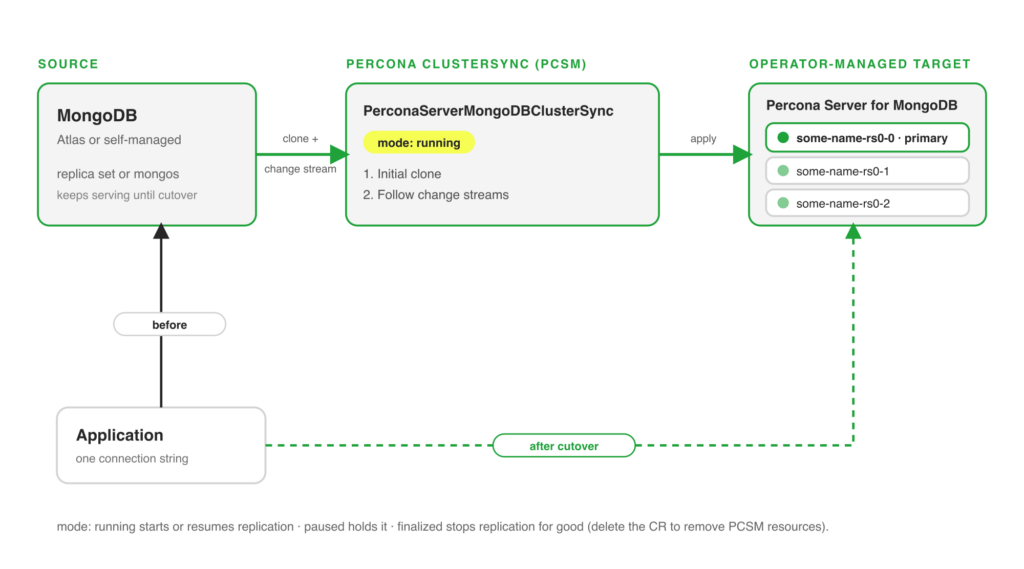
Moving a live MongoDB database onto the operator has always been the awkward first step. Dump-and-restore needs a maintenance window sized to your data, and hand-built replication between a source and a target is fragile to set up and easy to get wrong. This release introduces Percona ClusterSync for MongoDB (PCSM) as an operator-managed component, so the migration path is via a Kubernetes object rather than a runbook.


Why it matters

The common case is migrating a hosted MongoDB service, for example MongoDB Atlas, for an operator-managed Percona Server for MongoDB cluster you control end to end. A typical trigger in production is a hosted-service bill that climbs with the workload, or a compliance requirement to keep data inside your own VPC and region: a team running a user-profile store on Atlas points PCSM at it, lets the target catch up over a day or two while the application keeps serving from Atlas, then cuts over in a maintenance window measured in seconds. PCSM clones the existing data, then tracks ongoing changes through MongoDB change streams, so the target stays current while you validate it. When you are ready, you cut the application over during a short window rather than a long one. The same mechanism keeps a continuously updated replica for non-production use or a hybrid-cloud copy.

How it works

PCSM runs as its own container, deployed and managed through a new PerconaServerMongoDBClusterSync custom resource. It performs an initial clone from the source connection string, then consumes change stream events to apply subsequent writes to the target. A mode field controls the lifecycle: running starts or resumes replication, paused holds it, and finalized stops replication.


Wiring it up

apiVersion: psmdb.percona.com/v1
kind: PerconaServerMongoDBClusterSync
metadata:
  name: my-cluster-sync
spec:
  clusterName: my-target-cluster-name
  image: percona/percona-clustersync-mongodb:0.9.0
  # mode controls the PCSM lifecycle intent. Allowed values:
  #   running   - start/resume replication (default)
  #   paused    - pause an active replication
  #   finalized - stop replication
  mode: running
  source:
    uri: mongodb://source-cluster-mongos.source-namespace.svc.cluster.local:27017
    credentialsSecret: my-cluster-sync-source
  # excludeNamespaces lists MongoDB namespaces (db or db.collection) to skip.
  # excludeNamespaces:
  #   - admin
  #   - local

clusterName names the operator-managed target that receives the data. source.uri and source.credentialsSecret point at the database you are migrating from, which can be Atlas, a self-managed replica set, or another operator cluster. mode is the control you drive the cutover with: run to catch up, pause to hold, then finalize once the application points at the new cluster. The optional excludeNamespaces list skips databases or collections you do not want to copy.
 

Cutover and rollback

The cutover is yours to time, not the operator’s. During the running replication, the target trails the source by the change-stream lag, which you watch until it is small and steady. You then stop writes on the source, let the last events drain, and repoint the application at the target cluster. Because the source keeps serving until you move the application, a rollback before cutover is simply leaving the application where it is. After cutover, treat the move as one-way once writes flow to the target, so verify the target thoroughly during the sync window rather than after.

Note: The PCSM component ships at version 0.9.0 with this release. Test the full migration and cutover against a staging copy before you run it on production data, and keep the source available until you have verified the target.


Vector search for semantic queries

Vector search retrieves results by meaning rather than exact keyword match, which is the retrieval pattern behind semantic search and retrieval-augmented generation for AI applications. Teams that already store their data in MongoDB have had to copy vectors into a separate engine to do this, which adds a system to run and a pipeline to keep in sync. In production, this is the pattern behind a support tool that surfaces past tickets describing the same problem in different words, a product catalog that returns items by intent rather than exact keywords, and a RAG service that grounds a model on internal documents. This release lets you store and query vector data alongside your regular documents in Percona Server for MongoDB, so those workloads query one system instead of two.
 

How it works

The operator deploys and manages the mongot search process, wires its authentication and TLS to the rest of the cluster, and keeps the search index synchronized for both replica set and sharded deployments. Applications query the index through the same MongoDB connection they already use, so you add semantic search without a second client, a second driver, or a second set of credentials. You do not stand up or secure a separate search tier; the operator treats mongot as another managed component of the cluster.
 

Wiring it up

Enable the search component in the custom resource:

spec:
  search:
    enabled: true
    image: perconalab/percona-server-mongodb-operator:main-mongot
    size: 1
    storage:
      persistentVolumeClaim:
        resources:
          requests:
            storage: 10Gi
    resources:
      requests:
        cpu: "2"
        memory: 2Gi

size sets how many search nodes to run, and storage gives the search index its own PersistentVolumeClaim so it does not compete with the database volume. Size the resources block to your index: vector indexes are memory-sensitive, so give mongot enough headroom for the corpus you intend to query.

Note: Vector search is a tech preview in 1.23.0 and is not recommended for production yet. It requires Percona Server for MongoDB 8.3 or later.


PVC snapshot backups

Logical and streamed physical backups both push data across the network to object storage, and for a multi-terabyte cluster, that path is the bottleneck. Backups run long, restores run longer, and both compete with production traffic for CPU and bandwidth. This release adds backups built on PersistentVolumeClaim snapshots, which takes the storage layer directly.


Why it matters

A PVC snapshot is a point-in-time copy of your data volumes taken at the storage layer through the Kubernetes VolumeSnapshot API. Because the operator asks the storage provider for a snapshot instead of streaming bytes out, a backup typically completes in seconds or minutes regardless of database size, and a restore is correspondingly fast. Two production situations show the difference: a nightly backup that no longer fits its window as a cluster grows past a few terabytes, and a staging refresh that ties up resources for hours while it restores a streamed copy. A storage-layer snapshot turns both into a near-instant operation. The speed comes from how the storage layer implements snapshots: instead of copying the whole volume, most backends record only the blocks that changed since the previous snapshot and reference the rest, so the cost tracks your change rate rather than the total database size. Snapshots also work with encrypted and TLS-enabled clusters, and they use fewer cluster resources because there is no long-running data-transfer job.


Wiring it up

The operator takes snapshot backups in two ways: on demand through a PerconaServerMongoDBBackup object, or on a schedule through a backup task. The scheduled form looks like this, using the external type and a VolumeSnapshotClass:

spec:
  backup:
    tasks:
      - name: daily-snapshot
        enabled: false
        schedule: "0 0 * * *"
        retention:
          count: 1
          type: count
          deleteFromStorage: true
        type: external
        volumeSnapshotClass: YOUR-VOLUME-SNAPSHOT-CLASS

type: external tells the operator to take a storage-layer snapshot rather than stream a backup, and volumeSnapshotClass names the VolumeSnapshotClass your CSI driver provides. The retention block prunes old snapshots on the schedule you set. Your storage provider must support the Kubernetes VolumeSnapshot API for this to work.

Snapshot backups complement the streamed and logical backups the operator already supports; they do not replace them. Snapshots usually live in the same storage account and region as the volumes they copy, so keep a streamed backup to object storage for off-site and cross-region disaster recovery. A practical policy pairs frequent fast snapshots for quick local recovery with a less frequent streamed backup for durability, and the operator runs both from the same backup.tasks list.


Note:
PVC snapshot backups are a tech preview in 1.23.0 and are not recommended for production yet. Snapshot portability and retention semantics depend on your CSI driver, so test restores before you rely on them.


Other improvements

Beyond the three headline features, 1.23.0 ships a set of enhancements that smooth day-two operations:

  • Operator-generated connection string Secrets (K8SPSMDB-1537): the operator now publishes a ready-to-use MongoDB connection string (URI) in a Kubernetes Secret for the databaseAdmin user. An application can read that one Secret and connect to it, instead of building the URI itself from Pod names, Services, TLS settings, and credentials.
  • Workload Identity for GCS backups (K8SPSMDB-1602): back up to Google Cloud Storage without storing a service-account JSON key in a Secret.
  • Oracle Cloud Infrastructure Object Storage (K8SPSMDB-1644) and Alibaba Cloud OSS (K8SPSMDB-1519): two more native backup destinations.
  • Restore a collection under a different name (K8SPSMDB-1603): use selective.nsFrom and nsTo to restore one collection alongside the live one for inspection or recovery.
  • External nodes as arbiters (K8SPSMDB-1031): set arbiterOnly: true on an external node to place a tie-breaker vote in a third location without a data-bearing member.
  • cert-manager ClusterIssuer and TLS policy (K8SPSMDB-1413, K8SPSMDB-1458): point the operator at an existing ClusterIssuer, and use certManagementPolicy to keep certificate lifecycle fully under your control.
  • Tunable reconciliation interval (K8SPSMDB-1571): set RECONCILE_INTERVAL to reduce Kubernetes API load on large fleets (default 5s).
  • Query Analytics via mongolog for PMM (K8SPSMDB-1546): choose mongolog as the QAN source in Percona Monitoring and Management.
  • Custom sidecar health probes (K8SPSMDB-1701, K8SPSMDB-1728) and StatefulSet revisionHistoryLimit (K8SPSMDB-1572): finer control over probes and rollout history. 

For the full list, including bug fixes, see the release notes linked below.


Conclusion

Percona Operator for MongoDB 1.23.0 covers the arc from getting data in to keeping it safe: ClusterSync brings a live database onto the operator with a short cutover, vector search lets one system serve both documents and semantic queries, and PVC snapshot backups take the network out of the backup path. With RKE2 and full ARM64 support added, more of that runs on the platforms teams actually use. If there is a workflow you still script around the operator, tell us on the forum, since that is where releases like this one come from.


Try Percona Operator for MongoDB 1.23.0


The post Percona Operator for MongoDB 1.23.0: ClusterSync Migration, Vector Search, and PVC Snapshot Backups appeared first on Percona.

Jul
14
2026
--

Inside MySQL 9.7 LTS Features

MySQL 9.7, a Long-Term Support (LTS) release, incorporates a variety of potential features spanning across multiple technical domains. This article covers some of the primary features introduced and evaluates their practical utility within the MySQL database environment.

Following the End-of-Life (EOL) status of MySQL 8.0, this subsequent LTS release is designed to provide enhanced stability alongside significant architectural innovations.

Let’s discuss each of these features below with some examples and usage.

Flow-control monitoring in Group Replication

Flow control monitoring has been improved and provides more granularity by introducing the additional status variables listed below.

  • Gr_flow_control_throttle_count : It denotes the number of transactions that have been throttled.
  • Gr_flow_control_throttle_time_sum :It denotes the time in microseconds that transactions have been throttled.
  • Gr_flow_control_throttle_active_count :It denotes the number of transactions currently being throttled.
  • Gr_flow_control_throttle_last_throttle_timestamp : It denotes the most recent date and time that a transaction was throttled.

To use these status variables, we must install the “Group Replication Flow Control Statistics”  component.

mysql> Install component 'file://component_group_replication_flow_control_stats';

After the component is installed, the statistics will be visible.

mysql> SELECT * FROM performance_schema.global_status WHERE VARIABLE_NAME LIKE 'Gr_flow_control%';
+--------------------------------------------------+----------------+
| VARIABLE_NAME                                    | VARIABLE_VALUE |
+--------------------------------------------------+----------------+
| Gr_flow_control_throttle_active_count            | 0              |
| Gr_flow_control_throttle_count                   | 0              |
| Gr_flow_control_throttle_last_throttle_timestamp |                |
| Gr_flow_control_throttle_time_sum                | 0              |
+--------------------------------------------------+----------------+

Multi-threaded applier extended statistics

We now have additional verbosity for the Applier threads for both Asynchronous and Group Replication topologies. This means we can get more details of the transactions or potential misbehaviours during the transactions applier stage. This feature is particularly useful for troubleshooting performance bottlenecks in multi-threaded replication environments, where understanding the specific cause of lag can be challenging.

This requires installing the “Replication Applier Metrics” component.

mysql> Install component 'file://component_replication_applier_metrics';

Upon successful installation of the requisite component, the performance schema tables facilitate tracking of transaction details and various performance metrics during the replication applier phase. For instance, monitoring the table “replication_applier_metrics” enables observing channel-specific operations.

mysql> SELECT * FROM performance_schema.replication_applier_metrics where CHANNEL_NAME='group_replication_applier'\G;
*************************** 1. row ***************************
                                CHANNEL_NAME: group_replication_applier
                  TOTAL_ACTIVE_TIME_DURATION: 0
                          LAST_APPLIER_START: 0000-00-00 00:00:00
                TRANSACTIONS_COMMITTED_COUNT: 0
                  TRANSACTIONS_ONGOING_COUNT: 0
                  TRANSACTIONS_PENDING_COUNT: 0
       TRANSACTIONS_COMMITTED_SIZE_BYTES_SUM: 0
    TRANSACTIONS_ONGOING_FULL_SIZE_BYTES_SUM: 0
TRANSACTIONS_ONGOING_PROGRESS_SIZE_BYTES_SUM: 0
         TRANSACTIONS_PENDING_SIZE_BYTES_SUM: NULL
                      EVENTS_COMMITTED_COUNT: 0
            WAITS_FOR_WORK_FROM_SOURCE_COUNT: 0
         WAITS_FOR_WORK_FROM_SOURCE_SUM_TIME: 0
            WAITS_FOR_AVAILABLE_WORKER_COUNT: 0
         WAITS_FOR_AVAILABLE_WORKER_SUM_TIME: 0
      WAITS_COMMIT_SCHEDULE_DEPENDENCY_COUNT: 0
   WAITS_COMMIT_SCHEDULE_DEPENDENCY_SUM_TIME: 0
         WAITS_FOR_WORKER_QUEUE_MEMORY_COUNT: 0
      WAITS_FOR_WORKER_QUEUE_MEMORY_SUM_TIME: 0
              WAITS_WORKER_QUEUES_FULL_COUNT: 0
           WAITS_WORKER_QUEUES_FULL_SUM_TIME: 0
             WAITS_DUE_TO_COMMIT_ORDER_COUNT: 0
          WAITS_DUE_TO_COMMIT_ORDER_SUM_TIME: 0
        TIME_TO_READ_FROM_RELAY_LOG_SUM_TIME: 0

In addition to aggregate metrics, MySQL 9.7 provides a way to inspect the progress of individual worker threads via monitoring stats in the “replication_applier_progress_by_worker” table. This level of detail helps administrators identify if a single transaction is monopolising a specific worker, causing overall replication delay.

mysql> SELECT * FROM performance_schema.replication_applier_progress_by_worker\G;
*************************** 1. row ***************************
                          CHANNEL_NAME: group_replication_applier
                             WORKER_ID: 0
                             THREAD_ID: 62
              ONGOING_TRANSACTION_TYPE: UNASSIGNED
   ONGOING_TRANSACTION_FULL_SIZE_BYTES: 0
ONGOING_TRANSACTION_APPLIED_SIZE_BYTES: 0
*************************** 2. row ***************************
                          CHANNEL_NAME: group_replication_applier
                             WORKER_ID: 1
                             THREAD_ID: 63
              ONGOING_TRANSACTION_TYPE: UNASSIGNED
   ONGOING_TRANSACTION_FULL_SIZE_BYTES: 0
ONGOING_TRANSACTION_APPLIED_SIZE_BYTES: 0
*************************** 3. row ***************************
                          CHANNEL_NAME: group_replication_applier
                             WORKER_ID: 2
                             THREAD_ID: 64
              ONGOING_TRANSACTION_TYPE: UNASSIGNED
   ONGOING_TRANSACTION_FULL_SIZE_BYTES: 0
ONGOING_TRANSACTION_APPLIED_SIZE_BYTES: 0
*************************** 4. row ***************************
                          CHANNEL_NAME: group_replication_applier
                             WORKER_ID: 3
                             THREAD_ID: 65
              ONGOING_TRANSACTION_TYPE: UNASSIGNED
   ONGOING_TRANSACTION_FULL_SIZE_BYTES: 0
ONGOING_TRANSACTION_APPLIED_SIZE_BYTES: 0

Automatic eviction & rejoin

The Group Replication resource manager now provides auto-eviction functionality, which we can configure using the available options. This basically ensures that the unhealthy node is removed from the Group to maintain the cluster’s high availability and overall performance.

This requires installing the “group replication resource manager” component.

mysql> INSTALL COMPONENT 'file://component_group_replication_resource_manager';

Once the component is available,  we can use various options to decide the node expulsion policy.

1) Applier channel

We can set the applier channel replication lag threshold values using the configuration parameter below.

mysql> set global group_replication_resource_manager.applier_channel_lag = <value>;

If lag exceeds  “applier_channel_lag” threshold 10 times or more in a row, this server is expelled from the group. The status variable below is used for tracking the lag exceed rate.

mysql> show global status like 'Gr_resource_manager_applier_channel_lag';
+-----------------------------------------+-------+
| Variable_name                           | Value |
+-----------------------------------------+-------+
| Gr_resource_manager_applier_channel_lag | 0     |
+-----------------------------------------+-------+


2) Recovery Channel

Similarly, we can define a threshold for the group member recovery process to attempt to rejoin the cluster. 

mysql> set global group_replication_resource_manager.recovery_channel_lag = <value>;

If the secondary’s recovery lag exceeds “recovery_channel_lag”, 10 times or more in succession, the server is expelled from the group. 

mysql show global status like 'Gr_resource_manager_recovery_channel_lag';
+------------------------------------------+-------+
| Variable_name                            | Value |
+------------------------------------------+-------+
| Gr_resource_manager_recovery_channel_lag | 0     |
+------------------------------------------+-------+

3) Memory/Resource Usage

We can also define an expelled condition based on the group member’s memory or resource usage %.

mysql> set global group_replication_resource_manager.memory_used_limit = 10;

If the memory usage exceeds memory_used_limit % by 10 or more consecutive times, the node will be expelled from the group.

mysql> show global status like 'Gr_resource_manager_memory_used%';
+---------------------------------+-------+
| Variable_name                   | Value |
+---------------------------------+-------+
| Gr_resource_manager_memory_used | 78    |
+---------------------------------+-------+
1 row in set (0.002 sec)

In addition to the discussed options above, we can also track various server status variables to monitor group replication and the resource manager component.

mysql> select * from performance_schema.global_status where variable_name in ('Gr_resource_manager_applier_channel_threshold_hits','Gr_resource_manager_applier_channel_eviction_timestamp','Gr_resource_manager_recovery_channel_threshold_hits','Gr_resource_manager_recovery_channel_eviction_timestamp','Gr_resource_manager_memory_threshold_hits','Gr_resource_manager_memory_eviction_timestamp');
+---------------------------------------------------------+----------------+
| VARIABLE_NAME                                           | VARIABLE_VALUE |
+---------------------------------------------------------+----------------+
| Gr_resource_manager_applier_channel_eviction_timestamp  |                |
| Gr_resource_manager_applier_channel_threshold_hits      | 0              |
| Gr_resource_manager_memory_eviction_timestamp           |                |
| Gr_resource_manager_memory_threshold_hits               | 6703           |
| Gr_resource_manager_recovery_channel_eviction_timestamp |                |
| Gr_resource_manager_recovery_channel_threshold_hits     | 0              |
+---------------------------------------------------------+----------------+
6 rows in set (0.003 sec)

The expelled node can attempt to automatically rejoin based on the value of the group_replication_autorejoin_tries variable.

mysql> show variables like '%group_replication_autorejoin_tries%';
+------------------------------------+-------+
| Variable_name                      | Value |
+------------------------------------+-------+
| group_replication_autorejoin_tries | 3     |
+------------------------------------+-------+
1 row in set (0.006 sec)

If the node cannot join, it will perform the behaviour specified in the group_replication_exit_state_action variable.

mysql> show variables like '%group_replication_exit_state_action%';
+-------------------------------------+--------------+
| Variable_name                       | Value        |
+-------------------------------------+--------------+
| group_replication_exit_state_action | OFFLINE_MODE |
+-------------------------------------+--------------+
1 row in set (0.005 sec)

After a server is evicted from the group (for whatever reason), it gets a grace period (group_replication_resource_manager) when it rejoins. During this period, the Resource Manager won’t immediately kick it out again, even if it’s still lagging or breaching the defined threshold as discussed above.

mysql> show variables like '%group_replication_resource_manager.quarantine_time%';
+----------------------------------------------------+-------+
| Variable_name                                      | Value |
+----------------------------------------------------+-------+
| group_replication_resource_manager.quarantine_time | 3600  |
+----------------------------------------------------+-------+

Up-to-date aware Primary election

The Primary election process is more mature and cohesive. The Group Replication Manager now uses the most up-to-date status as a criterion for selecting the new primary.

Here is how the Group Replication Manager performs the most up-to-date primary selection prior to MySQL v9.7.

  1. The lowest MySQL version is checked for each member.
  2. If more than one member is running the lowest MySQL Server version, each member’s weight is determined by the “group_replication_member_weight” system variable.
  3. If there is more than one member running the lowest MySQL Server version, and also more than one of those members has the highest member weight, the third factor considered is the lexicographical order of the generated server UUIDs “server_uuid” of each group member. The member with the lowest server UUID is chosen as the new primary.

In MySQL version 9.7, “group_replication_elect_prefers_most_updated” was introduced, so the failover will be determined by how many transactions are in the secondary backlog. Basically the secondary with the least backlog will be selected as Primary.

Now, it will consider the “most up-to-date” node first, then “weight” and then “UUID”

To use “group_replication_elect_prefers_most_updated”, we need to install the “Group Replication Primary Election” component listed below on each Group Member.

mysql> Install component 'file://component_group_replication_elect_prefers_most_updated';

By default, the most up-to-date group member selection is enabled. We need to make sure it’s enabled on all Group Members. 

mysql> select @@group_replication_elect_prefers_most_updated.enabled;
+--------------------------------------------------------+
| @@group_replication_elect_prefers_most_updated.enabled |
+--------------------------------------------------------+
|                                                      1 |
+--------------------------------------------------------+
1 row in set (0.007 sec)

In the event that a new primary is elected via the most up-to-date selection mechanism, this metric represents the transaction processing differential between the newly designated primary and the secondary node with the highest level of synchronisation.

mysql> show status like 'Gr_latest_primary_election_by_most_uptodate_members_trx_delta';
+---------------------------------------------------------------+-------+
| Variable_name                                                 | Value |
+---------------------------------------------------------------+-------+
| Gr_latest_primary_election_by_most_uptodate_members_trx_delta | 0     |
+---------------------------------------------------------------+-------+

Also, we can track the timestamp of the most recent primary election on the most up-to-date node.

mysql> show status like 'Gr_latest_primary_election_by_most_uptodate_member_timestamp';
+--------------------------------------------------------------+-------+
| Variable_name                                                | Value |
+--------------------------------------------------------------+-------+
| Gr_latest_primary_election_by_most_uptodate_member_timestamp |       |
+--------------------------------------------------------------+-------+
1 row in set (0.005 sec)

The database logs also tell exactly what criteria the primary member selected during failover.

2026-06-14T10:04:02.243809Z 0 [System] [MY-015575] [Repl] Plugin group_replication reported: 'Member with uuid 00021702-2222-2222-2222-222222222222 was elected primary since it was the most up-to-date member with 2755 transactions more than second most up-to-date member 00021703-3333-3333-3333-333333333333. In case of a tie member weight and then uuid lexical order was used over the most updated members.'

MySQL JSON duality views

With the introduction of JSON duality views, we can leverage a single unified JSON document for both relational and hierarchical JSON data. This provides a common, structured JSON format for the application, allowing it to perform both read and write operations.

Let’s see a quick scenario below on how it works.

Below are two relational tables from which we obtain aggregated information in JSON format. 

mysql> CREATE TABLE products (
  product_id INT PRIMARY KEY,
  product_type VARCHAR(100)
);

mysql> CREATE TABLE products_details (
  product_detail_id INT PRIMARY KEY,
  product_id INT,
  name VARCHAR(100),
  active varchar(10)
);

mysql> INSERT INTO products (product_id,product_type) VALUES (1,'IT'), (2,'TEL');
mysql> INSERT INTO products_details (product_detail_id,product_id,name,active) VALUES (1,1,'Laptop','Yes'), (2,2,'Mobile','Yes');

Here is the exact Json View which fetch the columns from the relation table based on the join condition. Each of those relational table columns is mapped with a JSON data structure (_id,v_product_type,v_product_type ), and the complete details of the product details table are fetched into the (product) array.

mysql> CREATE JSON RELATIONAL DUALITY VIEW view_product AS
SELECT JSON_DUALITY_OBJECT( WITH(INSERT,UPDATE,DELETE)
    '_id': product_id,
    'v_product_type': product_type,
    'product': (
        SELECT JSON_ARRAYAGG(
            JSON_DUALITY_OBJECT(WITH(INSERT,UPDATE,DELETE)
                'v_product_detail_id': product_detail_id,
                'v_name': name,
                'v_active': active
                
            )
        )
        FROM products_details
        WHERE products_details.product_id = products.product_id
    )
)
FROM products;

mysql> select * from view_product;
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| data                                                                                                                                                                           |
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| {"_id": 1, "product": [{"v_name": "Laptop", "v_active": "Yes", "v_product_detail_id": 1}], "_metadata": {"etag": "313642c2aa24f0571264332afa140715"}, "v_product_type": "IT"}  |
| {"_id": 2, "product": [{"v_name": "Mobile", "v_active": "Yes", "v_product_detail_id": 2}], "_metadata": {"etag": "3d229ada02ac660f9f6cac994b44831a"}, "v_product_type": "TEL"} |
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
2 rows in set (0.002 sec)

Once the duality view is created, we can perform both read/write operations.

Reading the duality view

mysql> select * from view_product;
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| data                                                                                                                                                                           |
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| {"_id": 1, "product": [{"v_name": "Laptop", "v_active": "Yes", "v_product_detail_id": 1}], "_metadata": {"etag": "313642c2aa24f0571264332afa140715"}, "v_product_type": "IT"}  |
| {"_id": 2, "product": [{"v_name": "Mobile", "v_active": "Yes", "v_product_detail_id": 2}], "_metadata": {"etag": "3d229ada02ac660f9f6cac994b44831a"}, "v_product_type": "TEL"} |
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+

Writing the underlying table in the duality view

mysql> UPDATE view_product
SET data = JSON_SET(
    data,
    '$.product[0].v_name',
    'Notepad'
)
WHERE JSON_EXTRACT(data, '$._id') = 1;

mysql> select * from products_details;
+-------------------+------------+---------+--------+
| product_detail_id | product_id | name    | active |
+-------------------+------------+---------+--------+
|                 1 |          1 | Notepad | Yes    |
|                 2 |          2 | Mobile  | Yes    |
+-------------------+------------+---------+--------+

After performing the above write operations, we can see that the view now shows the updated data.

mysql > select * from view_product;
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| data                                                                                                                                                                           |
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+
| {"_id": 1, "product": [{"v_name": "Notepad", "v_active": "Yes", "v_product_detail_id": 1}], "_metadata": {"etag": "72c4368420cdc698842d0ab4bd9315ab"}, "v_product_type": "IT"} |
| {"_id": 2, "product": [{"v_name": "Mobile", "v_active": "Yes", "v_product_detail_id": 2}], "_metadata": {"etag": "3d229ada02ac660f9f6cac994b44831a"}, "v_product_type": "TEL"} |
+--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------+

Hypergraph Optimizer

With the Hypergraph Optimiser, we now have more advanced optimisation for complex queries and a broader set of Join plans than the older traditional method, missing earlier. By using “Join hypergraph”, the optimiser now has better reach to all tables in the join condition.

Hypergraph Optimiser is OFF

mysql> SET optimizer_switch='hypergraph_optimizer=off';

mysql> SELECT t1.k, COUNT(*) AS cnt
FROM sbtest1 t1
JOIN sbtest2 t2 ON t1.id = t2.id
JOIN sbtest3 t3 ON t1.id = t3.id
WHERE t1.k BETWEEN 200000 AND 500000
GROUP BY t1.k
ORDER BY cnt DESC
LIMIT 100;

Output:

| 498870 | 119 |
| 498729 | 119 |
| 497668 | 119 |
| 498076 | 119 |
+--------+-----+
100 rows in set (4.000 sec)

Explain output:

-> Limit: 100 row(s)
    -> Sort: cnt DESC, limit input to 100 row(s) per chunk
        -> Stream results  (cost=1.22e+6 rows=175136)
            -> Group aggregate: count(0)  (cost=1.22e+6 rows=175136)
                -> Nested loop inner join  (cost=1.1e+6 rows=493200)
                    -> Nested loop inner join  (cost=601547 rows=493200)
                        -> Filter: (t1.k between 200000 and 500000)  (cost=99122 rows=493200)
                            -> Covering index range scan on t1 using k_1 over (200000 <= k <= 500000)  (cost=99122 rows=493200)
                        -> Single-row covering index lookup on t2 using PRIMARY (id = t1.id)  (cost=0.919 rows=1)
                    -> Single-row covering index lookup on t3 using PRIMARY (id = t1.id)  (cost=0.919 rows=1)

Hypergraph Optimiser is ON

mysql> SET optimizer_switch='hypergraph_optimizer=on';

mysql> SELECT t1.k, COUNT(*) AS cnt
FROM sbtest1 t1
JOIN sbtest2 t2 ON t1.id = t2.id
JOIN sbtest3 t3 ON t1.id = t3.id
WHERE t1.k BETWEEN 200000 AND 500000
GROUP BY t1.k
ORDER BY cnt DESC
LIMIT 100;

Output:

| 499721 | 119 |
| 499052 | 119 |
| 498870 | 119 |
| 498384 | 119 |
+--------+-----+
100 rows in set (0.498 sec)

Explain output:

-> Sort: cnt DESC, limit input to 100 row(s) per chunk  (cost=1.96e+6..1.96e+6 rows=100)
    -> Table scan on <temporary>  (cost=1.87e+6..1.9e+6 rows=175136)
        -> Aggregate using temporary table  (cost=1.87e+6..1.87e+6 rows=175136)
            -> Inner hash join (t2.id = t3.id)  (cost=990754..1.44e+6 rows=493200)
                -> Covering index scan on t3 using k_1  (cost=0.312..308240 rows=986400)
                -> Hash
                    -> Inner hash join (t1.id = t2.id)  (cost=370988..824021 rows=493200)
                        -> Covering index scan on t2 using k_1  (cost=0.312..308240 rows=986400)
                        -> Hash
                            -> Filter: (t1.k between 200000 and 500000)  (cost=0.416..205287 rows=493200)
                                -> Covering index range scan on t1 using k_1 over (200000 <= k <= 500000)  (cost=0.359..176877 rows=493200)

We can see that with “hypergraph_optimizer=enabled”, the query execution time is almost 8x faster.

The performance difference might not be noticeable with a few joins or a smaller table’s data set, but with more complex joins, it can yield better performance. In the above example, we can see that when “hypergraph_optimizer=enabled”, the optimiser replaces “Nested loop inner join” with “Inner hash join”, which is generally better for large datasets. 

Higher version source allowed

Now, it’s possible that a lower version replica can connect to a higher version source when the major versions differ. That means we don’t have to rely on all replicas being upgraded in one go; we can just upgrade the source, verify it, and later perform rolling upgrades on lower-version replicas as per our own timelines and convenience.

Of course, we have to be cautious not to run any such feature or change on the source that doesn’t support lower-version replicas.

Please note – This won’t be applicable to previous releases, say (8.4, 8.0), as they didn’t restrict such replication connectivity. It would be useful for 9.7 or the next major release.

To enable this functionality, we need to ensure the following variable is enabled on the Replica. By default its enabled on 9.7

mysql> show variables like 'replica_allow_higher_version_source';
+-------------------------------------+-------+
| Variable_name                       | Value |
+-------------------------------------+-------+
| replica_allow_higher_version_source | ON    |
+-------------------------------------+-------+
1 row in set (0.008 sec)

Summary

The above discussion highlights key advancements in MySQL 9.7 LTS, ranging from some innovative or operational improvements to developer-centric features such as “JSON Duality” Views. Also, the “Hypergraph Optimiser” is now available for community release, which was previously exclusive to MySQL Heatwave/Enterprise.  As a Long-Term Support (LTS) release, MySQL 9.7 is structured to provide a stable and consistent environment, prioritising architectural reliability over frequent experimental changes.

One more important mention here: It’s suggested to use MySQL 9.7.1, or the next sub-releases, as 9.7.0 has some higer severity CVE’s. If you are using Percona Server for MySQL (PS), we skipped 9.7.0 and are shipping the fixed 9.7.1 version directly.

Still, it’s highly recommended to test any new component or changes in your lower/staging environment before deploying in production to better assess the overall impact on existing workload, queries, and database behaviour.


The post Inside MySQL 9.7 LTS Features appeared first on Percona.
Jul
10
2026
--

Running DuckDB as a MySQL 9.7 storage engine

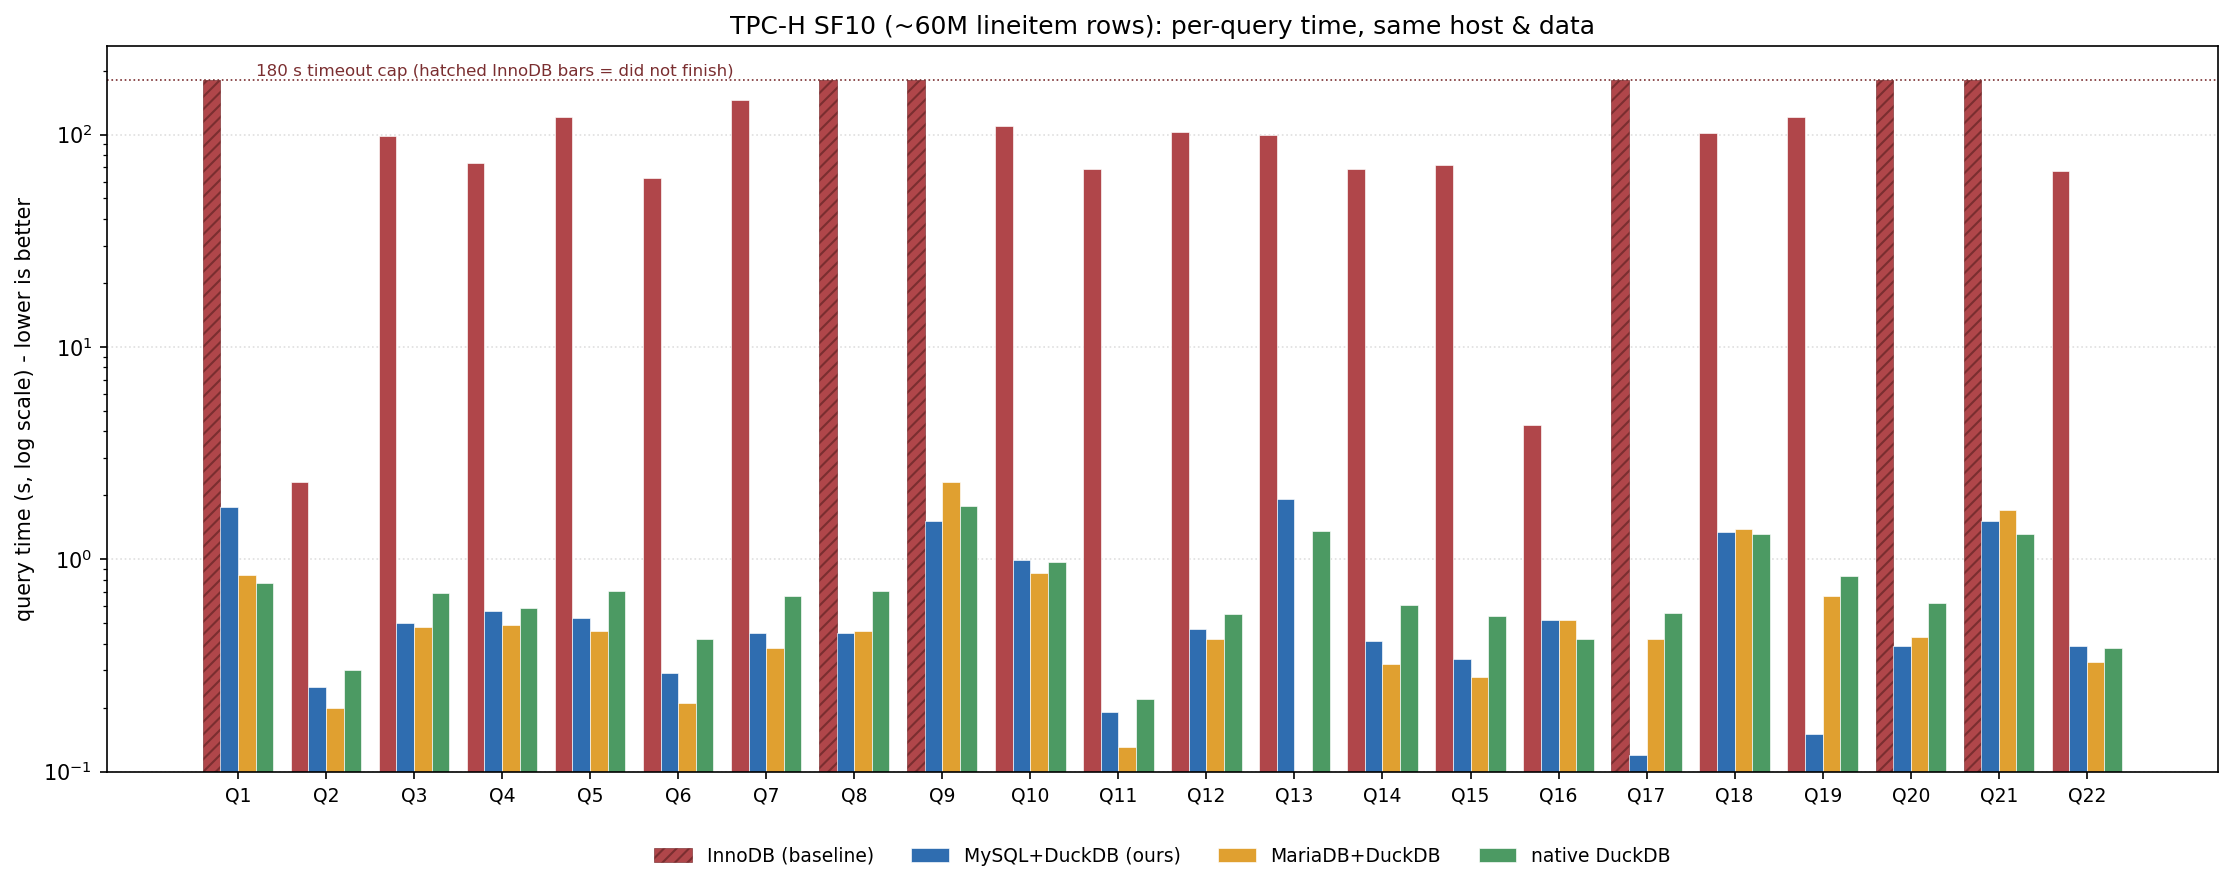
ducksdb-mysql-engine is an experimental build of MySQL 9.7 where a table you mark ENGINE=DuckDB answers analytical queries from DuckDB instead of InnoDB. Same server, same connection, no second copy of the data. On TPC-H at scale factor 10, InnoDB times out on 6 of the 22 queries and burns 1317 seconds on the 16 it finishes. The DuckDB tables run all 22 in about 15 seconds.

It’s an experiment, not production software. It patches mysqld and has rough edges, which we list at the end. Source is on GitHub under GPLv2:     https://github.com/EvgeniyPatlan/ducksdb-mysql-engine.

Why we made it

MySQL is great for transactions and slow at analytics. A wide GROUP BY over a few hundred million rows, or a six-way join, takes minutes on InnoDB. The usual fix is to copy the data into a column store and keep it in sync, so now you’re running two systems and the pipeline between them.

We wanted the table itself to be the column store, with the heavy queries offloaded for you. Mark it ENGINE=DuckDB, query it the way you always have, and DuckDB does the analytical work.

What it actually is

DuckDB is an in-process columnar query engine, basically SQLite for OLAP. It stores data by column and it’s built for scans and aggregations, which is exactly what a row store is bad at.

We’re not the first to put it behind a relational table. Alibaba’s AliSQL has had a built-in DuckDB engine for a while. MariaDB shipped MariaDB DuckDB about a week ago, while we were already building ours. AliSQL got there first; MariaDB and we landed on the same idea independently, around the same time, them on MariaDB and us on stock MySQL 9.7. Their engine is the closest comparison to ours, so it’s in the benchmarks below.

How it hooks into MySQL

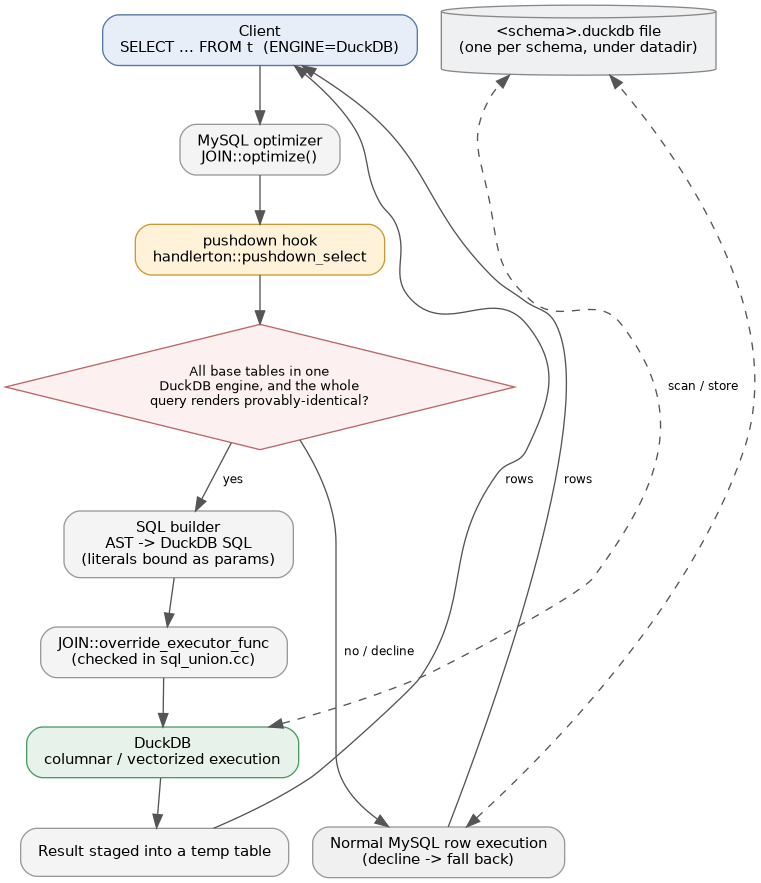
MySQL doesn’t have a select_handler, the API MariaDB uses to grab a whole SELECT and run it inside an engine. We added our own: a handlerton::pushdown_select hook.

The pushdown path. Either the whole query renders to DuckDB SQL and runs columnar, or it declines and the normal row path handles it.

The engine is compiled into mysqld, and each schema is one DuckDB file under the datadir. Three patches do the integration, and all three are generic, so they’ll fire for any engine that exposes the hook:

  • The hook runs at the end of JOIN::optimize(). If every base table in the block is one engine that has the hook, that engine looks at the optimized JOIN, and if it can translate the whole query it sets JOIN::override_executor_func (which the executor already checks in sql_union.cc). The query gets regenerated as DuckDB SQL, prepared once, run, and the aggregated result is staged into a temp table. EXPLAIN is left alone.
  • A server-side LOAD DATA INFILE goes into a DuckDB COPY instead of crawling through write_row row by row. At 600M rows that’s a 20-minute load instead of 80.
  • For single-engine statements we clear OPTIMIZER_SWITCH_SEMIJOIN in prepare, so IN, EXISTS, NOT IN and NOT EXISTS stay as subqueries the builder can render instead of getting rewritten into semijoin nests it can’t recognize.

The builder only renders a node when the output is provably identical to what MySQL would return. If it can’t, it declines and MySQL runs the query unchanged. Literals are bound as parameters. Collation, NULL ordering and decimal scale are matched on purpose, and an unmapped collation or a REAL literal is enough to make it back off. With that in place, all 22 TPC-H queries push down and match InnoDB row for row.


Getting started

The fastest way in is the image:

docker run -d --name mysql-duckdb -p 3306:3306 \
-e MYSQL_ROOT_PASSWORD=secret \
-v mysql-duckdb-data:/var/lib/mysql \
evgeniypatlan/test-images:mysql-9.7-duckdb-v0.2.0

Make a table, put a few rows in, run an aggregate:

CREATE DATABASE shop; USE shop;
CREATE TABLE sales (id INT PRIMARY KEY, region INT, amount DECIMAL(12,2)) ENGINE=DuckDB;
INSERT INTO sales VALUES (1,1,100),(2,1,200),(3,2,50);

SELECT region, SUM(amount) FROM sales GROUP BY region;
-- region | SUM(amount)
-- 1 | 300.00
-- 2 | 50.00


Nothing about that query is special, and that is the point. To check it actually went to DuckDB rather than down the row path, watch the Ducksdb_pushdown_count status variable:

SELECT region, SUM(amount) FROM sales GROUP BY region; -- offloaded
SHOW STATUS LIKE 'Ducksdb_pushdown_count'; -- counter goes +1

SELECT * FROM sales WHERE id = 3; -- point lookup
SHOW STATUS LIKE 'Ducksdb_pushdown_count'; -- counter unchanged


The single-row lookup stays on the row path deliberately. For one row an index seek beats spinning up a DuckDB result, so there is no reason to offload it. OLTP keeps its path, analytics get the column store, and you do not pick by hand.

If you would rather build it, you need the MySQL 9.7 tree under vendor/mysql-server/ and a DuckDB prefix, then:

ln -s ../../engine vendor/mysql-server/storage/duckdb
scripts/build-server.sh # applies the 3 patches, builds mysqld + clients


Does it actually go fast?

All 22 TPC-H queries, were executed in a Docker on one laptop (20 cores, 62 GiB RAM), the same data loaded into four engines: InnoDB, our MySQL+DuckDB, MariaDB+DuckDB, and standalone DuckDB as the reference. Warm wall-clock, minimum over a few runs, in seconds.

SF10, around 60 million lineitem rows

A handful of rows here; the whole table is in docs/tpch_engine_comparison.md:

Query InnoDB MySQL+DuckDB MariaDB +DuckDB Native DuckDB
Q1 >180 1.77 0.84 0.77
Q5 127.6 0.53 0.46 0.71
Q7 145.0 0.45 0.38 0.67
Q9 >180 1.52 2.30 1.78
Q18 101.7 1.35 1.39 1.31
Q19 120.4 0.15 0.67 0.83
All 22  Finished 16/22 15.1s 13.3s 16.3


SF10, all 22 queries, log scale (lower is better). Hatched InnoDB bars did not finish inside 180 s. The three DuckDB engines sit in a tight band near the floor.

InnoDB is somewhere between 100 and 340 times slower per query, and on 6 of the 22 it never finished inside the 180-second cap (the correlated subqueries and the heaviest scans). It burned 1317 seconds on just the 16 it did finish. The three DuckDB engines get through all 22 in about 15 seconds, and ours lands right between MariaDB and plain DuckDB. The gap is so big there is not much else to say about it.

SF100, around 600 million lineitem rows

At this size InnoDB is out of the running (a copy of the data alone is about 100 GB and queries run for hours), so it is the three DuckDB engines only, run one at a time:

Query MySQL+DuckDB MariaDB+DuckDB Native DuckDB
Q1 15.25 6.50 5.50
Q9 20.97 115.29 19.54
Q10 10.64 ERR 8.14
Q13 19.75 ERR 13.27
Q18 14.88 29.62 11.08
Q19 2.91 7.98 6.61
Correct 22/22 20/22 22/22


SF100, three DuckDB engines, log scale (lower is better). Q15 for our engine is shown at its matched-memory time (~4 s); the capped run measured 1309 s, explained below. MariaDB errored on Q10 and Q13.

At 600 million rows ours is still correct on all 22 and stays close to plain DuckDB. MariaDB’s engine drops two queries (Q10, and Q13 on its column-list syntax) and is a lot slower on the big joins – Q9 took 115 seconds against our 21 and native’s 20.

One honest word on Q15 at SF100, because in the full table it shows an ugly number for our engine. It is not a real loss. We capped DuckDB’s memory so it spills to disk instead of getting OOM-killed inside mysqld, and under that cap Q15’s CTE spills a lot. Give it the memory MariaDB had and it runs in about 4 seconds, like native. The answer was always right; only the clock was bad.

And one number we did not expect: loading those 600 million rows took about 20 minutes with our engine (the COPY shortcut) versus about 80 minutes with MariaDB, which loads row by row on a single core. Roughly four times faster to get the data in.

Try it, then tell us

If any of this sounds useful, pull the image and throw your own queries at it:

docker run -d -p 3306:3306 -e MYSQL_ROOT_PASSWORD=secret \
evgeniypatlan/test-images:mysql-9.7-duckdb-v0.2.0

The source is on GitHub (GPLv2), patches and benchmark harness included: https://github.com/EvgeniyPatlan/ducksdb-mysql-engine. The full per-query benchmark and how we measured it live in docs/tpch_engine_comparison.md.


The post Running DuckDB as a MySQL 9.7 storage engine appeared first on Percona.

Apr
30
2026
--

Continued Commitment to Percona XtraDB Cluster

At Percona, our priority has always been to provide the open source database solutions that our users can count on for the long term. Percona XtraDB Cluster (PXC) is a core part of that promise, delivering the high availability, scalability, and data integrity that mission-critical MySQL deployments depend on.

MariaDB has announced that September 30, 2026 will be the end-of-life date for continued maintenance and regular binary releases of MySQL Galera Cluster. We want to be clear about what this means for the organizations that rely on PXC: nothing is changing. Our commitment to PXC and the community that runs it is as strong as ever.

What is ending upstream is precisely what we already have in place. For anyone looking for an alternative path forward, PXC is the natural place to land.

What PXC users can count on

  • Our open Galera fork: Percona maintains its own Galera repository, open today and staying that way. We track upstream Galera releases, carry the fixes our customers need, and keep the codebase fully available for the community. PXC is built on this work, on terms we control.
  • Regular releases at the current cadence: Binary releases, bug fixes, and security patches continue to ship on the same terms and schedule our users have come to expect. You can review our full release history and release notes on the Percona documentation site.
  • Long-term support: PXC remains fully supported under our existing long-term support terms. If your organization is planning three to five years ahead, PXC is a safe foundation for those plans.
  • Compatibility and ecosystem integration: Strong binary compatibility with MySQL and Percona Server for MySQL, tight integration with Percona XtraBackup and Percona Monitoring and Management, and continued support across Kubernetes and traditional deployment environments.

What we’re continuing to invest in

Our engineering teams remain committed to making PXC better, focused on the things that make it a trusted choice: performance, stability, security, and a smooth operator experience. That work continues at pace. The PXC you depend on today will keep getting better, and the PXC you are evaluating for tomorrow will be ready when you need it.

Talk to us

If you have specific questions about your PXC deployment, your upgrade path, or your long-term high availability strategy, we’d love to hear from you. Reach out to your Percona contact, post a question in the Percona community forums, or connect with our team directly. High availability is too important to leave to uncertainty, and we are here to make sure you have the clarity and the support you need.

The post Continued Commitment to Percona XtraDB Cluster appeared first on Percona.

Apr
16
2026
--

MariaDB’s Snapshot Isolation: A Fix That Breaks More Than It Fixes

Jepsen’s analysis of MySQL 8.0.34 walked through a set of concurrency and isolation anomalies in InnoDB. MariaDB, which inherits the same codebase, took the report seriously and shipped a response: a new server variable called innodb_snapshot_isolation, turned on by default starting in 11.8. The announcement claims that with the flag enabled, Repeatable Read in MariaDB now satisfies snapshot isolation.

It’s a good intention. The problem is what actually ships.

Two things fall apart once you start looking. First, the fix isn’t complete — the anomalies Jepsen flagged can still be reproduced under concurrent load.

Second, it introduces incompatibilities with MySQL (in default enabled mode) – the moment the SNAPSHOT ISOLATION does fire as intended, it introduces ERROR 1020: Record has changed since last read into transactions that used to complete silently. That error now shows up in multiple applications, requiring to make changes either on code level or disabling innodb_snapshot_isolation

A quick refresher on what snapshot isolation promises

Snapshot isolation is supposed to let a transaction see a consistent view of the database taken at the moment it started.

Key behaviors of Snapshot Isolation:

  • Consistency: A transaction sees data as it was at its start time, ignoring updates from concurrent transactions.
  • Non-Blocking Reads: Readers do not block writers, and writers do not block readers, reducing contention.
  • Conflict Detection: A transaction only commits if its updates do not conflict with concurrent updates made since the snapshot was taken.

Two anomalies are specifically should not be present with Snapshot Isolation:

Lost Update Anomaly: Two transactions read the same value, both modify it, and one overwrites the other. Two users increment a counter from 10. Both read 10, both write 11. The correct answer is 12.

Non-Repeatable Read Anomaly: A transaction reads a row, someone else commits a change, and the first transaction reads the same row again and sees something different. Product price was $100, then it’s $120 — all inside one transaction.

What MySQL does today

Plain Repeatable Read handles the simple case (two reads) fine:

# Session A Session B A sees
1 SET TRANSACTION ISOLATION LEVEL REPEATABLE READ; START TRANSACTION;
2 SELECT name FROM test_nrr WHERE id=0; 'Alice'
3 UPDATE test_nrr SET name='Bob' WHERE id=0; (autocommit)
4 SELECT name FROM test_nrr WHERE id=0; 'Alice' ? RR holds
5 COMMIT;

Add a write on Session A between the two reads, though, and RR does not hold (we get Non-Repeatable Read Anomaly):

# Session A Session B A sees
1 SET TRANSACTION ISOLATION LEVEL REPEATABLE READ; START TRANSACTION WITH CONSISTENT SNAPSHOT;
2 SELECT name FROM test_nrr WHERE id=0; 'Alice'
3 UPDATE test_nrr SET name='Bob' WHERE id=0;
4 UPDATE test_nrr SET gender=99 WHERE id=0;
5 SELECT name FROM test_nrr WHERE id=0; 'Bob' ? Non-Repeatable Read

And here’s Lost Update under plain Repeatable Read in MySQL:

Time Session A Session B
t1 BEGIN;
t2 BEGIN;
t3 SELECT counter FROM t WHERE id=1; ? 10
t4 SELECT counter FROM t WHERE id=1; ? 10
t5 UPDATE t SET counter=10+1 WHERE id=1; COMMIT; (counter = 11)
t6 UPDATE t SET counter=10+1 WHERE id=1; COMMIT; (still 11)

Expected 12. Got 11. Session A’s increment is gone.

For the full picture of what every isolation level actually guarantees across engines, Martin Kleppmann’s Hermitage suite is the good reference: github.com/ept/hermitage.

What MariaDB is supposed to do

With innodb_snapshot_isolation=ON, the Non-Repeatable Read scenario should stop at step 4 with:

# Session A Session B A sees
1 SET TRANSACTION ISOLATION LEVEL REPEATABLE READ; START TRANSACTION WITH CONSISTENT SNAPSHOT;
2 SELECT name FROM test_nrr WHERE id=0; 'Alice'
3 UPDATE test_nrr SET name='Bob' WHERE id=0;
4 UPDATE test_nrr SET gender=99 WHERE id=0;
ERROR 1020: Record has changed since last read in table ‘test_nrr
5 TRANSACTION ROLLBACK


And the Lost Update case should force whichever transaction tries to commit the stale write to roll back instead. That’s the guarantee:


Time Session A Session B
t1 BEGIN;
t2 BEGIN;
t3 SELECT counter FROM t WHERE id=1; ? 10
t4 SELECT counter FROM t WHERE id=1; ? 10
t5 UPDATE t SET counter=10+1 WHERE id=1; COMMIT; (counter = 11)
t6 UPDATE t SET counter=10+1 WHERE id=1; -> ERROR 1020: Record has changed since last read in table 'test_nrr'

TRANSACTION ROLLBACK

That is in both cases MariaDB introduces

ERROR 1020: Record has changed since last read in table

What actually happens

Run it under concurrent load and both anomalies still turn up:

ERROR 1020 fires most of the time, but  not every time. A snapshot-isolation guarantee that only holds “usually” isn’t a guarantee. The whole reason you pick an isolation level is for the bound it gives you.

The another problem: compatibility

Even when the error does fire when it should, MariaDB, by default, introduced a new failure mode into every client connected to the database. Almost nothing in the MySQL ecosystem catches ERROR 1020 mid-transaction and retries. It sees an unexpected error, it bails.

Issues already filed against applications running on MariaDB 11.8:

These are apps that work on MySQL, work on earlier MariaDB, and now fail on 11.8. The clean workaround is turning the flag off — which defeats the point of shipping it on by default.

Where that leaves us

Jepsen pointed at real transactional anomalies and MariaDB tried to answer them.  But a partial fix that silently breaks working applications isn’t what “drop-in MySQL replacement” is supposed to mean. If the goal was to make migration easier, 11.8 went the other direction.

The post MariaDB’s Snapshot Isolation: A Fix That Breaks More Than It Fixes appeared first on Percona.

Apr
13
2026
--

Auditing Login Attempts in MySQL and MariaDB

My colleague Miguel wrote about ways to audit login attempts in MySQL over 13 years ago, and this is still a relevant subject. I decided to refresh this topic to include some important changes since then.

Very often, it is important to track login attempts to our databases due to security reasons as well as to catch application misconfigurations. I’ll focus here on the most convenient ways to log authentication attempts. While auditing all client connections is usually pointless on busy production systems, when even thousands of new client sessions may be authenticating per second, let’s concentrate especially on the failed ones.

The Error Log

All MySQL and MariaDB variants have an easy way of logging failed authentication attempts in the standard error log via elevated log verbosity. To enable it, in older MySQL versions up to 5.7, as well as in all MariaDB versions, set log_warnings = 2 (or higher).

In MySQL 5.7+, the role of setting the error log talkativeness was moved to the new variable: log_error_verbosity. MySQL 8.0+ no longer recognizes log_warnings. To log failed logins, set log_error_verbosity = 3 instead.

An example log entry when login credentials were incorrect may look like this:

2026-02-24T20:36:09.186218Z 22 [Note] [MY-010926] [Server] Access denied for user 'myuser2'@'192.168.121.12' (using password: YES)

Another error occurs when user credentials are fine, but the user does not have privileges to access a given database:

2026-02-24T23:12:19.600451Z 35 [Note] [MY-010914] [Server] Access denied for user 'myuser'@'192.168.46.%' to database 'test1'

Now, the problem with this is that the above note will only be printed when there is a system user allowing the source hostname, IP address, or subnet, and the actual username authentication phase is engaged. When the host is rejected early, we will not find anything in the error log! Only the client side will receive a rejection message, like this one:

$ mysql -h192.168.46.20 -uuser
ERROR 1130 (HY000): Host '192.168.46.13' is not allowed to connect to this MySQL server

Therefore, the error log cannot provide the complete information about failed login attempts if some are incoming from undefined hosts. Btw, the general log does not log these either.

The Audit Log (old type)

The traditional Audit Log Plugin feature, available in all recent MySQL variants, allows us to limit logging for connection activities, while we can ignore other queries. Unfortunately, we cannot log only failed logins, so the log may grow very fast when applications actively open new connections, and further filtering for failed attempts has to be done externally.

In Percona Audit Log Plugin, it can be done via the policy setting: audit_log_policy = LOGINS.

An example of a netcat TCP probe will result in the following audit log entry:

tail -1 /var/lib/mysql/audit.log |jq
{
  "audit_record": {
    "name": "Connect",
    "record": "2138_2026-02-26T09:32:27",
    "timestamp": "2026-02-26T09:33:54Z",
    "connection_id": "13",
    "status": 1158,
    "user": "",
    "priv_user": "",
    "os_login": "",
    "proxy_user": "",
    "host": "test-host1",
    "ip": "192.168.46.12",
    "db": ""
  }
}

The entry provides a status error code:

$ perror 1158
MySQL error code MY-001158 (ER_NET_READ_ERROR): Got an error reading communication packets

Interestingly, the corresponding error log entry has the same message with a different code:

2026-02-26T09:33:54.917323Z 13 [Note] [MY-010914] [Server] Got an error reading communication packets

Another example of an unknown user login attempt:

{
  "audit_record": {
    "name": "Connect",
    "record": "2142_2026-02-26T09:32:27",
    "timestamp": "2026-02-26T09:39:45Z",
    "connection_id": "17",
    "status": 1045,
    "user": "wronguser",
    "priv_user": "",
    "os_login": "",
    "proxy_user": "",
    "host": "test-host1",
    "ip": "192.168.46.12",
    "db": ""
  }
}

Here, we can determine that the user part is wrong, as the priv_user field is empty.

A typical legit client session will have two entries, with status “0”, i.e:

{"audit_record":{"name":"Connect","record":"2145_2026-02-26T09:32:27","timestamp":"2026-02-26T09:42:27Z","connection_id":"19","status":0,"user":"myuser","priv_user":"myuser","os_login":"","proxy_user":"","host":"test-host1","ip":"192.168.46.13","db":""}}
{"audit_record":{"name":"Quit","record":"2146_2026-02-26T09:32:27","timestamp":"2026-02-26T09:42:27Z","connection_id":"19","status":0,"user":"myuser","priv_user":"myuser","os_login":"","proxy_user":"","host":"test-host1","ip":"192.168.46.13","db":""}}

In the MariaDB Audit Plugin, connection events can be logged via the server_audit_events = CONNECT setting. An example logging attempt with the wrong password would be seen as:

20260226 10:52:48,test-host1,root,localhost,8,0,FAILED_CONNECT,,,1045
20260226 10:52:48,test-host1,root,localhost,8,0,DISCONNECT,,,0

The Audit Log Filter (new type)

The new audit log functionality comes as a plugin in versions 8.0.x or a component in versions 8.4+, and provides way higher flexibility and finer-grained control on what and when is logged.

With Audit Log Filter, to minimize noise and overhead, it is possible to log only failed login attempts, so legitimate application sessions won’t flood the log.

Here is an example of how to enable such a filter rule:

mysql› SELECT audit_log_filter_set_filter(
  'failed_logins_only',
  '{
    "filter": {
      "log": false,
      "class": {
        "name": "connection",
        "event": {
          "name": "connect",
          "log": {
            "not": {
              "field": { "name": "status", "value": "0" }
            }
          }
        }
      }
    }
  }'
);
mysql› SELECT audit_log_filter_set_user('%', 'failed_logins_only');

The above rules set logging for the connection class, for all events that resulted in an error (status is not success).

An example entry for a client trying to authenticate with the wrong user credentials may look like this (if JSON format is used):

{
    "timestamp": "2026-03-05 11:31:12",
    "id": 8,
    "class": "connection",
    "event": "connect",
    "connection_id": 31,
    "account": { "user": "wronguser", "host": "" },
    "login": { "user": "wronguser", "os": "", "ip": "192.168.121.16", "proxy": "" },
    "connection_data": {
      "connection_type": "ssl",
      "status": 1045,
      "db": ""
    },
    "connection_attributes": {
      "_pid": "3608615",
      "_platform": "x86_64",
      "_os": "Linux",
      "_client_name": "libmysql",
      "os_user": "przemek",
      "_client_version": "8.4.7-7"
    }
  }

And a simple TCP probe (netcat) may look like this:

{
    "timestamp": "2026-03-05 11:31:26",
    "id": 9,
    "class": "connection",
    "event": "connect",
    "connection_id": 32,
    "account": { "user": "", "host": "test-host1" },
    "login": { "user": "", "os": "", "ip": "192.168.46.13", "proxy": "" },
    "connection_data": {
      "connection_type": "tcp/ip",
      "status": 1158,
      "db": ""
    }
  }

Unfortunately, again, connections from unknown hosts are not logged. Logging attempts aborted early on the host validation phase, do not reach the audit log or any other log! This is because the validation occurs at the very beginning of the handshake workflow, and if it returns failure, the connection is terminated before reaching the logging capabilities.

To workaround this limitation and make all unsuccessful login attempts be logged, we need to create a catch-all user account. However, we don’t want to extend the possible attack surface at the same time, so let’s disable authentication entirely for such an account. We will need the no-login plugin first:

INSTALL PLUGIN mysql_no_login SONAME 'mysql_no_login.so';

Now, the following user entry will allow auditing connection attempts from any host/IP:

CREATE USER ''@'%' IDENTIFIED WITH mysql_no_login;

Now, specific port knocking may still not be logged, like with nmap, as the client sends a RST packet even before the initial MySQL “hello” packet. So, we will not see this session anywhere in the MySQL logs:

$ nmap 192.168.46.20 -sT -p 3306
Starting Nmap 7.94SVN ( https://nmap.org ) at 2026-03-11 07:24 CET
Nmap scan report for 192.168.46.20 (192.168.46.20)
Host is up (0.00021s latency).
PORT     STATE SERVICE
3306/tcp open  mysql
Nmap done: 1 IP address (1 host up) scanned in 0.02 seconds

The only way to capture the above would be to watch the wire protocol, i.e., with tcpdump.

Additional Instrumentation

The error log entries can be viewed in a more structured manner, with the P_S table, so the entry:

2026-02-25T20:46:40.779435Z 66 [Note] [MY-010926] [Server] Access denied for user 'wronguser'@'test-host1' (using password: YES)

Will have equivalent in:

mysql› select * from performance_schema.error_log order by LOGGED desc limit 1?G
*************************** 1. row ***************************
    LOGGED: 2026-02-25 20:46:40.779435
 THREAD_ID: 66
      PRIO: Note
ERROR_CODE: MY-010926
 SUBSYSTEM: Server
      DATA: Access denied for user 'wronguser'@'test-host1' (using password: YES)
1 row in set (0.00 sec)

And it allows SQL queries against the log, like aggregations:

mysql› select count(*) from performance_schema.error_log where ERROR_CODE='MY-010926';
+----------+
| count(*) |
+----------+
|       11 |
+----------+
1 row in set (0.00 sec)

Also, MySQL keeps track of connection attempts from external hosts in the host cache structure, which can be observed via performance_schema.host_cache view. The view provides statistics on the number of failed connections grouped by reason categories, together with success and failure timestamps. This view provides information only about source hosts’ connection events, but not users. An example output may look like this:

mysql› select * from performance_schema.host_cache?G
*************************** 1. row ***************************
                                        IP: 192.168.46.12
                                      HOST: test-host1
                            HOST_VALIDATED: YES
                        SUM_CONNECT_ERRORS: 2
                 COUNT_HOST_BLOCKED_ERRORS: 0
           COUNT_NAMEINFO_TRANSIENT_ERRORS: 0
           COUNT_NAMEINFO_PERMANENT_ERRORS: 0
                       COUNT_FORMAT_ERRORS: 0
           COUNT_ADDRINFO_TRANSIENT_ERRORS: 0
           COUNT_ADDRINFO_PERMANENT_ERRORS: 0
                       COUNT_FCRDNS_ERRORS: 0
                     COUNT_HOST_ACL_ERRORS: 0
               COUNT_NO_AUTH_PLUGIN_ERRORS: 0
                  COUNT_AUTH_PLUGIN_ERRORS: 3
                    COUNT_HANDSHAKE_ERRORS: 2
                   COUNT_PROXY_USER_ERRORS: 0
               COUNT_PROXY_USER_ACL_ERRORS: 0
               COUNT_AUTHENTICATION_ERRORS: 5
                          COUNT_SSL_ERRORS: 0
         COUNT_MAX_USER_CONNECTIONS_ERRORS: 0
COUNT_MAX_USER_CONNECTIONS_PER_HOUR_ERRORS: 0
             COUNT_DEFAULT_DATABASE_ERRORS: 2
                 COUNT_INIT_CONNECT_ERRORS: 0
                        COUNT_LOCAL_ERRORS: 0
                      COUNT_UNKNOWN_ERRORS: 0
                                FIRST_SEEN: 2026-02-25 20:41:57
                                 LAST_SEEN: 2026-02-26 09:02:35
                          FIRST_ERROR_SEEN: 2026-02-25 20:42:17
                           LAST_ERROR_SEEN: 2026-02-26 09:02:38
1 row in set (0.00 sec)

Depending on what was wrong with the connection or authentication attempt, a different counter will increment. For instance, when a user tries to log in with the default database, it does not have the privilege to, the COUNT_DEFAULT_DATABASE_ERRORS will increase. When an unknown user tries to log in without a password, the COUNT_AUTH_PLUGIN_ERRORS is used, but when any user (existing or not) tries a wrong password, the COUNT_AUTHENTICATION_ERRORS gets used instead.

Some cases of port probing, for example, using telnet or netcat, will increment COUNT_HANDSHAKE_ERRORS. Interestingly, though, the nmap probe does not increment any of them.

Also, when there is no catch-all user and no user entry matching the source IP/host/network, the host_cache table will allow us to at least observe statistics about failed logins per source IP, as each connection refused on the host validation phase will increment the COUNT_HOST_ACL_ERRORS counter.

Some limited visibility into failed login attempts can be available via the Connection Control Plugin. However, this plugin’s main purpose is not auditing, but rather slowing down brute force attacks against MySQL user accounts. Still, when installed, failed attempt counts are visible via the following view:

mysql› select * from information_schema.CONNECTION_CONTROL_FAILED_LOGIN_ATTEMPTS;
+---------------------+-----------------+
| USERHOST            | FAILED_ATTEMPTS |
+---------------------+-----------------+
| ''@'test-host1'     |              10 |
| ''@'192.168.121.13' |               4 |
| 'root'@'localhost'  |               3 |
| ''@'%'              |              10 |
+---------------------+-----------------+
4 rows in set (0.01 sec)

Finally, another per-user view was added in recent Percona Server versions, which shows how many failed login attempts are left until the account gets locked. This feature is active (tracking active) only for the accounts that have the FAILED_LOGIN_ATTEMPTS and PASSWORD_LOCK_TIME limitations:

mysql› select * from performance_schema.account_failed_login_lock_status;
+-------------------+-----------+--------------------+--------------+--------------------+-----------+--------------------+-----------------------+
| USER              | HOST      | IS_TRACKING_ACTIVE | MAX_ATTEMPTS | PASSWORD_LOCK_DAYS | IS_LOCKED | REMAINING_ATTEMPTS | REMAINING_DAYS_LOCKED |
+-------------------+-----------+--------------------+--------------+--------------------+-----------+--------------------+-----------------------+
| mysql.infoschema  | localhost | NO                 |            0 |                  0 | NULL      |               NULL |                  NULL |
| mysql.session     | localhost | NO                 |            0 |                  0 | NULL      |               NULL |                  NULL |
| mysql.sys         | localhost | NO                 |            0 |                  0 | NULL      |               NULL |                  NULL |
| percona.telemetry | localhost | NO                 |            0 |                  0 | NULL      |               NULL |                  NULL |
| root              | localhost | NO                 |            0 |                  0 | NULL      |               NULL |                  NULL |
| user1             | %         | YES                |          100 |                  1 | NO        |                 96 |                     0 |
| NULL              | %         | NO                 |            0 |                  0 | NULL      |               NULL |                  NULL |
+-------------------+-----------+--------------------+--------------+--------------------+-----------+--------------------+-----------------------+
7 rows in set (0.00 sec)

Summary

There are multiple ways to monitor MySQL or MariaDB login attempts, but only the Audit Log Filter allows you to specify exactly what you want to log, like only failed logins, for instance. Due to MySQL connection handling behavior, in order to log authentication attempts from undefined hosts, a secure catch-all user account may be needed, though.

As for the TCP scanners, MySQL may not be able to log all such connection attempts, depending on how fast the connection is terminated.

The article was created by a human.


The post Auditing Login Attempts in MySQL and MariaDB appeared first on Percona.

Jan
27
2026
--

Automatic “Multi-Source” Async Replication Failover Using PXC Replication Manager

Automatic "Multi-Source" Async Replication Failover Using PXC Replication ManagerThe replication  manager script can be particularly useful in complex PXC/Galera topologies that require Async/Multi-source replication. This will ease the auto source and replica failover to ensure all replication channels are healthy and in sync. If certain nodes shouldn’t  be part of a async/multi-source replication, we can disable the replication manager script there to tightly controlled the flow. Alternatively, node participation can be controlled by adjusting the weights in the percona.weight table, allowing replication behavior to be managed more precisely.

Jan
23
2026
--

MySQL January 2026 Performance Review

MySQL January 2026 Performance ReviewThis article is focused on describing the latest performance benchmarking executed on the latest releases of Community MySQL, Percona Server for MySQL and MariaDB.  In this set of tests I have used the machine described here.  Assumptions There are many ways to run tests, and we know that results may vary depending on how you […]

Jan
12
2026
--

Using PXC Replication Manager to Auto Manage Both Source and Replica Failover in Galera-Based Environments

In this blog post, we will be discussing the PXC Replication Manager script/tool which basically facilitates both source and replica failover when working with multiple PXC clusters, across different DC/Networks connected via asynchronous replication mechanism. Such topologies emerge from requirements like database version upgrades, reporting or streaming for applications, separate disaster recovery or backup solutions, […]

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com