Sep
02
2026
--

Mongorewind: Rewind Your MongoDB Test Data Without Restoring a Backup

Mongorewind: Rewind Your MongoDB Test Data Without Restoring a Backup

One day, my friend Martín told me about a problem he and his team were dealing with. 

Every time they needed to run a pre-production test, they had to restore a copy of the production database into their test cluster. That process alone takes about three hours because of the size of the database.

If something went wrong during the test and they needed to run it again, they had no choice but to sit through the entire restore cycle again.

Three hours. Twice (or more) just to run the pre-production test.

That’s what motivated me to build mongorewind, a terminal UI tool that watches your MongoDB cluster for changes and lets you instantly undo all of them, inserts, updates, replaces, and deletes. In reverse order, without touching your backup.

How It Works

mongorewind opens a cluster-wide change stream and records every data-modifying operation to a local log file. When you press R to rewind, it applies the inverse of each recorded operation in reverse chronological order:

Recorded operation Rewind action
insert deleteOne
update / replace replaceOne with pre-image (upsert)
delete replaceOne with pre-image (upsert)

To undo updates and deletes correctly, mongorewind needs to know what the document looked like before the change. 

It captures this automatically using MongoDB’s changeStreamPreAndPostImages feature, which it enables on every collection it finds — and on any new collection the moment it is created.


Requirements

  • Go 1.24+ and MongoDB 6.0+ running as a replica set or sharded cluster (change streams are not available on standalone instances, can be a 1 node replica set)

Installation

git clone https://github.com/zelmario/mongorewind.git
cd mongorewind
go build -o mongorewind .


Or install directly:

go install github.com/zelmario/mongorewind@latest


Running It

Start mongorewind pointing at your cluster before running any tests:

mongorewind --uri "mongodb://host1:27017,host2:27017,host3:27017/?replicaSet=rs0"

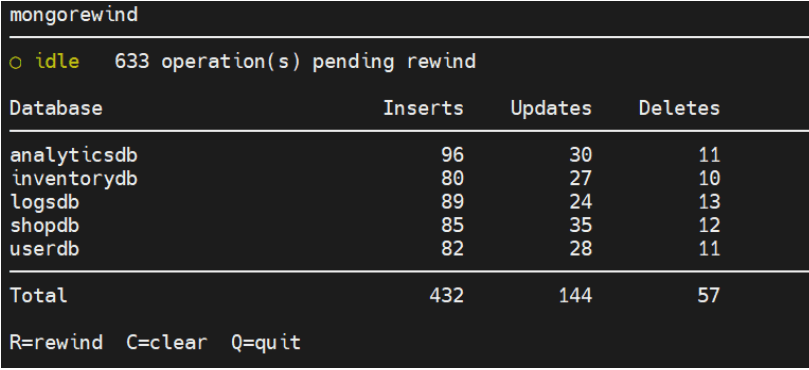
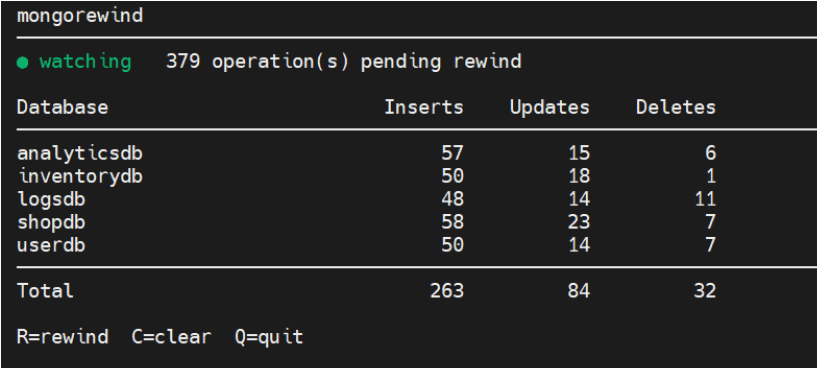
While mongorewind is running, you will see a terminal dashboard showing the operations it has recorded:

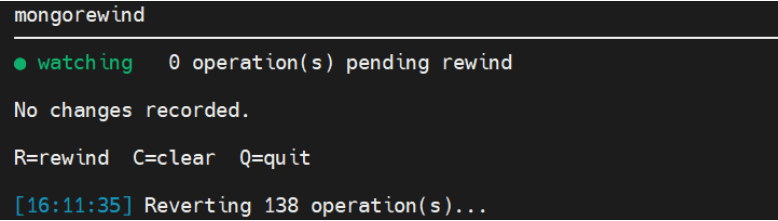
The status indicator shows ? watching (green) while the change stream is active. When you press R, it switches to ?idle (yellow) while the rewind is in progress.


Once the test run is complete and something went wrong, you can press R and mongorewind undoes every change it recorded — bringing the data back to exactly the state it was in before the test started. No restore, no waiting.


Using It in CI Pipelines

If you are running automated tests in a CI environment, mongorewind also supports a non-interactive mode. You can start the watcher in a terminal or the background and trigger rewinds from your scripts:

bash

# Start the watcher in the background

mongorewind --uri "mongodb://..." &

# Run your test suite

run_tests


# Rewind all changes and run again

mongorewind --rewind

run_tests


mongorewind –rewind exits with code 0 on success and 1 on error, so it integrates naturally into any CI pipeline.

If you use a custom log path, pass the same –log value to both commands so they share the same socket:

mongorewind --log /tmp/mytest.log --uri "mongodb://..." &

mongorewind --log /tmp/mytest.log --rewind


A Few Things to Keep in Mind

Replica set required. Change streams need a replica set or sharded cluster. If you are working locally, you can start a single-node replica set with:

mongod --replSet rs0


And then run rs.initiate() in the mongo shell.

The log file is scoped to a session. The file is truncated on startup and after a successful rewind, so each test session starts clean. System databases (admin, local, config) and system.* collections are ignored automatically.

Pre-images are enabled automatically. mongorewind polls every 2 seconds to catch newly created collections and enables changeStreamPreAndPostImages on them. You don’t need to configure anything manually.

Going Back to Martín’s Problem

With mongorewind, Martín’s team does the restoration once. After that, every time a test fails and they need to start over, they just run mongorewind –rewind. The database goes back to its original state in seconds, and the test runs again. Three hours become just a few seconds.


Contributions are welcome! Since I’m not a developer, your feedback is valuable. If you are a developer and notice any mistakes or want to enhance the script, please feel free to contribute!

The post Mongorewind: Rewind Your MongoDB Test Data Without Restoring a Backup appeared first on Percona.

Aug
31
2026
--

Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption

Expired TLS certificates can prevent new client connections and, when X.509 is used for Percona Server for MongoDB internal authentication, also prevent members of a replica set or sharded cluster from authenticating to one another.

In this post we will discuss performing a same-CA renewal: replacement certificates for server, member, and client leaf are issued by the existing trusted CA, and the X.509 attributes used for cluster membership do not change. In this scenario, the rotateCertificates command reloads TLS material for new connections without restarting mongod or mongos.

Important: Do not apply this hot-reload procedure when replacing the issuing CA, changing a certificate subject DN, or changing cluster-membership attributes. Those are not ordinary renewals.

What rotates, and what does not

Percona Server for MongoDB can reload the files configured through the following TLS options:

net:
  tls:
    mode: requireTLS
    certificateKeyFile: /etc/mongod/tls/server.pem
    CAFile: /etc/mongod/tls/ca.pem
    clusterFile: /etc/mongod/tls/cluster.pem

The certificateKeyFile contains the certificate and private key presented to normal clients. The clusterFile holds the certificate and key that a mongod or mongos process presents when connecting to other cluster members. If clusterFile is not configured, certificateKeyFile is also used for member authentication.

The rotateCertificates command affects new TLS connections. It does not terminate established client sessions or force a replica-set election.

Before the maintenance window

Begin this process well in advance of the certificate expiry, and avoid performing your first attempt in a production environment.

  1. Inventory every process and client certificates. Include all mongod members, all mongos routers, application drivers, mongosh hosts, backup jobs, monitoring, and automation tools.
  2. Confirm this is a same-CA renewal. The issuer chain trusted by every participant stays the same, and the O, OU, and DC attributes used for default internal X.509 membership matching remain unchanged.
  3. Create a new PEM file for every server and client that needs rotation. A PEM file referenced by certificateKeyFile or clusterFile must include both the certificate and its matching private key. The file must strictly contain the key first, followed by the certificate, including their encapsulation boundaries.
  4. Verify the new certificate details and validate the cert against the CA before copying to the production TLS directory

Stage a renewed server or member certificate

There are a few limitations for rotating certificates online:

  • Each new certificate must have the same filename and same filepath as the certificate it is replacing.
  • If the TLS Certificate is password-protected, its password must be the same as the old certificate it is replacing.

If CAFile, a CRL, or another configured TLS input is being renewed as part of the same operation, replace it before invoking the reload command. The command reloads the configured TLS inputs as a set; a missing or invalid input causes the reload to fail.

Luckily, incorrect certificate files will cause the rotation to fail, but will not invalidate the existing configuration or have any other side effects.

Reload one process

Connect directly to the specific mongod or mongos with an administrative user and execute the following command:

db.getSiblingDB("admin").runCommand({rotateCertificates: 1, message: "Renewed TLS certificate"})'

Immediately validate a new TLS connection to that process with a renewed client certificate. Also inspect the log for the successful certificate-rotation message and any TLS errors. Check our documentation for guidelines to perform the procedure on a replica set or sharded cluster.

Final validation and cleanup

After completing the procedure, it is a good idea to reconfirm the expiry date and SANs of the certificate presented by every mongod and mongos. Retain the old certificates only for the approved overlap period, then remove or revoke them. Don’t forget to record the new expiry dates and create alerts with enough lead time before the expiration date of the new certificates.

When the CA or member identity changes

A different procedure is required when any of the following changes:

  • The issuing CA or trusted CA chain.
  • The subject DN used by a MONGODB-X509 client user.
  • The O, OU, or DC values used for default intra-cluster X.509 membership matching.
  • net.tls.clusterAuthX509.attributes or net.tls.clusterAuthX509.extensionValue.

This is a topic for another time.


The post Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption appeared first on Percona.

Aug
31
2026
--

Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption

Expired TLS certificates can prevent new client connections and, when X.509 is used for Percona Server for MongoDB internal authentication, also prevent members of a replica set or sharded cluster from authenticating to one another.

In this post we will discuss performing a same-CA renewal: replacement certificates for server, member, and client leaf are issued by the existing trusted CA, and the X.509 attributes used for cluster membership do not change. In this scenario, the rotateCertificates command reloads TLS material for new connections without restarting mongod or mongos.

Important: Do not apply this hot-reload procedure when replacing the issuing CA, changing a certificate subject DN, or changing cluster-membership attributes. Those are not ordinary renewals.

What rotates, and what does not

Percona Server for MongoDB can reload the files configured through the following TLS options:

net:
  tls:
    mode: requireTLS
    certificateKeyFile: /etc/mongod/tls/server.pem
    CAFile: /etc/mongod/tls/ca.pem
    clusterFile: /etc/mongod/tls/cluster.pem

The certificateKeyFile contains the certificate and private key presented to normal clients. The clusterFile holds the certificate and key that a mongod or mongos process presents when connecting to other cluster members. If clusterFile is not configured, certificateKeyFile is also used for member authentication.

The rotateCertificates command affects new TLS connections. It does not terminate established client sessions or force a replica-set election.

Before the maintenance window

Begin this process well in advance of the certificate expiry, and avoid performing your first attempt in a production environment.

  1. Inventory every process and client certificates. Include all mongod members, all mongos routers, application drivers, mongosh hosts, backup jobs, monitoring, and automation tools.
  2. Confirm this is a same-CA renewal. The issuer chain trusted by every participant stays the same, and the O, OU, and DC attributes used for default internal X.509 membership matching remain unchanged.
  3. Create a new PEM file for every server and client that needs rotation. A PEM file referenced by certificateKeyFile or clusterFile must include both the certificate and its matching private key. The file must strictly contain the key first, followed by the certificate, including their encapsulation boundaries.
  4. Verify the new certificate details and validate the cert against the CA before copying to the production TLS directory

Stage a renewed server or member certificate

There are a few limitations for rotating certificates online:

  • Each new certificate must have the same filename and same filepath as the certificate it is replacing.
  • If the TLS Certificate is password-protected, its password must be the same as the old certificate it is replacing.

If CAFile, a CRL, or another configured TLS input is being renewed as part of the same operation, replace it before invoking the reload command. The command reloads the configured TLS inputs as a set; a missing or invalid input causes the reload to fail.

Luckily, incorrect certificate files will cause the rotation to fail, but will not invalidate the existing configuration or have any other side effects.

Reload one process

Connect directly to the specific mongod or mongos with an administrative user and execute the following command:

db.getSiblingDB("admin").runCommand({rotateCertificates: 1, message: "Renewed TLS certificate"})'

Immediately validate a new TLS connection to that process with a renewed client certificate. Also inspect the log for the successful certificate-rotation message and any TLS errors. Check our documentation for guidelines to perform the procedure on a replica set or sharded cluster.

Final validation and cleanup

After completing the procedure, it is a good idea to reconfirm the expiry date and SANs of the certificate presented by every mongod and mongos. Retain the old certificates only for the approved overlap period, then remove or revoke them. Don’t forget to record the new expiry dates and create alerts with enough lead time before the expiration date of the new certificates.

When the CA or member identity changes

A different procedure is required when any of the following changes:

  • The issuing CA or trusted CA chain.
  • The subject DN used by a MONGODB-X509 client user.
  • The O, OU, or DC values used for default intra-cluster X.509 membership matching.
  • net.tls.clusterAuthX509.attributes or net.tls.clusterAuthX509.extensionValue.

This is a topic for another time.


The post Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption appeared first on Percona.

Aug
25
2026
--

Software Bill of Materials in Percona Server for MongoDB

Introduction

A software bill of materials (SBOM) offers end users enhanced supply chain visibility, thereby facilitating license compliance and timely vulnerability detection. An SBOM of an application, library, or framework (collectively referred to as a “component”) is a machine-readable document that enumerates all other components it incorporates, including transitive ones. In this way, an SBOM represents the dependency graph of a particular component. For each component, including the one for which the SBOM is created, it provides the component’s specific version and license.

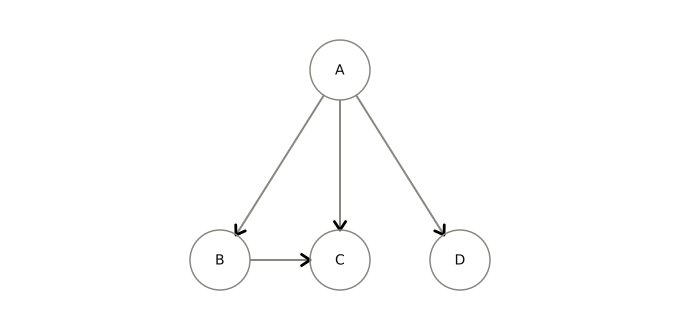
Given the dependency graph in the figure below, the SBOM for component A would include components B, C, and D. In addition, the SBOM would list each relationship between components (depicted as arrows in the figure) in its “dependencies” section.

Periodic SBOM scans

Given an SBOM file for a component, one can scan it for vulnerabilities with one of the many available tools. If the tool doesn’t show any, it can be tempting to declare that we are safe and forget about the SBOM until the next version of the component in question is released, together with a new SBOM. That, however, would be a mistake.

SBOM scanning tools have two data inputs. The first one is an SBOM itself. It is passed to the tool explicitly and typically doesn’t change over time for a particular component version. The second data input is the complete opposite: it is implicit and updated daily or even more often. We are talking about the vulnerability database(s). SBOM scanning tools download the updates to the vulnerability database(s) before each SBOM scan. The same scan command, using the same SBOM file that previously reported no vulnerabilities, can easily report serious vulnerabilities in an hour.

That is why it is important to run scans periodically to be notified of new vulnerabilities in a timely manner and to start remediation before the component’s maintainers prepare a fix. This is especially true in the era of AI-assisted vulnerability discovery, which often leaves maintainers overloaded with vulnerability reports, so fixing takes longer than before.

SBOMs in Percona Server for MongoDB

Since versions 7.0.39-21, 8.0.28-12, and 8.3.7-1, Percona Server for MongoDB (further referred to as PSMDB) provides SBOMs in its binary packages. In Debian and RPM packages, one can find the SBOM in the /usr/share/doc/percona-server-mongodb-server/sbom.cdx.json file once the percona-server-mongodb-server package is installed. In the binary tarball, the SBOM is located at doc/sbom.cdx.json relative to the tarball’s root directory. As you might have already guessed, the cdx extension in the filename indicates that the SBOM is in the CycloneDX format.

Percona Server for MongoDB also provides two SBOMs for its Docker images. The first one covers PSMDB exclusively and is embedded in the image’s filesystem at the same /usr/share/doc/percona-server-mongodb-server/sbom.cdx.json path. It is the same SBOM as in the corresponding RPM package. The second one covers the image as a whole, including the base OS, libraries and utilities installed on top of it, and so on. This SBOM considers PSMDB as a dependency, and is associated with the Docker image as an OCI artifact.

Since PSMDB’s second SBOM differs little from other OCI-attached SBOMs in how it is scanned, we won’t discuss it here. One can refer to the documentation for detailed instructions and examples. Instead, the rest of the post focuses on the first SBOM: the one that is included in a Debian package, an RPM package, and a binary tarball, and embedded in the Docker image.

Scanning the SBOM

One can scan PSMDB’s SBOM with grype as follows:

grype --distro ubuntu:24.04 sbom:/usr/share/doc/percona-server-mongodb-server/sbom.cdx.json

Clearly, they need to pass the distribution name and version they run PSMDB on, e.g.: —distro rhel:9.8.

One can also use OWASP Dependency Track. Instead of being a command-line utility, Dependency Track is a fully fledged GUI-based service. Nevertheless, deploying it is as easy as two shell commands:

curl -fsSLO https://dependencytrack.org/docker-compose.yml
docker compose up -d

Then, do the following:

  • Go to http://localhost:8080 and authenticate with username admin and password admin
  • Change the password and reauthenticate with the username admin and the new password
  • In the left pane, select “Projects” and then click the “Create Project” button
  • After creating the project, click on its name and select the “Component” tab
  • Click the “Upload BOM” button and upload the “sbom.cdx.json” file

At the time of writing, Grype and OWASP Dependency Track are the only tools we are aware of that can scan PSMDB’s SBOM. Other popular options, notably Trivy, skip analysis of the most PSMDB dependencies in the SBOM. This is the result of the approach to dependency management that PSMDB has to follow.

Evaluating Scanning Results

Running Grype as shown above on the SBOM from PSMDB version 7.0.39-21 gives quite a scary report (redacted for length):

$ grype --distro ubuntu:24.04 \
    sbom:/usr/share/doc/percona-server-mongodb-server/sbom.cdx.json
NAME                          INSTALLED  VULNERABILITY   SEVERITY  EPSS
unicode-org/ICU4C             57.1       CVE-2016-7415   Critical  5.8% (92nd)
unicode-org/ICU4C             57.1       CVE-2017-14952  Critical  5.1% (91st)
unicode-org/ICU4C             57.1       CVE-2016-6293   Critical  5.0% (91st)
unicode-org/ICU4C             57.1       CVE-2017-17484  Critical  4.6% (90th)
unicode-org/ICU4C             57.1       CVE-2017-7867   High      4.6% (90th)
unicode-org/ICU4C             57.1       CVE-2017-7868   High      4.4% (90th)
unicode-org/ICU4C             57.1       CVE-2020-10531  High      2.7% (84th)
unicode-org/ICU4C             57.1       CVE-2017-15422  Medium    2.5% (82nd)
unicode-org/ICU4C             57.1       CVE-2017-15396  Medium    2.2% (80th)
libtom/LibTomCrypt            1.18.2     CVE-2019-17362  Critical  3.1% (86th)
google.opensource/Protobuf    3.19.5     CVE-2024-7254   High      2.8% (84th)
c-ares/c-ares                 1.19.1     CVE-2024-25629  Medium    0.3% (27th)
pcre2/PCRE2                   10.40      CVE-2022-41409  High      1.1% (63rd)
google.opensource/gRPC (C++)  1.46.6     CVE-2026-33186  Critical  1.6% (72nd)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-44487  High      100.0% (99th)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-4785   High      0.7% (48th)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-33953  High      0.5% (38th)
google.opensource/gRPC (C++)  1.46.6     CVE-2023-32732  Medium    0.5% (41st)
mongodb/mongodb/mongo         7.0.39     CVE-2017-2665   High      0.3% (25th)
mongodb/mongodb/mongo         7.0.39     CVE-2014-8180   Medium    0.3% (19th)
mongodb/MongoDB C Driver      1.27.6     CVE-2026-6231   High      0.2% (8th)
mongodb/MongoDB C Driver      1.27.6     CVE-2025-12119  Low       0.2% (10th)
mongodb/MongoDB C Driver      1.27.6     CVE-2026-4359   Low       0.2% (8th)

The first thing to note about the results above is that PSMDB version 7.0.39-21 does not introduce all those vulnerabilities. They have existed for a long time in the 7.0 version series; the SBOM and the scanning tools only made them visible.

We can start sorting out this pile of vulnerabilities with the critical CVE-2026-33186 in the gRPC framework. If we read its description, we will learn that it affects only the Go implementation of the framework. The C++ implementation used in PSMDB is hosted in a separate repository (https://github.com/grpc/grpc, as opposed to https://github.com/grpc/grpc-go) and is not affected by the vulnerability. But why did Grype report it then? We believe that is a result of the quite wide Common Platform Enumeration (CPE) of this component in the SBOM file:

cpe:2.3:a:grpc:grpc:1.46.6:*:*:*:*:*:*:*

In the CVEs page, CPE is cpe:2.3:a:grpc:grpc:*:*:*:*:*:go:*:* stating that only Go code is vulnerable. So the SBOM’s CPE matched the CVE’s CPE, making Grype report the vulnerability, though it is a false positive in reality.

Another gRPC vulnerability, CVE-2023-44487, does not apply to Percona Server for MongoDB either. It is exploitable only if the support of the alternative gRPC-based wire-protocol transport is enabled during the build process. It is disabled by default, though, and Percona has never enabled it.

Next, let us look at the critical CVE-2016-7415 in ICU4C, which is a C/C++ library for handling Unicode. The CVE correctly points out that version 57.1 is vulnerable to a buffer overflow. However, the PSMDB codebase has local fixes for this and other ICU4C-related CVEs. This is still version 57.1, but with fixes applied.

Finally, consider the critical vulnerability CVE-2019-17362 in LibTomCrypt. Its description says the issue is in the der_decode_utf8_string function in the der_decode_utf8_string.c file. However, Percona Server for MongoDB codebase does not even include the file: only a small part of LibTomCrypt is vendored into the PSMDB codebase, leaving der_decode_utf8_string.c aside. That brings us to the conclusion that the vulnerability does not actually affect Percona Server for MongoDB.

False Positives and Paranoia

By now, you have probably noticed a pattern here. Many of the reported CVEs are false positives, meaning that they are reported but don’t actually affect PSMDB. One may argue that Grype produces too many of them. But there are a couple of reasons for that. First, Grype could not know about local patches for some components, components excluded from the build, or partially vendored components.

Second, if we consider the “paranoia spectrum”, where the left extreme is total naivety and the right one is being suspicious even in innocent cases, it is perfectly reasonable for a security tool to lean to the right end. In our use case, that means reporting false-positive results and leaving the analysis to a human being is a much safer choice than omitting a potential issue that could turn into a serious security breach.

Vulnerability Exploitability Exchange

Repeating the analysis we showed above for each reported CVE on the user side is tedious and sometimes difficult. In theory, a user could realize CVE-2026-33186 (an issue in the Go code) and CVE-2019-17362 (an issue in the code that doesn’t actually exist in PSMDB) are false positives. But it would be unreasonable to expect a user to dig into the internals of Percona Server for MongoDB to discover that some code is excluded from the build (CVE-2023-44487) or has local patches (CVE-2016-7415).

That is why the developers of Percona Server for MongoDB conducted the analysis themselves and prepared its results as a Vulnerability Exploitability eXchange (VEX) document. Each Percona Server for MongoDB release that comes with an SBOM file (versions 7.0.39-21, 8.0.28-12, and 8.3.7-1 and above) also has a corresponding VEX document located at https://percona.github.io/percona-server-mongodb/vex/percona-server-mongodb-<version>.vex.json. Below is an example of downloading the VEX document and using it in Grype to filter out false positives for version 7.0.39-21 (redacted for length):

$ curl -fsSLO https://percona.github.io/percona-server-mongodb/vex/percona-server-mongodb-7.0.39-21.vex.json
$ grype --distro ubuntu:24.04 \
    --vex=percona-server-mongodb-7.0.39-21.vex.json \
    sbom:/usr/share/doc/percona-server-mongodb-server/sbom.cdx.json
NAME                      INSTALLED  VULNERABILITY  SEVERITY  EPSS
mongodb/MongoDB C Driver  1.27.6     CVE-2026-6231  High      0.2% (8th)

We can see that after taking a VEX document into account, only one vulnerability that actually affects PSMDB remains. What is more, a VEX document can list not only those vulnerabilities that don’t affect particular software but also those that actually do. In our case, percona-server-mongodb-7.0.39-21.vex.json says that CVE-2026-6231 would affect PSMDB only if Queryable Encryption (aka Field Level Encryption) is enabled. As a side comment, at Percona, we plan to eliminate that vulnerability in the future.

The dependency on MongoDB Community Edition

An attentive reader could have probably noticed that scanning the SBOM of Percona Server for MongoDB version 7.0.39-21 reported a couple of vulnerabilities in mongodb/mongodb/mongo, also version 7.0.39, which can look strange, but it is actually not. Percona Server for MongoDB is a fork and a drop-in replacement of MongoDB Community Edition. That is the reason every vulnerability that affects the latter also affects the former. Percona Server for MongoDB having a “dependency” on MongoDB Community Edition enables SBOM scanning tools to detect vulnerabilities in the MongoDB Community Edition code itself, in addition to those in its dependencies.

Shared Libraries

Even if an SBOM scanning tool had shown no CVEs after being passed a VEX file, we still can’t conclude that our PSMDB deployment is free from known vulnerabilities. That is because an SBOM file can’t cover dependencies linked to Percona Server for MongoDB at runtime as shared libraries. Their specific versions are governed by a particular OS and can change over time. Even if the PSMDB package for a particular OS version included shared libraries specifying their versions at build time, any upgrade of the packages on the machine where PSMDB is installed could make those versions incorrect.

In addition to periodically scanning the Percona Server for MongoDB SBOM, we recommend that users download and scan the SBOMs for the shared libraries that Percona Server for MongoDB directly links to at runtime. At the time of writing, those libraries are:

Name Typical Linked Library Filename(s)
GNU C Library libc.so.6, libm.so.6, libresolv.so.2, etc.
GCC Support Library libgcc_s.so.1
libcurl libcurl.so.4
Cyrus SASL libsasl2.so.2
Kerberos 5 GSS-API libgssapi_krb5.so.2
OpenLDAP liblber.so.2, libldap.so.2
OpenSSL libcrypto.so.3, libssl.so.3

Please note version numbers in library filenames above (e.g. 6 in libc.so.6). They are just examples and can differ from platform to platform.

Conclusion

Percona Server for MongoDB has provided SBOM and VEX documents since versions 7.0.39-21, 8.0.28-12, and 8.3.7-1, giving users better visibility into its supply chain for both licensing and security. Regularly scanning PSMDB’s SBOM, along with the SBOMs of the shared libraries it links to, helps operators detect potential vulnerabilities and begin remediation before they become security breaches.

The post Software Bill of Materials in Percona Server for MongoDB appeared first on Percona.

Aug
11
2026
--

Percona for MongoDB: RHEL 10, Its Derivatives, and Debian 13 – On Both x86_64 and ARM

We’re happy to announce that Percona Server for MongoDB (PSMDB) 8.0.28-12 extends platform support to RHEL 10 and its derivatives (Oracle Linux 10, Rocky Linux 10, AlmaLinux 10, and other RHEL-compatible distributions) for both x86_64 and ARM (aarch64) architectures. This release also adds support for Debian 13 “Trixie” on x86_64 and ARM64. We’ll continue to support that for 8.0, 8.3, and newer releases.

This is an important step for anyone planning infrastructure refreshes around the latest Linux releases, and it’s especially notable for teams evaluating ARM to cut infrastructure spend without sacrificing performance.

What’s new in 8.0.28-12

Starting with this release, Percona Server for MongoDB packages are available for:

  • RHEL 10 and derivatives like Oracle Linux 10, Rocky Linux 10, AlmaLinux 10 on x86_64 and ARM (aarch64)
  • Debian 13 “Trixie” on x86_64 and ARM64 (aarch64)

Additionally, starting this release, we’ve included Software Bills of Materials (SBOMs) and Vulnerability Exploitability Exchange (VEX) for every release. SBOMs improve software supply chain transparency by documenting the components and dependencies included in a build. They are generated automatically as part of the release pipeline in the industry-standard CycloneDX format. OpenVEX files are published on GitHub Pages and provide the exploitability status of known vulnerabilities. For comprehensive information, refer to our [documentation](../sbom.md).

To learn more, see the full release notes of Percona Server for MongoDB 8.0.28-12.

Ahead of upstream on Debian 13

As of this writing (August 2026), upstream MongoDB Community/Enterprise Server does not yet officially package or support Debian 13. Trixie isn’t in MongoDB’s supported platforms list, and the documented community workaround is to install the Debian 12 “Bookworm” build on Trixie hosts, since a native Trixie server build hasn’t landed yet. PSMDB closes that gap now, with native Debian 13 packages rather than a buggy Bookworm build running out-of-distro.

Why ARM is worth a serious look for MongoDB workloads

We have heard multiple times from you directly, via our forum, or on Reddit about the Interest in ARM for database workloads. Over the last few years, adoption has moved well past the experimental phase to resilient production readiness. Our adoption telemetry data show nearly 3x as many ARM instances over the last 12 months!

I can see a number of benefits and reasons why our community users and customers adopted ARM over AMD or Intel CPU architectures:

(Note: The above figures come from third-party blogs and vendor case studies rather than peer-reviewed benchmarks. Treat them as directional evidence that ARM is worth evaluating, not a guarantee of results for your specific workload. For the official recommendation based on your workload, reach out to Percona)

Netflix has publicly stated that it saves over $15 million annually after migrating video encoding workloads to Graviton, while also seeing faster processing times, and other large-scale AWS customers have reported double-digit percentage reductions in compute costs after moving meaningful portions of their backend fleets to ARM (byteiota; sanj.dev).

What to watch out for

One RHEL 10 detail to keep in mind when planning a migration: Red Hat raised the CPU baseline for x86_64 to the x86-64-v3 microarchitecture level, meaning the processor needs to support instruction sets such as AVX2 (Red Hat, RHEL 10 architecture documentation; vInfrastructure Blog). On the ARM side, RHEL 10 targets the ARMv8.0-A baseline (Red Hat documentation). This applies equally to Oracle Linux 10, Rocky Linux 10, and AlmaLinux 10, since they build from the same upstream sources. I highly recommend checking your current infrastructure before planning the move, especially for older bare-metal fleets.

In general, but especially on ARM, remember that performance is workload-dependent. Some code paths and workloads leaning on x64-specific instruction extensions may not see the same gains as throughput-oriented, multi-threaded workloads on ARM. Benchmarking your own query patterns and index-heavy operations before a full cutover is essential. General benchmarks are a good signal, not a guarantee.

Percona can help you get there

Migrating a production MongoDB deployment to a different infrastructure is a project with real decision points. There are a number of questions to answer around: Hardware or instance selection, driver and tooling compatibility, benchmarking against your actual workload, and a rollback plan. The Percona Services team helps customers plan and execute exactly this kind of migration. We start from initial architecture assessment and proof-of-concept benchmarking and go through to production cutover and post-migration tuning.

If you’re weighing a move to ARM, or just want to get onto RHEL 10 or Debian 13 without surprises, reach out to Percona to talk through your environment.

The post Percona for MongoDB: RHEL 10, Its Derivatives, and Debian 13 – On Both x86_64 and ARM appeared first on Percona.

Aug
07
2026
--

The open way of Percona Search for MongoDB

Percona Search for MongoDB is Percona’s downstream distribution of mongot, the search engine that provides MongoDB’s full-text and vector search capabilities. With this addition, you can power your applications with AI and advanced search techniques – anywhere, and without vendor lock-in. It’s the same search engine that powers MongoDB Atlas Search. 

Percona Search for MongoDB runs as a separate mongot process alongside Percona Server for MongoDB. The deployment topology determines how many mongot instances are required and how search requests are routed. Applications and users continue to connect to mongod in a replica set, or to mongos in a sharded cluster – never directly to mongot.
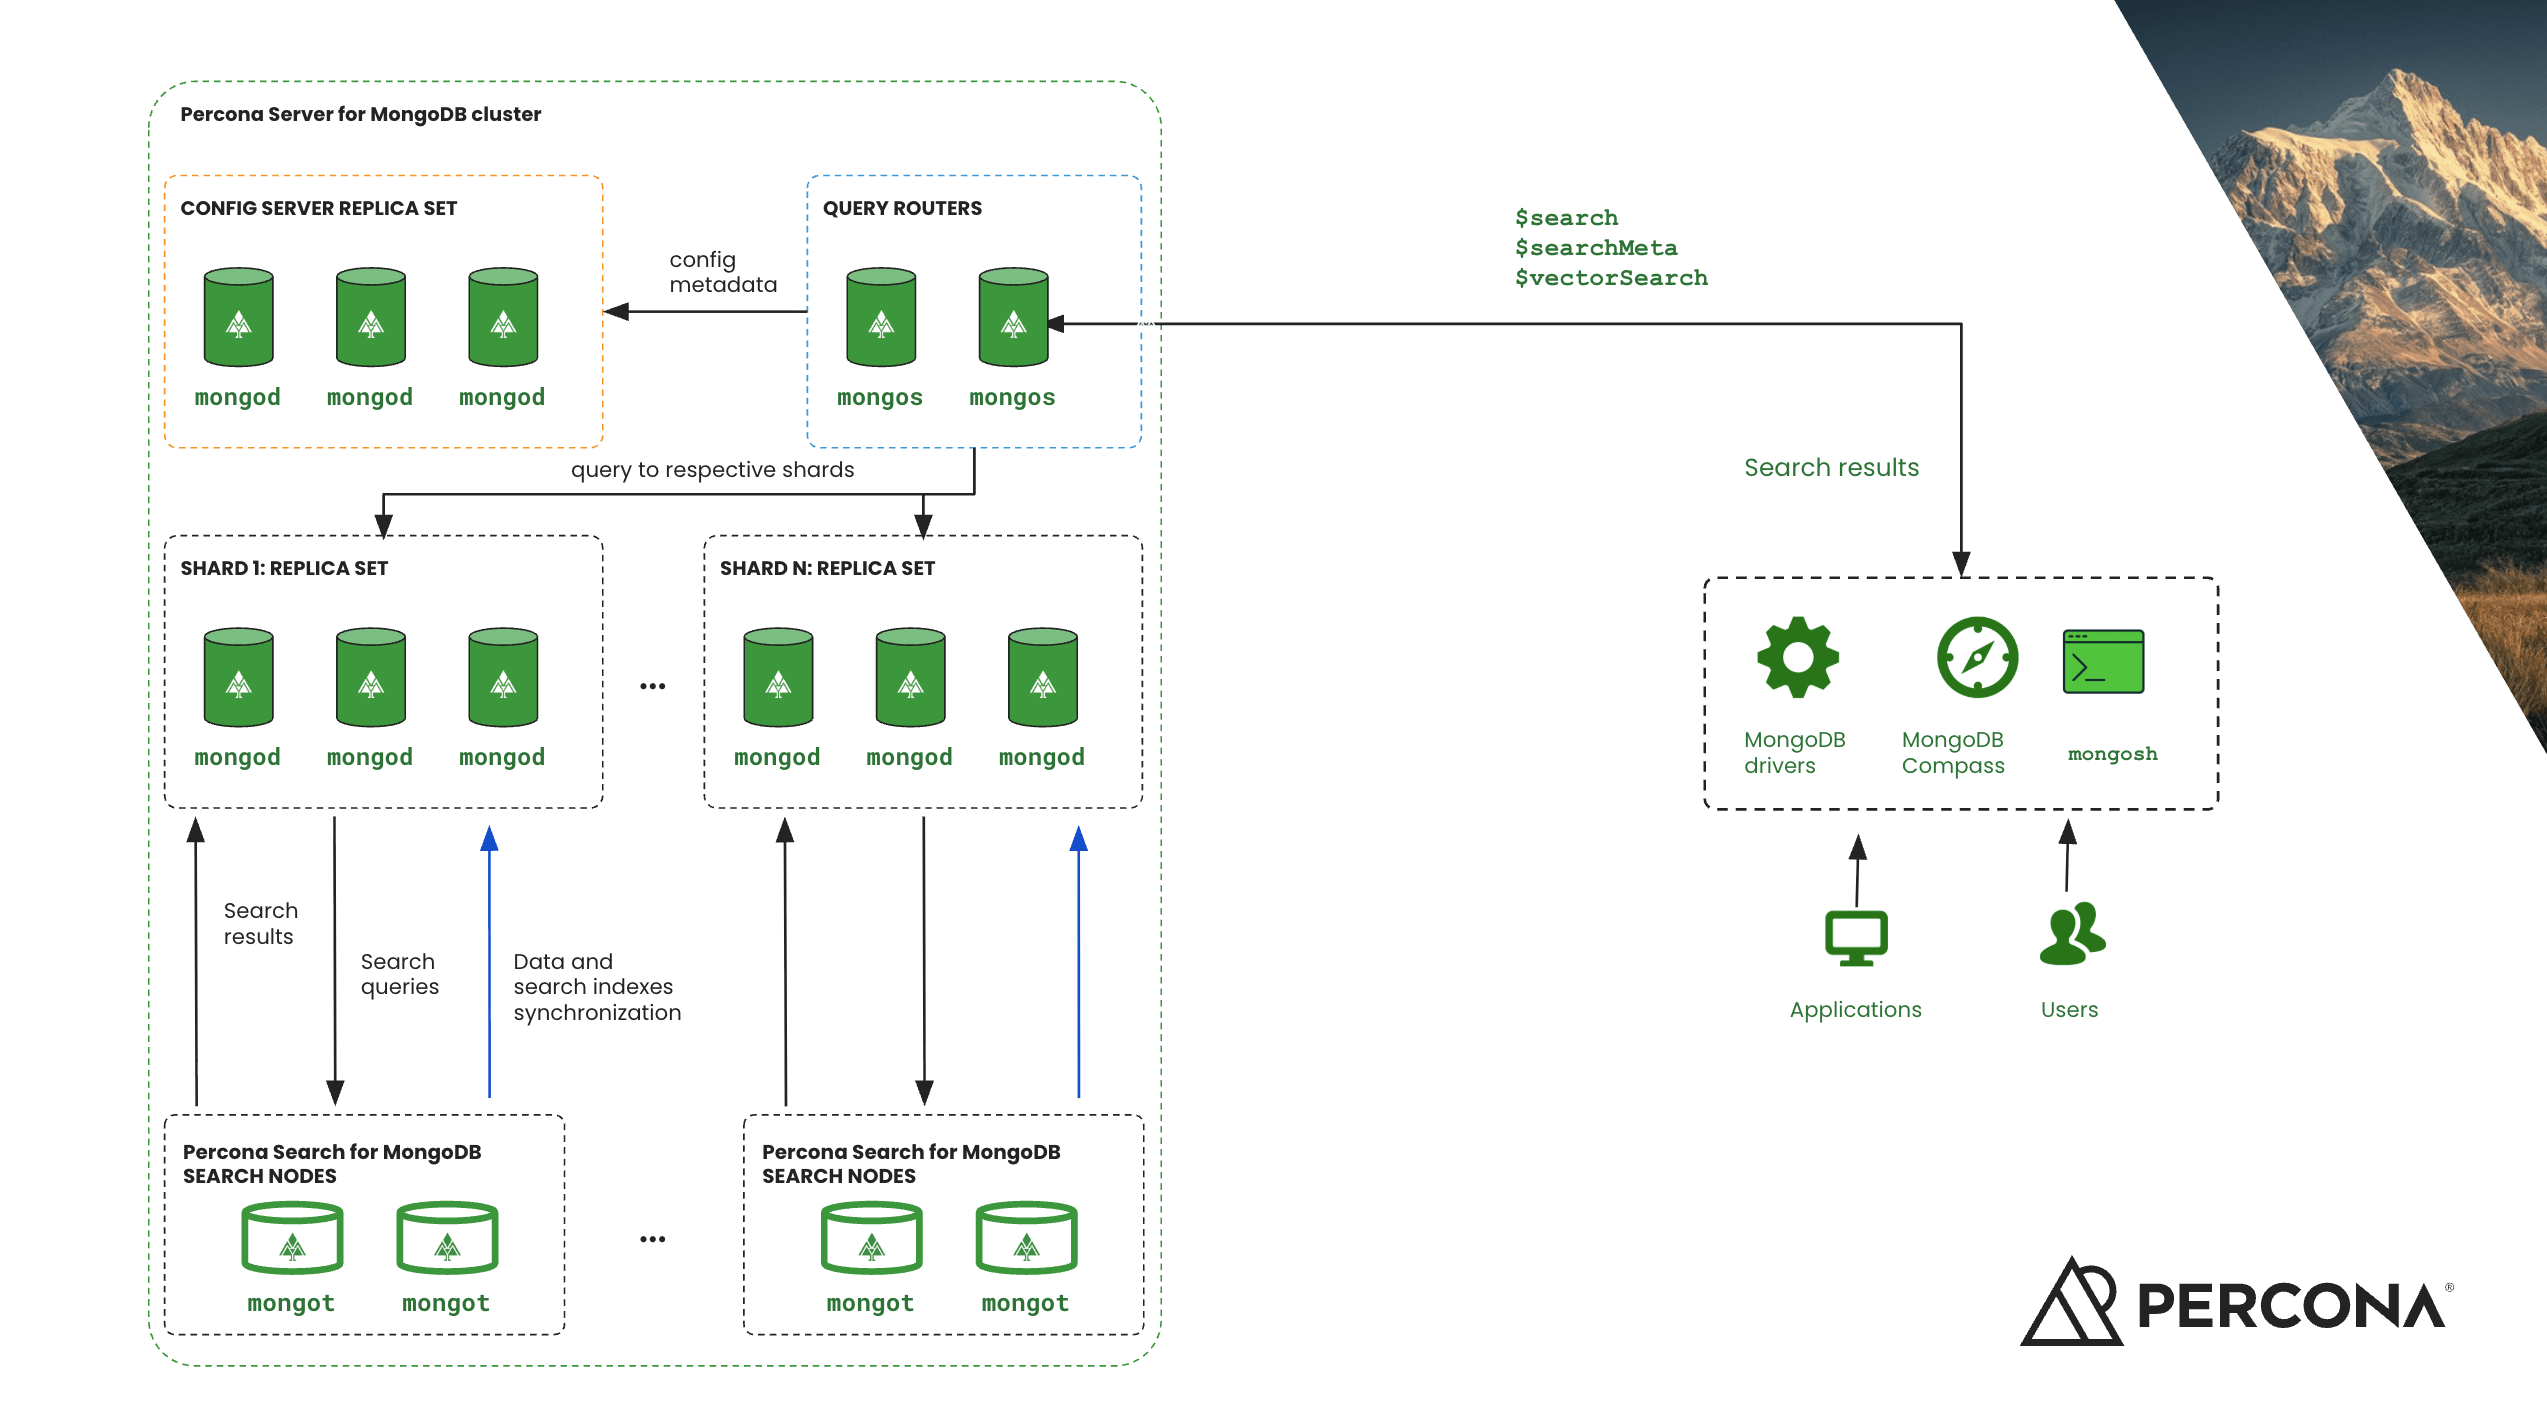
On behalf of the entire product and engineering team for MongoDB at Percona, I’m pleased to share that we’re starting a Technical Preview with version 1.70.3-1.

The way is open. Search should be too.

Before anything else, credit where it is due. MongoDB Inc. released full-text and vector search for self-managed deployments as GA in July 2026, and published the source for mongot – the same search engine that powers MongoDB Atlas Search. Opening up the engine behind a flagship commercial service is a significant step and precisely what makes this Technical Preview possible. 

What we want to add is the next layer of openness: freedom to choose your embedding model, to run inference where your data already lives, and to operate search with the same automated backup, monitoring, and Kubernetes tooling you already expect from every other tier of your database. That is the Percona way, and this post is our map for getting there.

What we found in mongot

We went through the current release, reviewing everything needed to run it the way you want in production. Below is what we found, stated as plainly as we can, with the Percona plan attached to each item. None of these is a defect. They describe where today’s release draws the line between the search engine and the operational layer around it. The operational layer is exactly where Percona has always done its work.

Automatic embeddings and model choice 

This is the big one, and it needs a little setup to see properly.

Vector search doesn’t search text. It searches vectors. If a user wants to find a document, they need to type a query that is first run through an embedding model and turned into an array of numbers. That conversion is not a one-time import step, either – it has to keep pace with your data, because a document whose text changed while its vector didn’t is now quietly unfindable. No errors are raised. Query results simply get worse over time.

There are two ways to handle it.

Manually

You generate embeddings yourself and write the vectors into the document. This path is completely open, with no restrictions. It is also where a lot of vector search projects stall, because you have just taken ownership of an embedding pipeline: something has to watch inserts and updates, batch them, call a model, handle failures and retries, backfill the whole corpus when you change models, and guarantee every vector still matches the text next to it. That is a distributed-systems problem bolted onto a database that already solved distributed-systems problems. For a fixed corpus, you index once and forget – it is fine. For live operational data, it becomes a permanent tax on the team. In my humble opinion, it isn’t the way to go for a production deployment at scale.

Automatically

You declare which field holds your text and which model to use – the autoEmbed type in the index definition – and the database generates the embeddings, keeps them in sync as the data changes, and accepts plain text at query time. This exists precisely because the manual path does not scale. It is the path the documentation leads with, the path every tutorial will use, and for most teams running search on data that changes, it is the only realistically maintainable option.
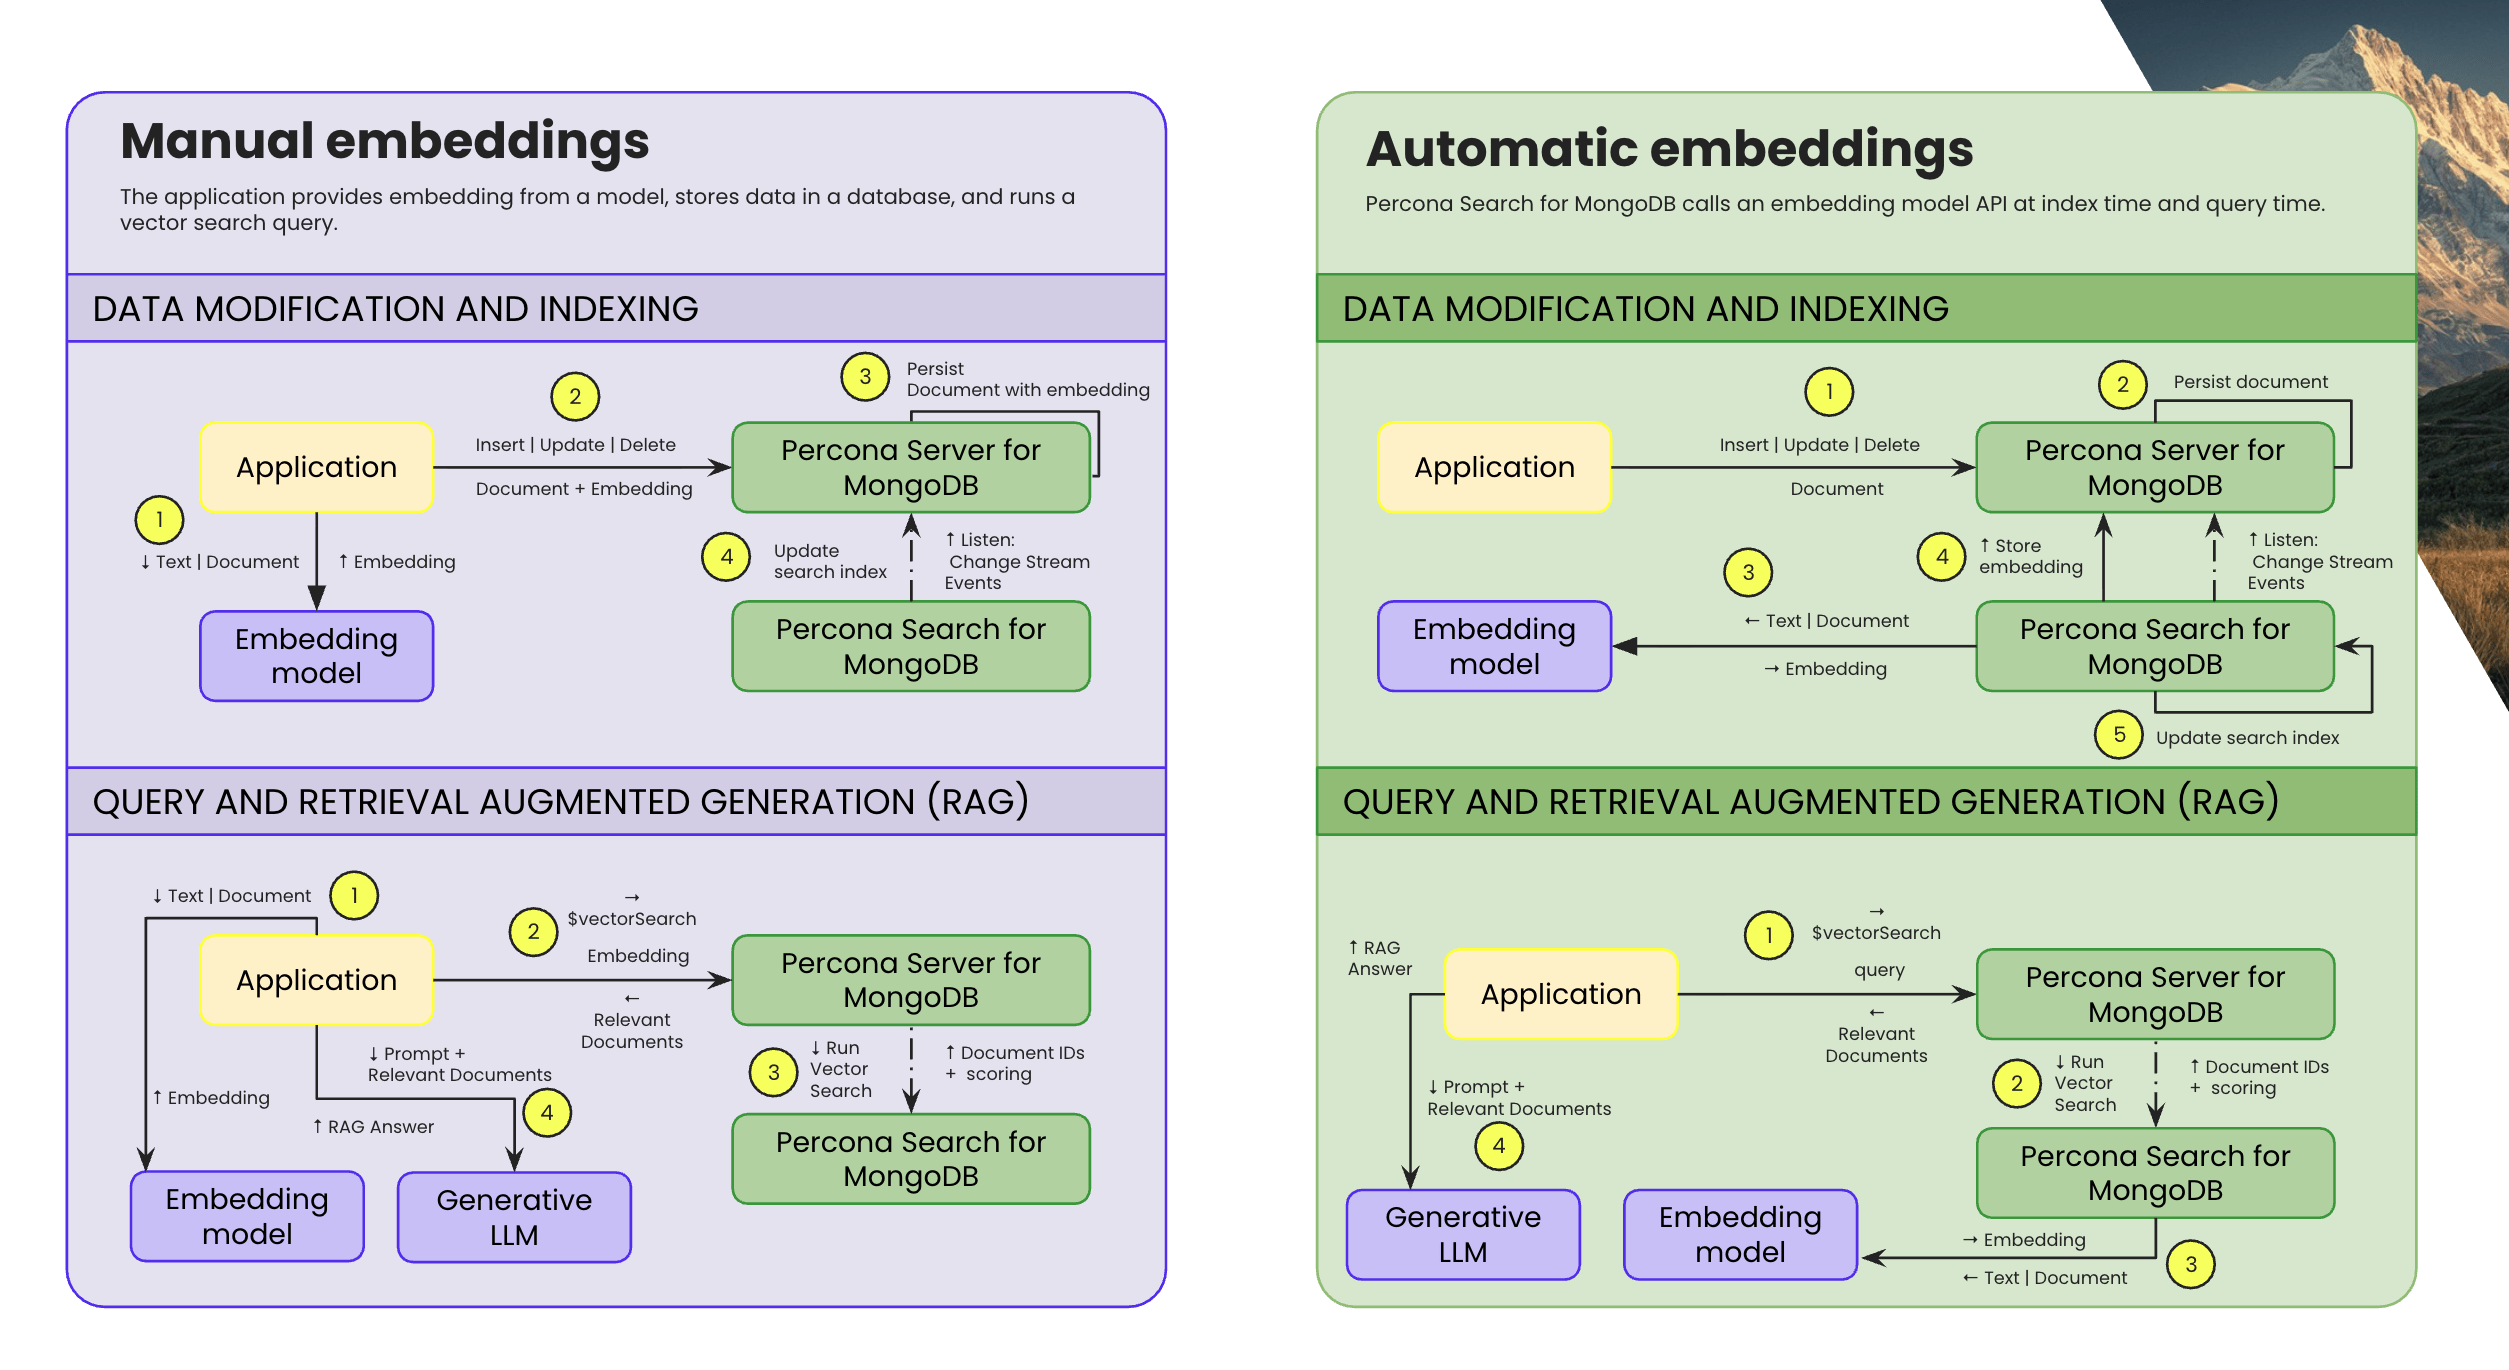
Today, automatic embeddings are supported only with Voyage AI models: voyage-4-large, voyage-4, voyage-4-lite, and voyage-code-3. Three practical consequences follow from that.

  • Your data travels to a third-party service. Every document you index and every query your users type are sent to Voyage AI’s cloud for processing. The support tickets, the patient notes, the contracts, the internal wiki – whatever you actually store – are handled outside your perimeter, from a database you self-host on hardware you own. Voyage AI does offer an on-premises deployment, which comes with its own licensing and costs. Without it, an air-gapped deployment cannot use automatic embeddings, and neither can teams working under data-residency obligations, which covers most of regulated Europe.
  • It’s metered. There is a free tier – 200 million tokens to get you started, less for specialized models – but it is capped on both volume and velocity, with requests and tokens per minute throttled. Beyond that, it runs roughly $0.02 to $0.12 per million tokens, on every reindex and every query your application serves.
  • The model is chosen for you. Not the one that performs best in your language. Not the domain model your data science team fine-tuned. Not a smaller open-weights model that is good enough for your use case.

The Percona plan

We want automatic embeddings to be open, so you have a genuinely unlimited choice of models suited to your needs. We will start with everything that speaks to the OpenAI-compatible embeddings API, which already covers a large and growing ecosystem:

  • Ollama – local, free, 100+ open models including nomic-embed-text, mxbai-embed-large, and all-minilm
  • vLLM – self-hosted GPU inference
  • llama.cpp server – local CPU or GPU inference
  • LocalAI and LM Studio
  • Hugging Face Text Embeddings Inference (TEI)

Over time, we intend to widen that further, toward the 25,000-model catalog the open ecosystem has already built. Cloud providers remain available to teams that prefer them. They just stop being the only option.

Reranking

Reranking is the second half of how serious retrieval works. Vector search is fast because the query and the documents are embedded separately and never actually compared – the model sees your query, sees a document, and never sees them side by side. That approximation is what makes it possible to search millions of documents in milliseconds, and it is also why the top result is often merely in the right neighborhood rather than right. A reranker fixes that: it takes the top 50 or 100 candidates and runs each through a model that reads the query and the document together, scoring genuine relevance rather than vector proximity. In practice, this is usually the single largest accuracy improvement available in a retrieval pipeline, and it matters most for RAG, where the language model only ever sees the top handful of results. If the passage that answers the question is sitting at rank eight, your application behaves as though the answer does not exist.

The $rerank stage is available only on MongoDB Atlas.

The Percona plan

We intend to open reranking as well. Our initial target is BAAI/bge-reranker-large, a strong cross-encoder text-ranking model from the Beijing Academy of Artificial Intelligence, published on Hugging Face under the permissive MIT license.

Contextual chunking and multimodal pipelines

Contextual chunking matters because embedding models have fixed context windows, so anything longer than a few paragraphs has to be split before it can be indexed. Split it naively on a character count, and you shred the meaning: a clause reading “this must be renewed within 30 days” is worthless when “this” was defined two chunks earlier. Contextual and late-chunking techniques embed each chunk with awareness of the surrounding document, so the retrieved passage still makes sense on its own. This is the difference between a RAG system that cites something useful and one that confidently quotes a fragment.

Multimodal pipelines embed text and images into a single vector space, so a search for “worn leather armchair, mid-century” can match a photograph with no caption. Product catalogs, media archives, scanned paperwork, engineering diagrams – anywhere the information lives in the picture rather than the metadata.

The Percona plan

For both of these, the path available today is a Voyage cloud API, called and paid for per token, with your content leaving your network. Meanwhile, the open-weights ecosystem offers excellent cross-encoder rerankers such as BGE-M3 from BAAI, and CLIP- and SigLIP-class multimodal encoders that run comfortably on a single GPU, or on CPU if you are patient. None of them is wired in yet. We would like to change that.

Search-index backup, restore, and recovery

This is documented rather than absent, and it is worth reading closely to understand what it asks of you.

mongot is not your primary data store, so a lost index can always be rebuilt from mongod. The docs note the trade-off in the same breath: index builds “can be slow and in some cases can take days to complete.” For anything with a recovery-time objective, days of degraded search after a disk failure need a faster answer.

That faster answer is a filesystem snapshot, and here is the whole procedure. Stop mongot, then snapshot its data directory with the tool of your choice – the docs provide a working LVM example. To restore, put the directory back, generate a fresh server identity, and restart. mongot then resumes replication from mongod and catches up.

It works. It is also entirely yours to build, and there are a few properties worth planning around:

  • No orchestration or scheduling, and no coordination with your database backup – so no consistent point-in-time across mongod and mongot.
  • No object storage integration.
  • The search process is stopped while the copy is taken.
  • The snapshot has a shelf life. A mongot backup is valid only for as long as the change stream can carry it forward, so a snapshot older than your oplog retention window is detected as having fallen off the oplog and triggers the full rebuild you took the snapshot to avoid.
  • On Kubernetes, MongoDB Controllers for Kubernetes does not back up or restore mongot volumes, and the docs recommend planning this with your storage platform.

The Percona plan

Automated, scheduled, verified backups are a problem the open-source community solved for databases a long time ago, and search indexes deserve the same treatment. Percona Backup for MongoDB and Percona Operator for MongoDB are a natural fit: PBM to orchestrate search-index snapshots alongside the database backup it already handles, with fast index initialization from object storage – S3, Azure, GCS, MinIO – instead of a full change-stream replay. The goal is for search-index recovery to be something you configure once, rather than script.

Observability

There is a /metrics endpoint that exposes a great deal. What isn’t there yet is anything built on top of it. Atlas has a Search Metrics UI; for self-managed deployments, dashboards are, in the documentation’s own phrasing, “not provided in a UI component.” Alerting is yours to define, as are log retention and diagnostic-data rotation.

To be concrete about what “yours to define” involves: the upstream docs publish a genuinely thoughtful set of seventeen recommended alerts across three severity tiers, each with example PromQL to adapt to your environment and thresholds to tune to your workload. The recommended approach is to implement the paging tier first, run it for a week, tune out false positives, then add the other two. That is good advice. It is also multi-week work, repeated for every deployment, before you have the monitoring that a hosted service provides on day one.

Some of the behaviors worth alerting on are genuinely subtle. mongot enforces three disk thresholds internally, and the docs note they take effect whether or not you are monitoring:

  1. Level 1: at 85% full, new index builds remain in PENDING. 
  2. Level 2 – at 90%, steady-state replication is disabled – existing indexes stop receiving change events, and search begins serving stale results while the database itself reports healthy.
  3. Level 3: at 95%, the process stops and requires disk space to be freed before it restarts cleanly. The middle threshold is the one worth wiring up carefully, because it doesn’t announce itself.
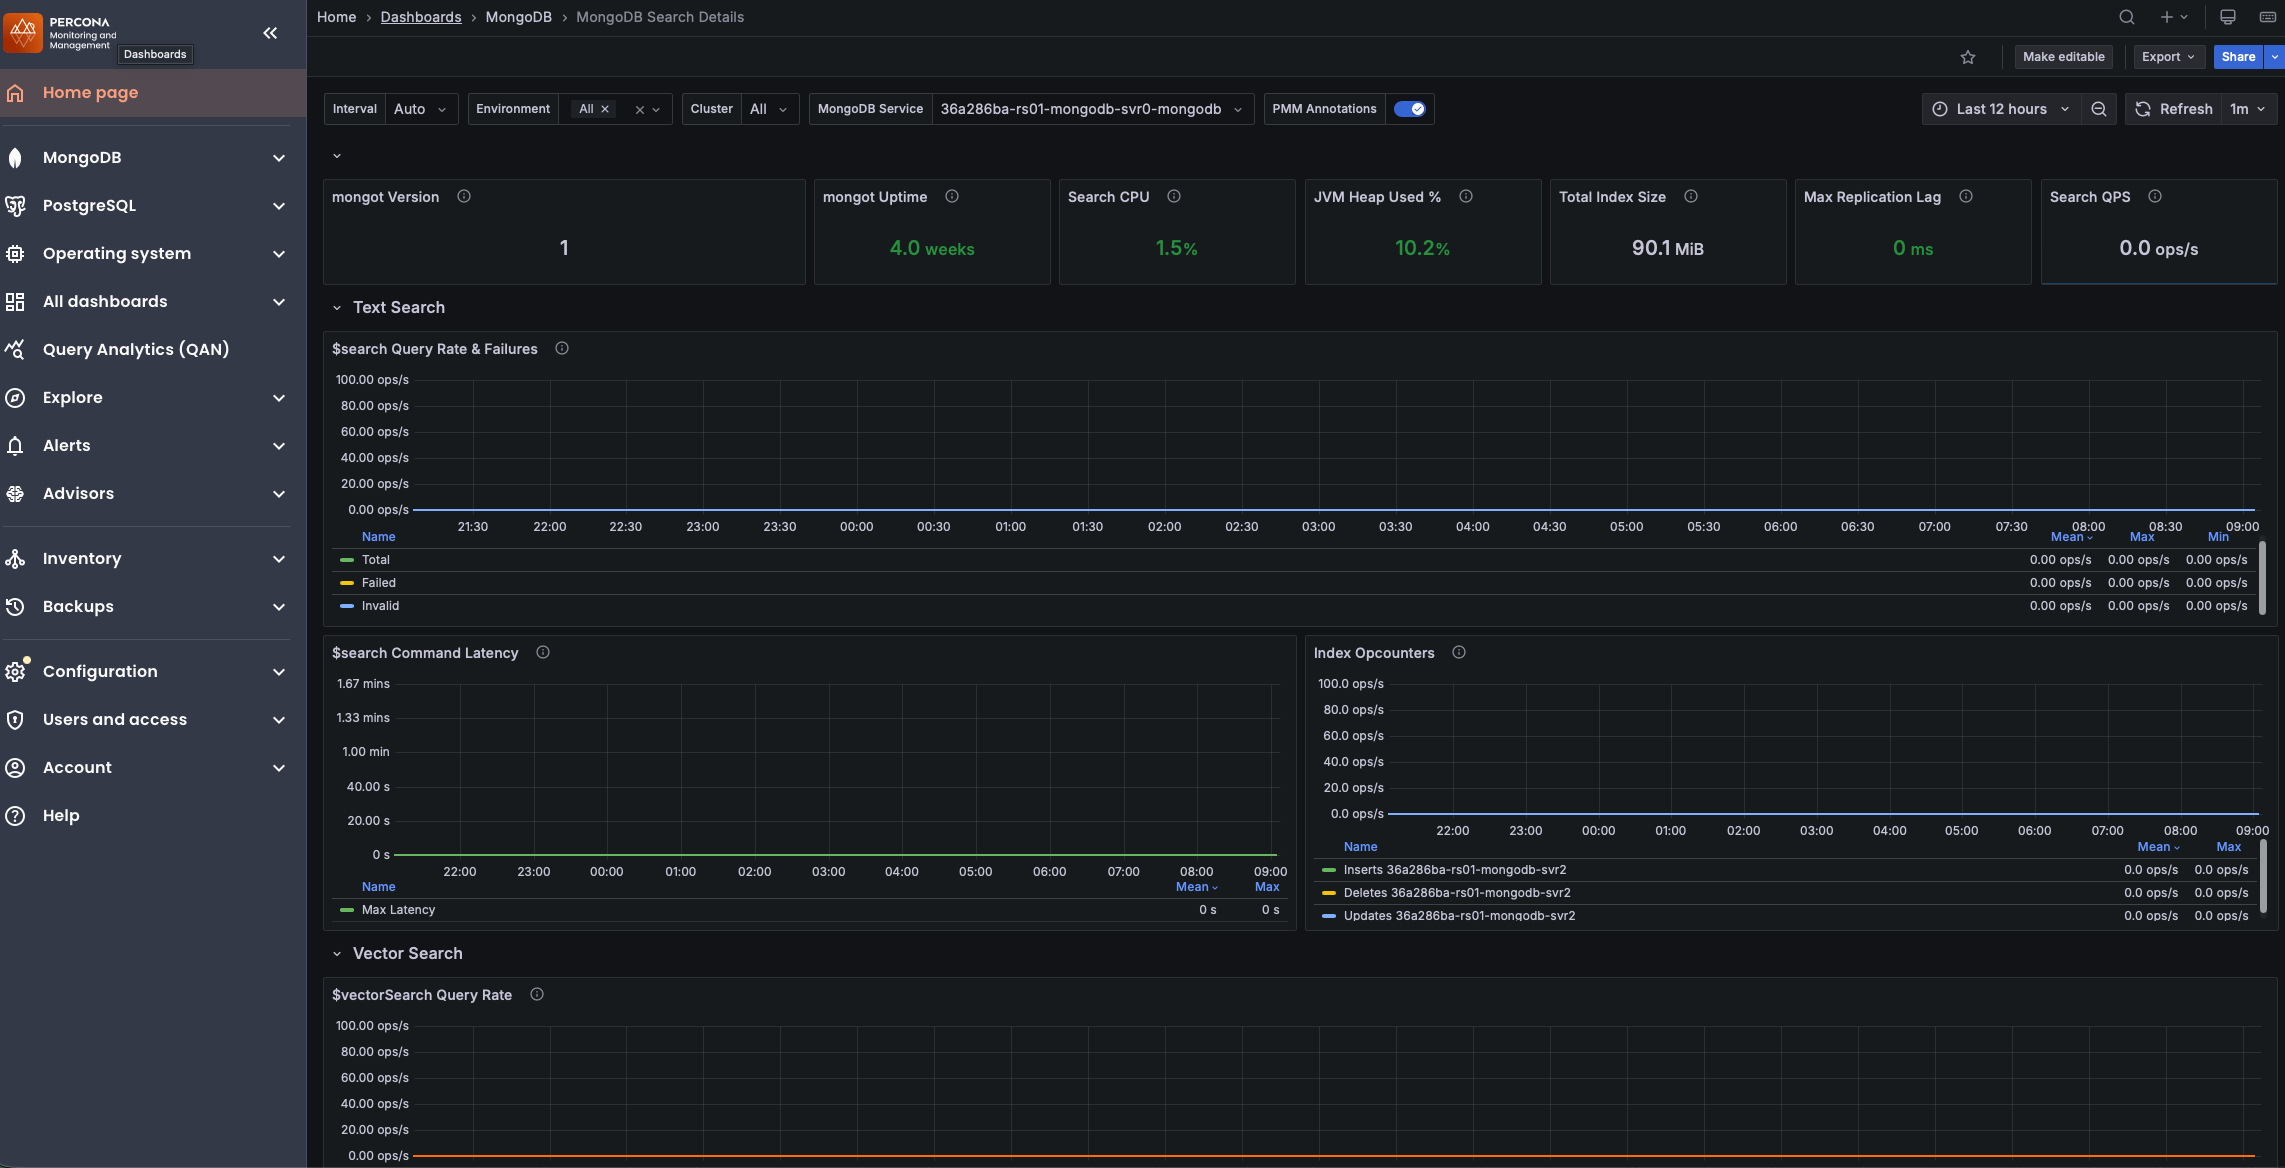
The Percona plan

Percona Monitoring and Management is where this belongs. We believe that collecting these metrics, presenting them on turnkey dashboards, and shipping alert rules with sensible thresholds is exactly the kind of work that should be done once and shared, rather than rebuilt by every team. Sync lag, heap and JVM health, index build progress, executor queue depth, disk headroom – including an alert for the case above, so you learn that replication stopped before your users do.

About the license

mongot is published under the Server Side Public License, and so is our distribution. You can read every line of it on GitHub, and we add no restrictions of our own on top.

SSPL is source-available rather than OSI-approved open source, and we would rather say so than blur the term. What we can commit to is the part we control:

  • Capabilities stay yours.
  • Self-hostable.
  • Air-gappable.
  • No metered API on the critical path.
  • Software remains open and free.

Choice of automation, choice of model, choice of where the inference happens. That is the freedom we are working toward.

Getting started

Percona Search for MongoDB requires Percona Server for MongoDB 8.3, which we shipped as a Technical Preview last week – the first Percona release carrying the $search, $searchMeta, $vectorSearch, $rankFusion and $scoreFusion stages that the search process plugs into.

Before you deploy it

This is a Technical Preview. Please don’t run it in production yet.

Specifically, this version may not fully work with the rest of the Percona software for MongoDB:

  • Percona Backup for MongoDB (PBM) doesn’t yet cover search indexes.
  • Percona Operator for MongoDB search support, recently released in 1.23.0, is currently in tech preview and limited to 1 search node. More automation is coming in the next version.
  • Percona Monitoring and Management doesn’t have search dashboards yet, but they’re coming!

Point it at a copy of your data. Then share with us where it breaks for you.

Tell us what you need

Everything above is a position, which means it can be wrong. If we’ve missed a limitation, picked the wrong first target, or left out the embedding provider you actually use, we would like to hear it:

Search and AI on your own data, on your own hardware, with the model you chose. That is what we are building, and that is what we mean by openness.

If you’re not using Percona for MongoDB yet but you’re interested in Percona Search for MongoDB, you might like to read how Sailthru by Zeta cut more than $1 million a year by migrating to Percona Server for MongoDB.

The way is open.

Disclaimer: Roadmap items are intentions, not delivery commitments. Scope and sequencing may change, and the fastest way to change them is to tell us what you need.


The post The open way of Percona Search for MongoDB appeared first on Percona.
Aug
06
2026
--

The diagnostic data MongoDB Atlas doesn’t hand you

The diagnostic data MongoDB Atlas doesn’t hand you

Every MongoDB server keeps a flight recorder. It’s called FTDC, Full Time Diagnostic Data Capture, and it writes about 5,700 metrics every second into a folder called diagnostic.data, right next to your log. It’s delta-encoded and compressed so aggressively that days of history fit in a few hundred megabytes.

You’ve probably never looked at it. But if you’ve ever opened a performance ticket with MongoDB, it’s the first thing they asked you for, and there’s a good reason: when your cluster goes strange for twenty minutes on a Tuesday, this is usually the only artifact that can tell you what actually happened. Not a five-minute average. The WiredTiger ticket pool, second by second.

If you run your own servers, Percona Server for MongoDB, community MongoDB, whatever you manage yourself, that file is just sitting on disk. You copy it and you look at it.

On Atlas, the same file is written by the same code on a machine you’re paying for, and you can’t get to it. It isn’t in the UI. The log download gives you mongodb.gz and your audit logs and nothing else. Somebody asked how to do this on GitHub back in February 2021 and nobody ever answered.

There is a way. It just isn’t where you’d look. Everything below I ran against an Atlas M10 on MongoDB 8.0.29.


Ask the Admin API to build you a bundle

There’s an endpoint that packages FTDC on demand. Three calls and you have it:

BASE="https://cloud.mongodb.com/api/atlas/v1.0/groups/$GROUP_ID"
AUTH=(-u "$PUB:$PRIV" --digest -sS)

# 1. create the job
curl "${AUTH[@]}" -X POST "$BASE/logCollectionJobs" -H 'Content-Type: application/json' \
  -d '{"resourceType":"REPLICASET","resourceName":"<rs-name>","redacted":true,
      "sizeRequestedPerFileBytes":100000000,"logTypes":["FTDC"]}'

# 2. poll until it says SUCCESS
curl "${AUTH[@]}" "$BASE/logCollectionJobs/<job_id>"

# 3. download
curl "${AUTH[@]}" "$BASE/logCollectionJobs/<job_id>/download" -o ftdc.tar.gz


A few things that will trip you up. <rs-name> is the internal replica set name, not the display name you gave your cluster, run GET $BASE/processes and you’ll see it next to each host. You need a programmatic API key, not a database user. And if your organization requires an access list for API keys, add your IP first or the very first call comes back with ORG_REQUIRES_ACCESS_LIST.

What you get is the real thing: one diagnostic.data directory per replica set member, in exactly the layout every FTDC tool already understands.

Don’t ignore metrics.interim. That’s the chunk the server hasn’t flushed to a numbered file yet, and it holds your most recent samples. In my bundle the newest numbered file stopped at 22:33 while the interim carried data all the way to 22:38. If you’re chasing something that just happened, that’s the file you need.


Your data has a shorter shelf life than you think

Here’s the part that will hurt you if you don’t know it.

The bundle includes a metadata document with getCmdLineOpts in it, which tells you how Atlas starts mongod. There it is:

diagnosticDataCollectionDirectorySizeMB: 400


That’s twice the mongod default of 200 MB, and it’s a hard ceiling. When the directory fills up, the oldest file gets deleted. No warning, no archive.

How long 400 MB lasts depends entirely on how hard your cluster is working, because FTDC compresses by delta, a metric that sits still costs you almost nothing, a metric that moves every second costs real bytes. On an idle cluster I measured about 0.93 MB per 32 minutes per node, which works out to something close to ten days. On a busy production cluster, expect two to five.

So picture the usual sequence. Something goes wrong on a Thursday night. Nobody’s sure how bad it was. The postmortem gets scheduled for the following week, somebody finally asks what the cluster was actually doing at 3 AM, and the answer is gone. Not archived somewhere. Gone.

Collect during the incident, not during the retrospective. On your own servers this is a setting you control: raise diagnosticDataCollectionDirectorySizeMB, or copy the directory somewhere durable on a cron. On Atlas it’s a ceiling somebody else picked for you, and the only way around it is to pull the data yourself before it rolls off.


This shouldn’t have taken an afternoon

None of what I just showed you is documented anywhere.

Think about what FTDC actually is. It’s the first artifact MongoDB support asks for on a performance ticket. It contains no user data, it’s counters, and you can verify that yourself: I looked at 228 KB of diagnostic document and found 38 distinct strings, not one of them the name of a database or collection on the cluster. It’s the single most useful thing you can hand to somebody debugging your server, and it’s safe to share.

And on MongoDB’s own managed platform, the only way to get it is an endpoint that appears nowhere in the log download UI, isn’t mentioned in the Atlas docs, and sits on an API version that never made it to v2.

What you end up with is a two-tier arrangement. The engineers supporting your cluster work from the full second-by-second record. You work from a metrics page with a few dozen series and seven days of retention.

I don’t think anyone decided this. It reads like a capability nobody owned the job of surfacing, the endpoint exists and it works, after all. But intent doesn’t change what it costs you, and right now the gap is being filled by community projects with single-digit star counts. A “Download diagnostic data” button next to “Download logs” would close it in an afternoon.

This is the kind of thing that gets abstracted away when your database becomes somebody else’s service, and it’s almost never what anyone evaluates up front. You compare features and uptime. You don’t think to ask whether you’ll still be able to see what your own server was doing.


Now go read it

Once you have the folder, you need something to open it with, and the tooling here is thinner than the data deserves.

keyhole (https://github.com/simagix/keyhole) has been the reference for years and renders FTDC through Grafana. If you want dashboards and don’t mind standing up the stack, start there.

I built Big Hole (https://github.com/zelmario/Big-hole) for the other case, opening a capture the way you open a log file. It runs entirely in your browser: no backend, no container, nothing uploaded. You drop the folder in and it decodes on your machine. That turns out to matter a lot with this particular file, because the captures worth analysing usually belong to somebody else’s production cluster, and “nothing leaves your machine” is often the difference between being allowed to look at it and not. It opens the Atlas tarball as-is, puts every replica set member on one time axis, shows you who was primary when, overlays your mongod.log on the same timeline, and runs automated checks for the usual suspects, ticket pool exhaustion, cache pressure, flow control. MIT licensed, tested against MongoDB 4.4 through 8.0. You can see a live demo here: https://zelmario.github.io/Big-hole/

Pick whichever you like. Just don’t wait until you need it, by then the data you wanted is already gone.


The post The diagnostic data MongoDB Atlas doesn’t hand you appeared first on Percona.

Jul
24
2026
--

Alert on CVEs in Your Percona Tools for MongoDB on Day One

TL;DR: Starting with PBM 2.15.0 and PCSM 0.9.0, every release artifact – binary tarballs, RPM and DEB packages, and Docker images – ships a CycloneDX 1.6 Software Bill of Materials in JSON. Scan it with Trivy, Grype, or any CycloneDX-compatible tool. For Docker images, the fastest path is a Trivy image –sbom-sources oci <image>. There is nothing to enable, as the SBOM is already a part of the artifact you were going to download.

If you run Percona Backup for MongoDB (PBM) or Percona ClusterSync for MongoDB (PCSM), both part of the Percona Software for MongoDB family, you can now answer one of the stressful questions in operations: “Is my database tooling affected by this CVE?” in seconds instead of days. And when a customer or auditor asks for a parts list of what you deployed, you can hand it over as a single file instead of starting a multi-day investigation.

That parts list is a Software Bill of Materials (SBOM), and starting with PBM 2.15.0 and PCSM 0.9.0, it comes along in every channel we publish – tarballs, RPM and DEB packages, and Docker images. This post shows what is in it, where to find it, and three ways to scan it.

The problem: you can’t patch what you can’t see

Most MongoDB operators run database tooling assembled by someone else – official RPMs, official containers, official tarballs. When something goes wrong upstream, the first question is always the same: what is actually inside this artifact, and is any of it affected?

Two incidents made that question a board-level concern, and a third made it personal for MongoDB teams. Log4Shell in late 2021 forced thousands of teams to manually audit Java dependencies they did not know they had. The xz-utils backdoor disclosed in early 2024 hid in a compression library buried deep inside Linux base images. Then, in December 2025, MongoBleed (CVE-2025-14847) forced MongoDB teams to urgently identify which server and tooling versions were actually deployed. In every case, teams that already had an SBOM per artifact answered “are we affected?” in minutes; teams that did not took days.

The other version of the problem is that the SBOM is something someone else asks of you – a customer running a security review, an auditor checking EU Cyber Resilience Act or US Executive Order 14028 compliance, or a procurement team working through a vendor questionnaire. Without one, every such request turns into a discovery project.

What Percona Backup for MongoDB and ClusterSync now ship

An SBOM is a machine-readable inventory of every component, library, and OS package inside a built artifact, with versions, licenses, and dependency relationships. Think of it as a packing slip for a software shipment, except a computer can parse it, search it, and cross-reference it against vulnerability databases.

Plenty of vendors now ship SBOMs. What matters is whether the SBOM is actually usable, and PBM and PCSM cover the three things that decide that. The format is CycloneDX 1.6, an OWASP-backed JSON standard that every major tool reads: Trivy, Grype, Snyk, and Dependency-Track. The files are generated with Syft from the actual built binary and the staged file tree, so the inventory reflects what was really packaged, not what the source tree implies. And the SBOM ships in every distribution channel, not just one:

Distribution channel SBOM location
Binary tarball <product>-<version>.cdx.json at the root of the archive
RPM package /usr/share/doc/<product>/<product>-<version>.cdx.json
DEB package /usr/share/doc/<product>/<product>-<version>.cdx.json
Docker image Two SBOMs ship side by side — see below

Docker images carry two SBOMs

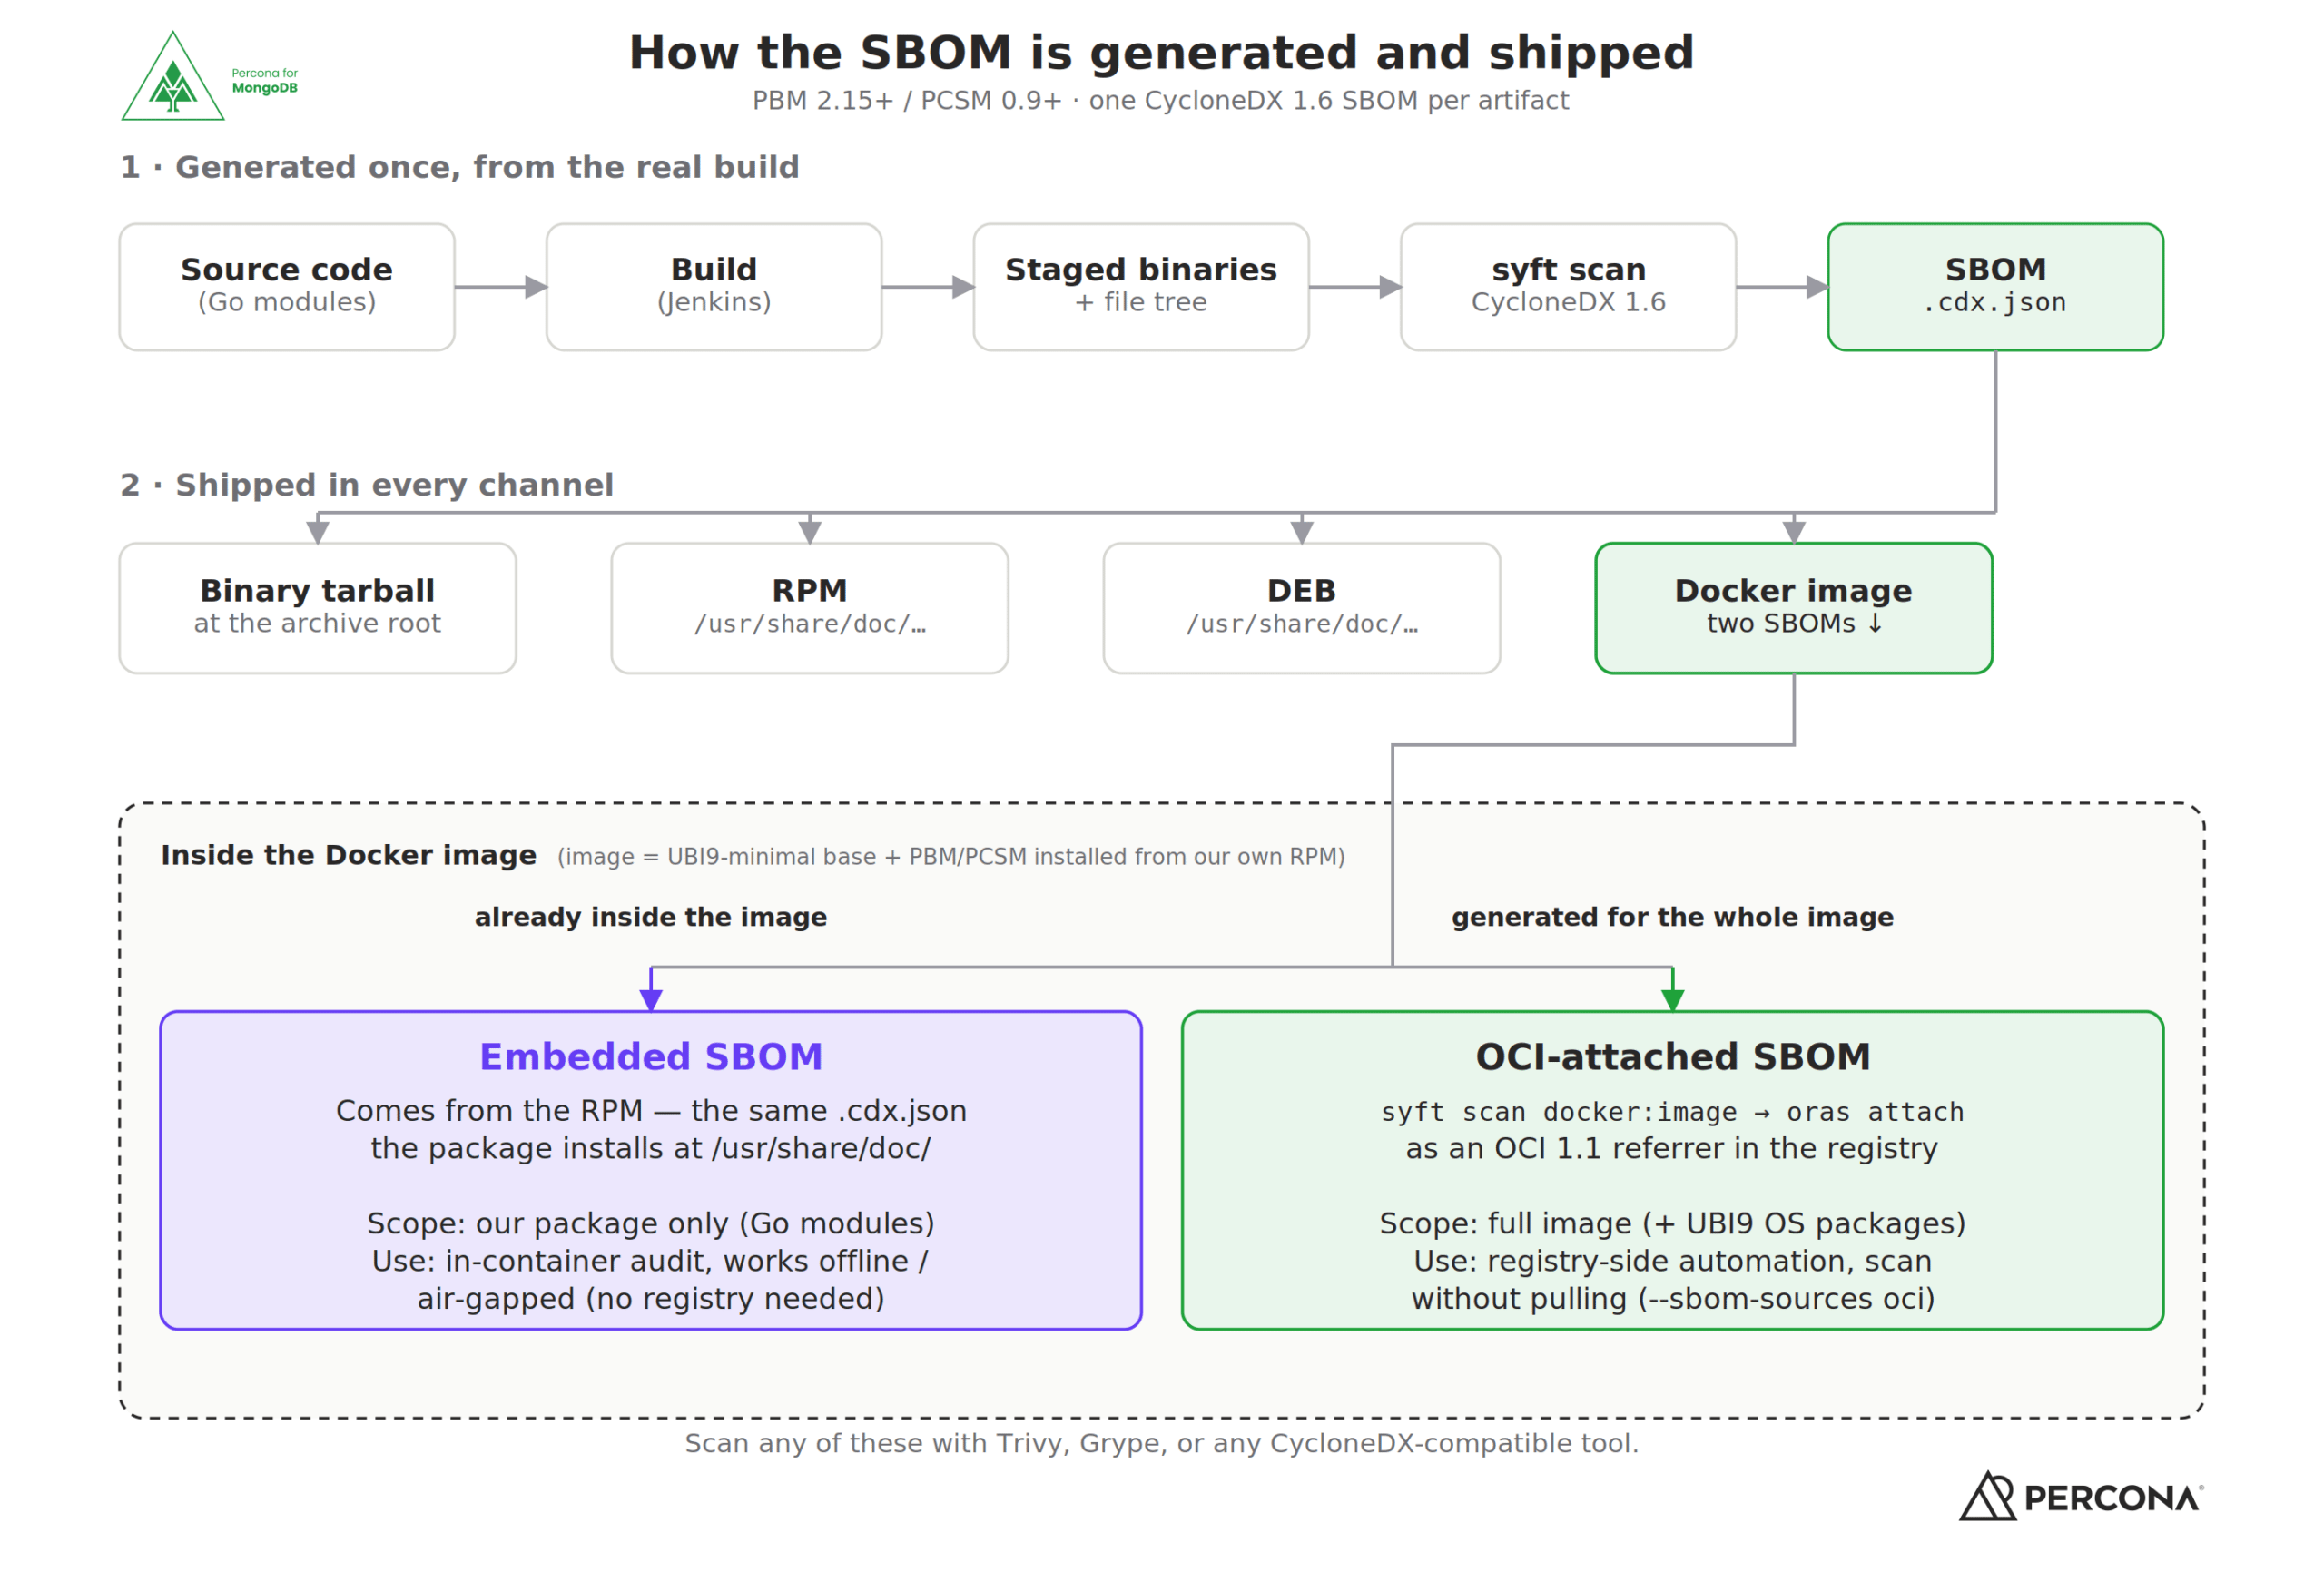
Docker images get special treatment because they bundle two different things: our binary on top of a base operating system. Each PBM and PCSM image, therefore, carries two SBOMs with overlapping scopes.

The embedded SBOM is stored in the image filesystem (the same file the RPM installs) and describes our binary and its Go modules. This is the SBOM to use in offline or air-gapped clusters where you cannot reach a registry.

The OCI-attached SBOM lives next to the image in the registry as an OCI 1.1 referrer artifact and describes the full image, including the base OS packages. This is the canonical SBOM for a Docker image, and the easiest to fetch programmatically.

SBOM Scope / how you reach it
Embedded (installed by the RPM) Our package only: Go modules of the binary; inside the image filesystem
OCI-attached (registry-side) Full image: our package + UBI9 OS packages; via the OCI Referrers API


How the SBOM is generated across PBM and PCSM artifacts, and why a Docker image carries two.

Three ways to scan your SBOM

The examples below use Trivy because it is the most common choice in Percona QA pipelines, but Grype, Snyk, and any other CycloneDX-compatible scanner accept the same .cdx.json files unchanged. By default, these commands report everything the scanner finds. In a CI pipeline, you would want to narrow down the output by leaving only –severity HIGH, CRITICAL to focus on the most serious findings, and –ignore-unfixed to skip CVEs that have no upstream fix yet.

  • From a downloaded package or tarball

Once the artifact is on disk, the SBOM is just a file in a predictable location. Point Trivy at it:

trivy sbom --severity HIGH,CRITICAL,MEDIUM,LOW \
    /usr/share/doc/percona-clustersync-mongodb/percona-clustersync-mongodb-0.9.0.cdx.json

The same command works against the SBOM extracted from a tarball or installed by an RPM or DEB package – only the file path changes. For Oracle Linux, replace with the exact compatible RHEL minor, e.g., --distro redhat/9.8, since Trivy does not recognize the ol OS family on its own, but the RHEL vulnerability database is binary-compatible.

  • From a Docker image, without pulling it

For Docker images, Trivy can fetch the OCI-attached SBOM straight from the registry. No image pull, no extraction step:

trivy image --severity HIGH,CRITICAL,MEDIUM,LOW --sbom-sources oci \
    docker.io/percona/percona-clustersync-mongodb:0.9.0

Trivy resolves the multi-arch index, picks your platform-specific child digest, asks the registry for any attached SBOMs via the OCI Referrers API, and scans whichever one it finds. A typical run looks like this:

Report Summary:

Target Type Vulnerabilities
docker.io/percona/percona-clustersync-mongodb:0.9.0 (redhat 9.8) redhat 0
usr/bin/pcsm gobinary 8

Two targets, two scopes: the base OS layer (no findings) and the PCSM binary (eight Go standard-library CVEs, all flagged because the image was built against a Go release that has since been superseded). The same –sbom-sources oci flag works for PBM images, and against both the public percona/ images on Docker Hub and the engineering perconalab/ images.

  • By hand, with ORAS

If you would rather inspect the OCI artifact directly, to confirm what is attached, or pull the SBOM to disk, the ORAS CLI does that without a scanner in the loop:

oras discover --format tree \
    docker.io/percona/percona-clustersync-mongodb:0.9.0-amd64

The per-arch tag (:<version>-<arch>) resolves straight to the image manifest that the SBOM is attached to. From there, oras pull <digest> writes the .cdx.json to disk for archival or for feeding into a scanner of your choice.

What changes for you

For operators, the upgrade story gets simpler. When a new CVE is disclosed, you no longer have to guess whether your PBM or PCSM deployment is affected; you scan the SBOM that shipped with the exact version you are running and get a yes/no answer in seconds. The SBOM is also a stable input for the dashboards you already run (Dependency-Track, DefectDojo, your SIEM), so PBM and PCSM are no longer blind spots in the inventory.

For security and platform teams, the OCI-attached SBOM means you can pre-screen container images in CI before they ever reach a cluster. Pull-request gates that already scan first-party images for HIGH/CRITICAL findings can pick up PBM and PCSM with no extra glue code: –sbom-sources oci is enough.


Try it on your own deployment

SBOMs ship starting with PBM 2.15.0 and PCSM 0.9.0 across every channel we publish: tarballs, RPM, DEB, and Docker. There is nothing to switch on: download the artifact you would have downloaded, and the SBOM is already there.Full details, including the ORAS walkthrough and per-channel paths, are in the PBM and PCSM documentation (PBM, PCSM).&amp;amp;amp;amp;amp;amp;amp;amp;amp;amp;lt;/p>

Run a scanner over your Percona Backup for MongoDB or Percona ClusterSync for MongoDB deployment using one of the commands above. If the result surprises you in any direction, if you have a finding you would like us to address, or if a workflow did not behave as our docs imply, we would like to hear about it, and the SBOM lets you point us to the exact component and version rather than a hunch. Open an issue in the PBM or PCSM Jira project, or stop by the Percona Community Forum.

One last thing: an SBOM tells you what is inside the artifact, not what we have determined about each finding. That second part is coming. Alongside the per-artifact SBOMs described here, we also plan to publish source SBOMs in the repository, and a follow-up in this series will cover the VEX (Vulnerability Exploitability eXchange) documents that record, for each finding, whether it is fixed, not exploitable in our build, or still under investigation. Watch for both in future re

leases.

The post Alert on CVEs in Your Percona Tools for MongoDB on Day One appeared first on Percona.

Jul
24
2026
--

Alert on CVEs in Your Percona Tools for MongoDB on Day One

TL;DR: Starting with PBM 2.15.0 and PCSM 0.9.0, every release artifact – binary tarballs, RPM and DEB packages, and Docker images – ships a CycloneDX 1.6 Software Bill of Materials in JSON. Scan it with Trivy, Grype, or any CycloneDX-compatible tool. For Docker images, the fastest path is a Trivy image –sbom-sources oci <image>. There is nothing to enable, as the SBOM is already a part of the artifact you were going to download.

If you run Percona Backup for MongoDB (PBM) or Percona ClusterSync for MongoDB (PCSM), both part of the Percona Software for MongoDB family, you can now answer one of the stressful questions in operations: “Is my database tooling affected by this CVE?” in seconds instead of days. And when a customer or auditor asks for a parts list of what you deployed, you can hand it over as a single file instead of starting a multi-day investigation.

That parts list is a Software Bill of Materials (SBOM), and starting with PBM 2.15.0 and PCSM 0.9.0, it comes along in every channel we publish – tarballs, RPM and DEB packages, and Docker images. This post shows what is in it, where to find it, and three ways to scan it.

The problem: you can’t patch what you can’t see

Most MongoDB operators run database tooling assembled by someone else – official RPMs, official containers, official tarballs. When something goes wrong upstream, the first question is always the same: what is actually inside this artifact, and is any of it affected?

Two incidents made that question a board-level concern, and a third made it personal for MongoDB teams. Log4Shell in late 2021 forced thousands of teams to manually audit Java dependencies they did not know they had. The xz-utils backdoor disclosed in early 2024 hid in a compression library buried deep inside Linux base images. Then, in December 2025, MongoBleed (CVE-2025-14847) forced MongoDB teams to urgently identify which server and tooling versions were actually deployed. In every case, teams that already had an SBOM per artifact answered “are we affected?” in minutes; teams that did not took days.

The other version of the problem is that the SBOM is something someone else asks of you – a customer running a security review, an auditor checking EU Cyber Resilience Act or US Executive Order 14028 compliance, or a procurement team working through a vendor questionnaire. Without one, every such request turns into a discovery project.

What Percona Backup for MongoDB and ClusterSync now ship

An SBOM is a machine-readable inventory of every component, library, and OS package inside a built artifact, with versions, licenses, and dependency relationships. Think of it as a packing slip for a software shipment, except a computer can parse it, search it, and cross-reference it against vulnerability databases.

Plenty of vendors now ship SBOMs. What matters is whether the SBOM is actually usable, and PBM and PCSM cover the three things that decide that. The format is CycloneDX 1.6, an OWASP-backed JSON standard that every major tool reads: Trivy, Grype, Snyk, and Dependency-Track. The files are generated with Syft from the actual built binary and the staged file tree, so the inventory reflects what was really packaged, not what the source tree implies. And the SBOM ships in every distribution channel, not just one:

Distribution channel SBOM location
Binary tarball <product>-<version>.cdx.json at the root of the archive
RPM package /usr/share/doc/<product>/<product>-<version>.cdx.json
DEB package /usr/share/doc/<product>/<product>-<version>.cdx.json
Docker image Two SBOMs ship side by side — see below

Docker images carry two SBOMs

Docker images get special treatment because they bundle two different things: our binary on top of a base operating system. Each PBM and PCSM image, therefore, carries two SBOMs with overlapping scopes.

The embedded SBOM is stored in the image filesystem (the same file the RPM installs) and describes our binary and its Go modules. This is the SBOM to use in offline or air-gapped clusters where you cannot reach a registry.

The OCI-attached SBOM lives next to the image in the registry as an OCI 1.1 referrer artifact and describes the full image, including the base OS packages. This is the canonical SBOM for a Docker image, and the easiest to fetch programmatically.

SBOM Scope / how you reach it
Embedded (installed by the RPM) Our package only: Go modules of the binary; inside the image filesystem
OCI-attached (registry-side) Full image: our package + UBI9 OS packages; via the OCI Referrers API


How the SBOM is generated across PBM and PCSM artifacts, and why a Docker image carries two.

Three ways to scan your SBOM

The examples below use Trivy because it is the most common choice in Percona QA pipelines, but Grype, Snyk, and any other CycloneDX-compatible scanner accept the same .cdx.json files unchanged. By default, these commands report everything the scanner finds. In a CI pipeline, you would want to narrow down the output by leaving only –severity HIGH, CRITICAL to focus on the most serious findings, and –ignore-unfixed to skip CVEs that have no upstream fix yet.

  • From a downloaded package or tarball

Once the artifact is on disk, the SBOM is just a file in a predictable location. Point Trivy at it:

trivy sbom --severity HIGH,CRITICAL,MEDIUM,LOW \
    /usr/share/doc/percona-clustersync-mongodb/percona-clustersync-mongodb-0.9.0.cdx.json

The same command works against the SBOM extracted from a tarball or installed by an RPM or DEB package – only the file path changes. For Oracle Linux, replace with the exact compatible RHEL minor, e.g., --distro redhat/9.8, since Trivy does not recognize the ol OS family on its own, but the RHEL vulnerability database is binary-compatible.

  • From a Docker image, without pulling it

For Docker images, Trivy can fetch the OCI-attached SBOM straight from the registry. No image pull, no extraction step:

trivy image --severity HIGH,CRITICAL,MEDIUM,LOW --sbom-sources oci \
    docker.io/percona/percona-clustersync-mongodb:0.9.0

Trivy resolves the multi-arch index, picks your platform-specific child digest, asks the registry for any attached SBOMs via the OCI Referrers API, and scans whichever one it finds. A typical run looks like this:

Report Summary:

Target Type Vulnerabilities
docker.io/percona/percona-clustersync-mongodb:0.9.0 (redhat 9.8) redhat 0
usr/bin/pcsm gobinary 8

Two targets, two scopes: the base OS layer (no findings) and the PCSM binary (eight Go standard-library CVEs, all flagged because the image was built against a Go release that has since been superseded). The same –sbom-sources oci flag works for PBM images, and against both the public percona/ images on Docker Hub and the engineering perconalab/ images.

  • By hand, with ORAS

If you would rather inspect the OCI artifact directly, to confirm what is attached, or pull the SBOM to disk, the ORAS CLI does that without a scanner in the loop:

oras discover --format tree \
    docker.io/percona/percona-clustersync-mongodb:0.9.0-amd64

The per-arch tag (:<version>-<arch>) resolves straight to the image manifest that the SBOM is attached to. From there, oras pull <digest> writes the .cdx.json to disk for archival or for feeding into a scanner of your choice.

What changes for you

For operators, the upgrade story gets simpler. When a new CVE is disclosed, you no longer have to guess whether your PBM or PCSM deployment is affected; you scan the SBOM that shipped with the exact version you are running and get a yes/no answer in seconds. The SBOM is also a stable input for the dashboards you already run (Dependency-Track, DefectDojo, your SIEM), so PBM and PCSM are no longer blind spots in the inventory.

For security and platform teams, the OCI-attached SBOM means you can pre-screen container images in CI before they ever reach a cluster. Pull-request gates that already scan first-party images for HIGH/CRITICAL findings can pick up PBM and PCSM with no extra glue code: –sbom-sources oci is enough.


Try it on your own deployment

SBOMs ship starting with PBM 2.15.0 and PCSM 0.9.0 across every channel we publish: tarballs, RPM, DEB, and Docker. There is nothing to switch on: download the artifact you would have downloaded, and the SBOM is already there.Full details, including the ORAS walkthrough and per-channel paths, are in the PBM and PCSM documentation (PBM, PCSM).&amp;amp;amp;amp;amp;amp;amp;amp;amp;amp;lt;/p>

Run a scanner over your Percona Backup for MongoDB or Percona ClusterSync for MongoDB deployment using one of the commands above. If the result surprises you in any direction, if you have a finding you would like us to address, or if a workflow did not behave as our docs imply, we would like to hear about it, and the SBOM lets you point us to the exact component and version rather than a hunch. Open an issue in the PBM or PCSM Jira project, or stop by the Percona Community Forum.

One last thing: an SBOM tells you what is inside the artifact, not what we have determined about each finding. That second part is coming. Alongside the per-artifact SBOMs described here, we also plan to publish source SBOMs in the repository, and a follow-up in this series will cover the VEX (Vulnerability Exploitability eXchange) documents that record, for each finding, whether it is fixed, not exploitable in our build, or still under investigation. Watch for both in future re

leases.

The post Alert on CVEs in Your Percona Tools for MongoDB on Day One appeared first on Percona.

Jul
23
2026
--

Percona Operator for MongoDB 1.23.0: ClusterSync Migration, Vector Search, and PVC Snapshot Backups


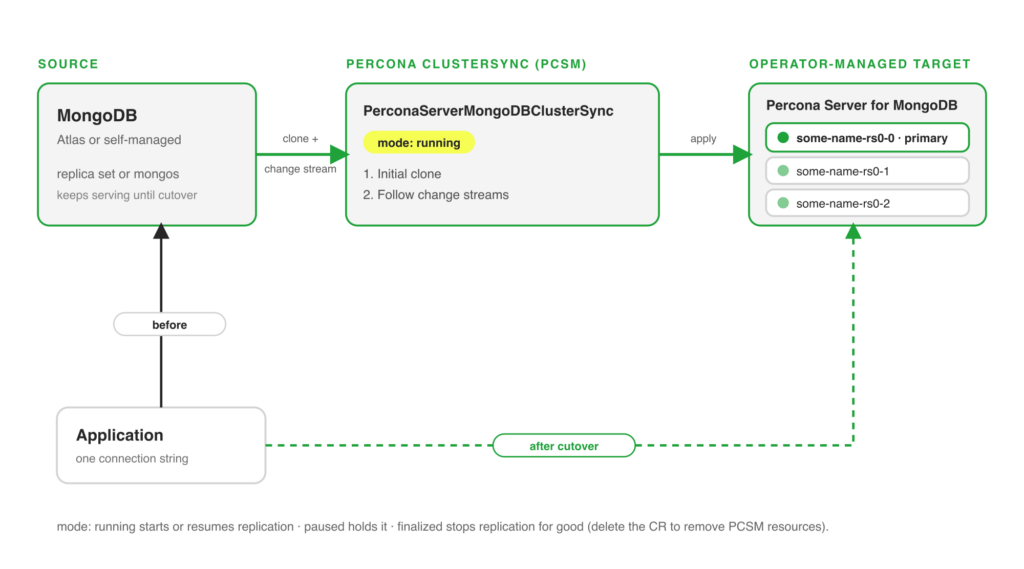
Percona Operator for MongoDB 1.23.0 makes the operator a place you move to, not just a place you start. A new ClusterSync component clones a live source and follows its change streams, so leaving a hosted service is a short cutover rather than a long outage. Alongside it, this release adds semantic vector search and storage-layer snapshot backups, two features that matter most once the data is yours to run.

The three headline features are Percona ClusterSync for MongoDB, vector search, and PVC snapshot backups. ClusterSync clones and continuously replicates a live source into an operator-managed cluster. Vector search brings semantic queries to Percona Server for MongoDB. PVC snapshot backups move backups off the network path and onto the storage layer.

This release also widens where you can run it, adding official Rancher Kubernetes Engine (RKE2) support and full ARM64 images. Much of what shipped here traces back to requests on forums.percona.com and the public issue tracker.


In this post, you’ll learn about:

  • ClusterSync migration and replication
  • Vector search for semantic queries
  • PVC snapshot backups
  • Other improvements worth knowing about


Zero-Downtime Migration with Percona ClusterSync

Moving a live MongoDB database onto the operator has always been the awkward first step. Dump-and-restore needs a maintenance window sized to your data, and hand-built replication between a source and a target is fragile to set up and easy to get wrong. This release introduces Percona ClusterSync for MongoDB (PCSM) as an operator-managed component, so the migration path is via a Kubernetes object rather than a runbook.


Why it matters

The common case is migrating a hosted MongoDB service, for example MongoDB Atlas, for an operator-managed Percona Server for MongoDB cluster you control end to end. A typical trigger in production is a hosted-service bill that climbs with the workload, or a compliance requirement to keep data inside your own VPC and region: a team running a user-profile store on Atlas points PCSM at it, lets the target catch up over a day or two while the application keeps serving from Atlas, then cuts over in a maintenance window measured in seconds. PCSM clones the existing data, then tracks ongoing changes through MongoDB change streams, so the target stays current while you validate it. When you are ready, you cut the application over during a short window rather than a long one. The same mechanism keeps a continuously updated replica for non-production use or a hybrid-cloud copy.

How it works

PCSM runs as its own container, deployed and managed through a new PerconaServerMongoDBClusterSync custom resource. It performs an initial clone from the source connection string, then consumes change stream events to apply subsequent writes to the target. A mode field controls the lifecycle: running starts or resumes replication, paused holds it, and finalized stops replication.


Wiring it up

apiVersion: psmdb.percona.com/v1
kind: PerconaServerMongoDBClusterSync
metadata:
  name: my-cluster-sync
spec:
  clusterName: my-target-cluster-name
  image: percona/percona-clustersync-mongodb:0.9.0
  # mode controls the PCSM lifecycle intent. Allowed values:
  #   running   - start/resume replication (default)
  #   paused    - pause an active replication
  #   finalized - stop replication
  mode: running
  source:
    uri: mongodb://source-cluster-mongos.source-namespace.svc.cluster.local:27017
    credentialsSecret: my-cluster-sync-source
  # excludeNamespaces lists MongoDB namespaces (db or db.collection) to skip.
  # excludeNamespaces:
  #   - admin
  #   - local

clusterName names the operator-managed target that receives the data. source.uri and source.credentialsSecret point at the database you are migrating from, which can be Atlas, a self-managed replica set, or another operator cluster. mode is the control you drive the cutover with: run to catch up, pause to hold, then finalize once the application points at the new cluster. The optional excludeNamespaces list skips databases or collections you do not want to copy.
 

Cutover and rollback

The cutover is yours to time, not the operator’s. During the running replication, the target trails the source by the change-stream lag, which you watch until it is small and steady. You then stop writes on the source, let the last events drain, and repoint the application at the target cluster. Because the source keeps serving until you move the application, a rollback before cutover is simply leaving the application where it is. After cutover, treat the move as one-way once writes flow to the target, so verify the target thoroughly during the sync window rather than after.

Note: The PCSM component ships at version 0.9.0 with this release. Test the full migration and cutover against a staging copy before you run it on production data, and keep the source available until you have verified the target.


Vector search for semantic queries

Vector search retrieves results by meaning rather than exact keyword match, which is the retrieval pattern behind semantic search and retrieval-augmented generation for AI applications. Teams that already store their data in MongoDB have had to copy vectors into a separate engine to do this, which adds a system to run and a pipeline to keep in sync. In production, this is the pattern behind a support tool that surfaces past tickets describing the same problem in different words, a product catalog that returns items by intent rather than exact keywords, and a RAG service that grounds a model on internal documents. This release lets you store and query vector data alongside your regular documents in Percona Server for MongoDB, so those workloads query one system instead of two.
 

How it works

The operator deploys and manages the mongot search process, wires its authentication and TLS to the rest of the cluster, and keeps the search index synchronized for both replica set and sharded deployments. Applications query the index through the same MongoDB connection they already use, so you add semantic search without a second client, a second driver, or a second set of credentials. You do not stand up or secure a separate search tier; the operator treats mongot as another managed component of the cluster.
 

Wiring it up

Enable the search component in the custom resource:

spec:
  search:
    enabled: true
    image: perconalab/percona-server-mongodb-operator:main-mongot
    size: 1
    storage:
      persistentVolumeClaim:
        resources:
          requests:
            storage: 10Gi
    resources:
      requests:
        cpu: "2"
        memory: 2Gi

size sets how many search nodes to run, and storage gives the search index its own PersistentVolumeClaim so it does not compete with the database volume. Size the resources block to your index: vector indexes are memory-sensitive, so give mongot enough headroom for the corpus you intend to query.

Note: Vector search is a tech preview in 1.23.0 and is not recommended for production yet. It requires Percona Server for MongoDB 8.3 or later.


PVC snapshot backups

Logical and streamed physical backups both push data across the network to object storage, and for a multi-terabyte cluster, that path is the bottleneck. Backups run long, restores run longer, and both compete with production traffic for CPU and bandwidth. This release adds backups built on PersistentVolumeClaim snapshots, which takes the storage layer directly.


Why it matters

A PVC snapshot is a point-in-time copy of your data volumes taken at the storage layer through the Kubernetes VolumeSnapshot API. Because the operator asks the storage provider for a snapshot instead of streaming bytes out, a backup typically completes in seconds or minutes regardless of database size, and a restore is correspondingly fast. Two production situations show the difference: a nightly backup that no longer fits its window as a cluster grows past a few terabytes, and a staging refresh that ties up resources for hours while it restores a streamed copy. A storage-layer snapshot turns both into a near-instant operation. The speed comes from how the storage layer implements snapshots: instead of copying the whole volume, most backends record only the blocks that changed since the previous snapshot and reference the rest, so the cost tracks your change rate rather than the total database size. Snapshots also work with encrypted and TLS-enabled clusters, and they use fewer cluster resources because there is no long-running data-transfer job.


Wiring it up

The operator takes snapshot backups in two ways: on demand through a PerconaServerMongoDBBackup object, or on a schedule through a backup task. The scheduled form looks like this, using the external type and a VolumeSnapshotClass:

spec:
  backup:
    tasks:
      - name: daily-snapshot
        enabled: false
        schedule: "0 0 * * *"
        retention:
          count: 1
          type: count
          deleteFromStorage: true
        type: external
        volumeSnapshotClass: YOUR-VOLUME-SNAPSHOT-CLASS

type: external tells the operator to take a storage-layer snapshot rather than stream a backup, and volumeSnapshotClass names the VolumeSnapshotClass your CSI driver provides. The retention block prunes old snapshots on the schedule you set. Your storage provider must support the Kubernetes VolumeSnapshot API for this to work.

Snapshot backups complement the streamed and logical backups the operator already supports; they do not replace them. Snapshots usually live in the same storage account and region as the volumes they copy, so keep a streamed backup to object storage for off-site and cross-region disaster recovery. A practical policy pairs frequent fast snapshots for quick local recovery with a less frequent streamed backup for durability, and the operator runs both from the same backup.tasks list.


Note:
PVC snapshot backups are a tech preview in 1.23.0 and are not recommended for production yet. Snapshot portability and retention semantics depend on your CSI driver, so test restores before you rely on them.


Other improvements

Beyond the three headline features, 1.23.0 ships a set of enhancements that smooth day-two operations:

  • Operator-generated connection string Secrets (K8SPSMDB-1537): the operator now publishes a ready-to-use MongoDB connection string (URI) in a Kubernetes Secret for the databaseAdmin user. An application can read that one Secret and connect to it, instead of building the URI itself from Pod names, Services, TLS settings, and credentials.
  • Workload Identity for GCS backups (K8SPSMDB-1602): back up to Google Cloud Storage without storing a service-account JSON key in a Secret.
  • Oracle Cloud Infrastructure Object Storage (K8SPSMDB-1644) and Alibaba Cloud OSS (K8SPSMDB-1519): two more native backup destinations.
  • Restore a collection under a different name (K8SPSMDB-1603): use selective.nsFrom and nsTo to restore one collection alongside the live one for inspection or recovery.
  • External nodes as arbiters (K8SPSMDB-1031): set arbiterOnly: true on an external node to place a tie-breaker vote in a third location without a data-bearing member.
  • cert-manager ClusterIssuer and TLS policy (K8SPSMDB-1413, K8SPSMDB-1458): point the operator at an existing ClusterIssuer, and use certManagementPolicy to keep certificate lifecycle fully under your control.
  • Tunable reconciliation interval (K8SPSMDB-1571): set RECONCILE_INTERVAL to reduce Kubernetes API load on large fleets (default 5s).
  • Query Analytics via mongolog for PMM (K8SPSMDB-1546): choose mongolog as the QAN source in Percona Monitoring and Management.
  • Custom sidecar health probes (K8SPSMDB-1701, K8SPSMDB-1728) and StatefulSet revisionHistoryLimit (K8SPSMDB-1572): finer control over probes and rollout history. 

For the full list, including bug fixes, see the release notes linked below.


Conclusion

Percona Operator for MongoDB 1.23.0 covers the arc from getting data in to keeping it safe: ClusterSync brings a live database onto the operator with a short cutover, vector search lets one system serve both documents and semantic queries, and PVC snapshot backups take the network out of the backup path. With RKE2 and full ARM64 support added, more of that runs on the platforms teams actually use. If there is a workflow you still script around the operator, tell us on the forum, since that is where releases like this one come from.


Try Percona Operator for MongoDB 1.23.0


The post Percona Operator for MongoDB 1.23.0: ClusterSync Migration, Vector Search, and PVC Snapshot Backups appeared first on Percona.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com