 For a long time, I’ve been thinking about the possibility of importing a single file with multiple connections. Why? Simply because we have scenarios where we end up importing a big file with a single loader thread. Well, I have good news: since the release of 0.16.3-1, we are able to do it. There are […]
Jul
09
2024
09
2024
--
MyLoader Is Now Importing at Full Speed
Aug
23
2021
23
2021
--
myloader Stops Causing Data Fragmentation

 During the development of the myloader –innodb-optimize-keys option, which was released in version 0.10.7, we found several issues and opportunities to improve the process. We had to change the approach, reimplement some of the core functionality and add a couple of data structures. That allowed us to implement, at a really low cost, a feature that executes the files that contain INSERT statements, sorted by Primary Key. This is desirable to reduce page splits, which cause on-disk tablespace fragmentation.
In this blog post, I will present the differences in data fragmentation for each version.
Test Details
These are local vm tests as there is no intention to show performance gain.
The table that I used is:
CREATE TABLE `perf_test` (
 `id` int(11) NOT NULL AUTO_INCREMENT,
 `val` varchar(108) DEFAULT NULL,
 PRIMARY KEY (`id`),
 KEY `val` (`val`(2)),
 KEY `val_2` (`val`(4)),
 KEY `val_3` (`val`(8))
) ENGINE=InnoDB
And I inserted the data with:
INSERT INTO perf_test(val) SELECT concat(uuid(),uuid(),uuid()) FROM perf_test;
The graphs below were made with innodb_ruby (more info about it in this blog post) and based on a table of 131K rows with –rows 100. The intention of this test was to create a lot of files that will cause better spread in the Primary Key. The timings are over the same table structure but the table has 32M rows. Finally, I performed the test with 1 and 4 threads and with –innodb-optimize-keys when possible.
Tests Performed
In myloader v0.10.5 there was no file sorting, which is why we can see that lower Primary Key values were updated recently:
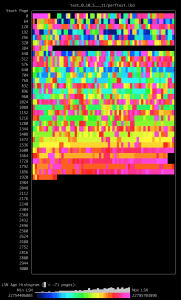
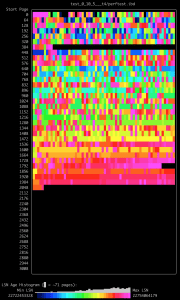
It doesn’t matter the number of threads, we can see how pages, across the whole file, are being updated at any time.
This is happening because mydumper exported the files in order with these min_id and max_id values:
| File | min_id | max_id |
| test.perf_test.00000.sql | 1 | 21261 |
| test.perf_test.00001.sql | 21262 | 42522 |
| test.perf_test.00002.sql | 42523 | 49137 |
| test.perf_test.00003.sql | 65521 | 85044 |
| test.perf_test.00004.sql | 85045 | 98288 |
| test.perf_test.00006.sql | 131056 | 148827 |
| test.perf_test.00007.sql | 148828 | 170088 |
| test.perf_test.00008.sql | 170089 | 191349 |
| test.perf_test.00009.sql | 191350 | 196591 |
| test.perf_test.00012.sql | 262126 | 276393 |
But, during import, there was no order, let’s see the log:
** Message: 12:55:12.267: Thread 3 restoring `test`.`perf_test` part 1476. Progress 1 of 1589 .
** Message: 12:55:12.269: Thread 1 restoring `test`.`perf_test` part 87. Progress 2 of 1589 .
** Message: 12:55:12.269: Thread 2 restoring `test`.`perf_test` part 1484. Progress 3 of 1589 .
** Message: 12:55:12.269: Thread 4 restoring `test`.`perf_test` part 1067. Progress 4 of 1589 .
** Message: 12:55:13.127: Thread 1 restoring `test`.`perf_test` part 186. Progress 5 of 1589 .
** Message: 12:55:13.128: Thread 4 restoring `test`.`perf_test` part 1032. Progress 6 of 1589 .
With these max_id and max_id per file:
| File | min_id | max_id |
| test.perf_test.01476.sql | 31381237 | 31402497 |
| test.perf_test.00087.sql | 1849708 | 1870968 |
| test.perf_test.01484.sql | 31551325 | 31572585 |
| test.perf_test.01067.sql | 22685488 | 22706748 |
| test.perf_test.00186.sql | 3954547 | 3975807 |
| test.perf_test.01032.sql | 21941353 | 21962613 |
With this kind of insert order, you can only imagine the amount of page splits that cause the fragmentation in the InnoDB datafile.
Timings were:
0.10.5/mydumper/myloader  -t 1 6:52
0.10.5/mydumper/myloader  -t 4 4:55
In v0.10.7-2 we have the same behavior:
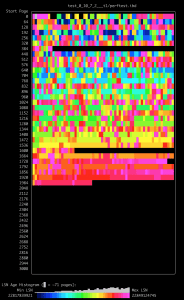
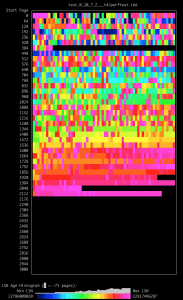
But we have a small performance increase:
0.10.7-2/mydumper/myloader  -t 1 6:49
0.10.7-2/mydumper/myloader  -t 4 4:47
We see the same pattern, even if we use the –innodb-optimize-keys:
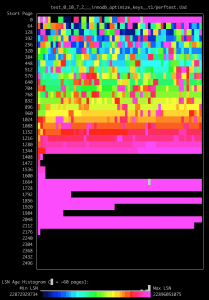
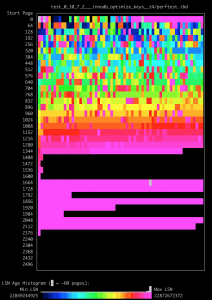
The main difference is the index creation stage.
0.10.7-2/mydumper/myloader --innodb-optimize-keys -t 1 6:07
0.10.7-2/mydumper/myloader --innodb-optimize-keys -t 4 5:53
Now, in v0.10.9, where we have table and file sorting, the graphs have a significant change:
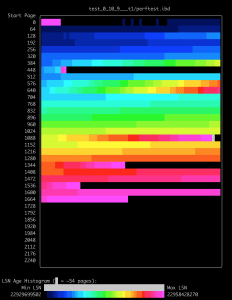
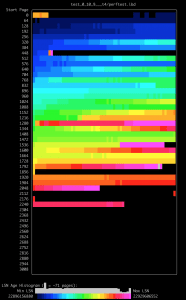
It is also a bit shocking the difference between the 2 graphs, not about color trending, but about the number of pages used which indicates a high fragmentation when multiple threads are used.
master/mydumper/myloader  -t 1 5:50
master/mydumper/myloader  -t 4 4:29
Let’s check now with –innodb-optimize-keys:
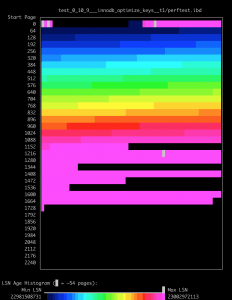
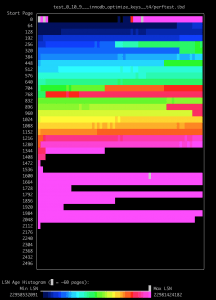
This is what we are looking for! As you can see with 1 thread is perfect, but with 4 threads there is some odd distribution, but for sure, much better than the other options.
However, the timings are not the best:
master/mydumper/myloader --innodb-optimize-keys -t 1 5:33
master/mydumper/myloader --innodb-optimize-keys -t 4 5:10
Let’s compare them:
Data       | Index      | Total      | Table
0 00:05:50 | 0 00:00:00 | 0 00:05:50 | `test`.`perf_test`  -t 1
0 00:04:29 | 0 00:00:00 | 0 00:04:29 | `test`.`perf_test`  -t 4
0 00:02:33 | 0 00:02:59 | 0 00:05:33 | `test`.`perf_test`  -t 1 --innodb-optimize-keys
0 00:02:01 | 0 00:03:09 | 0 00:05:10 | `test`.`perf_test`  -t 4 --innodb-optimize-keys
But that makes sense if you read this blog post. Actually, it would be really nice to have a feature that determines when –innodb-optimize-keys needs to be used.
Conclusions
Version 0.10.9 of MyDumper will allow myloader to insert better than previous versions. Multithreaded inserts sorted by Primary Key are now possible and faster than ever!
Jan
21
2015
21
2015
--
Importing big tables with large indexes with Myloader MySQL tool
Mydumper is known as the faster (much faster) mysqldump alternative. So, if you take a logical backup you will choose Mydumper instead of mysqldump. But what about the restore? Well, who needs to restore a logical backup? It takes ages! Even with Myloader. But this could change just a bit if we are able to take advantage of Fast Index Creation.
As you probably know, Mydumper and mysqldump export the struct of a table, with all the indexes and the constraints, and of course, the data. Then, Myloader and MySQL import the struct of the table and import the data. The most important difference is that you can configure Myloader to import the data using a certain amount of threads. The import steps are:
- Create the complete struct of the table
- Import the data
When you execute Myloader, internally it first creates the tables executing the “-schema.sql” files and then takes all the filenames without “schema.sql” and puts them in a task queue. Every thread takes a filename from the queue, which actually is a chunk of the table, and executes it. When finished it takes another chunk from the queue, but if the queue is empty it just ends.
This import procedure works fast for small tables, but with big tables with large indexes the inserts are getting slower caused by the overhead of insert the new values in secondary indexes. Another way to import the data is:
- Split the table structure into table creation with primary key, indexes creation and constraint creation
- Create tables with primary key
- Per table do:
- Load the data
- Create index
- Create constraints
This import procedure is implemented in a branch of Myloader that can be downloaded from here or directly executing bzr with the repository:
bzr branch lp:~david-ducos/mydumper/mydumper
The tool reads the schema files and splits them into three separate statements which create the tables with the primary key, the indexes and the constraints. The primary key is kept in the table creation in order to avoid the recreation of the table when a primary key is added and the “KEY” and “CONSTRAINT” lines are removed. These lines are added to the index and constraint statements, respectively.
It processes tables according to their size starting with the largest because creating the indexes of a big table could take hours and is single-threaded. While we cannot process other indexes at the time, we are potentially able to create other tables with the remaining threads.
It has a new thread (monitor_process) that decides which chunk of data will be put in the task queue and a communication queue which is used by the task processes to tell the monitor_process which chunk has been completed.
I run multiple imports on an AWS m1.xlarge machine with one table comparing Myloader and this branch and I found that with large indexes the times were:

As you can see, when you have less than 150M rows, import the data and then create the indexes is higher than import the table with the indexes all at once. But everything changes after 150M rows, import 200M takes 64 minutes more for Myloader but just 24 minutes for the new branch.
On a table of 200M rows with a integer primary key and 9 integer columns, you will see how the time increases as the index gets larger:

Where:
2-2-0: two 1-column and two 2-column index
2-2-1: two 1-column, two 2-column and one 3-column index
2-3-1: two 1-column, three 2-column and one 3-column index
2-3-2: two 1-column, three 2-column and two 3-column index
Conclusion
This branch can only import all the tables with this same strategy, but with this new logic in Myloader, in a future version it could be able to import each table with the best strategy reducing the time of the restore considerably.
The post Importing big tables with large indexes with Myloader MySQL tool appeared first on MySQL Performance Blog.