Apr
29
2026
--

XtraBackup incremental prepare phase is 2x-3x faster!

TL;DR

Percona XtraBackup is a 100% open-source backup solution for Percona Server for MySQL and MySQL®. It is designed for high-availability environments, performing online, non-blocking, and highly secure backups of transactional systems without interrupting your production traffic.

While full backups work for small databases, large-scale systems rely on incremental backups to save space and time. However, the “prepare” stage, required to make the incremental backups consistent, was slow because XtraBackup processed the .delta files serially. The .delta files are generated per table and store only the modifications since the last backup.

Great news! In XtraBackup versions 8.0.35-33 and 8.4.0-3 and later, we’ve added support for the --parallel option during the prepare stage. This option lets XtraBackup process multiple .delta files simultaneously, significantly reducing the preparation time, especially when you have a large number of IBD files.

Please add --parallel=X, with the number of threads to use, to the xtrabackup --prepare --apply-log-only command to speed up the incremental prepare operation.

The Incremental Backup Workflow

Before we dive into the performance gains, it’s important to understand how Incremental backups work.

1. Creating the Backups

The process starts with a full backup followed by a backup that captures the changes since the last backup. This smaller backup is called an incremental backup. XtraBackup creates .delta files during incremental backups. Let’s review an example.

  • Take Full Backup: Your starting point is Point A. This backup is an entire copy of your data.
  • Take Inc1 Backup: XtraBackup identifies the changes between Point A and Point B. It creates a .delta file for every table that has been changed. Delta files contain only the pages that changed between the backups.
  • Take Inc2 Backup: XtraBackup identifies the changes between Point B and Point C. It creates a new set of .delta files for this specific period.

For more detailed steps/commands, please check the documentation here: https://docs.percona.com/percona-xtrabackup/8.0/create-incremental-backup.html

2. Preparing the Backups

To restore the data to the latest point, you must merge these changes back into the full backup. The “prepare” phase works differently here:

  • Prepare Inc1: You merge the Inc1 changes into the full backup using the --apply-log-only option. In this step, XtraBackup applies the .delta files and the redo logs, but does not apply the Undo logs
  • Prepare Inc2: You merge the Inc2 changes into the updated base using the --apply-log-only option. XtraBackup applies the .delta files and the Redo logs but skips the Undo logs.
  • Final Prepare: After all the incremental backups are merged, you run a final prepare command on the full backup. This final step applies the Undo logs to make the entire dataset consistent. If you apply the Undo logs during the intermediate steps, you cannot merge any further backups.

More detailed steps to prepare an incremental backup are described here: https://docs.percona.com/percona-xtrabackup/8.0/prepare-incremental-backup.html

The Improvement: Parallel Incremental Delta Apply

We have improved the Incremental Delta Apply phase. These are “Prepare inc1” and “Prepare inc2” phases as described above. --parallel option should be used along with the --apply-log-only to apply the .delta files in parallel.

We completed this essential improvement as part of [PXB-3427].

In previous versions, XtraBackup applied the .delta files as soon as a file was discovered in the incremental backup directory. Starting with versions 8.0.35-33 and 8.4.0-3, to apply the .delta files, XtraBackup scans the backup directory and builds a queue of delta files. Multiple threads (defined by --parallel ) consume this queue simultaneously. Each thread reads a .delta file and writes its pages to the corresponding InnoDB Data File (.ibd file).

Benchmarks

This benchmark is created using the scripts, and the instructions are in JIRA: PXB-3427
xtrabackup prepare performance

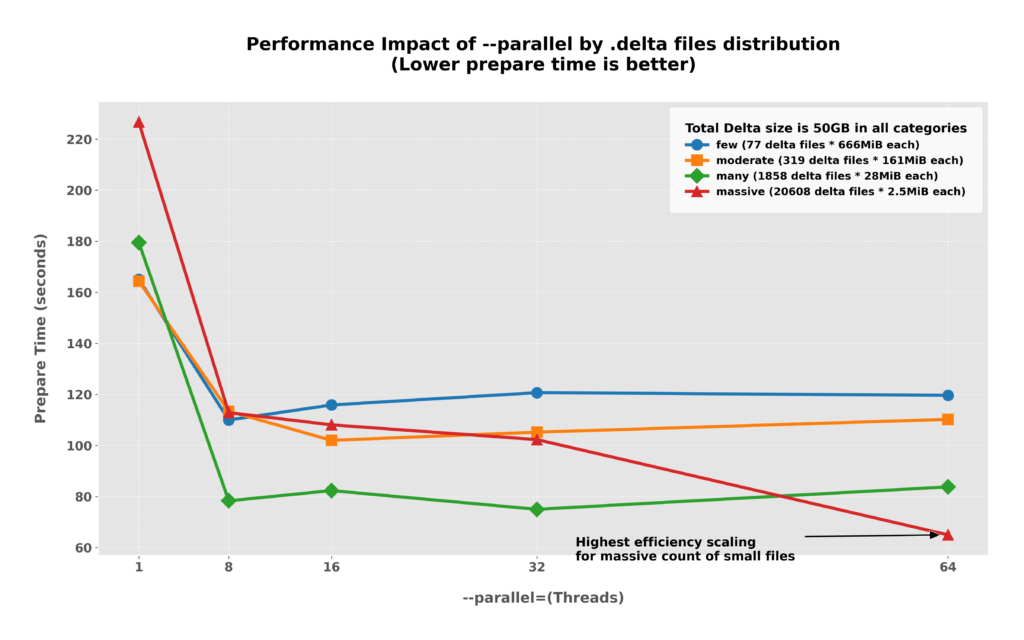
When your backup contains a large number of small .delta files, increasing the --parallel value can drastically reduce the time taken to prepare the incremental backup by distributing the high per-file overhead across more threads. However, for other categories with fewer or larger files, performance typically plateaus after 16 threads, and pushing higher can even lead to slight regressions due to thread management overhead. While there is no single “golden value” to recommend for every scenario, we recommend starting with a value of 8 to find the optimal balance for your specific environment.

Disk Utilization with XtraBackup prepare using --parallel=1 vs --parallel=64

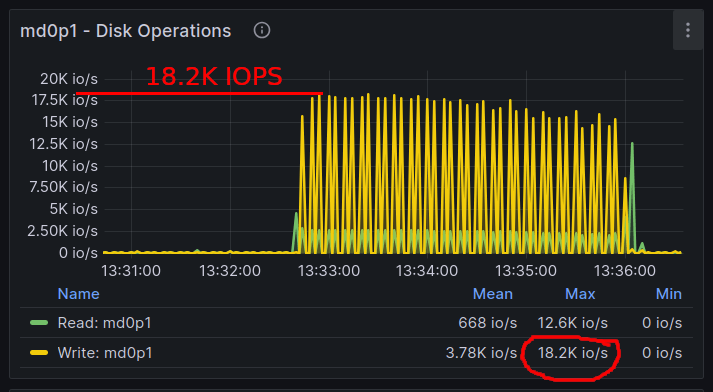
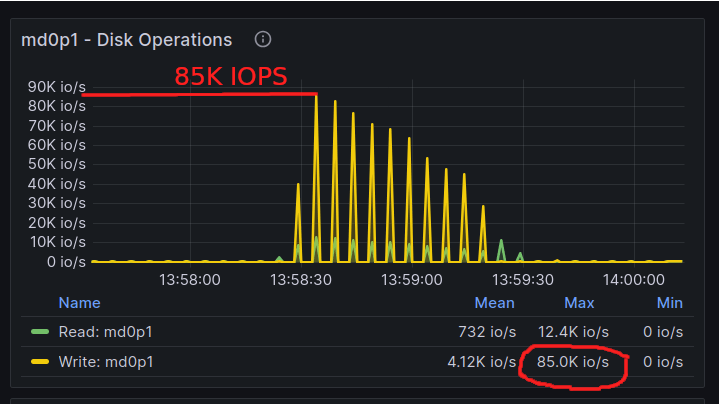
The PMM graphs below show the Disk IOPs used by the XtraBackup prepare command. The graph is generated when XtraBackup applies the incremental backup to a full backup directory. Incremental backup directory that has 20,608 .delta files, each of which is 2.5 MB.

With --parallel=1
xtrabackup incremental disk IOPs with --parllel=1

With --parallel=1, max Disk IOPs utilized is 18.2 K, and the XtraBackup prepare operation finished in 3.76 minutes.

With --parallel=64
xtrabackup incremental delta prepare performance with parallel 64


With --parallel=64, the max Disk Write IOPs utilized is 85K, and the XtraBackup prepare operation finished in around a minute. XtraBackup utilized 4.67x more disk IOPS and finished 3.49x faster.

Results from the bug reporter

We saw some amazing results shared by the reporter on PXB-3427.  The time required for XtraBackup prepare command (--prepare --apply-log-only)  to complete, reduced from 237 minutes to just 6 minutes. That’s an incredible 40X speed-up!

Here are the details from their setup:

  • Full backup: 235,188 *.ibd files
  • Incremental backup: 236,214 *.ibd.delta files
  • Average .delta size: 53,041 bytes (~53KB)
  • Threads used: 48 (–parallel=48)
  • Disk specs: 25K IOPS performance and an average of 500 to 600 MB/s of throughput

We hear you! This specific feature came to us from a post on the community forum. We reached out, asked them to create a JIRA ticket, and then implemented the improvement. We wanted to share this story as a demonstration of our commitment to listening to and acting on community feedback!

The post XtraBackup incremental prepare phase is 2x-3x faster! appeared first on Percona.

Apr
29
2026
--

XtraBackup incremental prepare phase is 2x-3x faster!

TL;DR

Percona XtraBackup is a 100% open-source backup solution for Percona Server for MySQL and MySQL®. It is designed for high-availability environments, performing online, non-blocking, and highly secure backups of transactional systems without interrupting your production traffic.

While full backups work for small databases, large-scale systems rely on incremental backups to save space and time. However, the “prepare” stage, required to make the incremental backups consistent, was slow because XtraBackup processed the .delta files serially. The .delta files are generated per table and store only the modifications since the last backup.

Great news! In XtraBackup versions 8.0.35-33 and 8.4.0-3 and later, we’ve added support for the --parallel option during the prepare stage. This option lets XtraBackup process multiple .delta files simultaneously, significantly reducing the preparation time, especially when you have a large number of IBD files.

Please add --parallel=X, with the number of threads to use, to the xtrabackup --prepare --apply-log-only command to speed up the incremental prepare operation.

The Incremental Backup Workflow

Before we dive into the performance gains, it’s important to understand how Incremental backups work.

1. Creating the Backups

The process starts with a full backup followed by a backup that captures the changes since the last backup. This smaller backup is called an incremental backup. XtraBackup creates .delta files during incremental backups. Let’s review an example.

  • Take Full Backup: Your starting point is Point A. This backup is an entire copy of your data.
  • Take Inc1 Backup: XtraBackup identifies the changes between Point A and Point B. It creates a .delta file for every table that has been changed. Delta files contain only the pages that changed between the backups.
  • Take Inc2 Backup: XtraBackup identifies the changes between Point B and Point C. It creates a new set of .delta files for this specific period.

For more detailed steps/commands, please check the documentation here: https://docs.percona.com/percona-xtrabackup/8.0/create-incremental-backup.html

2. Preparing the Backups

To restore the data to the latest point, you must merge these changes back into the full backup. The “prepare” phase works differently here:

  • Prepare Inc1: You merge the Inc1 changes into the full backup using the --apply-log-only option. In this step, XtraBackup applies the .delta files and the redo logs, but does not apply the Undo logs
  • Prepare Inc2: You merge the Inc2 changes into the updated base using the --apply-log-only option. XtraBackup applies the .delta files and the Redo logs but skips the Undo logs.
  • Final Prepare: After all the incremental backups are merged, you run a final prepare command on the full backup. This final step applies the Undo logs to make the entire dataset consistent. If you apply the Undo logs during the intermediate steps, you cannot merge any further backups.

More detailed steps to prepare an incremental backup are described here: https://docs.percona.com/percona-xtrabackup/8.0/prepare-incremental-backup.html

The Improvement: Parallel Incremental Delta Apply

We have improved the Incremental Delta Apply phase. These are “Prepare inc1” and “Prepare inc2” phases as described above. --parallel option should be used along with the --apply-log-only to apply the .delta files in parallel.

We completed this essential improvement as part of [PXB-3427].

In previous versions, XtraBackup applied the .delta files as soon as a file was discovered in the incremental backup directory. Starting with versions 8.0.35-33 and 8.4.0-3, to apply the .delta files, XtraBackup scans the backup directory and builds a queue of delta files. Multiple threads (defined by --parallel ) consume this queue simultaneously. Each thread reads a .delta file and writes its pages to the corresponding InnoDB Data File (.ibd file).

Benchmarks

This benchmark is created using the scripts, and the instructions are in JIRA: PXB-3427

xtrabackup prepare performance

When your backup contains a large number of small .delta files, increasing the --parallel value can drastically reduce the time taken to prepare the incremental backup by distributing the high per-file overhead across more threads. However, for other categories with fewer or larger files, performance typically plateaus after 16 threads, and pushing higher can even lead to slight regressions due to thread management overhead. While there is no single “golden value” to recommend for every scenario, we recommend starting with a value of 8 to find the optimal balance for your specific environment.

Disk Utilization with XtraBackup prepare using --parallel=1 vs --parallel=64

The PMM graphs below show the Disk IOPs used by the XtraBackup prepare command. The graph is generated when XtraBackup applies the incremental backup to a full backup directory. Incremental backup directory that has 20,608 .delta files, each of which is 2.5 MB.

With --parallel=1

xtrabackup incremental disk IOPs with --parllel=1

With --parallel=1, max Disk IOPs utilized is 18.2 K, and the XtraBackup prepare operation finished in 3.76 minutes.

With --parallel=64

xtrabackup incremental delta prepare performance with parallel 64


With --parallel=64, the max Disk Write IOPs utilized is 85K, and the XtraBackup prepare operation finished in around a minute. XtraBackup utilized 4.67x more disk IOPS and finished 3.49x faster.

Results from the bug reporter

We saw some amazing results shared by the reporter on PXB-3427.  The time required for XtraBackup prepare command (--prepare --apply-log-only)  to complete, reduced from 237 minutes to just 6 minutes. That’s an incredible 40X speed-up!

Here are the details from their setup:

  • Full backup: 235,188 *.ibd files
  • Incremental backup: 236,214 *.ibd.delta files
  • Average .delta size: 53,041 bytes (~53KB)
  • Threads used: 48 (–parallel=48)
  • Disk specs: 25K IOPS performance and an average of 500 to 600 MB/s of throughput

We hear you! This specific feature came to us from a post on the community forum. We reached out, asked them to create a JIRA ticket, and then implemented the improvement. We wanted to share this story as a demonstration of our commitment to listening to and acting on community feedback!

The post XtraBackup incremental prepare phase is 2x-3x faster! appeared first on Percona.

Sep
26
2023
--

The MySQL Clone Plugin Is Not Your Backup

MySQL clone plugin

This blog post discusses the limitations of the MySQL Clone plugin.

The MySQL clone plugin significantly simplifies the process of replica provisioning. All you need to do is:

  • Ensure that the source server has binary logs enabled
  • Grant appropriate permissions
  • Execute the
    CLONE INSTANCE  command on the recipient

This works extremely easily when you provision a new replica that doesn’t have any data.

Due to its simplicity, you may want to use the clone plugin instead of a backup to restore a server that survives data inconsistency or corruption. E.g., after crash.

However, if you have data on your replica, you need to consider how you will recover if the
CLONE INSTANCE  command fails with an error.

CLONE INSTANCE  command, by default, works as follows:

  • Checks prerequisites on the replica
  • Wipes out data directory
  • Copies data from the source server to the replica
  • Finalizes data on the replica

Let’s discuss these steps in detail.

Checking prerequisites on the replica

This is a safe operation that stops the clone if any of the prerequisites listed at https://dev.mysql.com/doc/refman/8.0/en/clone-plugin-remote.html#clone-remote-prerequisites are not met. Data and user settings are left intact if failure happens at this stage.

However, not every option affecting the future clone operation could be verified. Debugging options, such as
innodb_force_recovery, could cause clone operation failure at further steps, as reported in MySQL Bug 109035. Unfortunately, even if Oracle adds this option into the prerequisites check, it would not zero all risks of option incompatibility failures that could occur during the
CLONE INSTANCE  operation.

Wiping the data directory

By default, after prerequisites are checked, the clone plugin wipes out the content of the data directory. This leads to the situation when all subsequent failures during the
CLONE INSTANCE  operation will leave your server unusable.

This means that you may have to re-install the MySQL server and re-apply all clone-related settings in order to repeat the
CLONE INSTANCE operation.

To avoid the negative effect of possible failures, use clause
DATA DIRECTORY of the
CLONE INSTANCE command. It will add an extra step to the finalization step but will save you in case of failure. Note that you must have enough disk space to store your current data on the replica together with the data copied from the source server.

Copying data from the source server to the replica

This stage is the most risky because MySQL has limited control over data transfer. If something bad happens to your network while MySQL copies data, the clone operation will be stopped with an error. You need to be prepared for this, and if you decide not to use the
DATA DIRECTORY  option, be ready to re-install the replica MySQL server from scratch.

Note. Some options control data retrieval in case of network failure. So, the copy operation will be retrieved if the network is recovered within clone_donor_timeout_after_network_failure minutes. However, this option does not protect you from all possible disaster scenarios.

Finalizing data on the replica

If the clone operation completes successfully, the replica is automatically restarted. Otherwise, an error is reported.

Recovering from error if data is wiped out

After the error is reported, you need to fix the error before restarting the clone operation. If data is already wiped, you should try fixing the error without restarting the replica while your privileges are still in the memory cache. If fixing the error requires a replica restart, as in the case of mistakenly setting option
innodb_force_recovery, your only option is to re-initialize the MySQL instance on the replica from scratch as you would do for any new MySQL installation.

Recovering from error if you used option DATA DIRECTORY

In this case, just remove data in the directory specified by the option
DATA DIRECTORY, fix the error, and repeat the
CLONE INSTANCE command. In this case, you can safely restart the replica without the risk of losing your clone-related privileges and settings.

Conclusion

The MySQL clone plugin simplifies new replica provisioning but does not simplify server restore after failure unless you are ready to re-install your MySQL instance from scratch. Using the MySQL clone plugin on servers with data is not easier than using traditional backup tools, such as Percona XtraBackup.

MySQL clone plugin resources

Provisioning Replication With Clone Plugin

MySQL 8.0.17 Clone Plugin: How to Create a Slave from Scratch

The MySQL Clone Wars: Plugin vs. Percona XtraBackup

Jul
23
2015
--

The Q&A: Creating best-in-class backup solutions for your MySQL environment

Percona MySQL and MongoDB WebinarsThank you for attending my July 15 webinar, “Creating Best in Class Backup solutions for your MySQL environment.” Due to the amount of content we discussed and some minor technical difficulties faced near the end of webinar we have decided to cover the final two slides of the presentation along with the questions asked by attendees during the webinar via this blog post.

The slides are available for download. And you can watch the webinar in it’s entirety here.

The final two slides were about our tips for having a good backup and recovery strategy. Lets see the bullet points along with what would have been their explanation during the webinar :

  • Use the three types of backups
    • Binary for full restores, new slaves
      • Binary backups are easy to restore, plus takes the least amount of time to restore. The mean time to recover is mostly bound by the time to transfer backup to the appropriate target server,
    • Logical for partial restores
      • Logical backups, especially when done table-wise come in handy when you’re wanting to restore one or few smaller tables,
    • Binlog for point in time recovery
      • Very often the need is to have Point In Time Recovery, with a Full backup of any type (Logical or Binary) its half the story, we still need the DML statements processed on the server in order to bring it to the latest state, thats where Binary logs (Binlog) backups come into picture.
  • Store on more than one server and off-site
    •  Store your backups on more than one location, what if the backup server goes down ? Considering offsite storages like Amazon S3 and Glacier with weekly or monthly backups retention can be cheaper options.
  • Test your backups!!!!
    • Testing your backups is very important, its always great to know backups are recoverable and not corrupted. Spin off an EC2 instance if you want, copy and restore the backup there, roll-forward a days worth of binlogs just to be sure.
  • Document restore procedures, script them and test them!!!
    • Also when you test your backups, make sure to document the steps to restore the backup to avoid last minute hassle over which commands to use.
  • If taking from a slave run pt-table-checksum
    • Backups are mostly taken from slaves, as such make sure to checksum them regularly, you dont wanna backup inconsistent data. 
  • Configuration files, scripts
    • Data is not the only thing you should be backing up, backup your config files, scripts and user access at a secure location.
  • Do you need to backup everything all days?
    • For very large instances doing a logical backup is a toughie, in such cases evaluate your backup needs, do you want to backup all the tables ? Most of the time smaller tables are the more important ones, and needs partial restore, backup only those.
  • Hardlinking backups can save lot of disk space in some circumstances
    • There are schemas which contains only a few high activity tables, rest of them are probably updated once a week or are updated by an archiver job that runs montly, make sure to hardlink the files with the previous backup, it can save good amount of space in such scenarios.
  • Monitor your Backups
    • Lastly, monitor your backups. You do not want to realize that you’re backup had been failing the whole time. Even a simple email notification from your backup scripts can help reduce the chance of failure.

Now lets try to answer some of the questions asked during the webinar :

Q : –use-memory=2G, is that pretty standard, if we have more more, should we have a higher value?
Usually we would evaluate the value based on size of xtrabackup_logfile (amount of transactions to apply). If you have more free memory feel free to provide it to –use-memory, you dont want to let the memory be a bottleneck in the restore process.

Q : which is the best backup option for a 8Tb DB?
Usually it would depend on what type of data would you have and business requirements for the backups. For eg: a full xtrabackup and later incrementals on the weekdays would be a good idea. Time required for backups play an important role here, backing up to a slow NAS share can be time consuming, and it will make xtrabackup record lot of transactions which will further increase your restore time. Also look into backing up very important medium-small size tables via logical backups.

Q : I’m not sure if this will be covered, but if you have a 3 master-master-master cluster using haproxy, is it recommended to run the backup from the haproxy server or directly on a specific server? Would it be wise to have a 4th server which would be part of the cluster, but not read from to perform the backups?
I am assuming this a Galera cluster setup, in which case you can do backups locally on any of the node by using tools like percona xtrabackup, however the best solution would be spinning off a slave from one of the nodes and running backups there.

Q : With Mudumper, can we strem the data over SSH or netcat to another server? Or would one have to use something like NFS? I’ve used mysqldump and piped it over netcat before.. curious if we can do that with Mydumper ?
Mydumper is similar in nature with other mysql client tools. They can be run remotely (–host option). Which means you can run mydumper from another server to backup from the master or slave. Mydumper can be piped for sure too.

Q : Is Mydumper still maintained. It hasn’t had a release since March of last year?
Indeed, Max Bubenick from Percona is currently maintaining the project. Actually he has added new features to the tool which  makes it more comprehensive and feature rich. He is planning the next release soon, stay tuned for the blog post.

Q : Is MyDumper an opensource ? prepare and restore are same ?
Absolutely. Right now we need to download the source and compile, however very soon we will have packages built for it too. Prepare and Restore are common terminologies used in the backup lingo, in the webinar, Restore means copying back the backup files from its storage location to the destination location, whereas Prepare means applying the transactions to the backup and making it ready to restore.

Q : Is binlog mirroring needed on Galera (PXC)?
It is good idea to keep binlog mirroring. Even though the IST and SST will do its job to join the node, the binlogs could play a role in case you wanted to rollforward a particular schema on a slave or QA instance.

Q : As we know that Percona XtraBackup takes Full & Incremental as well. Like that Does MyDumper helps in taking the incremental backup.?
At this moment we do not have the ability to take Incremental backups with mydumper or with any other logical backup tool. However, Weekly full backups (logical) and daily binlog backups can serve as the same strategy with other Incremental backup solutions, plus they are easy to restore :)

Q : Is it possible to encrypt the output file ? What will be Best methodology to back up data with the database size of 7 to 8 Gb and increses 25 % each day ? what is difference between innobackupex and mydumper ?
Indeed its possible to encrypt the backup files, as a matter of fact, we encrypt backup files with GPG keys before uploading to offsite storage. The best method to backup a 7 to 8G instance would be implementing all 3 types of backup we discussed in the webinar, your scenarios require planning for the future, so its always best to have different solutions available as the data grows. Innobackupex is part of the Percona-Xtrabackup toolkit and is a script which does binary backups of databases, MyDumper on the other hand is a logical backup tool which creates backups as text files.

Q : How can I optimize a MySQL dump of a large database? The main bottleneck while taking MySQL dump backup of a large database is if any table is found to be corrupted then it never goes beyond by skipping this corrupted tables temporary. Can we take database backup of large database without using locking mechanism i.e. Does someone know how to make the backup without locking the tables ? Is there any tools which would faster in restoration and backup technique or how come we use MySQL dump to optimize this kind of issue in future during crash recovery.
Mysqldump is logical backup tool, and as such it executes full table scans to backup the tables and write them down in the output file, hence its very difficult to improve performance of mysqldump (query-wise). Assuming that you’re referring the corruption to MyISAM tables, it is highly recommended you repair them before backing up, also to make sure mysqldump doesnt fail due to error on such a corrupt table try using –force option to mysqldump. If you’re using MyISAM tables first recommendation would be to switch to Innodb, with most of the tables innodb locking can be greatly reduced, actually till a point where the locking is negligible, look into –single-transaction. Faster backup recovery can be achieved with binary backups, look into using Percona Xtrabackup tool, we have comprehensive documentation to get you started.

Hope this was a good webinar and we have answered most of your questions. Stay tuned for more such webinars from Percona.

The post The Q&A: Creating best-in-class backup solutions for your MySQL environment appeared first on Percona Data Performance Blog.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com