 In November 2023, Bill Gates wrote an article about how AI would change the way we interact with computers and personal devices through so-called Agents: “Agents are not only going to change how everyone interacts with computers. They’re also going to upend the software industry, bringing about the biggest revolution in computing since we went from […]
May
23
2024
23
2024
--
Beyond Cloud: The Impact of AI Agents on Platform Engineering
Aug
08
2019
08
2019
--
‘The Operators’: Experts from Airbnb and Carta on building and managing your company’s customer support
Welcome to this transcribed edition of The Operators. TechCrunch is beginning to publish podcasts from industry experts, with transcriptions available for Extra Crunch members so you can read the conversation wherever you are.
The Operators features insiders from companies like Airbnb, Brex, Docsend, Facebook, Google, Lyft, Carta, Slack, Uber, and WeWork sharing their stories and tips on how to break into fields like marketing and product management. They also share best practices for entrepreneurs on how to hire and manage experts from domains outside their own.
This week’s edition features Airbnb’s Global Product Director of Customer and Community Support Platform Products, Andy Yasutake, and Carta’s Head of Enterprise Relationship Management, Jared Thomas.
Airbnb, one of the most valuable private tech companies in the world, has millions of hosts who trust strangers (guests) to come into their homes and hundreds of millions of guests who trust strangers (hosts) to provide a roof over their head. Carta, a $1 Billion+ company formerly known as eShares, is the leading provider of cap table management and valuation software, with thousands of customers and almost a million individual shareholders as users. Customers and users entrust Carta to manage their investments, a very serious responsibility requiring trust and security.
In this episode, Andy and Jared share with Neil how companies like Airbnb, Carta, and LinkedIn think about customer service, how to get into and succeed in the field and tech generally, and how founders should think about hiring and managing the customer support. With their experiences at two of tech’s trusted companies, Airbnb and Carta, this episode is packed with broad perspectives and deep insights.
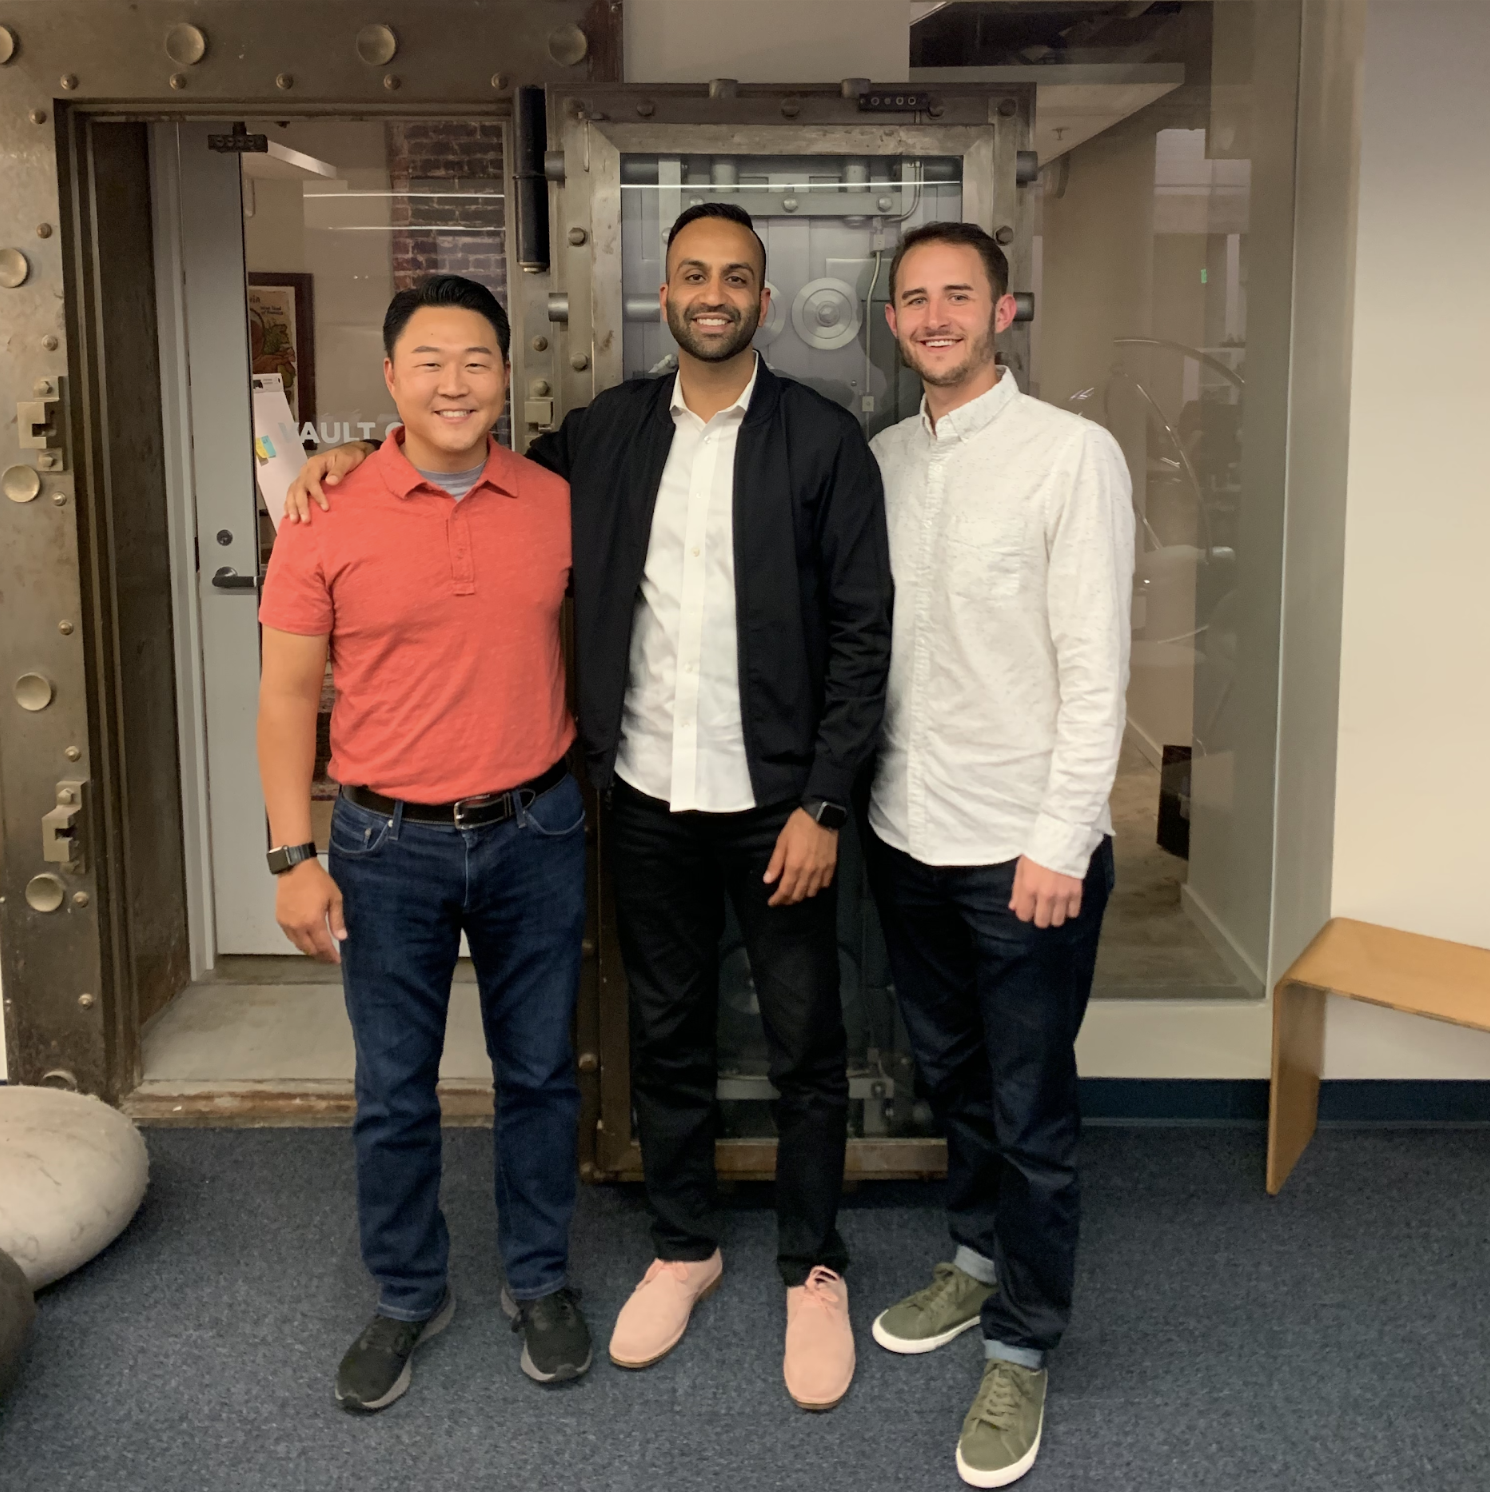
Neil Devani and Tim Hsia created The Operators after seeing and hearing too many heady, philosophical podcasts about the future of tech, and not enough attention on the practical day-to-day work that makes it all happen.
Tim is the CEO & Founder of Media Mobilize, a media company and ad network, and a Venture Partner at Digital Garage. Tim is an early-stage investor in Workflow (acquired by Apple), Lime, FabFitFun, Oh My Green, Morning Brew, Girls Night In, The Hustle, Bright Cellars, and others.
Neil is an early-stage investor based in San Francisco with a focus on companies building stuff people need, solutions to very hard problems. Companies he’s invested in include Andela, Clearbit, Kudi, Recursion Pharmaceuticals, Solugen, and Vicarious Surgical.
If you’re interested in starting or accelerating your marketing career, or how to hire and manage this function, you can’t miss this episode!
The show:
The Operators brings experts with experience at companies like Airbnb, Brex, Docsend, Facebook, Google, Lyft, Carta, Slack, Uber, WeWork, etc. to share insider tips on how to break into fields like marketing and product management. They also share best practices for entrepreneurs on how to hire and manage experts from domains outside their own.
In this episode:
In Episode 5, we’re talking about customer service. Neil interviews Andy Yasutake, Airbnb’s Global Product Director of Customer and Community Support Platform Products, and Jared Thomas, Carta’s Head of Enterprise Relationship Management.
Neil Devani: Hello and welcome to the Operators, where we talk to entrepreneurs and executives from leading technology companies like Google, Facebook, Airbnb, and Carta about how to break into a new field, how to build a successful career, and how to hire and manage talent beyond your own expertise. We skip over the lofty prognostications from venture capitalists and storytime with founders to dig into the nuts and bolts of how it all works here from the people doing the real day to day work, the people who make it all happen, the people who know what it really takes. The Operators.
Today we are talking to two experts in customer service, one with hundreds of millions of individual paying customers and the other being the industry standard for managing equity investments. I’m your host, Neil Devani, and we’re coming to you today from Digital Garage in downtown San Francisco.
Joining me is Jared Thomas, head of Enterprise Relationship Management at Carta, a $1 billion-plus company after a recent round of financing led by Andreessen Horowitz. Carta, formerly known as eShares, is the leading provider of cap table management and valuation software with thousands of customers and almost a million individual shareholders as users. Customers and users trust Carta to manage their investments, a very serious responsibility requiring trust and security.
Also joining us is Andy Yasutake, the Global Product Director of Customer and Community Support Platform Products at Airbnb, one of the most valuable private tech startups today. Airbnb has millions of hosts who are trusting strangers to come into their homes and hundreds of millions of guests who are trusting someone to provide a roof over their head. The number of cases and types of cases that Andy and his team have to think about and manage boggle the mind. Jared and Andy, thank you for joining us.
Andy Yasutake: Thank you for having us.
Jared Thomas: Thank you so much.
Devani: To start, Andy, can you share your background and how you got to where you are today?
Yasutake: Sure. I’m originally from southern California. I was born and raised in LA. I went to USC for undergrad, University of Southern California, and I actually studied psychology and information systems.
Late-90s, the dot com was going on, I’d always been kind of interested in tech, went into management consulting at interstate consulting that became Accenture, and was in consulting for over 10 years and always worked on large systems of implementation of technology projects around customers. So customer service, sales transformation, anything around CRM, as kind of a foundation, but it was always very technical, but really loved the psychology part of it, the people side.
And so I was always on multiple consulting projects and one of the consulting projects with actually here in the Bay Area. I eventually moved up here 10 years ago and joined eBay, and at eBay I was the director of product for the customer services organization as well. And was there for five years.
I left for Linkedin, so another rocket ship that was growing and was the senior director of technology solutions and operations where I had all the kind of business enabling functions as well as the technology, and now have been at Airbnb for about four months. So I’m back to kind of my, my biggest passion around products and in the customer support and community experience and customer service world.
Jul
11
2017
11
2017
--
SAP wants to bridge the gap between IoT and business data
 SAP announced a new tool today called the Leonardo IoT Bridge designed to help bridge the gap between data coming from sensors in the field and business systems operating inside a firm.
The manufacturing sector is in the middle of a massive shift where machines are being equipped with sensors that transmit torrents of data about their health, and the environment around them, over the… Read More
Dec
01
2016
01
2016
--
Database Daily Ops Series: GTID Replication and Binary Logs Purge

 This blog continues the ongoing series on daily operations and GTID replication.
In this blog, I’m going to investigate why the error below has been appearing in a special environment I’ve been working with on the last few days:
Last_IO_Errno: 1236
Last_IO_Error: Got fatal error 1236 from master when reading data from binary log:
'The slave is connecting using CHANGE MASTER TO MASTER_AUTO_POSITION = 1, but the
master has purged binary logs containing GTIDs that the slave requires.'
The error provides the right message, and explains what is going on. But sometimes, it can be a bit tricky to solve this issue: you need additional information discovered after some tests and readings. We try and keep Managed Services scripted, in the sense that our advice and best practices are repeatable and consistent. However, some additional features and practices can be added depending on the customer situation.
Some time ago one of our customer’s database servers presented the above message. At that point, we could see the binary log files in a compressed form on master (gzipped). Of course, MySQL can’t identify a compressed file with a .gz extension as a binary log. We uncompressed the file, but replication presented the same problem – even after uncompressing the file and making sure the UUID of the current master and the TRX_ID were there. Obviously, I needed to go and investigate the problem to see what was going on.
After some reading, I re-read the below:
When the server starts, the global value of gtid_purged, which was called before as gtid_lost, is initialized to the set of GTIDs contained by the Previous_gtid_log_event of the oldest binary log. When a binary log is purged, gtid_purged is re-read from the binary log that has now become the oldest one.
=> https://dev.mysql.com/doc/refman/5.6/en/replication-options-gtids.html#sysvar_gtid_purged
That makes me think: if something is compressing binlogs on the master without purging them as expected by the GTID mechanism, it’s not going to be able to re-read existing GTIDs on disk. When the slave replication threads restarts, or the DBA issues commands like reset slave and reset master (to clean out the increased GTID sets on Executed_Gtid_Set from the SHOW SLAVE STATUS command, for example), this error can occur. But if I compress the file:
- Will the slave get lost and not find all the needed GTIDs on the master after a reset slave/reset master?
- If I purge the logs correctly, using PURGE BINARY LOGS, will the slave be OK when restarting replication threads?
Test 1: Compressing the oldest binary log file on master, restarting slave threads
I would like to test this very methodically. We’ll create one GTID per binary log, and then I will compress the oldest binary log file in order to make it unavailable for the slaves. I’m working with three virtual machines, one master and two slaves. On the second slave, I’m going to run the following sequence: stop slave, reset slave, reset master, start slave, and then, check the results. Let’s see what happens.
On master (tool01):
tool01 [(none)]:> show master logs;
+-------------------+-----------+
| Log_name          | File_size |
+-------------------+-----------+
| mysqld-bin.000001 |       341 |
| mysqld-bin.000002 |       381 |
| mysqld-bin.000003 |       333 |
+-------------------+-----------+
3 rows in set (0.00 sec)
tool01 [(none)]:> show binlog events in 'mysqld-bin.000001';
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
| Log_name          | Pos | Event_type     | Server_id | End_log_pos | Info                                                              |
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
| mysqld-bin.000001 |   4 | Format_desc    |         1 |         120 | Server ver: 5.6.32-log, Binlog ver: 4                             |
| mysqld-bin.000001 | 120 | Previous_gtids |         1 |         151 |                                                                   |
| mysqld-bin.000001 | 151 | Gtid           |         1 |         199 | SET @@SESSION.GTID_NEXT= '4fbe2d57-5843-11e6-9268-0800274fb806:1' |
| mysqld-bin.000001 | 199 | Query          |         1 |         293 | create database wb01                                              |
| mysqld-bin.000001 | 293 | Rotate         |         1 |         341 | mysqld-bin.000002;pos=4                                           |
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
5 rows in set (0.00 sec)
tool01 [(none)]:> show binlog events in 'mysqld-bin.000002';
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
| Log_name          | Pos | Event_type     | Server_id | End_log_pos | Info                                                              |
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
| mysqld-bin.000002 |   4 | Format_desc    |         1 |         120 | Server ver: 5.6.32-log, Binlog ver: 4                             |
| mysqld-bin.000002 | 120 | Previous_gtids |         1 |         191 | 4fbe2d57-5843-11e6-9268-0800274fb806:1                            |
| mysqld-bin.000002 | 191 | Gtid           |         1 |         239 | SET @@SESSION.GTID_NEXT= '4fbe2d57-5843-11e6-9268-0800274fb806:2' |
| mysqld-bin.000002 | 239 | Query          |         1 |         333 | create database wb02                                              |
| mysqld-bin.000002 | 333 | Rotate         |         1 |         381 | mysqld-bin.000003;pos=4                                           |
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
5 rows in set (0.00 sec)
tool01 [(none)]:> show binlog events in 'mysqld-bin.000003';
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
| Log_name          | Pos | Event_type     | Server_id | End_log_pos | Info                                                              |
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
| mysqld-bin.000003 |   4 | Format_desc    |         1 |         120 | Server ver: 5.6.32-log, Binlog ver: 4                             |
| mysqld-bin.000003 | 120 | Previous_gtids |         1 |         191 | 4fbe2d57-5843-11e6-9268-0800274fb806:1-2                          |
| mysqld-bin.000003 | 191 | Gtid           |         1 |         239 | SET @@SESSION.GTID_NEXT= '4fbe2d57-5843-11e6-9268-0800274fb806:3' |
| mysqld-bin.000003 | 239 | Query          |         1 |         333 | create database wb03                                              |
+-------------------+-----+----------------+-----------+-------------+-------------------------------------------------------------------+
4 rows in set (0.00 sec)
Here we see that each existing binary log file has just one transaction. That will make it easier to compress the oldest binary log, and then disappear with part of the existing GTIDs. When the slave connects to a master, it will first send all the Executed_Gtid_Set, and then the master sends all the missing IDs to the slave. As Stephane Combaudon said, we will force it to happen! Slave database servers are both currently in the same position:
tool02 [(none)]:> show slave statusG
*************************** 1. row ***************************
               Slave_IO_State: Waiting for master to send event
                  Master_Host: 192.168.0.10
                  Master_User: repl
                  Master_Port: 3306
                Connect_Retry: 60
              Master_Log_File: mysqld-bin.000003
          Read_Master_Log_Pos: 333
               Relay_Log_File: mysqld-relay-bin.000006
                Relay_Log_Pos: 545
        Relay_Master_Log_File: mysqld-bin.000003
             Slave_IO_Running: Yes
            Slave_SQL_Running: Yes
            ...
           Retrieved_Gtid_Set: 4fbe2d57-5843-11e6-9268-0800274fb806:1-3
            Executed_Gtid_Set: 4fbe2d57-5843-11e6-9268-0800274fb806:1-3

tool03 [(none)]:> show slave statusG
*************************** 1. row ***************************
               Slave_IO_State: Waiting for master to send event
                  Master_Host: 192.168.0.10
                  Master_User: repl
                  Master_Port: 3306
                Connect_Retry: 60
              Master_Log_File: mysqld-bin.000003
          Read_Master_Log_Pos: 333
               Relay_Log_File: mysqld-relay-bin.000008
                Relay_Log_Pos: 451
        Relay_Master_Log_File: mysqld-bin.000003
             Slave_IO_Running: Yes
            Slave_SQL_Running: Yes
...
           Retrieved_Gtid_Set: 4fbe2d57-5843-11e6-9268-0800274fb806:1-3
            Executed_Gtid_Set: 4fbe2d57-5843-11e6-9268-0800274fb806:1-3
Now, we’ll compress the oldest binary log on master:
[root@tool01 mysql]# ls -lh | grep mysqld-bin.
-rw-rw---- 1 mysql mysql  262 Nov 11 13:55 mysqld-bin.000001.gz #: this is the file containing 4fbe2d57-5843-11e6-9268-0800274fb806:1
-rw-rw---- 1 mysql mysql  381 Nov 11 13:55 mysqld-bin.000002
-rw-rw---- 1 mysql mysql  333 Nov 11 13:55 mysqld-bin.000003
-rw-rw---- 1 mysql mysql   60 Nov 11 13:55 mysqld-bin.index
On tool03, which is the database server that will be used, we will execute the replication reload:
tool03 [(none)]:> stop slave; reset slave; reset master; start slave;
Query OK, 0 rows affected (0.01 sec)
Query OK, 0 rows affected (0.03 sec)
Query OK, 0 rows affected (0.00 sec)
Query OK, 0 rows affected (0.02 sec)
tool03 [(none)]:> show slave statusG
*************************** 1. row ***************************
               Slave_IO_State:
                  Master_Host: 192.168.0.10
                  Master_User: repl
                  Master_Port: 3306
                Connect_Retry: 60
              Master_Log_File:
          Read_Master_Log_Pos: 4
               Relay_Log_File: mysqld-relay-bin.000002
                Relay_Log_Pos: 4
        Relay_Master_Log_File:
             Slave_IO_Running: No
            Slave_SQL_Running: Yes
              Replicate_Do_DB:
          Replicate_Ignore_DB:
           Replicate_Do_Table:
       Replicate_Ignore_Table:
      Replicate_Wild_Do_Table:
  Replicate_Wild_Ignore_Table:
                   Last_Errno: 0
                   Last_Error:
                 Skip_Counter: 0
          Exec_Master_Log_Pos: 0
              Relay_Log_Space: 151
              Until_Condition: None
               Until_Log_File:
                Until_Log_Pos: 0
           Master_SSL_Allowed: No
           Master_SSL_CA_File:
           Master_SSL_CA_Path:
              Master_SSL_Cert:
            Master_SSL_Cipher:
               Master_SSL_Key:
        Seconds_Behind_Master: 0
Master_SSL_Verify_Server_Cert: No
                Last_IO_Errno: 1236
                Last_IO_Error: Got fatal error 1236 from master when reading data from binary log: 'The slave is connecting using CHANGE MASTER TO MASTER_AUTO_POSITION = 1, but the master has purged binary logs containing GTIDs that the slave requires.'
               Last_SQL_Errno: 0
               Last_SQL_Error:
  Replicate_Ignore_Server_Ids:
             Master_Server_Id: 1
                  Master_UUID: 4fbe2d57-5843-11e6-9268-0800274fb806
             Master_Info_File: /var/lib/mysql/master.info
                    SQL_Delay: 0
          SQL_Remaining_Delay: NULL
      Slave_SQL_Running_State: Slave has read all relay log; waiting for the slave I/O thread to update it
           Master_Retry_Count: 86400
                  Master_Bind:
      Last_IO_Error_Timestamp: 161111 14:47:13
     Last_SQL_Error_Timestamp:
               Master_SSL_Crl:
           Master_SSL_Crlpath:
           Retrieved_Gtid_Set:
            Executed_Gtid_Set:
                Auto_Position: 1
1 row in set (0.00 sec)
Bingo! We broke the replication streaming on the slave. Now we know that the missing GTID on the master was due to the compressed file, and wasn’t able to be passed along to the connecting slave during their negotiation. Additionally, @@GTID_PURGED was not reloaded as per what the online manual said. The test done and we confirmed the theory (if you have additional comments, enter it at the end of the blog).
Test 2: Purge the oldest file on master and reload replication on slave
Let’s make it as straightforward as possible. The purge can be done manually using the PURGE BINARY LOGS command to get it done a proper way as the binary log index file should be considered a part of this purge operation as well (it should be edited to remove the file name index entry together with the log file on disk). I’m going to execute the same as before, but include purging the file manually with the mentioned command.
tool01 [(none)]:> show master logs;
+-------------------+-----------+
| Log_name | File_size |
+-------------------+-----------+
| mysqld-bin.000001 | 341 |
| mysqld-bin.000002 | 381 |
| mysqld-bin.000003 | 333 |
+-------------------+-----------+
3 rows in set (0.00 sec)
tool01 [(none)]:> purge binary logs to 'mysqld-bin.000002';
Query OK, 0 rows affected (0.01 sec)
tool01 [(none)]:> show master logs;
+-------------------+-----------+
| Log_name | File_size |
+-------------------+-----------+
| mysqld-bin.000002 | 381 |
| mysqld-bin.000003 | 333 |
+-------------------+-----------+
2 rows in set (0.00 sec)
Now, we’ll execute the commands to check how it goes:
tool03 [(none)]:> stop slave; reset slave; reset master; start slave;
Query OK, 0 rows affected (0.00 sec)
Query OK, 0 rows affected (0.02 sec)
Query OK, 0 rows affected (0.00 sec)
Query OK, 0 rows affected (0.02 sec)
tool03 [(none)]:> show slave statusG
*************************** 1. row ***************************
               Slave_IO_State:
                  Master_Host: 192.168.0.10
                  Master_User: repl
                  Master_Port: 3306
                Connect_Retry: 60
              Master_Log_File:
          Read_Master_Log_Pos: 4
               Relay_Log_File: mysqld-relay-bin.000002
                Relay_Log_Pos: 4
        Relay_Master_Log_File:
             Slave_IO_Running: No
            Slave_SQL_Running: Yes
              Replicate_Do_DB:
          Replicate_Ignore_DB:
           Replicate_Do_Table:
       Replicate_Ignore_Table:
      Replicate_Wild_Do_Table:
  Replicate_Wild_Ignore_Table:
                   Last_Errno: 0
                   Last_Error:
                 Skip_Counter: 0
          Exec_Master_Log_Pos: 0
              Relay_Log_Space: 151
              Until_Condition: None
               Until_Log_File:
                Until_Log_Pos: 0
           Master_SSL_Allowed: No
           Master_SSL_CA_File:
           Master_SSL_CA_Path:
              Master_SSL_Cert:
            Master_SSL_Cipher:
               Master_SSL_Key:
        Seconds_Behind_Master: 0
Master_SSL_Verify_Server_Cert: No
                Last_IO_Errno: 1236
                Last_IO_Error: Got fatal error 1236 from master when reading data from binary log: 'The slave is connecting using CHANGE MASTER TO MASTER_AUTO_POSITION = 1, but the master has purged binary logs containing GTIDs that the slave requires.'
               Last_SQL_Errno: 0
               Last_SQL_Error:
  Replicate_Ignore_Server_Ids:
             Master_Server_Id: 1
                  Master_UUID: 4fbe2d57-5843-11e6-9268-0800274fb806
             Master_Info_File: /var/lib/mysql/master.info
                    SQL_Delay: 0
          SQL_Remaining_Delay: NULL
      Slave_SQL_Running_State: Slave has read all relay log; waiting for the slave I/O thread to update it
           Master_Retry_Count: 86400
                  Master_Bind:
      Last_IO_Error_Timestamp: 161111 16:35:02
     Last_SQL_Error_Timestamp:
               Master_SSL_Crl:
           Master_SSL_Crlpath:
           Retrieved_Gtid_Set:
            Executed_Gtid_Set:
                Auto_Position: 1
1 row in set (0.00 sec)
The GTID on the purged file is needed by the slave. In both cases, we can set the @@GTID_PURGED as below with the transaction that we know was purged, and move forward with replication:
tool03 [(none)]:> stop slave; set global gtid_purged='4fbe2d57-5843-11e6-9268-0800274fb806:1';
Query OK, 0 rows affected, 1 warning (0.00 sec)
Query OK, 0 rows affected (0.01 sec)
tool03 [(none)]:> start slave;
Query OK, 0 rows affected (0.01 sec)
The above adjusts the GTID on @@GTID_PURGED to just request the existing GTIDs, using the oldest existing GTID minus one to make the slave start the replication from the oldest existing GTID. In our scenario above, the replica restarts replication from 4fbe2d57-5843-11e6-9268-0800274fb806:2, which lives on binary log file mysqld-bin.000002. Replication is fixed, as its threads can restart processing the data streaming coming from master.
You will need to execute additional steps in checksum and sync for the set of transactions that were jumped when setting a new value for @@GTID_PURGED. If replication continues to break after restarting, I advise you rebuild the slave (possibly the subject of future blog).
Good explanations about this can be found on the below bug, reported by the Facebook guys and Laurynas Biveinis, the Percona Server Lead (who clarified the issue):
- MySQL Bugs: #72635: Data inconsistencies when master has truncated binary log with GTID after crash;
- MySQL Bugs: #73032: Setting gtid_purged may break auto_position and thus slaves;
Conclusion
Be careful when purging or doing something manually with binary logs, because @@GTID_PURGED needs to be automatically updated when binary logs are purged. It seems to happen only when
expire_logs_days
is set to purge binary logs. Yet you need to be careful when trusting this variable, because it doesn’t consider fraction of days, depending the number of writes on a database server, it can get disks full in minutes. This blog showed that even housekeeping scripts and the PURGER BINARY LOGS command were able to make it happen.
Apr
19
2016
19
2016
--
Capital One open sources Cloud Custodian AWS resource management tool
 Capital One is a huge organization with lots of compliance issues related to being a financial services company. It also happens to be an Amazon Web Services customer and it needed a tool to set rules and policies in an efficient way around AWS usage. Last July it started developing the tool that would become Cloud Custodian; today it announced at an AWS event in Chicago that it was making… Read More