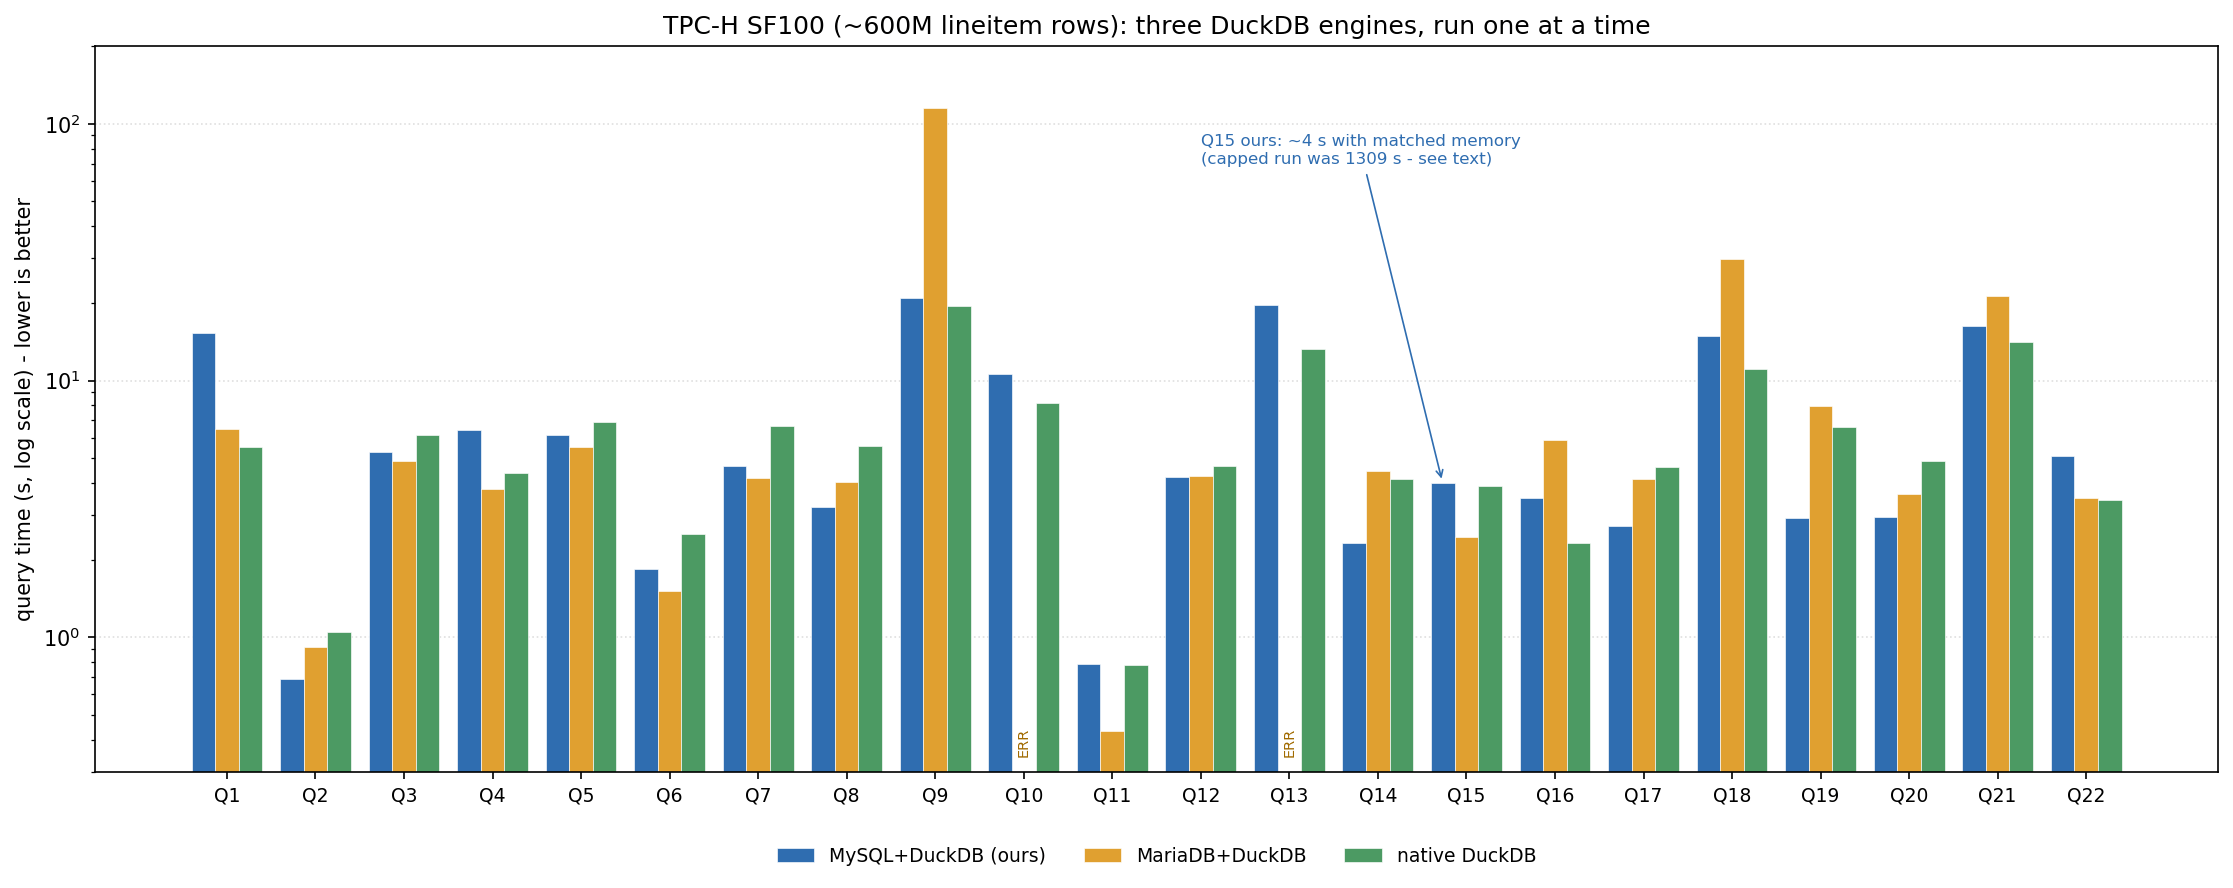Sep
02
2026
--

OpenID Connect Authentication for MySQL, Now Fully Open Source

Percona Server for MySQL now ships with a fully open source OpenID Connect (OIDC) authentication plugin, available starting with Percona Server for MySQL 8.4.11-11 and 9.7.2-2 (not yet released as of this writing). It allows a MySQL account to authenticate against any standards-compliant Identity Provider (IdP) instead of relying on a locally stored password, closing the gap with MySQL Enterprise Edition, which has offered OIDC authentication since MySQL 9.1 and, in several respects, going beyond it.

Oracle offers the same category of functionality, but its server-side plugin is part of the paid MySQL Enterprise Edition. Percona’s implementation is open source and adds three capabilities the Enterprise plugin does not provide: automatic signing-key synchronization from a JWKS endpoint, IdP group-to-role mapping, and proxy-user support. This article explains how the plugin works and why those differences matter in practice.

What OpenID Connect Brings to MySQL Authentication

OpenID Connect is an identity layer built on top of the OAuth 2.0 authorization framework [5]. Whereas OAuth 2.0 governs delegated access to resources, OIDC adds a standardized way for a client to establish who a user is. After a user signs in to an Identity Provider, the IdP issues a signed JSON Web Token (JWT), called an ID token, that carries the user’s identity and attributes in a verifiable, tamper-evident form.

Using that model for MySQL authentication brings several practical advantages over password-based accounts:

  • Alignment with single sign-on. Users authenticate once with their IdP and can reuse that session context across OIDC-aware applications, including databases. User lifecycle and password management remain centralized.
  • No long-lived secrets on the wire. ID tokens are short-lived and cryptographically signed, so there is no static password to steal, rotate, or accidentally commit to a configuration file.
  • Support for hybrid deployments. Organizations that run MySQL on-premises while hosting applications in the cloud can still authenticate through the same identity plane on both sides.
  • Broad interoperability. Because OpenID Connect is a widely adopted standard, the plugin can work with any compliant provider, including Keycloak, Okta, Microsoft Entra ID, and Google Identity.

None of that is unique to Percona; Oracle makes a similar value proposition for the Enterprise plugin. The real difference lies in how much operational burden the plugin removes from the administrator, which becomes clear in the next sections.

How OpenID Connect Authentication Works
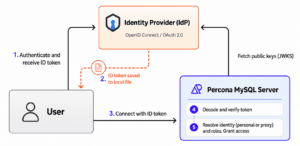
Once the plugin and its configuration are in place, the authentication path is the same regardless of which IdP issued the token:

  1. The user authenticates to the IdP and receives a signed ID token.
  2. The token is written to a local file that only the client operating system account can read.
  3. The MySQL client uses an option that causes the client-side OIDC plugin to load and read the token from the file. The token is sent to the server as part of the authentication handshake.
  4. The server validates the secure channel and decodes the token. It then verifies the token signature using the selected IdP’s public key, checks the expiration time, and validates the configured claims.
  5. The server resolves the final identity as either a personal account or a group-based proxy target. The plugin may also return roles mapped from the user’s group membership.

Configuring Trusted Providers and Letting the Plugin Manage the Keys

Identity Providers rotate their signing keys periodically as a basic security measure. If a key is ever compromised, limiting its lifetime reduces the potential impact, and regular rotation also lowers the long-term value of any one key as a target. In practice, rotation is gradual: a new key is published and accepted before it starts signing tokens, and an old key remains valid for a period after it stops signing so that tokens already in flight can still be verified.

Public keys are exposed through the standard JWKS (JSON Web Key Set) endpoint, which applications can use to verify tokens issued by the IdP [6].

The Percona OpenID Connect authentication plugin can download public keys from a configured JWKS endpoint when the plugin is loaded, typically during installation and server startup, and store them in a cache. It also provides a User Defined Function (UDF) that can refresh the cache on demand or periodically through the Event Scheduler.

By contrast, Oracle’s counterpart plugin requires signing keys to be configured statically through the authentication_openid_connect_configuration server variable, supplied either as an inline JSON string or as a path to a JSON file. There is no retrieval or refresh from the JWKS endpoint, so keeping keys current after each rotation remains a manual task for the administrator. In the window just after a rotation, tokens signed with the previous key are still valid but cannot be verified until the configuration is updated. Percona’s plugin supports static key configuration as well, but that mode is better suited to testing or temporary setups than to production.

Example

Using the feature requires two simple steps. First, JWKS endpoint URL must be set in the plugin’s configuration. For example, the below configuration defines IdP named as example-keycloak (pay attention to jwks-url element):

{
  "example-keycloak": {
  "issuer-name": "https://keycloak.example.com/realms/master",
  "jwks-url": "https://keycloak.example.com/realms/master/protocol/openid-connect/certs",
  "audiences": [ "mysql-oidc" ]
  }
}

The second step is ensuring the MySQL event scheduler is running and creating an event updating the keys. For example, to enable updating the keys for example-keycloak every hour run from MySQL client:

CREATE EVENT update_oidc_keys
  ON SCHEDULE EVERY 1 HOUR
  DO SELECT update_jwks("example-keycloak");

Benefits of Using IdP Groups

This is where Percona’s plugin diverges most clearly from the Enterprise implementation.

Groups are managed by the corporate Identity Provider and group membership may be carried by ID tokens. OIDC does not define a standard claim for that, but most IdP implementations allow adding a group claim to the tokens. The Percona’s plugin allows the administrator to configure the group claim name so that it matches the token format used by the chosen IdP.

There are two practical ways to take advantage of this feature:  group-to-role mapping and proxy users.

Group-to-Role Mapping

Membership in a group can automatically translate into MySQL roles and therefore privileges across multiple MySQL servers at the same time. On a single server, the flow looks like this:

  1. The administrator creates roles and grants them privileges.
  2. The administrator defines the IdP group-to-MySQL role mapping in the plugin configuration file.
  3. When the user connects, the plugin returns the roles that match the user’s groups, and the server automatically grants those roles to the user.
  4. The user can activate any granted role and exercise the privileges assigned to it.

Please note, that group-to-role mapping still requires an account created for each user, but automates managing user privileges.

Example

To create roles and grant them some privileges one may run:

CREATE ROLE accounting;
GRANT ALL PRIVILEGES ON accounting_database.* TO accounting;
CREATE ROLE sales;
GRANT ALL PRIVILEGES ON sales_database.* TO sales;

Then, to to define the mapping add to IDP configuration:

"group-claim": "groups",
"group-role": [
  { "/accounting": "accounting" },
  { "/marketing": "marketing" }
]

Any user connecting with an ID token containing claim “groups”:[“/accounting”] will be granted with role accounting and effectively obtain access to accounting_database and so on.

Proxy Users

The proxy capability in MySQL allows an authentication plugin to request that the connecting external user be logged in as a different MySQL user. In this model, the external identity is the proxy user and the mapped MySQL account is the proxied user. The purpose is to let multiple users share accounts with the same privilege set, avoiding the need to create a separate personal database account for every individual.

This feature must be supported by the authentication plugin, whose job is to choose the proxied user according to the specifics of the authentication method. In the Percona OIDC plugin, that selection is based on the group claim in the token and works as follows:

  1. The administrator creates a proxy user identified by the OIDC plugin. This can be either a single anonymous account (”@”) without a specific group name, referred to as anonymous proxying, or multiple group-related accounts, referred to as named group proxying.
  2. The administrator creates proxied users for each group. These accounts should not use a login plugin, so nobody can connect to them directly. The username must match the group name.
  3. The administrator grants the PROXY privilege for each proxy user on all related proxied users.
  4. When a user connects, in the anonymous proxying case the plugin returns the user’s first group as the proxied username. In the named group proxying case, the plugin checks whether the user belongs to the group and returns that group as the proxied username.
  5. The server verifies that the requested proxied account exists and that the proxy user has the required PROXY privilege on it. If both checks succeed, the session runs with the proxied account’s privileges.

Other Features

Supported signing algorithms include RSASSA-PKCS1-v1_5, RSASSA-PSS, and ECDSA with SHA-256, SHA-384, and SHA-512 hashing functions.

The Percona approach uses the client-side OpenID Connect plugin from upstream MySQL, which ensures compatibility with the standard Oracle client.

Both client-side and server-side OpenID Connect plugins ensure that the token is sent via a secure channel. Accepted protocols are TCP protected by TLS, Unix sockets, and shared memory.

What OpenID Connect Authentication Does Not Do

There are some limits worth knowing.

The first comes from MySQL’s authentication design: any authentication plugin is used at connection time only. In the case of OIDC, the token is validated when the user connects, and a session that stays open may outlive the ID token that opened it. There is no out-of-the-box mechanism to force re-authentication after some time (except for idle connection timeout).

A similar situation applies to group-role mapping. The roles tied to the user’s groups in the ID token are granted or revoked at connection time. As a result, if a user is added to or removed from an IdP group, they must reconnect to Percona Server for the change to be reflected in their granted roles.

The proxying mechanism uses group membership claim instead of the token’s subject, so any token signed by a configured IdP that carries the required group is accepted. Group membership is your trust boundary in those modes, so treat it that way.

The current proxying implementation assumes the proxied user’s name matches the group name. This can be a problem when a group name isn’t a valid MySQL username (for example, it’s too long or contains disallowed characters), or when multiple groups need to map to a single account. We plan to add group-to-proxied-account mapping in future releases to address this.

The client-side plugin doesn’t verify the ID token (for example, check whether it has expired) before connecting, and the server doesn’t report the reason for access being denied (for security reasons). A good practice is to obtain a fresh token before connecting.

Conclusion

Functionally, Percona’s OpenID Connect plugin covers the same core ground as the counterpart in MySQL Enterprise Edition: signed ID tokens, claim validation, subject matching, and secure-transport enforcement.

It goes further in several important areas:

  • It is open source.
  • Keys can stay current automatically through JWKS synchronization.
  • Group-to-role mapping allows IdP group membership to drive MySQL role grants for the lifetime of the session.
  • Proxy-user support allows many IdP identities to share a smaller set of MySQL accounts.

Our OIDC implementation is suitable for real-world identity operations at scale. It can automatically map identities and groups managed by an IdP to database users and roles, and synchronize cryptographic keys.

References

  1. Percona Server for MySQL documentation: OpenID Connect authentication.
  2. Percona Server for MySQL documentation: Get started with OpenID Connect authentication.
  3. MySQL 9.7 Reference Manual: OpenID Connect Pluggable Authentication.
  4. MySQL 9.7 Reference Manual: Proxy Users.
  5. OpenID Foundation: How OpenID Connect Works
  6. auth0 Docs: JSON Web Key Sets.

Written by Michal Jankowski. Reviewed by Dennis Kittrell and Oleksiy Lukin.
Percona® is a registered trademark of Percona LLC. MySQL® is a registered trademark of Oracle Corporation.

The post OpenID Connect Authentication for MySQL, Now Fully Open Source appeared first on Percona.
Aug
07
2026
--

The DuckDB MySQL engine at 500 GB

We ran DuckDB MySQL storage engine at scale factor 500. It is around 500 GB of raw TPC-H, three billion lineitem rows  on an 80-core server with 187 GB of RAM. Three engines on the same box: InnoDB, our MySQL+DuckDB engine, and plain DuckDB as the reference.

Here is what came out. InnoDB finished 18 of the 22 queries and spent more than 28 hours of query time on them. Four never finished. Our engine ran all 22 in about three minutes. It loaded the data 25 times faster than InnoDB, and it used 5 times less disk. On the queries it stays close to plain DuckDB, and on a few it is ahead.

It’s still an experiment, not production software. Code and the benchmark harness are on GitHub under GPLv2: https://github.com/Percona-Lab/ducksdb-mysql-engine.

The machine, and how we ran it

  • One server, 80 cores, 187.5 GB RAM.
  • SF500: about 500 GB of raw CSV, 3,000,028,242 lineitem rows.
  • Three engines, one at a time: InnoDB, our engine, native DuckDB.
  • All of it through the harness in the repo (bench/tb), in Docker.

Two details about how we ran it change how the numbers read.

The load streams. We generate a chunk of CSV, load it, delete it, then generate the next one. So the disk never holds more than one 20 GB chunk, which is the only reason 500 GB fits on the box at all.

And “native DuckDB” is not a second copy of the data. It opens the engine’s own DuckDB file read-only and queries that. Same bytes on both sides. That keeps the comparison honest, and it means there is no separate native load time to report.

Loading the data

Engine Load time
ENGINE=DuckDB (COPY fast path) 36m 05s
InnoDB (bulk LOAD DATA) 15h 21m

InnoDB took 25.5 times longer. The engine hands LOAD DATA straight to a DuckDB COPY instead of going row by row through the handler, so the three billion lineitem rows go in in about nineteen minutes, and the whole set in thirty-six. InnoDB inserts row by row and builds the primary key as it goes. That is where the rest of the fifteen hours goes.

Storage on disk

Component Size vs raw CSV
raw TPC-H CSV 500.0 GB 100%
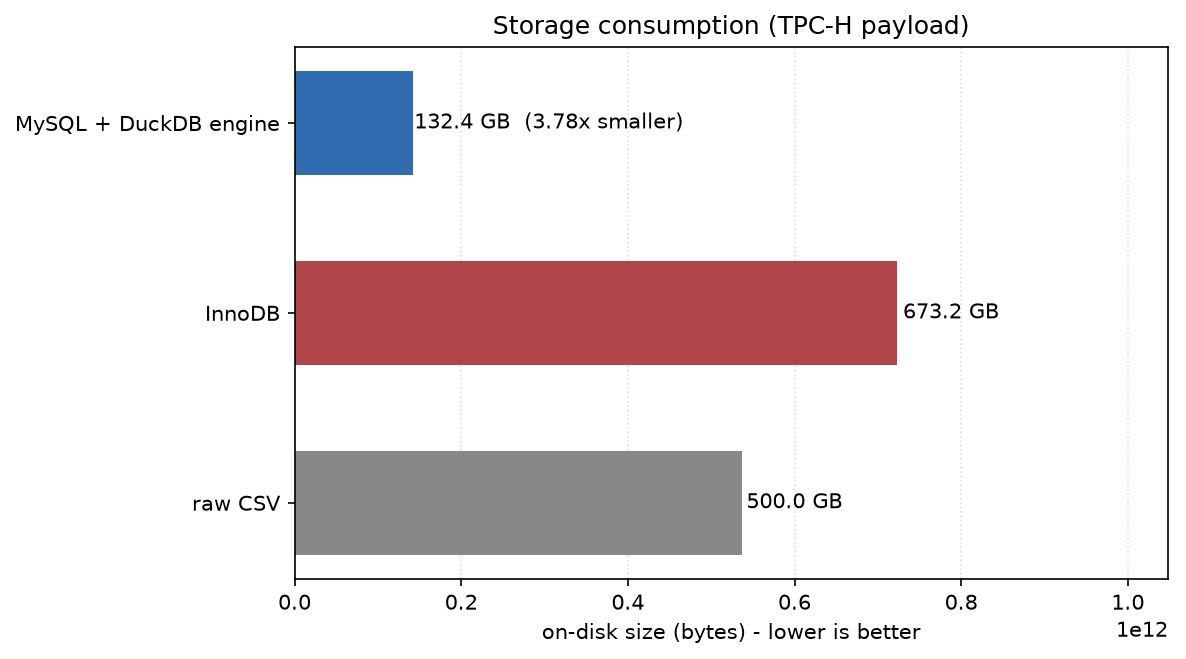
ENGINE=DuckDB (tpch.duckdb) 132.4 GB 26% (3.78x smaller)
InnoDB (tpch/*.ibd) 673.2 GB 135%

DuckDB stores columns and compresses them, so 500 GB of CSV comes down to 132 GB. InnoDB stores rows and carries the index with them, and it ends up bigger than the CSV it came from: 673 GB, five times the DuckDB file. The InnoDB lineitem.ibd on its own is 446 GB. That is more than three times our entire database.

Storage, lower is better. The DuckDB engine holds all of SF500 in 132 GB.

Query time

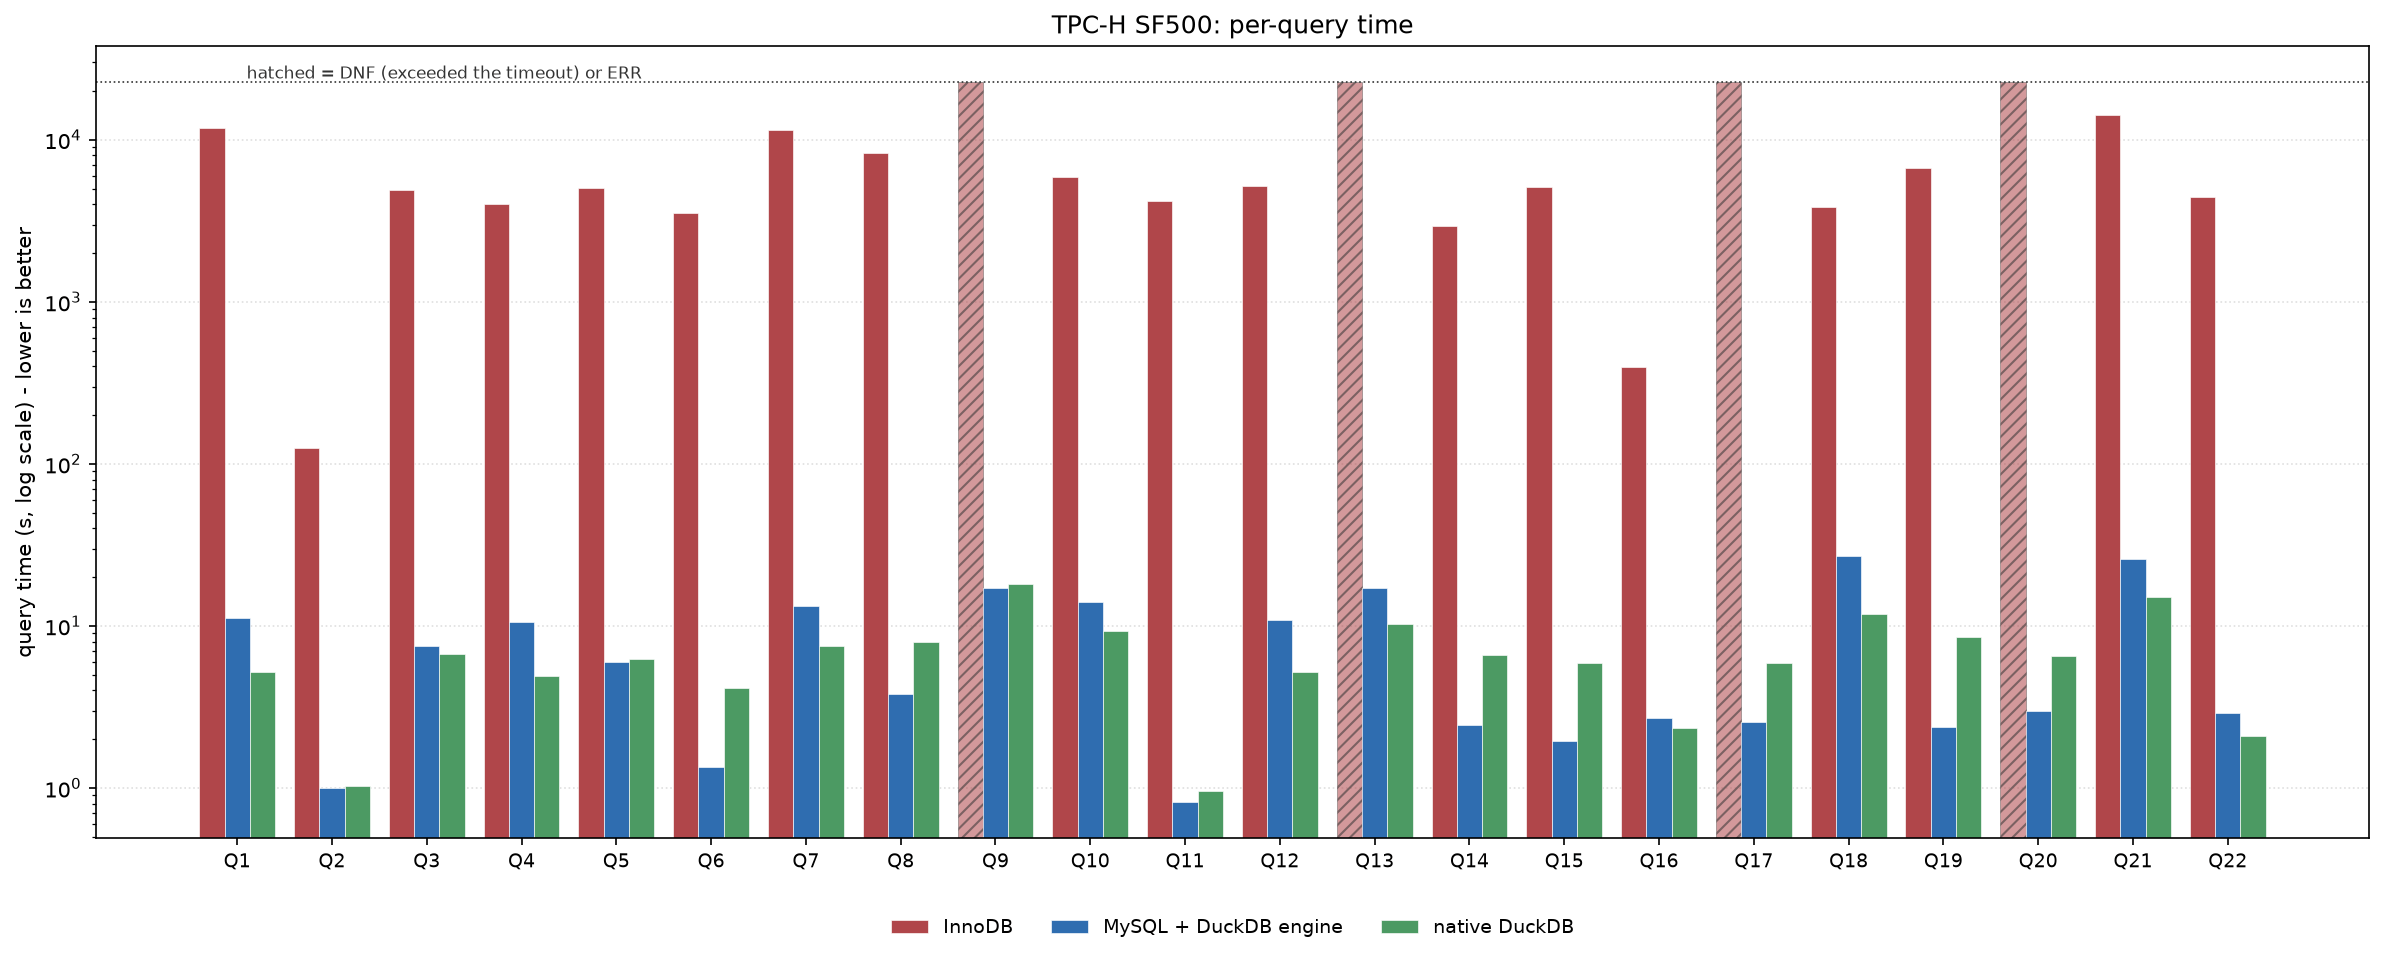
All 22 queries. Warm runs, minimum of a few, in seconds. InnoDB had a two-hour cap per query; the ones that hit it are marked DNF.


Query InnoDB MySQL+DuckDB (ours) native DuckDB
Q1 11864.5 11.1 5.2
Q6 3539.4 1.3 4.1
Q9 DNF 17.1 18.1
Q13 DNF 17.1 10.4
Q18 3846.1 27.0 11.9
Q19 6672.3 2.4 8.6
Q21 14211.7 26.0 15.1
All 22 18/22 finished, ~28 h 185.6 s 152.7 s

SF500, all 22 queries, log scale, lower is better. Hatched InnoDB bars did not finish inside the cap.

Two things to take from this.

InnoDB is far behind, which is no surprise. Scanning three billion rows for a wide GROUP BY or a six-way join is the wrong job for a row store. Four queries (Q9, Q13, Q17, Q20) did not finish at all, and the eighteen that did add up to more than 28 hours. This is the exact problem the engine is for. It is not a mark against InnoDB, which is doing the transactional job it was built for.

The comparison worth reading is our engine against plain DuckDB, since both are the same DuckDB reading the same file. Over all 22 they are close: 186 seconds for ours, 153 for native. Query by query it goes both ways. On the selective ones ours is often faster — Q6 (1.3 vs 4.1), Q19 (2.4 vs 8.6), Q17, Q20. On the biggest joins native wins — Q18 (27 vs 12), Q21, Q1. That gap comes from settings, not data: the memory limit, the thread count, and running inside mysqld versus a bare CLI. Either way, both are around a thousand times faster than the row store.

Correctness

We checked the answers, not only the clock. For every query we compared our engine’s output to native DuckDB’s, numbers rounded to four decimals and the order ignored. 21 of 22 matched exactly. None mismatched. One was skipped because a result file came back empty on one side. So the engine gives the same answers as plain DuckDB.

What this means, and where it stops

At 500 GB the small-scale picture holds and gets sharper. Analytical queries that took hours on InnoDB, or never finished, come back in seconds on the DuckDB engine. The load is far quicker, and the footprint is far smaller. All of it inside one MySQL server, with the tables queried the normal way.

The limits are the same as before:

  • It is for analytics, not OLTP. Point lookups and single-row work stay on the row path, where an index seek is the right tool.
  • DuckDB runs inside mysqld, so a heavy query under a tight memory limit can go over budget. DUCKSDB_MEMORY_LIMIT and DUCKSDB_TEMP_DIR let it spill to disk instead of failing. We set a limit here so the big CTEs spill rather than get OOM-killed.
  • Some queries still fall back to normal MySQL and run on the row path.
  • It is one workload on one machine. The result is strong, but the engine is still an experiment, not something for production traffic.

Try it

Pull the image and run your own queries:

docker run -d -p 3306:3306 -e MYSQL_ROOT_PASSWORD=secret \
  perconalab/ducksdb-mysql-engine:latest

The engine, the patches, and the harness that produced these numbers are on GitHub: https://github.com/Percona-Lab/ducksdb-mysql-engine. The per-query numbers and the method are in the repo. If it breaks, or your hardware gives different numbers, open an issue.

The post The DuckDB MySQL engine at 500 GB appeared first on Percona.

Jul
24
2026
--

Alert on CVEs in Your Percona Tools for MongoDB on Day One

TL;DR: Starting with PBM 2.15.0 and PCSM 0.9.0, every release artifact – binary tarballs, RPM and DEB packages, and Docker images – ships a CycloneDX 1.6 Software Bill of Materials in JSON. Scan it with Trivy, Grype, or any CycloneDX-compatible tool. For Docker images, the fastest path is a Trivy image –sbom-sources oci <image>. There is nothing to enable, as the SBOM is already a part of the artifact you were going to download.

If you run Percona Backup for MongoDB (PBM) or Percona ClusterSync for MongoDB (PCSM), both part of the Percona Software for MongoDB family, you can now answer one of the stressful questions in operations: “Is my database tooling affected by this CVE?” in seconds instead of days. And when a customer or auditor asks for a parts list of what you deployed, you can hand it over as a single file instead of starting a multi-day investigation.

That parts list is a Software Bill of Materials (SBOM), and starting with PBM 2.15.0 and PCSM 0.9.0, it comes along in every channel we publish – tarballs, RPM and DEB packages, and Docker images. This post shows what is in it, where to find it, and three ways to scan it.

The problem: you can’t patch what you can’t see

Most MongoDB operators run database tooling assembled by someone else – official RPMs, official containers, official tarballs. When something goes wrong upstream, the first question is always the same: what is actually inside this artifact, and is any of it affected?

Two incidents made that question a board-level concern, and a third made it personal for MongoDB teams. Log4Shell in late 2021 forced thousands of teams to manually audit Java dependencies they did not know they had. The xz-utils backdoor disclosed in early 2024 hid in a compression library buried deep inside Linux base images. Then, in December 2025, MongoBleed (CVE-2025-14847) forced MongoDB teams to urgently identify which server and tooling versions were actually deployed. In every case, teams that already had an SBOM per artifact answered “are we affected?” in minutes; teams that did not took days.

The other version of the problem is that the SBOM is something someone else asks of you – a customer running a security review, an auditor checking EU Cyber Resilience Act or US Executive Order 14028 compliance, or a procurement team working through a vendor questionnaire. Without one, every such request turns into a discovery project.

What Percona Backup for MongoDB and ClusterSync now ship

An SBOM is a machine-readable inventory of every component, library, and OS package inside a built artifact, with versions, licenses, and dependency relationships. Think of it as a packing slip for a software shipment, except a computer can parse it, search it, and cross-reference it against vulnerability databases.

Plenty of vendors now ship SBOMs. What matters is whether the SBOM is actually usable, and PBM and PCSM cover the three things that decide that. The format is CycloneDX 1.6, an OWASP-backed JSON standard that every major tool reads: Trivy, Grype, Snyk, and Dependency-Track. The files are generated with Syft from the actual built binary and the staged file tree, so the inventory reflects what was really packaged, not what the source tree implies. And the SBOM ships in every distribution channel, not just one:

Distribution channel SBOM location
Binary tarball <product>-<version>.cdx.json at the root of the archive
RPM package /usr/share/doc/<product>/<product>-<version>.cdx.json
DEB package /usr/share/doc/<product>/<product>-<version>.cdx.json
Docker image Two SBOMs ship side by side — see below

Docker images carry two SBOMs

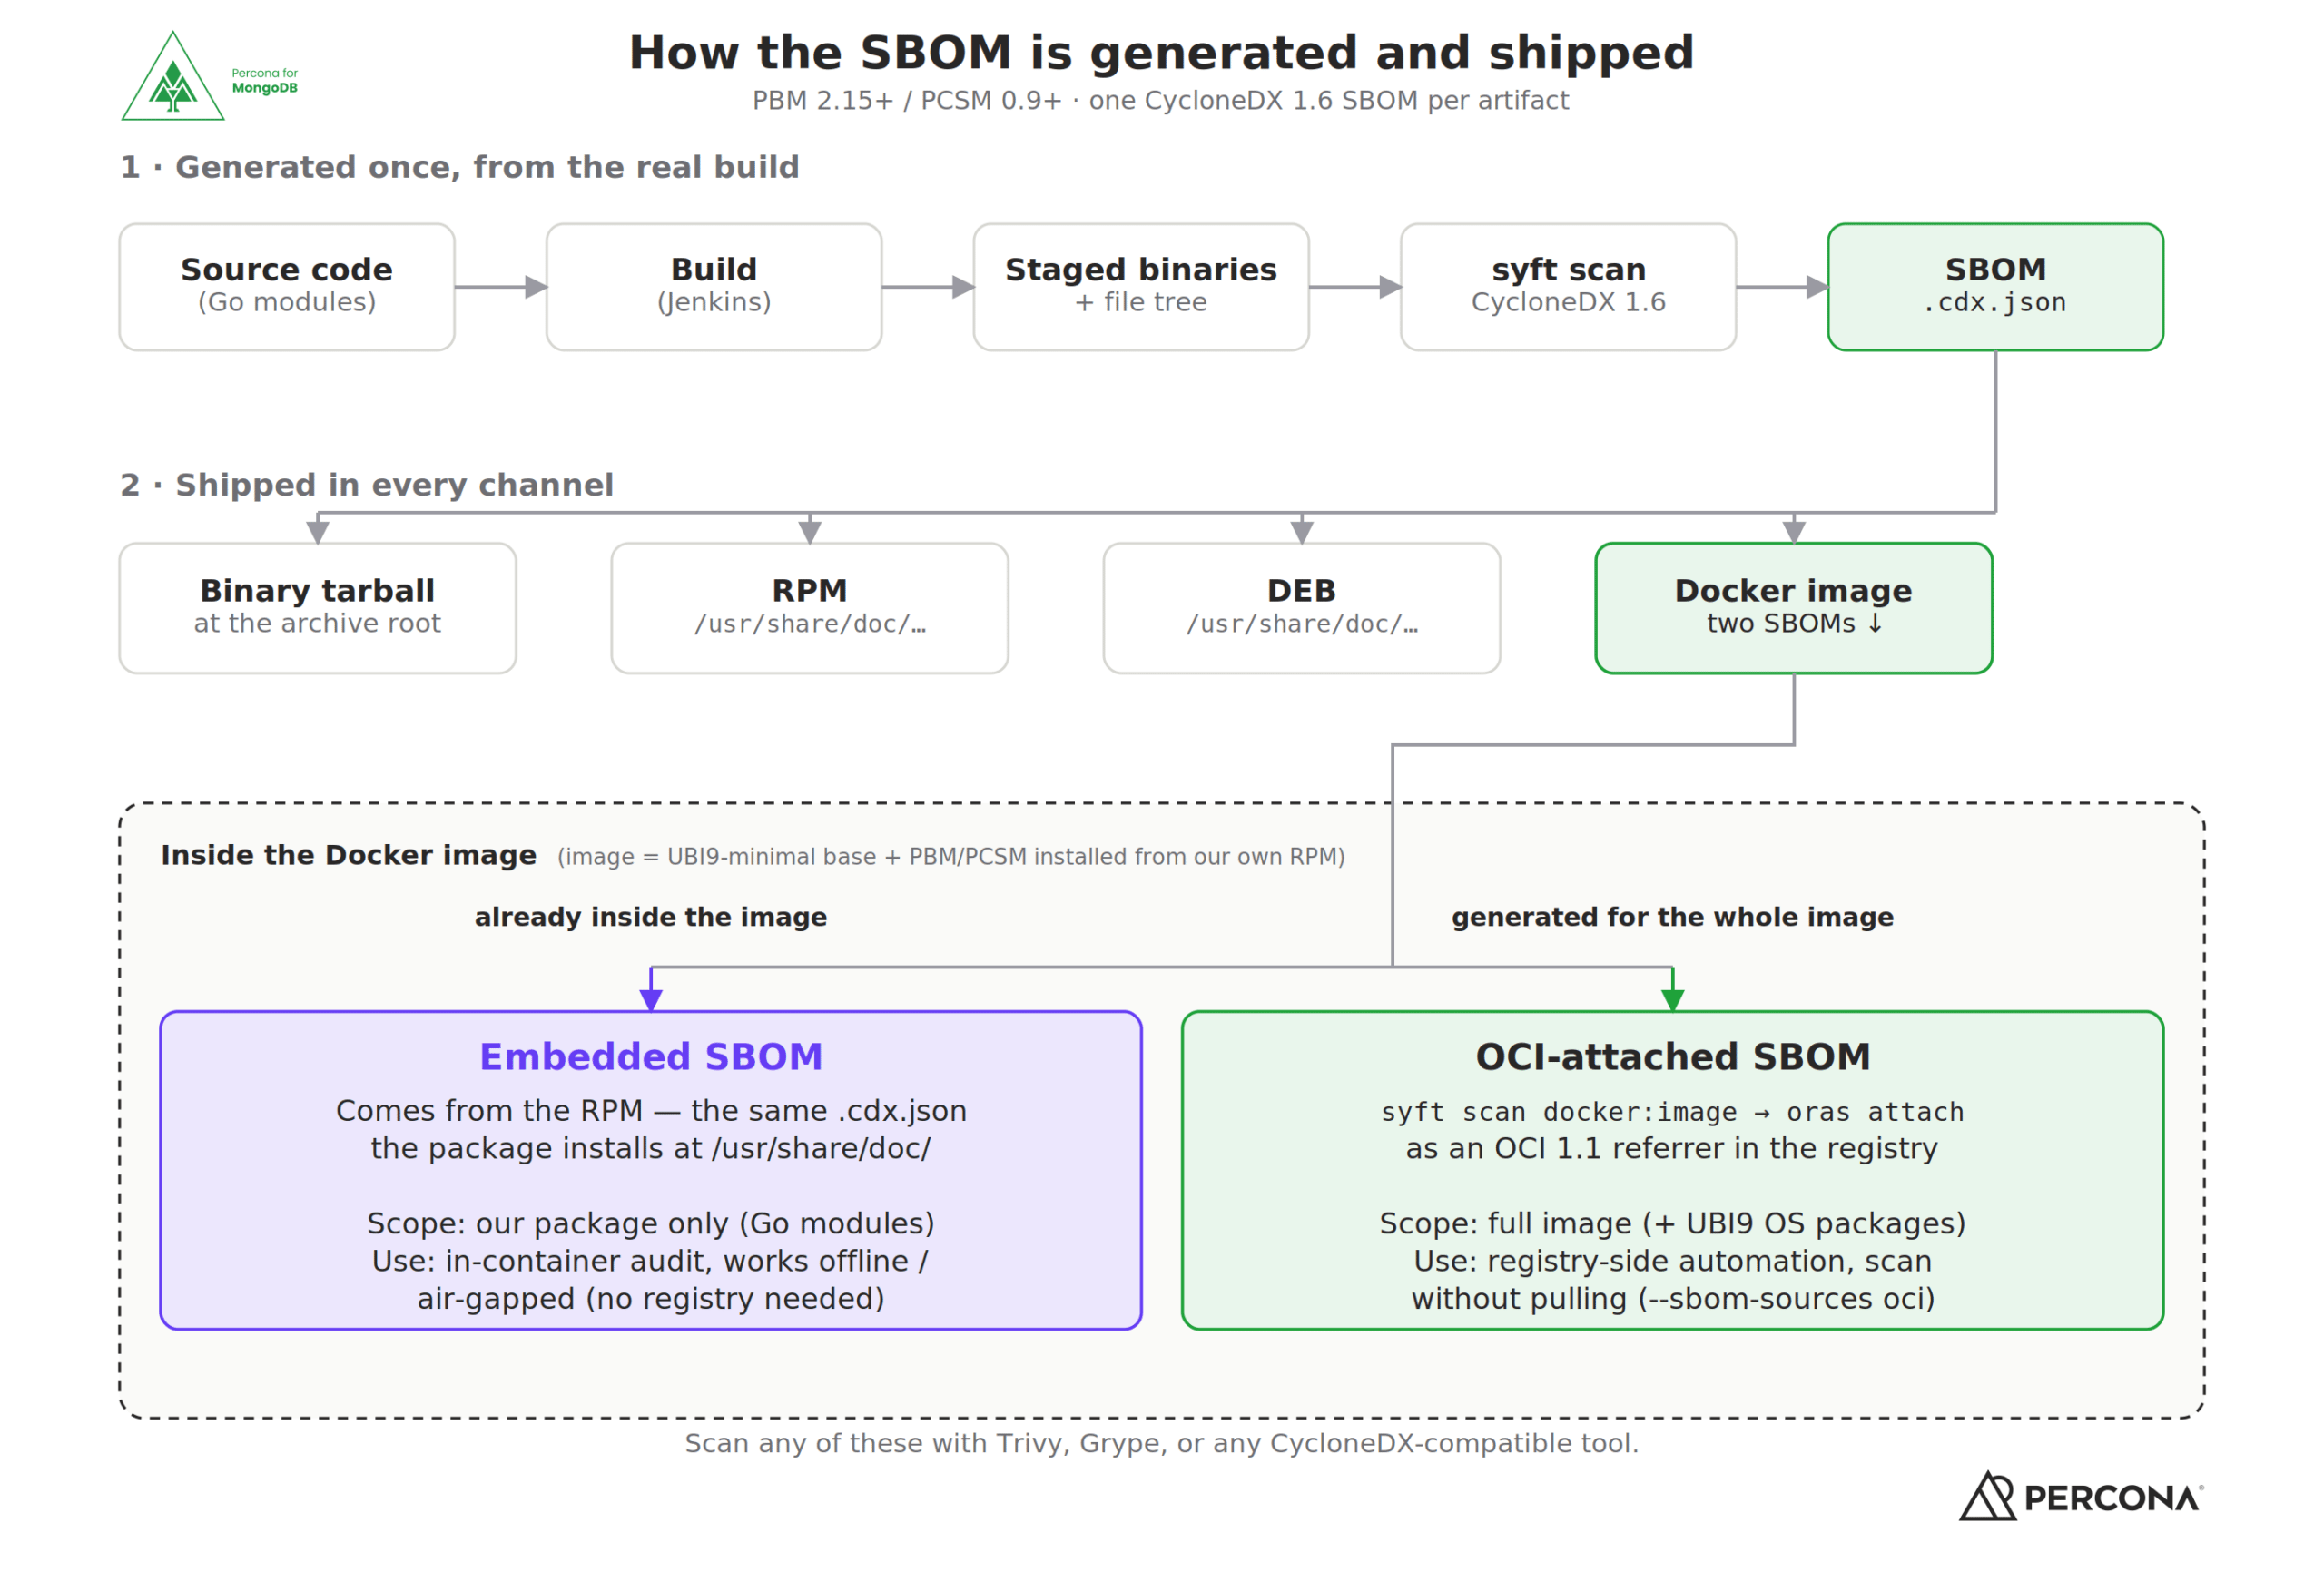
Docker images get special treatment because they bundle two different things: our binary on top of a base operating system. Each PBM and PCSM image, therefore, carries two SBOMs with overlapping scopes.

The embedded SBOM is stored in the image filesystem (the same file the RPM installs) and describes our binary and its Go modules. This is the SBOM to use in offline or air-gapped clusters where you cannot reach a registry.

The OCI-attached SBOM lives next to the image in the registry as an OCI 1.1 referrer artifact and describes the full image, including the base OS packages. This is the canonical SBOM for a Docker image, and the easiest to fetch programmatically.

SBOM Scope / how you reach it
Embedded (installed by the RPM) Our package only: Go modules of the binary; inside the image filesystem
OCI-attached (registry-side) Full image: our package + UBI9 OS packages; via the OCI Referrers API


How the SBOM is generated across PBM and PCSM artifacts, and why a Docker image carries two.

Three ways to scan your SBOM

The examples below use Trivy because it is the most common choice in Percona QA pipelines, but Grype, Snyk, and any other CycloneDX-compatible scanner accept the same .cdx.json files unchanged. By default, these commands report everything the scanner finds. In a CI pipeline, you would want to narrow down the output by leaving only –severity HIGH, CRITICAL to focus on the most serious findings, and –ignore-unfixed to skip CVEs that have no upstream fix yet.

  • From a downloaded package or tarball

Once the artifact is on disk, the SBOM is just a file in a predictable location. Point Trivy at it:

trivy sbom --severity HIGH,CRITICAL,MEDIUM,LOW \
    /usr/share/doc/percona-clustersync-mongodb/percona-clustersync-mongodb-0.9.0.cdx.json

The same command works against the SBOM extracted from a tarball or installed by an RPM or DEB package – only the file path changes. For Oracle Linux, replace with the exact compatible RHEL minor, e.g., --distro redhat/9.8, since Trivy does not recognize the ol OS family on its own, but the RHEL vulnerability database is binary-compatible.

  • From a Docker image, without pulling it

For Docker images, Trivy can fetch the OCI-attached SBOM straight from the registry. No image pull, no extraction step:

trivy image --severity HIGH,CRITICAL,MEDIUM,LOW --sbom-sources oci \
    docker.io/percona/percona-clustersync-mongodb:0.9.0

Trivy resolves the multi-arch index, picks your platform-specific child digest, asks the registry for any attached SBOMs via the OCI Referrers API, and scans whichever one it finds. A typical run looks like this:

Report Summary:

Target Type Vulnerabilities
docker.io/percona/percona-clustersync-mongodb:0.9.0 (redhat 9.8) redhat 0
usr/bin/pcsm gobinary 8

Two targets, two scopes: the base OS layer (no findings) and the PCSM binary (eight Go standard-library CVEs, all flagged because the image was built against a Go release that has since been superseded). The same –sbom-sources oci flag works for PBM images, and against both the public percona/ images on Docker Hub and the engineering perconalab/ images.

  • By hand, with ORAS

If you would rather inspect the OCI artifact directly, to confirm what is attached, or pull the SBOM to disk, the ORAS CLI does that without a scanner in the loop:

oras discover --format tree \
    docker.io/percona/percona-clustersync-mongodb:0.9.0-amd64

The per-arch tag (:<version>-<arch>) resolves straight to the image manifest that the SBOM is attached to. From there, oras pull <digest> writes the .cdx.json to disk for archival or for feeding into a scanner of your choice.

What changes for you

For operators, the upgrade story gets simpler. When a new CVE is disclosed, you no longer have to guess whether your PBM or PCSM deployment is affected; you scan the SBOM that shipped with the exact version you are running and get a yes/no answer in seconds. The SBOM is also a stable input for the dashboards you already run (Dependency-Track, DefectDojo, your SIEM), so PBM and PCSM are no longer blind spots in the inventory.

For security and platform teams, the OCI-attached SBOM means you can pre-screen container images in CI before they ever reach a cluster. Pull-request gates that already scan first-party images for HIGH/CRITICAL findings can pick up PBM and PCSM with no extra glue code: –sbom-sources oci is enough.


Try it on your own deployment

SBOMs ship starting with PBM 2.15.0 and PCSM 0.9.0 across every channel we publish: tarballs, RPM, DEB, and Docker. There is nothing to switch on: download the artifact you would have downloaded, and the SBOM is already there.Full details, including the ORAS walkthrough and per-channel paths, are in the PBM and PCSM documentation (PBM, PCSM).&amp;amp;amp;amp;amp;amp;amp;amp;amp;amp;lt;/p>

Run a scanner over your Percona Backup for MongoDB or Percona ClusterSync for MongoDB deployment using one of the commands above. If the result surprises you in any direction, if you have a finding you would like us to address, or if a workflow did not behave as our docs imply, we would like to hear about it, and the SBOM lets you point us to the exact component and version rather than a hunch. Open an issue in the PBM or PCSM Jira project, or stop by the Percona Community Forum.

One last thing: an SBOM tells you what is inside the artifact, not what we have determined about each finding. That second part is coming. Alongside the per-artifact SBOMs described here, we also plan to publish source SBOMs in the repository, and a follow-up in this series will cover the VEX (Vulnerability Exploitability eXchange) documents that record, for each finding, whether it is fixed, not exploitable in our build, or still under investigation. Watch for both in future re

leases.

The post Alert on CVEs in Your Percona Tools for MongoDB on Day One appeared first on Percona.

Jul
24
2026
--

Alert on CVEs in Your Percona Tools for MongoDB on Day One

TL;DR: Starting with PBM 2.15.0 and PCSM 0.9.0, every release artifact – binary tarballs, RPM and DEB packages, and Docker images – ships a CycloneDX 1.6 Software Bill of Materials in JSON. Scan it with Trivy, Grype, or any CycloneDX-compatible tool. For Docker images, the fastest path is a Trivy image –sbom-sources oci <image>. There is nothing to enable, as the SBOM is already a part of the artifact you were going to download.

If you run Percona Backup for MongoDB (PBM) or Percona ClusterSync for MongoDB (PCSM), both part of the Percona Software for MongoDB family, you can now answer one of the stressful questions in operations: “Is my database tooling affected by this CVE?” in seconds instead of days. And when a customer or auditor asks for a parts list of what you deployed, you can hand it over as a single file instead of starting a multi-day investigation.

That parts list is a Software Bill of Materials (SBOM), and starting with PBM 2.15.0 and PCSM 0.9.0, it comes along in every channel we publish – tarballs, RPM and DEB packages, and Docker images. This post shows what is in it, where to find it, and three ways to scan it.

The problem: you can’t patch what you can’t see

Most MongoDB operators run database tooling assembled by someone else – official RPMs, official containers, official tarballs. When something goes wrong upstream, the first question is always the same: what is actually inside this artifact, and is any of it affected?

Two incidents made that question a board-level concern, and a third made it personal for MongoDB teams. Log4Shell in late 2021 forced thousands of teams to manually audit Java dependencies they did not know they had. The xz-utils backdoor disclosed in early 2024 hid in a compression library buried deep inside Linux base images. Then, in December 2025, MongoBleed (CVE-2025-14847) forced MongoDB teams to urgently identify which server and tooling versions were actually deployed. In every case, teams that already had an SBOM per artifact answered “are we affected?” in minutes; teams that did not took days.

The other version of the problem is that the SBOM is something someone else asks of you – a customer running a security review, an auditor checking EU Cyber Resilience Act or US Executive Order 14028 compliance, or a procurement team working through a vendor questionnaire. Without one, every such request turns into a discovery project.

What Percona Backup for MongoDB and ClusterSync now ship

An SBOM is a machine-readable inventory of every component, library, and OS package inside a built artifact, with versions, licenses, and dependency relationships. Think of it as a packing slip for a software shipment, except a computer can parse it, search it, and cross-reference it against vulnerability databases.

Plenty of vendors now ship SBOMs. What matters is whether the SBOM is actually usable, and PBM and PCSM cover the three things that decide that. The format is CycloneDX 1.6, an OWASP-backed JSON standard that every major tool reads: Trivy, Grype, Snyk, and Dependency-Track. The files are generated with Syft from the actual built binary and the staged file tree, so the inventory reflects what was really packaged, not what the source tree implies. And the SBOM ships in every distribution channel, not just one:

Distribution channel SBOM location
Binary tarball <product>-<version>.cdx.json at the root of the archive
RPM package /usr/share/doc/<product>/<product>-<version>.cdx.json
DEB package /usr/share/doc/<product>/<product>-<version>.cdx.json
Docker image Two SBOMs ship side by side — see below

Docker images carry two SBOMs

Docker images get special treatment because they bundle two different things: our binary on top of a base operating system. Each PBM and PCSM image, therefore, carries two SBOMs with overlapping scopes.

The embedded SBOM is stored in the image filesystem (the same file the RPM installs) and describes our binary and its Go modules. This is the SBOM to use in offline or air-gapped clusters where you cannot reach a registry.

The OCI-attached SBOM lives next to the image in the registry as an OCI 1.1 referrer artifact and describes the full image, including the base OS packages. This is the canonical SBOM for a Docker image, and the easiest to fetch programmatically.

SBOM Scope / how you reach it
Embedded (installed by the RPM) Our package only: Go modules of the binary; inside the image filesystem
OCI-attached (registry-side) Full image: our package + UBI9 OS packages; via the OCI Referrers API


How the SBOM is generated across PBM and PCSM artifacts, and why a Docker image carries two.

Three ways to scan your SBOM

The examples below use Trivy because it is the most common choice in Percona QA pipelines, but Grype, Snyk, and any other CycloneDX-compatible scanner accept the same .cdx.json files unchanged. By default, these commands report everything the scanner finds. In a CI pipeline, you would want to narrow down the output by leaving only –severity HIGH, CRITICAL to focus on the most serious findings, and –ignore-unfixed to skip CVEs that have no upstream fix yet.

  • From a downloaded package or tarball

Once the artifact is on disk, the SBOM is just a file in a predictable location. Point Trivy at it:

trivy sbom --severity HIGH,CRITICAL,MEDIUM,LOW \
    /usr/share/doc/percona-clustersync-mongodb/percona-clustersync-mongodb-0.9.0.cdx.json

The same command works against the SBOM extracted from a tarball or installed by an RPM or DEB package – only the file path changes. For Oracle Linux, replace with the exact compatible RHEL minor, e.g., --distro redhat/9.8, since Trivy does not recognize the ol OS family on its own, but the RHEL vulnerability database is binary-compatible.

  • From a Docker image, without pulling it

For Docker images, Trivy can fetch the OCI-attached SBOM straight from the registry. No image pull, no extraction step:

trivy image --severity HIGH,CRITICAL,MEDIUM,LOW --sbom-sources oci \
    docker.io/percona/percona-clustersync-mongodb:0.9.0

Trivy resolves the multi-arch index, picks your platform-specific child digest, asks the registry for any attached SBOMs via the OCI Referrers API, and scans whichever one it finds. A typical run looks like this:

Report Summary:

Target Type Vulnerabilities
docker.io/percona/percona-clustersync-mongodb:0.9.0 (redhat 9.8) redhat 0
usr/bin/pcsm gobinary 8

Two targets, two scopes: the base OS layer (no findings) and the PCSM binary (eight Go standard-library CVEs, all flagged because the image was built against a Go release that has since been superseded). The same –sbom-sources oci flag works for PBM images, and against both the public percona/ images on Docker Hub and the engineering perconalab/ images.

  • By hand, with ORAS

If you would rather inspect the OCI artifact directly, to confirm what is attached, or pull the SBOM to disk, the ORAS CLI does that without a scanner in the loop:

oras discover --format tree \
    docker.io/percona/percona-clustersync-mongodb:0.9.0-amd64

The per-arch tag (:<version>-<arch>) resolves straight to the image manifest that the SBOM is attached to. From there, oras pull <digest> writes the .cdx.json to disk for archival or for feeding into a scanner of your choice.

What changes for you

For operators, the upgrade story gets simpler. When a new CVE is disclosed, you no longer have to guess whether your PBM or PCSM deployment is affected; you scan the SBOM that shipped with the exact version you are running and get a yes/no answer in seconds. The SBOM is also a stable input for the dashboards you already run (Dependency-Track, DefectDojo, your SIEM), so PBM and PCSM are no longer blind spots in the inventory.

For security and platform teams, the OCI-attached SBOM means you can pre-screen container images in CI before they ever reach a cluster. Pull-request gates that already scan first-party images for HIGH/CRITICAL findings can pick up PBM and PCSM with no extra glue code: –sbom-sources oci is enough.


Try it on your own deployment

SBOMs ship starting with PBM 2.15.0 and PCSM 0.9.0 across every channel we publish: tarballs, RPM, DEB, and Docker. There is nothing to switch on: download the artifact you would have downloaded, and the SBOM is already there.Full details, including the ORAS walkthrough and per-channel paths, are in the PBM and PCSM documentation (PBM, PCSM).&amp;amp;amp;amp;amp;amp;amp;amp;amp;amp;lt;/p>

Run a scanner over your Percona Backup for MongoDB or Percona ClusterSync for MongoDB deployment using one of the commands above. If the result surprises you in any direction, if you have a finding you would like us to address, or if a workflow did not behave as our docs imply, we would like to hear about it, and the SBOM lets you point us to the exact component and version rather than a hunch. Open an issue in the PBM or PCSM Jira project, or stop by the Percona Community Forum.

One last thing: an SBOM tells you what is inside the artifact, not what we have determined about each finding. That second part is coming. Alongside the per-artifact SBOMs described here, we also plan to publish source SBOMs in the repository, and a follow-up in this series will cover the VEX (Vulnerability Exploitability eXchange) documents that record, for each finding, whether it is fixed, not exploitable in our build, or still under investigation. Watch for both in future re

leases.

The post Alert on CVEs in Your Percona Tools for MongoDB on Day One appeared first on Percona.

Jul
10
2026
--

Running DuckDB as a MySQL 9.7 storage engine

ducksdb-mysql-engine is an experimental build of MySQL 9.7 where a table you mark ENGINE=DuckDB answers analytical queries from DuckDB instead of InnoDB. Same server, same connection, no second copy of the data. On TPC-H at scale factor 10, InnoDB times out on 6 of the 22 queries and burns 1317 seconds on the 16 it finishes. The DuckDB tables run all 22 in about 15 seconds.

It’s an experiment, not production software. It patches mysqld and has rough edges, which we list at the end. Source is on GitHub under GPLv2:     https://github.com/EvgeniyPatlan/ducksdb-mysql-engine.

Why we made it

MySQL is great for transactions and slow at analytics. A wide GROUP BY over a few hundred million rows, or a six-way join, takes minutes on InnoDB. The usual fix is to copy the data into a column store and keep it in sync, so now you’re running two systems and the pipeline between them.

We wanted the table itself to be the column store, with the heavy queries offloaded for you. Mark it ENGINE=DuckDB, query it the way you always have, and DuckDB does the analytical work.

What it actually is

DuckDB is an in-process columnar query engine, basically SQLite for OLAP. It stores data by column and it’s built for scans and aggregations, which is exactly what a row store is bad at.

We’re not the first to put it behind a relational table. Alibaba’s AliSQL has had a built-in DuckDB engine for a while. MariaDB shipped MariaDB DuckDB about a week ago, while we were already building ours. AliSQL got there first; MariaDB and we landed on the same idea independently, around the same time, them on MariaDB and us on stock MySQL 9.7. Their engine is the closest comparison to ours, so it’s in the benchmarks below.

How it hooks into MySQL

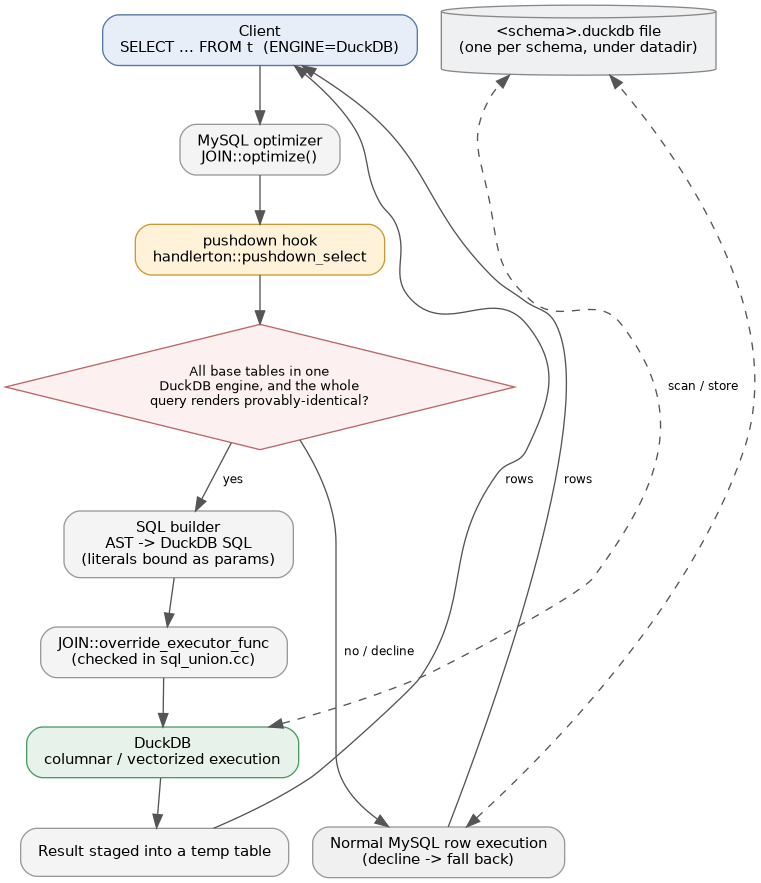
MySQL doesn’t have a select_handler, the API MariaDB uses to grab a whole SELECT and run it inside an engine. We added our own: a handlerton::pushdown_select hook.

The pushdown path. Either the whole query renders to DuckDB SQL and runs columnar, or it declines and the normal row path handles it.

The engine is compiled into mysqld, and each schema is one DuckDB file under the datadir. Three patches do the integration, and all three are generic, so they’ll fire for any engine that exposes the hook:

  • The hook runs at the end of JOIN::optimize(). If every base table in the block is one engine that has the hook, that engine looks at the optimized JOIN, and if it can translate the whole query it sets JOIN::override_executor_func (which the executor already checks in sql_union.cc). The query gets regenerated as DuckDB SQL, prepared once, run, and the aggregated result is staged into a temp table. EXPLAIN is left alone.
  • A server-side LOAD DATA INFILE goes into a DuckDB COPY instead of crawling through write_row row by row. At 600M rows that’s a 20-minute load instead of 80.
  • For single-engine statements we clear OPTIMIZER_SWITCH_SEMIJOIN in prepare, so IN, EXISTS, NOT IN and NOT EXISTS stay as subqueries the builder can render instead of getting rewritten into semijoin nests it can’t recognize.

The builder only renders a node when the output is provably identical to what MySQL would return. If it can’t, it declines and MySQL runs the query unchanged. Literals are bound as parameters. Collation, NULL ordering and decimal scale are matched on purpose, and an unmapped collation or a REAL literal is enough to make it back off. With that in place, all 22 TPC-H queries push down and match InnoDB row for row.


Getting started

The fastest way in is the image:

docker run -d --name mysql-duckdb -p 3306:3306 \
-e MYSQL_ROOT_PASSWORD=secret \
-v mysql-duckdb-data:/var/lib/mysql \
evgeniypatlan/test-images:mysql-9.7-duckdb-v0.2.0

Make a table, put a few rows in, run an aggregate:

CREATE DATABASE shop; USE shop;
CREATE TABLE sales (id INT PRIMARY KEY, region INT, amount DECIMAL(12,2)) ENGINE=DuckDB;
INSERT INTO sales VALUES (1,1,100),(2,1,200),(3,2,50);

SELECT region, SUM(amount) FROM sales GROUP BY region;
-- region | SUM(amount)
-- 1 | 300.00
-- 2 | 50.00


Nothing about that query is special, and that is the point. To check it actually went to DuckDB rather than down the row path, watch the Ducksdb_pushdown_count status variable:

SELECT region, SUM(amount) FROM sales GROUP BY region; -- offloaded
SHOW STATUS LIKE 'Ducksdb_pushdown_count'; -- counter goes +1

SELECT * FROM sales WHERE id = 3; -- point lookup
SHOW STATUS LIKE 'Ducksdb_pushdown_count'; -- counter unchanged


The single-row lookup stays on the row path deliberately. For one row an index seek beats spinning up a DuckDB result, so there is no reason to offload it. OLTP keeps its path, analytics get the column store, and you do not pick by hand.

If you would rather build it, you need the MySQL 9.7 tree under vendor/mysql-server/ and a DuckDB prefix, then:

ln -s ../../engine vendor/mysql-server/storage/duckdb
scripts/build-server.sh # applies the 3 patches, builds mysqld + clients


Does it actually go fast?

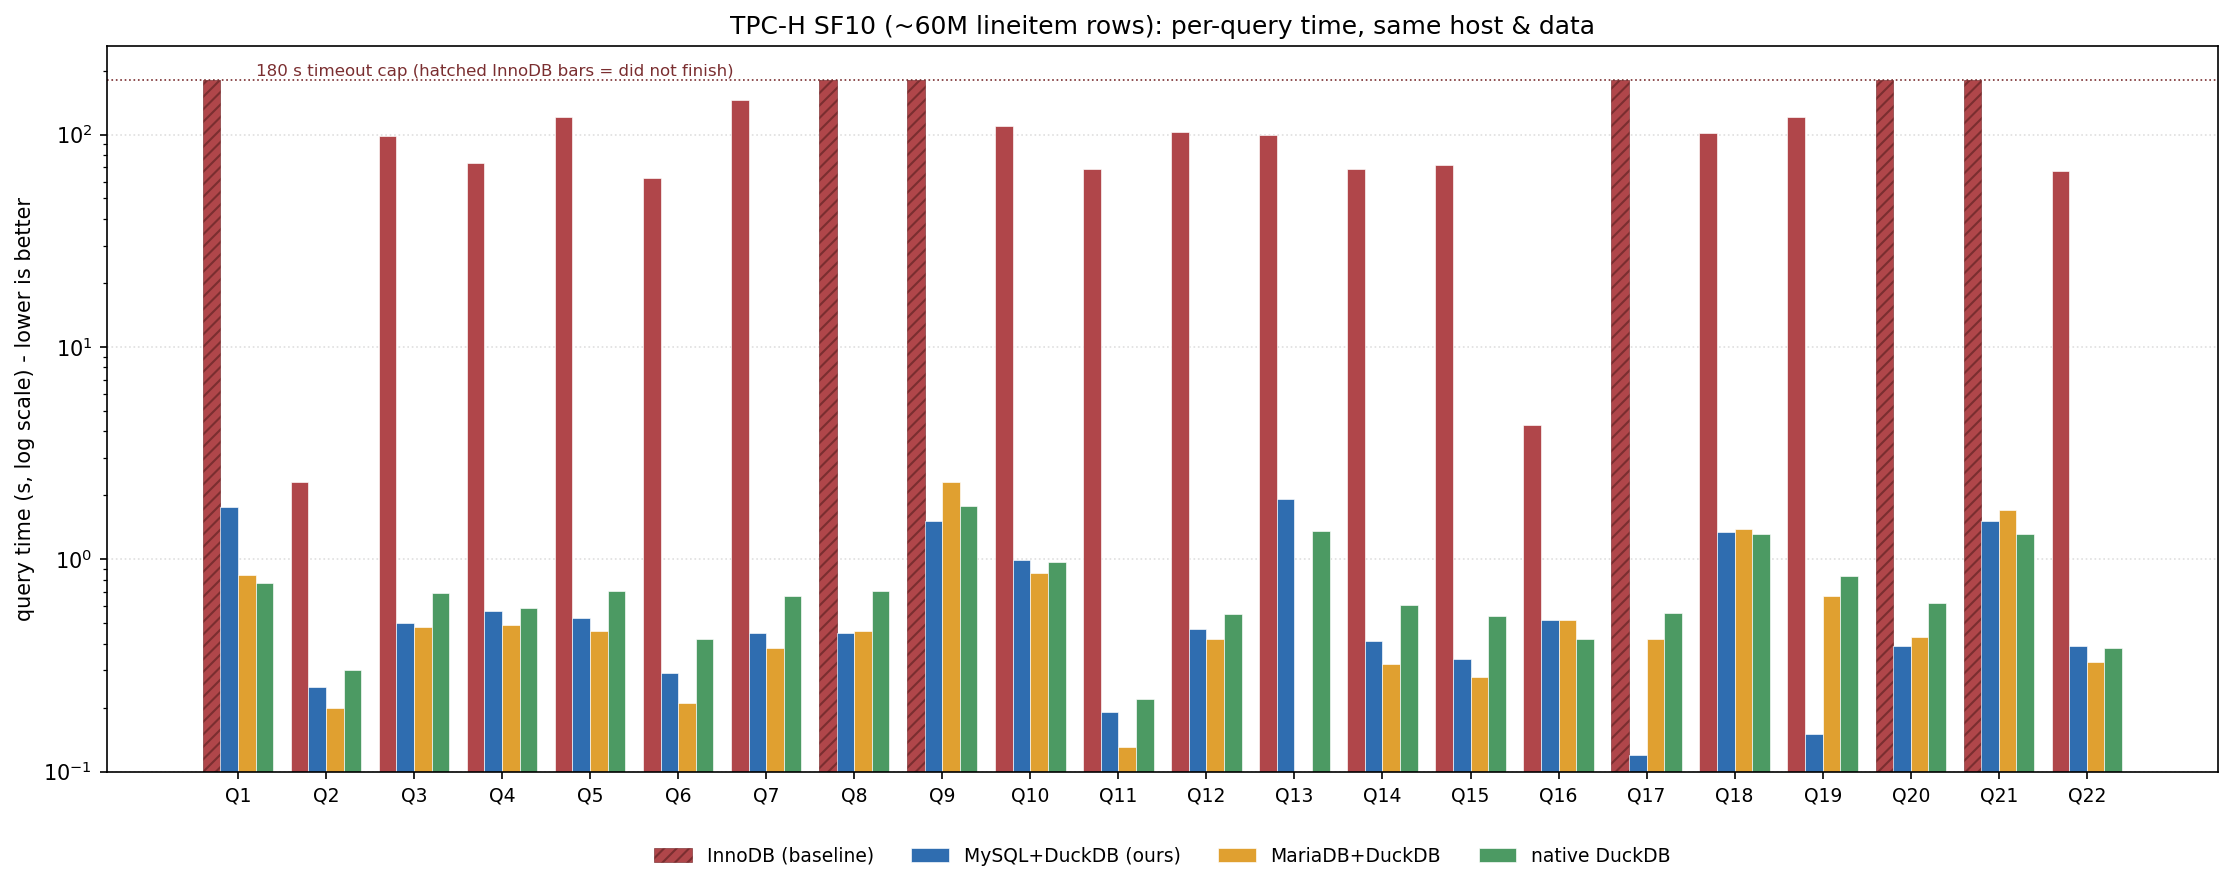
All 22 TPC-H queries, were executed in a Docker on one laptop (20 cores, 62 GiB RAM), the same data loaded into four engines: InnoDB, our MySQL+DuckDB, MariaDB+DuckDB, and standalone DuckDB as the reference. Warm wall-clock, minimum over a few runs, in seconds.

SF10, around 60 million lineitem rows

A handful of rows here; the whole table is in docs/tpch_engine_comparison.md:

Query InnoDB MySQL+DuckDB MariaDB +DuckDB Native DuckDB
Q1 >180 1.77 0.84 0.77
Q5 127.6 0.53 0.46 0.71
Q7 145.0 0.45 0.38 0.67
Q9 >180 1.52 2.30 1.78
Q18 101.7 1.35 1.39 1.31
Q19 120.4 0.15 0.67 0.83
All 22  Finished 16/22 15.1s 13.3s 16.3


SF10, all 22 queries, log scale (lower is better). Hatched InnoDB bars did not finish inside 180 s. The three DuckDB engines sit in a tight band near the floor.

InnoDB is somewhere between 100 and 340 times slower per query, and on 6 of the 22 it never finished inside the 180-second cap (the correlated subqueries and the heaviest scans). It burned 1317 seconds on just the 16 it did finish. The three DuckDB engines get through all 22 in about 15 seconds, and ours lands right between MariaDB and plain DuckDB. The gap is so big there is not much else to say about it.

SF100, around 600 million lineitem rows

At this size InnoDB is out of the running (a copy of the data alone is about 100 GB and queries run for hours), so it is the three DuckDB engines only, run one at a time:

Query MySQL+DuckDB MariaDB+DuckDB Native DuckDB
Q1 15.25 6.50 5.50
Q9 20.97 115.29 19.54
Q10 10.64 ERR 8.14
Q13 19.75 ERR 13.27
Q18 14.88 29.62 11.08
Q19 2.91 7.98 6.61
Correct 22/22 20/22 22/22


SF100, three DuckDB engines, log scale (lower is better). Q15 for our engine is shown at its matched-memory time (~4 s); the capped run measured 1309 s, explained below. MariaDB errored on Q10 and Q13.

At 600 million rows ours is still correct on all 22 and stays close to plain DuckDB. MariaDB’s engine drops two queries (Q10, and Q13 on its column-list syntax) and is a lot slower on the big joins – Q9 took 115 seconds against our 21 and native’s 20.

One honest word on Q15 at SF100, because in the full table it shows an ugly number for our engine. It is not a real loss. We capped DuckDB’s memory so it spills to disk instead of getting OOM-killed inside mysqld, and under that cap Q15’s CTE spills a lot. Give it the memory MariaDB had and it runs in about 4 seconds, like native. The answer was always right; only the clock was bad.

And one number we did not expect: loading those 600 million rows took about 20 minutes with our engine (the COPY shortcut) versus about 80 minutes with MariaDB, which loads row by row on a single core. Roughly four times faster to get the data in.

Try it, then tell us

If any of this sounds useful, pull the image and throw your own queries at it:

docker run -d -p 3306:3306 -e MYSQL_ROOT_PASSWORD=secret \
evgeniypatlan/test-images:mysql-9.7-duckdb-v0.2.0

The source is on GitHub (GPLv2), patches and benchmark harness included: https://github.com/EvgeniyPatlan/ducksdb-mysql-engine. The full per-query benchmark and how we measured it live in docs/tpch_engine_comparison.md.


The post Running DuckDB as a MySQL 9.7 storage engine appeared first on Percona.

Mar
03
2026
--

What Exactly Is the MySQL Ecosystem? 

How MySQL writes workAs we set out to help the MySQL ecosystem assert greater independence from Oracle by establishing a vendor-neutral industry association, we had to confront a deceptively simple question: What exactly is the MySQL ecosystem? There are many views on this question. Some argue it should revolve strictly around the MySQL brand—meaning MariaDB would be excluded. […]

May
07
2018
--

Webinar Wednesday, May 9, 2018: MySQL Troubleshooting and Performance Optimization with Percona Monitoring and Management (PMM)

MySQL Troubleshooting

MySQL TroubleshootingPlease join Percona’s CEO, Peter Zaitsev as he presents MySQL Troubleshooting and Performance Optimization with PMM on Wednesday, May 9, 2018, at 11:00 AM PDT (UTC-7) / 2:00 PM EDT (UTC-4).

Optimizing MySQL performance and troubleshooting MySQL problems are two of the most critical and challenging tasks for MySQL DBAs. The databases powering your applications must handle heavy traffic loads while remaining responsive and stable so that you can deliver an excellent user experience. Further, DBAs’ bosses expect solutions that are cost-efficient.

In this webinar, Peter discusses how you can optimize and troubleshoot MySQL performance and demonstrate how Percona Monitoring and Management (PMM) enables you to solve these challenges using free and open source software. We will look at specific, common MySQL problems and review the essential components in PMM that allow you to diagnose and resolve them.

Register for the webinar now.

Peter ZaitsevPeter Zaitsev, CEO

Peter Zaitsev co-founded Percona and assumed the role of CEO in 2006. As one of the foremost experts on MySQL strategy and optimization, Peter leveraged both his technical vision and entrepreneurial skills to grow Percona from a two-person shop to one of the most respected open source companies in the business. With over 140 professionals in 30 plus countries, Peter’s venture now serves over 3000 customers – including the “who’s who” of internet giants, large enterprises and many exciting startups. The Inc. 5000 recognized Percona in 2013, 2014, 2015 and 2016. Peter was an early employee at MySQL AB, eventually leading the company’s High-Performance Group. A serial entrepreneur, Peter co-founded his first startup while attending Moscow State University where he majored in Computer Science. Peter is a co-author of High-Performance MySQL: Optimization, Backups, and Replication, one of the most popular books on MySQL performance. Peter frequently speaks as an expert lecturer at MySQL and related conferences, and regularly posts on the Percona Database Performance Blog. He was also tapped as a contributor to Fortune and DZone, and his recent ebook Practical MySQL Performance Optimization is one of percona.com’s most popular downloads.

The post Webinar Wednesday, May 9, 2018: MySQL Troubleshooting and Performance Optimization with Percona Monitoring and Management (PMM) appeared first on Percona Database Performance Blog.

Feb
05
2018
--

Percona Monitoring Plugins 1.1.8 Release Is Now Available

Percona Monitoring Plugins 1.1.7

Percona Monitoring Plugins 1.1.8Percona announces the release of Percona Monitoring Plugins 1.1.8.

Changelog

  • Add MySQL 5.7 support
  • Changed a canary check to use timestamp.now() and return a timedelta.seconds
  • Remove an additional condition for the Dictionary memory allocated
  • Fixed a false-positive problem when the calculated delay was less than 0 and the -m was not set.
  • Fixed the problem where slaves would alert due to deadlocks on the master.
  • If using pt-heartbeat, get_slave_status was only called when the -s option is set to MASTER
  • Disabled UNK alerts by default (it is possible to enable them explicitly).
  • A fix was added for MySQL Multi-Source replication.
  • The graph Percona InnoDB Memory Allocation showed zeroes for the
    metrics Total memory (data source item nl) and Dictionary memory
    (data source item nm) when used for MySQL 5.7.18, because the syntax
    of SHOW ENGINE INNODB STATUS has changed in MySQL 5.7 (see https://dev.mysql.com/doc/refman/5.7/en/innodb-standard-monitor.html).
  • The graph Percona InnoDB I/O Pending showed NaN for the metrics
    Pending Log Writes (data source item hn) and Pending Chkp Writes
    (data source item hk) when used for MySQL 5.7.18, because the syntax
    of SHOW ENGINE INNODB STATUS has changed in MySQL 5.7 (see https://dev.mysql.com/doc/refman/5.7/en/innodb-standard-monitor.html).
  • Added server @@hostname as a possible match to avoid DNS lookups while allowing hostname-match.

A new tarball is available from downloads area or in packages from our software repositories. The plugins are fully supported for customers with a Percona Support contract and free installation services are provided as part of some contracts. You can find links to the documentation, forums and more at the project homepage.

About Percona Monitoring Plugins
Percona Monitoring Plugins are monitoring and graphing components designed to integrate seamlessly with widely deployed solutions such as Nagios, Cacti and Zabbix.

Dec
21
2017
--

This Week in Data with Colin Charles 20: cPanel changes strategy, Percona Live CFP extended

Colin Charles

Colin CharlesJoin Percona Chief Evangelist Colin Charles as he covers happenings, gives pointers and provides musings on the open source database community.

I think the biggest news from last week was from cPanel – if you haven’t already read the post, please do – on Being a Good Open Source Community Member: Why we hesitated on MySQL 5.7. cPanel anticipated MariaDB being the eventual replacement for MySQL, based on movements from Red Hat, Wikipedia and Google. The advantage focused on transparency around security disclosure, and the added features/improvements. Today though, “MySQL now consistently matches or outpaces MariaDB when it comes to development and releases, which in turn is increasing the demand on us for providing those upgraded versions of MySQL by our users.” And maybe a little more telling, “when MariaDB 10.2 became stable in May 2017 it included many features found in MySQL 5.7. However, MySQL reached stable nearly 18 months earlier in October 2015.” (emphasis mine).

So cPanel is going forth and supporting MySQL 5.7. They will continue supporting MariaDB Server for the foreseeable future. This really is cPanel ensuring they are responsive to users: “The people using and building database-driven applications are doing so with MySQL in mind, and are hesitant to add support for MariaDB. Responding to our community’s desires is one of the most important things to us, and this is something that we are hearing asked for from our community consistently.”

I, of course, think this is a great move. Users deserve choice. And MySQL has features that are sometimes still not included in MariaDB Server. Have you seen the Complete list of new features in MySQL 5.7? Or my high-level response to a MariaDB Corporation white paper?

I can only hope to see more people think pragmatically like cPanel. Ubuntu as a Linux distribution still does – you get MySQL 5.7 as a default (very unlike the upstream Debian which ships MariaDB Server nowadays). I used to be a proponent of MariaDB Server being everywhere, when it was community-developed, feature-enhanced, and backward-compatible. However, the moment it stopped being a branch and a true fork is the moment where trouble lies for users. I think it was still marginally fine with 10.0, and maybe even 10.1, but the ability to maintain feature parity with enhanced features has long gone. Short of a rebase? But then… what would be different to the already popular branch of MySQL called Percona Server for MySQL?

While there are wins and support from cloud vendors, like Amazon AWS RDS and Microsoft Azure, you’ll notice that they offer both MySQL and MariaDB Server. Google Cloud SQL notably only offers MySQL. IBM may be a sponsor of the MariaDB Foundation, but I don’t see their services like Compose offering anything other than MySQL (with group replication nonetheless!). Platinum member Alibaba Cloud offers MySQL and PostgreSQL. However, Tencent seems to suggest that MariaDB is coming soon? One interesting statistic to watch would be user uptake naturally.

Events

From an events standpoint, the Percona Live 2018 Call for Papers has been extended to January 12, 2018. We expect an early announcement of maybe ten talks in the week of  January 5. Please submit to the CFP. Have you got your tickets yet? Nab them during our Percona Live 2018 super saver registration when they are the best price!

FOSDEM has got Sveta and myself speaking in the MySQL and Friends DevRoom, but we also have good news in the sense that Peter Zaitsev is also going to be at FOSDEM – speaking in the main track. We’ll also have plenty of schwag at the stand.

I think it’s important to take note of the updates to Percona bug tracking: yes, its Jira all the way. Would be good for everyone to start also looking at how the sausage is made.

Dragph, a “distributed fast graph database“, just raised $3m and released 1.0. Have you used it?

On a lighter note, there seems to be a tweet going around by many, so I thought I’d share it here. Merry Christmas and Happy Holidays.

He’s making a database
He’s sorting it twice
SELECT * FROM girls_boys WHERE behaviour = “nice”
SQL Claus is coming to town!

Releases

Link List

Upcoming appearances

  • FOSDEM 2018 – Brussels, Belgium – February 3-4 2018
  • SCALE16x – Pasadena, California, USA – March 8-11 2018

Feedback

I look forward to feedback/tips via e-mail at colin.charles@percona.com or on Twitter @bytebot.

Dec
21
2017
--

Three P’s of a Successful Black Friday: Percona, Pepper Media Holding, and PMM

Successful Black Friday

As we close out the holiday season, let’s look at some data that tells us how to guarantee a successful Black Friday (from a database perspective).

There are certain peak times of the year where companies worldwide hold their breath in the hope that their databases do not become overloaded or unresponsive. A large percentage of yearly profits are achieved in a matter of hours during peak events. It is critical that the database environment remains online and responsive. According to a recent survey, users will not wait more than 2.5 seconds for a site to load before navigating elsewhere. Percona has partnered with many clients over the years to ensure success during these critical events. Our goal is always to provide our clients with the most responsive, stable open-source database environments in order to meet their business needs.

First Stop: Germany

In this blog post, we are going to take a closer look at what happened during Black Friday for a high-demand, high-traffic, business-critical application. Pepper Media Holding runs global deals sites where users post and vote on top deals on products in real-time. To give you a better idea of what the user sees, there is a screenshot below from their Germany mydealz.de branch of Pepper Media Holding.Successful Black Friday

As you can imagine, Black Friday results in a huge spike in traffic and user contribution. In order to ensure success during these crucial times, Pepper Media Holding utilizes Percona’s fully managed service offering. Percona’s Managed Services team has become an extension of Pepper Media Holding’s team by helping plan, prepare, and implement MySQL best-practices across their entire database environment.

Pepper Media Holding and Percona thought it would be interesting to reflect on Black Friday 2017 and how we worked together to flourish under huge spikes in query volume and user connections.

Below is a graph of MySQL query volume for Germany servers supporting the mydealz.de front-end. This graph is taken from Percona’s Managed Service Team’s installation of Percona Monitoring and Management (PMM), which they use to monitor Pepper Media’s environment.

As to be expected, MySQL query volume peaked shortly before and during midnight local time. It also spiked early in the morning as users were waking up. The traffic waned throughout the day. The most interesting data point is the spike from 5 AM to 9 AM which saw an 800% increase from the post-midnight dip. The sustained two-day traffic surge was on average a 200% increase when compared to normal, day-to-day query traffic hitting the database.

For more statistics on how the mydealz.de fared from a front-end and user perspective, visit Pepper Media Holding’s newsroom where Pepper Media has given a breakdown of various statistics related to website traffic during Black Friday.

Next Stop: United Kingdom

Another popular Pepper Media Holding branch is in the United Kingdom – better known as HotUKDeals. HotUKDeals hosts user-aggregated and voted-on deals for UK users. This is the busiest Pepper Media Holding database environment on average. Below is a screenshot of the user interface.

The below graphs are from our Managed Service Team’s Percona Monitoring and Management installation and representative of the UK servers supporting the HotUKDeals website traffic.

The first graph we are taking a look at is MySQL Replication Delay. As you can see, the initial midnight wave of Black Friday deals caused a negligible replica delay. The Percona Monitoring and Management MySQL Replication Delay graph is based on seconds_behind_master which is an integer value only. This means the delay is somewhere between 0 and 1 most of the time. Only once did it go between 1 and 2 over the entire course of Black Friday traffic.

The below graphs highlight the MySQL Traffic seen on the UK servers during the Black Friday traffic spike. One interesting note with this graph is the gradual lead-up to the midnight Black Friday spike. It looks like Black Friday is overstepping its boundaries into Gray Thursday. The traffic spikes here mimic the ones we saw in Germany. There’s an initial spike at midnight on Black Friday and then another spike as shoppers are waking up for their day. The UK servers saw a 361% spike in traffic the morning of Black Friday.

MySQL connections also saw an expected and significant spike during this time. Neglecting to consider max_connections system parameter during an event rush might result in “ERROR 1040 (00000): Too many connections.” However, our CEO, Peter Zaitsev, cautions against absent-mindedly setting this parameter at an unreachable level just to avoid this error. In a blog post, he explained best-practices for this scenario.

The MySQL query graph below shows a 400% spike in MySQL queries during the peak Black Friday morning traffic rush. The average number of queries hitting the database over this two day period is significantly higher than normal – approximately 183%.

Conclusion

Percona reported no emergencies during the Black Friday period for its Managed Service customers – including Pepper Media Holding. We saw similarly high traffic spikes among our customers during this 2017 Black Friday season. I hope that this run-down of a few PMM graphs taken during Pepper Media Holding’s Black Friday traffic period was informative and interesting. Special thanks to Pepper Media Holding for working with us to create this blog post.

Note: Check out our Pepper Media case study on how Percona helps them manage their database environment.

If you would like to further explore the graphs and statistics that Percona Monitoring and Management has to offer, we have a live demo available at https://pmmdemo.percona.com. To discuss how Percona Managed Services can help your database thrive during event-based traffic spikes (and all year round), please call us at +1-888-316-9775 (USA), +44 203 608 6727 (Europe), or have us contact you.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com