May
27
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Backup-Restore and PV Reuse


A Percona PostgreSQL operator pgBackRest restore is the simplest way to move off the Crunchy Data PostgreSQL Operator: take a full Crunchy backup, point the new Percona cluster’s dataSource at the existing pgBackRest archive, and the cluster bootstraps from it before its first start. This post covers that path, plus a second option, persistent-volume reuse, for cases where you want to skip the data copy entirely.

This is part 3 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0. Part 2 covered the standby cluster method, the safest migration path when downtime budget is tight.

This post covers two simpler paths:

  • Backup and restore, the fastest if you can tolerate a short application-downtime window
  • Persistent volume reuse, when you want to skip the data copy entirely and keep the existing PGDATA

If you are landing here cold, start with part 1 for the why, then read Part 2 for the standby method. The rest of this post assumes you have already decided to migrate and want a tested playbook.

Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any S3-compatible service. Required for the backup-and-restore method, optional for PV reuse.
Tools kubectl, helm (v3)

Different versions may have slight differences in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


What this post does NOT cover

  • Application-side connection-string changes beyond updating to the new pgBouncer service
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations
  • Crunchy enterprise-only features like TDE or pgBackRest custom encryption
  • Operating two operators against the same namespace before the hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


1. Migration using backup and restore

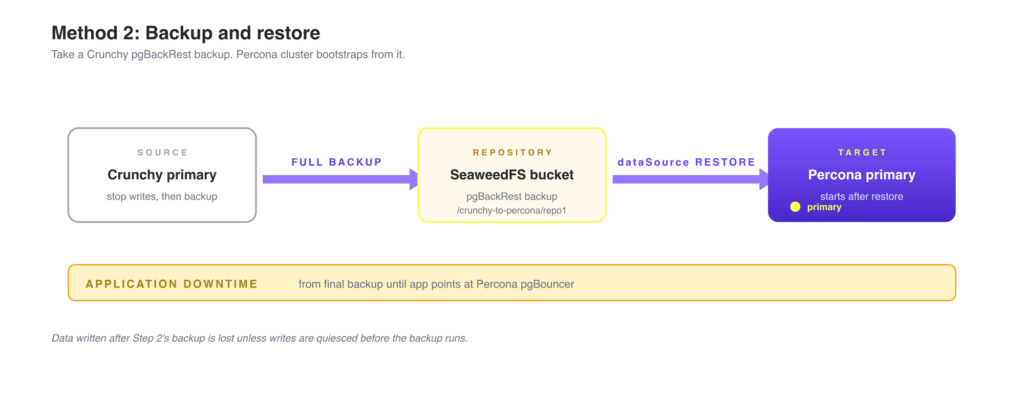
This is often the fastest and simplest path, especially when you do not need a live standby. You take a full backup of the Crunchy source cluster, then create a Percona cluster that automatically restores from that backup before its first start.

Data written between the final backup and the application cutover is lost, so the migration window is the time between those two events. For a near-zero-downtime alternative, see part 2: standby cluster method.


Overview
Before you begin

Set the namespace once. Every command in this guide reads from this variable:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: "n" is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.

Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secrets.yaml:

# Copy and edit the file first to set your credentials.
kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/01-pgbackrest-secrets.yaml

Both contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket. The repo1-path value must match the path that will be referenced in the Percona dataSource.pgbackrest.global.repo1-path field.

Optional: deploy the Crunchy operator for testing. The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait

To start a fresh source cluster for testing, apply examples/02-crunchy-source-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/02-crunchy-source-cluster.yaml

The key pgBackRest settings:

global:
  repo1-path: /crunchy-to-percona/repo1   # source repo referenced in Percona dataSource
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1

Wait for the cluster and its pgBackRest stanza to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 2. Trigger a full backup (the migration cutover point)

This is the backup the Percona cluster will restore from. Stop accepting writes on the application side before triggering it to ensure a consistent snapshot, or accept that data written after this backup will be lost.

kubectl annotate postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"

kubectl wait job \
  --selector postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Deploy the Percona Operator

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s

Step 4. Create the Percona cluster from the backup

Apply examples/03-percona-restored-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/03-percona-restored-cluster.yaml

The key section that bootstraps the cluster from the Crunchy backup:

dataSource:
  pgbackrest:
    stanza: db
    configuration:
      - secret:
          name: percona-pgbackrest-secret
    global:
      # Must match repo1-path in the Crunchy source cluster exactly.
      repo1-path: /crunchy-to-percona/repo1
      repo1-s3-uri-style: path
      repo1-s3-verify-tls: "n"
    repo:
      name: repo1
      s3:
        bucket: pg-migration
        endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
        region: us-east-1

The Percona cluster’s own backup repository must use a different path from the Crunchy source:

backups:
  pgbackrest:
    global:
      repo1-path: /percona-restored/repo1   # different from Crunchy's path

As soon as the Custom Resource is applied, the cluster is bootstrapped from the storage referenced in dataSource and then started. Once the cluster becomes ready, you can immediately create new backups; in this case, repo1 from the backups section will be used as the target repository.

Wait for the cluster to reach ready state:

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify the data was restored successfully:

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f. The cluster is the primary and accepts writes.

Step 5. Verify the cluster is healthy

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Step 6. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery baseline on the Percona cluster’s own repository. All future PITR restores will use this backup, independent of the Crunchy archive.

Step 7. Reconnect your application

kubectl get service -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/role=pgbouncer

Step 8. Clean up the Crunchy cluster

Once the migration is verified and your application is connected to the new cluster:

kubectl delete postgrescluster crunchy-source -n $MIGRATION_NS
helm uninstall pgo -n $MIGRATION_NS


Rollback

Until Step 8, rollback is straightforward: switch the application connection string back to the Crunchy pgBouncer service. The Crunchy primary still holds the authoritative state because no writes were directed at the Percona cluster during the cutover (you stopped writes before Step 2). Any writes the application sent to the Percona cluster after cutover will not be present on Crunchy and would need to be replayed manually.

After Step 8, rollback requires restoring the Crunchy cluster from a backup, which is feasible because the original repo1 is still in the bucket.

Troubleshooting

archive.info missing. The repo1-path in dataSource.pgbackrest.global must match the Crunchy source cluster’s repo1-path exactly:

kubectl get postgrescluster crunchy-source -n $MIGRATION_NS \
  -o jsonpath='{.spec.backups.pgbackrest.global.repo1-path}'

kubectl get perconapgcluster percona-restored -n $MIGRATION_NS \
  -o jsonpath='{.spec.dataSource.pgbackrest.global.repo1-path}'


Restore job fails with TLS errors. pgBackRest requires HTTPS even with repo1-s3-verify-tls: "n". Verify SeaweedFS is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "


Cluster stuck in restoring state. Check the pgBackRest restore job logs:

kubectl logs \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/pgbackrest-restore=percona-restored \
  -n $MIGRATION_NS \
  -c pgbackrest

Data missing after restore. The restore captures data up to the latest backup. If post-backup data is critical, re-run the backup on the Crunchy cluster after quiescing writes, then delete and recreate the Percona cluster to restore from the newer backup.

2. Migration using existing persistent volumes

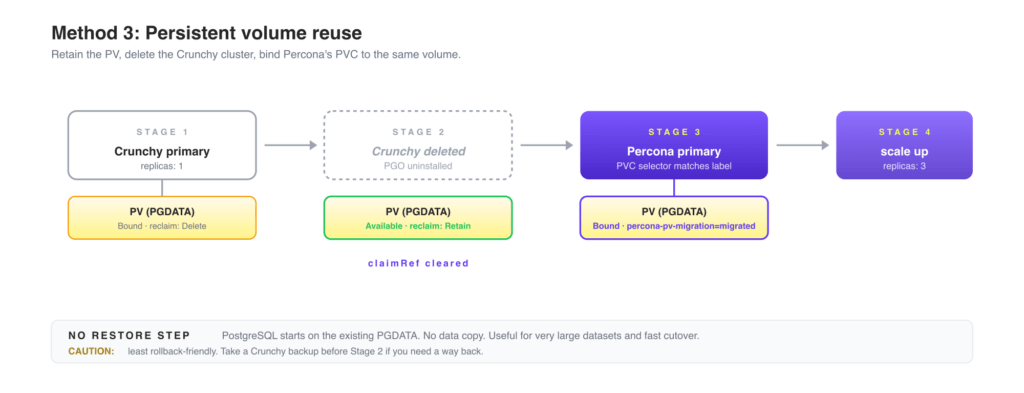
This method reuses the Crunchy primary’s PGDATA persistent volume directly. It avoids a full backup-restore cycle: you retain the Crunchy primary’s PV, delete the Crunchy cluster, then create a Percona cluster whose PVC binds to that same PV. PostgreSQL starts on the existing data directory without any restore step.

It is useful when:

  • you want to avoid copying data
  • your storage is very large
  • you must preserve the original data directory exactly
  • you removed the cluster but kept the PV


Overview
 

Before you begin

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS

Step 1. Deploy the Crunchy and Percona operators

Both operators run in the same namespace. Crunchy PGO is uninstalled during the migration once the PV is retained.

Note (Crunchy): The Helm install for Crunchy PGO below is shown only as a quick way to reproduce this blog post’s example. If you are running Crunchy PGO in production, follow the official Crunchy Data documentation for installation. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Note (Percona): The kubectl apply of the Percona operator below uses defult configuration of v3.0.0 from the operator repo for reproducibility of this guide. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation to ensure the cluster configuration is properly sized and configured for your workload and traffic requirements.

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

kubectl wait deployment pgo \
  -n $MIGRATION_NS --for=condition=Available --timeout=120s

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS --for=condition=Available --timeout=120s

Step 2. Start the Crunchy source cluster

If you already have a running Crunchy cluster with replicas: 1, proceed to Step 3.

To start a fresh cluster for testing:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/01-crunchy-source-cluster.yaml

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s

Step 3. Stop writes and identify the primary PV

Stop your application from writing to the database. This is the start of the downtime window. Then identify the primary pod, its PVC, and the backing PV:

PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -o jsonpath='{.items[0].metadata.name}')

PVC_NAME=$(kubectl get pod -n $MIGRATION_NS "${PRIMARY}" \
  -o jsonpath='{.spec.volumes[?(@.name=="postgres-data")].persistentVolumeClaim.claimName}')

PV_NAME=$(kubectl get pvc -n $MIGRATION_NS "${PVC_NAME}" \
  -o jsonpath='{.spec.volumeName}')

echo "Primary pod: ${PRIMARY}"
echo "PVC:         ${PVC_NAME}"
echo "PV:          ${PV_NAME}"

Step 4. Configure the source cluster to retain PVs

If you want to delete the Crunchy source cluster but keep the persistent volumes, the PV reclaim policy must be set to Retain. For dynamically provisioned PersistentVolumes, the default reclaim policy is Delete, which removes the data once there are no more PersistentVolumeClaims associated with the PV.

kubectl patch pv "${PV_NAME}" \
  -p '{"spec":{"persistentVolumeReclaimPolicy":"Retain"}}'

kubectl get pv -n $MIGRATION_NS

Delete the Crunchy cluster and uninstall PGO:

kubectl patch postgrescluster crunchy-source -n $MIGRATION_NS \
  --type=json -p='[{"op":"remove","path":"/metadata/finalizers"}]' 2>/dev/null || true

kubectl delete postgrescluster crunchy-source -n $MIGRATION_NS
helm uninstall pgo -n $MIGRATION_NS

After the PVC is deleted, the PV enters Released state. A Released PV retains its old claimRef and cannot be claimed by a new PVC until it is cleared:

kubectl patch pv "${PV_NAME}" --type=json \
  -p='[{"op":"remove","path":"/spec/claimRef"}]'

kubectl wait pv "${PV_NAME}" \
  --for=jsonpath='{.status.phase}'=Available \
  --timeout=60s

Label the PV so the Percona PVC selector binds to it exclusively. This prevents accidental binding to another available volume:

kubectl label pv "${PV_NAME}" percona-pv-migration=migrated


Step 5. Create the Percona cluster with the retained volume

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/02-percona-migrated-cluster.yaml

The key section that binds the PVC to the labelled PV:

instances:
  - name: instance1
    replicas: 1
    dataVolumeClaimSpec:
      selector:
        matchLabels:
          percona-pv-migration: migrated

The Percona Operator creates a PVC with that selector. The PVC binds to the labelled PV, and PostgreSQL starts on the existing PGDATA directory with no restore needed. pgBackRest uses a local PVC-backed repository (repo1.volume), so no S3 credentials or external storage are required, but you can use S3 storage as well.

Wait for the cluster to become ready and verify the data is intact:

kubectl wait perconapgcluster/percona-migrated \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-migrated,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f. The cluster is the primary and accepts writes.

Step 6. Scale up replicas

The cluster started with a single replica to reuse the migrated PV. Once the primary is healthy, drop the PVC selector and scale out so the operator can provision fresh replica volumes from the storage class:

kubectl patch perconapgcluster percona-migrated \
  --namespace $MIGRATION_NS \
  --type=json \
  -p='[
    {"op":"remove","path":"/spec/instances/0/dataVolumeClaimSpec/selector"},
    {"op":"replace","path":"/spec/instances/0/replicas","value":3}
  ]'

kubectl wait perconapgcluster/percona-migrated \
  --namespace $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=300s

Removing the selector here is important: leaving it in place would cause the new replica PVCs to fail provisioning because no other PV carries the migration label.

Step 7. Take a post-migration backup

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/03-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates the first backup on the Percona cluster’s local pgBackRest repository, establishing a baseline for future PITR restores.

Step 8. Reconnect your application

kubectl get service -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-migrated,postgres-operator.crunchydata.com/role=pgbouncer

Step 9. Cleanup

After the migration is verified, remove the migration label from the PV (Step 6 already removed the PVC selector that depended on it):

kubectl label pv "${PV_NAME}" percona-pv-migration-


Rollback

PV migration is the least rollback-friendly of the three methods. Once the Percona cluster has started writing to the PGDATA directory, the original Crunchy timeline is gone. If you need a way back, take a Crunchy-side pgBackRest backup before Step 4 and treat that backup as your rollback point. Recovery is then a fresh Crunchy cluster restored from that backup.

Troubleshooting

PVC stays in Pending state. The PVC selector did not match the labelled PV. Verify the label and PV phase:

kubectl get pv "${PV_NAME}" --show-labels
kubectl get pv "${PV_NAME}" -o jsonpath='{.status.phase}'

PostgreSQL fails to start (data directory errors). Check the database container logs:

kubectl -n $MIGRATION_NS logs "${PERCONA_PRIMARY}" -c database

If the Crunchy cluster was shut down uncleanly, there may be incomplete WAL. Patroni will attempt crash recovery automatically; check the logs for progress.

PV was deleted before setting Retain. If the PV was deleted along with the PVC (default Delete policy), the data is gone and PV migration is no longer possible. Use the backup-and-restore migration above, restoring from the most recent pgBackRest backup.


Conclusion

Two more migration paths from the Crunchy Data PostgreSQL Operator to the fully open-source Percona PostgreSQL Operator. Combined with Part 2, the series gives you three production-tested options:

  • Standby cluster (part 2): near-zero downtime via streaming replication and pgBackRest standby
  • Backup and restore (this post): the simplest path, restoring directly from a Crunchy pgBackRest backup
  • Persistent volume reuse (this post): when you want to keep storage and skip the data copy

All three approaches are safe, predictable, and reversible, with the rollback caveats noted in each section. Because Percona’s operator, images, and tooling are 100 percent open source, you keep full control: you can always migrate back to the Crunchy operator, or out to another open-source operator (Zalando, StackGres, CloudNativePG) using the same patterns. That last journey is a topic for a future post.

This post covers basic deployment patterns and simplified configuration examples. If your environment uses custom images, Crunchy enterprise features, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Backup-Restore and PV Reuse appeared first on Percona.
May
24
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method

A Crunchy to Percona PostgreSQL migration is more straightforward than most cross-operator moves on Kubernetes, because the Percona PostgreSQL Operator is a hard fork of the Crunchy Data PostgreSQL Operator. Same Patroni HA, same pgBackRest backups, same overall CRD shape. This post walks through the safest of the three migration paths: a standby cluster method with near-zero downtime.

This is part 2 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0.

This post is the first practical playbook of the series. It covers the standby cluster method, the safest migration path when the downtime budget is tight. Part 3 will cover two simpler paths: backup-and-restore and persistent-volume reuse.

If you are landing here without context on why you might want to migrate at all, start with part 1. The rest of this post assumes you have already decided to move and want a tested playbook.


Migration approach in one paragraph

The Percona PostgreSQL Kubernetes Operator is a hard fork of the Crunchy Data PostgreSQL Kubernetes Operator, which simplifies the migration paths considerably: the same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both operators. All three migration paths in this series are reversible: because Percona’s operator is fully open source and remains compatible with the same backup format, the move back to Crunchy is also possible if your team decides to walk it


A note on the storage layer

All examples in this guide use an in-cluster SeaweedFS instance as the pgBackRest S3 repository. SeaweedFS is Apache-2.0 licensed, actively maintained, and a clean drop-in replacement for the role MinIO used to fill in this stack. Any other S3-compatible storage works just as well: AWS S3, Google Cloud Storage (via HMAC keys), Ceph RadosGW, Cloudflare R2, and so on. For non-SeaweedFS endpoints, remove repo1-s3-uri-style: path and repo1-s3-verify-tls: “n” from the pgBackRest configuration and replace the endpoint with your provider’s URL.


What this series does NOT cover

To keep scope honest:

  • Application-side connection-string changes beyond updating to the new pgBouncer service. If your app uses connection-pool tuning, custom auth, or a service mesh, that work stays with you.
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations. The PostgreSQL major version must match between the source and the target.
  • Crunchy enterprise-only features like TDE, Crunchy Postgres for Kubernetes-specific operators, or pgBackRest custom encryption. If your environment uses these, contact the Percona team for a tailored plan.
  • Operating two operators against the same namespace before the PGO hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any other S3-compatible service accessible from all cluster pods
Tools kubectl, helm (v3), yq

Different versions may differ slightly in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


Migration using a standby cluster

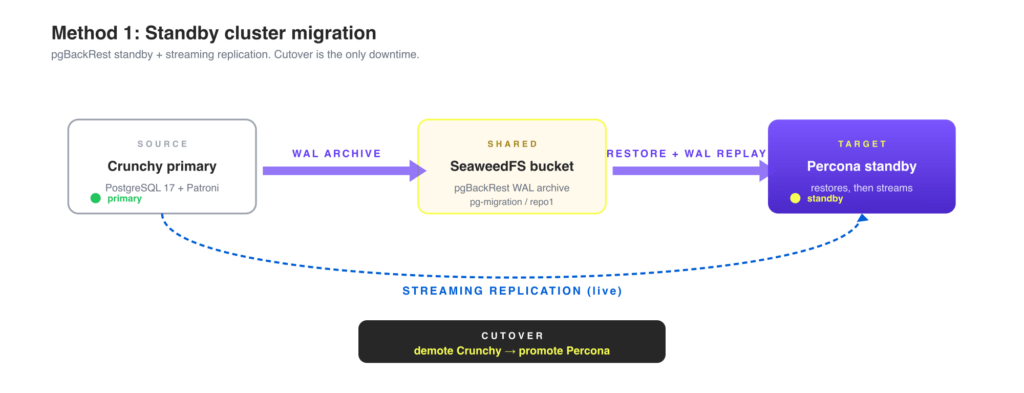
This is the safest method when the downtime budget is tight. The Percona cluster is brought up as a standby of the Crunchy primary, catches up via pgBackRest plus streaming replication, and is promoted at cutover. The only downtime is the cutover step itself.

You can wire the standby in two ways, and combining both gives you maximum safety:

  • pgBackRest repo-based standby seeds the standby from the latest base backup and replays archived WAL
  • Streaming replication keeps the standby in sync with the live primary


Overview


Before you begin

Set the target namespace once. Every command in this guide reads from this variable, so you can change it in a single place:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: “n” is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.


Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secret.yaml after filling in your access key and secret key:

# Copy and edit the file first to set your credentials.

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/01-pgbackrest-secret.yaml

Both secrets contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket and path. The repo1-path value must be identical in both cluster specs. Mismatched paths will prevent the Percona standby from finding the WAL archive.

The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Optional: deploy a Crunchy operator to test the migration end to end:

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait


Apply
examples/02-crunchy-source-cluster.yaml (or adapt your existing cluster’s pgBackRest config):

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/02-crunchy-source-cluster.yaml


The key pgBackRest settings in the example:

global:
  repo1-path: /crunchy-to-percona/repo1   # shared path, must match Percona side
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1


Wait for the cluster to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  --namespace $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s


Step 2. Trigger a full backup on the Crunchy cluster

Wait for the pgBackRest stanza to be created:

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Take a full backup before creating the Percona standby. This gives the standby a recent base to restore from, so it only needs to replay a small amount of WAL to catch up. This matches the realistic production migration pattern.

kubectl annotate postgrescluster crunchy-source \
  --namespace $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"


Wait for the backup job to complete:

kubectl wait job \
  -l postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Copy TLS certificates (cross-namespace only)

If the Percona cluster is in a different namespace from the Crunchy cluster, copy the Crunchy TLS secrets to the Percona namespace. These allow mutual TLS authentication during streaming replication:

for secret in crunchy-source-cluster-cert crunchy-source-replication-cert; do
  kubectl get secret "${secret}" -n <CRUNCHY_NS> -o json | \
    yq '{"apiVersion": .apiVersion, "kind": .kind, "data": .data,
         "metadata": {"name": .metadata.name}, "type": .type}' -o yaml | \
    kubectl -n $MIGRATION_NS apply -f -
done

If both clusters are in the same namespace, skip this step. The secrets are already accessible.


Step 4. Deploy the Percona PG Operator

The Crunchy PGO operator can stay in the same or a different namespace.

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

Wait until the operator deployment is ready:

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s


Step 5. Create the Percona cluster in standby mode

Note: The kubectl apply below pulls the CR manifest from the migration-from-crunchy-guide branch of the operator repo, which is the source for this guide’s examples. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation and pin to a released version tag rather than a feature branch.

Apply examples/03-percona-standby-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/03-percona-standby-cluster.yaml

The key settings that wire the Percona cluster to the Crunchy source:

standby:
  enabled: true
  repoName: repo1                             # restore initial base backup from this repo
  host: crunchy-source-ha.postgres-migration.svc.cluster.local
  port: 5432

secrets:
  customTLSSecret:
    name: crunchy-source-cluster-cert         # Crunchy CA for mutual TLS
  customReplicationTLSSecret:
    name: crunchy-source-replication-cert     # cert for _crunchyreplication user

The Percona operator will:

  1. Restore the base backup from the SeaweedFS bucket.
  2. Replay WAL from SeaweedFS until it catches up with the live Crunchy cluster.
  3. Switch to streaming replication from crunchy-source-ha.

Wait for the cluster to reach the ready state:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify that data is replicating to the standby:

STANDBY_POD=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/data=postgres \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery(), pg_last_wal_replay_lsn();"

Expected output: t (in recovery) and a non-null LSN.


Step 6. Verify replication lag before cutover

Query the Crunchy primary to confirm the Percona standby has caught up:

CRUNCHY_PRIMARY=$(kubectl get pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -c "
    SELECT
        client_addr,
        state,
        pg_wal_lsn_diff(sent_lsn, replay_lsn) AS byte_lag,
        write_lag,
        flush_lag,
        replay_lag
    FROM pg_stat_replication;
  "

Proceed to the next step only when write_lag and replay_lag are NULL or under a few seconds.


Step 7. Cutover the Crunchy cluster

This is the only step that causes downtime. Stop accepting writes on the application side, then patch the Crunchy cluster into standby mode. Patroni steps down and archives the final WAL.

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": true, "repoName": "repo1"}}}'

Verify demotion (poll until pg_is_in_recovery() returns t):

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"


Step 8. (Optional) Shut down the Crunchy cluster

Once the Percona standby has replayed all WAL, shut down the Crunchy cluster to prevent split-brain:

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"shutdown": true}}'

kubectl wait pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=delete \
  --timeout=120s || true


Step 9. Promote the Percona cluster

Confirm that the Percona standby has finished replaying all WAL (the LSN stops advancing):

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_last_wal_replay_lsn();"

Run this a few times. When the LSN is stable, replay is complete.

kubectl patch perconapgcluster percona-standby \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": false}}}'

Wait for the cluster to become ready and confirm it is writable:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=480s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f (the cluster is now the primary and accepts writes).


Step 10. Verify stanza creation

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 11. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery point on the new timeline. All future PITR restores will use this backup as their starting point, independent of the old Crunchy WAL archive.


Reconnecting your application

Update your application’s connection string to point at the Percona cluster’s pgBouncer service:

kubectl get service -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=pgbouncer

This migration path works almost entirely out of the box. For users coming from the Crunchy Data PostgreSQL Operator, this method feels familiar because it leverages the same standby/replica mechanisms used for HA and disaster recovery. The key difference is that you can now use this familiar mechanism to migrate safely to the Percona PostgreSQL Operator, a fully open-source alternative running on a fully open-source storage layer.


Rollback

The standby method is the most rollback-friendly of the three. Until you take the post-migration backup, the Crunchy cluster still holds the original timeline. To roll back:

  1. Stop writes on the Percona side and patch the Percona cluster back into standby mode (spec.standby.enabled: true).
  2. Patch the Crunchy cluster out of standby mode and let Patroni promote it.
  3. Verify with pg_is_in_recovery() on both sides.
  4. Switch the application connection string back to the Crunchy pgBouncer service.

After Step 11 (post-migration backup), the timelines have diverged. From that point, the rollback story is the same as a fresh restore, and you should treat the Crunchy cluster as a historical reference, not a live target.


Troubleshooting

Percona standby not connecting to the Crunchy primary. Verify the crunchy-source-ha service resolves from within the Percona pod:

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  bash -c "getent hosts crunchy-source-ha.${MIGRATION_NS}.svc.cluster.local"

Replication authentication errors. The Percona standby authenticates as the _crunchyreplication PostgreSQL user using the certificate in crunchy-source-replication-cert. Verify the secret exists and matches what the Crunchy operator generated:

kubectl get secret crunchy-source-replication-cert -n $MIGRATION_NS

pgBackRest restore fails. Confirm both secrets contain identical credentials and that repo1-path is the same in both cluster specs (/crunchy-to-percona/repo1 in this guide). Mismatched paths cause an archive.info missing error. Verify the bucket is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "

Timeline history file (00000002.history) missing after promotion. This is a known issue with Crunchy PGO’s async archive mode. After promotion, push the history file synchronously:

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  bash -c "
    pgbackrest --stanza=db --no-archive-async \
      archive-push \"\${PGDATA}/pg_wal/00000002.history\" || true
  "


What’s next

This was the safest migration path. Part 3 will cover two simpler options:

  • Backup and restore. The simplest path. You take a Crunchy pgBackRest backup and the Percona cluster bootstraps from it. Cutover is the time between the final backup and pointing the application at the new cluster.
  • Persistent volume reuse. For when you want to skip the data copy entirely. The Percona cluster takes over the existing PGDATA volume, no restore step required.

Pick the method that fits your downtime budget, data size, and storage layout.

This post covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method appeared first on Percona.

Oct
31
2025
--

How to Configure pgBackRest Backups and Restores in PostgreSQL (Local/k8s) Using a MinIO Object Store

How to Configure pgBackRestThis blog post explains how to configure and use MinIO as S3-compatible storage for managing PostgreSQL backups, and how to perform data restoration and recovery in both standalone (local) and Kubernetes environments.

Nov
30
2023
--

Enhancing PostgreSQL Security: How to Encrypt the pgBackRest Repository

Encrypt the pgBackRest Repository

Encryption is the process of turning data into an unrecognizable format unless the necessary password (also known as passphrase) or decryption key is provided.

This blog describes how to encrypt the pgBackRest repository. pgBackRest is the backup tool used to perform Postgres database backup, restoration, and point-in-time recovery (PITR). The repository is where pgBackRest stores backups and archives WAL segments.

pgBackRest will encrypt the repository based on a user-provided password, thereby preventing unauthorized access to data stored within the repository.

In this demonstration, it is assumed that the pgBackRest is already installed and configured on the dedicated backup node and configured to take backups from the remote database node. The repository will be configured with a cipher type and key to demonstrate encryption. 

Follow the below steps to encrypt the pgBackRest repository:

Backup node 172.20.20.20 (Dummy IP) 

Remote DB node  172.15.15.15 (Dummy IP)

1) First, generate the cipher key. pgBackRest will use this cipher key to encrypt the pgBackRest repository.

It is important to use a long, random passphrase for the cipher key. A good way to generate one is to run: openssl rand -base64 48. (on the backup node):

postgres@ip-172.20.20.20:~$ openssl rand -base64 48
PNaf798o9Sz1RRRRRRRRhH62R1BSQal+lAxpb3ZTAblNPTxC72E1nAcQGVwn40co
postgres@ip-172.20.20.20:~$

2) On the backup node, add the cipher type and key parameters in the pgBackRest configuration file. /etc/pgbackrest.conf:

vi /etc/pgbackrest.conf
repo1-cipher-pass=PNaf798o9Sz1RRRRRRRRhH62R1BSQal+lAxpb3ZTAblNPTxC72E1nAcQGVwn40co
repo1-cipher-type=aes-256-cbc

If you have an existing pgbackrest setup, then the existing stanza cannot be used after configuring the encryption for the repository. A new stanza needs to be created for taking the backup in the encryption-enabled repository. Using the existing stanza will result in the following error:

In the below example, the existing stanza dbtest has been used.

postgres@ip-172.20.20.20:~$ pgbackrest --config=/etc/pgbackrest.conf --stanza=dbtest --log-level-console=info backup --type=full
2023-09-08 14:22:06.178 P00   INFO: backup command begin 2.47: --config=/etc/pgbackrest.conf --exec-id=5971-2fe78c47 
--log-level-console=info --log-level-file=debug--pg1-host=172.15.15.15 --pg1-host-user=postgres --pg1-path=/var/lib/postgresql/15/main
 --process-max=2 --repo1-cipher-pass=<redacted> --repo1-cipher-type=aes-256-cbc --repo1-path=/var/lib/pgbackrest
 --repo1-retention-full=2 --stanza=dbtest --start-fast --stop-auto --type=full
ERROR: [095]: unable to load info file '/var/lib/pgbackrest/backup/dbtest/backup.info' or '/var/lib/pgbackrest/backup/dbtest/
backup.info.copy':
       CryptoError: cipher header invalid
       HINT: is or was the repo encrypted?
       CryptoError: cipher header invalid
       HINT: is or was the repo encrypted?
       HINT: backup.info cannot be opened and is required to perform a backup.
       HINT: has a stanza-create been performed?
2023-09-08 14:22:06.180 P00   INFO: backup command end: aborted with exception [095]
postgres@ip-172.20.20.20:~$

The pgBackRest configuration files will look like this after adding the cypher pass (key) and type.

Backup node

cat /etc/pgbackrest.conf:
[global]
repo1-path=/var/lib/pgbackrest
repo1-retention-full=2
process-max=2
log-level-console=info
log-level-file=debug
start-fast=y
stop-auto=y
repo1-cipher-pass=PNaf798o9Sz1RRRRRRRRhH62R1BSQal+lAxpb3ZTAblNPTxC72E1nAcQGVwn40co
repo1-cipher-type=aes-256-cbc
[dbtest_new]
pg1-path=/var/lib/postgresql/15/main
pg1-host=172.15.15.15
pg1-host-user=postgres

DB node

cat /etc/pgbackrest.conf:
[global]
repo1-path=/var/lib/pgbackrest
repo1-host=172.20.20.20
repo1-host-user=postgres
process-max=2
log-level-console=info
log-level-file=debug
[dbtest_new]
pg1-path=/var/lib/postgresql/15/main

3) Create a new stanza (on the backup node):

postgres@ip-172.20.20.20:~$ pgbackrest --config=/etc/pgbackrest.conf --stanza=dbtest_new  stanza-create
2023-09-08 14:24:55.779 P00   INFO: stanza-create command begin 2.47: --config=/etc/pgbackrest.conf --exec-id=5980-f29c6484
 --log-level-console=info --log-level-file=debug --pg1-host=172.15.15.15 --pg1-host-user=postgres
 --pg1-path=/var/lib/postgresql/15/main --repo1-cipher-pass=<redacted> --repo1-cipher-type=aes-256-cbc
 --repo1-path=/var/lib/pgbackrest --stanza=dbtest_new
2023-09-08 14:24:56.927 P00   INFO: stanza-create for stanza 'dbtest_new' on repo1
2023-09-08 14:24:57.045 P00   INFO: stanza-create command end: completed successfully (1269ms)
postgres@ip-172.20.20.20:~$

4) Update the archive_command with the new stanza details on the DB node:

postgres=# ALTER SYSTEM SET archive_command = '/bin/pgbackrest --config=/etc/pgbackrest.conf --stanza=dbtest_new archive-push %p';
ALTER SYSTEM

5) Reload the Postgres cluster (on the DB node):

postgres=# select pg_reload_conf();
pg_reload_conf
----------------
 t
(1 row)

6) Execute the check command. The check command validates that pgBackRest and the archive_command setting are configured correctly for archiving and backups for the specified stanza:

postgres@ip-172.20.20.20:~$ pgbackrest --config=/etc/pgbackrest.conf --stanza=dbtest_new --log-level-console=info check
2023-09-08 15:26:34.349 P00   INFO: check command begin 2.47: --config=/etc/pgbackrest.conf --exec-id=7993-5acde7b9
 --log-level-console=info --log-level-file=debug --pg1-host=172.15.15.15 --pg1-host-user=postgres
 --pg1-path=/var/lib/postgresql/15/main --repo1-cipher-pass=<redacted> --repo1-cipher-type=aes-256-cbc
 --repo1-path=/var/lib/pgbackrest --stanza=dbtest_new
2023-09-08 15:26:35.585 P00   INFO: check repo1 configuration (primary)
2023-09-08 15:26:35.788 P00   INFO: check repo1 archive for WAL (primary)
2023-09-08 15:26:36.990 P00   INFO: WAL segment 000000010000000000000018 successfully archived to 
'/var/lib/pgbackrest/archive/dbtest_new/15-1/0000000100000000/000000010000000000000018-7cef04977b8b50f102a3d74ace8ab1cc4a035c8d.gz' 
on repo1
2023-09-08 15:26:37.092 P00   INFO: check command end: completed successfully (2745ms)
postgres@ip-172.20.20.20:~$

7) Perform a FULL backup:

postgres@ip-172.20.20.20:~$ pgbackrest --config=/etc/pgbackrest.conf --stanza=dbtest_new --log-level-console=info backup --type=full
2023-09-08 15:26:49.028 P00   INFO: backup command begin 2.47: --config=/etc/pgbackrest.conf --exec-id=8060-e6fa0627
 --log-level-console=info --log-level-file=debug --pg1-host=172.15.15.15 --pg1-host-user=postgres
 --pg1-path=/var/lib/postgresql/15/main --process-max=2 --repo1-cipher-pass=<redacted> --repo1-cipher-type=aes-256-cbc
 --repo1-path=/var/lib/pgbackrest --repo1-retention-full=2 --stanza=dbtest_new --start-fast --stop-auto --type=full
2023-09-08 15:26:50.016 P00 INFO: execute non-exclusive backup start: backup begins after the requested immediate checkpoint completes
2023-09-08 15:26:50.622 P00   INFO: backup start archive = 00000001000000000000001A, lsn = 0/1A000028
2023-09-08 15:26:50.622 P00   INFO: check archive for prior segment 000000010000000000000019
2023-09-08 15:26:54.242 P00   INFO: execute non-exclusive backup stop and wait for all WAL segments to archive
2023-09-08 15:26:54.447 P00   INFO: backup stop archive = 00000001000000000000001A, lsn = 0/1A000100
2023-09-08 15:26:54.454 P00   INFO: check archive for segment(s) 00000001000000000000001A:00000001000000000000001A
2023-09-08 15:26:54.970 P00   INFO: new backup label = 20230908-152649F
2023-09-08 15:26:55.024 P00   INFO: full backup size = 22.0MB, file total = 961
2023-09-08 15:26:55.024 P00   INFO: backup command end: completed successfully (5999ms)
2023-09-08 15:26:55.025 P00   INFO: expire command begin 2.47: --config=/etc/pgbackrest.conf --exec-id=8060-e6fa0627
 --log-level-console=info --log-level-file=debug --repo1-cipher-pass=<redacted> --repo1-cipher-type=aes-256-cbc
 --repo1-path=/var/lib/pgbackrest --repo1-retention-full=2 --stanza=dbtest_new
2023-09-08 15:26:55.026 P00   INFO: repo1: expire full backup 20230908-145538F
2023-09-08 15:26:55.035 P00   INFO: repo1: remove expired backup 20230908-145538F
2023-09-08 15:26:55.068 P00   INFO: repo1: 15-1 remove archive, start = 000000010000000000000015, stop = 000000010000000000000016
2023-09-08 15:26:55.068 P00   INFO: expire command end: completed successfully (43ms)
postgres@ip-172.20.20.20:~$

8) Perform a DIFFERENTIAL backup (optional step):

postgres@ip-172.20.20.20:~$ pgbackrest --config=/etc/pgbackrest.conf --stanza=dbtest_new --log-level-console=info backup --type=diff
2023-09-08 15:27:01.723 P00   INFO: backup command begin 2.47: --config=/etc/pgbackrest.conf --exec-id=8216-4d363fc8 
--log-level-console=info --log-level-file=debug --pg1-host=172.15.15.15 --pg1-host-user=postgres 
--pg1-path=/var/lib/postgresql/15/main --process-max=2 --repo1-cipher-pass=<redacted> --repo1-cipher-type=aes-256-cbc 
--repo1-path=/var/lib/pgbackrest --repo1-retention-full=2 --stanza=dbtest_new --start-fast --stop-auto --type=diff
2023-09-08 15:27:02.644 P00   INFO: last backup label = 20230908-152649F, version = 2.47
2023-09-08 15:27:02.645 P00   INFO: execute non-exclusive backup start: backup begins after the requested immediate checkpoint completes
2023-09-08 15:27:03.250 P00   INFO: backup start archive = 00000001000000000000001C, lsn = 0/1C000028
2023-09-08 15:27:03.251 P00   INFO: check archive for prior segment 00000001000000000000001B
2023-09-08 15:27:04.810 P00   INFO: execute non-exclusive backup stop and wait for all WAL segments to archive
2023-09-08 15:27:05.012 P00   INFO: backup stop archive = 00000001000000000000001C, lsn = 0/1C000100
2023-09-08 15:27:05.017 P00   INFO: check archive for segment(s) 00000001000000000000001C:00000001000000000000001C
2023-09-08 15:27:05.536 P00   INFO: new backup label = 20230908-152649F_20230908-152702D
2023-09-08 15:27:05.591 P00   INFO: diff backup size = 8.3KB, file total = 961
2023-09-08 15:27:05.592 P00   INFO: backup command end: completed successfully (3872ms)
2023-09-08 15:27:05.592 P00   INFO: expire command begin 2.47: --config=/etc/pgbackrest.conf --exec-id=8216-4d363fc8 
--log-level-console=info --log-level-file=debug --repo1-cipher-pass=<redacted> --repo1-cipher-type=aes-256-cbc 
--repo1-path=/var/lib/pgbackrest --repo1-retention-full=2 --stanza=dbtest_new
2023-09-08 15:27:05.602 P00   INFO: repo1: 15-1 no archive to remove
2023-09-08 15:27:05.603 P00   INFO: expire command end: completed successfully (11ms)
postgres@ip-172.20.20.20:~$

9) To check out the backup status and its details, use the info command:

postgres@ip-172.20.20.20:~$ pgbackrest --config=/etc/pgbackrest.conf --stanza=dbtest_new info
stanza: dbtest_new
    status: ok
    cipher: aes-256-cbc
    db (current)
        wal archive min/max (15): 000000010000000000000017/00000001000000000000001C
        full backup: 20230908-151854F
            timestamp start/stop: 2023-09-08 15:18:54+00 / 2023-09-08 15:18:59+00
            wal start/stop: 000000010000000000000017 / 000000010000000000000017
            database size: 22.0MB, database backup size: 22.0MB
            repo1: backup set size: 2.9MB, backup size: 2.9MB
        full backup: 20230908-152649F
            timestamp start/stop: 2023-09-08 15:26:49+00 / 2023-09-08 15:26:54+00
            wal start/stop: 00000001000000000000001A / 00000001000000000000001A
            database size: 22.0MB, database backup size: 22.0MB
            repo1: backup set size: 2.9MB, backup size: 2.9MB
        diff backup: 20230908-152649F_20230908-152702D
            timestamp start/stop: 2023-09-08 15:27:02+00 / 2023-09-08 15:27:04+00
            wal start/stop: 00000001000000000000001C / 00000001000000000000001C
            database size: 22.0MB, database backup size: 8.3KB
            repo1: backup set size: 2.9MB, backup size: 512B
            backup reference list: 20230908-152649F
postgres@ip-172.20.20.20:~$

Conclusion

pgBackRest is a completely free and open source backup tool available for PostgreSQL, and here we have seen the steps to encrypt the pgBackRest repository. You may use it for personal or commercial purposes without any restrictions whatsoever. Its advanced backup repository encryption feature is very easy to implement. 

To learn more about the pgBackRest backup tool and encryption, click the links below: 


Percona Distribution for PostgreSQL provides the best and most critical enterprise components from the open-source community, in a single distribution, designed and tested to work together.


Download Percona Distribution for PostgreSQL Today!

Mar
28
2023
--

What if the Backup Server Is Down and a Backup Is Needed? (Multi-repo Functionality of PgBackRest)

Multi Repo Functionality of PgBackRest

Our previous blogs discussed configuring and setting up backups using the pgBackRest solution. To briefly explain pgBackRest, it is an open source backup tool that takes FULL Backup, Incremental Backup, and Differential Backup for PostgreSQL databases.

Repository means the location/path on the server or the cloud where the actual copy of the backup will reside. In this blog, we will specifically discuss one of the important features of the pgBackRest called Multiple Repository (or, in short, Multi Repo). This attribute helps take the redundant copies of the databases at multiple locations remotely on different servers or locally on the same server.

Let’s discuss a few scenarios one by one.

Scenarios:
1. Behavior of pgBackRest with single repo
2. Behavior of pgBackRest with multiple repos
2.1. Configuring archives redundantly (async=y)
2.2. Taking backup locally with multiple repos
2.3. Taking backup locally and remotely on the cloud
2.4. Take backup locally and in multiple clouds

Pre-configured Setup:
>PostgreSQL installed and configured on the database host.
>pgBackRest is installed and configured on a dedicated backup and database host.

Scenario – 1: Behavior of pgBackRest with single repo

By default, pgBackRest takes backups in a single repository or location, which can reside locally on the same server, remote server, or cloud.

Below is the configuration file, which is normally configured for taking backups with single repo:

Backup Host: DB Host:
[global]
repo1-path=/var/lib/pgbackrest_repo1
repo1-retention-full=2
repo1-host-user=postgres
log-level-console=info
log-level-file=debug
start-fast=y
[pgstanza]
pg1-path=/var/lib/postgresql/15/main
pg1-host=18.210.15.186
[global]
repo1-host=172.31.54.194
repo1-path=/var/lib/pgbackrest_repo1
repo1-retention-full=2
repo1-host-user=postgres
log-level-console=info
log-level-file=debug
[pgstanza]
pg1-path=/var/lib/postgresql/15/main


This configuration file contains details about the global section having common parameters like repo details, log details, etc. Even though there is a single repository, the parameter’s name starts from “repo1” to accommodate as many repositories as possible. Here, the backup will be stored on the local backup host at the /var/lib/pgbackrest_repo1 path that is already created with the proper user (in this case, Postgres) and permissions.

[pgstanza] is the name of the stanza for which backup is taken. For the sake of simplicity, we are considering backup for one DB Server only.

Let’s take the backup using the pgbackrest command:

On the Backup Host:

postgres@ip-172-31-54-194:~$ pgbackrest --stanza=pgstanza --log-level-console=info --type=full backup
2023-03-23 04:19:14.059 P00 INFO: backup command begin 2.44: --exec-id=157866-5813ef0e --log-level-console=info --log-level-file=debug --pg1-host=18.210.15.186 --pg1-path=/var/lib/postgresql/15/main --repo1-path=/var/lib/pgbackrest_repo1 --repo1-retention-full=2 --stanza=pgstanza --start-fast --type=full
2023-03-23 04:19:15.315 P00 INFO: execute non-exclusive backup start: backup begins after the requested immediate checkpoint completes
2023-03-23 04:19:15.822 P00 INFO: backup start archive = 000000010000000000000039, lsn = 0/39000028
2023-03-23 04:19:15.822 P00 INFO: check archive for prior segment 000000010000000000000038
2023-03-23 04:19:23.184 P00 INFO: execute non-exclusive backup stop and wait for all WAL segments to archive
2023-03-23 04:19:23.386 P00 INFO: backup stop archive = 000000010000000000000039, lsn = 0/39000138
2023-03-23 04:19:23.394 P00 INFO: check archive for segment(s) 000000010000000000000039:000000010000000000000039
2023-03-23 04:19:23.711 P00 INFO: new backup label = 20230323-041915F
2023-03-23 04:19:23.790 P00 INFO: full backup size = 22.0MB, file total = 961
2023-03-23 04:19:23.790 P00 INFO: backup command end: completed successfully (9733ms)
2023-03-23 04:19:23.791 P00 INFO: expire command begin 2.44: --exec-id=157866-5813ef0e --log-level-console=info --log-level-file=debug --repo1-path=/var/lib/pgbackrest_repo1 --repo1-retention-full=2 --stanza=pgstanza
2023-03-23 04:19:23.792 P00 INFO: repo1: expire full backup 20230323-040330F
2023-03-23 04:19:23.806 P00 INFO: repo1: remove expired backup 20230323-040330F
2023-03-23 04:19:23.829 P00 INFO: repo1: 15-1 remove archive, start = 000000010000000000000035, stop = 000000010000000000000036
2023-03-23 04:19:23.830 P00 INFO: expire command end: completed successfully (39ms)

As shown below, the backup goes into the local directory, and inside that, we have two directories as below:

>backup – contains backup when FULL/INCR/DIFF backup is taken
>archive – contains archives that help in PITR

postgres@ip-172-31-54-194:~$ cd /var/lib/pgbackrest_repo1
postgres@ip-172-31-54-194:/var/lib/pgbackrest_repo1$ ls -ltr
total 8
drwxr-x--- 3 postgres postgres 4096 Feb 15 13:16 archive
drwxr-x--- 3 postgres postgres 4096 Feb 15 13:16 backup
postgres@ip-172-31-54-194:/var/lib/pgbackrest_repo1$

Scenario – 2: Behavior of pgBackRest with multiple repo

Multiple Repository (or multi-repo) functionalities of pgBackRest support different combinations of storing redundant backup copies. In this section, we have discussed a few of the most useful combinations where multiple backup copies can be stored.

2.1 Configuring Asynchronous archiving (archive-async=y)
Wal files redundancy in the two different repos is possible by using asynchronous archiving.
This (archive-async=y) parameter allows the archive-push and archive-get commands to work asynchronously.

When this parameter is enabled, the pgBackRest will copy the wal files into both the repos. The example below shows that the pgBackRest is archiving the wal files into two different repos.

--repo1-path=/var/lib/pgbackrest_repo1
--repo2-path=/var/lib/pgbackrest_repo2

If the first repo is unavailable and the second repo is available, then, in this case, the pgBackRest will continue copying/archiving the wal files to the second repo. Still, It will accumulate those wal files in the pg_wal directory not archived in the first repo.

A spool path (spool-path) parameter is necessary when asynchronous archiving is enabled. The current WAL archiving status is getting stored in the spool path.

We can track the activities of the asynchronous process in the [stanza]-archive-push-async.log file.

On the Backup Host:
postgres@ip-172-31-54-194:~$ pgbackrest --stanza=pgstanza --log-level-console=info check
2023-03-23 04:35:59.074 P00 INFO: check command begin 2.44: --exec-id=158656-d4a8f71e --log-level-console=info --log-level-file=debug --pg1-host=18.210.15.186 --pg1-path=/var/lib/postgresql/15/main --repo1-path=/var/lib/pgbackrest_repo1 --repo2-path=/var/lib/pgbackrest_repo2 --stanza=pgstanza
2023-03-23 04:35:59.920 P00 INFO: check repo1 configuration (primary)
2023-03-23 04:35:59.921 P00 INFO: check repo2 configuration (primary)
2023-03-23 04:36:00.124 P00 INFO: check repo1 archive for WAL (primary)
2023-03-23 04:36:01.327 P00 INFO: WAL segment 00000001000000000000003C successfully archived to '/var/lib/pgbackrest_repo1/archive/pgstanza/15-1/0000000100000000/00000001000000000000003C-6aa2de4dca50db51592d139010bdfb7a8c2c45ce.gz' on repo1
2023-03-23 04:36:01.328 P00 INFO: check repo2 archive for WAL (primary)
2023-03-23 04:36:01.328 P00 INFO: WAL segment 00000001000000000000003C successfully archived to '/var/lib/pgbackrest_repo2/archive/pgstanza/15-1/0000000100000000/00000001000000000000003C-6aa2de4dca50db51592d139010bdfb7a8c2c45ce.gz' on repo2
2023-03-23 04:36:01.430 P00 INFO: check command end: completed successfully (2358ms)
postgres@ip-172-31-54-194:~$

2.2 Taking backup locally with multiple repos:
In this example, we have tried to create two repositories in the local backup server itself, namely pgbackrest_repo1 and pgbackrest_repo2. One can configure both repositories in different storage. In case one storage is unavailable, then another storage will still have a backup, which can be helpful.

Please find the example of pgbackrest.conf in the backup host with two local repositories:

Backup Host: DB Host:
[global]
repo1-path=/var/lib/pgbackrest_repo1
repo1-retention-full=2
repo1-host-user = postgres
repo2-path=/var/lib/pgbackrest_repo2
repo2-retention-full=2
repo2-host-user = postgres
archive-async=y
log-level-console=info
log-level-file=debug
start-fast=y
[pgstanza]
pg1-path=/var/lib/postgresql/15/main
pg1-host=18.210.15.186
[global]
repo1-host=172.31.54.194
repo1-path=/var/lib/pgbackrest_repo1
repo1-retention-full=2
repo1-host-user = postgres
repo2-host=172.31.54.194
repo2-path=/var/lib/pgbackrest_repo2
repo2-retention-full=2
repo2-host-user = postgres
archive-async=y
spool-path=/var/spool/pgbackrest
log-level-console=info
log-level-file=debug
[pgstanza]
pg1-path=/var/lib/postgresql/15/main

Let’s rename pgbackrest_repo1 so that it becomes inaccessible, and then let’s try to take the backup:

On the Backup Host:

ubuntu@ip-172-31-54-194:~$ sudo mv /var/lib/pgbackrest_repo1 /var/lib/pgbackrest_repo1_bkp
ubuntu@ip-172-31-54-194:~$ sudo su - postgres
postgres@ip-172-31-54-194:~$
postgres@ip-172-31-54-194:~$ pgbackrest --stanza=pgstanza --log-level-console=info --type=full backup
2023-02-10 12:40:27.160 P00 INFO: backup command begin 2.44: --exec-id=23422-c65cc1d9 --log-level-console=info --log-level-file=debug --pg1-host=18.210.15.186 --pg1-path=/var/lib/postgresql/15/main --repo1-path=/var/lib/pgbackrest_repo1 --repo2-path=/var/lib/pgbackrest_repo2 --repo1-retention-full=2 --repo2-retention-full=2 --stanza=pgstanza --start-fast --type=full
2023-02-10 12:40:27.161 P00 INFO: repo option not specified, defaulting to repo1
ERROR: [055]: unable to load info file '/var/lib/pgbackrest_repo1/backup/pgstanza/backup.info' or '/var/lib/pgbackrest_repo1/backup/pgstanza/backup.info.copy':
FileMissingError: unable to open missing file '/var/lib/pgbackrest_repo1/backup/pgstanza/backup.info' for read
FileMissingError: unable to open missing file '/var/lib/pgbackrest_repo1/backup/pgstanza/backup.info.copy' for read
HINT: backup.info cannot be opened and is required to perform a backup.
HINT: has a stanza-create been performed?
2023-02-10 12:40:27.162 P00 INFO: backup command end: aborted with exception [055]
postgres@ip-172-31-54-194:~$

As shown above, it cannot take the backup and throws the error message highlighted, which is expected.

Let’s try to take a backup in repo=2 and check whether it allows us to do so.

On the Backup Host:

postgres@ip-172-31-54-194:~$ pgbackrest --stanza=pgstanza --log-level-console=info --type=full backup --repo=2
2023-02-10 12:40:34.605 P00 INFO: backup command begin 2.44: --exec-id=23423-e840ad8d --log-level-console=info --log-level-file=debug --pg1-host=18.210.15.186 --pg1-path=/var/lib/postgresql/15/main --repo=2 --repo1-path=/var/lib/pgbackrest_repo1 --repo2-path=/var/lib/pgbackrest_repo2 --repo1-retention-full=2 --repo2-retention-full=2 --stanza=pgstanza --start-fast --type=full
2023-02-10 12:40:35.949 P00 INFO: execute non-exclusive backup start: backup begins after the requested immediate checkpoint completes
2023-02-10 12:40:36.456 P00 INFO: backup start archive = 000000010000000000000028, lsn = 0/28000028
2023-02-10 12:40:36.456 P00 INFO: check archive for prior segment 000000010000000000000027
2023-02-10 12:40:43.993 P00 INFO: execute non-exclusive backup stop and wait for all WAL segments to archive
2023-02-10 12:40:44.195 P00 INFO: backup stop archive = 000000010000000000000028, lsn = 0/28000138
2023-02-10 12:40:44.201 P00 INFO: check archive for segment(s) 000000010000000000000028:000000010000000000000028
2023-02-10 12:40:45.521 P00 INFO: new backup label = 20230210-124035F
2023-02-10 12:40:45.579 P00 INFO: full backup size = 22.0MB, file total = 961
2023-02-10 12:40:45.580 P00 INFO: backup command end: completed successfully (10978ms)
2023-02-10 12:40:45.580 P00 INFO: expire command begin 2.44: --exec-id=23423-e840ad8d --log-level-console=info --log-level-file=debug --repo=2 --repo1-path=/var/lib/pgbackrest_repo1 --repo2-path=/var/lib/pgbackrest_repo2 --repo1-retention-full=2 --repo2-retention-full=2 --stanza=pgstanza
2023-02-10 12:40:45.592 P00 INFO: repo2: 15-1 remove archive, start = 000000010000000000000020, stop = 000000010000000000000025
2023-02-10 12:40:45.592 P00 INFO: expire command end: completed successfully (12ms)
postgres@ip-172-31-54-194:~$

Excellent… the backup was successful for repo2. Now, let’s check the info and see what it says for repo1.

On the Backup Host:

postgres@ip-172-31-54-194:~$ pgbackrest --stanza=pgstanza --log-level-console=info info
stanza: pgstanza
status: mixed
repo1: error (missing stanza path)
repo2: ok
cipher: none
db (current)
wal archive min/max (15): 000000010000000000000026/000000010000000000000028
full backup: 20230210-123819F
timestamp start/stop: 2023-02-10 12:38:19 / 2023-02-10 12:38:28
wal start/stop: 000000010000000000000026 / 000000010000000000000026
database size: 22.0MB, database backup size: 22.0MB
repo2: backup set size: 2.9MB, backup size: 2.9MB
full backup: 20230210-124035F
timestamp start/stop: 2023-02-10 12:40:35 / 2023-02-10 12:40:44
wal start/stop: 000000010000000000000028 / 000000010000000000000028
database size: 22.0MB, database backup size: 22.0MB
repo2: backup set size: 2.9MB, backup size: 2.9MB
postgres@ip-172-31-54-194:~$
postgres@ip-172-31-54-194:~$ pgbackrest --stanza=pgstanza --log-level-console=info info --repo=1
stanza: pgstanza
status: error (missing stanza path)
postgres@ip-172-31-54-194:~$

2.3 Taking backup locally and remotely on the cloud:
Let’s consider a scenario where one repo is locally available on the dedicated backup server, and another repo is available on the cloud. The advantage here is that in case anyone repo from a local system or cloud is unavailable, it can be availed. This combination can help us to take advantage of the cloud and on-prem local machines.

Let’s check the main configuration needed in pgbackrest.conf:

Backup Host: DB Host:
[global]
## Repo1: Local
repo1-path=/var/lib/pgbackrest_repo1
repo1-retention-full=2
repo1-host-user=postgres
## Repo2: AWS S3
repo2-type=s3
repo2-path=/pgbackrest_repo2
repo2-retention-full=2
repo2-host-user=postgres
repo2-s3-bucket=s3bucket
repo2-s3-endpoint=s3.us-east-1.amazonaws.com
repo2-s3-key=accessKey2
repo2-s3-key-secret=verySecretKey2
repo2-s3-region=us-east-1
archive-async=y
log-level-console=info
log-level-file=debug
start-fast=y
[pgstanza]
pg1-path=/var/lib/postgresql/15/main
pg1-host=18.210.15.186
[global]
## Repo1: Local
repo1-host=172.31.54.194
repo1-path=/var/lib/pgbackrest_repo1
repo1-retention-full=2
repo1-host-user=postgres
## Repo2: AWS S3
repo2-type=s3
repo2-path=/pgbackrest_repo2
repo2-retention-full=2
repo2-host-user=postgres
repo2-s3-bucket=s3bucket
repo2-s3-endpoint=s3.us-east-1.amazonaws.com
repo2-s3-key=accessKey2
repo2-s3-key-secret=verySecretKey2
repo2-s3-region=us-east-1
archive-async=y
spool-path=/var/spool/pgbackrest
log-level-console=info
log-level-file=debug
[pgstanza]
pg1-path=/var/lib/postgresql/15/main


As we can see, repo1 related options are specific to storing the backup in the local repository present in the dedicated backup host on the path – /var/lib/pgbackrest_repo1.A few important options for repo2, available in the AWS S3:repo-type is s3 indicating the AWS S3, and it could be azure for Azure Cloud, GCS for Google Cloud,repo2-s3-bucket, repo2-s3-endpoint, repo2-s3-key-secret, and repo2-s3-region attributes varies from cloud to cloud. A bucket or required repo with proper user and permission must be created before configuring pgBackRest backups. More information on the same can be found in pgBackRest User Guide.

2.4 Take backup locally and in multiple clouds:
Another very useful scenario is creating a repository on multiple clouds and one locally in the dedicated backup host. Even if one cloud provider is unavailable, a backup could be available from any other cloud or the local repository. In this case, a configuration could be like repo1-type, repo2-type, repo3-type, and so on.

PostgreSQL backup locally and in multiple clouds

In the above diagram, four repositories have been created where one repository is available locally, and other repositories are at different clouds viz AWS S3, Azure, and Google Cloud, respectively. In this case, the configuration on the backup host will be as follows.

On the Backup Host:

postgres@ip-172-31-54-194:~$ cat /etc/pgbackrest.conf
[global]
## Repo1: Local
repo1-path=/var/lib/pgbackrest_repo1
repo1-retention-full=2
repo1-host-user = postgres
## Repo2: AWS S3
repo2-type=s3
repo2-path=/pgbackrest_repo2
repo2-retention-full=2
repo2-host-user = postgres
repo2-s3-bucket=s3bucket
repo2-s3-endpoint=s3.us-east-1.amazonaws.com
repo2-s3-key=accessKey2
repo2-s3-key-secret=verySecretKey2
repo2-s3-region=us-east-1
## Repo3: Azure
repo3-type=azure
repo3-path=/pgbackrest_repo3
repo3-retention-full=2
repo3-azure-account=pgbackrest
repo3-azure-container=pgbackrest-container
repo3-azure-key=accessKey3
## Repo4: Google Cloud
repo4-type=gcs
repo4-path=/pgbackrest_repo4
repo4-retention-full=2
repo4-gcs-bucket=pgbackrest-bucket
repo4-gcs-key=/etc/pgbackrest/gcs-key.json
archive-async=y
log-level-console=info
log-level-file=debug
start-fast=y
[pgstanza]
pg1-path=/var/lib/postgresql/15/main
pg1-host=18.210.15.186

DB Host configurations will be set in the same way that has been mentioned in the earlier sections, along with the multiple repository details of the cloud.

Conclusion

To conclude, the major advantage of pgBackRest multi-repo functionality is that redundant backup copies can be taken. With the async=y option – archives will move to multiple repositories, and in case the default repo is unavailable, then the second repository will take care of archive files automatically.

The only limitation of this feature is that, by default, the backup will not go to repo=2 even though it is configured. We need to mention the repository number in case a backup needs to be taken in repo2. Also, one needs to take backup multiple times, mentioning the repo number explicitly so that backup can be taken in repositories other than the default repo. Eg – pgbackrest –stanza=pgstanza –log-level-console=info –type=full backup –repo=2.

Despite these limitations, multi-repo functionality can be used to take the backups on the secondary repo, even if the dedicated backup server is unavailable.

Percona Distribution for PostgreSQL provides the best and most critical enterprise components from the open-source community, in a single distribution, designed and tested to work together.

Download Percona Distribution for PostgreSQL Today!

Dec
23
2022
--

Rebuild Patroni Replica Using pgBackRest

Rebuild Patroni Replica Using pgBackRest

Patroni is one of the most used high availability (HA) solutions with the PostgreSQL database. It uses a Distributed Configuration Store (DCS) to keep the configuration in a centralized location available for all nodes making it an easy-to-use and reliable HA solution available in the market today.

On the other hand, pgBackRest is a backup solution that helps in taking not only the FULL backup but also incremental and differential backup. This is one of the most used backup tool used for PostgreSQL databases.

In the previous blogs, we have discussed how to set up PostgreSQL HA with Patroni, and how to configure pgBackRest. Both these open source tools have been saviors for DBAs for achieving high availability and performing restoration in ample ways. In this blog, we will integrate both of these tools and understand how they can work together to reduce the server load.

Scenarios:

  • Reinitializing the Patroni cluster using pgBackRest (instead of pgBaseBackup).
  • Creating the Patroni replica using pgBackRest.

Pre-configured setup:

  • Patroni configuration setup for two or more databases.
  • pgBackRest configured on a dedicated backup host.

For the purpose of testing these scenarios, the below configurations will be used throughout this blog:

Patroni Nodes:

+ Cluster: prod (7171021941707843784) ----+-----------+
| Member | Host  | Role    | State   | TL | Lag in MB |
+--------+-------+---------+---------+----+-----------+
| node1  | node1 | Leader  | running | 1 |           |
| node2  | node2 | Replica | running | 1 |         0 |
+--------+-------+---------+---------+----+-----------+

Patronictl edit-config shows below:

loop_wait: 10
maximum_lag_on_failover: 1048576
postgresql:
  create_replica_methods:
  - pgbackrest
  - basebackup
  parameters:
    archive_command: pgbackrest --stanza=patroni archive-push %p
    archive_mode: 'on'
    archive_timeout: 120s
    hot_standby: 'on'
    listen_addresses: '*'
    logging_collector: 'on'
    max_replication_slots: 10
    max_wal_senders: 10
    pg_hba:
    - host all all 0.0.0.0/0 md5
    - host replication all 0.0.0.0/0 md5
    - local all  postgres    peer
    wal_level: replica
    wal_log_hints: 'on'
  pgbackrest:
    command: /usr/bin/pgbackrest --stanza=patroni --log-level-file=detail --delta restore
    keep_data: true
    no_params: true
  recovery_conf:
    restore_command: pgbackrest --stanza=patroni archive-get %f %p
  use_pg_rewind: true
  use_slots: true
retry_timeout: 10
ttl: 30

Note: Please check the highlighted sections, which are specific for rebuilding nodes using pgBackRest backup.

Apart from Patroni, we will need a Backup Repo host where pgBackRest has been configured. It can be on a dedicated server or one of the DB hosts. However, it is recommended to use a dedicated server as in case DB goes down, we have a separate server to make the life of the DBAs easier.

Let’s test the scenarios one by one:

Reinitializing the Patroni cluster using pgBackRest (instead of pgBaseBackup)

The main advantage of using pgBackRest instead of pgBaseBackup while reinitializing the node is that it’ll reduce the load from the leader node. This will not make any difference if the DB size is smaller. However, this feature is very useful in case the DB size is huge and it takes hours or days to build the node. This will divert the resource utilization on the dedicated backup host instead of the primary server, which anyways is busy fulfilling the majority of the requests coming to the database.

Let us try to understand how we can rebuild the node using backup.

Many times, we are unable to start the secondary nodes after failover or switchover. To handle this situation, Patroni allows us to reinitialize the database cluster, which will create/rebuild the node by wiping the data directory. In the background, it will copy all the contents of the data directory from the Primary Server and re-create the desired node. 

Please make the changes in the Patroni configuration/yml file and reload the configuration, as shown previously. To reinitialize the Patroni replica node, the reinit command is used as below:

ubuntu@192.168.0.1:~$ patronictl -c /etc/patroni/node1.yml reinit prod
+ Cluster: prod (7171021941707843784) ----+-----------+
| Member | Host  | Role    | State   | TL | Lag in MB |
+--------+-------+---------+---------+----+-----------+
| node1  | node1 | Leader  | running | 1 |           |
| node2  | node2 | Replica | running | 1 |         0 |
+--------+-------+---------+---------+----+-----------+
Which member do you want to reinitialize [node1, node2]? []: node2
Are you sure you want to reinitialize members node2? [y/N]: y
Success: reinitialize for member node2

On the replica node, we can notice in the top command that it is rebuilding the node using pgBackRest backup and not pgBackRest. Ideally, Patroni uses pgBaseBackup in case create_replica_methods is not used which increases the load on the leader node.

 PID USER      PR  NI    VIRT    RES    SHR S  %CPU  %MEM     TIME+ COMMAND
  12939 postgres  20   0  306440 268140      4 S  34.9  27.1   8871:14 GkwP468a
 791850 postgres  20   0  218692  29544  26820 S   8.9   3.0   0:00.28 /usr/lib/postgresql/14/bin/postgres -D /var/lib/postgresql/14/main --config-file=/var/lib/postgresql/14/main/postgresql.conf --listen_ad+
 791881 postgres  20   0   60980  12696  10628 S   3.2   1.3   0:00.10 pgbackrest --config=/etc/pgbackrest/pgbackrest.conf --stanza=patroni archive-get 00000013.history pg_wal/RECOVERYHISTORY
 791874 postgres  20   0  218692   8032   5260 S   2.2   0.8   0:00.07 postgres: prod: startup
 791827 postgres  20   0    7760   3516   3212 R   1.3   0.4   0:00.04 bash
 784973 postgres  20   0   23316    212      0 S   0.3   0.0   0:18.42 tracepath

In case it is using pgBackRest, then it will create a restore file mentioning pgBackRest command as below:

2022-12-15 15:41:29.070 P00   INFO: restore command begin 2.41: --config=/etc/pgbackrest/pgbackrest.conf --delta --exec-id=791815-82f4ea68 --log-level-console=info --log-level-file=detail --pg1-path=/var/lib/postgresql/14/main --process-max=2 --repo1-host=192.168.0.5 --repo1-host-user=postgres --repo1-path=/pgrdbackups --stanza=patroni
2022-12-15 15:41:30.800 P00   INFO: repo1: restore backup set 20221213-154604F, recovery will start at 2022-12-13 15:46:04
2022-12-15 15:41:30.877 P00 DETAIL: check '/var/lib/postgresql/14/main' exists
2022-12-15 15:41:30.877 P00 DETAIL: remove 'global/pg_control' so cluster will not start if restore does not complete
2022-12-15 15:41:30.918 P00   INFO: remove invalid files/links/paths from '/var/lib/postgresql/14/main'
2022-12-15 15:41:30.919 P00 DETAIL: remove invalid file '/var/lib/postgresql/14/main/backup_label.old'
2022-12-15 15:41:31.841 P00 DETAIL: remove invalid file '/var/lib/postgresql/14/main/base/13761/pg_internal.init'
2022-12-15 15:41:31.920 P00 DETAIL: remove invalid file '/var/lib/postgresql/14/main/global/pg_internal.init'


Creating the Patroni replica using pgBackRest:

In case the bootstrap section contains code to rebuild the node using pgBackRest, then while adding the node in the already existing Patroni cluster, the first time building of the new node will use pgBackRest backup instead of pgBaseBackup. Also, point-in-time recovery can be done using the bootstrap section. This will help in not only reducing the load from the leader node but also the backup node will help restore the data with comparatively lesser resource utilization.

To configure the same, please use the below in the Patroni configuration file:

bootstrap:
    method: <custom_bootstrap_method_name>
    <custom_bootstrap_method_name>:
        command: <path_to_custom_bootstrap_script> [param1 [, ...]]
        keep_existing_recovery_conf: True/False
        no_params: True/False
        recovery_conf:
            recovery_target_action: promote
            recovery_target_timeline: <PITR_Time>
            restore_command: <method_specific_restore_command>

In this example, the below section has been added to Patroni config, which will build the node by performing point-in-time recovery using the time stamp mentioned.

bootstrap:
  method: pitr_restore_by_pgbackrest
  pitr_restore_by_pgbackrest:
    command: 'pgbackrest --config=/etc/pgbackrest/pgbackrest.conf --stanza=patroni --log-level-file=detail --link-all --type=time
 --target="2022-12-13 15:46:04" restore'
    keep_existing_recovery_conf: True
    no_params: True
    recovery_conf:
      recovery_target_action: "promote"
      recovery_target_time: "2022-12-13 15:46:04"
      restore_command: 'pgbackrest -config=/etc/rdba/pgbackrest/pgbackrest.conf --stanza=patroni --log-level-file=detail archive-get %f "%p"'
      recovery_target_inclusive: true

When the node is being built, one can see in the TOP processes that pgBackRest is being used instead of base backup and Patroni Status when the node is being built:

? patroni.service - PostgreSQL high-availability manager
     Loaded: loaded (/lib/systemd/system/patroni.service; enabled; vendor preset: enabled)
    Drop-In: /etc/systemd/system/patroni.service.d
             ??override.conf
     Active: active (running) since Mon 2022-12-19 19:06:16 UTC; 3s ago
   Main PID: 2094 (patroni)
      Tasks: 11 (limit: 1143)
     Memory: 114.6M
        CPU: 941ms
     CGroup: /system.slice/patroni.service
             ??2094 /usr/bin/python3 /usr/bin/patroni /etc/patroni/db2.yml
             ??2100 /usr/bin/pgbackrest --config=/etc/pgbackrest/pgbackrest.conf --stanza=patroni --log-level-file=detail --delta restore
             ??2102 /usr/bin/pgbackrest --config=/etc/pgbackrest/pgbackrest.conf --exec-id=2100-9618fafd --log-level-console=off --log-level-file=off --log-level-stderr=error --process=1 --remote-type=repo --stanza=p>
             ??2103 /usr/bin/pgbackrest --config=/etc/pgbackrest/pgbackrest.conf --exec-id=2100-9618fafd --log-level-console=off --log-level-file=off --log-level-stderr=error --process=2 --remote-type=repo --stanza=p>
             ??2104 ssh -o LogLevel=error -o Compression=no -o PasswordAuthentication=no postgres@192.168.0.3 "/usr/bin/pgbackrest --exec-id=2100-9618fafd --log-level-console=off --log-level-file=off --log-level-st>
             ??2105 ssh -o LogLevel=error -o Compression=no -o PasswordAuthentication=no postgres@192.168.0.3 "/usr/bin/pgbackrest --exec-id=2100-9618fafd --log-level-console=off --log-level-file=off --log-level-st>
Dec 19 19:06:16 ip-192-168-0-2 systemd[1]: Started PostgreSQL high-availability manager.
Dec 19 19:06:16 ip-192-168-0-2 patroni[2094]: 2022-12-19 19:06:16,415 INFO: Selected new etcd server http://192.168.0.1:2379
Dec 19 19:06:16 ip-192-168-0-2 patroni[2094]: 2022-12-19 19:06:16,434 INFO: No PostgreSQL configuration items changed, nothing to reload.
Dec 19 19:06:16 ip-192-168-0-2 patroni[2094]: 2022-12-19 19:06:16,551 INFO: Lock owner: node3; I am db2
Dec 19 19:06:16 ip-192-168-0-2 patroni[2094]: 2022-12-19 19:06:16,633 INFO: trying to bootstrap from leader 'node3'
Dec 19 19:06:16 ip-192-168-0-2 patroni[2100]: 2022-12-19 19:06:16.645 P00   INFO: restore command begin 2.41: --config=/etc/pgbackrest/pgbackrest.conf --delta --exec-id=2100-9618fafd --log-level-console=info --log-l>
Dec 19 19:06:16 ip-192-168-0-2 patroni[2100]: WARN: --delta or --force specified but unable to find 'PG_VERSION' or 'backup.manifest' in '/var/lib/postgresql/14/main' to confirm that this is a valid $PGDATA director
Dec 19 19:06:17 ip-192-168-0-2 patroni[2100]: 2022-12-19 19:06:17.361 P00   INFO: repo1: restore backup set 20221213-154604F, recovery will start at 2022-12-13 15:46:04

Notice that it is using delta restore which means it will automatically identify which files are required to restore and only those will be restored making the whole process faster.

Also, the log file (by default – /var/log/pgbackrest) will contain the restore date and time as below:

-------------------PROCESS START-------------------
2022-12-19 19:06:16.645 P00   INFO: restore command begin 2.41: --config=/etc/pgbackrest/pgbackrest.conf --delta --exec-id=2100-9618fafd --log-level
-console=info --log-level-file=detail --pg1-path=/var/lib/postgresql/14/main --process-max=2 --repo1-host=192.168.0.3 --repo1-host-user=postgres -
-repo1-path=/pgrdbackups --stanza=patroni
2022-12-19 19:06:16.646 P00   WARN: --delta or --force specified but unable to find 'PG_VERSION' or 'backup.manifest' in '/var/lib/postgresql/14/mai
n' to confirm that this is a valid $PGDATA directory.  --delta and --force have been disabled and if any files exist in the destination directories
the restore will be aborted.
2022-12-19 19:06:17.361 P00   INFO: repo1: restore backup set 20221213-154604F, recovery will start at 2022-12-13 15:46:04
2022-12-19 19:06:17.361 P00 DETAIL: check '/var/lib/postgresql/14/main' exists
2022-12-19 19:06:17.362 P00 DETAIL: create path '/var/lib/postgresql/14/main/base'
2022-12-19 19:06:17.362 P00 DETAIL: create path '/var/lib/postgresql/14/main/base/1'
2022-12-19 19:06:17.362 P00 DETAIL: create path '/var/lib/postgresql/14/main/base/13760'
2022-12-19 19:06:17.362 P00 DETAIL: create path '/var/lib/postgresql/14/main/base/13761'

This blog majorly focuses on integrating the pgBackRest and Patroni, however, one can use other backup tools like WAL_E or BARMAN to rebuild the nodes. More information on such configuration can be found in the Patroni documentation.

Conclusion

Patroni and pgBackRest solutions work best when integrated, which helps in reducing the load from the Primary DB Server. This integration, where the node is reinitialized using pgBackRest, makes the optimum utilization of the dedicated backup server. If the Patroni setup is already configured and the dedicated backup host is also available, then making a few configuration changes in patroni.yml can work like wonders.

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com