Aug
26
2026
--

Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in

These days there’s been a lot of talk about Postgres having an impact on “everything”. Whether it’s replacing legacy systems, creating a new greenfield project or even implementing it as a back-end to an agentic AI, Postgres is today’s poster child for innovation.

So performing something as dull and straightforward as a database migration should be easy, eh?

Well, not quite.

Its popular adoption and success has, in a sense, created a problem of its own making, which is otherwise known as the Walled Garden Effect.

The Walled Garden effect in open source is where software that is nominally open but a vendor, platform, or ecosystem has exerted control over its governance, distribution and compatibility in such a manner that its interaction with the same open source technology managed in another environment becomes problematic.

It’s an unfortunate reality that some commercial ecosystems built around Postgres can become walled gardens. Postgres itself remains open and portable, but its widespread adoption has also produced commercial ecosystems in which that portability can become progressively constrained.

At its most extreme; here are the risks of a Walled Garden to the Postgres end-user:

  • In the context of a Postgres offering from a cloud computing service offering DBaaS:
    • They “Control” the core platform, set the standards, and host the marketplace.
    • They “Acquire” developers, hardware manufacturers, and service providers who build products that add value to the core platform.
    • They “Convince” users to join the ecosystem whose data, attention, and capital eventually fuels the network’s growth.
    • The financial and cultural health of satellite vendors whose very existence is “Tied” directly to the decisions and policies made by the platform owner.
  • In the context of the technology used:
    • Modifying” the backend with unique attributes while enticing you with standard front-end protocols. A Postgres compatible interface does not necessarily imply Postgres equivalent portability. A service may emulate familiar SQL, drivers, and tools all the while introducing backend capabilities or operational dependencies that do not exist in community Postgres.
  • What it means over the life of your system:
    • As the ecosystem becomes more valuable to the user, it creates a greater “Disincentive” to exit.
    • If an exit strategy is undertaken:
      • High switching “Costs” can be incurred when migration introduces data-integrity risks and extraordinary complexity into what has become a tightly integrated workflow.
      • Extra “Expert” costs must be budgeted because specialized expertise may be required when vendor-specific features or dependencies exceed the experience of in-house staff.

        Working on past projects I’ve often found myself paraphrasing an old Eagles refrain “You can provision Postgres any time you like, but your architecture can never leave.

        While PostgreSQL itself is fully open-source and free, some vendors have created a Hotel California effect using these three specific mechanisms:

      • Proprietary Forks & Features: They offer “Postgres-compatible” databases. They add custom, closed-source performance layers or automated scaling. If you build your application to rely on these specific features, moving back to community Postgres can require a massive architecture rewrite.
      • Migration Cost Asymmetry: Moving data into an ecosystem can be relatively inexpensive. Moving that database to an alternate environment later can be considerably more complex.
      • Ecosystem Gravity: Databases do not sit in a vacuum. Once your Postgres instance is tightly integrated with a vendor’s proprietary backup systems, security roles (IAM), and serverless analytics tools, leaving the database can mean rebuilding your entire infrastructure. Postgres data can remain portable while the architecture surrounding it becomes progressively less portable.

        So what does it mean for you?

        While today’s database landscape can make vendor dependency seem unavoidable, it isn’t. There are still organizations that build commercial services around the principles that made open source successful in the first place: transparency, interoperability, portability, and the customer’s freedom to choose where and how their software runs. Percona is one example of a commercial model built around the premise that commercial expertise and open-source values do not have to be opposing ideas.

        Reference:
        https://arxiv.org/html/2409.01118v1 

The post Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in appeared first on Percona.

Aug
25
2026
--

Replication Lag on AWS FSx: The Hidden EC2 Single-Flow Bandwidth Limit

A recent case in our Percona Support team started with a familiar complaint. A PostgreSQL standby lagging behind its primary. Although the problem was simple, it brought a specific flavor that’s worth sharing.

The customer had already reached out to AWS Support about the storage layer behind the database, an Amazon FSx filesystem mounted over NFS on the standby’s EC2 instance. Let’s not stigmatize the infrastructure choice. It met the customer’s requirements, and they paid for provisioned resources to guarantee a performance baseline, a better starting point than many similar cases we see.

AWS confirmed that both the EC2 instance and the FSx filesystem looked healthy, with the filesystem sitting at roughly 50% of its provisioned capacity. From that angle, storage looked like a non-issue, and the investigation could easily have moved elsewhere in PostgreSQL.

We see this pattern often enough to call it out. A component reporting comfortable headroom relative to its provisioned limit does not mean the component isn’t the bottleneck. This post walks through what we found and why the standard utilization numbers didn’t show it.

The problem with looking at utilization alone

Provisioned IOPS and throughput numbers describe what a storage backend can deliver, regardless of what the path between the database host and that backend can actually carry.

An EC2 instance talking to FSx over NFS goes through several layers, including the instance’s own network bandwidth, the network path to the filesystem, and the filesystem’s own limits. Usually, monitoring dashboards only consider the last of those. If any of the other layers cap out below the provisioned limit, the system can become saturated even as every capacity dashboard still shows green.

That’s exactly what we found here.

Step 1. vmstat shows processes stuck waiting on I/O

The first signal came from vmstat. The “b” column reports the number of processes blocked waiting for I/O to complete. In a healthy system, “b” sits at zero most of the time, with occasional small blips, but not this time. The “wa” column was also consistently high across all samples, pointing to storage/network wait, while si/so stayed low, an early sign that memory wasn’t the initial suspect.

procs -------------memory------------ ---swap-- -----io---- ---system---- ------cpu-----
 r  b   swpd   free   buff  cache       si   so    bi    bo   in   cs     us sy id wa st
15 10 839168 1411800      0 199145760    7   18    14    25   23   21      7 15 61 17  0
 3 10 839424 1399408      0 199137696   12   84    12    84 198108 221859 11 18 50 20  0
 9  5 839424 1453656      0 199109952   12    4    12     8 206128 237222 10 17 51 22  0
10  7 839424 1412500      0 199134752   20    8    44     8 221809 252061 11 18 50 21  0
 8  7 839168 1439736      0 199120608   20   56    20    56 212175 236773 11 17 52 20  0
12  8 839424 1436540      0 199113056   28   72    28   544 212031 238994 11 18 51 19  0
 5  4 839680 1829036      0 198694080   32   96    32    96 176937 185345 10 16 53 21  0
 6  8 839680 1632944      0 198926912    0    0     0    28 213123 253983 10 16 55 19  0
14 15 843008 1677392      0 198866720    8 3620     8  3620 193275 227061 11 16 52 21  0
 5 14 843264 1639992      0 198931488    0  288     0   288 237257 273167 11 18 50 21  0

That was not an occasional blip. Across all the samples, we classified every reading:

awk '$1 ~ /^[0-9]+$/ && $2 ~ /^[0-9]+$/ { b=$2+0; n++; if (b==0) a++; else if (b<=5) c++; else if (b<=10) d++; else e++ } END { printf "b = 0      : %6d (%5.1f%%)\nb = 1-5    : %6d (%5.1f%%)\nb = 6-10   : %6d (%5.1f%%)\nb > 10     : %6d (%5.1f%%)\ntotal      : %6d\n", a,100*a/n, c,100*c/n, d,100*d/n, e,100*e/n, n }' vmstat.log
b = 0      :      1 (  0.6%)
b = 1-5    :     86 ( 47.8%)
b = 6-10   :     79 ( 43.9%)
b > 10     :     14 (  7.8%)
total      :    180

“b” was above zero in 99.4% of samples, and above 5 more than half the time. The CPU columns in the same output showed a consistent I/O wait (wa) value across all lines. Both point to a storage subsystem bottleneck, somewhere between the disk, the network, or the NFS server.

Step 2. nfsiostat sends mixed signals

nfsiostat displays NFS traffic by read and write operations, including latency. Looking at averages:

fs-xxxxxxxxxxxxxxxxx.fsx.us-east-1.amazonaws.com:/fsx mounted on /postgres/data1:

          ops/s       rpc bklog
      15927.396           0.000

read:              ops/s            kB/s           kB/op         retrans    avg RTT (ms)    avg exe (ms)  avg queue (ms)          errors
                7144.840      303386.959          42.462        0 (0.0%)           1.304          12.281          10.960       72 (0.0%)
write:             ops/s            kB/s           kB/op         retrans    avg RTT (ms)    avg exe (ms)  avg queue (ms)          errors
                3040.323       94332.387          31.027        0 (0.0%)           1.976         136.517         134.531        0 (0.0%)

Average write exe time is 136.52 ms, most of which (134.53 ms) is queue time. That’s already a red flag, as 136.52 ms is long enough for any modern storage system. Since most of the time is spent in the queue rather than in the actual round trip, the bottleneck doesn’t seem to be the underlying disks themselves.

Comparing peak and p95 usage against the provisioned limits looked fine at first:

grep -A1 '^read:' nfsiostat.log | awk '/^ +[0-9]/{print $2}' | tail -n +2 | sort -rn | \
awk -v prov=1280 'NR==1{max=$1}{v[NR]=$1} END{p95=v[int(NR*0.05)];
printf "NFS reads (%d x 1s samples) vs %d MB/s provisioned\n  PEAK : %7.0f MB/s (%.2f Gbit/s) = %2.0f%% of provisioned\n  p95  : %7.0f MB/s (%.2f Gbit/s) = %2.0f%% of provisioned\n  CEILING: no sample exceeds %.0f MB/s (p95 is within %.1f%% of peak)\n",
NR, prov, max*1024/1e6, max*1024*8/1e9, 100*(max*1024/1e6)/prov, p95*1024/1e6, p95*1024*8/1e9, 100*(p95*1024/1e6)/prov, max*1024/1e6, 100*(max-p95)/max}'

NFS reads (179 x 1s samples) vs 1280 MB/s provisioned
  PEAK :     626 MB/s (5.01 Gbit/s) = 49% of provisioned
  p95  :     623 MB/s (4.98 Gbit/s) = 49% of provisioned
  CEILING: no sample exceeds 626 MB/s (p95 is within 0.5% of peak)

grep -A1 'rpc bklog' nfsiostat.log | awk '/^ +[0-9]/{print $1}' | tail -n +2 | sort -rn | \
awk -v prov=80000 'NR==1{max=$1}{v[NR]=$1} END{
printf "NFS IOPS (%d x 1s samples) vs %d provisioned\n  PEAK : %6.0f ops/s = %2.0f%% of provisioned\n  p50  : %6.0f ops/s = %2.0f%% of provisioned\n",
NR, prov, max, 100*max/prov, v[int(NR*0.5)], 100*v[int(NR*0.5)]/prov}'

NFS IOPS (179 x 1s samples) vs 80000 provisioned
  PEAK :  33676 ops/s = 42% of provisioned
  p50  :  16170 ops/s = 20% of provisioned

49% of provisioned throughput and 42% of provisioned IOPS at peak. On paper, this storage subsystem has plenty of room left. This is the same conclusion AWS Support reached, and it’s a reasonable one to draw from these two numbers alone.

Step 3. The distribution tells a different story from the average

Peak and p95 only describe the top of the range. They don’t say how often the system sits there. So we built a distribution of every 1-second read throughput sample instead of collapsing it into a single peak or percentile:

grep -A1 '^read:' nfsiostat.log | awk '/^ +[0-9]/{print $2}' | tail -n +2 | \
awk '{g=$1*1024*8/1e9; b=int(g*4); c[b]++; n++; if(c[b]>mx)mx=c[b]}
END{printf "NFS read throughput distribution (%d x 1s samples)\n\n",n;
for(i=0;i<=21;i++) if(i in c){bar=""; w=int(c[i]*50/mx); for(j=0;j<w;j++) bar=bar "#";
printf "%4.2f-%4.2f Gbit/s |%-50s| %3d (%4.1f%%)\n", i/4, i/4+0.25, bar, c[i], 100*c[i]/n}}'

NFS read throughput distribution (179 x 1s samples)
1.25-1.50 Gbit/s |###                                               |   2 ( 1.1%)
1.50-1.75 Gbit/s |#######                                           |   4 ( 2.2%)
1.75-2.00 Gbit/s |#########                                         |   5 ( 2.8%)
2.00-2.25 Gbit/s |#                                                 |   1 ( 0.6%)
2.25-2.50 Gbit/s |#########                                         |   5 ( 2.8%)
2.50-2.75 Gbit/s |######################                            |  12 ( 6.7%)
2.75-3.00 Gbit/s |##############                                    |   8 ( 4.5%)
3.00-3.25 Gbit/s |###########################                       |  15 ( 8.4%)
3.25-3.50 Gbit/s |########################                          |  13 ( 7.3%)
3.50-3.75 Gbit/s |#####################################             |  20 (11.2%)
3.75-4.00 Gbit/s |##############################################    |  25 (14.0%)
4.00-4.25 Gbit/s |###################################               |  19 (10.6%)
4.25-4.50 Gbit/s |#########################                         |  14 ( 7.8%)
4.50-4.75 Gbit/s |##############                                    |   8 ( 4.5%)
4.75-5.00 Gbit/s |##################################################|  27 (15.1%)
5.00-5.25 Gbit/s |#                                                 |   1 ( 0.6%)

The single most common bucket among all samples is 4.75-5.00 Gbit/s, and no sample surpassed 5.01 Gbit/s, not a random peak but a ceiling. Every time the workload tried to push beyond 5 Gbit/s, it was capped at that rate instead of climbing further, which explains the queue time we saw in nfsiostat. The requests were piling up behind a virtual wall unrelated to the FSx filesystem’s provisioned throughput.

Step 4. The limit on the network path

A number that consistently caps out at 5 Gbit/s pointed us to networking limits rather than disk performance issues. According to AWS documentation, an r5n.8xlarge instance provides 25 Gbps of bandwidth. However, an EC2 instance can become a victim of what AWS calls “single-flow traffic” (a single TCP connection). This limitation caps network transfer bandwidth at 5 Gbps regardless of the EC2 instance’s total aggregate network bandwidth, and it applies to most of today’s EC2 instances.

One look at the mount confirmed a single flow was carrying everything:

fs-xxxxxxxxxxxxxxxxx.fsx.us-east-1.amazonaws.com:/fsx on /postgres/data1 type nfs4 (rw,relatime,vers=4.2,rsize=1048576,wsize=1048576,namlen=255,hard,fatal_neterrors=none,proto=tcp,timeo=600,retrans=2,sec=sys,clientaddr=10.0.0.10,local_lock=none,addr=10.0.0.20)

No nconnect option, which means a single TCP connection was carrying all NFS traffic between the EC2 instance and FSx. That single connection was subject to EC2’s single-flow bandwidth limit, not the instance’s aggregate limit, and definitely not the throughput FSx itself was provisioned for. The 25 Gbps the EC2 instance could theoretically use, and the 10.2 Gbps throughput FSx could theoretically deliver, were both irrelevant as long as everything moved through a single flow capped at roughly 5 Gbps.

This is why the AWS Support answer and the customer’s own checks weren’t wrong, but were just looking at the wrong layer.

The fix

NFS supports the nconnect mount option, which allows a client to multiplex operations across multiple TCP connections to the same NFS export rather than a single one. It’s supported on NFS v3, v4.0, v4.1, and v4.2, and available by default on modern Linux kernels (5.3+), with backports available on some enterprise distributions. AWS itself documents and suggests using nconnect when possible:

sudo mount -t nfs -o nconnect=16 filesystem_dns_name:/vol_path /localpath

We recommended reviewing the nconnect configuration with their own infrastructure team or AWS Support, since this is a network and infrastructure configuration decision, not a PostgreSQL one. We did not commit to a specific nconnect value, not because we didn’t want to, but because properly benchmarking it would require resources and access our team didn’t have. 

The customer came back after setting nconnect=16 and reported that the lag immediately started to close. That’s a good outcome, but the value itself probably deserves a second look. Any value greater than the default of a single connection would have shown improvements right away in this capped environment. However, sixteen connections (16*5 Gbps each) is a theoretical maximum of 80 Gbps, far beyond both endpoints in this setup, the EC2 instance’s own 25 Gbps aggregate limit, and the 10.2 Gbps FSx filesystem’s own provisioned throughput.

Two connections would theoretically already reach close to the FSx throughput ceiling, and three would cover it with a comfortable buffer. Going straight to sixteen removed the bottleneck, but it also means the OS is maintaining far more resources with no measurable benefit.

Parallelism doesn’t scale as a clean multiplication of a single connection’s throughput. Other resources, on both the client and server sides, become part of the equation as concurrency increases. As with any other piece of infrastructure or software, finding the right number requires proper benchmarking.

As a database support team, our role was to identify and prove the cause behind the lag, provide the evidence, and propose a possible path forward.

Conclusion

A component reporting low utilization against its provisioned limit doesn’t rule out an I/O bottleneck elsewhere in the path, it only rules out that specific limit. In this case, FSx itself was never the problem. The actual constraint was the single-flow network bandwidth cap between the EC2 instance and its FSx filesystem, throttling every request that went through it.

Two things are worth carrying into the next investigation, like this one. First, vmstat’s “b” column and a sustained “wa” value are cheap and fast signals that something downstream of PostgreSQL is the bottleneck, before diving into storage-specific tooling. Second, when checking a metric against a provisioned limit, consider the full distribution of samples, not just the peak or a single percentile. A value that repeatedly hits the same ceiling (even one well below the provisioned maximum) is a stronger signal than a single peak value.

The post Replication Lag on AWS FSx: The Hidden EC2 Single-Flow Bandwidth Limit appeared first on Percona.

Jul
15
2026
--

PostgreSQL Meta Commands that save time every day

When most people start working with PostgreSQL, they quickly learn SQL:

SELECT * FROM employees;

But very soon, another world opens up inside psql — a set of commands that don’t look like SQL, don’t end with semicolons.

These are PostgreSQL Meta Commands, and they quietly power the daily workflow of almost every experienced DBA.

Meta commands are not about querying data — they are about navigating, inspecting, and controlling the PostgreSQL session/database efficiently.

What exactly are Meta Commands?

Meta commands are special instructions interpreted by psql, not PostgreSQL itself.

That means:

  • They are not SQL
  • They execute instantly on the client side
  • They are specific to the psql terminal tool
  • They do not end with semicolon like SQL statements
  • The main focus area for meta commands is database interaction and not the interaction with the data in the database.

Cheat Sheet (Quick Reference) 

The most commonly used meta commands are as follows. There are many more apart from these, however, below are the most frequently used ones:

Connect and Manage Sessions

These commands help discover databases, establish connections, and verify the current session.

\c Connect to another database 
\l List all the databases available in the cluster
\l+ List all the databases available in the cluster with more details, like DB Size, etc
\conninfo Displays information about the current database connection

Please find the example of the commands used to connect and manage sessions in the screenshot below:

Inspect Database Objects                

The
\d 
family of commands is one of the most powerful features of
psql 
. These commands can be used to discover database objects, inspect their definitions, and view additional metadata.

\d Describe database objects or list objects visible in the current search path.
\d object_name Describe a specific table, view, sequence, or other database object.
\d+ object_name Display extended information about an object.
\dt List tables. Supports schema names and wildcard patterns.
\di List indexes. Supports wildcard patterns.
\dn List schemas in the current database.
\du List database roles.
\db List tablespaces
\dx List installed extensions
\df List functions and procedures
\sf function name Displays the source code of the specific function/procedure

Using object names and wildcards

Most object-inspection commands accept object names, schema-qualified names, and wildcard patterns.

For example:

\dt

Lists all tables in the current search path.

\dt public.*

Lists all tables in the public schema.

The same pattern matching is supported by several other meta-commands, including \di, \df, and the \d family.

Please find the example of the \d family commands in the screenshot below:

Format Query Results

Several meta-commands are available to improve the readability of query output, particularly when working with wide result sets.

\x [on|off|auto] Toggle expanded (vertical) display
\o filename Redirect query output to a file or pipe.
\o Restore query output to the terminal.

Monitor Query Executions

These commands assist in measuring query performance and repeatedly executing queries for monitoring purposes.

\timing [on|off] Toggle Query execution timing
\watch seconds Re-execute the current query at the specified interval

Execute and Automate tasks

These commands simplify repetitive tasks and enable integration between psql, SQL scripts, and the operating system

\i filename Execute the commands from the file
\gexec Execute each field returned by a query as an SQL statement.
\! command Execute a shell command without leaving a psql prompt

Get Help

Built-in help commands provide quick access to both psql meta-command documentation and PostgreSQL SQL syntax without leaving the terminal.

\? Display all available psql meta-commands.
\h List SQL commands for which syntax help is available.
\h command Display syntax help for a specific SQL command.

What is .psqlrc?

.psqlrc is a startup file in the home directory that psql reads when a session begins. It can hold meta-commands and SQL that run before the first prompt. The main benefit is consistent defaults — timing, formatting, and a custom prompt — without repeating setup each time, which speeds daily work and reduces connection mistakes across databases.

A minimal .psqlrc might look like this:

\timing on 
\x auto

These settings load automatically on every new psql session as highlighted below:

Conclusion

PostgreSQL is powerful because of SQL — but for DBAs, psql meta commands make daily management far easier and more efficient.

Most developers use only a handful like \dt or \d. But experienced DBAs rely on a much broader toolkit to:

  • Investigate production issues faster
  • Navigate systems efficiently
  • Reduce reliance on repetitive SQL
  • Repetitive tasks can be automated
  • Debug complex problems quickly

An easy way to understand the relationship between SQL and PostgreSQL meta commands is to compare them to driving a car.

SQL is like driving the car — it is the primary means of reaching a destination. It is used to retrieve, insert, update, and delete data, enabling applications and users to interact with the information stored in the database.

Meta commands, on the other hand, are like the car’s dashboard. While the dashboard does not move the vehicle, it provides essential information such as speed, fuel level, engine health, navigation status, and warning indicators. Driving without a dashboard is certainly possible, but it would mean operating with limited visibility into the vehicle’s condition and performance.

Similarly, SQL is responsible for manipulating and retrieving data, whereas PostgreSQL meta commands provide valuable insight into the database environment itself. They help administrators inspect database objects, navigate schemas, monitor sessions, examine roles and privileges, review object definitions, and perform numerous administrative tasks efficiently.

In essence, SQL enables interaction with the data, while meta commands enable interaction with the PostgreSQL environment. Together, they form a complementary toolkit that allows database professionals to work more effectively, troubleshoot issues faster, and administer PostgreSQL with greater confidence.

The post PostgreSQL Meta Commands that save time every day appeared first on Percona.

Jun
30
2026
--

Community Docker Images: keeping the operator open without a vendor registry lock-in

PostgreSQL community images address a real gap in how a Kubernetes database operator earns your trust. Running a database operator on Kubernetes means trusting two things: the code, and the container images the operator pulls. The code is on GitHub, easy to inspect, easy to fork. The container images, the registry that hosts them, and the license that governs them all sit with the vendor, and any of those three can change without the source repository changing at all. Starting with Percona Operator for PostgreSQL 3.0.0, you can run the operator against community images you build yourself from the official PostgreSQL packages on download.postgresql.org, in a registry you control.


TL;DR

  • Community Docker Images: tech preview in PGO 3.0.0, official in 3.1.0. Point the operator at upstream-built PostgreSQL images instead of the Percona Distribution images.
  • Build them yourself from the official PostgreSQL source. The Dockerfiles pull packages from download.postgresql.org (the PGDG repositories), so the trust chain runs from PGDG to your registry with no vendor in the middle.
  • There are limits. Anything Percona-specific (TDE in our distribution build, for example) does not exist in an upstream-built image. That trade is intentional.

In this post:

  • How open source gets diluted in practice
  • Why distributions exist anyway, honestly
  • How Community Docker Images work
  • Limits of the upstream path
  • What to try, what to tell us


How open source gets diluted

Open source has changed in the last few years, and not always for the better. Companies have learned that you can keep a project’s source code fully open and still capture most of the lock-in by quietly closing the parts that matter in production: the release artifacts, the container images, the supported OS list, the certified Kubernetes distributions, the marketplace listings.


Same project, closed artifacts

You can have a fully community CNCF project that does not appear on the Red Hat Marketplace except as a paid Enterprise edition. Similarly, you can have a vendor that ships one packaging in the community and a richer one in Enterprise with the features you actually need in production. The license still says “open source.” The practical experience says “you depend on us.” And the source repository’s license is not the only license that matters here: a vendor can change the license, the trademark policy, or the distribution terms on the container images alone, while leaving the source repository untouched. That has happened in the PostgreSQL operator space recently, and the community noticed.


Why the community is right to be wary

Nobody outside the vendor can predict when a license will change, when a feature will move behind a paywall, or when an external contribution will get rejected because it competes with an Enterprise feature. Recent history has plenty of examples and the PostgreSQL community has been paying attention. When this community resists vendor-controlled distributions, it is not nostalgia. It is a rational read of where things have gone before.

I work on Percona’s PostgreSQL operator, so I see this conversation from the vendor side. The skepticism is fair. The honest question for us is what to do about it.
 

Why distributions exist anyway

Acknowledging the community’s concerns does not mean distributions are pointless. There are real reasons to ship one, and pretending otherwise makes for bad blog posts.
 

What a distribution buys you

A vendor-built distribution lets the vendor:

  1. Control the build process, dependencies, and defaults so they fit a specific user shape.
  2. Ship hotfixes faster, because the whole release path sits in one place.
  3. Fork PostgreSQL itself when something the upstream community will not accept, or can take years to accept, matters to customers, such as Transparent Data Encryption.
  4. For a Kubernetes operator, ship images with exactly the tools and extensions the operator supports, and skip everything else. The CVE surface stays smaller.
  5. Give QA and Service teams a predictable environment. “We support extensions A, B, C and not D, X, Z” is only honest if QA actually exercises A, B, C and the Service team can work with them in the production environment.
  6. Give customers one accountable party for the full release cycle, from hotfix through package availability. Some teams explicitly need that contract for compliance and audit reasons.
  7. And yes, less positive reasons that we covered above also apply, which is exactly the part the community keeps pointing at.


The trade-off you accept

If you run the vendor distribution, you accept that the vendor’s registry, image policy, and supported-extension matrix become part of your stack. If the vendor changes any of that, your operator deployment changes with it. That is not hypothetical for users who have lived through it on other products.

So the real question is whether you can keep the benefits a distribution provides for the users who want them, while leaving an honest, supported door open for users who do not. That is the door PGO 3.0.0 opens.


Community PostgreSQL Images in PGO 3.0.0

Starting with Percona Operator for PostgreSQL 3.0.0, the operator can run against images built from upstream PostgreSQL packages, not just the Percona Distribution images. This is what we are calling Community PostgreSQL Images. In 3.0.0, the feature ships as a tech preview. In 3.1.0, these images become part of our official release cycle and are fully documented.

One of the main advantages of Community Docker Images is that the community can request or contribute any extension that does not exist in the official Percona PostgreSQL distribution. TimescaleDB and Citus are the first examples: the community asked for them, and we shipped both in the Community Images set from day one.


How to use “Community PostgreSQL images”

The operator does not care where the image came from, as long as the image meets the operator’s runtime expectations 

A typical CR using a community image looks like this:

apiVersion: pgv2.percona.com/v2
kind: PerconaPGCluster
metadata:
  name: cluster1
spec:
  image: registry.example.com/postgresql-community:18
  postgresVersion: 18
  proxy:
    pgBouncer:
      image: registry.example.com/pgbouncer-community:1.23
  backups:
    pgbackrest:
      image: registry.example.com/pgbackrest-community:2.51
  # other spec fields unchanged from a normal CR

The fields that change are spec.image, spec.proxy.pgBouncer.image, and spec.backups.pgbackrest.image. You can build and publish all three images under your own registry, with your own tags if that helps you track versions. The operator drives the rest of the deployment the same way it always has: instances, backups, replication, monitoring, all of it.


What ships are in each image

Each Community Docker Image is a thin layer over the chosen base (UBI9 or UBI8) plus the packages the operator needs for that role. Where you see {N}, substitute the PostgreSQL major you build for (17, 18, and so on).

postgres image (e.g. postgres17):

Package Role
postgresql{N}-server PostgreSQL server
postgresql{N}-contrib contrib modules
pg_repack_{N} online table/index reorganization
pgaudit_{N} audit logging
set_user_{N} privilege escalation control
pgvector_{N} vector similarity search
wal2json_{N} WAL to JSON logical decoding
pg_cron_{N} in-database cron scheduler
pgbackrest&lt;/code> backup/restore tool
patroni HA cluster manager
timescaledb-2-postgresql-{N} time-series extension (x86_64 only; EL9 only for PG18)
citus_{N} distributed PostgreSQL (PG16+ only)

pgbackrest image:

Package Role
pgbackrest backup/restore tool only

pgbouncer image:

Package Role
pgbouncer connection pooler only


The split is intentional. The postgres image ships the full operator-aware runtime. The backup and proxy images stay minimal. As a result, the operator’s components are in separate failure domains and shrink the attack surface of each container.


Limits worth being honest about

A community image is not a Percona Distribution image. Two practical consequences:

  • Distribution-only features will not work. Transparent Data Encryption, for example, lives in the Percona Distribution build. A community image built from upstream PostgreSQL does not include it. If you depend on TDE, run the distribution image.
  • Support boundaries are different. Percona Support is responsible for the Percona Distribution images and the operator code. A community image you built yourself

Ultimately, these are the right trade-offs. The point of community images is to give you transparency and control. Taking care of your own image is part of that deal. At the same time, we publish all three images under perconalab/percona-postgresql-operator on Docker Hub so you can evaluate the tech preview without standing up your own build pipeline first. perconalab is Percona’s non-production namespace, so use those images for testing. For production, build and sign your own.

UBI9 (EL9):

docker.io/perconalab/percona-postgresql-operator:main-postgres14-community
docker.io/perconalab/percona-postgresql-operator:main-postgres15-community
docker.io/perconalab/percona-postgresql-operator:main-postgres16-community
docker.io/perconalab/percona-postgresql-operator:main-postgres17-community
docker.io/perconalab/percona-postgresql-operator:main-postgres18-community
docker.io/perconalab/percona-postgresql-operator:main-pgbackrest-community
docker.io/perconalab/percona-postgresql-operator:main-pgbouncer-community
docker.io/perconalab/percona-postgresql-operator:main-upgrade-community

UBI8 (EL8):

docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres14-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres15-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres16-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres17-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-postgres18-community
docker.io/perconalab/percona-postgresql-operator:main-ubi8-upgrade-community


How to build the images

The Dockerfile, the package list, and a sample CI job ship in percona-docker/postgresql-containers/community. The build is a regular make target on top of docker buildx, so you can run it on any multi-platform builder.

# Prerequisites: docker buildx with a multi-platform builder
docker buildx create --use --name multiarch

# Build and push all PostgreSQL community images (UBI9 / EL9)
git clone https://github.com/percona/percona-docker
cd percona-docker/postgresql-containers/community
make all TAG=1.0.0 REGISTRY=myrepo/percona-postgresql-operator

# Or a single image
make postgres17 TAG=1.0.0 REGISTRY=myrepo/percona-postgresql-operator

# UBI8 / EL8 variants
make all-ubi8 TAG=1.0.0-ubi8 REGISTRY=myrepo/percona-postgresql-operator

make all builds all three images (postgres, pgBouncer, pgBackRest) so they stay version-aligned. Override REGISTRY and TAG to point at your own namespace and tagging scheme. Once the images are in your registry, plug them into the CR fields shown earlier, and the operator picks them up.

Full build documentation: percona-docker/postgresql-containers/community/README.md.


How to contribute

Community images live in percona/percona-docker, and the build is driven by a transform.py generator that produces the Dockerfiles under build/. The files under build/ are regenerated on every sync, so contributions go through the generator, never through the generated files.

Full contribution guide: community/CONTRIBUTING.md.


How to provide feedback

Two channels, depending on the shape of the feedback:

  • GitHub issue on percona/percona-postgresql-operator with the community-images label. Use this for bug reports, missing extensions, build problems, and concrete requests. The label keeps all community-image reports in one filter the team watches.


What’s next

The first step was taking full engineering ownership of Percona Operator for PostgreSQL as an independent project, so the roadmap, the release cadence, and the governance live with one team that the community can talk to directly. Community PostgreSQL Images are the next step in that same commitment. If the community adopts this path, we have ideas for what to invest in next.

We will let the community tell us. If this is useful, we keep investing here. We are ready to add more features to the operator around Community Images. Conversely, if nobody adopts it, that is also a signal, and an honest one.

Try the tech preview in 3.0.0. Open an issue if the build flow is rougher than it should be. Tell us what you want next on the forum or directly on GitHub.


Try It Out

The post Community Docker Images: keeping the operator open without a vendor registry lock-in appeared first on Percona.

May
28
2026
--

Percona Operator for PostgreSQL 3.0.0: Hard Fork, OLM Scoping, Major Upgrades


The Percona Operator for PostgreSQL 3.0.0 is here. This is the release that completes the hard fork of the operator from the Crunchy Data PostgreSQL Operator into a fully independent project, with a dedicated upstream.pgv2.percona.com API group for the inherited CRDs, an automatic CRD-rename rollout for existing 2.x installs on upgrade, and a public roadmap that drives what comes next.

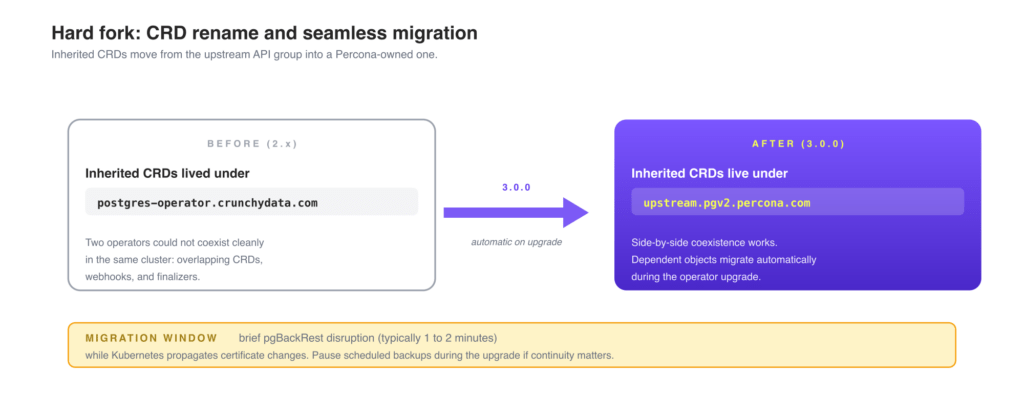
This release ships three headline changes that matter for production teams. The CRD renaming under a Percona-owned API group, which finally lets the Crunchy operator and the Percona operator coexist in the same Kubernetes cluster. Proper OLM namespace scoping for OpenShift installations. And the move to the official Percona Distribution image for major PostgreSQL version upgrades, aligning the upgrade path with the same binaries that run in your clusters.


All three land in service of the same goal: making 3.0.0 a clean, durable operational baseline for the operator’s next several years as an independent project. Future releases will be shaped by what the community asks for and contributes back. The public roadmap is the durable signal of that commitment.

In this post, you will learn about:

  • The hard fork and how the CRD rename unlocks coexistence with the Crunchy operator
  • OLM namespace-scoping improvements for OpenShift installations
  • The move to the official Percona Distribution image for major PostgreSQL version upgrades
  • Other improvements and the 2.7.0 deprecation
  • Supported PostgreSQL versions and platforms


Hard fork: CRDs renamed under upstream.pgv2.percona.com

The Percona Operator for PostgreSQL has, until now, been a soft fork. Custom Resources inherited from Crunchy PGO used the upstream postgres-operator.crunchydata.com API group. The two operators shared CRDs, which meant you could only run one of them in a given Kubernetes cluster. Installing both would lead to overlapping CRDs, conflicting webhooks, and finalizer collisions, so platform teams had to pick a side before they had finished evaluating.

Starting with 3.0.0, every inherited CRD is renamed into a new dedicated upstream.pgv2.percona.com API group (K8SPG-1007). Percona’s own native CRDs (such as PerconaPGCluster under pgv2.percona.com/v2) are unchanged. The change applies to the inherited resources: PostgresCluster, PGUpgrade, PGAdmin, and the rest.


Coexistence: running both operators in the same cluster

The practical effect is that the Crunchy Data PostgreSQL Operator and the Percona Operator for PostgreSQL can now run on the same Kubernetes cluster at the same time, even in the same namespaces, with no CRD or webhook conflict. That unlocks a few real workflows: evaluating both operators on the same staging cluster without spinning up a second cluster, running existing Crunchy-managed clusters in some namespaces while bringing up new Percona-managed clusters in others, or testing a new database version on the Percona side while production stays on Crunchy until you are confident. The choice between the two operators stops being all-or-nothing.


Upgrade behavior for existing 2.x installs

For an existing install, the upgrade to 3.0.0 is mechanically simple. The operator creates the new-API-group CRDs alongside the legacy ones, then runs a one-time migration that updates dependent objects (Secrets, certificates, finalizer references) to point at the new CRD instances. Existing custom resources keep working through the legacy CRDs during the transition, and once migration completes, all reconciliation moves to the new group.

Old PostgresCluster reference:

apiVersion: postgres-operator.crunchydata.com/v1beta1
kind: PostgresCluster
metadata:
  name: cluster1


New (after upgrade to 3.0.0):

apiVersion: upstream.pgv2.percona.com/v1beta1
kind: PostgresCluster
metadata:
  name: cluster1


Day-to-day, your PerconaPGCluster Custom Resource (the one most teams interact with directly) is unchanged. The rename mostly matters in three situations: when a kubectl filter or a GitOps repository hard-codes the old API group, when a CI pipeline references the legacy CRD by name, and when you run the Percona and Crunchy operators side by side and need them not to collide.

Note: During the CRD migration on upgrade, the release notes report brief disruptions to pgBackRest operations (typically 1 to 2 minutes) while Kubernetes propagates certificate changes. Plan the upgrade during a maintenance window if backup continuity is critical, or pause scheduled backups during the upgrade.

Full details on the API-group change are in the Percona PostgreSQL operator documentation.


Improved OLM namespace scoping for OpenShift

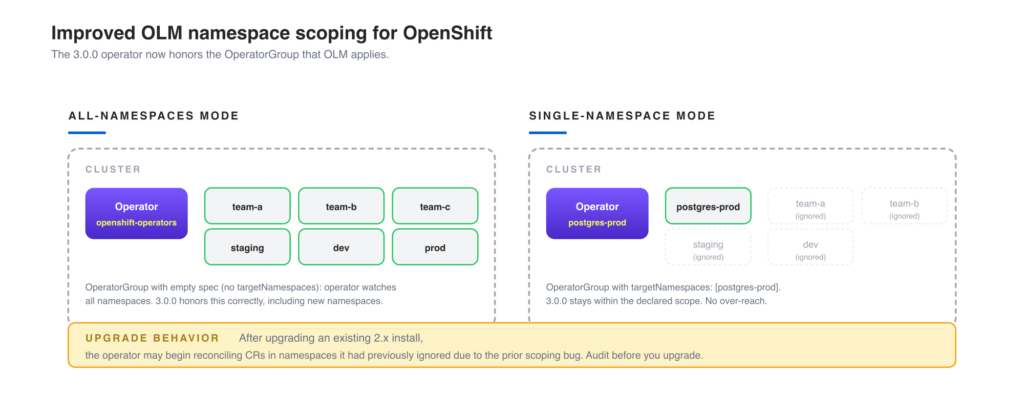
OpenShift users install operators through the OpenShift Lifecycle Manager (OLM), and OLM enforces an OperatorGroup to scope which namespaces an operator watches. In practice, 2.x had quirks: teams that selected “Single namespace” mode would sometimes see the operator reconciling CRs in other namespaces, and teams in “All namespaces” mode would sometimes see incomplete coverage when CRs were created in newly-added namespaces.

3.0.0 fixes this by aligning the operator’s namespace watch list with the OperatorGroup that OLM applies. All-namespaces installs watch all namespaces. Single-namespace installs respect the targetNamespaces set on the OperatorGroup.


Why it matters in shared infrastructure

For an OpenShift platform team running shared infrastructure, this distinction matters operationally. A typical setup has the database operator installed once in a platform namespace (such as openshift-operators) but expected to serve PerconaPGCluster resources owned by individual application teams in their own namespaces. If the operator over-reaches into namespaces it should not watch, RBAC noise multiplies. If it under-reaches, application teams file tickets about clusters that never reconcile. The 3.0.0 alignment with OperatorGroup semantics removes both failure modes.


OperatorGroup wiring

For users installing through OLM via the OpenShift web console, the install flow is unchanged. The fix is in how the operator’s reconciler interprets the OLM-supplied namespace scope after install. For users who manage OperatorGroups directly, a single-namespace install looks like this:

apiVersion: operators.coreos.com/v1
kind: OperatorGroup
metadata:
  name: percona-pg-operator-group
  namespace: postgres-prod
spec:
  targetNamespaces:
    - postgres-prod

And an all-namespaces install:

apiVersion: operators.coreos.com/v1
kind: OperatorGroup
metadata:
  name: percona-pg-operator-group
  namespace: openshift-operators
spec: {}

The empty spec: {} (or an OperatorGroup with no targetNamespaces) means “watch all namespaces” by OLM convention. The 3.0.0 operator now honors that.


Note: After you upgrade an existing 2.x install to 3.0.0, the operator may begin reconciling PerconaPGCluster resources in namespaces it had previously ignored due to the prior scoping bug. Audit existing CRs across your cluster before upgrading, especially if you have stale test clusters in unintended namespaces. The release notes call this out explicitly.

Note for community vs certified bundle users: Community OLM bundles did not support cluster-wide (all-namespaces) mode in earlier versions, 3.0.0 adds it. Certified bundles already supported cluster-wide mode, but they used a separate stable-cw channel for it with 3.0.0 the channels are unified, so users upgrading from a certified stable-cw install need to switch their subscription channel to stable to receive the upgrade.

For the full install workflow on OpenShift, see the OpenShift installation documentation.


Major PostgreSQL version upgrades now use the official Percona Distribution image


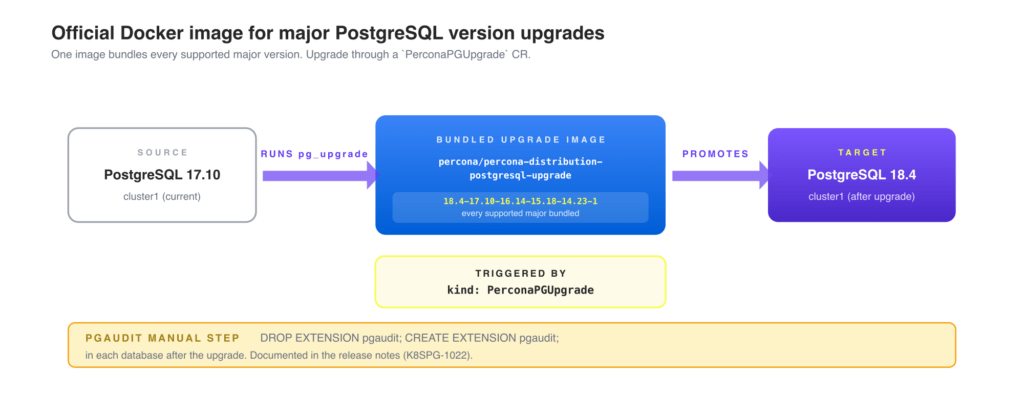
Major-version upgrades (for example, PostgreSQL 17 to 18) require running pg_upgrade, which needs binaries for both the source and target versions in the same environment. The operator has supported major-version upgrades since 2.x, but it shipped its own dedicated upgrade image to do so. That worked, but it meant a Percona-specific image lived in the upgrade path, separate from the same Percona Distribution for PostgreSQL build that runs in your clusters.


Switching to the official Percona Distribution image

In 3.0.0, the operator switches to using the official Percona Distribution for PostgreSQL image for major-version upgrades: percona/percona-distribution-postgresql-upgrade (current tag: 18.4-17.10-16.14-15.18-14.23-1, which encodes the bundled major versions). The benefit is alignment: the binaries that run pg_upgrade are the same binaries that ship in the corresponding percona-distribution-postgresql image you already run in production, built from the same source, signed the same way, and patched on the same schedule. The operator orchestrates the upgrade through the PerconaPGUpgrade Custom Resource that names the source and target versions, the upgrade image, and the target component images (PostgreSQL, pgBouncer, pgBackRest).


Running an upgrade through the PerconaPGUpgrade CR

A PostgreSQL 17 to 18 upgrade looks like this:

apiVersion: pgv2.percona.com/v2
kind: PerconaPGUpgrade
metadata:
  name: cluster1-17-to-18
spec:
  postgresClusterName: cluster1
  image: docker.io/percona/percona-distribution-postgresql-upgrade:18.4-17.10-16.14-15.18-14.23-1
  fromPostgresVersion: 17
  toPostgresVersion: 18
  toPostgresImage: docker.io/percona/percona-distribution-postgresql:18.4-1
  toPgBouncerImage: docker.io/percona/percona-pgbouncer:1.25.2-1
  toPgBackRestImage: docker.io/percona/percona-pgbackrest:2.58.0-2

Apply it with kubectl apply -f upgrade.yaml -n <namespace>. The operator reconciles the upgrade as a controlled, observable process: it brings the cluster down for the upgrade window, runs pg_upgrade from the bundled image, brings the cluster back up on the target version, and updates pgBouncer and pgBackRest images in the same step.

Operationally, this matters for teams running on PostgreSQL’s annual major-version cadence. Every September brings a new major release; staying on a supported version means executing one major upgrade per cluster per year. Pulling the upgrade image from the same percona-distribution-postgresql registry path as the runtime image means image-signature verification, mirror-to-private-registry rules, and CVE-scanning policies you already have in place apply to the upgrade flow without any per-image exception.

Note: The pgaudit extension is not upgraded automatically. After the operator completes the major version upgrade, drop and recreate pgaudit manually in each database that uses it: DROP EXTENSION pgaudit; followed by CREATE EXTENSION pgaudit;. The release notes call this out as a required step (K8SPG-1022). Also worth scanning for collation-dependent indexes after the upgrade and refreshing collation metadata with ALTER DATABASE <name> REFRESH COLLATION VERSION; per the upstream PostgreSQL 18 release notes.

Full procedure, prerequisites, and rollback notes are in the major version upgrade documentation.

Other Improvements

Operational polish landed alongside the headline changes:

  • Go 1.26 update (K8SPG-1019): the operator binary is now built with Go 1.26, picking up performance optimizations, tooling improvements, and the security fixes that landed in the Go runtime since the previous release.
  • pgaudit upgrade documentation (K8SPG-1022): the major-version upgrade docs now include an explicit pgaudit drop-and-recreate procedure, surfacing the gotcha that previously caught users mid-upgrade.

The release also defaults the cluster-upgrade documentation to PostgreSQL 18 across all examples and tutorials.


Supported software and platforms

The Percona Operator for PostgreSQL 3.0.0 is developed and tested on:

  • PostgreSQL: 14.23-1, 15.18-1, 16.14-1, 17.10-1, 18.4-1 
  • pgBackRest: 2.58.0-2
  • pgBouncer: 1.25.2-1
  • Patroni: 4.1.3
  • PostGIS: 3.5.6
  • PMM Client: 2.44.1-1 and 3.7.1


Supported Kubernetes platforms:

  • Google Kubernetes Engine (GKE) 1.33 to 1.35
  • Amazon Elastic Kubernetes Service (EKS) 1.33 to 1.35
  • OpenShift 4.18 to 4.21
  • Azure Kubernetes Service (AKS) 1.33 to 1.35
  • Minikube 1.38.1 (Kubernetes v1.35.1) for local development


Deprecation: 2.7.0 support dropped

Support for Custom Resource Definitions from operator version 2.7.0 has been removed. If you are still on 2.7.0, upgrade to 2.8.x or 2.9.x first, then upgrade to 3.0.0. The CRD migration described above only handles 2.8.x and 2.9.x to 3.0.0 transitions cleanly.


Conclusion

3.0.0 is the release where the Percona Operator for PostgreSQL becomes a fully independent project. The CRD rename removes the last upstream coupling that mattered operationally. The OLM scoping fix removes a long-standing OpenShift quirk. The official major-version upgrade image removes one of the more painful operational gaps in earlier versions.

Beyond the technical work, 3.0.0 is also where Percona’s commitment to community-driven development moves from intent to mechanism. The public roadmap is open. The issue tracker is open. The images are freely redistributable. Future releases will be shaped by what the community asks for, files, and contributes back. If there is a feature you want to see in 3.1.0 or 3.2.0, open an issue or a PR, that is where the work happens now.


Try It Out

The post Percona Operator for PostgreSQL 3.0.0: Hard Fork, OLM Scoping, Major Upgrades appeared first on Percona.

May
27
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Backup-Restore and PV Reuse


A Percona PostgreSQL operator pgBackRest restore is the simplest way to move off the Crunchy Data PostgreSQL Operator: take a full Crunchy backup, point the new Percona cluster’s dataSource at the existing pgBackRest archive, and the cluster bootstraps from it before its first start. This post covers that path, plus a second option, persistent-volume reuse, for cases where you want to skip the data copy entirely.

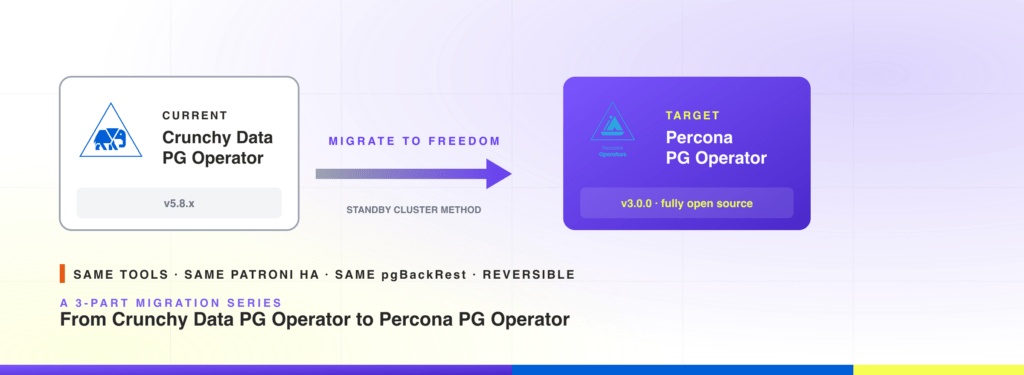
This is part 3 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0Part 2 covered the standby cluster method, the safest migration path when downtime budget is tight.

This post covers two simpler paths:

  • Backup and restore, the fastest if you can tolerate a short application-downtime window
  • Persistent volume reuse, when you want to skip the data copy entirely and keep the existing PGDATA

If you are landing here cold, start with part 1 for the why, then read Part 2 for the standby method. The rest of this post assumes you have already decided to migrate and want a tested playbook.

Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any S3-compatible service. Required for the backup-and-restore method, optional for PV reuse.
Tools kubectlhelm (v3)

Different versions may have slight differences in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


What this post does NOT cover

  • Application-side connection-string changes beyond updating to the new pgBouncer service
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations
  • Crunchy enterprise-only features like TDE or pgBackRest custom encryption
  • Operating two operators against the same namespace before the hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


1. Migration using backup and restore

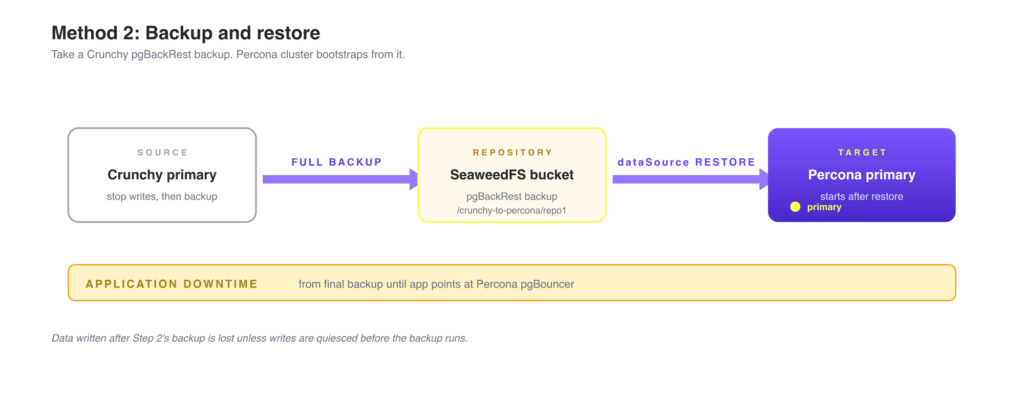
This is often the fastest and simplest path, especially when you do not need a live standby. You take a full backup of the Crunchy source cluster, then create a Percona cluster that automatically restores from that backup before its first start.

Data written between the final backup and the application cutover is lost, so the migration window is the time between those two events. For a near-zero-downtime alternative, see part 2: standby cluster method.


Overview

Before you begin

Set the namespace once. Every command in this guide reads from this variable:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: "n" is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.

Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secrets.yaml:

# Copy and edit the file first to set your credentials.
kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/01-pgbackrest-secrets.yaml

Both contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket. The repo1-path value must match the path that will be referenced in the Percona dataSource.pgbackrest.global.repo1-path field.

Optional: deploy the Crunchy operator for testing. The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait

To start a fresh source cluster for testing, apply examples/02-crunchy-source-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/02-crunchy-source-cluster.yaml

The key pgBackRest settings:

global:
  repo1-path: /crunchy-to-percona/repo1   # source repo referenced in Percona dataSource
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1

Wait for the cluster and its pgBackRest stanza to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 2. Trigger a full backup (the migration cutover point)

This is the backup the Percona cluster will restore from. Stop accepting writes on the application side before triggering it to ensure a consistent snapshot, or accept that data written after this backup will be lost.

kubectl annotate postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"

kubectl wait job \
  --selector postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Deploy the Percona Operator

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s

Step 4. Create the Percona cluster from the backup

Apply examples/03-percona-restored-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/03-percona-restored-cluster.yaml

The key section that bootstraps the cluster from the Crunchy backup:

dataSource:
  pgbackrest:
    stanza: db
    configuration:
      - secret:
          name: percona-pgbackrest-secret
    global:
      # Must match repo1-path in the Crunchy source cluster exactly.
      repo1-path: /crunchy-to-percona/repo1
      repo1-s3-uri-style: path
      repo1-s3-verify-tls: "n"
    repo:
      name: repo1
      s3:
        bucket: pg-migration
        endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
        region: us-east-1

The Percona cluster’s own backup repository must use a different path from the Crunchy source:

backups:
  pgbackrest:
    global:
      repo1-path: /percona-restored/repo1   # different from Crunchy's path

As soon as the Custom Resource is applied, the cluster is bootstrapped from the storage referenced in dataSource and then started. Once the cluster becomes ready, you can immediately create new backups; in this case, repo1 from the backups section will be used as the target repository.

Wait for the cluster to reach ready state:

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify the data was restored successfully:

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f. The cluster is the primary and accepts writes.

Step 5. Verify the cluster is healthy

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

kubectl wait perconapgcluster/percona-restored \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Step 6. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-backup-restore/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery baseline on the Percona cluster’s own repository. All future PITR restores will use this backup, independent of the Crunchy archive.

Step 7. Reconnect your application

kubectl get service -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/role=pgbouncer

Step 8. Clean up the Crunchy cluster

Once the migration is verified and your application is connected to the new cluster:

kubectl delete postgrescluster crunchy-source -n $MIGRATION_NS
helm uninstall pgo -n $MIGRATION_NS


Rollback

Until Step 8, rollback is straightforward: switch the application connection string back to the Crunchy pgBouncer service. The Crunchy primary still holds the authoritative state because no writes were directed at the Percona cluster during the cutover (you stopped writes before Step 2). Any writes the application sent to the Percona cluster after cutover will not be present on Crunchy and would need to be replayed manually.

After Step 8, rollback requires restoring the Crunchy cluster from a backup, which is feasible because the original repo1 is still in the bucket.

Troubleshooting

archive.info missing. The repo1-path in dataSource.pgbackrest.global must match the Crunchy source cluster’s repo1-path exactly:

kubectl get postgrescluster crunchy-source -n $MIGRATION_NS \
  -o jsonpath='{.spec.backups.pgbackrest.global.repo1-path}'

kubectl get perconapgcluster percona-restored -n $MIGRATION_NS \
  -o jsonpath='{.spec.dataSource.pgbackrest.global.repo1-path}'


Restore job fails with TLS errors. pgBackRest requires HTTPS even with repo1-s3-verify-tls: "n". Verify SeaweedFS is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "


Cluster stuck in restoring state. Check the pgBackRest restore job logs:

kubectl logs \
  --selector postgres-operator.crunchydata.com/cluster=percona-restored,postgres-operator.crunchydata.com/pgbackrest-restore=percona-restored \
  -n $MIGRATION_NS \
  -c pgbackrest

Data missing after restore. The restore captures data up to the latest backup. If post-backup data is critical, re-run the backup on the Crunchy cluster after quiescing writes, then delete and recreate the Percona cluster to restore from the newer backup.

2. Migration using existing persistent volumes

This method reuses the Crunchy primary’s PGDATA persistent volume directly. It avoids a full backup-restore cycle: you retain the Crunchy primary’s PV, delete the Crunchy cluster, then create a Percona cluster whose PVC binds to that same PV. PostgreSQL starts on the existing data directory without any restore step.

It is useful when:

  • you want to avoid copying data
  • your storage is very large
  • you must preserve the original data directory exactly
  • you removed the cluster but kept the PV


Overview


Before you begin

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS

Step 1. Deploy the Crunchy and Percona operators

Both operators run in the same namespace. Crunchy PGO is uninstalled during the migration once the PV is retained.

Note (Crunchy): The Helm install for Crunchy PGO below is shown only as a quick way to reproduce this blog post’s example. If you are running Crunchy PGO in production, follow the official Crunchy Data documentation for installation. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Note (Percona): The kubectl apply of the Percona operator below uses defult configuration of v3.0.0 from the operator repo for reproducibility of this guide. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation to ensure the cluster configuration is properly sized and configured for your workload and traffic requirements.

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

kubectl wait deployment pgo \
  -n $MIGRATION_NS --for=condition=Available --timeout=120s

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS --for=condition=Available --timeout=120s

Step 2. Start the Crunchy source cluster

If you already have a running Crunchy cluster with replicas: 1, proceed to Step 3.

To start a fresh cluster for testing:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/01-crunchy-source-cluster.yaml

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s

Step 3. Stop writes and identify the primary PV

Stop your application from writing to the database. This is the start of the downtime window. Then identify the primary pod, its PVC, and the backing PV:

PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -o jsonpath='{.items[0].metadata.name}')

PVC_NAME=$(kubectl get pod -n $MIGRATION_NS "${PRIMARY}" \
  -o jsonpath='{.spec.volumes[?(@.name=="postgres-data")].persistentVolumeClaim.claimName}')

PV_NAME=$(kubectl get pvc -n $MIGRATION_NS "${PVC_NAME}" \
  -o jsonpath='{.spec.volumeName}')

echo "Primary pod: ${PRIMARY}"
echo "PVC:         ${PVC_NAME}"
echo "PV:          ${PV_NAME}"

Step 4. Configure the source cluster to retain PVs

If you want to delete the Crunchy source cluster but keep the persistent volumes, the PV reclaim policy must be set to Retain. For dynamically provisioned PersistentVolumes, the default reclaim policy is Delete, which removes the data once there are no more PersistentVolumeClaims associated with the PV.

kubectl patch pv "${PV_NAME}" \
  -p '{"spec":{"persistentVolumeReclaimPolicy":"Retain"}}'

kubectl get pv -n $MIGRATION_NS

Delete the Crunchy cluster and uninstall PGO:

kubectl patch postgrescluster crunchy-source -n $MIGRATION_NS \
  --type=json -p='[{"op":"remove","path":"/metadata/finalizers"}]' 2>/dev/null || true

kubectl delete postgrescluster crunchy-source -n $MIGRATION_NS
helm uninstall pgo -n $MIGRATION_NS

After the PVC is deleted, the PV enters Released state. A Released PV retains its old claimRef and cannot be claimed by a new PVC until it is cleared:

kubectl patch pv "${PV_NAME}" --type=json \
  -p='[{"op":"remove","path":"/spec/claimRef"}]'

kubectl wait pv "${PV_NAME}" \
  --for=jsonpath='{.status.phase}'=Available \
  --timeout=60s

Label the PV so the Percona PVC selector binds to it exclusively. This prevents accidental binding to another available volume:

kubectl label pv "${PV_NAME}" percona-pv-migration=migrated


Step 5. Create the Percona cluster with the retained volume

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/02-percona-migrated-cluster.yaml

The key section that binds the PVC to the labelled PV:

instances:
  - name: instance1
    replicas: 1
    dataVolumeClaimSpec:
      selector:
        matchLabels:
          percona-pv-migration: migrated

The Percona Operator creates a PVC with that selector. The PVC binds to the labelled PV, and PostgreSQL starts on the existing PGDATA directory with no restore needed. pgBackRest uses a local PVC-backed repository (repo1.volume), so no S3 credentials or external storage are required, but you can use S3 storage as well.

Wait for the cluster to become ready and verify the data is intact:

kubectl wait perconapgcluster/percona-migrated \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-migrated,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f. The cluster is the primary and accepts writes.

Step 6. Scale up replicas

The cluster started with a single replica to reuse the migrated PV. Once the primary is healthy, drop the PVC selector and scale out so the operator can provision fresh replica volumes from the storage class:

kubectl patch perconapgcluster percona-migrated \
  --namespace $MIGRATION_NS \
  --type=json \
  -p='[
    {"op":"remove","path":"/spec/instances/0/dataVolumeClaimSpec/selector"},
    {"op":"replace","path":"/spec/instances/0/replicas","value":3}
  ]'

kubectl wait perconapgcluster/percona-migrated \
  --namespace $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=300s

Removing the selector here is important: leaving it in place would cause the new replica PVCs to fail provisioning because no other PV carries the migration label.

Step 7. Take a post-migration backup

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-pv/examples/03-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates the first backup on the Percona cluster’s local pgBackRest repository, establishing a baseline for future PITR restores.

Step 8. Reconnect your application

kubectl get service -n $MIGRATION_NS \
  --selector postgres-operator.crunchydata.com/cluster=percona-migrated,postgres-operator.crunchydata.com/role=pgbouncer

Step 9. Cleanup

After the migration is verified, remove the migration label from the PV (Step 6 already removed the PVC selector that depended on it):

kubectl label pv "${PV_NAME}" percona-pv-migration-


Rollback

PV migration is the least rollback-friendly of the three methods. Once the Percona cluster has started writing to the PGDATA directory, the original Crunchy timeline is gone. If you need a way back, take a Crunchy-side pgBackRest backup before Step 4 and treat that backup as your rollback point. Recovery is then a fresh Crunchy cluster restored from that backup.

Troubleshooting

PVC stays in Pending state. The PVC selector did not match the labelled PV. Verify the label and PV phase:

kubectl get pv "${PV_NAME}" --show-labels
kubectl get pv "${PV_NAME}" -o jsonpath='{.status.phase}'

PostgreSQL fails to start (data directory errors). Check the database container logs:

kubectl -n $MIGRATION_NS logs "${PERCONA_PRIMARY}" -c database

If the Crunchy cluster was shut down uncleanly, there may be incomplete WAL. Patroni will attempt crash recovery automatically; check the logs for progress.

PV was deleted before setting Retain. If the PV was deleted along with the PVC (default Delete policy), the data is gone and PV migration is no longer possible. Use the backup-and-restore migration above, restoring from the most recent pgBackRest backup.


Conclusion

Two more migration paths from the Crunchy Data PostgreSQL Operator to the fully open-source Percona PostgreSQL Operator. Combined with Part 2, the series gives you three production-tested options:

  • Standby cluster (part 2): near-zero downtime via streaming replication and pgBackRest standby
  • Backup and restore (this post): the simplest path, restoring directly from a Crunchy pgBackRest backup
  • Persistent volume reuse (this post): when you want to keep storage and skip the data copy

All three approaches are safe, predictable, and reversible, with the rollback caveats noted in each section. Because Percona’s operator, images, and tooling are 100 percent open source, you keep full control: you can always migrate back to the Crunchy operator, or out to another open-source operator (Zalando, StackGres, CloudNativePG) using the same patterns. That last journey is a topic for a future post.

This post covers basic deployment patterns and simplified configuration examples. If your environment uses custom images, Crunchy enterprise features, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Backup-Restore and PV Reuse appeared first on Percona.

May
24
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method

A Crunchy to Percona PostgreSQL migration is more straightforward than most cross-operator moves on Kubernetes, because the Percona PostgreSQL Operator is a hard fork of the Crunchy Data PostgreSQL Operator. Same Patroni HA, same pgBackRest backups, same overall CRD shape. This post walks through the safest of the three migration paths: a standby cluster method with near-zero downtime.

This is part 2 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0.

This post is the first practical playbook of the series. It covers the standby cluster method, the safest migration path when the downtime budget is tight. Part 3 will cover two simpler paths: backup-and-restore and persistent-volume reuse.

If you are landing here without context on why you might want to migrate at all, start with part 1. The rest of this post assumes you have already decided to move and want a tested playbook.


Migration approach in one paragraph

The Percona PostgreSQL Kubernetes Operator is a hard fork of the Crunchy Data PostgreSQL Kubernetes Operator, which simplifies the migration paths considerably: the same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both operators. All three migration paths in this series are reversible: because Percona’s operator is fully open source and remains compatible with the same backup format, the move back to Crunchy is also possible if your team decides to walk it


A note on the storage layer

All examples in this guide use an in-cluster SeaweedFS instance as the pgBackRest S3 repository. SeaweedFS is Apache-2.0 licensed, actively maintained, and a clean drop-in replacement for the role MinIO used to fill in this stack. Any other S3-compatible storage works just as well: AWS S3, Google Cloud Storage (via HMAC keys), Ceph RadosGW, Cloudflare R2, and so on. For non-SeaweedFS endpoints, remove repo1-s3-uri-style: path and repo1-s3-verify-tls: “n” from the pgBackRest configuration and replace the endpoint with your provider’s URL.


What this series does NOT cover

To keep scope honest:

  • Application-side connection-string changes beyond updating to the new pgBouncer service. If your app uses connection-pool tuning, custom auth, or a service mesh, that work stays with you.
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations. The PostgreSQL major version must match between the source and the target.
  • Crunchy enterprise-only features like TDE, Crunchy Postgres for Kubernetes-specific operators, or pgBackRest custom encryption. If your environment uses these, contact the Percona team for a tailored plan.
  • Operating two operators against the same namespace before the PGO hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any other S3-compatible service accessible from all cluster pods
Tools kubectl, helm (v3), yq

Different versions may differ slightly in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


Migration using a standby cluster

This is the safest method when the downtime budget is tight. The Percona cluster is brought up as a standby of the Crunchy primary, catches up via pgBackRest plus streaming replication, and is promoted at cutover. The only downtime is the cutover step itself.

You can wire the standby in two ways, and combining both gives you maximum safety:

  • pgBackRest repo-based standby seeds the standby from the latest base backup and replays archived WAL
  • Streaming replication keeps the standby in sync with the live primary


Overview
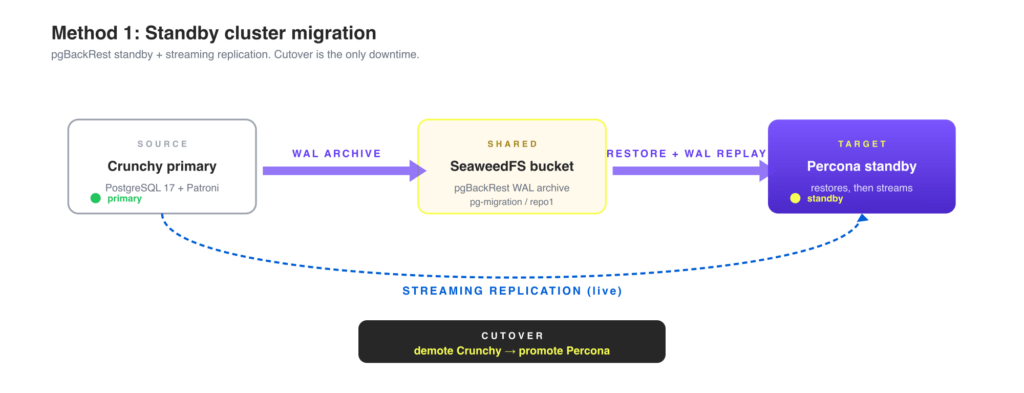


Before you begin

Set the target namespace once. Every command in this guide reads from this variable, so you can change it in a single place:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: “n” is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.


Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secret.yaml after filling in your access key and secret key:

# Copy and edit the file first to set your credentials.

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/01-pgbackrest-secret.yaml

Both secrets contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket and path. The repo1-path value must be identical in both cluster specs. Mismatched paths will prevent the Percona standby from finding the WAL archive.

The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Optional: deploy a Crunchy operator to test the migration end to end:

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait


Apply
examples/02-crunchy-source-cluster.yaml (or adapt your existing cluster’s pgBackRest config):

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/02-crunchy-source-cluster.yaml


The key pgBackRest settings in the example:

global:
  repo1-path: /crunchy-to-percona/repo1   # shared path, must match Percona side
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1


Wait for the cluster to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  --namespace $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s


Step 2. Trigger a full backup on the Crunchy cluster

Wait for the pgBackRest stanza to be created:

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Take a full backup before creating the Percona standby. This gives the standby a recent base to restore from, so it only needs to replay a small amount of WAL to catch up. This matches the realistic production migration pattern.

kubectl annotate postgrescluster crunchy-source \
  --namespace $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"


Wait for the backup job to complete:

kubectl wait job \
  -l postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Copy TLS certificates (cross-namespace only)

If the Percona cluster is in a different namespace from the Crunchy cluster, copy the Crunchy TLS secrets to the Percona namespace. These allow mutual TLS authentication during streaming replication:

for secret in crunchy-source-cluster-cert crunchy-source-replication-cert; do
  kubectl get secret "${secret}" -n <CRUNCHY_NS> -o json | \
    yq '{"apiVersion": .apiVersion, "kind": .kind, "data": .data,
         "metadata": {"name": .metadata.name}, "type": .type}' -o yaml | \
    kubectl -n $MIGRATION_NS apply -f -
done

If both clusters are in the same namespace, skip this step. The secrets are already accessible.


Step 4. Deploy the Percona PG Operator

The Crunchy PGO operator can stay in the same or a different namespace.

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

Wait until the operator deployment is ready:

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s


Step 5. Create the Percona cluster in standby mode

Note: The kubectl apply below pulls the CR manifest from the migration-from-crunchy-guide branch of the operator repo, which is the source for this guide’s examples. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation and pin to a released version tag rather than a feature branch.

Apply examples/03-percona-standby-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/03-percona-standby-cluster.yaml

The key settings that wire the Percona cluster to the Crunchy source:

standby:
  enabled: true
  repoName: repo1                             # restore initial base backup from this repo
  host: crunchy-source-ha.postgres-migration.svc.cluster.local
  port: 5432

secrets:
  customTLSSecret:
    name: crunchy-source-cluster-cert         # Crunchy CA for mutual TLS
  customReplicationTLSSecret:
    name: crunchy-source-replication-cert     # cert for _crunchyreplication user

The Percona operator will:

  1. Restore the base backup from the SeaweedFS bucket.
  2. Replay WAL from SeaweedFS until it catches up with the live Crunchy cluster.
  3. Switch to streaming replication from crunchy-source-ha.

Wait for the cluster to reach the ready state:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify that data is replicating to the standby:

STANDBY_POD=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/data=postgres \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery(), pg_last_wal_replay_lsn();"

Expected output: t (in recovery) and a non-null LSN.


Step 6. Verify replication lag before cutover

Query the Crunchy primary to confirm the Percona standby has caught up:

CRUNCHY_PRIMARY=$(kubectl get pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -c "
    SELECT
        client_addr,
        state,
        pg_wal_lsn_diff(sent_lsn, replay_lsn) AS byte_lag,
        write_lag,
        flush_lag,
        replay_lag
    FROM pg_stat_replication;
  "

Proceed to the next step only when write_lag and replay_lag are NULL or under a few seconds.


Step 7. Cutover the Crunchy cluster

This is the only step that causes downtime. Stop accepting writes on the application side, then patch the Crunchy cluster into standby mode. Patroni steps down and archives the final WAL.

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": true, "repoName": "repo1"}}}'

Verify demotion (poll until pg_is_in_recovery() returns t):

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"


Step 8. (Optional) Shut down the Crunchy cluster

Once the Percona standby has replayed all WAL, shut down the Crunchy cluster to prevent split-brain:

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"shutdown": true}}'

kubectl wait pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=delete \
  --timeout=120s || true


Step 9. Promote the Percona cluster

Confirm that the Percona standby has finished replaying all WAL (the LSN stops advancing):

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_last_wal_replay_lsn();"

Run this a few times. When the LSN is stable, replay is complete.

kubectl patch perconapgcluster percona-standby \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": false}}}'

Wait for the cluster to become ready and confirm it is writable:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=480s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f (the cluster is now the primary and accepts writes).


Step 10. Verify stanza creation

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 11. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery point on the new timeline. All future PITR restores will use this backup as their starting point, independent of the old Crunchy WAL archive.


Reconnecting your application

Update your application’s connection string to point at the Percona cluster’s pgBouncer service:

kubectl get service -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=pgbouncer

This migration path works almost entirely out of the box. For users coming from the Crunchy Data PostgreSQL Operator, this method feels familiar because it leverages the same standby/replica mechanisms used for HA and disaster recovery. The key difference is that you can now use this familiar mechanism to migrate safely to the Percona PostgreSQL Operator, a fully open-source alternative running on a fully open-source storage layer.


Rollback

The standby method is the most rollback-friendly of the three. Until you take the post-migration backup, the Crunchy cluster still holds the original timeline. To roll back:

  1. Stop writes on the Percona side and patch the Percona cluster back into standby mode (spec.standby.enabled: true).
  2. Patch the Crunchy cluster out of standby mode and let Patroni promote it.
  3. Verify with pg_is_in_recovery() on both sides.
  4. Switch the application connection string back to the Crunchy pgBouncer service.

After Step 11 (post-migration backup), the timelines have diverged. From that point, the rollback story is the same as a fresh restore, and you should treat the Crunchy cluster as a historical reference, not a live target.


Troubleshooting

Percona standby not connecting to the Crunchy primary. Verify the crunchy-source-ha service resolves from within the Percona pod:

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  bash -c "getent hosts crunchy-source-ha.${MIGRATION_NS}.svc.cluster.local"

Replication authentication errors. The Percona standby authenticates as the _crunchyreplication PostgreSQL user using the certificate in crunchy-source-replication-cert. Verify the secret exists and matches what the Crunchy operator generated:

kubectl get secret crunchy-source-replication-cert -n $MIGRATION_NS

pgBackRest restore fails. Confirm both secrets contain identical credentials and that repo1-path is the same in both cluster specs (/crunchy-to-percona/repo1 in this guide). Mismatched paths cause an archive.info missing error. Verify the bucket is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "

Timeline history file (00000002.history) missing after promotion. This is a known issue with Crunchy PGO’s async archive mode. After promotion, push the history file synchronously:

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  bash -c "
    pgbackrest --stanza=db --no-archive-async \
      archive-push \"\${PGDATA}/pg_wal/00000002.history\" || true
  "


What’s next

This was the safest migration path. Part 3 will cover two simpler options:

  • Backup and restore. The simplest path. You take a Crunchy pgBackRest backup and the Percona cluster bootstraps from it. Cutover is the time between the final backup and pointing the application at the new cluster.
  • Persistent volume reuse. For when you want to skip the data copy entirely. The Percona cluster takes over the existing PGDATA volume, no restore step required.

Pick the method that fits your downtime budget, data size, and storage layout.

This post covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method appeared first on Percona.
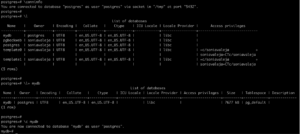
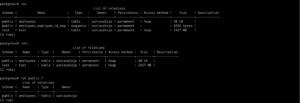
May
24
2026
--

Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method

A Crunchy to Percona PostgreSQL migration is more straightforward than most cross-operator moves on Kubernetes, because the Percona PostgreSQL Operator is a hard fork of the Crunchy Data PostgreSQL Operator. Same Patroni HA, same pgBackRest backups, same overall CRD shape. This post walks through the safest of the three migration paths: a standby cluster method with near-zero downtime.

This is part 2 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator. Part 1 walked through the changing open-source landscape and announced the hard fork of the Crunchy Data PostgreSQL Operator into the fully independent Percona PostgreSQL Operator v3.0.0.

This post is the first practical playbook of the series. It covers the standby cluster method, the safest migration path when the downtime budget is tight. Part 3 will cover two simpler paths: backup-and-restore and persistent-volume reuse.

If you are landing here without context on why you might want to migrate at all, start with part 1. The rest of this post assumes you have already decided to move and want a tested playbook.


Migration approach in one paragraph

The Percona PostgreSQL Kubernetes Operator is a hard fork of the Crunchy Data PostgreSQL Kubernetes Operator, which simplifies the migration paths considerably: the same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both operators. All three migration paths in this series are reversible: because Percona’s operator is fully open source and remains compatible with the same backup format, the move back to Crunchy is also possible if your team decides to walk it


A note on the storage layer

All examples in this guide use an in-cluster SeaweedFS instance as the pgBackRest S3 repository. SeaweedFS is Apache-2.0 licensed, actively maintained, and a clean drop-in replacement for the role MinIO used to fill in this stack. Any other S3-compatible storage works just as well: AWS S3, Google Cloud Storage (via HMAC keys), Ceph RadosGW, Cloudflare R2, and so on. For non-SeaweedFS endpoints, remove repo1-s3-uri-style: path and repo1-s3-verify-tls: “n” from the pgBackRest configuration and replace the endpoint with your provider’s URL.


What this series does NOT cover

To keep scope honest:

  • Application-side connection-string changes beyond updating to the new pgBouncer service. If your app uses connection-pool tuning, custom auth, or a service mesh, that work stays with you.
  • Schema-changing upgrades, major PostgreSQL version upgrades, or extension migrations. The PostgreSQL major version must match between the source and the target.
  • Crunchy enterprise-only features like TDE, Crunchy Postgres for Kubernetes-specific operators, or pgBackRest custom encryption. If your environment uses these, contact the Percona team for a tailored plan.
  • Operating two operators against the same namespace before the PGO hard fork. Use Percona PostgreSQL Operator v3.0.0 or higher.


Tested with

Component Version
Crunchy Data PostgreSQL Kubernetes Operator v5.8.x (tested on v5.8.7)
Percona PostgreSQL Kubernetes Operator v3.x.x (tested on v3.0.0)
PostgreSQL 18 (must match between source and target)
Object storage SeaweedFS (Apache-2.0), or any other S3-compatible service accessible from all cluster pods
Tools kubectl, helm (v3), yq

Different versions may differ slightly in CR fields or behavior. Always consult the official documentation for the operator and PostgreSQL version you are running.


Migration using a standby cluster

This is the safest method when the downtime budget is tight. The Percona cluster is brought up as a standby of the Crunchy primary, catches up via pgBackRest plus streaming replication, and is promoted at cutover. The only downtime is the cutover step itself.

You can wire the standby in two ways, and combining both gives you maximum safety:

  • pgBackRest repo-based standby seeds the standby from the latest base backup and replays archived WAL
  • Streaming replication keeps the standby in sync with the live primary


Overview


Before you begin

Set the target namespace once. Every command in this guide reads from this variable, so you can change it in a single place:

export MIGRATION_NS=postgres-migration
kubectl create namespace $MIGRATION_NS


Deploy SeaweedFS

Skip this step if you already have an S3-compatible repository (AWS S3, GCS, Ceph). Update the endpoint and credentials in the YAML examples accordingly.

SeaweedFS provides an S3-compatible object store that runs inside Kubernetes. Both operators will use it as the shared pgBackRest WAL archive.

TLS is required. pgBackRest always connects to S3 endpoints over HTTPS, even when repo1-s3-verify-tls: “n” is set (that flag skips certificate verification, it does not fall back to HTTP). The steps below generate a self-signed certificate and pass it to SeaweedFS via Helm values.

# Generate a self-signed TLS certificate for SeaweedFS S3
openssl req -x509 -nodes -days 3650 -newkey rsa:2048 \
  -keyout /tmp/seaweedfs.key \
  -out /tmp/seaweedfs.crt \
  -subj "/CN=seaweedfs-all-in-one"

kubectl -n $MIGRATION_NS create secret tls seaweedfs-s3-tls \
  --cert=/tmp/seaweedfs.crt \
  --key=/tmp/seaweedfs.key

helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm repo update

helm install seaweedfs seaweedfs/seaweedfs \
  --namespace $MIGRATION_NS \
  --version 4.23.0 \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/seaweedfs-values.yaml \
  --wait

The Helm values file in the repo creates the pg-migration bucket on first start, so no separate aws s3 mb step is needed.


Step 0. Create pgBackRest secrets

Both operators need credentials to read and write the shared SeaweedFS bucket. Apply the secrets from examples/01-pgbackrest-secret.yaml after filling in your access key and secret key:

# Copy and edit the file first to set your credentials.

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/01-pgbackrest-secret.yaml

Both secrets contain the same SeaweedFS credentials (pgmigration / pgmigration123). For AWS S3, replace those with your IAM access key ID and secret access key.


Step 1. Start with your existing Crunchy Data cluster

If you already have a running Crunchy cluster, ensure its pgBackRest repo1 points at the shared bucket and path. The repo1-path value must be identical in both cluster specs. Mismatched paths will prevent the Percona standby from finding the WAL archive.

The Helm install below is shown only as a quick way to reproduce this blog post’s example. The migration steps in the rest of this post do not depend on how you deployed the source operator.

Optional: deploy a Crunchy operator to test the migration end to end:

helm install pgo \
  oci://registry.developers.crunchydata.com/crunchydata/pgo \
  -n $MIGRATION_NS \
  --version 5.8.7 \
  --set singleNamespace=true \
  --wait


Apply
examples/02-crunchy-source-cluster.yaml (or adapt your existing cluster’s pgBackRest config):

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/02-crunchy-source-cluster.yaml


The key pgBackRest settings in the example:

global:
  repo1-path: /crunchy-to-percona/repo1   # shared path, must match Percona side
  repo1-s3-uri-style: path                # required for path-style S3 endpoints (SeaweedFS, MinIO)
  repo1-s3-verify-tls: "n"                # skip TLS verification for self-signed cert; remove for AWS S3
repos:
  - name: repo1
    s3:
      bucket: pg-migration
      endpoint: seaweedfs-all-in-one.postgres-migration.svc.cluster.local:8443
      region: us-east-1


Wait for the cluster to be ready:

kubectl wait pod \
  --selector postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  --namespace $MIGRATION_NS \
  --for=condition=Ready \
  --timeout=300s


Step 2. Trigger a full backup on the Crunchy cluster

Wait for the pgBackRest stanza to be created:

kubectl wait postgrescluster/crunchy-source \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s

Take a full backup before creating the Percona standby. This gives the standby a recent base to restore from, so it only needs to replay a small amount of WAL to catch up. This matches the realistic production migration pattern.

kubectl annotate postgrescluster crunchy-source \
  --namespace $MIGRATION_NS \
  postgres-operator.crunchydata.com/pgbackrest-backup="$(date +%s)"


Wait for the backup job to complete:

kubectl wait job \
  -l postgres-operator.crunchydata.com/pgbackrest-backup=manual,postgres-operator.crunchydata.com/cluster=crunchy-source \
  -n $MIGRATION_NS \
  --for=condition=Complete \
  --timeout=600s


Step 3. Copy TLS certificates (cross-namespace only)

If the Percona cluster is in a different namespace from the Crunchy cluster, copy the Crunchy TLS secrets to the Percona namespace. These allow mutual TLS authentication during streaming replication:

for secret in crunchy-source-cluster-cert crunchy-source-replication-cert; do
  kubectl get secret "${secret}" -n <CRUNCHY_NS> -o json | \
    yq '{"apiVersion": .apiVersion, "kind": .kind, "data": .data,
         "metadata": {"name": .metadata.name}, "type": .type}' -o yaml | \
    kubectl -n $MIGRATION_NS apply -f -
done

If both clusters are in the same namespace, skip this step. The secrets are already accessible.


Step 4. Deploy the Percona PG Operator

The Crunchy PGO operator can stay in the same or a different namespace.

kubectl apply -n $MIGRATION_NS --server-side \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/tags/v3.0.0/deploy/bundle.yaml

Wait until the operator deployment is ready:

kubectl wait deployment percona-postgresql-operator \
  -n $MIGRATION_NS \
  --for=condition=Available \
  --timeout=120s


Step 5. Create the Percona cluster in standby mode

Note: The kubectl apply below pulls the CR manifest from the migration-from-crunchy-guide branch of the operator repo, which is the source for this guide’s examples. For production deployments, follow the official Percona Operator for PostgreSQL installation documentation and pin to a released version tag rather than a feature branch.

Apply examples/03-percona-standby-cluster.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/03-percona-standby-cluster.yaml

The key settings that wire the Percona cluster to the Crunchy source:

standby:
  enabled: true
  repoName: repo1                             # restore initial base backup from this repo
  host: crunchy-source-ha.postgres-migration.svc.cluster.local
  port: 5432

secrets:
  customTLSSecret:
    name: crunchy-source-cluster-cert         # Crunchy CA for mutual TLS
  customReplicationTLSSecret:
    name: crunchy-source-replication-cert     # cert for _crunchyreplication user

The Percona operator will:

  1. Restore the base backup from the SeaweedFS bucket.
  2. Replay WAL from SeaweedFS until it catches up with the live Crunchy cluster.
  3. Switch to streaming replication from crunchy-source-ha.

Wait for the cluster to reach the ready state:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=600s

Verify that data is replicating to the standby:

STANDBY_POD=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/data=postgres \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery(), pg_last_wal_replay_lsn();"

Expected output: t (in recovery) and a non-null LSN.


Step 6. Verify replication lag before cutover

Query the Crunchy primary to confirm the Percona standby has caught up:

CRUNCHY_PRIMARY=$(kubectl get pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/role=master \
  -n $MIGRATION_NS \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -c "
    SELECT
        client_addr,
        state,
        pg_wal_lsn_diff(sent_lsn, replay_lsn) AS byte_lag,
        write_lag,
        flush_lag,
        replay_lag
    FROM pg_stat_replication;
  "

Proceed to the next step only when write_lag and replay_lag are NULL or under a few seconds.


Step 7. Cutover the Crunchy cluster

This is the only step that causes downtime. Stop accepting writes on the application side, then patch the Crunchy cluster into standby mode. Patroni steps down and archives the final WAL.

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": true, "repoName": "repo1"}}}'

Verify demotion (poll until pg_is_in_recovery() returns t):

kubectl -n $MIGRATION_NS exec "${CRUNCHY_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"


Step 8. (Optional) Shut down the Crunchy cluster

Once the Percona standby has replayed all WAL, shut down the Crunchy cluster to prevent split-brain:

kubectl patch postgrescluster crunchy-source \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"shutdown": true}}'

kubectl wait pod \
  -l postgres-operator.crunchydata.com/cluster=crunchy-source,postgres-operator.crunchydata.com/data=postgres \
  -n $MIGRATION_NS \
  --for=delete \
  --timeout=120s || true


Step 9. Promote the Percona cluster

Confirm that the Percona standby has finished replaying all WAL (the LSN stops advancing):

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  psql -t -c "SELECT pg_last_wal_replay_lsn();"

Run this a few times. When the LSN is stable, replay is complete.

kubectl patch perconapgcluster percona-standby \
  -n $MIGRATION_NS \
  --type=merge \
  -p '{"spec": {"standby": {"enabled": false}}}'

Wait for the cluster to become ready and confirm it is writable:

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=ready \
  --timeout=480s

PERCONA_PRIMARY=$(kubectl get pod -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=primary \
  -o jsonpath='{.items[0].metadata.name}')

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  psql -t -c "SELECT pg_is_in_recovery();"

Expected output: f (the cluster is now the primary and accepts writes).


Step 10. Verify stanza creation

kubectl wait perconapgcluster/percona-standby \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.pgbackrest.repos[0].stanzaCreated}'=true \
  --timeout=300s


Step 11. Take a post-migration backup

Apply examples/04-post-migration-backup.yaml:

kubectl apply -n $MIGRATION_NS \
  -f https://raw.githubusercontent.com/percona/percona-postgresql-operator/refs/heads/migration-from-crunchy-guide/e2e-tests/tests/migration-from-crunchy-standby/examples/04-post-migration-backup.yaml

kubectl wait perconapgbackup/post-migration-backup \
  -n $MIGRATION_NS \
  --for=jsonpath='{.status.state}'=Succeeded \
  --timeout=600s

This creates a clean recovery point on the new timeline. All future PITR restores will use this backup as their starting point, independent of the old Crunchy WAL archive.


Reconnecting your application

Update your application’s connection string to point at the Percona cluster’s pgBouncer service:

kubectl get service -n $MIGRATION_NS \
  -l postgres-operator.crunchydata.com/cluster=percona-standby,postgres-operator.crunchydata.com/role=pgbouncer

This migration path works almost entirely out of the box. For users coming from the Crunchy Data PostgreSQL Operator, this method feels familiar because it leverages the same standby/replica mechanisms used for HA and disaster recovery. The key difference is that you can now use this familiar mechanism to migrate safely to the Percona PostgreSQL Operator, a fully open-source alternative running on a fully open-source storage layer.


Rollback

The standby method is the most rollback-friendly of the three. Until you take the post-migration backup, the Crunchy cluster still holds the original timeline. To roll back:

  1. Stop writes on the Percona side and patch the Percona cluster back into standby mode (spec.standby.enabled: true).
  2. Patch the Crunchy cluster out of standby mode and let Patroni promote it.
  3. Verify with pg_is_in_recovery() on both sides.
  4. Switch the application connection string back to the Crunchy pgBouncer service.

After Step 11 (post-migration backup), the timelines have diverged. From that point, the rollback story is the same as a fresh restore, and you should treat the Crunchy cluster as a historical reference, not a live target.


Troubleshooting

Percona standby not connecting to the Crunchy primary. Verify the crunchy-source-ha service resolves from within the Percona pod:

kubectl -n $MIGRATION_NS exec "${STANDBY_POD}" -c database -- \
  bash -c "getent hosts crunchy-source-ha.${MIGRATION_NS}.svc.cluster.local"

Replication authentication errors. The Percona standby authenticates as the _crunchyreplication PostgreSQL user using the certificate in crunchy-source-replication-cert. Verify the secret exists and matches what the Crunchy operator generated:

kubectl get secret crunchy-source-replication-cert -n $MIGRATION_NS

pgBackRest restore fails. Confirm both secrets contain identical credentials and that repo1-path is the same in both cluster specs (/crunchy-to-percona/repo1 in this guide). Mismatched paths cause an archive.info missing error. Verify the bucket is reachable:

kubectl run -i --rm s3-check \
  --image=perconalab/awscli \
  --restart=Never \
  -n $MIGRATION_NS \
  -- bash -c "
    AWS_ACCESS_KEY_ID=pgmigration \
    AWS_SECRET_ACCESS_KEY=pgmigration123 \
    AWS_DEFAULT_REGION=us-east-1 \
    aws --endpoint-url https://seaweedfs-all-in-one.${MIGRATION_NS}.svc.cluster.local:8443 \
        --no-verify-ssl \
        s3 ls s3://pg-migration
  "

Timeline history file (00000002.history) missing after promotion. This is a known issue with Crunchy PGO’s async archive mode. After promotion, push the history file synchronously:

kubectl -n $MIGRATION_NS exec "${PERCONA_PRIMARY}" -c database -- \
  bash -c "
    pgbackrest --stanza=db --no-archive-async \
      archive-push \"\${PGDATA}/pg_wal/00000002.history\" || true
  "


What’s next

This was the safest migration path. Part 3 will cover two simpler options:

  • Backup and restore. The simplest path. You take a Crunchy pgBackRest backup and the Percona cluster bootstraps from it. Cutover is the time between the final backup and pointing the application at the new cluster.
  • Persistent volume reuse. For when you want to skip the data copy entirely. The Percona cluster takes over the existing PGDATA volume, no restore step required.

Pick the method that fits your downtime budget, data size, and storage layout.

This post covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Migrate from Crunchy Data PostgreSQL Operator to Percona PostgreSQL Operator: Standby Cluster Method appeared first on Percona.
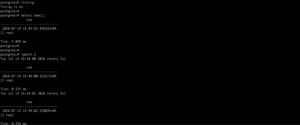
May
19
2026
--

Not All Open Source Is Equal: Choosing a PostgreSQL Operator for Kubernetes in 2026


Choosing an open source PostgreSQL operator for Kubernetes used to be a question about features and community size. In 2026, it has become a question about licensing posture, image distribution, and whether the project you pick today will still be operationally open in three years.

This is part 1 of a 3-part series on running PostgreSQL on Kubernetes with a fully open-source operator.

  • Part 1 (this post): how the open-source landscape has shifted under your feet, and what to look for in an operator before you commit
  • Part 2: migrating from the Crunchy Data PostgreSQL Operator to the Percona PostgreSQL Operator using the standby cluster method (near-zero downtime)
  • Part 3: two simpler migration paths: backup-and-restore and persistent-volume reuse

In this post, you will learn about:

  • What has changed in the open-source landscape over the last few years, with specific examples
  • What licensing and redistribution actually mean for Kubernetes operators in production
  • How to evaluate whether a project is “open source in theory” or open source in practice
  • Where Percona’s PostgreSQL Operator fits in, and what the practical migration looks like

Open source isn’t what it used to be
The landscape of open source has undergone significant changes in recent years, and selecting the right operator and tooling for PostgreSQL clusters in Kubernetes has never been more important. Three recent shifts illustrate the pattern.


MinIO

MinIO was the default open-source S3-compatible storage backend for Kubernetes workloads for years. The trajectory over the last few years tells the story:

  • Switched its license to AGPLv3, with several enterprise features moved into a commercial-only edition
  • Entered what amounted to maintenance mode, narrowing community engagement, limiting support to paid subscriptions, and reducing acceptance of community contributions
  • On April 25, 2026, the github.com/minio/minio repository was archived by the project owner, ending public development of the open-source version

The code is still cloneable, but the project is no longer maintained as open source. Teams running MinIO in production now need an exit plan.


Bitnami images

Bitnami Docker images have long been a staple for databases (including Postgres), middleware, and developer tooling. In July 2025, Broadcom’s Tanzu Division announced Bitnami Secure Images and signalled the deprecation of the free public catalog. The concrete timeline that followed:

  • August 28, 2025: deprecation of non-hardened Debian-based images in the free tier began, and non-latest images started to be removed
  • September 29, 2025 (after community pushback): the public docker.io/bitnami catalog was reduced. The remaining free images were limited to a small curated set of latest-version, hardened images intended for development use; older versions of most applications were moved to a “Bitnami Legacy” repository
  • The full catalog and the hardened production images now require a paid Bitnami Secure Images subscription, reportedly priced in the tens of thousands of dollars per year per organization

For Kubernetes teams, the practical impact was immediate: any Helm chart that pinned a specific Bitnami image version (a recommended practice) found that image gone or moved, breaking CI pipelines and air-gapped deployments.


Crunchy Data PostgreSQL images

Crunchy Data illustrates the same dynamic in the Postgres operator space. To be clear: the Crunchy Data PostgreSQL Operator is a mature, well-engineered project, and the team behind it has done a lot of valuable work upstream and around pgBackRest and Patroni integrations. The point of this section is not the engineering, it is the redistribution and usage terms that govern the official builds.

Crunchy’s licensing shifts, 2022 to 2024

Between 2022 and 2024, several shifts occurred:

  • Redistribution restrictions. While the PostgreSQL code is open source, Crunchy’s official Docker images include branding and enterprise features that are not freely redistributable. The Crunchy Data Developer Program terms describe the software as intended for internal or personal use; production use by larger organizations typically requires an active support subscription.
  • Restrictions on consulting and resale. The terms explicitly prohibit using Crunchy’s images to deliver support or consulting services to others without an authorized agreement. The PostgreSQL source code remains open source, but the official images and their packaging are not freely redistributable, which limits practical use in commercial and customer-facing settings.
  • Registry move. Most images were moved to registry.developers.crunchydata.com, which requires authentication and acceptance of terms before pulling. That draws a clearer line between open-source code and proprietary builds.

In other words, the project is open source on the code side, but the practical artifacts (images, Helm releases) are gated.


What these restrictions really mean for Kubernetes users

When container images and operators come with redistribution limits, authentication requirements, or “internal-use-only” clauses, the impact on Kubernetes environments is immediate and concrete. Teams can no longer:

  • Build air-gapped clusters by mirroring images to a private registry without working through a license review
  • Rely on GitOps workflows that assume publicly accessible OCI images
  • Fork or customize the operator freely, because official images cannot be redistributed with modifications
  • Use the software in commercial or customer-facing products without additional licensing
  • Run multi-cluster or multi-tenant Postgres at scale without bumping into usage terms

For a database operator, where almost every operational pattern depends on the container images you can pull and run, these restrictions effectively turn a project into a “source-available but not operationally open” solution. The code is open. The operating story is not.
As a result, many teams are switching to fully open-source alternatives: the Percona Operator for PostgreSQL, CloudNativePG, Zalando Postgres Operator, StackGres, and a few others.


How to evaluate “open source” in 2026

The bigger picture here is that “open source” today often exists more in theory than in practice. It pays to look past the badge and check the operating reality. Three questions to ask before you commit to an operator:

1. Are the container images publicly redistributable?

If you cannot pull the official images without authentication, or you cannot mirror them to your private registry without a license review, your air-gapped and GitOps stories are constrained from day one. This is the question that turned out to be the most consequential one for MinIO, Bitnami, and Crunchy users in 2025.

2. Are core operational features in the open-source build, or behind a paywall?

Backup, monitoring, HA, and security features should be in the build everyone uses, not gated behind an enterprise tier. A “community edition” that omits the feature most teams actually need is a marketing build, not a real open-source build.

3. Is the governance and roadmap public?

A project where you can see the issues, the PRs, and the roadmap is one you can plan around. The Percona PG Operator’s public roadmap is an example of what this looks like in practice. A project run inside a vendor’s private tracker, by contrast, gives you no visibility.
These are not gotchas. They are the questions that decide whether a project will still serve you the same way in three years.


Migrate to freedom

Announcing the hard fork

We strongly believe in fully open-source software and want to increase our investment in the PostgreSQL and Kubernetes ecosystems. To back that up, we have decided to hard fork the Crunchy Data PostgreSQL Kubernetes Operator. Starting from version 3.0.0 (coming soon), the Percona PostgreSQL Kubernetes Operator is a fully independent project, with a public roadmap, public issue tracker, and freely redistributable images.

The hard fork is not a critique of Crunchy’s engineering. It is a commitment that the operator will keep evolving in a fully open-source direction, with no surprises about which features will be available to which audience.

Why migration is straightforward

Because the Percona PostgreSQL Operator is a hard fork of the Crunchy operator, the migration paths are surprisingly straightforward. The same underlying tools (Patroni, pgBackRest, PgBouncer) and the same overall design are used in both, which means migration can be done in multiple ways, sometimes with near-zero downtime, sometimes faster with a small downtime window. The next two posts in this series walk through three concrete options.

What’s next

This was the “why.” The next two posts are the “how”:

  • Part 2: Standby cluster migration. Bring up a Percona cluster as a standby of the Crunchy primary, catch it up via pgBackRest plus streaming replication, and promote it at cutover. The only downtime is the cutover itself.
  • Part 3: Backup-restore and PV reuse. Two simpler paths: bootstrap a Percona cluster directly from a Crunchy pgBackRest backup, or retain the existing PGDATA persistent volume and have Percona pick up where Crunchy left off.

Reversibility and exit options

All three paths are reversible: because Percona’s operator, images, and tooling are 100 percent open source and remain compatible with the same backup format and the same Patroni HA model, you keep full control. You can migrate back to Crunchy if your team decides to, or out to another open-source operator (CloudNativePG, Zalando, StackGres) using the same patterns. That last journey is a topic for a future article.

This series covers basic deployment patterns and simplified configuration examples. If your environment is more complex, uses custom images, includes Crunchy enterprise features like TDE, or otherwise needs tailored migration steps, contact the Percona team and we will help you plan and execute the move.


Try It Out

The post Not All Open Source Is Equal: Choosing a PostgreSQL Operator for Kubernetes in 2026 appeared first on Percona.
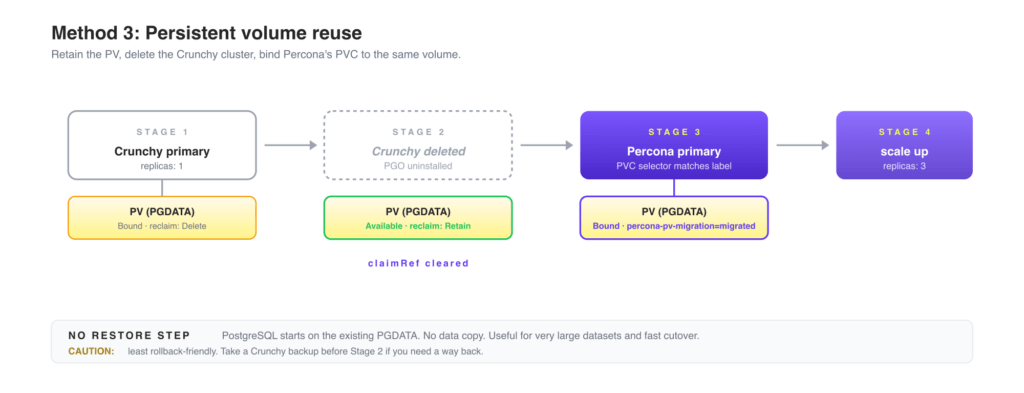
May
19
2026
--

Keeping pgBackRest Open, Healthy, and Community Driven

When the future of pgBackRest suddenly became uncertain, the PostgreSQL ecosystem reacted quickly.

At Percona, we believed the most important question was not:

what replaces it?

but:

how do we ensure pgBackRest remains healthy, sustainable, and open for everyone?

That distinction matters.

pgBackRest is critical infrastructure used by enterprises around the world to protect some of their most important data. When projects like this face maintainership or sustainability challenges, organizations need trusted open source partners that can help provide continuity, stability, and confidence.

Supporting continuity, not fragmentation

From the beginning, Percona believed the best outcome for pgBackRest was not fragmentation, forks, or closed alternatives.

What the project needed was continuity.

That meant working collaboratively across the ecosystem to help strengthen the project itself:

– coordinating funding discussions
– contributing engineering resources
– helping expand the maintainer base
– encouraging participation from multiple organizations

The goal was never to control the project. The goal was to help ensure pgBackRest remained open, healthy, and sustainable for the entire PostgreSQL community.

A healthier future for pgBackRest

Those efforts are already producing results.

A joint effort across maintainers, contributors, and multiple companies is helping ensure pgBackRest returns in a stronger and healthier position than before. Funding, engineering support, and long-term sustainability discussions are now happening collaboratively across the ecosystem.

Percona is proud to play a part in that effort.
Just as importantly, this moment would likely never have happened without David Steele bringing visibility to the sustainability realities behind maintaining critical open source infrastructure.

For more than a decade, David built pgBackRest into one of the most trusted backup and recovery solutions in the PostgreSQL ecosystem. The current momentum around the project reflects the value of that work and the trust the community has in what he created.

The announcement around renewed support for pgBackRest is not a story about one company “saving” a project. It is a story about the PostgreSQL ecosystem stepping up together to support critical open infrastructure.

That is how healthy open source ecosystems should work.

The role of trusted open source partners

At Percona, this is not simply a business decision. It reflects how we see open source itself: the strongest ecosystems are built in the open, through collaboration, shared responsibility, and long-term commitment.

Enterprises need more than software alone. They need trusted partners that can help support continuity, sustainability, and long-term ecosystem health.

We believe critical open source infrastructure is strongest when it remains:
– community driven
– vendor neutral
– collaboratively maintained
– available to everyone

The pgBackRest story is also a reminder that the PostgreSQL ecosystem needs stronger long-term sustainability structures around critical community infrastructure.

Whether that ultimately takes the form of an ecosystem foundation or another collaborative model, the goal should remain the same: ensuring the projects enterprises rely on stay healthy, trusted, and sustainably maintained.

Because ultimately:

the way is open.


The post Keeping pgBackRest Open, Healthy, and Community Driven appeared first on Percona.
Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com