 You probably missed the news, but… PT-1751: Adds –where param to pt-online-schema-change This brings the possibility to perform what I would call an “inverted purge” because you are not actually purging rows from your multi-terabyte table, but rather, you copy the small percentage of rows you want to keep to a new table and then […]
Jul
15
2024
15
2024
--
Using pt-online-schema-change for Purging Rows and Reclaiming Disk Space in a Single Operation
Nov
29
2022
29
2022
--
MySQL Data Archival With Minimal Disruption

 We all know that data is important, and some businesses need historical data to be available all the time. The problem is that queries on large tables perform poorly if they are not properly optimized. We get many customer requests in Managed Services to purge/archive large tables, and to achieve it, we use pt-archiver.
Recently, we received a request to archive a large table, and the customer was worried about the downtime and performance issues during the archival.
We proposed a solution to the customer to archive the table using pt-archive. The idea is to archive old data to other tables and keep the latest data on the current table with minimal performance issues. All of the data will remain available and can be queried anytime.

In the blog, I will not explain how to use the pt-archiver, but we will discuss a use case of the pt-archiver.
If you are unfamiliar with pt-archiver, please refer to “Want to archive tables? Use Percona Toolkit’s pt-archive “; it explains how pt-archiver works and various pt-archiver arguments.
We will test data archival to keep 100 days’ worth of data with a few simple steps for demonstration.
Note: This method uses timestamp datatype to filter the data.
- Create two dummy tables.
- Insert records in the source table.
- Archive the record from the source to the destination table using –where condition per business requirements.
- Rename the tables.
- Add Pt-archiver as a cron.
This diagram better illustrates the process.
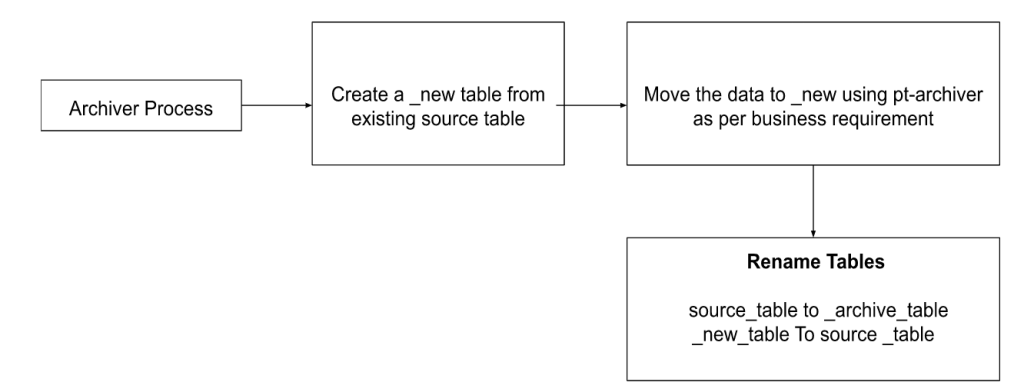
Remember —Date and –where the condition in this example is just a reference. Use the archiving condition in pt-archiver as per business requirements.
Let’s create a source table and insert records using mysql_random_data_load:
Create Table: CREATE TABLE `blogpost` (

  `id` bigint(20) unsigned NOT NULL AUTO_INCREMENT,

  `created_at` timestamp NULL DEFAULT NULL,

  `updated_at` timestamp NULL DEFAULT NULL,

  `deleted_at` timestamp NULL DEFAULT NULL,

  PRIMARY KEY (`id`),

  KEY `blogpost_created_at_index` (`created_at`)

) ENGINE=InnoDB DEFAULT CHARSET=latin1

1 row in set (0.00 sec)
Let’s create the destination table;
(Using the following table for demonstration purposes only)
create table if not exists blogpost_new like blogpost;

Query OK, 0 rows affected (0.02 sec)
Create the following triggers using pt-online-schema-change
Why triggers?
Any modifications to data in the original tables during the copy will be reflected in the new table because the pt-online-schema-change creates triggers on the original table to update the corresponding rows in the new table.
(For demonstration purposes, I have added triggers created from the pt-online-schema-change test run)
# Event: DELETE

delimiter //

CREATE TRIGGER `pt_osc_test_blogpost_del` AFTER DELETE ON `test`.`blogpost` FOR EACH ROW BEGIN DECLARE CONTINUE HANDLER FOR 1146 begin end; DELETE IGNORE FROM `test`.`blogpost_new` WHERE `test`.`blogpost_new`.`id` <=> OLD.`id`; END

//

delimiter ; //


# Event : UPDATE

delimiter //

CREATE TRIGGER `pt_osc_test_blogpost_upd` AFTER UPDATE ON `test`.`blogpost` FOR EACH ROW BEGIN DECLARE CONTINUE HANDLER FOR 1146 begin end; DELETE IGNORE FROM `test`.`_blogpost_new` WHERE !(OLD.`id` <=> NEW.`id`) AND `test`.`blogpost_new`.`id` <=> OLD.`id`; REPLACE INTO `test`.`_blogpost_new` (`id`, `created_at`, `updated_at`, `deleted_at`) VALUES (NEW.`id`, NEW.`created_at`, NEW.`updated_at`, NEW.`deleted_at`); END

//

delimiter ; //

# Event : INSERT

delimiter //

CREATE TRIGGER `pt_osc_test_blogpost_ins` AFTER INSERT ON `test`.`blogpost` FOR EACH ROW BEGIN DECLARE CONTINUE HANDLER FOR 1146 begin end; REPLACE INTO `test`.`blogpost_new` (`id`, `created_at`, `updated_at`, `deleted_at`) VALUES (NEW.`id`, NEW.`created_at`, NEW.`updated_at`, NEW.`deleted_at`);END

delimiter ; //
Verify that all triggers have been created.
SELECT * FROM INFORMATION_SCHEMA.TRIGGERS WHERE TRIGGER_SCHEMA='test' and EVENT_OBJECT_TABLE in ('blogpost')\G
The output should be something like
+--------------------------+

| trigger_name             |

+--------------------------+

| pt_osc_test_blogpost_ins |

| pt_osc_test_blogpost_upd |

| pt_osc_test_blogpost_del |

+--------------------------+

3 rows in set (0.01 sec)
Copy the last 100 days of data using the pt-archiver. Verify with –dry-run,
(Screen session can be used to perform pt-archiver if the table is large in size.)
pt-archiver --source h=localhost,D=test,t=blogpost,i=blogpost_created_at_index \

--dest h=localhost,D=test,t=blogpost_new \

--where "created_at >= date_sub(curdate(), interval 100 day)" --no-delete --no-check-columns \

--limit=10000 --progress=10000 --no-check-charset --dry-run
The output should be something like this:
SELECT /*!40001 SQL_NO_CACHE */ `id`,`created_at`,`updated_at`,`deleted_at` FROM `test`.`blogpost` FORCE INDEX(`blogpost_created_at_index`) WHERE (created_at >= date_sub(curdate(), interval 100 day)) ORDER BY `created_at` LIMIT 10000

SELECT /*!40001 SQL_NO_CACHE */ `id`,`created_at`,`updated_at`,`deleted_at` FROM `test`.`blogpost` FORCE INDEX(`blogpost_created_at_index`) WHERE (created_at >= date_sub(curdate(), interval 100 day)) AND (((? IS NULL AND `created_at` IS NOT NULL) OR (`created_at` > ?))) ORDER BY `created_at` LIMIT 10000

INSERT INTO `test`.`blogpost_new`(`id`,`created_at`,`updated_at`,`deleted_at`) VALUES (?,?,?,?)
Let’s execute the pt-archiver:
(Following Pt-archiver will copy 100 days worth of the data to _new table and triggers will up to date the _new table.)
pt-archiver --source h=localhost,D=test,t=blogpost,i=blogpost_created_at_index \

--dest h=localhost,D=test,t=blogpost_new \

--where "created_at >= date_sub(curdate(), interval 100 day)" --no-delete --no-check-columns \

--limit=10000 –replace --progress=10000 --no-check-charset
The pt-archiver output should be something like this:
TIME                ELAPSED   COUNT

2022-09-28T23:50:20       0       0

2022-09-28T23:50:44      24   10000

2022-09-28T23:51:08      48   20000

2022-09-28T23:51:25      65   27590
Once the pt-archiver finishes, check the condition code of the pt-archiver:
echo $?
(should be 0)
The next step is to check if the rows have been inserted into a new table and compare it with the original table.
NOTE: The below results are just examples of tests; use the right date or where condition:
select max(created_at) from test.blogpost_new;

+---------------------+

| max(created_at)     |

+---------------------+

| 2022-27-09 02:11:00 |

+---------------------+
select count(1) from test.blogpost where created_at <= date_sub('2022-27-09', interval 100 day);

+----------+

| count(1) |

+----------+

|    65366 |

+----------+

1 row in set (0.02 sec)
select count(1) from test.blogpost_new where created_at >= date_sub('2022-09-26', interval 100 day);

+----------+

| count(1) |

+----------+

|    23758 |

+----------+

1 row in set (0.01 sec)
Why rename tables?
The idea is to keep 100 days’ worth of data in the new table and rename it as the source table, and the original table with the _archive prefix will have all the data, including the last 100 days.
RENAME TABLE blogpost TO blogpost_archive, blogpost_new to blogpost;
It should appear something like this:
+--------------------------------+

| Tables_in_test                 |

+--------------------------------+

| blogpost         |

| blogpost_archive |

+--------------------------------+
Drop the triggers created using pt-online-schema-change .
DROP TRIGGER IF EXISTS test.test_blogpost_ins;

DROP TRIGGER IF EXISTS test.test_blogpost_upd;

DROP TRIGGER IF EXISTS test.test_blogpost_del;
Once the table rename is completed, copy data from the blogpost table to _archive table.
Let’s add the pt-archiver command to cron to make the process automatic. (It is advisable to create the script, use the below archiver command, and test it.)
pt-archiver --source h=localhost,D=test,t=blogpost,i=blogpost_created_at_index \

--dest h=localhost,D=test,t=blogpost_archive \

--where "created_at >= date_sub(curdate(), interval 100 day)" --no-delete --no-check-columns \

--limit=10000 --progress=10000 –replace b=0,L=yes –bulk-insert --no-check-charset >dev>null 2>1> path/to/logs
Now it is time to check if the cron was successful.
Check if the rows deleted have been copied to the test.blogpost_archive table, and deleted from the test.blogpost:
SELECT COUNT(1) FROM test.blogpost_archive WHERE created_at <= date_sub('2022-09-02', interval 100 day);
Verify if the blogpost table has 100 days of data, and the following query should return 0 rows:
SELECT COUNT(1) FROM test.blogpost WHERE created_at <= date_sub('2022-09-02', interval 100 day);
Hope you found this use case of the pt-archiver helpful when you need to purge/archive large tables!
Oct
27
2022
27
2022
--
pt-archiver Misbehaving With Secondary Index

 Not long ago, we found a long-running query in one of our clients on Managed Services. While reviewing this long-running query, we found it was generated by a pt-archiver operation. That doesn’t sound good, right?
I was able to reproduce the issue on my test environment. In this article, I will show you how to use pt-archiver to purge data from a table using a secondary index. First, we need to have the full picture before going any deeper. Here is a representation of the table structure:
Create Table: CREATE TABLE `sbtest1` (
  `id` int(11) NOT NULL AUTO_INCREMENT,
  `k` int(11) NOT NULL DEFAULT '0',
  `c` char(120) NOT NULL DEFAULT '',
  `pad` char(60) NOT NULL DEFAULT '',
  PRIMARY KEY (`id`),
  KEY `k_1` (`k`)
) ENGINE=InnoDB AUTO_INCREMENT=4000001 DEFAULT CHARSET=latin1
As you can see, this test table was generated with sysbench. The criteria defined to perform the purge process was to remove all rows where column “k” is lower than 1,500,000. In my test environment, this represents around 40K rows.
mysql> select count(1) from `dbtest`.`sbtest1` where (k < 1500000);
+----------+
| count(1) |
+----------+
|    41687 |
+----------+
Examining the pt-archiver operation used, we found that the options used were logical according to the archiving criteria and the table structure. These are the pt-archiver options used:
pt-archiver \
--source=h=localhost,P=3306,D=dbtest,t=sbtest1,b=0,i=k_1 \
--where='k < 1500000' --limit=1000 \
--primary-key-only --bulk-delete --purge
As you can see, it is suggesting the usage of index “k_1”, which references the column used on the purging criteria, and it is also using the option “–primary-key-only” which is suggested if you just want to purge data, which is our case. The option “–primary–key-only” makes pt-archiver include only the primary key columns on the SELECT clause to avoid fetching all columns from the table; this simple feature speeds up the purge process, especially on wide tables.
However, reviewing the sentence executed in the database, I found that the query running was not using the suggested index:
SELECT /*!40001 SQL_NO_CACHE */ `id` FROM `dbtest`.`sbtest1` FORCE INDEX(`PRIMARY`) WHERE (k < 1500000) AND (`id` < '4000000') ORDER BY `id` LIMIT 1000
Now, if we get the actual explain plan for this query, we will see it is not optimal at all, as it is fetching almost two million rows and forcing the usage of the “PRIMARY” index. No wonder why this was a long-running query.
mysql> explain format=json SELECT /*!40001 SQL_NO_CACHE */ `id` FROM `dbtest`.`sbtest1` FORCE INDEX(`PRIMARY`) WHERE (k < 1500000) AND (`id` < '4000000') ORDER BY `id` LIMIT 1000\G
*************************** 1. row ***************************
EXPLAIN: {
  "query_block": {
    "select_id": 1,
    "cost_info": {
      "query_cost": "783367.33"
    },
    "ordering_operation": {
      "using_filesort": false,
      "table": {
        "table_name": "sbtest1",
        "access_type": "range",
        "possible_keys": [
          "PRIMARY"
        ],
        "key": "PRIMARY",
        "used_key_parts": [
          "id"
        ],
        "key_length": "4",
        "rows_examined_per_scan": 1928044,
        "rows_produced_per_join": 642617,
        "filtered": "33.33",
        "cost_info": {
          "read_cost": "654843.92",
          "eval_cost": "128523.41",
          "prefix_cost": "783367.33",
          "data_read_per_join": "117M"
        },
        "used_columns": [
          "id",
          "k"
        ],
        "attached_condition": "((`dbtest`.`sbtest1`.`k` < 1500000) and (`dbtest`.`sbtest1`.`id` < '4000000'))"
      }
    }
  }
}
But why is pt-archiver doing this? Why isn’t it using the index suggested? After playing around with pt-archiver options, I realized that the usage of option “–primary-key-only” inhibits the usage of the suggested secondary index. This was reported initially on ticket PT-157, and it was marked as fixed. However, we can confirm that the most recent version of pt-archiver 3.4.0 is behaving as expected. So I opened this ticket PT-2112 to follow up on the fix.
Anyways, we need to fix the issue on our client, and to do so, we just need to remove the “–primary-key-only” option, which will allow us to use the suggested index. The downside of doing this is that it will fetch all columns from the table. We can see the SQL statement pt-archiver will generate by specifying the option “–dry-run”; this is a cool feature to see if the statement generated is optimal.
michael@testbox1:~$ pt-archiver \
> --source=h=localhost,P=3306,D=dbtest,t=sbtest1,b=0,i=k_1 \
> --where='k < 1500000' --limit=1000 \
> --bulk-delete --purge --dry-run
SELECT /*!40001 SQL_NO_CACHE */ `id`,`k`,`c`,`pad` FROM `dbtest`.`sbtest1` FORCE INDEX(`k_1`) WHERE (k < 1500000) ORDER BY `k` LIMIT 1000
SELECT /*!40001 SQL_NO_CACHE */ `id`,`k`,`c`,`pad` FROM `dbtest`.`sbtest1` FORCE INDEX(`k_1`) WHERE (k < 1500000) AND ((`k` >= ?)) ORDER BY `k` LIMIT 1000
DELETE FROM `dbtest`.`sbtest1` WHERE (((`k` >= ?))) AND (((`k` <= ?))) AND (k < 1500000) LIMIT 1000
If we examine the explain plan for this generated statement we can see that the query cost for this new sentence is up to 7X times better than the previous one, and we are fetching only 79K rows compared to the 2M from the previous query. So definitely a better query.
mysql> explain format=json SELECT /*!40001 SQL_NO_CACHE */ `id`,`k`,`c`,`pad` FROM `dbtest`.`sbtest1` FORCE INDEX(`k_1`) WHERE (k < 1500000) ORDER BY `k` LIMIT 1000\G
*************************** 1. row ***************************
EXPLAIN: {
  "query_block": {
    "select_id": 1,
    "cost_info": {
      "query_cost": "111060.21"
    },
    "ordering_operation": {
      "using_filesort": false,
      "table": {
        "table_name": "sbtest1",
        "access_type": "range",
        "possible_keys": [
          "k_1"
        ],
        "key": "k_1",
        "used_key_parts": [
          "k"
        ],
        "key_length": "4",
        "rows_examined_per_scan": 79328,
        "rows_produced_per_join": 79328,
        "filtered": "100.00",
        "index_condition": "(`dbtest`.`sbtest1`.`k` < 1500000)",
        "cost_info": {
          "read_cost": "95194.61",
          "eval_cost": "15865.60",
          "prefix_cost": "111060.21",
          "data_read_per_join": "14M"
        },
        "used_columns": [
          "id",
          "k",
          "c",
          "pad"
        ]
      }
    }
  }
}
Conclusion
Hopefully, we will see this feature fixed in the future, but for now, we can just use pt-archiver as we did to take advantage of the secondary indexes. Also, as a recommendation, always use the “–dry-run” option to test your pt-archiver command and make sure the query produced is optimal for your database.
Jun
30
2016
30
2016
--
Rescuing a crashed pt-online-schema-change with pt-archiver

 This article discusses how to salvage a crashed
pt-online-schema-change by leveraging pt-archiver and executing queries to ensure that the data gets accurately migrated. I will show you how to continue the data copy process, and how to safely close out the pt-online-schema-change via manual operations such as RENAME TABLE and DROP TRIGGER commands. The normal process to recover from a crashed pt-online-schema-change is to drop the triggers on your original table and drop the new table created by the script. Then you would restart pt-online-schema-change. In this case, this wasn’t possible.
A customer recently needed to add a primary key column to a very busy table (with around 200 million rows). The table only had a unique key on one column (called our_id below). The customer had concerns about slave lag, and wanted to ensure there was little or no lag. This, as well as the fact that you can’t add a primary key as an online DDL in MySQL and Percona Server 5.6, meant the obvious answer was using pt-online-schema-change.
Due to the sensitivity of their environment, they could only afford one short window for the initial metadata locks, and needed to manually do the drop swap that pt-online-schema-change normally does automatically. This is where no-drop-triggers and no-swap-tables come in. The triggers will theoretically run indefinitely to keep the new and old tables in sync once pt-online-schema-change is complete. We crafted the following command:
pt-online-schema-change
--execute
--alter-foreign-keys-method=auto
--max-load Threads-running=30
--critical-load Threads_running=55
--check-slave-lag mysql-slave1,mysql-slave2,mysql-slave3
--max?lag=10
--chunk-time=0.5
--set-vars=lock_timeout=1
--tries="create_triggers:10:2,drop_triggers:10:2"
--no-drop-new-table
--no-drop-triggers
--no-swap-tables
--chunk-index "our_id"
--alter "ADD newcol BIGINT(20) UNSIGNED NOT NULL AUTO_INCREMENT PRIMARY KEY FIRST"
D=website,t=largetable
--nocheck-plan
You can see some of the specifics of other flags and why we used them in the Percona Toolkit Manual.
Once we ran the command the customer got concerned, as their monitoring tools weren’t showing any work done (which is by design, pt-online-schema-change doesn’t want to hurt your running environment). The customer ran strace -p to verify it was working. This wasn’t a great choice as it crashed pt-online-schema-change.
At this point, we knew that the application (and management) would not allow us to take new metadata locks to create triggers on the table, as we had passed our metadata lock window.
So how do we recover?
First, let’s start with a clean slate. We issued the following commands to create a new table, where __largetable_new is the table created by pt-online-schema-change:
CREATE TABLE mynewlargetable LIKE __largetable_new;
RENAME TABLE __largetable_new TO __largetable_old, mynewlargetable TO __largetable_new;
DROP TABLE __largetable_old;
Now the triggers on the original table, largetable are updating the new empty table that has our new schema.
Now let’s address the issue of actually moving the data that’s already in largetable to __largetable_new. This is where pt-archiver comes in. We crafted the following command:
pt-archiver
--execute
--max-lag=10
--source D=website,t=largetable,i=our_id
--dest D=website,t=__largetable_new
--where "1=1"
--no-check-charset
--no-delete
--no-check-columns
--txn-size=500
--limit=500
--ignore
--statistics
We use pt-archiver to slowly copy records non-destructively to the new table based on our_id and WHERE 1=1 (all records). At this point, we periodically checked the MySQL data directory over the course of a day with ls -l to compare table sizes.
Once the table files were close to the same size, we ran counts on the tables. We noticed something interesting: the new table had thousands more records than the original table.
This concerned us. We wondered if our “hack” was a mistake. At this point we ran some verification queries:
select min(our_id) from __largetable_new;
select max(our_id) from __largetable_new;
select min(our_id) from largetable;
select max(our_id) from largetable;
We learned that there were older records that didn’t exist in the live table. This means that pt-archiver and the DELETE trigger may have missed each other (i.e., pt-archiver was already in a transaction but hadn’t written records to the new table until after the DELETE trigger already fired).
We verified with more queries:
SELECT COUNT(*) FROM largetable l WHERE NOT EXISTS (SELECT our_id FROM __largetable_new n WHERE n.our_id=l.our_id);
They returned nothing.
SELECT COUNT(*) FROM __largetable_new n WHERE NOT EXISTS (SELECT our_id FROM largetable l WHERE n.our_id=l.our_id);
Our result showed 4000 extra records in the new table. This shows that we ended up with extra records that were deleted from the original table. We ran other queries based on their data to verify as well.
This wasn’t a huge issue for our application, and it could have been easily dealt with using a simple DELETE query based on the unique index (i.e., if it doesn’t exist in the original table, delete it from the new one).
Now to complete the pt-online-schema-change actions. All we need to do is the atomic rename or drop swap. This should be done as soon as possible to avoid running in a degraded state, where all writes to the old table are duplicated on the new one.
RENAME TABLE largetable TO __largetable_old , __largetable_new TO largetable;
Then drop the triggers for safety:
DROP TRIGGER pt_osc_website_largetable_ins;
DROP TRIGGER pt_osc_website_largetable_upd;
DROP TRIGGER pt_osc_website_largetable_del;
At this point it is safer to wait for the old table to clear out of the buffer pool before dropping it, just to ensure there is no impact on the server (maybe a week to be safe). You can check information_schema for a more accurate reading on this:
SELECT COUNT(*) FROM INFORMATION_SCHEMA.INNODB_BUFFER_PAGE WHERE TABLE_NAME = '`website`.`__largetable_old`';
+----------+
| count(*) |
+----------+
|   279175 |
+----------+
1 row in set (8.94 sec)
Once this goes to 0 you can issue:
DROP TABLE __largetable_old;
Aug
12
2013
12
2013
--
Want to archive tables? Use Percona Toolkit’s pt-archiver
 Percona Toolkit’s pt-archiver is one of the best utilities to archive the records from large tables to another tables or files. One interesting thing is that pt-archiver is a read-write tool. It deletes data from the source by default, so after archiving you don’t need to delete it separately.
As it is done by default, you should take care before actually running it on then production server. You can test your archiving jobs with the – dry-run OR you can use the –no-delete option if you’re not sure about. The purpose of this script is mainly to archive old data from the table without impacting OLTP queries and insert the data into another table on the same/different server OR into a file in a format which is suitable for LOAD DATA INFILE.
How does pt-archiver select records to archive?
Pt-archiver uses the index to select records from the table. The index is used to optimize repeated accesses to the table. Pt-archiver remembers the last row it retrieves from each SELECT statement, and uses it to construct a WHERE clause. It does this using the columns in the specified index that should allow MySQL to start the next SELECT where the last one ended – rather than potentially scanning from the beginning of the table with each successive SELECT.
If you want to run pt-archiver with a specific index you can use the “-i” option in –source DSN options. The “-i” option tells pt-archiver which index it should scan to archive. This appears in a FORCE INDEX or USE INDEX hint in the SELECT statements that are used to fetch rows to archive. If you don’t specify anything, pt-archiver will auto-discover a good index, preferring a PRIMARY KEY if one exists. Most of the time, without “-i” option, pt-archiver works well.
How to run pt-archiver?
For archive records into normal file, you can run something like
pt-archiver --source h=localhost,D=nil,t=test --file '/home/nilnandan/%Y-%m-%d-tabname' --where "name='nil'" --limit-1000
From archive records from one table to another table on same server or different, you can run something like
pt-archiver --source h=localhost,D=nil,t=test --dest h=fedora.vm --where "name='nil'" --limit-1000
Please check this before you use default file option (-F) in –source http://www.percona.com/doc/percona-toolkit/2.1/pt-archiver.html#cmdoption-pt-archiver–dest
Archiving in a replication environment:
In the replication environment it’s really important that the slave should not lag for a long time. So for that, there are two options which we can use while archiving to control the slave lag on slave server.
–check-slave-lag : Pause archiving until the specified DSN’s slave lag is less than –max-lag. In this option, you can give slave details to connect slave lag. (i.e –check-slave-lag h=localhost,S=/tmp/mysql_sandbox29784.sock)
–max-lag : Pause archiving if the slave given by –check-slave-lag lags.
This options causes pt-archiver to look at the slave every time when it’s about to fetch another row. If the slave’s lag is greater than the option’s value, or if the slave isn’t running (so its lag is NULL), pt-archiver sleeps for –check-interval seconds and then looks at the lag again. It repeats until the slave is caught up, then proceeds to fetch and archive the row.
Some useful options for pt-archiver:
–for-update/-share-lock : Adds the FOR UPDATE/LOCK IN SHARE MODE modifier to SELECT statements.
–no-delete : Do not delete archived rows.
–plugin : Perl module name to use as a generic plugin.
–progress : Print progress information every X rows.
–statistics : Collect and print timing statistics.
–where : WHERE clause to limit which rows to archive (required).
nilnandan@nil:~$ pt-archiver --source h=localhost,D=nil,t=test,S=/tmp/mysql_sandbox29783.sock --file '/home/nilnandan/%Y-%m-%d-tabname' --where "name='nilnandan'" --limit=50000 --progress=50000 --txn-size=50000 --statistics --bulk-delete --max-lag=1 --check-interval=15 --check-slave-lag h=localhost,S=/tmp/mysql_sandbox29784.sock
TIME ELAPSED COUNT
2013-08-08T10:08:39 0 0
2013-08-08T10:09:25 46 50000
2013-08-08T10:10:32 113 100000
2013-08-08T10:11:41 182 148576
Started at 2013-08-08T10:08:39, ended at 2013-08-08T10:11:59
Source: D=nil,S=/tmp/mysql_sandbox29783.sock,h=localhost,t=test
SELECT 148576
INSERT 0
DELETE 148576
Action Count Time Pct
print_file 148576 18.2674 9.12
bulk_deleting 3 8.9535 4.47
select 4 2.9204 1.46
commit 3 0.0005 0.00
other 0 170.0719 84.95
nilnandan@nil:~$
Percona Toolkit’s pt-archiver works with Percona XtraDB Cluster (PXC) 5.5.28-23.7 and newer, but there are three limitations you should consider before archiving on a cluster. You can get more information here.
pt-archiver is extensible via a plugin mechanism. You can inject your own code to add advanced archiving logic that could be useful for archiving dependent data, applying complex business rules, or building a data warehouse during the archiving process. Follow this URL for more info on that.
Bugs related to pt-archiver: https://bugs.launchpad.net/percona-toolkit/+bugs?field.tag=pt-archiver
More details about pt-archiver: http://www.percona.com/doc/percona-toolkit/2.2/pt-archiver.html
The post Want to archive tables? Use Percona Toolkit’s pt-archiver appeared first on MySQL Performance Blog.
May
06
2013
06
2013
--
Percona Toolkit 2.2.2 released; bug fixes include pt-heartbeat & pt-archiver
During the Percona Live MySQL Conference & Expo 2013 the week before last, we quietly released Percona Toolkit 2.2.2 with a few bug fixes:
- pt-archiver –bulk-insert may corrupt data
- pt-heartbeat –utc –check always returns 0
- pt-query-digest 2.2 prints unwanted debug info on tcpdump parsing errors
- pt-query-digest 2.2 prints too many string values
- Some tools don’t have –help or –version
- Some tools use @@hostname without /*!50038*/
- pt-stalk prints the wrong variable name in verbose mode when –function is used
- And more
 The first two bugs are important. Those using pt-archiver –bulk-insert with UTF-8 data should definitely upgrade. Those using pt-heartbeat –utc should also definitely upgrade.
Users may note the revival of the –show-all option in pt-query-digest. This had been removed in 2.2.1, but resulted in too much output in certain cases.
A new –recursion-method was added to pt-table-checksum: cluster. This method attempts to auto-discover cluster nodes, alleviating the need to specify cluster node DSNs in a DSN table (–recursion-method=dsn).
See https://launchpad.net/percona-toolkit/+milestone/2.2.2 for the full list of bugs fixed in Percona Toolkit 2.2.2.
Visit http://www.percona.com/software/percona-toolkit to download Percona Toolkit 2.2.2; it’s also in our main repos.
The post Percona Toolkit 2.2.2 released; bug fixes include pt-heartbeat & pt-archiver appeared first on MySQL Performance Blog.
Mar
22
2013
22
2013
--
5 Percona Toolkit Tools for MySQL That Could Save Your Day: April 3 Webinar
On April 3 at 10 a.m. PST, I’ll be giving a webinar titled “5 Percona Toolkit Tools for MySQL That Could Save Your Day.” In this presentation you’ll learn how to perform typical but challenging MySQL database administration tasks.
My focus will be on the following tools:
- pt-query-digest, to select the queries you should try to improve to get optimal response times
- pt-archiver, to efficiently purge purge data from huge tables
- pt-table-checksum/pt-table-sync, to check if data on replicas is in sync with data on the master
- pt-stalk, to gather data when performance problems happen randomly or are very short
- pt-online-schema-change, to run ALTER TABLE statements on large tables without downtime
You can reserve your spot for this free MySQL webinar now. If you can’t attend you’ll receive an link to the recording and the slides after the webinar.
More info on “5 Percona Toolkit Tools for MySQL That Could Save Your Day”Percona Toolkit for MySQL is a must-have set of tools that can help serious MySQL administrators perform tasks that are common but difficult to do manually. Years of deployments by tens of thousands of users including some of the best-known Internet sites, have proven the reliability of the Percona Toolkit tools for MySQL.
In this presentation, you will learn how you can use some of these tools to solve typical, real-world MySQL database administration challenges, such as:
- Selecting which queries you should try to optimize to get better response times
- How to efficiently purge data from a huge table without putting too much load on your server
- How to check which tables are affected when someone accidentally wrote to a replica and fix the problem without rebuilding the tables
- How to gather data for performance problems that happen randomly and last only a few seconds
- How to run ALTER TABLE on your largest tables without downtime
REGISTER NOW for this MySQL webinar
DOWNLOAD Percona Toolkit for MySQL
The post 5 Percona Toolkit Tools for MySQL That Could Save Your Day: April 3 Webinar appeared first on MySQL Performance Blog.