Sep
10
2026
--

Talking Drupal #569 – Site Templates

On today’s show we are talking about Site Templates, What they do, and How you can use them with guests Tim Lehnen & Adam Globus-Hoenich. We’ll also cover Haven as our module of the week.

For show notes visit: https://www.talkingDrupal.com/569

Topics

  • MOTW: Haven
  • What Site Templates Are
  • Canvas Components Included
  • Promoting Templates Beyond Drupal
  • Templates vs Distributions
  • Who Benefits from Templates
  • Template Types and Adoption
  • Where to Find Templates
  • Featured vs Installer List
  • Free vs Paid Templates
  • Recipes vs Templates
  • Distributions and Themes
  • Empowering Site Builders
  • Exporting a Template
  • Designing for Users
  • Releases Without Upgrades
  • Best Practices and AI
  • How to Contribute

Resources

Webinar: Drupal Canvas and Agentic Content Management: What Enterprise Teams Need to Know Drupal Site Templates Tim’s book – Fog & Fireflies

Guests

Tim Lehnen – @TimLehnen hestenet

Adam Globus-Hoenich – @PhenaProxima phenaproxima

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan Stephen Cross – SecondSginalMedia.com [stephencross]](https://www.drupal.org/u/stephencross) Amber Matz – tugboatqa.com [amber himes matz](https://www.drupal.org/u/amber himes matz)

Module of the Week Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

Haven – Site Template – Designed for non-profit sites, this template features a bright, warm design that can be adapted for many use cases. It comes pre-confifgured with blog, projects and people profiles, as well as newsletter signup, donation add-ons and more.

Sep
03
2026
--

Talking Drupal #568 – Off The Cuff #12

Today we are talking about Drupal Performance, Rapid Development, and Drupal Canvas Maturity with our hosts. We’ll also cover Microsoft 365 FullCalendar as our module of the week.

For show notes visit: https://www.talkingDrupal.com/568

Topics

  • Deprecating Module Theme Files
  • Migrating Hooks to Classes
  • Why This Change Matters
  • Drupal Performance Gains
  • Performance Audits and Lighthouse
  • Automating Checks and Spreadsheet Rant
  • AI Spreadsheet Cautionary Tale
  • Privacy Concerns with AI
  • Freelancer Pressure
  • Rapid Change Reality
  • Canvas Release Risks
  • Community Support Needed
  • AI For Documentation
  • Canvas Production Readiness
  • Canvas Architecture Debate
  • AI For Voting Research
  • LLM Bias And Sources

Resources

Guests

Martin Anderson-Clutz – mandclu.com mandclu

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi Amber Matz – tugboatqa.com [amber himes matz](https://www.drupal.org/u/amber himes matz)

MOTW Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

  • Brief description:
    • Have you ever wanted your users’ own Outlook calendars to show up right alongside your Drupal content in a calendar view? There’s a module for that.
  • Module name/project name:
  • Brief history
    • How old: created just last month, August 19 2026, by fabianderijk of Finalist
    • Versions available: 1.0.0, which works with Drupal 11
  • Maintainership
    • Brand new — the first and only release is from last month, and the whole commit history is basically launch day
    • Security coverage: brand new, so not yet
    • Test coverage: yes, both unit tests and kernel tests
    • Documentation: a genuinely thorough README — it walks through privacy, the config guard rails, and three different ways to customize event output
    • Open issues: none yet, it’s less than two weeks old
  • Usage stats:
    • Too new for a site count
  • Module features and usage
    • With this installed, it adds the signed-in user’s Microsoft 365, or Outlook, calendar as an extra event source on a FullCalendar view — so their personal appointments sit right next to the Drupal content the view already renders
    • It leans on the Microsoft 365 Connector module and its SSO submodule, plus the FullCalendar module. Each user must have signed in through Microsoft 365 SSO: anyone who hasn’t just sees no events, which is a clean fallback
    • It uses lazy loading, so it only fetches events in the date range the calendar is currently showing, not your whole calendar
    • Privacy is baked in: anything marked private or confidential in Outlook is masked, so it shows up as just “Busy”, with no title, location, or meeting link, unless the site builder deliberately turns masking off
    • The response itself is per-user and marked private, no-store, so it never lands in a shared or CDN cache
    • There’s a clever server-side cache too: it stores the raw Graph response before masking, so a single fetch can serve several displays that each have different masking settings
    • You get guard rails you can tune with Drush or an admin form: max events, max date range, cache lifetime, and a separate, shorter failure cache
    • That failure cache is a nice touch — if there’s no active Microsoft session, or Graph errors out, it caches the empty result briefly so a broken connection doesn’t get re-polled on every single calendar click
    • Under the hood it calls Graph’s calendarView endpoint rather than /me/events, which means recurring meetings get expanded into their individual occurrences — exactly what a calendar grid needs
    • Every event carries CSS classes for its status — busy, free, tentative, out-of-office, working elsewhere, cancelled — so you can style them however you want
    • And if CSS isn’t enough, there’s a server-side alter hook and a JavaScript pre-build event for fully custom rendering. Nice detail: the hook is explicitly guarded so you can’t use it to put back a title or location that masking just stripped out
    • Clearly this will be more useful for edge cases, for example an intranet, but I think this is a really interesting example of the power of Drupal as an integration layer, or as some like to put it, the “glass” through which a user can interact with multiple systems
Sep
02
2026
--

Mongorewind: Rewind Your MongoDB Test Data Without Restoring a Backup

Mongorewind: Rewind Your MongoDB Test Data Without Restoring a Backup

One day, my friend Martín told me about a problem he and his team were dealing with. 

Every time they needed to run a pre-production test, they had to restore a copy of the production database into their test cluster. That process alone takes about three hours because of the size of the database.

If something went wrong during the test and they needed to run it again, they had no choice but to sit through the entire restore cycle again.

Three hours. Twice (or more) just to run the pre-production test.

That’s what motivated me to build mongorewind, a terminal UI tool that watches your MongoDB cluster for changes and lets you instantly undo all of them, inserts, updates, replaces, and deletes. In reverse order, without touching your backup.

How It Works

mongorewind opens a cluster-wide change stream and records every data-modifying operation to a local log file. When you press R to rewind, it applies the inverse of each recorded operation in reverse chronological order:

Recorded operation Rewind action
insert deleteOne
update / replace replaceOne with pre-image (upsert)
delete replaceOne with pre-image (upsert)

To undo updates and deletes correctly, mongorewind needs to know what the document looked like before the change. 

It captures this automatically using MongoDB’s changeStreamPreAndPostImages feature, which it enables on every collection it finds — and on any new collection the moment it is created.


Requirements

  • Go 1.24+ and MongoDB 6.0+ running as a replica set or sharded cluster (change streams are not available on standalone instances, can be a 1 node replica set)

Installation

git clone https://github.com/zelmario/mongorewind.git
cd mongorewind
go build -o mongorewind .


Or install directly:

go install github.com/zelmario/mongorewind@latest


Running It

Start mongorewind pointing at your cluster before running any tests:

mongorewind --uri "mongodb://host1:27017,host2:27017,host3:27017/?replicaSet=rs0"

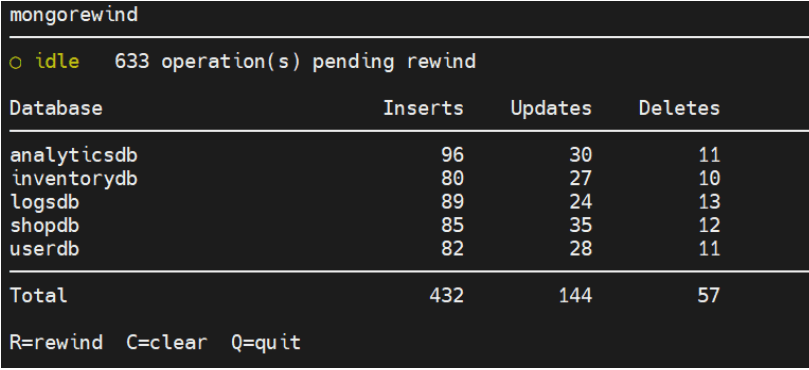
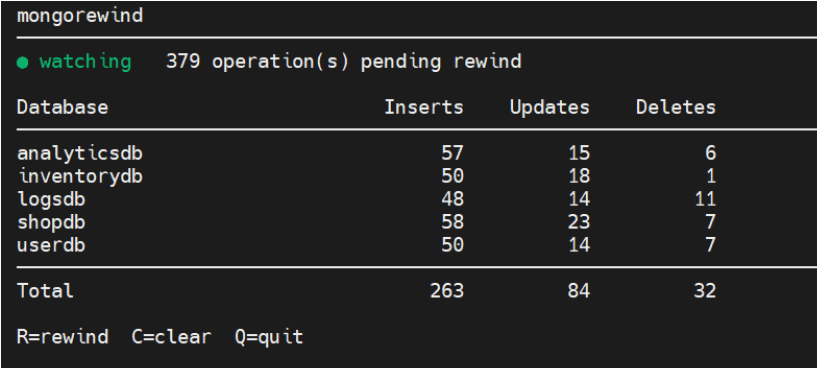
While mongorewind is running, you will see a terminal dashboard showing the operations it has recorded:

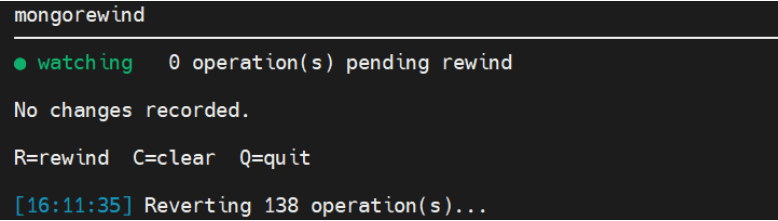
The status indicator shows ? watching (green) while the change stream is active. When you press R, it switches to ?idle (yellow) while the rewind is in progress.


Once the test run is complete and something went wrong, you can press R and mongorewind undoes every change it recorded — bringing the data back to exactly the state it was in before the test started. No restore, no waiting.


Using It in CI Pipelines

If you are running automated tests in a CI environment, mongorewind also supports a non-interactive mode. You can start the watcher in a terminal or the background and trigger rewinds from your scripts:

bash

# Start the watcher in the background

mongorewind --uri "mongodb://..." &

# Run your test suite

run_tests


# Rewind all changes and run again

mongorewind --rewind

run_tests


mongorewind –rewind exits with code 0 on success and 1 on error, so it integrates naturally into any CI pipeline.

If you use a custom log path, pass the same –log value to both commands so they share the same socket:

mongorewind --log /tmp/mytest.log --uri "mongodb://..." &

mongorewind --log /tmp/mytest.log --rewind


A Few Things to Keep in Mind

Replica set required. Change streams need a replica set or sharded cluster. If you are working locally, you can start a single-node replica set with:

mongod --replSet rs0


And then run rs.initiate() in the mongo shell.

The log file is scoped to a session. The file is truncated on startup and after a successful rewind, so each test session starts clean. System databases (admin, local, config) and system.* collections are ignored automatically.

Pre-images are enabled automatically. mongorewind polls every 2 seconds to catch newly created collections and enables changeStreamPreAndPostImages on them. You don’t need to configure anything manually.

Going Back to Martín’s Problem

With mongorewind, Martín’s team does the restoration once. After that, every time a test fails and they need to start over, they just run mongorewind –rewind. The database goes back to its original state in seconds, and the test runs again. Three hours become just a few seconds.


Contributions are welcome! Since I’m not a developer, your feedback is valuable. If you are a developer and notice any mistakes or want to enhance the script, please feel free to contribute!

The post Mongorewind: Rewind Your MongoDB Test Data Without Restoring a Backup appeared first on Percona.

Sep
02
2026
--

OpenID Connect Authentication for MySQL, Now Fully Open Source

Percona Server for MySQL now ships with a fully open source OpenID Connect (OIDC) authentication plugin, available starting with Percona Server for MySQL 8.4.11-11 and 9.7.2-2 (not yet released as of this writing). It allows a MySQL account to authenticate against any standards-compliant Identity Provider (IdP) instead of relying on a locally stored password, closing the gap with MySQL Enterprise Edition, which has offered OIDC authentication since MySQL 9.1 and, in several respects, going beyond it.

Oracle offers the same category of functionality, but its server-side plugin is part of the paid MySQL Enterprise Edition. Percona’s implementation is open source and adds three capabilities the Enterprise plugin does not provide: automatic signing-key synchronization from a JWKS endpoint, IdP group-to-role mapping, and proxy-user support. This article explains how the plugin works and why those differences matter in practice.

What OpenID Connect Brings to MySQL Authentication

OpenID Connect is an identity layer built on top of the OAuth 2.0 authorization framework [5]. Whereas OAuth 2.0 governs delegated access to resources, OIDC adds a standardized way for a client to establish who a user is. After a user signs in to an Identity Provider, the IdP issues a signed JSON Web Token (JWT), called an ID token, that carries the user’s identity and attributes in a verifiable, tamper-evident form.

Using that model for MySQL authentication brings several practical advantages over password-based accounts:

  • Alignment with single sign-on. Users authenticate once with their IdP and can reuse that session context across OIDC-aware applications, including databases. User lifecycle and password management remain centralized.
  • No long-lived secrets on the wire. ID tokens are short-lived and cryptographically signed, so there is no static password to steal, rotate, or accidentally commit to a configuration file.
  • Support for hybrid deployments. Organizations that run MySQL on-premises while hosting applications in the cloud can still authenticate through the same identity plane on both sides.
  • Broad interoperability. Because OpenID Connect is a widely adopted standard, the plugin can work with any compliant provider, including Keycloak, Okta, Microsoft Entra ID, and Google Identity.

None of that is unique to Percona; Oracle makes a similar value proposition for the Enterprise plugin. The real difference lies in how much operational burden the plugin removes from the administrator, which becomes clear in the next sections.

How OpenID Connect Authentication Works

Once the plugin and its configuration are in place, the authentication path is the same regardless of which IdP issued the token:

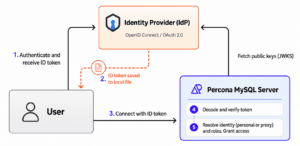
  1. The user authenticates to the IdP and receives a signed ID token.
  2. The token is written to a local file that only the client operating system account can read.
  3. The MySQL client uses an option that causes the client-side OIDC plugin to load and read the token from the file. The token is sent to the server as part of the authentication handshake.
  4. The server validates the secure channel and decodes the token. It then verifies the token signature using the selected IdP’s public key, checks the expiration time, and validates the configured claims.
  5. The server resolves the final identity as either a personal account or a group-based proxy target. The plugin may also return roles mapped from the user’s group membership.

Configuring Trusted Providers and Letting the Plugin Manage the Keys

Identity Providers rotate their signing keys periodically as a basic security measure. If a key is ever compromised, limiting its lifetime reduces the potential impact, and regular rotation also lowers the long-term value of any one key as a target. In practice, rotation is gradual: a new key is published and accepted before it starts signing tokens, and an old key remains valid for a period after it stops signing so that tokens already in flight can still be verified.

Public keys are exposed through the standard JWKS (JSON Web Key Set) endpoint, which applications can use to verify tokens issued by the IdP [6].

The Percona OpenID Connect authentication plugin can download public keys from a configured JWKS endpoint when the plugin is loaded, typically during installation and server startup, and store them in a cache. It also provides a User Defined Function (UDF) that can refresh the cache on demand or periodically through the Event Scheduler.

By contrast, Oracle’s counterpart plugin requires signing keys to be configured statically through the authentication_openid_connect_configuration server variable, supplied either as an inline JSON string or as a path to a JSON file. There is no retrieval or refresh from the JWKS endpoint, so keeping keys current after each rotation remains a manual task for the administrator. In the window just after a rotation, tokens signed with the previous key are still valid but cannot be verified until the configuration is updated. Percona’s plugin supports static key configuration as well, but that mode is better suited to testing or temporary setups than to production.

Example

Using the feature requires two simple steps. First, JWKS endpoint URL must be set in the plugin’s configuration. For example, the below configuration defines IdP named as example-keycloak (pay attention to jwks-url element):

{
  "example-keycloak": {
  "issuer-name": "https://keycloak.example.com/realms/master",
  "jwks-url": "https://keycloak.example.com/realms/master/protocol/openid-connect/certs",
  "audiences": [ "mysql-oidc" ]
  }
}

The second step is ensuring the MySQL event scheduler is running and creating an event updating the keys. For example, to enable updating the keys for example-keycloak every hour run from MySQL client:

CREATE EVENT update_oidc_keys
  ON SCHEDULE EVERY 1 HOUR
  DO SELECT update_jwks("example-keycloak");

Benefits of Using IdP Groups

This is where Percona’s plugin diverges most clearly from the Enterprise implementation.

Groups are managed by the corporate Identity Provider and group membership may be carried by ID tokens. OIDC does not define a standard claim for that, but most IdP implementations allow adding a group claim to the tokens. The Percona’s plugin allows the administrator to configure the group claim name so that it matches the token format used by the chosen IdP.

There are two practical ways to take advantage of this feature:  group-to-role mapping and proxy users.

Group-to-Role Mapping

Membership in a group can automatically translate into MySQL roles and therefore privileges across multiple MySQL servers at the same time. On a single server, the flow looks like this:

  1. The administrator creates roles and grants them privileges.
  2. The administrator defines the IdP group-to-MySQL role mapping in the plugin configuration file.
  3. When the user connects, the plugin returns the roles that match the user’s groups, and the server automatically grants those roles to the user.
  4. The user can activate any granted role and exercise the privileges assigned to it.

Please note, that group-to-role mapping still requires an account created for each user, but automates managing user privileges.

Example

To create roles and grant them some privileges one may run:

CREATE ROLE accounting;
GRANT ALL PRIVILEGES ON accounting_database.* TO accounting;
CREATE ROLE sales;
GRANT ALL PRIVILEGES ON sales_database.* TO sales;

Then, to to define the mapping add to IDP configuration:

"group-claim": "groups",
"group-role": [
  { "/accounting": "accounting" },
  { "/marketing": "marketing" }
]

Any user connecting with an ID token containing claim “groups”:[“/accounting”] will be granted with role accounting and effectively obtain access to accounting_database and so on.

Proxy Users

The proxy capability in MySQL allows an authentication plugin to request that the connecting external user be logged in as a different MySQL user. In this model, the external identity is the proxy user and the mapped MySQL account is the proxied user. The purpose is to let multiple users share accounts with the same privilege set, avoiding the need to create a separate personal database account for every individual.

This feature must be supported by the authentication plugin, whose job is to choose the proxied user according to the specifics of the authentication method. In the Percona OIDC plugin, that selection is based on the group claim in the token and works as follows:

  1. The administrator creates a proxy user identified by the OIDC plugin. This can be either a single anonymous account (”@”) without a specific group name, referred to as anonymous proxying, or multiple group-related accounts, referred to as named group proxying.
  2. The administrator creates proxied users for each group. These accounts should not use a login plugin, so nobody can connect to them directly. The username must match the group name.
  3. The administrator grants the PROXY privilege for each proxy user on all related proxied users.
  4. When a user connects, in the anonymous proxying case the plugin returns the user’s first group as the proxied username. In the named group proxying case, the plugin checks whether the user belongs to the group and returns that group as the proxied username.
  5. The server verifies that the requested proxied account exists and that the proxy user has the required PROXY privilege on it. If both checks succeed, the session runs with the proxied account’s privileges.

Other Features

Supported signing algorithms include RSASSA-PKCS1-v1_5, RSASSA-PSS, and ECDSA with SHA-256, SHA-384, and SHA-512 hashing functions.

The Percona approach uses the client-side OpenID Connect plugin from upstream MySQL, which ensures compatibility with the standard Oracle client.

Both client-side and server-side OpenID Connect plugins ensure that the token is sent via a secure channel. Accepted protocols are TCP protected by TLS, Unix sockets, and shared memory.

What OpenID Connect Authentication Does Not Do

There are some limits worth knowing.

The first comes from MySQL’s authentication design: any authentication plugin is used at connection time only. In the case of OIDC, the token is validated when the user connects, and a session that stays open may outlive the ID token that opened it. There is no out-of-the-box mechanism to force re-authentication after some time (except for idle connection timeout).

A similar situation applies to group-role mapping. The roles tied to the user’s groups in the ID token are granted or revoked at connection time. As a result, if a user is added to or removed from an IdP group, they must reconnect to Percona Server for the change to be reflected in their granted roles.

The proxying mechanism uses group membership claim instead of the token’s subject, so any token signed by a configured IdP that carries the required group is accepted. Group membership is your trust boundary in those modes, so treat it that way.

The current proxying implementation assumes the proxied user’s name matches the group name. This can be a problem when a group name isn’t a valid MySQL username (for example, it’s too long or contains disallowed characters), or when multiple groups need to map to a single account. We plan to add group-to-proxied-account mapping in future releases to address this.

The client-side plugin doesn’t verify the ID token (for example, check whether it has expired) before connecting, and the server doesn’t report the reason for access being denied (for security reasons). A good practice is to obtain a fresh token before connecting.

Conclusion

Functionally, Percona’s OpenID Connect plugin covers the same core ground as the counterpart in MySQL Enterprise Edition: signed ID tokens, claim validation, subject matching, and secure-transport enforcement.

It goes further in several important areas:

  • It is open source.
  • Keys can stay current automatically through JWKS synchronization.
  • Group-to-role mapping allows IdP group membership to drive MySQL role grants for the lifetime of the session.
  • Proxy-user support allows many IdP identities to share a smaller set of MySQL accounts.

Our OIDC implementation is suitable for real-world identity operations at scale. It can automatically map identities and groups managed by an IdP to database users and roles, and synchronize cryptographic keys.

References

  1. Percona Server for MySQL documentation: OpenID Connect authentication.
  2. Percona Server for MySQL documentation: Get started with OpenID Connect authentication.
  3. MySQL 9.7 Reference Manual: OpenID Connect Pluggable Authentication.
  4. MySQL 9.7 Reference Manual: Proxy Users.
  5. OpenID Foundation: How OpenID Connect Works
  6. auth0 Docs: JSON Web Key Sets.

Written by Michal Jankowski. Reviewed by Dennis Kittrell and Oleksiy Lukin.
Percona® is a registered trademark of Percona LLC. MySQL® is a registered trademark of Oracle Corporation.

The post OpenID Connect Authentication for MySQL, Now Fully Open Source appeared first on Percona.

Aug
31
2026
--

Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption

Expired TLS certificates can prevent new client connections and, when X.509 is used for Percona Server for MongoDB internal authentication, also prevent members of a replica set or sharded cluster from authenticating to one another.

In this post we will discuss performing a same-CA renewal: replacement certificates for server, member, and client leaf are issued by the existing trusted CA, and the X.509 attributes used for cluster membership do not change. In this scenario, the rotateCertificates command reloads TLS material for new connections without restarting mongod or mongos.

Important: Do not apply this hot-reload procedure when replacing the issuing CA, changing a certificate subject DN, or changing cluster-membership attributes. Those are not ordinary renewals.

What rotates, and what does not

Percona Server for MongoDB can reload the files configured through the following TLS options:

net:
  tls:
    mode: requireTLS
    certificateKeyFile: /etc/mongod/tls/server.pem
    CAFile: /etc/mongod/tls/ca.pem
    clusterFile: /etc/mongod/tls/cluster.pem

The certificateKeyFile contains the certificate and private key presented to normal clients. The clusterFile holds the certificate and key that a mongod or mongos process presents when connecting to other cluster members. If clusterFile is not configured, certificateKeyFile is also used for member authentication.

The rotateCertificates command affects new TLS connections. It does not terminate established client sessions or force a replica-set election.

Before the maintenance window

Begin this process well in advance of the certificate expiry, and avoid performing your first attempt in a production environment.

  1. Inventory every process and client certificates. Include all mongod members, all mongos routers, application drivers, mongosh hosts, backup jobs, monitoring, and automation tools.
  2. Confirm this is a same-CA renewal. The issuer chain trusted by every participant stays the same, and the O, OU, and DC attributes used for default internal X.509 membership matching remain unchanged.
  3. Create a new PEM file for every server and client that needs rotation. A PEM file referenced by certificateKeyFile or clusterFile must include both the certificate and its matching private key. The file must strictly contain the key first, followed by the certificate, including their encapsulation boundaries.
  4. Verify the new certificate details and validate the cert against the CA before copying to the production TLS directory

Stage a renewed server or member certificate

There are a few limitations for rotating certificates online:

  • Each new certificate must have the same filename and same filepath as the certificate it is replacing.
  • If the TLS Certificate is password-protected, its password must be the same as the old certificate it is replacing.

If CAFile, a CRL, or another configured TLS input is being renewed as part of the same operation, replace it before invoking the reload command. The command reloads the configured TLS inputs as a set; a missing or invalid input causes the reload to fail.

Luckily, incorrect certificate files will cause the rotation to fail, but will not invalidate the existing configuration or have any other side effects.

Reload one process

Connect directly to the specific mongod or mongos with an administrative user and execute the following command:

db.getSiblingDB("admin").runCommand({rotateCertificates: 1, message: "Renewed TLS certificate"})'

Immediately validate a new TLS connection to that process with a renewed client certificate. Also inspect the log for the successful certificate-rotation message and any TLS errors. Check our documentation for guidelines to perform the procedure on a replica set or sharded cluster.

Final validation and cleanup

After completing the procedure, it is a good idea to reconfirm the expiry date and SANs of the certificate presented by every mongod and mongos. Retain the old certificates only for the approved overlap period, then remove or revoke them. Don’t forget to record the new expiry dates and create alerts with enough lead time before the expiration date of the new certificates.

When the CA or member identity changes

A different procedure is required when any of the following changes:

  • The issuing CA or trusted CA chain.
  • The subject DN used by a MONGODB-X509 client user.
  • The O, OU, or DC values used for default intra-cluster X.509 membership matching.
  • net.tls.clusterAuthX509.attributes or net.tls.clusterAuthX509.extensionValue.

This is a topic for another time.


The post Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption appeared first on Percona.

Aug
31
2026
--

Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption

Expired TLS certificates can prevent new client connections and, when X.509 is used for Percona Server for MongoDB internal authentication, also prevent members of a replica set or sharded cluster from authenticating to one another.

In this post we will discuss performing a same-CA renewal: replacement certificates for server, member, and client leaf are issued by the existing trusted CA, and the X.509 attributes used for cluster membership do not change. In this scenario, the rotateCertificates command reloads TLS material for new connections without restarting mongod or mongos.

Important: Do not apply this hot-reload procedure when replacing the issuing CA, changing a certificate subject DN, or changing cluster-membership attributes. Those are not ordinary renewals.

What rotates, and what does not

Percona Server for MongoDB can reload the files configured through the following TLS options:

net:
  tls:
    mode: requireTLS
    certificateKeyFile: /etc/mongod/tls/server.pem
    CAFile: /etc/mongod/tls/ca.pem
    clusterFile: /etc/mongod/tls/cluster.pem

The certificateKeyFile contains the certificate and private key presented to normal clients. The clusterFile holds the certificate and key that a mongod or mongos process presents when connecting to other cluster members. If clusterFile is not configured, certificateKeyFile is also used for member authentication.

The rotateCertificates command affects new TLS connections. It does not terminate established client sessions or force a replica-set election.

Before the maintenance window

Begin this process well in advance of the certificate expiry, and avoid performing your first attempt in a production environment.

  1. Inventory every process and client certificates. Include all mongod members, all mongos routers, application drivers, mongosh hosts, backup jobs, monitoring, and automation tools.
  2. Confirm this is a same-CA renewal. The issuer chain trusted by every participant stays the same, and the O, OU, and DC attributes used for default internal X.509 membership matching remain unchanged.
  3. Create a new PEM file for every server and client that needs rotation. A PEM file referenced by certificateKeyFile or clusterFile must include both the certificate and its matching private key. The file must strictly contain the key first, followed by the certificate, including their encapsulation boundaries.
  4. Verify the new certificate details and validate the cert against the CA before copying to the production TLS directory

Stage a renewed server or member certificate

There are a few limitations for rotating certificates online:

  • Each new certificate must have the same filename and same filepath as the certificate it is replacing.
  • If the TLS Certificate is password-protected, its password must be the same as the old certificate it is replacing.

If CAFile, a CRL, or another configured TLS input is being renewed as part of the same operation, replace it before invoking the reload command. The command reloads the configured TLS inputs as a set; a missing or invalid input causes the reload to fail.

Luckily, incorrect certificate files will cause the rotation to fail, but will not invalidate the existing configuration or have any other side effects.

Reload one process

Connect directly to the specific mongod or mongos with an administrative user and execute the following command:

db.getSiblingDB("admin").runCommand({rotateCertificates: 1, message: "Renewed TLS certificate"})'

Immediately validate a new TLS connection to that process with a renewed client certificate. Also inspect the log for the successful certificate-rotation message and any TLS errors. Check our documentation for guidelines to perform the procedure on a replica set or sharded cluster.

Final validation and cleanup

After completing the procedure, it is a good idea to reconfirm the expiry date and SANs of the certificate presented by every mongod and mongos. Retain the old certificates only for the approved overlap period, then remove or revoke them. Don’t forget to record the new expiry dates and create alerts with enough lead time before the expiration date of the new certificates.

When the CA or member identity changes

A different procedure is required when any of the following changes:

  • The issuing CA or trusted CA chain.
  • The subject DN used by a MONGODB-X509 client user.
  • The O, OU, or DC values used for default intra-cluster X.509 membership matching.
  • net.tls.clusterAuthX509.attributes or net.tls.clusterAuthX509.extensionValue.

This is a topic for another time.


The post Rotating Expiring X.509 Certificates in Percona Server for MongoDB with Minimal Service Interruption appeared first on Percona.

Aug
27
2026
--

Talking Drupal #567 – Common Vulnerabilities & Exposures

Today we are talking about Security, Vulnerabilities, and how to avoid exposure with guest Dave Welch. We’ll also cover Security Scanner as our module of the week.

For show notes visit: https://www.talkingDrupal.com/567

Topics

  • What Are CVEs
  • CVE Lifecycle and Disclosure
  • AI Era Security Challenges
  • What CVE Program Excludes
  • Patch Fast Reality
  • Global Security Signals
  • CVE Timing Judgment
  • KEV Flags Explained
  • CVE Updates Link Rot
  • Who Decides CVE
  • Sneaky Patch Dangers
  • ADP Program Fixes
  • Small Team Triage
  • Vulnerability Tsunami AI
  • Autonomous Security Future
  • Legal Pressure Budgets

Resources

Guests

David Welch – github: dwelch2344 dwelch2344

Hosts

Nic Laflin – nLighteneddevelopment.com nicxvan John Picozzi – epam.com johnpicozzi JD Flynn – dorficus

MOTW Correspondent

Martin Anderson-Clutz – mandclu.com mandclu

  • Brief description:
    • Have you ever wanted a fast way to catch the security mistakes that slip into custom Drupal code — especially the code your AI assistant just wrote — before it ships? There’s a module for that.
  • Module name/project name:
  • Brief history
    • How old: created in July 2026 by Mayank Gupta (mayankguptadotcom) of Acquia
    • Versions available: 1.0.0, which works with Drupal 10.3 and 11
  • Maintainership
    • Actively maintained — created and shipped its first stable this summer, with steady development right through late July
    • Security coverage
    • Test coverage — and it’s strong: unit and kernel tests, including a regression corpus built from real Drupal core advisories
    • Documentation? In-depth README with a full check table and CI recipes, plus a CHANGELOG
    • Number of open issues: 1 issue, not a bug
  • Usage stats:
    • 2 sites (it’s brand new)
  • Module features and usage
    • Provide a Drush command, has no UI — you point drush security:scan at a module or any path, it reads the code statically, and prints a prioritized, OWASP-mapped list of things to review
    • It’s built for the age of AI-written code — the checks target the classes AI assistants keep reintroducing: routes with no access check, #markup and |raw XSS, missing CSRF tokens, unserialize() on untrusted data, hardcoded secrets
    • Then there’s an optional deep pass: with the Psalm static analysis scanning engine installed, it’ll trace untrusted input across functions and files to catch cross-function issues. And it’s honest about state — the report always says whether that deep pass ran, was skipped, or failed, so a failure never gets mistaken for a clean scan
    • One nice detail under the hood: a tokenizer-backed “code map” that knows whether a match is real code, a comment, or a string — so it won’t flag the word “unserialize” sitting in a doc comment. That kills the single biggest source of false positives
    • The checks are regression-tested against real Drupal advisories (Drupalgeddon, Drupalgeddon2, the 2019 unserialize bug, etc) so a pattern that caused an actual CVE can’t quietly come back in your custom code
    • Output comes in three flavors: a readable table, JSON for CI and AI agents, and SARIF — which means findings show up as annotations right on your GitHub or GitLab merge-request diff instead of buried in a job log
    • For adopting it on an existing codebase there’s a baseline file — you fingerprint the findings you’ve reviewed, with a required reason on each, and they stop failing the build but never go invisible; every run still counts them
    • It exits non-zero on error-level findings, so it drops straight into CI or a pre-commit hook
    • And it’s extensible — checks are Drupal plugins with a #[SecurityCheck] attribute, so any module can add its own or alter the ones that ship
    • Big caveat, and the module says this itself: a finding means “review this,” not “this is broken.” Static analysis has false positives, and a clean scan doesn’t prove the code is secure — access-control logic especially still needs human review
    • I first heard about this module over beverages at Drupalcamp Asheville, so I know that this module was largely vibe-coded, after having an AI agent ingest every single Drupal security team CVE. So I like to think of this module as security pattern recognition tool, but of course it does even more
Aug
27
2026
--

Benchmarking vector indexes

Nearly every database has vector search now, and every one of them has a blog post with a big number in it. Almost none of those numbers can be checked, because the thing that makes them meaningful is usually missing.

We built a vector-bench to stop guessing. You name the engines you want, build them from pinned versions, put each one in the same container on the same cores with the same data, run the same measurements against all of them, and write a report. This post is about how it measures.

If you work with databases but haven’t touched vectors yet, the first half is the part you need.

What’s being indexed

An embedding is a fixed-length array of floats that comes out of a model. The useful property is that semantically similar inputs land close together when you measure the distance between them.

Two distance measures cover almost everything. L2 is an ordinary straight-line distance, the Pythagorean one, extended to however many dimensions you have. Cosine Similarity  measures the angle between two vectors and ignores their length. Which one applies is decided by the model that produced the embeddings. It isn’t a choice you get to make at query time, and getting it wrong is a good way to produce nonsense.

So the query you want is “the 10 rows whose vectors are nearest this one”:

SELECT id FROM documents ORDER BY distance(embedding, ?) LIMIT 10;

That 10 is k.

Now the problem. Answering that exactly means computing the distance from your query vector to every single row, then sorting. No B-tree or hash index helps, because neither one can order a million points by proximity in 1536 dimensions. Exact vector search is a full table scan with a lot of arithmetic bolted on.

A vector index gives up exactness to avoid that. It looks at a few thousand promising candidates instead of every row and returns the best it found. That’s the approximate nearest neighbour search, or ANN. It’s usually right.

“Usually” is doing a lot of work in that sentence, and pinning it down is most of what this benchmark does.
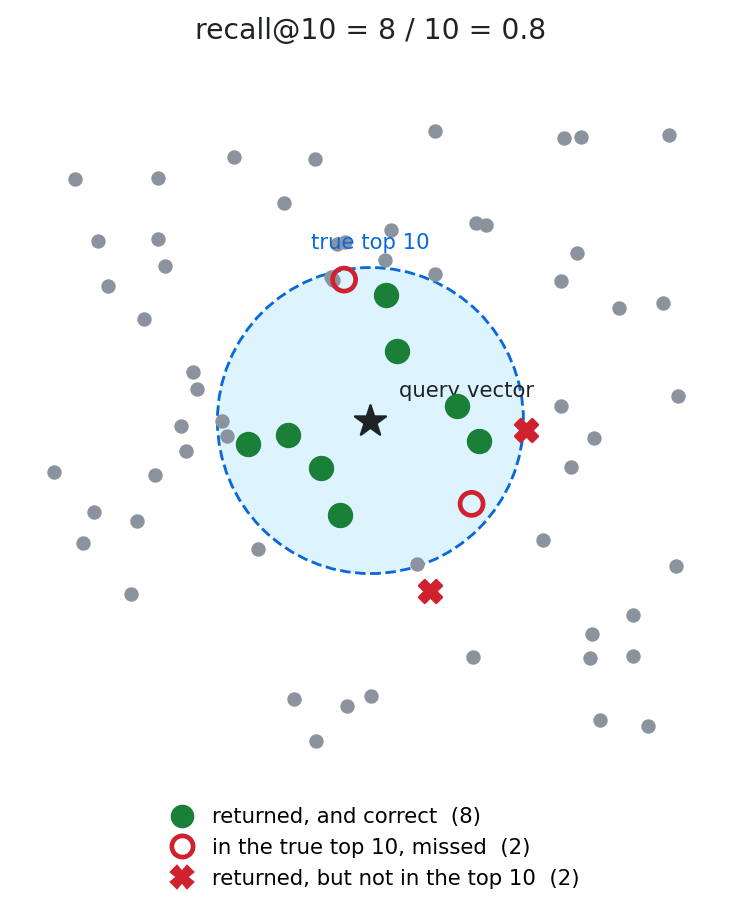
To score that you need to know the right answer in the first place. That’s the ground truth: the true nearest neighbours for every query, computed once by brute force with no index involved. The public ANN datasets ship theirs alongside the vectors, and without it you couldn’t score an approximate index at all.

This is the number that makes everything else meaningful, and it’s the one most vector search claims leave out. That omission is the reason this project exists.

The two kinds of vector index

Almost every database that has added vector search picked one of two designs. They attack the same problem from opposite ends, and which one you have decides what you’re allowed to tune.

HNSW

HNSW stands for Hierarchical Navigable Small World, which is a mouthful for something fairly intuitive. If you’ve ever implemented a skip list, you already have the shape of it.

It’s a graph of vectors built in layers. Every vector is a node, linked to some number of its nearest neighbours. The top layer has few nodes and its links jump long distances across the data. Each layer below has more nodes and shorter links. A search starts at the top and keeps hopping to whichever neighbour is closer to the query. When nothing is closer, it drops a layer and carries on, until it runs out of layers.
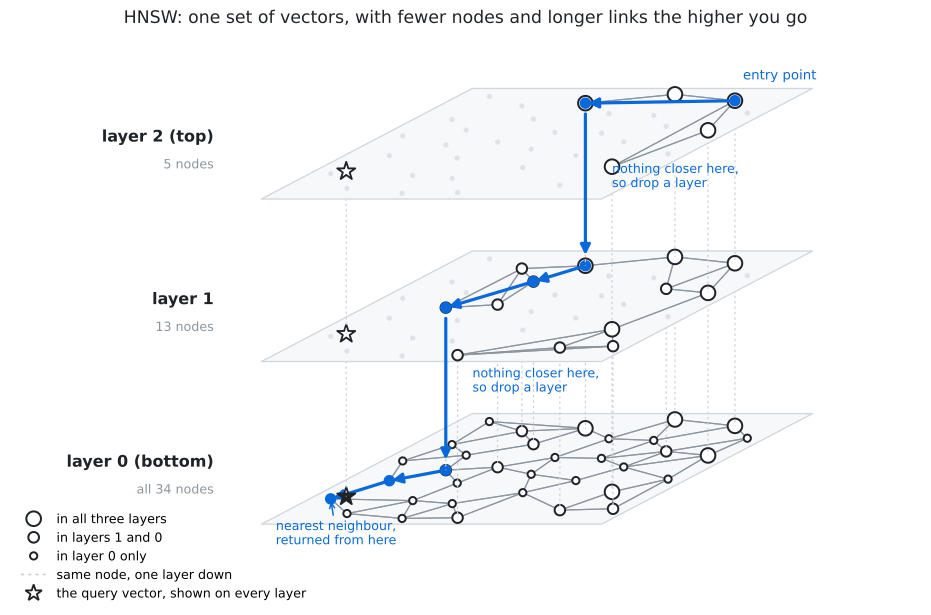
Two settings matter:

  • M is how many links each node keeps. It’s fixed when the index is built. Higher M means a better-connected graph and better recall, at the cost of a slower build and a bigger index.
  • ef_search is how many candidates the search keeps track of while it walks. It’s a session variable, so you can change it per query. Turn it up and the search visits more nodes, gets better recall, and runs slower.

There’s ef_construction too, the same idea applied while the index is being built. Not every engine lets you set it, which turns out to matter when you try to compare them fairly.

IVF

IVF stands for Inverted File. It partitions the data instead of linking it, not unlike list partitioning on a table.

At build time it groups the vectors into nlist clusters, each with a representative vector at its centre. At query time it compares the query against those representatives, picks the closest nprobe clusters, and searches only inside them. It builds much faster than HNSW and uses less memory, but usually gives worse recall at the same speed. It misses when the true neighbour happens to sit just outside the clusters it looked in.
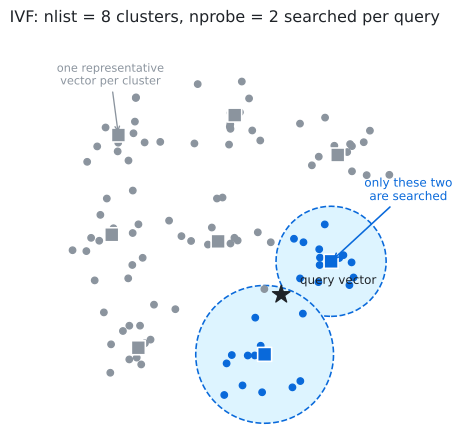
We only test engines running HNSW, which is what most databases shipped. Putting an IVF engine on the same chart would mostly measure the gap between two algorithms rather than how well anybody implemented one, so IVF-only engines get their own bucket.

Why one number is never enough

Recall isn’t a property of an engine. It’s a setting, and ef_search is the dial.

Here’s one HNSW index on one machine, same data, same queries. The only difference is that on the first row the search tracks 10 candidate nodes as it walks the graph, and on the second it tracks 800:

ef_search=10 3,678 queries/sec recall 0.9593
ef_search=800 409 queries/sec recall 0.9987

Keeping 800 candidates instead of 10 finds a better answer and takes nine times as long. Both rows are honest measurements of the same index on the same hardware.
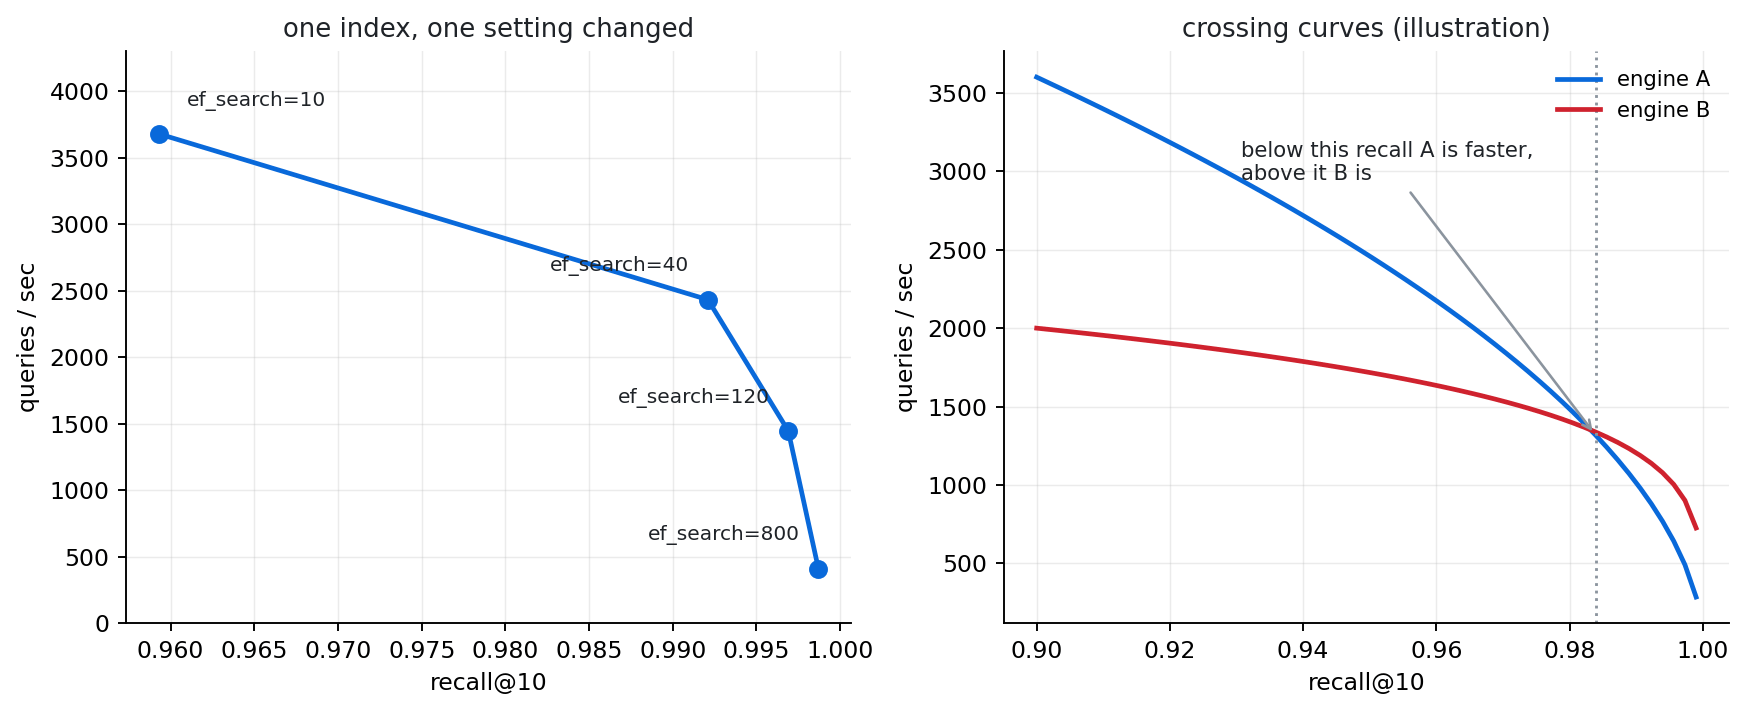
Which is why “our database does 3,678 vector queries a second” tells you nothing. You don’t know how often it was handing back the wrong rows, and the person quoting it may not know either. The reverse is just as empty: recall with no throughput next to it is free, because recall 1.0 is always available if you turn the index off and scan the table.

Every measurement here is a pair. If you take one thing from this post, take that.

What the harness puts on each engine

One table per engine. An id, an integer tag column used only by the filtered tests, the vector, and an HNSW index on it at a configured M.

CREATE TABLE t1 (
id INTEGER PRIMARY KEY,
tag INTEGER NOT NULL,
v VECTOR(1536)
);


Then two queries, plain top-k and the same search restricted to a subset of rows:

SELECT id FROM t1 ORDER BY distance(v, ?) LIMIT 10;
SELECT id FROM t1 WHERE tag < ? ORDER BY distance(v, ?) LIMIT 10;


tag holds values 0 to 99 spread evenly, so tag < 10 passes about 10% of rows and tag < 1 about 1%. That’s how we control selectivity.

Every engine writes all of this differently. Some declare the index inside CREATE TABLE, others want a separate CREATE INDEX, and the distance functions have different names everywhere. Translating that is the driver’s job, and the drivers are the only engine-specific code in the whole harness.

Every engine also has at least one setup detail that will quietly wreck your numbers. PostgreSQL, for instance, stores oversized values out of line in what it calls TOAST, and a 1536-dimension vector counts as oversized. Unless the column is set to STORAGE PLAIN, every single distance comparison pays for an extra fetch. It’s one line of DDL. Miss it and you publish PostgreSQL looking slow for a reason that has nothing to do with its vector search, and you’d never know from the results.

What we measure

Recall against throughput. Iterate ef_search against a fixed index, record recall and QPS at each point, repeat at a few values of M. k=10 throughout. The query vectors come from the dataset’s own held-out query set, never from the rows we loaded, because searching for a vector that’s already in the index is a much easier problem and would flatter everybody equally.

The two settings behave completely differently, and it shapes how long a run takes. ef_search is a session variable, so iterating it reuses the index that’s already built and each extra point costs almost nothing. M is baked into the index, so every value of M means dropping the table and loading the entire dataset again. On a million 1536-dimension vectors that’s hours per value. Hence many ef_search points and very few M values.

Build cost. Wall time, rows per second, index size on disk, peak memory.

This is the easiest place in the whole benchmark to publish a misleading number, because engines don’t build the index the same way. Engines can build indexes either incrementally, bulk, or both. What does that mean? 

Incremental. The graph is updated on every INSERT. Loading is slow, but when the last row lands the index is finished and the table is ready to query.

Bulk. All the rows load first, then the whole graph gets built in one pass. Much faster in total, but the table can’t answer a vector query until the build finishes.

Those are two different operations. One engine in our set does both, and its bulk path loaded 18 times more rows per second than its own incremental path. Same engine, same data, same machine, 18x apart.

So a bulk number from one engine put next to an incremental number from another doesn’t compare engines at all. It compares two ways of building an index, and the ratio looks impressive enough that people quote it anyway. We measure both paths on any engine that has both, and the report says which is which.

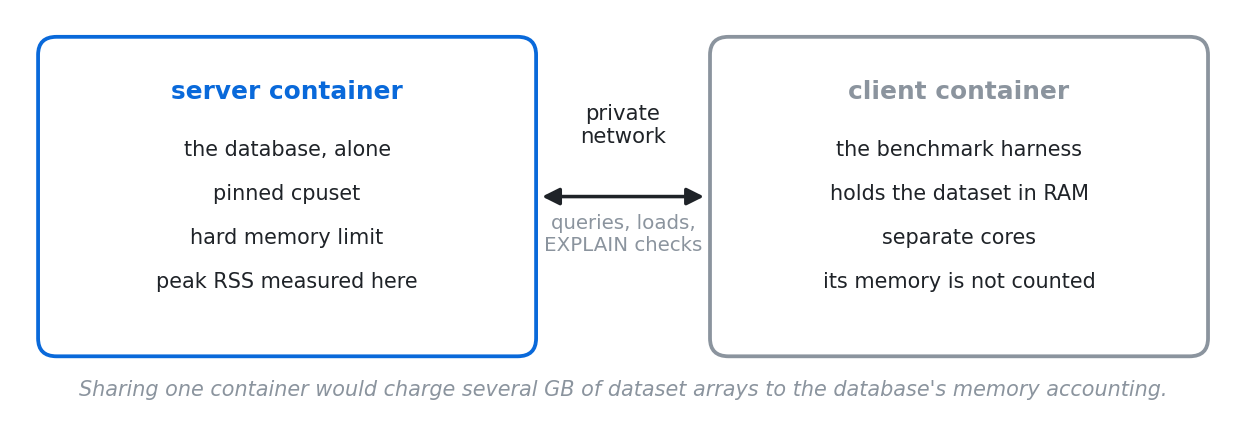
Peak memory comes from the server’s container, with the database as the only thing running in it. The harness runs in a separate container and reaches the server over a private network.

That separation matters more than it sounds. The client holds the entire dataset in memory, several GB of Python arrays. If it shared a container with the database, the container’s memory accounting would count those arrays as database memory, and every memory figure we published would be inflated by whatever the client happened to be holding.
Concurrency. QPS and latency percentiles from 1 to 32 clients. Engines cache their graphs in quite different ways and none of that shows up until clients start competing for the same cache. We report how much of the ideal speedup each engine actually got alongside raw QPS, because an engine that stops gaining throughput at 2 clients while its p99 gets 15 times worse is doing something very different from one that keeps scaling, and a throughput column on its own hides that completely.

Filtered search, at several selectivities down to 1% of rows passing. This is the case that’s supposed to justify keeping vectors in your database instead of a dedicated store, so it deserves more attention than it usually gets.

Filtering changes what “correct” means. The true top 10 among rows where tag < 10 is not the true top 10 overall, so for every selectivity we recompute ground truth by brute force over only the rows that pass. Score filtered results against the unfiltered ground truth that shipped with the dataset and every engine gets a recall near zero. We know, because we did exactly that for a while.

Some queries come back with fewer than 10 rows. In one run, 81 out of 200 did. This is not the data running out. At 10% selectivity about 99,000 rows pass the filter, so there are always at least 10 to find. The cause is the order of the operations. HNSW searches by distance first, then applies the WHERE clause. It gathers a few thousand candidates, the filter throws most of them away, and sometimes fewer than 10 are left. (If a filter really did match fewer than 10 rows, the ground truth shrinks too, and the engine still scores 1.0.) Recall already handles this. A row the engine did not return counts as a miss, so six correct rows score 0.6. We report the count because two different problems score the same. “10 rows, four of them wrong” and “six rows, all correct” are both 0.6. The first needs a wider search. The second needs iterative scanning. The count tells you which one you have. It also means the throughput is flattered, since six rows is less work than ten.

Churn. Recall and throughput before and after deleting and reinserting part of the corpus, since deletions leave graph edges pointing at rows that are gone. Whether rebuilding the index recovers what’s lost, we don’t know yet. It’s the obvious next thing to test and we haven’t done it.

Keeping the comparison fair

Everything runs twice.

The normalized pass gives every engine identical CPU, memory and cache budgets, so a difference in the results belongs to the implementation rather than to who was handed more RAM. The tuned pass lets each engine use the settings its own documentation recommends. Tuned is more realistic and less controlled, which is exactly why it doesn’t replace the first one. A result that survives both passes is about the engine. One that flips between them is interesting for a completely different reason.

Cores are pinned explicitly. One logical CPU per physical core, because SMT siblings share execution units and two threads on one core don’t behave like two cores. Never a mix of P-cores and E-cores on hybrid chips either, since migration between core types adds more variance than several of the effects we’re trying to measure. Durability is relaxed the same way everywhere, or we’d be comparing default fsync policies and calling it vector search.

Some differences can’t be equalised at all, so we write them down instead of pretending. A knob only one engine exposes goes unused in the normalized pass, because using it would hand that engine a tuning axis nobody else has. An engine that insists on a particular isolation level gets it set for everyone. And defaults that are obviously placeholders get sized from a shared budget — one family of engines still ships a 16 MiB graph cache, which is nothing, and judging an engine on a value its own vendor expects you to change measures absolutely nothing. All of these land in a “known asymmetries” section above the results.

One hardware note that catches people out. Several of these implementations ship hand-written AVX-512 code for the distance maths, where a single instruction does the arithmetic for 16 floats at once. The same index on a CPU without AVX-512 is effectively a different benchmark, and the slowdown isn’t the same for every engine, so you can’t even scale the numbers to compensate. The CPU model and its feature flags go into every run’s manifest for that reason, along with engine versions and commits, image IDs, and the resource limits as they are actually resolved rather than as we requested them. No manifest, no report.

Reading the results

Read the validity section before you look at a single chart. Our reports go environment, then validity, then known asymmetries, then results, in that order on purpose. A failed phase, an engine returning short result sets, a CPU missing the instruction set the engines wanted — all of it lands in front of you before you’ve formed an opinion.

The thing to watch for is the silent full scan.

Any of these engines will quietly stop using the vector index and scan the table instead. A scan returns exact results, slowly, so in the output it looks like high recall and low throughput. That’s indistinguishable from a conservatively tuned index unless you go and read the query plan.

It happens for thoroughly boring reasons. One engine’s optimizer costs the vector index against a table scan and takes the scan once the LIMIT is above roughly a quarter of the table, and we still haven’t found a setting that moves it. Another falls back with no error and no warning when the query asks for a different distance than the index was built for — build the index for cosine, write the query with the L2 operator, and you get a sequential scan and a sort, with nothing anywhere to tell you.

So every driver runs EXPLAIN for each configuration and checks the index name appears in the plan.

WARNING: vector index NOT used (k=10, filtered=True). Plan: …Seq Scan…

Anything that is scanned goes into validity. This is far and away the easiest way to produce impressive vector benchmark numbers by accident, and if a benchmark doesn’t mention checking for it, we’d want to know why before believing anything in it.

For recall against throughput, the useful presentation is a curve rather than a number. Iterate ef_search, plot recall against QPS, keep the best points: for each level of accuracy, the highest throughput anything reached at it. One engine beats another only where its curve sits above the other’s at the same recall. If the curves cross, then the answer genuinely depends on how accurate you need to be, and saying so is a result rather than a dodge.

Curves do invite comparing shapes instead of heights at one point, so there are bar charts as well, QPS at recall floors of 0.90, 0.95 and 0.99. Pick the accuracy you’d actually accept and read across.

Things that went wrong while we built this

Worth listing, partly because they’re the reason to trust anything else here, and partly because anyone building something similar will walk into them.

Our first ingest numbers were garbage. The load path was doing one INSERT per network round trip with autocommit on, and we measured 88 rows a second. Batching 500 rows per transaction took the same engine to 373. Publishing the first number would have been benchmarking our own client and calling it a database.

Filtered search and churn were scored against full-corpus ground truth even on runs that used a subset of rows. Every engine looked bad and the bug was entirely ours. Ground truth is now keyed on dataset, k, row count and selectivity.

Both resource passes shared one results directory, and the ANN runner skips configurations that already have results. So the tuned pass quietly skipped everything the normalized pass had computed, and our tuned numbers were mostly normalized numbers wearing a different label. That one took an embarrassingly long time to notice.

Readiness probes lie. One engine’s standard “are you accepting connections” check returns success before the database it’s supposed to create actually exists. The probe passed, the first query failed, and we spent a while convinced it was an engine problem.

The most recent one, on a 1536-dimension corpus. The ANN runner holds the whole dataset in memory twice, once in the parent process and again in a forked worker, and the copies aren’t shared. That’s roughly 12 GB for a million embeddings, on top of whatever the server is using, in a container we’d sized for the server alone. The kernel killed the worker. The runner doesn’t check worker exit codes, so it logged “Terminating 1 workers”, exited successfully and wrote no results — which looks exactly like a run that had nothing left to do. Three hours to fail, and it failed silently.

Adding a database

This is the part we cared most about getting right, because the whole point was to avoid rebuilding the apparatus every time somebody ships vector search. Each engine needs:

  • a Dockerfile producing a runtime image and a test image from a pinned version
  • a config declaring ports, credentials, and which server settings map onto the normalized CPU and memory budget
  • a module for the recall and throughput side
  • a driver: create index, load, query, filtered query, index size, and the EXPLAIN check

What’s next

Results, published with the manifests and the raw per-configuration records, so you can check them instead of taking our word for it.

Everything is at https://github.com/Percona-Lab/vector-bench harness, drivers, Dockerfiles, docs. If we’re measuring something wrong, or being unfair to an engine you know better than we do, tell us.

The post Benchmarking vector indexes appeared first on Percona.
Aug
27
2026
--

Performance Progression of Percona Server for MySQL 8.4

1. Purpose and scope

This performance investigation aims to look into the read/write performance of Percona Server for MySQL 8.4 and how it changed between versions released in 2026:

  • 8.4.8-8 released on 12 March 2026
  • 8.4.10-10 released on 30 June 2026
  • 8.4.11-11 released on 20 August 2026

We want to see if there are improvements in scalability and performance in OLTP read/write operations, where the improvements are most noticeable and how they were achieved. For some readers this material might help with making the decision whether upgrading to a newer version is worth the effort.

An important note is that the new features or security patches will not be taken into consideration.

Measuring Latency (Percentiles) and Resource Utilization (CPU, RAM, I/O) is not in the scope of this post.


2. Configuration and Methodology

The configuration was as follows:

Benchmark Sysbench OLTP Read-Write
CPU Intel Xeon Gold 6230 (2×20 cores, HT = 80 logical CPUs)
RAM 187 GiB DDR4
Storage NVMe SSD (2.9 TB) INTEL SSDPE2KE032T8
OS Ubuntu 24.04, kernel 6.8.0-60-generic
DB Engines Percona Server for MySQL 8.4.8-8 (release build)
Percona Server for MySQL 8.4.10-10 (release build)Percona Server for MySQL 8.4.11-11 (release build)

The benchmarks were done across the following dimensions:

Database Sizes (Row Number) 24Gb (100M rows) / 48Gb (200M rows) / 96Gb (400M rows)
Number of tables in DB Schema 20 (this number is constant for all runs)

Database Schema definition can be downloaded from here: 

https://percona-lab-results.github.io/2026-interactive-metrics/schema_dump.sql

Number of concurrent threads 1 / 4 / 16 / 32 / 64 / 128 / 256 / 512
Buffer to Data Ratio 1:12 (I/O bound), 1:2 (Partially buffered), 1:1 (Fully buffered)

One of the points in benchmarking was to create combinations of similar Buffer to Data Ratios, but with the different Database Sizes. This gives us the following possible combinations of innodb_buffer_pool_size and Database Size:

1:12 (I/O bound) innodb_buffer_pool_size = 2G, Data Size = 24Gb
innodb_buffer_pool_size = 4G, Data Size = 48Gb
innodb_buffer_pool_size = 8G, Data Size = 96Gb
1:2 (Partially buffered) innodb_buffer_pool_size = 12G, Data Size = 24Gb
innodb_buffer_pool_size = 24G, Data Size = 48Gb
innodb_buffer_pool_size = 48G, Data Size = 96Gb
1:1 (Fully buffered) innodb_buffer_pool_size = 32G, Data Size = 24Gb
innodb_buffer_pool_size = 64G, Data Size = 48Gb
innodb_buffer_pool_size = 128G, Data Size = 96Gb

We should be able to see how efficiently the server manages an increasingly larger number of rows while keeping the Buffer to Data Ratio the same.

Execution of the benchmarks was done as follows:

Ramp-up 24G – 600 sec (10 min) – could be shorter
48G – 600 sec (10 min)96G – 900 sec (15 min)

The Ramp-up times were established experimentally depending on the Data Size until the point when increasing them further did not bring significant changes.
Measurement window 900 sec (15 min)

Ideally it should be as long as possible, but measurements should take reasonable time. Hence, we used the experience of previous benchmarks and established that this window is adequate for the purpose.
Number of runs 3

For each combination there are multiple runs.
The interactive graph can show data for individual runs as well as averaged value.

Important Database Configuration options (the actual config files with specific settings for each run can be downloaded from the interactive graphs):

InnoDB – Buffer pool Tier
innodb_buffer_pool_size 2G/4G/8G/12G/24G/32G/48G/64G/128G
innodb_buffer_pool_load_at_startup OFF
innodb_buffer_pool_dump_at_shutdown OFF
Thread Pool
thread_handling pool-of-threads
thread_pool_size 80 # match physical core count
thread_pool_max_threads 2000
thread_pool_oversubscribe 3
Threading
thread_stack 512K
thread_cache_size 256
back_log 4096
InnoDB I/O
innodb_io_capacity 10000
innodb_io_capacity_max 20000
innodb_read_io_threads 16
innodb_write_io_threads 16
innodb_use_native_aio ON
InnoDB Log / Durability
innodb_log_buffer_size 256M
innodb_flush_log_at_trx_commit 1 # full ACID
innodb_doublewrite ON
InnoDB – Concurrency & OLTP Tuning
innodb_stats_on_metadata OFF
innodb_open_files 65536
innodb_lock_wait_timeout 50
innodb_rollback_on_timeout ON
Per-Session Buffers
sort_buffer_size     4M
join_buffer_size     4M
read_buffer_size     2M
read_rnd_buffer_size 4M
tmp_table_size       256M
max_heap_table_size 256M
Binary Log
disable_log_bin ON # Disabled binlog
Other InnoDB settings
innodb_redo_log_capacity     4G
innodb_change_buffering      none
innodb_flush_method          O_DIRECT
innodb_buffer_pool_instances Calculated as
(innodb_buffer_pool_size G / 5)
But must be in range [1..8]
Misc server settings
collation_server utf8mb4_unicode_ci
bulk_insert_buffer_size 256M
myisam_sort_buffer_size  128M
key_buffer_size          64M # MyISAM only, keep small for OLTP

In the high concurrency scenario when all CPU cores are working under maximum load the performance fluctuations might appear out of the ability of a specific CPU crystal to work at a specific sustainable maximum frequency. Intel Xeon Gold 6230 processors installed in the test servers have a base frequency of 2100 MHz and maximum turbo frequency of 3900 MHz. However, such turbo frequency can only be achieved for a short period of time on an isolated core. The load and the heat production of the physical core neighbours limit the frequency of the whole CPU. Some CPU’s were able to hold 2530 MHz on all cores for 20+ hours of intense load, others could only reach 2420 MHz. For consistency of the tests the turbo frequency was capped to 2400 MHz from the beginning on all servers. It helped to eliminate the struggle between turbo mode trying to increase the frequency beyond sustainable levels and the CPU thermal protection bringing the clock down. More stable hardware performance reduced the measurement fluctuations during the benchmark runs regardless if they were done on the same or a different physical server.


3. Results

First, let’s check the I/O bound scenario where the InnoDB Buffer to Data Size is the smallest (1:12).

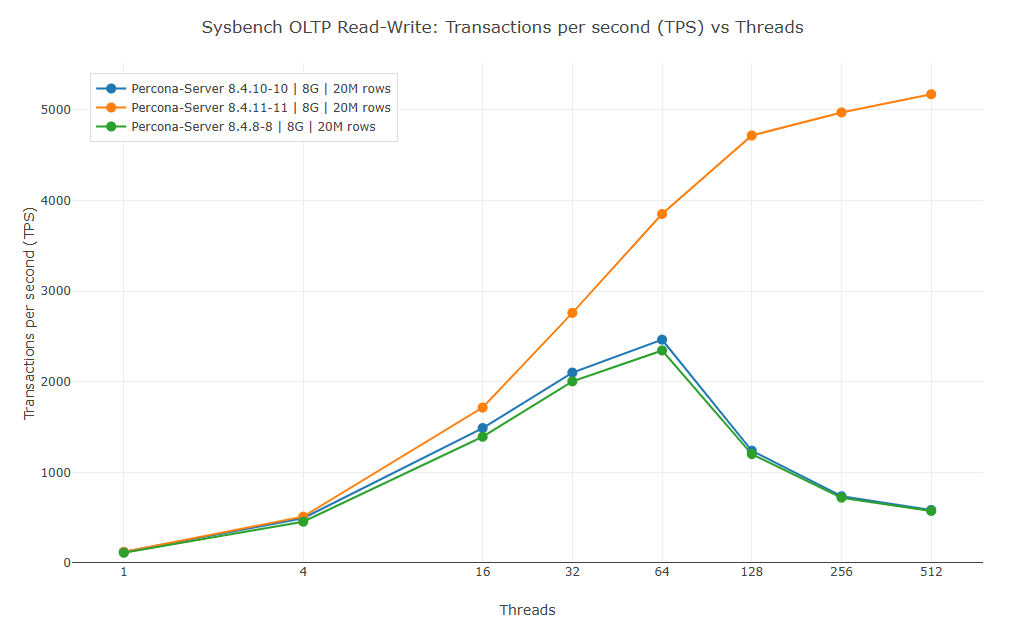
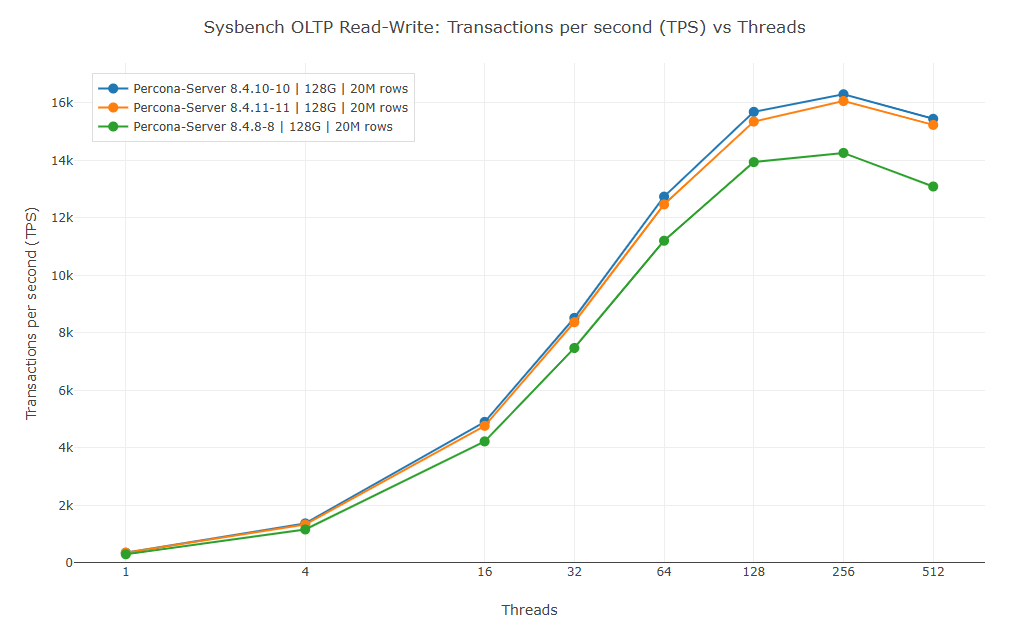
The graph shows the configurations with innodb_buffer_pool_size=8G and Data Size 96G (or 20M rows per table, 400M rows in total):


[ INTERACTIVE GRAPH ][ TABLE ]

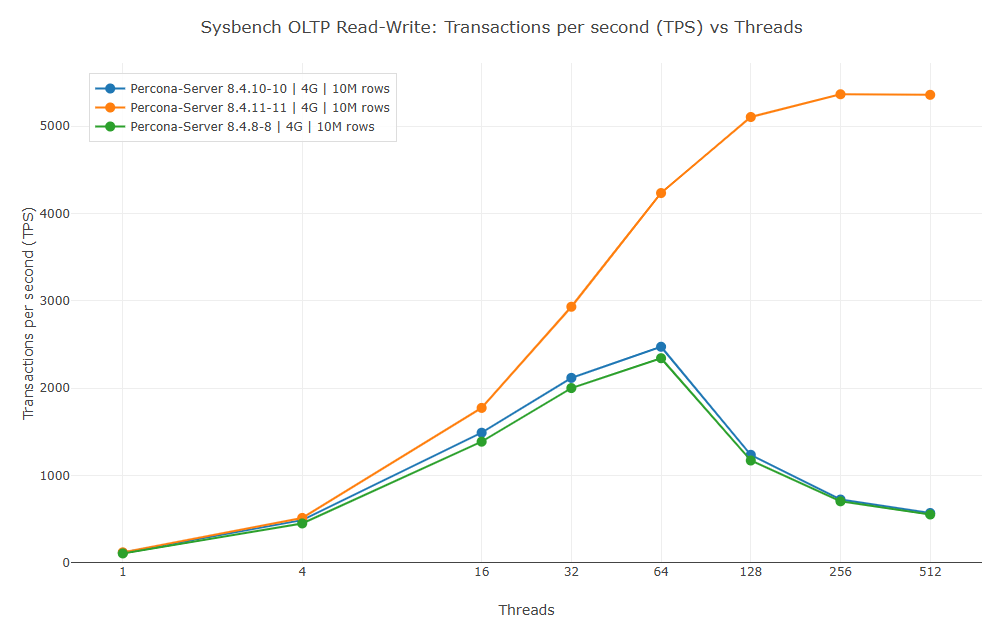
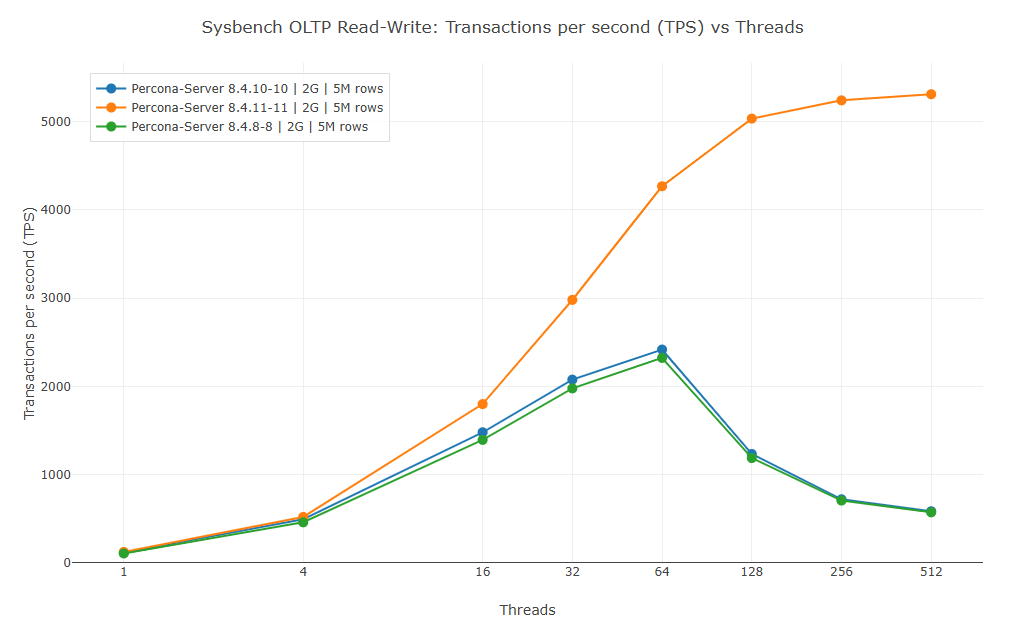
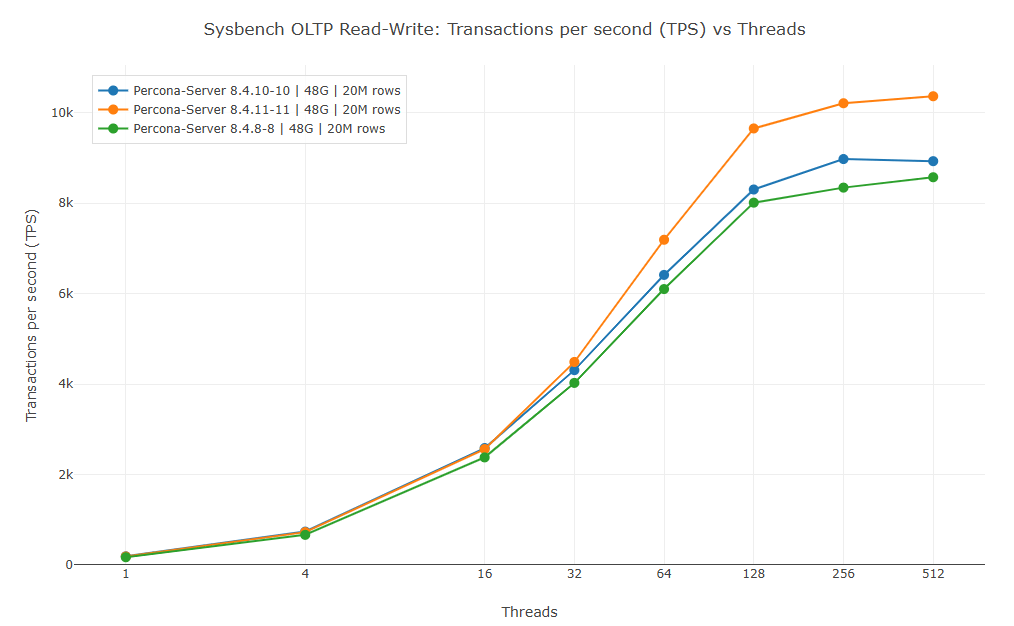
The first thing that catches the eye is the hugely superior performance of the version 8.4.11-11 over 8.4.10-10 and 8.4.8-8 in the high thread numbers. In the situations when the number of physical cores (80) is smaller than the number of threads (128+) the versions 8.4.10-10 and 8.4.8-8 have a steep performance degradation. However, the TPS for 8.4.11-11 keeps growing. This is due to the optimization done to InnoDB LRU pages flushing algorithm. The optimization specifically targeted the scenario when the data size is larger than the available server buffers and the server has many concurrent connections doing random read-write operations. The optimizations in 8.4.11-11 deserve a separate explanation and they will be published in another blog post.

The less noticeable, but important difference can be spotted between the TPS for 8.4.8-8 and 8.4.10-10.

The version 8.4.10-10 shows better performance (especially at the saturation point with 64 threads), which should mostly be attributed to the introduction of Performance Guided Optimization (PGO). 

More information on PGO can be found here:

https://docs.percona.com/percona-server/8.4/pgo.html

With the smaller data and buffer sizes the performance difference gives an almost identical picture:

4G buffer, 48G data [ INTERACTIVE GRAPH ][ TABLE ] 2G buffer, 24G data [ INTERACTIVE GRAPH ][ TABLE ]

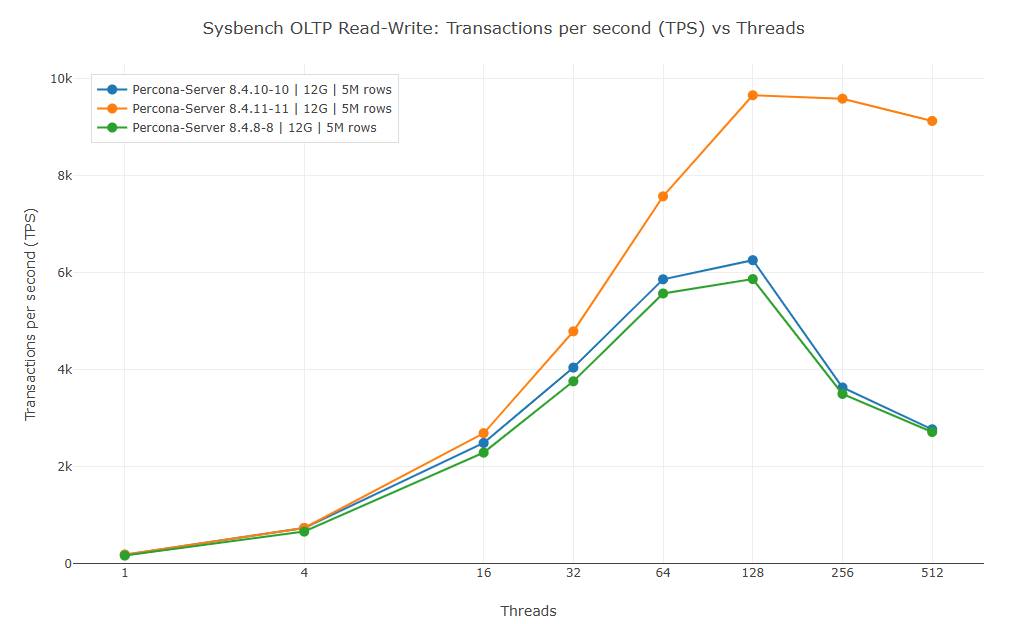
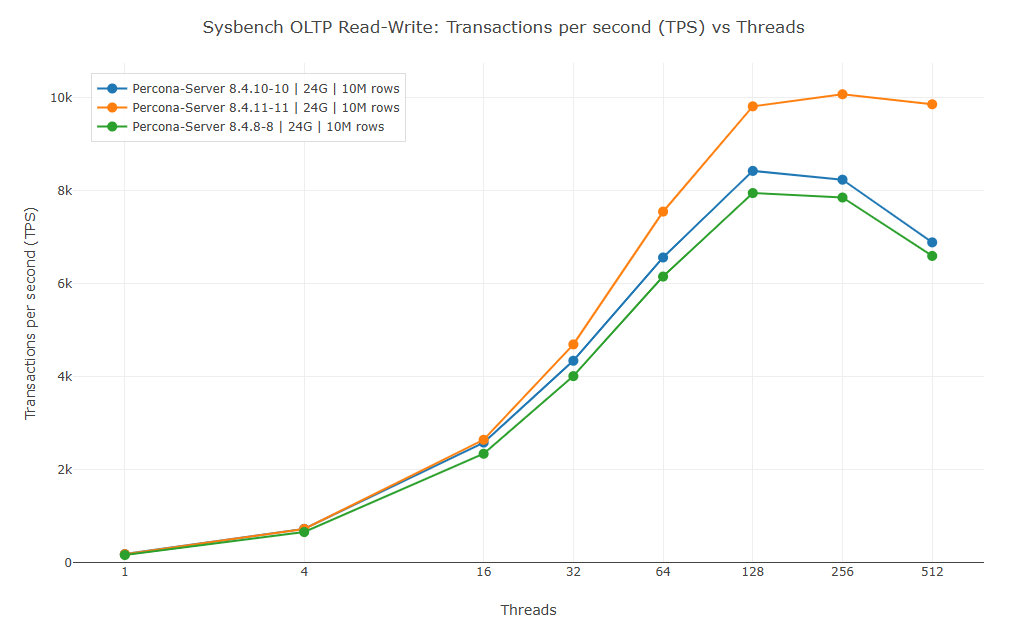
Now let’s review what happens with the ratio 1:2.
This time the buffer pool size also plays a more significant role and the performance difference is not characterized by the Buffer / Data size ratio.

With innodb_buffer_pool_size=12G and 24G data size the performance gap between 8.4.11-11 and older versions is still huge as can be seen on the graph:


[ INTERACTIVE GRAPH ][ TABLE ]

However, setting innodb_buffer_pool_size=24G and 48G data size reduces the gap. The superiority of 8.4.11-11 is still visible:


[ INTERACTIVE GRAPH ][ TABLE ]

Moving to innodb_buffer_pool_size=48G and 96G data size shrinks the gap even more:


[ INTERACTIVE GRAPH ][ TABLE ]

In this post we are not going to talk about mechanisms behind shrinking performance gaps in 1:2 Buffer / Data size ratio.

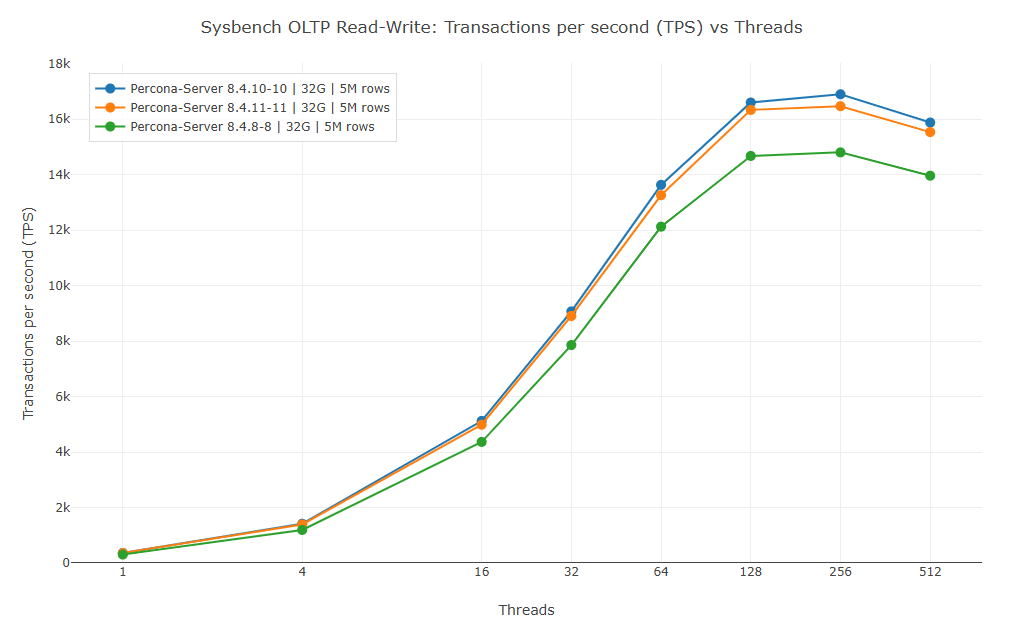
Holding the entire data set in memory is not the most common thing for the database server, but in some cases it happens. Therefore, we are covering such situations as well.


[ INTERACTIVE GRAPH ][ TABLE ]

As the above graph shows, 8.4.10-10 is slightly ahead of 8.4.11-11, but the gap is very small.

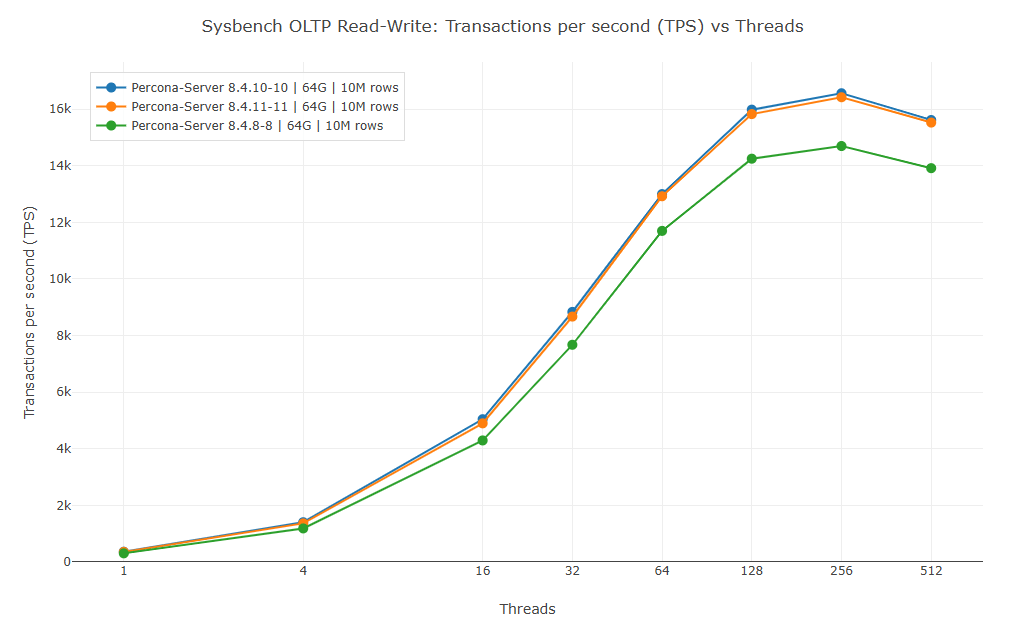
This behavior is consistent with other data sizes for fully buffered data:

innodb_buffer_pool_size=64G and 48G Data Size:


[ INTERACTIVE GRAPH ][ TABLE ]

innodb_buffer_pool_size=128G and 96G Data Size:


[ INTERACTIVE GRAPH ][ TABLE ]

Again, we will not go into details about why this happens. Though it is worth noting that both 8.4.10-10 and 8.4.11-11 do better than 8.4.8-8 in all runs and configurations.

The table interpretation of the results is available as well.


4. Comparing with Upstream MySQL 8.4.11.

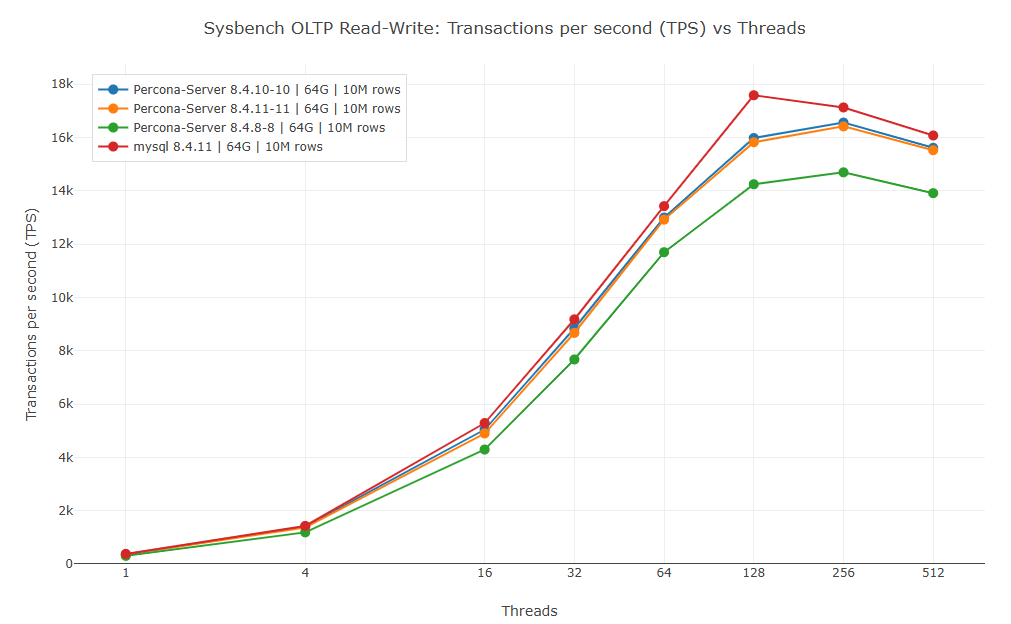
The performance improvements in Percona Server for MySQL 8.4.11-11 are not a part of the Upstream MySQL 8.4.11. The patch was specifically designed to address the issue of Percona Server being slower than MySQL in I/O bound scenarios.

Also, the patch eliminated the abrupt performance degradation in the higher thread count after reaching the saturation point at 64 threads:

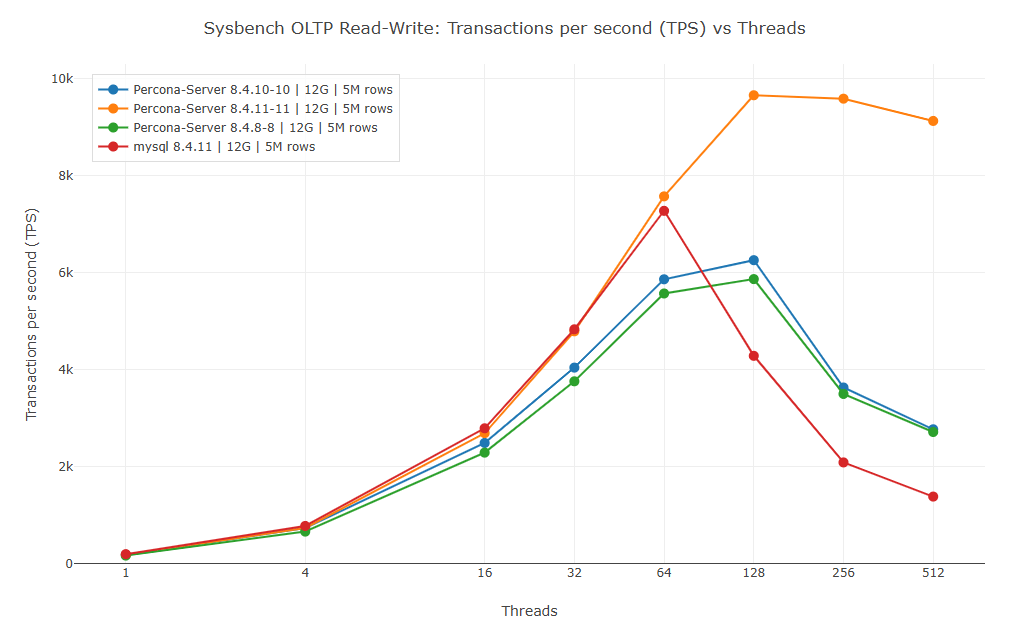
[ INTERACTIVE GRAPH ][ TABLE ]

As the graph shows – Percona Server 8.4.8-8 / 8.4.10-10 was slower than MySQL in lower thread count. Although it was still faster in 128+ threads, the Percona Server was still subject to a substantial slow-down. That is where Percona Server 8.4.11-11 really shines.

However, with the fully buffered data MySQL goes faster than any Percona Server:


[ INTERACTIVE GRAPH ][ TABLE ]

5. Summary

The Performance of the Percona Server 8.4 for MySQL is progressing well from older to newer version offering significant performance improvements especially in the version 8.4.11-11. This version shows very significant improvements in performance on the data sets that require I/O. Also, it outperformed the upstream MySQL 8.4.11.

With fully buffered data sets the version 8.4.10-10 is slightly better than 8.4.11-11. MySQL Server in this case shows the fastest performance.

The PGO had a positive impact demonstrating the version 8.4.10-10 being faster in all tests on all configurations than 8.4.8-8.

The performance depends not only on the ratio between the buffer and the data size, but also on the buffer size.

The post Performance Progression of Percona Server for MySQL 8.4 appeared first on Percona.
Aug
26
2026
--

Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in

These days there’s been a lot of talk about Postgres having an impact on “everything”. Whether it’s replacing legacy systems, creating a new greenfield project or even implementing it as a back-end to an agentic AI, Postgres is today’s poster child for innovation.

So performing something as dull and straightforward as a database migration should be easy, eh?

Well, not quite.

Its popular adoption and success has, in a sense, created a problem of its own making, which is otherwise known as the Walled Garden Effect.

The Walled Garden effect in open source is where software that is nominally open but a vendor, platform, or ecosystem has exerted control over its governance, distribution and compatibility in such a manner that its interaction with the same open source technology managed in another environment becomes problematic.

It’s an unfortunate reality that some commercial ecosystems built around Postgres can become walled gardens. Postgres itself remains open and portable, but its widespread adoption has also produced commercial ecosystems in which that portability can become progressively constrained.

At its most extreme; here are the risks of a Walled Garden to the Postgres end-user:

  • In the context of a Postgres offering from a cloud computing service offering DBaaS:
    • They “Control” the core platform, set the standards, and host the marketplace.
    • They “Acquire” developers, hardware manufacturers, and service providers who build products that add value to the core platform.
    • They “Convince” users to join the ecosystem whose data, attention, and capital eventually fuels the network’s growth.
    • The financial and cultural health of satellite vendors whose very existence is “Tied” directly to the decisions and policies made by the platform owner.
  • In the context of the technology used:
    • Modifying” the backend with unique attributes while enticing you with standard front-end protocols. A Postgres compatible interface does not necessarily imply Postgres equivalent portability. A service may emulate familiar SQL, drivers, and tools all the while introducing backend capabilities or operational dependencies that do not exist in community Postgres.
  • What it means over the life of your system:
    • As the ecosystem becomes more valuable to the user, it creates a greater “Disincentive” to exit.
    • If an exit strategy is undertaken:
      • High switching “Costs” can be incurred when migration introduces data-integrity risks and extraordinary complexity into what has become a tightly integrated workflow.
      • Extra “Expert” costs must be budgeted because specialized expertise may be required when vendor-specific features or dependencies exceed the experience of in-house staff.

        Working on past projects I’ve often found myself paraphrasing an old Eagles refrain “You can provision Postgres any time you like, but your architecture can never leave.

        While PostgreSQL itself is fully open-source and free, some vendors have created a Hotel California effect using these three specific mechanisms:

      • Proprietary Forks & Features: They offer “Postgres-compatible” databases. They add custom, closed-source performance layers or automated scaling. If you build your application to rely on these specific features, moving back to community Postgres can require a massive architecture rewrite.
      • Migration Cost Asymmetry: Moving data into an ecosystem can be relatively inexpensive. Moving that database to an alternate environment later can be considerably more complex.
      • Ecosystem Gravity: Databases do not sit in a vacuum. Once your Postgres instance is tightly integrated with a vendor’s proprietary backup systems, security roles (IAM), and serverless analytics tools, leaving the database can mean rebuilding your entire infrastructure. Postgres data can remain portable while the architecture surrounding it becomes progressively less portable.

        So what does it mean for you?

        While today’s database landscape can make vendor dependency seem unavoidable, it isn’t. There are still organizations that build commercial services around the principles that made open source successful in the first place: transparency, interoperability, portability, and the customer’s freedom to choose where and how their software runs. Percona is one example of a commercial model built around the premise that commercial expertise and open-source values do not have to be opposing ideas.

        Reference:
        https://arxiv.org/html/2409.01118v1 

The post Navigating the Walled Gardens of PostgreSQL: Hidden Risks of Postgres Vendor Lock-in appeared first on Percona.
Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com