Sep
29
2026
--

Valkey Memory Optimization, Version by Version and Encoding: How Many Bytes Did Each Release Actually Save?

Introduction

This RAM/Memory reduction is most useful for Valkey 9.1 environments that are key string heavy. They are used extensively in caching, sessions/authentication, real-time apps, ecomm, Ad tech/martech, and gaming.
These scenarios see a reduction of 37.5%, which has been attained in our testing environments versus version 7.2.. The biggest jump in the reduction came between 7.2 and 8.1 where the difference was 29.8%. Although the reduction doesn’t apply to every Valkey environment, those that are string heavy should experience 37.5% RAM reductions.

RAM usage scenario:

Starting point: 1 TB on Valkey 7.2

  • Valkey 7.2: 1,000 GB
  • Valkey 8.0: ~800 GB
  • Valkey 8.1: ~640 GB
  • Valkey 9.1: ~630 GB

This post is based on a rigorous benchmark and a structural teardown of the source, aimed at answering three questions:

    1. For the same data, how much memory does each version actually save?
    2. Where exactly does that saving come from at the data-structure level?
    3. How do different data structures and encoding result in significantly different memory footprints?


1. Test Setup: 

Five versions were tested — 7.2.14, 8.0.10, 8.1.9, 9.0.5, and 9.1.1 — all built from source, all using jemalloc 5.3.0 as the allocator, so version is the only variable.

Test Environment settings:

  • Standalone mode, not cluster, to rule out cluster-level overhead
  • –maxmemory 0, –save “” –appendonly no, to keep persistence and eviction out of the picture
  • valkey-benchmark -t set -n 1000000 -r 1000000 -d 16: one million SETs, 16-byte values
  • Both -n and -r are set to 1,000,000 on purpose — this causes random-key collisions, so only about 63.2% (~632K) land as unique keys. This matches the official Valkey benchmark methodology exactly
  • The baseline (empty instance) memory is subtracted for each version, giving the true marginal bytes per key


2. Results: Memory per Key, Version by Version

Version Unique Keys used_memory Bytes / Key vs Prev vs 7.2.14
7.2.14 632,181 61.78 MB 102.48 B — baseline
8.0.10 632,565 57.00 MB 94.49 B ?7.8% ?7.8%
8.1.9 632,573 43.43 MB 71.98 B ?23.8% ?29.8%
9.0.5 631,672 43.36 MB 71.99 B +0.0% ?29.8%
9.1.1 631,985 38.58 MB 64.02 B ?11.1% ?37.5%

We can see that across roughly 632K unique keys, the size of per key averages 102.48 bytes in version 7.2.14 down to 64.02 bytes in 9.1.1 — a cumulative drop of 37.5%. In other words, the same hardware stores roughly 60% more of these small keys on 9.1 than it did on 7.2. We can see 8.1 alone accounts for the single biggest jump, at -23.8%, because that’s where the hash table got rewritten. However 9.0 shows basically zero change, since that release simply wasn’t targeting memory.


3. Let us see how the change happens version by version.

7.2 ? 8.0: Embedding the Key into dictEntry
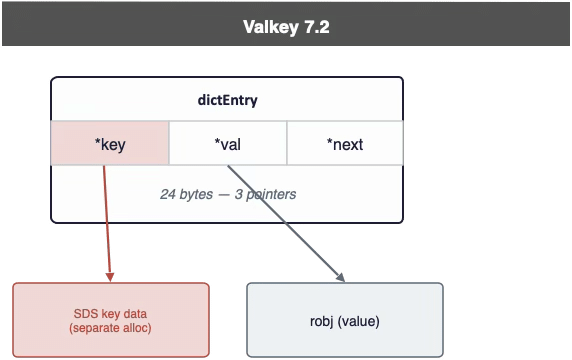
Valkey 7.2 dictEntry diagram: a 24-byte struct of three pointers (*key, *val, *next), with *key pointing to separately allocated SDS key data and *val pointing to the robj value


In 7.2, dictEntry is a classic three-pointer struct — *key, *val, *next — 24 bytes total. The catch is that the key itself is a pointer to a separately allocated SDS blob: every lookup pays for an extra malloc and an extra memory hop just to read the key.
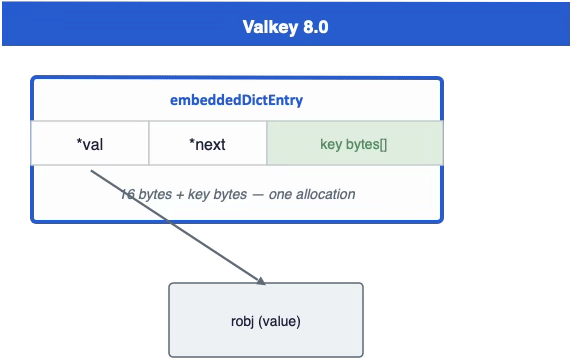
 

Valkey 8.0 embeddedDictEntry diagram: *val and *next pointers with the key bytes stored inline in one allocation (16 bytes plus key bytes), pointing to the robj value


8.0 introduces embeddedDictEntry: the key’s bytes are stored inline right after the struct. *val, *next, plus the inlined key data come to 16 bytes plus the key length — one allocation instead of two.

Result: ?8 bytes per key, one fewer memory hop on every lookup, automatic on upgrade, no config changes needed.

8.0 ? 8.1: A Cache-Line-Sized Hash Table

This is the single largest jump in the whole series. In 8.0, the dictionary is a classic chained hash table: reaching a value means “bucket ? entry ? key ? value” — four memory hops (plus two more per hash collision).
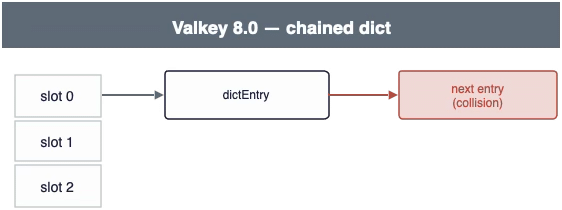
 

Valkey 8.0 chained dict diagram: hash table slots pointing to dictEntry structs, with collisions chained to the next entry


8.1 rewrites this as a new hashtable structure where one bucket is exactly 64 bytes — the size of a CPU cache line, — with the key and value embedded directly inside it.The bucket’s 8-byte metadata region packs a “has-child-bucket” bit, 7 filled-bits, and 7 bytes of secondary hash, letting most non-matching candidates be skipped without an extra memory access. Key and value are embedded in the same serverObject, shortening the path to roughly two hops — “bucket ? serverObject” — and a hash collision usually stays within the same cache line.

dictEntry as a struct disappears entirely. The result is roughly ?20 bytes per key-value pair (?30 bytes for keys with a TTL) — the single biggest jump in the entire 7.2?9.1 series.
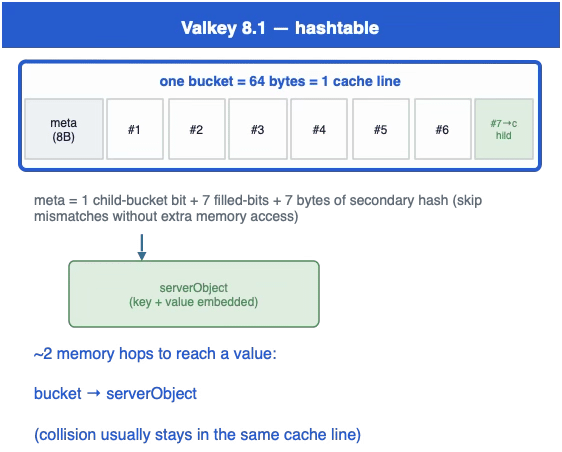
 

Valkey 8.1 hashtable diagram: one 64-byte cache-line bucket with an 8-byte metadata region and seven entry slots, pointing to a serverObject with the key and value embedded, about two memory hops per lookup

9.0 ? 9.1: Reusing the Pointer Field Itself
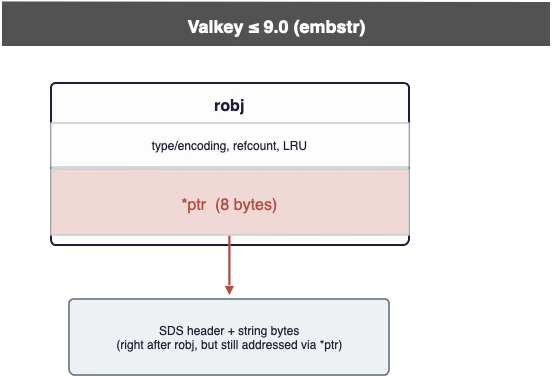
 

Valkey 9.0 and earlier embstr diagram: robj header (type/encoding, refcount, LRU) with an 8-byte *ptr field pointing to the SDS header and string bytes placed right after the robj

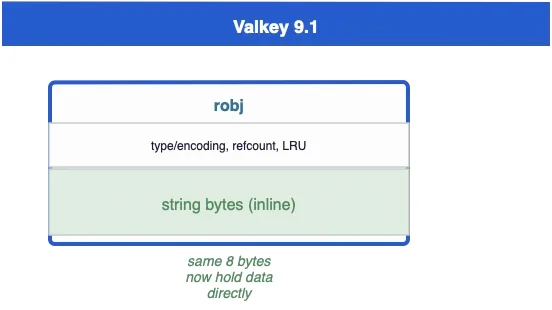
Valkey 9.1 robj diagram: the same 8 bytes previously used for *ptr now hold short string bytes inline, removing the pointer

In earlier versions, embedded strings (embstr) still wasted an 8-byte pointer field simply referencing the contiguous payload. 9.1’s fix: for short strings, the string bytes are stored directly inline in those same 8 bytes normally used for the pointer — no pointer needed, and no separate allocation for the value.

Result: up to a 20% memory reduction for strings under 128 bytes — and the benchmark’s “key + 16-byte value” pairs sit right in the middle of that range.

The three structural changes account for most of the improvement: 

8.0 inlined the key directly into dictEntry, eliminating a separate allocation and one memory hop (?8 bytes/key);    8.1 rewrote the dictionary into a 64-byte, cache-line-aligned hashtable that embeds both key and value, collapsing the lookup path from four hops to about two and removing dictEntry altogether (roughly ?20 to ?30 bytes per entry);   and 9.1 reused the embedded-string pointer field to store short string data inline instead of pointing to it, cutting up to 20% off strings under 128 bytes. 

Together, these changes show that Valkey’s memory efficiency gains came from targeted, low-level restructuring of core data structures rather than a single sweeping rewrite.


4. Same 1 Million Records, Two Encodings, 54% Less Memory

Two approaches to the same data:

  • Approach A: 4 separate String keys per user (SET user:1:name Alice, etc.)
  • Approach B: 1 Hash key per user, 4 fields (HSET user:1 name Alice age 30 city Toronto score 100)
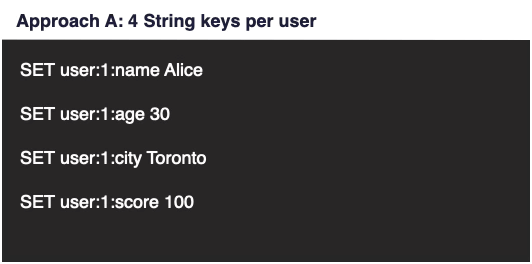
Approach A: four separate Valkey String keys per user using SET user:1:name Alice, SET user:1:age 30, SET user:1:city Toronto, SET user:1:score 100

Approach B: one Valkey Hash key per user using HSET user:1 name Alice age 30 city Toronto score 100


Same data, same record count. Approach A uses 220 MB; Approach B uses 100 MB — a 54% reduction. That gap comes from the fact that every key pays a fixed per-key overhead: four keys pay it four times, one key pays it once.

Beyond raw memory — where Hash wins because it shares per-key overhead, there’s per-field TTL, where String is native with EXPIRE per key, while Hash didn’t natively support field-level TTL before 7.4. 

For atomic multi-field operations, Hash wins with a single HSET or HMGET, while String needs multiple round trips. 

For cluster slot locality, String needs a manual {hashtag} to co-locate related keys, while a Hash is automatically one key, one slot. 

So there’s no universally correct choice — it’s memory versus flexibility, and it interacts with your cluster routing strategy too.
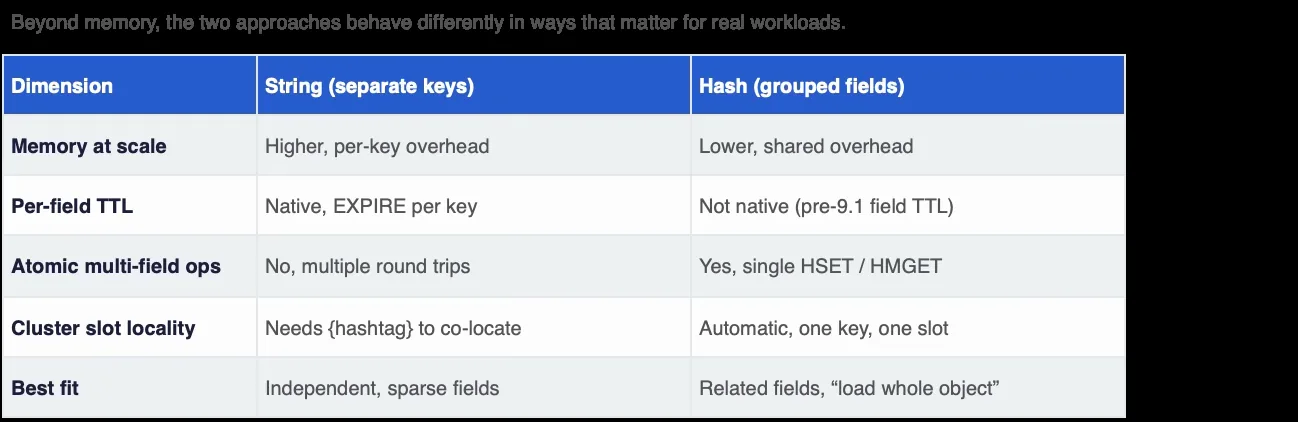
 

Comparison table of Valkey String (separate keys) versus Hash (grouped fields) across memory at scale, per-field TTL, atomic multi-field operations, cluster slot locality and best fit

Summary

Testing five Valkey versions (7.2.14 through 9.1.1) under identical conditions, per-key memory for a simple SET workload dropped from 102.48 bytes to 64.02 bytes — a cumulative 37.5% reduction, with 8.1 alone responsible for the largest single jump (?23.8%) and 9.0 showing essentially no change. Three targeted structural rewrites drove this: 8.0 inlined the key into dictEntry, removing a separate allocation (?8 bytes/key); 8.1 replaced the chained hash table with a 64-byte, cache-line-aligned hashtable that embeds key and value together, cutting the lookup path from four hops to two and eliminating dictEntry entirely (?20 to ?30 bytes/entry); and 9.1 reused the embedded-string pointer field to store short string data inline, saving up to 20% for strings under 128 bytes. Separately, how the same data is modeled also matters as much as the version: storing a user’s data as 4 individual String keys costs 220 MB, versus 100 MB for the same fields grouped into a single Hash — a 54% saving driven by paying the fixed per-key overhead once instead of four times. That memory advantage comes with trade-offs, though: Hash lags String on native per-field TTL support (pre-7.4) but wins on atomic multi-field operations and automatic cluster slot locality, so the right choice depends on whether memory efficiency or per-field flexibility matters more for the use case.


The post Valkey Memory Optimization, Version by Version and Encoding: How Many Bytes Did Each Release Actually Save? appeared first on Percona.
May
19
2026
--

Manually Migrate Hash Slots in a Valkey/Redis Cluster

This article explains how to manually migrate hash slots in Valkey/Redis clusters to expand your deployment with minimal disruption to availability.

Note: Valkey 9.0 introduces the Atomic Slot Migration (ASM) feature, which significantly improves migration speed (up to 9.52 times faster) and reliability, while reducing migration complexity. So you should use ASM instead if you are using Valkey version 9.0 and later. You can read more about ASM in the Valkey’s community blog.

Refresher on hash slots

Valkey and Redis clusters partition their keyspace into 16,384 hash slots. Each key is assigned to a slot based on the CRC16 hash of its name (or hashtag), ensuring consistent and deterministic routing across cluster nodes:

CRC16(<key>) % 16384

So, for example, the command SET hello world will store the key hello in slot 866.

Accessing keys in different slots

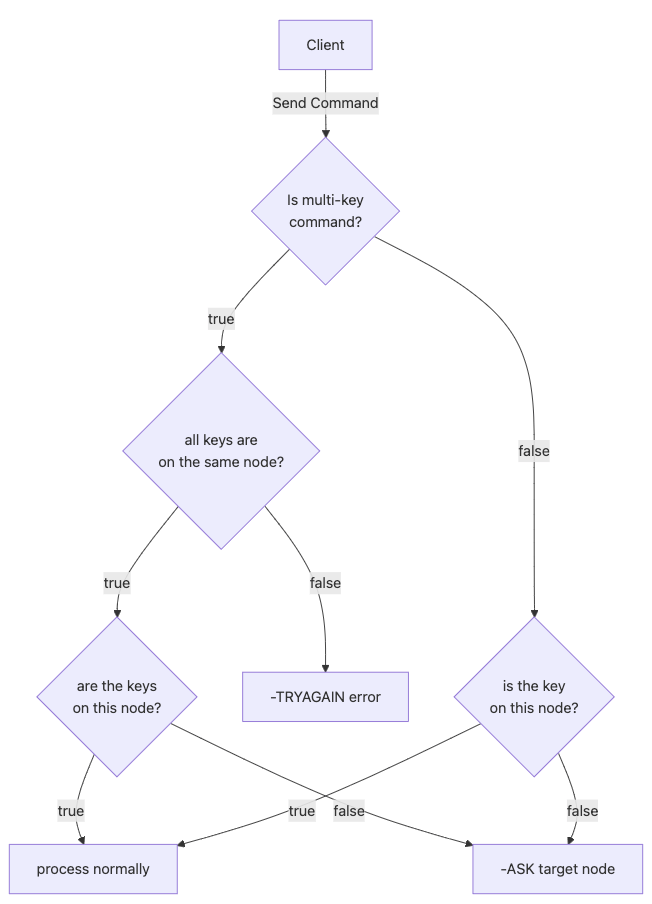
Because hash slots in Valkey/Redis can be located on different processes, if you access multiple slots in a single command, the cluster would have to coordinate between nodes. This can impact cluster performance and data consistency, as nodes can fail while processing a command. So, to keep things simple and fast, Valkey/Redis will disallow accessing keys that hash to different slots.

You can read more about distributing data in Valkey/Redis cluster in my colleague Agustin’s blog post.

Why do you need to migrate hash slots?

As your dataset grows, your Valkey/Redis cluster may not have enough memory to hold all the data; or the resource utilization between nodes is not evenly distributed. To address these issues, you might need to add more nodes to the cluster, or move the hash slots around so that data doesn’t get evicted, and no nodes are under/overutilized.

How the slot migration process works

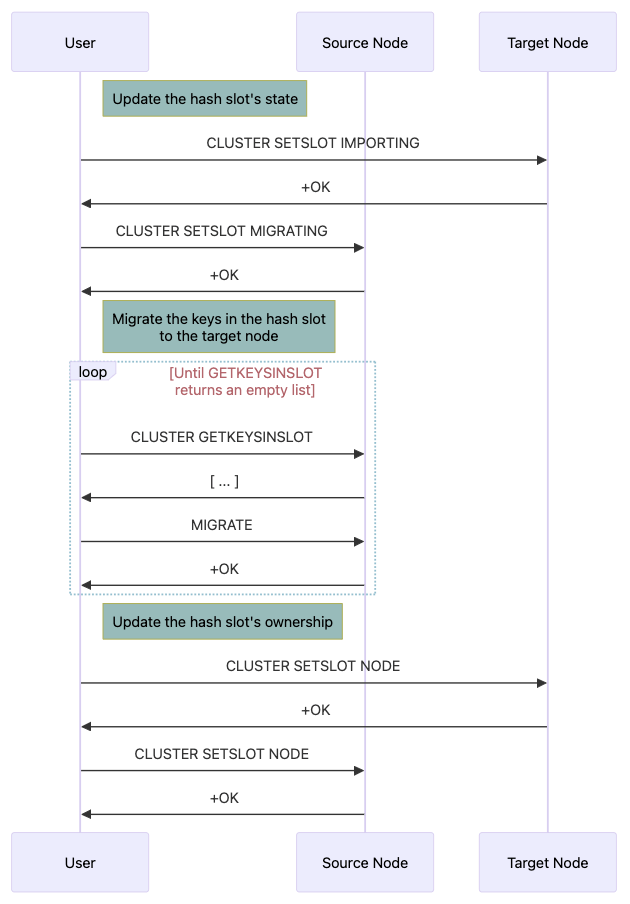
The slot migration process can be roughly divided into 3 steps:

1. Update the hash slot’s state so that clients can know where to get the keys during the migration stage:

CLUSTER SETSLOT <slot> IMPORTING <source ID>
CLUSTER SETSLOT <slot> MIGRATING <target ID>

2. MIGRATE the keys in the hash slot to the new owner:

CLUSTER GETKEYSINSLOT <slot> <number of keys to return>
MIGRATE <target host> <target port> "" 0 5000 KEYS <key1> <key2> ... <keyN>

3. Update the hash slot’s metadata to reflect the new ownership:

CLUSTER SETSLOT <slot> NODE <target ID>

What happens when the hash slot is accessed during migration

During hash slot migration, if a command accesses keys stored in the migrating slot, the instance will first check its local hash table. If the keys are not found locally, the client will receive an ASK redirection to the target node. Unlike MOVED (which also tells the client to retry requests at another node), an ASK redirection is meant to be temporary; it will not update the client’s slot cache and affects only a single request. So, when you re-run the same request, even if you are on the correct node, you will still get redirected:

127.0.0.1:30002> GET 123
-> Redirected to slot [5970] located at 127.0.0.1:30001
"123"

127.0.0.1:30001> GET 123
-> Redirected to slot [5970] located at 127.0.0.1:30002
-> Redirected to slot [5970] located at 127.0.0.1:30001
"123"

Commands executed during migration may fail if they access keys that are distributed across different nodes. In this case, the command will encounter the same limitation as a CROSSSLOT error, because all keys involved in the operation must reside on the same instance:

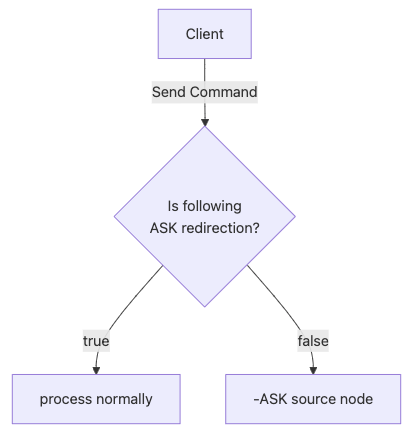
If the target node is the one receiving commands, the flow is much easier. It just checks if you are following an ASK redirection. If so, the command will be processed normally. If not, then the node will respond with -ASK and direct you to the original owner:

So, during the slot migration, your request will be redirected at most twice, first to the source node (since it is still registered as the owner of the hash slot), then to the target node if the keys are not found on the source:

# connect to the target node, and GET a non-existent key
valkey-cli -c -p 30001
127.0.0.1:30001> GET {123}1
-> Redirected to slot [5970] located at 127.0.0.1:30002
-> Redirected to slot [5970] located at 127.0.0.1:30001
(nil)

Why using valkey-cli --cluster rebalance won’t work for all cases

Depending on your application’s key pattern, the number of keys each slot holds can vary, and a slot might have a disproportionate number of keys (the hot-slot problem). And, the --cluster rebalance command only attempts to evenly distribute the number of slots each node has:

/* Calculate the slots balance for each node. It's the number of
     * slots the node should lose (if positive) or gain (if negative)
     * in order to be balanced. */
    int threshold_reached = 0, total_balance = 0;
    float threshold = config.cluster_manager_command.threshold;
    i = 0;
    listRewind(involved, &li);
    while ((ln = listNext(&li)) != NULL) {
        clusterManagerNode *n = ln->value;
        weightedNodes[i++] = n;
        int expected = (int)(((float)CLUSTER_MANAGER_SLOTS / total_weight) * n->weight);
        n->balance = n->slots_count - expected;
        total_balance += n->balance;
        /* Compute the percentage of difference between the
         * expected number of slots and the real one, to see
         * if it's over the threshold specified by the user. */
        int over_threshold = 0;
        if (threshold > 0) {
            if (n->slots_count > 0) {
                float err_perc = fabs((100 - (100.0 * expected / n->slots_count)));
                if (err_perc > threshold) over_threshold = 1;
            } else if (expected > 1) {
                over_threshold = 1;
            }
        }
        if (over_threshold) threshold_reached = 1;
    }

So, using --cluster rebalance could migrate all hot slots to the same node, further exacerbating the issue.

How to manually migrate a hash slot to a different node

1. Gather usage statistics on the slot

To find the list of big hash slots, we can use CLUSTER SLOT-STATS, which provides details for each slot (number of keys, CPU time, and network I/O).

Note: to display stats other than key-count, the config cluster-slot-stats-enabled needs to be set. The config can be modified during runtime, but remember to set it for all nodes in the cluster:

127.0.0.1:30001> CONFIG SET cluster-slot-stats-enabled yes
OK

127.0.0.1:30001> CLUSTER SLOT-STATS ORDERBY KEY-COUNT
1) 1) (integer) 12426
2) 1# "key-count" => (integer) 45
2# "cpu-usec" => (integer) 0
3# "network-bytes-in" => (integer) 0
4# "network-bytes-out" => (integer) 0
2) 1) (integer) 13902
2) 1# "key-count" => (integer) 20
2# "cpu-usec" => (integer) 0
3# "network-bytes-in" => (integer) 0
4# "network-bytes-out" => (integer) 0
3) ...

To find which node the hash slot belongs to, we can use the CLUSTER SLOTS command. In the example below, node 127.0.0.1:30001 holds slots 0-5460, 127.0.0.1:30003 holds slots 10923-16383:

127.0.0.1:30001> CLUSTER SLOTS
1) 1) (integer) 0
2) (integer) 5460
3) 1) "127.0.0.1"
2) (integer) 30001
3) "09dbe9720cda62f7865eabc5fd8857c5d2678366"
4) 1) hostname
2) "host-1.valkey.example.com"
3) availability-zone
4) "zone-a"
4) 1) "127.0.0.1"
2) (integer) 30004
3) "821d8ca00d7ccf931ed3ffc7e3db0599d2271abf"
4) 1) hostname
2) "host-2.valkey.example.com"
3) availability-zone
4) "zone-a"
2) 1) (integer) 10923
2) (integer) 16383
3) 1) "127.0.0.1"
2) (integer) 30003
3) "044ec91f325b7595e76dbcb18cc688b6a5b434a1"
4) 1) hostname
2) "host-5.valkey.example.com"
3) availability-zone
4) "zone-a"
4) 1) "127.0.0.1"
2) (integer) 30006
3) "58e6e48d41228013e5d9c1c37c5060693925e97e"
4) 1) hostname
2) "host-6.valkey.example.com"
3) availability-zone
4) "zone-a"
3) ...

To find the nodes’ IDs, use the CLUSTER NODES command. The ID of each node is shown in the first column:

127.0.0.1:30001> CLUSTER NODES
b1bb71c7d39d2c061ce3fc010b444cc20cbfb7b8 127.0.0.1:30001@40001 myself,master - 0 0 1 connected 0-5460
b32b8042b9280c6a5d266fcaf68c90f5167f8463 127.0.0.1:30002@40002 master - 0 1777009844302 2 connected 5461-10922
a4fc0747229514c300777d219fa80f90a0e656a2 127.0.0.1:30003@40003 master - 0 1777009844000 3 connected 10923-16383
4eeb33e93843559c51ec57a676e4e9d6a7489d5d 127.0.0.1:30004@40004 slave b32b8042b9280c6a5d266fcaf68c90f5167f8463 0 1777009844097 2 connected
f2acd5e5b73862c987b4c437919c4b1d3f7620c4 127.0.0.1:30005@40005 slave a4fc0747229514c300777d219fa80f90a0e656a2 0 1777009844202 3 connected
8889e25bc107d09d255c4f932c652e5d77ab1948 127.0.0.1:30006@40006 slave b1bb71c7d39d2c061ce3fc010b444cc20cbfb7b8 0 1777009843687 1 connected

2. Update slot metadata (MIGRATING status)

After collecting statistics for each hash slot, we should have a clear understanding of the data size and usage patterns for each slot. Based on this information, we can decide which underutilized node a slot should be migrated to. This helps ensure that resource utilization is evenly balanced across all nodes in the cluster.

On the target node, execute CLUSTER SETSLOT <SLOT> IMPORTING <SOURCE-NODE-ID>

valkey-cli -p 30001 -c CLUSTER SETSLOT 5970 IMPORTING b32b8042b9280c6a5d266fcaf68c90f5167f8463
OK

On the source node, execute CLUSTER SETSLOT <SLOT> MIGRATING <TARGET-NODE-ID>

valkey-cli -p 30002 -c CLUSTER SETSLOT 5970 MIGRATING b1bb71c7d39d2c061ce3fc010b444cc20cbfb7b8
OK

When set correctly, commands that create new keys in the hash slot will be directed to the target node:

127.0.0.1:30002> SET 123 hello
-> Redirected to slot [5970] located at 127.0.0.1:30001
OK

Note: remember to double-check the node IDs used in the commands. Currently, Valkey/Redis does not check if the node ID provided is the actual owner of the hash slot, so the (wrong) commands like below will still be able to execute successfully:

# set the hash slot 5970 as IMPORTING from myself
valkey-cli -p 30001 -c CLUSTER SETSLOT 5970 IMPORTING "$(valkey-cli -p 30001 -c CLUSTER MYID)"
OK

# set the hash slot 5970 as MIGRATING to myself
valkey-cli -p 30002 -c CLUSTER SETSLOT 5970 MIGRATING "$(valkey-cli -p 30002 -c CLUSTER MYID)"
OK

So, when a new key is created (or a migrated key is updated), the request still goes to the original owner, instead of the target node:

127.0.0.1:30002> SET 123 hello
OK

And if you attempt to migrate a duplicated key, you will get the following error:

127.0.0.1:30002> MIGRATE 127.0.0.1 30001 123 0 5000
(error) ERR Target instance replied with error: BUSYKEY Target key name already exists.

Since valkey-cli --cluster check will still report the correct status, debugging this issue will be pretty confusing:

valkey-cli --cluster check 127.0.0.1:30001
127.0.0.1:30001 (ed38d440...) -> 1 keys | 5461 slots | 1 replicas.
127.0.0.1:30002 (654a8caa...) -> 1 keys | 5462 slots | 1 replicas.
127.0.0.1:30003 (e0ed692b...) -> 0 keys | 5461 slots | 1 replicas.
[OK] 2 keys in 3 primaries.
0.00 keys per slot on average.
>>> Performing Cluster Check (using node 127.0.0.1:30001)
M: ed38d44008b75d1b04f9670672e117d5764da51c 127.0.0.1:30001
slots:[0-5460] (5461 slots) master
1 additional replica(s)
S: 00fa8982389641fb2b73b416f08fafb18d9cc404 127.0.0.1:30006
slots: (0 slots) slave
replicates e0ed692bdf8f203322077dfeefb4d72f3ae121d2
S: fa4c2f539e74c18fe3aba7e8cdae7a01b91dd782 127.0.0.1:30004
slots: (0 slots) slave
replicates ed38d44008b75d1b04f9670672e117d5764da51c
M: 654a8caa0b5f53cd02698cf46ef9a102d0277ead 127.0.0.1:30002
slots:[5461-10922] (5462 slots) master
1 additional replica(s)
M: e0ed692bdf8f203322077dfeefb4d72f3ae121d2 127.0.0.1:30003
slots:[10923-16383] (5461 slots) master
1 additional replica(s)
S: 2063030dab7cce9dcc248031f53e6224b7c727c3 127.0.0.1:30005
slots: (0 slots) slave
replicates 654a8caa0b5f53cd02698cf46ef9a102d0277ead
[OK] All nodes agree about slots configuration.
>>> Check for open slots...
[WARNING] Node 127.0.0.1:30001 has slots in importing state 5970.
[WARNING] Node 127.0.0.1:30004 has slots in importing state 5970.
[WARNING] Node 127.0.0.1:30002 has slots in migrating state 5970.
[WARNING] Node 127.0.0.1:30005 has slots in migrating state 5970.
[WARNING] The following slots are open: 5970.
>>> Check slots coverage...
[OK] All 16384 slots covered.

I have created a Pull Request to the Valkey project, disallowing the command CLUSTER SETSLOT MIGRATING/IMPORTING to point to itself, so future versions of Valkey should not encounter this issue.

3. Migrate keys in the slot

After updating the slots’ state, we need to perform the actual data migration in those slots. We need to get the list of keys in the migrating slot using CLUSTER GETKEYSINSLOT, then execute the MIGRATE command on the found keys.

The script below will get and migrate the keys in DB 0 in slot 5970 from node 127.0.0.1:30002 to 127.0.0.1:30001 in a batch of 10 keys, with the timeout for each MIGRATE command being 5000 milliseconds:

keys="$(valkey-cli -p 30002 -c CLUSTER GETKEYSINSLOT 5970 10)"
while [[ "${keys}" != "" ]]
do 
    valkey-cli -p 30002 -c MIGRATE 127.0.0.1 30001 "" 0 5000 KEYS $keys
    keys="$(valkey-cli -p 30002 -c CLUSTER GETKEYSINSLOT 5970 10)"
done
OK
OK
OK
...

The migration is finished when CLUSTER GETKEYSINSLOT returns an empty array:

valkey-cli -p 30002 -c CLUSTER GETKEYSINSLOT 5970 10
(empty array)

4. Update slot ownership

After the keys migration is completed, update the slot’s metadata on the original and new node using CLUSTER SETSLOT <SLOT> NODE <TARGET-NODE-ID> to reflect the new ownership:

valkey-cli -p 30001 -c CLUSTER SETSLOT 5970 NODE b1bb71c7d39d2c061ce3fc010b444cc20cbfb7b8
OK

valkey-cli -p 30002 -c CLUSTER SETSLOT 5970 NODE b1bb71c7d39d2c061ce3fc010b444cc20cbfb7b8
OK

It will take a little while for the cluster to agree on the new slot distribution, as the metadata is propagated via the gossip protocol.

5. Validate the cluster’s state

Validate the cluster’s hash slots distribution with valkey-cli –cluster check to ensure that all slots are covered:

valkey-cli --cluster check 127.0.0.1:30001&nbsp;
127.0.0.1:30001 (b1bb71c7...) -> 1000 keys | 5462 slots | 1 replicas.
127.0.0.1:30002 (b32b8042...) -> 0 keys | 5461 slots | 1 replicas.
127.0.0.1:30003 (a4fc0747...) -> 0 keys | 5461 slots | 1 replicas.
[OK] 1000 keys in 3 primaries.
0.06 keys per slot on average.
>>> Performing Cluster Check (using node 127.0.0.1:30001)
M: b1bb71c7d39d2c061ce3fc010b444cc20cbfb7b8 127.0.0.1:30001
slots:[0-5460],[5970] (5462 slots) master
1 additional replica(s)
M: b32b8042b9280c6a5d266fcaf68c90f5167f8463 127.0.0.1:30002
slots:[5461-6917],[6919-10922] (5461 slots) master
1 additional replica(s)
M: a4fc0747229514c300777d219fa80f90a0e656a2 127.0.0.1:30003
slots:[10923-16383] (5461 slots) master
1 additional replica(s)
S: 4eeb33e93843559c51ec57a676e4e9d6a7489d5d 127.0.0.1:30004
slots: (0 slots) slave
replicates b32b8042b9280c6a5d266fcaf68c90f5167f8463
S: f2acd5e5b73862c987b4c437919c4b1d3f7620c4 127.0.0.1:30005
slots: (0 slots) slave
replicates a4fc0747229514c300777d219fa80f90a0e656a2
S: 8889e25bc107d09d255c4f932c652e5d77ab1948 127.0.0.1:30006
slots: (0 slots) slave
replicates b1bb71c7d39d2c061ce3fc010b444cc20cbfb7b8
[OK] All nodes agree about slots configuration.
>>> Check for open slots...
>>> Check slots coverage...
[OK] All 16384 slots covered.

We can see that the migration is successful, with all 16384 hash slots covered, and the slot distribution is reported correctly, with node 127.0.0.1:30001 having 1 more slot than the rest.

Conclusion

In this article, we learned how to perform manual hash slot migration to balance/expand a Valkey/Redis cluster. And while manual hash slot migration is a necessary process to resolve hot-slot issues that automated rebalancing cannot, users on Valkey 9.0 and later should leverage the faster, more reliable Atomic Slot Migration (ASM) feature.

The post Manually Migrate Hash Slots in a Valkey/Redis Cluster appeared first on Percona.

Apr
30
2026
--

Managing Valkey Cluster in Kubernetes

Over the last several years, Percona has introduced several rock-star Kubernetes Operators for managing MySQL, Percona XtraDB Cluster, MongoDB, and PostgreSQL. For Valkey, we are actively working with the community to contribute our knowledge, and experience to help brainstorm, develop, and test the official Valkey Operator for Kubernetes.

While the Valkey Operator has not yet released a GA 1.0 version, we wanted to take this opportunity to highlight some recently added features.

Cluster Configuration

Up until recently, there was no native ability to provide configuration parameters to the Valkey server process running inside each deployed pod. This hurdle is now overcome, and you can supply configuration natively within the deployment CR.

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-valkey-cluster1
spec:
  shards: 3
  replicas: 1
  config:
    maxmemory: 500mb
    maxmemory-policy: allkeys-lfu
    maxclients: 5000
    commandlog-execution-slower-than: 10000

For now, these parameters are set on initial cluster deployment. There is already traction underway to allow certain parameters to be dynamically set at runtime. There are a small handful of certain cluster-based parameters that cannot be overridden by the user, otherwise it would break operator functionality.

User Access Control List (ACL)

Managing users is always a tedious task for any database administrator. Creating ACLs for users in Valkey can be a bit confusing coming from a traditional RDBMS using GRANT syntax. To make things just a bit easier, Valkey Operator has added user permissions management to the deployment CR.

Firstly, create your Secret containing usernames, and passwords:

apiVersion: v1
kind: Secret
metadata:
  name: valkey-cluster-sample-users
data:
  alicepw: M21wdHlQQHNzdzByZA==
  davidold: OVYqTHQlYXU4Mk5tdTlyeQ==
  davidnew: VmFsa2V5I1J1bHojMjIzMw==

Next, deploy your cluster with users:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: my-cool-valkey-cluster
spec:
  shards: 3
  replicas: 1
  users:
    - name: alice
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys: [alicepw]
      commands:
        allow: ["@read", "@write", "@connection"]
        deny: ["@admin", "@dangerous"]
      keys:
        readWrite: ["app:*", "cache:*"]
        readOnly: ["shared:*", "config:*"]
        writeOnly: ["logs:*", "metrics:*"]
    - name: david
      enabled: true
      passwordSecret:
        name: valkey-cluster-sample-users
        keys:
          - davidold
          - davidnew
      commands:
        allow: ["@admin"]

There’s quite a lot going on here. Let’s break it down by first looking at the user ‘alice’: 

The ‘alice’ user is enabled, with a password found in the referenced Secret and secret key. Next, we can see what commands, or in this case, command groups (Noted with ‘@’) that alice is allowed to execute, and which commands/groups are denied. Lastly, permissions on specific key patterns are identified for maximum security restrictions.

The other user, ‘david’, can access all of the admin-group commands, and cannot read or write to any keys. Note that david’s secret key reference is an array, which means you can provide multiple passwords per user; great for password rotation! Once david confirms the new password, the old password references can be removed from the CR and Secret, and the Valkey Operator will synchronize the ACLs.

Users are dynamic, which means they can be added, removed, and modified without restarting the cluster.

TLS Support

Bring on the encryption! TLS support was also recently added to the Valkey Operator. Create your Secret with the CA, TLS Key, and Cert files, and tell the CR where to find them:

apiVersion: valkey.io/v1alpha1
kind: ValkeyCluster
metadata:
  name: cluster-sample
spec:
  shards: 3
  replicas: 1
  tls:
    certificate:
      secretName: my-valkey-tls-secret

Once deployed, the Valkey operator will mount the referenced secret to each pod, and add all the proper configuration parameters. By doing so, the operator enforces SSL/TLS communication between each Valkey cluster node, securing node-to-node, and replication traffic within your kubernetes network. Additionally, by creating user certificates signed by the same CA, traffic between your clients, and the Valkey clusters nodes is secured. This configuration is BYOC (bring-your-own-certificate), which works well with the popular CertManager, or other certificate authority you may be using.

On The Horizon

As a teaser, here are a couple other features coming soon to Valkey Operator:

  • Data Persistence: The ability to enable background snapshots of the in-memory dataset for backup, and recovery. Additionally, supporting the AOF (append-only file) for streaming changes.
  • Simple Replication: The operator currently only supports Valkey in cluster mode. Be on the lookout for traditional primary -> N-replica configurations, along with Sentinel monitoring.

Join Us

Want to contribute to the Valkey Operator? Join any of the discussions/issues on our github, or come introduce yourself in the Valkey Slack community.

The post Managing Valkey Cluster in Kubernetes appeared first on Percona.

Apr
23
2026
--

Achieving High Availability with Valkey Sentinel

In the previous guide, a robust Primary-Replica topology for Valkey was established. Read scaling is now active, and a hot copy of the data is securely stored on a second node.

But there is a catch. If a primary node crashes, the replica will remain faithful and wait for instructions. It will not automatically take over the responsibilities of the primary. Applications will start throwing write errors until an administrator manually logs in and reconfigures the replica to become the new primary.

To achieve true High Availability (HA) and ensure continuous uptime without manual intervention, Valkey Sentinel is required.

What is Valkey Sentinel?

Valkey Sentinel is a distributed system designed to monitor Valkey instances, detect failures, and automatically handle failover.

When Sentinel detects that a primary node is unresponsive, it performs the following tasks:

  1. Monitoring: It continuously checks whether primary and replica nodes are functioning as expected.
  2. Notification: It can notify system administrators or another computer program via an API that something is wrong.
  3. Automatic Failover: It promotes a healthy replica to the new primary and reconfigures the other replicas to sync with it.
  4. Configuration Provider: It acts as a source of truth for clients. Applications can connect to Sentinel to ask for the current primary’s address. If a failover occurs, Sentinel reports the new address.

The Rule of Three (Quorum)

Sentinel is a distributed system, meaning multiple Sentinel processes must run and agree on a node’s failure before taking action. This agreement is called a quorum.

To prevent a “split-brain” scenario (where a network partition causes two nodes to both assume they are the primary), at least three Sentinel instances must be deployed.

For this guide, the environment consists of three dedicated database nodes. Each node will run both the Valkey database service and the Valkey Sentinel service:

  • ArunValkeyPrimary (Primary + Sentinel): 172.31.32.27
  • ArunValkeyReplica (Replica 1 + Sentinel): 172.31.37.55
  • ArunValkeyReplica2 (Replica 2 + Sentinel): 172.31.39.58

The primary node is healthy and running as the master, with two replicas connected and actively syncing.

root@ArunValkeyPrimary:/home/ubuntu# valkey-cli -a amma@123

Warning: Using a password with '-a' or '-u' option on the command line interface may not be safe.

127.0.0.1:6379> INFO replication

# Replication

role:master

connected_slaves:2

slave0:ip=172.31.37.55,port=6379,state=online,offset=98214,lag=1

slave1:ip=172.31.39.58,port=6379,state=online,offset=98214,lag=1

master_failover_state:no-failover

master_replid:629656a198b7290bf6492e470b449ad1ced509e0

master_replid2:30977276632877f46ad12fcc2bbc2c5191c67c0c

master_repl_offset:98214

second_repl_offset:1643

repl_backlog_active:1

repl_backlog_size:1048576

repl_backlog_first_byte_offset:1643

repl_backlog_histlen:96572

127.0.0.1:6379>

Step 1: Create the Sentinel Configuration File

Sentinel runs as a separate process from the main Valkey database, using its own configuration file and listening on port 26379 by default.

The Sentinel configuration file (typically /etc/valkey/sentinel.conf) must be created or edited on all three nodes(ArunValkeyPrimary, ArunValkeyReplica, and ArunValkeyReplica2).

Open the file and add the following core directives:

port 26379
# Format: sentinel monitor <cluster-name> <primary-ip> <primary-port> <quorum>
sentinel monitor mymaster 172.31.32.27 6379 2

# The primary password set in the previous setup
sentinel auth-user mymaster default

sentinel auth-pass mymaster amma@123

# How many milliseconds the primary must be unreachable before Sentinel considers it down
sentinel down-after-milliseconds mymaster 5000

# How long to wait before trying another failover if the first one fails
sentinel failover-timeout mymaster 10000

Understanding the monitor line:

  • mymaster is the arbitrary name given to this cluster.
  • 172.31.32.27 6379 points to the current primary node (ArunValkeyPrimary). (Sentinels will automatically discover both replicas by querying the primary, so the replica IPs do not need to be listed).
  • 2 is the quorum. This means at least 2 out of the 3 Sentinels must agree the primary is down to initiate a failover.

Step 2: Ensure Proper Permissions

Sentinel needs the ability to rewrite its own configuration file. When a failover happens, Sentinel updates sentinel.conf with the new primary’s IP address and the current state of the cluster.

Ensure the valkey user has write permissions to the file on all three nodes:

sudo chown valkey:valkey /etc/valkey/sentinel.conf

Step 3: Start the Sentinel Services

Start the Sentinel service on all three nodes. Depending on the Linux distribution and the Valkey installation method, this is usually done via systemctl:

root@ArunValkeyPrimary:/home/ubuntu# sudo systemctl enable valkey-sentinel
Synchronizing state of valkey-sentinel.service with SysV service script with /usr/lib/systemd/systemd-sysv-install.
Executing: /usr/lib/systemd/systemd-sysv-install enable valkey-sentinel
root@ArunValkeyPrimary:/home/ubuntu# sudo systemctl start valkey-sentinel
root@ArunValkeyPrimary:/home/ubuntu#


root@ArunValkeyReplica:/home/ubuntu# sudo systemctl enable valkey-sentinel
Synchronizing state of valkey-sentinel.service with SysV service script with /usr/lib/systemd/systemd-sysv-install.
Executing: /usr/lib/systemd/systemd-sysv-install enable valkey-sentinel
root@ArunValkeyReplica:/home/ubuntu# sudo systemctl start valkey-sentinel
root@ArunValkeyReplica:/home/ubuntu#

root@ArunValkeyReplica2:/home/ubuntu# sudo systemctl enable valkey-sentinel
Synchronizing state of valkey-sentinel.service with SysV service script with /usr/lib/systemd/systemd-sysv-install.
Executing: /usr/lib/systemd/systemd-sysv-install enable valkey-sentinel
root@ArunValkeyReplica2:/home/ubuntu# sudo systemctl start valkey-sentinel
root@ArunValkeyReplica2:/home/ubuntu#

Step 4: Verify the Sentinel Cluster

Check if the Sentinels are successfully communicating with each other and monitoring the database. Log into any node and use the Valkey CLI to connect to the Sentinel port (26379):

root@ArunValkeyPrimary:/home/ubuntu# valkey-cli -p 26379
AUTH failed: ERR AUTH <password> called without any password configured for the default user. Are you sure your configuration is correct?
127.0.0.1:26379> INFO sentinel
# Sentinel
sentinel_masters:1
sentinel_tilt:0
sentinel_tilt_since_seconds:-1
sentinel_running_scripts:0
sentinel_scripts_queue_length:0
sentinel_simulate_failure_flags:0
master0:name=mymaster,status=ok,address=172.31.32.27:6379,slaves=2,sentinels=3
127.0.0.1:26379>

Look closely at the master0 line at the bottom. This confirms everything is functioning correctly:

  • status=ok: The primary (ArunValkeyPrimary) is healthy.
  • slaves=2: Sentinel found both ArunValkeyReplica and ArunValkeyReplica2.
  • sentinels=3: All three Sentinel instances have discovered each other and formed a quorum.

Additional Verification: Sentinel Peer Health

To further validate that all Sentinel nodes are actively communicating and healthy, we can query the list of Sentinel peers and inspect their status:

root@ArunValkeyPrimary:/home/ubuntu# valkey-cli -p 26379 SENTINEL SENTINELS mymaster | grep -E -A 1 '^ip$|^flags$|^last-ok-ping-reply$|^down-after-milliseconds$'
ip
172.31.37.55
--
flags
sentinel
--
last-ok-ping-reply
65
--
down-after-milliseconds
5000
--
ip
172.31.39.58
--
flags
sentinel
--
last-ok-ping-reply
65
--
down-after-milliseconds
5000
root@ArunValkeyPrimary:/home/ubuntu#

What this means:

  • ip ? Lists the other Sentinel nodes in the cluster
  • flags=sentinel ? Confirms these are active Sentinel peers
  • last-ok-ping-reply ? Indicates the last successful heartbeat response (in milliseconds)
  • down-after-milliseconds: 5000 ms ? failure threshold

Lower values here indicate healthy and responsive communication between Sentinel nodes.

Step 5: The Chaos Test (Triggering a Failover)

The best way to trust an HA setup is to break it intentionally. We will simulate a crash by killing the primary node, verifying the failover, and then manually failing back to our original primary.

1. Kill the Primary

On ArunValkeyPrimary (172.31.32.27), stop the Valkey database service (do not stop Sentinel, just the database):

root@ArunValkeyPrimary:/home/ubuntu# sudo systemctl stop valkey
root@ArunValkeyPrimary:/home/ubuntu#

2. Verify the Failover via Sentinel

Wait for about 5 to 10 seconds to allow the down-after-milliseconds threshold to pass and the Sentinels to complete the election process. Instead of checking the logs, you can query the Sentinel information directly to confirm the failover has occurred and find out which node was promoted.

On ArunValkeyReplica, connect to the Sentinel port (26379) and run the INFO sentinel command:

root@ArunValkeyReplica:/home/ubuntu# valkey-cli -p 26379
127.0.0.1:26379> INFO sentinel
# Sentinel
sentinel_masters:1
sentinel_tilt:0
sentinel_tilt_since_seconds:-1
sentinel_running_scripts:0
sentinel_scripts_queue_length:0
sentinel_simulate_failure_flags:0
master0:name=mymaster,status=ok,address=172.31.37.55:6379,slaves=2,sentinels=3
127.0.0.1:26379>

Look at the master0 line at the bottom. It shows that the status is ok and the primary address is now 172.31.37.55:6379.

3. Verify the Failover via the Database

Now, connect to that newly promoted node (172.31.37.55) on the standard database port to verify the promotion from the database’s perspective:

root@ArunValkeyReplica:/home/ubuntu# valkey-cli -a amma@123
Warning: Using a password with '-a' or '-u' option on the command line interface may not be safe.
127.0.0.1:6379> INFO replication
# Replication
role:master
connected_slaves:1
slave0:ip=172.31.39.58,port=6379,state=online,offset=574633,lag=0
master_failover_state:no-failover
master_replid:b93b82982616a59a2304a799e548d7398ee15732
master_replid2:43ea3aeca4846f06c3c6dd11174e9bfd7ac7fabf
master_repl_offset:574633
second_repl_offset:475110
repl_backlog_active:1
repl_backlog_size:1048576
repl_backlog_first_byte_offset:450256
repl_backlog_histlen:124378
127.0.0.1:6379>

Notice that the role has changed from slave to master, and it now shows 1 connected slave (the other surviving replica, 172.31.39.58).

4. Restarting the Old Primary

When the Valkey service on ArunValkeyPrimary is eventually restarted, Sentinel will automatically detect it, reconfigure it as a read-only replica, and point it to the newly promoted primary to catch up on missed data.

root@ArunValkeyPrimary:/home/ubuntu# sudo systemctl start valkey
root@ArunValkeyPrimary:/home/ubuntu# valkey-cli -p 26379 INFO sentinel
AUTH failed: ERR AUTH <password> called without any password configured for the default user. Are you sure your configuration is correct?
# Sentinel
sentinel_masters:1
sentinel_tilt:0
sentinel_tilt_since_seconds:-1
sentinel_running_scripts:0
sentinel_scripts_queue_length:0
sentinel_simulate_failure_flags:0
master0:name=mymaster,status=ok,address=172.31.37.55:6379,slaves=2,sentinels=3

Check the database replication status on the old primary to see it is now acting as a replica:

root@ArunValkeyPrimary:/home/ubuntu# valkey-cli INFO replication
# Replication
role:slave
master_host:172.31.37.55
master_port:6379
master_link_status:up
master_last_io_seconds_ago:0
master_sync_in_progress:0
slave_read_repl_offset:614120
slave_repl_offset:614120
slave_priority:1
slave_read_only:1
replica_announced:1
connected_slaves:0
master_failover_state:no-failover
master_replid:b93b82982616a59a2304a799e548d7398ee15732
master_replid2:0000000000000000000000000000000000000000
master_repl_offset:614120
second_repl_offset:-1
repl_backlog_active:1
repl_backlog_size:1048576
repl_backlog_first_byte_offset:607384
repl_backlog_histlen:6737
root@ArunValkeyPrimary:/home/ubuntu#

5. Executing a Manual Failback

If you want ArunValkeyPrimary to reclaim its throne as the primary node, you can trigger a manual failover. First, configure it to have a high priority for elections, then issue the failover command to Sentinel:

root@ArunValkeyPrimary:/home/ubuntu# valkey-cli CONFIG SET replica-priority 1
OK
root@ArunValkeyPrimary:/home/ubuntu# valkey-cli CONFIG REWRITE
OK
root@ArunValkeyPrimary:/home/ubuntu# valkey-cli -p 26379 SENTINEL FAILOVER mymaster
AUTH failed: ERR AUTH <password> called without any password configured for the default user. Are you sure your configuration is correct?
OK

(Note: The AUTH failed warnings simply indicate the CLI attempted to pass a default auth to a Sentinel instance that might not require it or is configured differently, but the OK confirms the command successfully executed.)

Check Sentinel one last time to confirm ArunValkeyPrimary (172.31.32.27) is back in charge:

root@ArunValkeyPrimary:/home/ubuntu# valkey-cli -p 26379 INFO sentinel

AUTH failed: ERR AUTH <password> called without any password configured for the default user. Are you sure your configuration is correct?
# Sentinel
sentinel_masters:1
sentinel_tilt:0
sentinel_tilt_since_seconds:-1
sentinel_running_scripts:0
sentinel_scripts_queue_length:0
sentinel_simulate_failure_flags:0
master0:name=mymaster,status=ok,address=172.31.32.27:6379,slaves=2,sentinels=3
root@ArunValkeyPrimary:/home/ubuntu#

Wrapping Up

By combining replication with Sentinel, a single cache becomes a highly available, self-healing data cluster. If hardware fails or network hiccups occur, Sentinel automatically handles the reshuffling. Furthermore, as demonstrated, system administrators still retain full control to manually shuffle roles during planned maintenance or load balancing.

The post Achieving High Availability with Valkey Sentinel appeared first on Percona.

Apr
23
2026
--

Scaling Your Cache: A Step-by-Step Guide to Setting Up Valkey Replication

In the recent open-source data landscape, Valkey has emerged as a prominent player. Born as a Linux Foundation-backed, fully open-source fork of Redis (following Redis’s recent licensing changes), Valkey serves as a high-performance, in-memory key-value data store.

Whether Valkey is deployed as a primary database, an ephemeral cache, or a rapid message broker, a single node is rarely sufficient for production workloads, as it creates a single point of failure. Ensuring high availability and scaling out read operations requires replication.

This comprehensive guide explores how to configure a Primary-Replica (Master-Slave) replication topology in Valkey, detailing its underlying mechanics and the verification process.

How Valkey Replication Works

Valkey’s replication is asynchronous and non-blocking. When a replica connects to a primary node, it initiates a synchronisation process.

Initially, the primary creates a snapshot of its entire dataset in memory (an RDB file) and sends it to the replica. Once this initial full sync is complete, the primary continuously streams a log of all new write operations to the replica. Because this happens asynchronously, the primary node does not wait for the replica to acknowledge writes, meaning applications experience zero latency penalty from the replication process.

Why Use Replication?

Before diving into the configuration commands, it is important to understand the concrete benefits of this architecture:

  • Data Redundancy: Replication maintains a near real-time copy of the data on replicas. However, because replication is asynchronous, there may be a small delay, and recent writes might not be fully replicated at the moment of a primary failure. For applications requiring stronger durability guarantees, the WAIT command can be used to ensure that writes are acknowledged by one or more replicas.
  • Read Scaling: Heavy read operations (like GET or LRANGE commands) can be offloaded to replicas. This frees up the primary node to dedicate its CPU and network bandwidth to handling write operations efficiently.
  • High Availability: When paired with Valkey Sentinel or a cluster manager, replication forms the foundational layer for automatic failover.

Prerequisites

The following components are required:

  • Two servers, virtual machines, or containers with Valkey installed.
  • Network connectivity: The replica must be able to reach the primary on its Valkey port. Ensure firewalls (UFW, iptables) or cloud security groups (AWS, GCP) allow TCP traffic on port 6379 between the specified IPs.

This tutorial uses the following hypothetical IP addresses:

  • Primary Node: 172.31.32.27
  • Replica Node: 172.31.37.55
  • Valkey Port: 6379 (the default)

Step 1: Configure the Primary Node

By default, Valkey binds only to localhost (127.0.0.1), meaning it rejects connections from outside servers. This must be adjusted to allow replica connections.

  1. Open the Valkey configuration file on the Primary Node (typically located at /etc/valkey/valkey.conf, depending on the installation method).

      2. Find the bind directive. Update it to listen on both localhost and the internal network IP. Note: While * can be used to listen on all interfaces, specifying the exact IP provides better security.

bind 127.0.0.1 172.31.32.27

  1. Configure ACLs (Access Control Lists) for Security and Replication:

 While older versions of Redis used the requirepass directive, Valkey utilizes modern ACLs. Securing the default user and creating a dedicated, restricted user specifically for replication is highly recommended. This ensures the replica only has the permissions necessary to sync data. Add the following ACL rules:

# Secure the default user so unauthorized users cannot access the database
user default on >amma@123 ~* &* +@all

# Create a dedicated replication user with ONLY the permissions needed to sync
user repl_user on >ReplPass@123 -@all +psync +replconf +ping +info

  1. Restart the Valkey service to apply the changes:
sudo systemctl restart valkey

Note on Configuration Methods: This guide uses the File-Based method, which requires a service restart. Alternatively, ACLs can be configured dynamically at Runtime with zero downtime. To do this, log into the Valkey CLI, run the commands ACL SETUSER default on >amma@123 ~* &* +@all and ACL SETUSER repl_user on >ReplPass@123 -@all +psync +replconf +ping +info, and then immediately run CONFIG REWRITE to save the new users permanently to the .conf file.

Step 2: Configure the Replica Node

Now, let’s move over to the Replica Node (172.31.37.55). There are two ways to configure a replica: dynamically via the CLI using the REPLICAOF command (which resets upon reboot) or permanently via the configuration file. For production, we will use the permanent method.

  1. Open the Valkey configuration file on the Replica.
  2. Locate the replicaof directive (in older versions or Redis compat mode, this might be slaveof). Uncomment it and add the Primary’s IP and port:
replicaof 172.31.32.27 6379

  1. Authenticate using the Replication ACL: Because a dedicated repl_user was created on the primary node, the replica must be configured to use those specific credentials. Find the masteruser and masterauth directives and update them:
masteruser repl_user
masterauth ReplPass@123

  1. (Optional but recommended) Ensure the replica is strictly read-only by checking this directive:
replica-read-only yes

Restart the Valkey service on the replica:

sudo systemctl restart valkey

Note on Configuration Methods: This guide uses the File-Based method, which requires a service restart (sudo systemctl restart valkey) to apply changes. Alternatively, configurations can be changed at Runtime via the CLI (e.g., CONFIG SET masterauth …). If using the CLI method, you must run CONFIG REWRITE to save those changes permanently to the .conf file without a restart.

Step 3: Verify the Replication

The replica should now be connecting to the primary and synchronizing the dataset. Let’s verify the connection and test the data flow.

Checking Replication Status

Log in to the Primary Node using the Valkey CLI.

Pro tip: The CLI generates a warning when passing a password with -a, as it appears in bash history. For production systems, consider utilizing the VALKEYCLI_AUTH environment variable instead. Note for Valkey 7.2.x users: As the first release following the Redis fork, the system still uses the legacy REDISCLI_AUTH environment variable name.

valkey-cli -a YourSuperSecurePassword

Once inside the prompt, type the INFO replication command:

root@ArunValkeyPrimary:/home/ubuntu# valkey-cli -a  amma@123

127.0.0.1:6379> INFO replication
# Replication
role:master
connected_slaves:1
slave0:ip=172.31.37.55,port=6379,state=online,offset=126,lag=1
master_failover_state:no-failover
master_replid:7ef2ac2cc03b211c9571da0c0a53899327177349
master_replid2:0000000000000000000000000000000000000000
master_repl_offset:126
second_repl_offset:-1
repl_backlog_active:1
repl_backlog_size:1048576
repl_backlog_first_byte_offset:1
repl_backlog_histlen:126
127.0.0.1:6379>

Warning: Using a password with ‘-a’ or ‘-u’ option on the command line interface may not be safe.

Key Metrics to Watch:

  • role: Confirms this node is the master/primary.
  • state=online: The replica is fully synced and streaming.
  • lag=0: The replica is up to date. If this number climbs, the replica is struggling to keep up with the primary’s write volume.
  • offset: Matches the master_repl_offset, confirming data parity

The Write Test

To double-check the data flow, set a key on the primary:

# On Primary (172.31.32.27)
127.0.0.1:6379> SET blog_status "Replication works!"
OK
127.0.0.1:6379>

Then, hop over to the Replica’s CLI and read the key:

# On Replica (172.31.37.55)
127.0.0.1:6379> GET blog_status
"Replication works!"
127.0.0.1:6379>

Wrapping Up

With just a few configuration changes, you’ve transformed a single-node Valkey setup into a scalable, production-ready replication topology. You now have data redundancy, improved read performance, and a solid foundation for growth.

But there’s one missing piece—automatic failover. If the primary node goes down, the replicas won’t take over automatically. That’s where the next evolution comes in.

In the upcoming guide, I will dive into Valkey Sentinel and show how to turn this replicated setup into a fully self-healing, highly available system.

The post Scaling Your Cache: A Step-by-Step Guide to Setting Up Valkey Replication appeared first on Percona.

Mar
18
2026
--

Rate Limiting Strategies with Valkey/Redis

Rate limiting is one of those topics that looks simple until you’re actually doing it in production. Implement a counter with the INCR command and a TTL and away you go. But when you ask questions like “what happens at the boundary?”, “should I use a Valkey/Redis cluster?”, or “why are we getting twice the […]

Mar
06
2026
--

Valkey and Redis Sorted Sets: Leaderboards and Beyond

  This blog post covers the details about sorted set use cases as discussed in this video. Sorted sets are one of the most powerful data structures in Valkey and Redis. While most developers immediately think about “gaming leaderboards” when they hear about sorted sets, this versatile data type can solve many problems, from task […]
Feb
26
2026
--

Security Advisory: A Series of CVEs Affecting Valkey

A series of vulnerabilities has been identified that affect all versions of Valkey. Below is the summary of each vulnerability: The patches for these CVEs had been released in newer versions of valkey-server and valkey-bloom. Please consider upgrading to these versions as soon as possible: valkey-server 9.0.3 valkey-server 8.1.6 valkey-server 8.0.7 valkey-server 7.2.12 valkey-bloom 1.0.1 […]
Feb
19
2026
--

A Guide to Accelerating Your Application with Valkey: Caching Database Queries and Sessions

Modern applications often rely on multiple services to provide fast, reliable, and scalable responses. A common and highly effective architecture involves an application, a persistent database (like MySQL), and a high-speed cache service (like Valkey). In this guide, we’ll explore how to integrate these components effectively using Python to dramatically improve your application’s performance. Understanding […]

Powered by WordPress | Theme: Aeros 2.0 by TheBuckmaker.com